---
title: "Mainframe Offloading One Pager"
description: ""
lastUpdated: 2026-04-21T11:56:03.000Z
source_url:
html: "https://www.ververica.com/asset-library/mainframe-offloading-one-pager"
md: "https://www.ververica.com/asset-library/mainframe-offloading-one-pager.md"
---
# Mainframe Offloading
Download this one-page reference sheet to learn how to modernize your mainframe, slash processing time, and cut MIPs.
Mainframes are the backbone of many critical business operations. While reliable, these slow, batch-based systems also have high operational costs, limited agility, and struggle to support today's demand for real-time insights and actions.
With Ververica, you can evolve your mainframes beyond rigid, expensive systems into modern real-time solutions.
With Ververica, you can evolve your mainframes beyond rigid, expensive systems into modern real-time solutions.
Unlock real-time intelligence, make decisions at lightning-fast speed, and bridge the gap between your traditional systems and AI/ML pipelines by leveraging your existing mainframe data to power your next-gen applications.
Download this free one-page reference to learn:
- How one global bank slashed its MIPS (Millions of Instructions per Second) cost by 90%
- Why businesses choose to offload legacy workloads utilizing Ververica's Unified Streaming Data Platform
- Benefits of offloading mainframe data when building modern, real-time pipelines
- ...and more!
---
---
title: "Stream Processing vs. Batch Processing"
description: ""
lastUpdated: 2026-04-15T16:48:02.000Z
source_url:
html: "https://www.ververica.com/ecosystem-introduction/run-batch-and-stream-with-flink-on-ververica"
md: "https://www.ververica.com/ecosystem-introduction/run-batch-and-stream-with-flink-on-ververica.md"
---
# Stream Processing vs. Batch Processing
Apache Flink blends batch and stream. Ververica delivers the enterprise tools to run unified data workloads reliably, efficiently, and at scale.
## What do we mean by "Batch" vs "Stream" processing?
The difference between Batch and Stream processing
> **INFO:** Batch processing handles a finite, known dataset like a daily log file or database snapshot by running a job that processes all data, produces results, and then stops. In contrast, stream processing deals with unbounded, continuously arriving data such as sensor readings or user events, focusing on near-real-time insights and low latency. Because streaming systems never truly finish, they must manage event-time, late or out-of-order data, and maintain ongoing state for incremental computations.
### Batch processing
- You process a bounded dataset, i.e., a finite collection of data that is known (or assumed) to be complete, e.g., a file, a database snapshot, or a table of logs for the day.
- The job runs, processes the data, produces results, and finishes. There’s no ongoing “listening to new data forever”.
- Latency (time from data arrival to result) is typically higher - we don’t expect instant results; rather we process large volumes, often for analytics, [ETL](https://www.ververica.com/use-case/extract-transform-load?hsLang=en), and reporting.
- Because the input is static/known, you can use certain optimisations (e.g., global sorts, blocking operations) because you know the whole dataset ahead of time.
### Stream processing
- Here you deal with unbounded or semi‐unbounded data: data arrives continuously (e.g., sensor readings, Kafka topics, user events) and the job may never “finish”.
- The goal is to process data as it arrives, often with low latency: near-real-time reactions. Examples: fraud detection, alerting, click-stream analytics.
- Because data keeps coming, you must handle things like time (event-time, processing-time), windows, late data, out‐of‐order events.
- You cannot assume you know the full dataset ahead of time, so you have to design for ongoing computations, incremental updates, stateful streaming.
## How Apache Flink® approaches both - unified architecture
One of the big advantages of [Apache Flink](https://www.ververica.com/what-is-apache-flink?hsLang=en) is that it supports both paradigms in a unified way - you don’t need two completely separate engines. Let’s dive into how.
### Flink’s "stream‐native" mindset
- Flink was originally built as a **stream‐native** engine: meaning its core architectural model treats data as streams even when the streams are bounded.
- In fact, one of the core design philosophies: _batch is just a special case of streaming_.
- Because of that, even “batch” jobs in Flink often use the same fundamental runtime and APIs (for example, the DataStream API) rather than a completely separate batch engine.
### Bounded vs Unbounded & Execution Mode
- In Flink you can specify an execution mode: **STREAMING** or **BATCH**. For example, the documentation: _“Apache Flink’s unified approach to stream and batch processing means that a DataStream application executed over bounded input will produce the same final results regardless of the configured execution mode.”_
- The _boundedness_ of the input matters: if all sources are bounded, then a job is bounded; if at least one is unbounded, the job is unbounded. The BATCH execution mode only makes sense for bounded jobs.
- When you choose BATCH mode, Flink can apply additional optimisations (e.g., more efficient joins/aggregations, shuffle strategies) because it knows whole input is finite.
### Unified API & reuse
- Because of this unification, you can often write (or reuse) code that runs either as streaming or batch with minimal changes if the logic itself is compatible. The Table API/SQL in Flink is unified for both batch and stream.
- This helps in scenarios where you want to run the same logic over historical data (batch) and then continue with live incremental data (stream). For example: initial back‐fill + ongoing real-time processing.
### Optimisations when batch mode is used
Some specifics of how Flink optimises when working in BATCH mode:
- Because the input is finite, Flink can use blocking operators (operators that wait for all input before proceeding) and global sorting of keys, which you might not want in an unbounded stream scenario.
- The shuffle and task scheduling can be more efficient: tasks can materialise intermediate results differently (even spilling less, materialising more aggressively) because termination is guaranteed.
- State management can be simplified: for bounded jobs you might not need extensive checkpointing/back‐pressure in the same sense as streaming continuous jobs.
### Key implication: one engine, two modes
So practically:
- You use Flink’s DataStream (or Table/SQL) API.
- You choose your sources (bounded vs unbounded).
- You set execution mode accordingly (STREAMING vs BATCH).
- Flink’s runtime adapts optimisations under the hood.Therefore you avoid the “two completely separate code‐bases” problem.
## Use-cases: when to pick batch vs streaming (in Flink)
Let’s talk about when you might choose one vs the other, especially in a Flink context.
### Use-cases favouring batch mode
- You have a large historical dataset you want to process (say logs for last month) where latency isn't critical; you just want a final result (report, ETL load).
- You want to perform heavy aggregations, full joins, sorting across the whole dataset. Because input is bounded, optimisations can be applied.
- You’re doing a “back-fill” job: fill up data until now, then you might switch to streaming. Flink supports that transition nicely.
- Example: nightly job processing overnight logs, generating daily summary reports.
### Use-cases favouring streaming mode
- Data arrives continuously and you need results quickly (near real-time), e.g., fraud detection, monitoring, anomaly alerts, live dashboards.
- You need to maintain state over time, use event‐time semantics, handle windows, out‐of‐order events, and you cannot wait for all data to arrive.
- Example: online click-stream processing, sensor data pipelines, alerting on live transactions.
### Hybrid / mixed scenarios
- Many realistic architectures involve both: back‐fill large historical data (batch) then switch to live processing (stream). Flink’s unified model supports this.
- You might also want incremental full + incremental updates: process backlog (batch), then process new events as stream.
- It’s worth noting that having a pipeline that _mixes_ batch and streaming within the same job is possible but has constraints. For example, the input sources must support bounded/unbounded appropriately, and you must consider execution semantics accordingly.
### Rule-of-thumb in Flink
- If your input is unbounded and you care about low latency → streaming mode.
- If your input is bounded (finite) and latency is less critical than throughput/complete result → batch mode (or bounded streaming).
- If you want “both” (initial historical + ongoing real-time) → consider unified pipeline with Flink, perhaps start bounded, then switch to streaming.
## Practical considerations & differences in Flink implementation
When you’re working with Flink (or designing pipelines) you’ll want to keep in mind some of the implementation details and trade-offs.
### Time semantics, state, windows
- In streaming mode, you’ll often work with **event time** (when the event occurred) vs **processing time** (when Flink sees it). Flink supports both.
- For windows (e.g., tumbling, sliding windows) you need to consider late events, watermarking, state size. This is a streaming concern.
- In batch mode, because the data is bounded, these concerns simplify: you might not need complex watermarking or window‐handling of late data (assuming you ingest all data).
### Fault tolerance, checkpointing, resource usage
- Streaming mode needs to run indefinitely, so you care about fault tolerance (checkpoints, state backends) and resource usage over time.
- In batch mode, since job terminates, you may rely less on constant checkpointing; Flink’s BATCH mode may reduce overhead for those parts. For example, one user said: “On the docs it’s said that it does not use checkpointing, back-pressure, nor even a RocksDB, and that ‘keys are sorted and processed sequentially’.”
- Resource usage: streaming jobs hold resources long-term; batch jobs can release when done.
### Performance & optimisations
- Because Flink uses the same engine, you get benefits of pipelining and parallel processing in both modes.
- In batch mode, Flink can apply more aggressive optimisations: for example global sort, blocking operators, more efficient shuffles.
- However: streaming latency demands may limit some optimisations (you can’t wait for whole dataset).
- One article claims Flink can provide “up to 100× better throughput and latency for streaming workloads” compared to older batch-native systems when used appropriately.
### Code and API reuse
- Because the DataStream API and Table/SQL API are unified, you can write code that works in both modes (with minimal changes) if your logic doesn’t rely on e.g., the job terminating vs being infinite.
- That’s really valuable: less duplication between batch & streaming code‐bases.
### Things to watch out for
- Just because you’re using bounded input doesn’t necessarily mean you should auto‐choose batch mode: if you still need near‐real-time updates you might choose streaming even on bounded input.
- If your sources don’t support bounded/unbounded semantics properly (old connectors vs new), you may face issues. For example: only some sources (e.g., KafkaSource) support both bounded and unbounded mode.
- Be careful about mixing bounded/unbounded sources in the same job: unbounded means you’re effectively streaming.
- Ensure you pick the correct execution mode (BATCH vs STREAMING) so Flink can apply the correct optimisations.
## Summary: when to use what, and how Flink fits
Let’s wrap up the main take-home points:
- **Batch processing** = bounded datasets + full result + throughput prioritised over latency.
- **Stream processing** = continuous data + incremental results + low latency prioritised.
- Flink allows both in one engine, you don’t need entirely separate systems.
- With Flink:
- If you set execution mode = BATCH and have bounded sources, you can benefit from special optimisations.
- If you have unbounded streams (or need low latency), use execution mode = STREAMING (or default).
- Use-case oriented: choose streaming for “as events happen” processing; choose batch for “process the heavy dataset later” analytics.
- For many real systems: you’ll do _both_ (e.g., back‐fill batch, then continuous streaming) and Flink supports that via unified API.
- Technical considerations matter: time semantics, state management, checkpointing, resource usage, connector capabilities
The code reuse advantage: with Flink you can potentially write once and run in both modes (or switch modes) rather than maintain two separate pipelines.
## Example scenario: how you might implement in Flink
Here’s how you might approach a real scenario:
- Suppose you are ingesting user click events for a website you want to:
- A) process historical click logs (past 30 days) to compute user behaviour metrics;
- B) from now on process live click events to update metrics in near real‐time.
### Step A) Batch part
- Use a bounded source: e.g., read logs from S3/HDFS for the last 30 days.
- Set Flink execution mode to BATCH.
- Use DataStream API (or Table API) to compute aggregates, join with user profile data, etc. Because input is bounded you get full result (e.g., user metrics snapshot).
- After job completes, write results to a data store (e.g., a database or data warehouse).
### Step B) Streaming part
- Set up a KafkaSource (unbounded) reading live click events.
- Use Flink in STREAMING mode. Use event‐time windows (e.g., tumbling 5-minute windows) to compute sliding metrics. Maintain state for each user.
- Update results in near‐real‐time (e.g., a live dashboard, alerting, incremental enrichment).
- Possibly you join with the historical snapshot from the batch job or keep that in a store.
### Optionally
You might combine the logic so that you have _one_ Flink job: ingest the historical (bounded) data + stream data, and set the job to STREAMING mode but the bounded source is processed as “bounded”. Flink will handle it. But you’ll want to ensure you design appropriately (windows, eventual termination or graceful switch).
## How Ververica Platform supports both batch and stream processing
Here are the key ways [Ververica Platform](https://www.ververica.com/product?hsLang=en) (and its ecosystem) makes life easier for unified batch + streaming with Flink:
### Unified Processing and Batch Support
That’s why our Ververica Platform fully supports bounded streaming applications — batch-type jobs that run through the same runtime. When a batch job finishes successfully, the Deployment simply transitions to the **FINISHED** state.
We’ve built our entire ecosystem to bring together ingestion, processing, and storage into a cohesive, cloud-native platform for both batch and streaming.
### Closing the Gap Between Batch and Streaming: The Streamhouse
We introduced the concept of the [**Streamhouse**](https://www.ververica.com/what-is-streamhouse?hsLang=en) to unify streaming and batch analytics. Traditionally, organizations ran separate systems for batch (data lakehouses) and for real-time streaming. With the Streamhouse, we’re eliminating that divide.
You can now achieve incremental updates, low-latency analytics, and unified storage and compute for both historical and real-time data — all in one place.
### Engine Enhancements and Operations Tooling
Under the hood, our [**VERA (Ververica Runtime Assembly)**](https://www.ververica.com/vera?hsLang=en) engine combines the best of open-source Flink with our own advanced innovations.
Operationally, we provide a rich set of capabilities for managing both long-running streaming applications and bounded (batch) jobs. With our platform, you get cluster management, lifecycle UI, bounded-job awareness, deployment states, and more — all designed to simplify operations at scale.
Our ecosystem also includes built-in support for ingestion (e.g., CDC), storage (via Flink CDC + [Paimon](https://www.ververica.com/what-is-apache-paimon?hsLang=en)), state backends, and more — making end-to-end batch and streaming pipelines truly turnkey.
### How We Can Help You
Bringing it all together:
- You can run batch (bounded) and streaming (unbounded) workloads on the same platform and tooling, minimizing fragmentation.
- You get production-grade infrastructure, tooling, and operational support — no need to build everything yourself.
- Our unified Streamhouse architecture reduces duplication — no separate data lake and streaming stack required.
- Our optimized runtime (VERA) delivers exceptional performance, resiliency, and scalability.
- You gain [enterprise-grade features](https://www.ververica.com/product?hsLang=en) like governance, lifecycle management, monitoring, and cluster operations — all in one integrated platform.
## Advantages of using Ververica Platform compared to open-source Apache Flink
Now let’s compare: if you just use open-source Apache Flink vs. adopt Ververica Platform (which builds on Flink). Here are the advantages (and trade-offs).
### Key advantages
1. **Operational & deployment maturity**
- With open-source Flink you get a world-class engine, but you often need to build out the operational layer (cluster management, scalability, multi-tenant, monitoring, UI, lifecycle). Ververica builds much of that out of the box.
- Ververica provides enterprise support, structured best practices, and integrations suited for production-grade, large‐scale systems.
- Example: Job lifecycle management for bounded jobs (batch) is explicitly supported. Open source might require you to build additional orchestration.
1. **Unified architecture for both batch & streaming with less friction**
- While Flink supports both batch & streaming, Ververica emphasises this unification with features like Streamhouse, tightly integrated storage + compute + ingestion. That means less “glue code” or custom architecture.
- This is especially helpful if you’re doing hybrid workloads (back-fill + real-time) which many organisations are. Ververica is designed for that.
1. **Performance and scalability enhancements**
- The VERA runtime claims improved performance, optimised for cloud-native, large state, etc. For example: “Flink-powered lakehouse with 5-10× faster processing…”
- These enhancements might reduce need for tuning and deep internals knowledge (you still need good design).
1. **Integrated ecosystem and tooling**
- With Ververica you don’t just get the engine you get ingestion (CDC), storage (Paimon), unified platform, UI, dashboards, deployment tools. That reduces engineering overhead.
- For example: if you’re building a combined real-time + historical analytics pipeline, having Lakehouse + Streamhouse in one place is a big plus.
1. **Support and risk mitigation**
- Enterprises often prefer vendor support, SLAs, proven track record for critical use cases (finance, IoT, etc). Ververica’s heritage (the original creators of Flink) and its enterprise offering give that.
- If you rely purely on open-source Flink, you may have to invest more in in-house expertise, custom tooling, and risk mitigation.
### What to consider / trade-offs
- Cost: The enterprise platform (Ververica) may involve licensing, support costs vs “free” open-source Flink.
- Flexibility: With open source you’re free to customise deeply; a managed platform may impose some constraints (though likely minor).
- Vendor lock-in: If you adopt platform-specific enhancements, you might tie in to that vendor’s ecosystem (though Ververica is built on open source).
- Overhead vs light use-case: If you have a small project, simple pipeline, maybe open source Flink is sufficient without full platform overhead.
## Conclusion
When choosing between **stream processing** and **batch processing**, the decision always comes down to your data and your goals:
- If your data is _finite_ and you can afford to wait for complete results, **batch processing** is usually more efficient.
- If your data arrives _continuously_ and you need insights as it happens, **stream processing** is the way to go.
With [**Apache Flink**](https://www.ververica.com/what-is-apache-flink?hsLang=en), you don’t have to pick one world or the other; it's built around the idea that _batch is just a special case of streaming_. That means you can process both bounded and unbounded data within the same engine, APIs, and architecture. It gives you the flexibility to run large-scale historical analyses one moment and handle real-time event streams the next, all with consistent semantics and performance.
Now, where [**Ververica Platform**](https://www.ververica.com/product?hsLang=en) really shines is in making all of this easier to manage and operate. It builds directly on Apache Flink but adds a full layer of **enterprise-grade features**: deployment automation, monitoring dashboards, lifecycle management for both long-running streaming apps and finite batch jobs, and built-in optimizations via the [**VERA runtime**](https://www.ververica.com/vera?hsLang=en). It’s designed to take care of the “plumbing” so teams can focus on building data logic, not managing infrastructure.
On top of that, Ververica’s [**Streamhouse**](https://www.ververica.com/what-is-streamhouse?hsLang=en) architecture unifies streaming and batch data under one consistent ecosystem, so historical and real-time analytics no longer live in separate systems. Whether you’re replaying data to rebuild models, running continuous ETL, or feeding real-time dashboards, Ververica Platform gives you a single, cloud-native environment for it all.
In short:
- **Flink** gives you the flexibility and unified model for stream and batch.
- **Ververica Platform** gives you the tools, automation, and reliability to run it at scale, in production, with much less operational friction.
If you’re experimenting, open-source Flink is an excellent place to start. But if you need to move from prototypes to dependable, large-scale, always-on workloads or want an environment where both batch and stream pipelines can coexist seamlessly, Ververica Platform is built exactly for that.
## FAQ
### What’s the difference between batch and stream processing?
**Batch processing** handles a finite, known dataset like a daily log file or database snapshot by running a job that processes all data, produces results, and then stops. In contrast, **stream processing** deals with unbounded, continuously arriving data such as sensor readings or user events, focusing on near-real-time insights and low latency. Because streaming systems never truly finish, they must manage event-time, late or out-of-order data, and maintain ongoing state for incremental computations.
### How does Flink support batch and stream processing ?
**Apache Flink** supports both batch and stream processing through a unified architecture, meaning you don’t need separate engines for each paradigm. It was built as a stream-native engine, treating all data as streams—batch processing is simply a special case of streaming with bounded input. Users can choose between **STREAMING** or **BATCH** execution modes, allowing Flink to apply optimizations like efficient joins or global sorting for finite data. This unified model lets developers reuse the same APIs and logic for both historical (batch) and real-time (streaming) data processing seamlessly.
### When should I use Apache Flink batch mode?
Use **Batch mode** when your data is **bounded** (finite) and you want to process the entire dataset to produce a **complete result**. It’s ideal for offline analytics, historical data backfills, or workloads where **throughput** is more important than latency. In this mode, Flink applies **optimizations** like global sorting, blocking operators, and efficient joins since it knows all data is available upfront.
### When should I use Apache Flink streaming mode?
Use **Streaming mode** when your data is **unbounded** (continuous) or when you need **real-time, low-latency processing**. This mode is best for event-driven applications, live monitoring, or any “as events happen” scenario. Flink’s **stream-native runtime** ensures consistent, incremental updates with strong guarantees on time semantics and state management.
---
---
title: "Finance Industry Reference Sheet"
description: ""
lastUpdated: 2026-04-21T12:02:27.000Z
source_url:
html: "https://www.ververica.com/ecosystem-introduction/finance-industry-reference-sheet"
md: "https://www.ververica.com/ecosystem-introduction/finance-industry-reference-sheet.md"
---
# Finance Industry Reference Sheet
Milliseconds matter. Download this free resource to learn why financial leaders choose Ververica to solve real-time use cases.
In the competitive financial services industry, fresh data fuels real-time decisions, making the difference between leading the market or falling behind.
Learn how Ververica empowers financial institutions to act on data instantly, securely, and at scale.
Unlock real-time intelligence, make decisions at lightning-fast speed, and stay ahead of the market. Download this free reference to learn:
- The advantages investment bankers gain from using real-time data
- How continuous data streams transform commercial banking
- 4 ways to deliver exceptional customer experiences
- 4 real-time financial use cases
- What current customers achieve with Ververica
- ...and more!
---
---
title: "Ververica Platform"
description: ""
lastUpdated: 2026-06-15T09:47:47.000Z
source_url:
html: "https://www.ververica.com/product/ververica-platform"
md: "https://www.ververica.com/product/ververica-platform.md"
---
# Enterprise Flink. For Those Who Cannot Get It Wrong.
**Ververica Platform**
Auto-scaling. Auto-recovery. SOC 2 certified. Zero-downtime upgrades. Multi tenant governance. Plus 2x throughput and 40% lower TCO. 100% Flink API compatible. Drop-in replacement.
- We built Flink
- We know where it breaks.
- We fixed it
- **2x — Throughput**
- **40% — Lower TCO**
- **100% — Flink API compatible**
- We built Flink.
- We know where it breaks in production
- We fixed it
## What Is Ververica Platform?
The enterprise streaming and batch platform built by the original creators of Apache Flink. Unified stream and batch processing in one runtime. Materialized tables that maintain themselves. Auto-scaling, auto-recovery, SOC 2 & ISO 27001 certified, zero-downtime upgrades, multi-tenant RBAC everything production Flink needs, built in. Not bolted on.
## Key Statistics
- **Faster Processing**: Throughput vs open-source Flink
- **Lower TCO**: Same workload, less infrastructure
- **Flink Compatible**: Zero migration effort required
- **Recovery**: Automatic checkpoint restore
## The Problem
Open-Source Flink Is Powerful. Production Is the Hard Part. Manual cluster sizing. No auto-scaling. 2-5 minute recovery times on failure. Upgrades require downtime. No RBAC. No compliance certifications.
Auto-Scaling | Auto-Recovery | SOC 2 & ISO 27001 | Zero-Downtime Upgrades | Multi-Tenancy | Deployment Flexibility
## Technology Innovations
Why Ververica
Traditional: Spark batch + Flink stream, 2x cost
Ververica: One SQL both modes, freshness-driven execution, 40-60% Less Cost
OSS: 2-5 min recovery, full checkpoint
Ververica: <30s auto-recovery, 60% smaller checkpoints
Typical: Rewrite code, months to validate.
Ververica: Same SQL & DataStream, deploy done. 0 Code Changes.
OSS: Row-by-row, full CPU burn
Ververica: Columnar SIMD batches, 40% less CPU, 2x Throughput
## Benchmarks Table
| Feature | Ververica | Open-Source | Improvement |
| --- | --- | --- | --- |
| Throughput | 6.9B records/sec | 3.4B records/sec | 2x |
| Latency (p99) | 8ms | 45ms | 5.6x |
| Resource Usage | 60% | 100% | 40% less |
| Recovery Time | < 30 seconds | 2-5 minutes | 10x |
| Checkpoint Duration | 1.2 seconds | 3.1 seconds | 2.6x |
## Unified Processing
One Platform. Streaming and Batch. Unified.
- Unified Semantics
- Freshness-Driven Execution
- Built-In Scheduling
- Resource Isolation
- 10x Faster Deployment
- 40-60% Cost Reduction
- 97% Faster Snapshots
## Materialized Tables
Define Once. Always Fresh. Query Instantly
- Interactive MaterializedTableDemo component
- SQL-Native
- Always Fresh
- Instant Lookups (<10ms)
## Compatibility (Zero Migration)
Your Flink Code. Unchanged.
- Flink SQL syntax
- DataStream API
- Table API
- All connectors
- State backends
- Checkpointing
- Savepoints
- Python UDFs
- Custom serializers
- Metrics reporters
---
---
title: "Supplemental Privacy Policy"
description: "Learn how Ververica collects and uses your personal data during live events, ensuring compliance and your privacy throughout the process."
lastUpdated: 2026-06-23T08:15:54.000Z
source_url:
html: "https://www.ververica.com/events/supplemental-privacy-policy"
md: "https://www.ververica.com/events/supplemental-privacy-policy.md"
---
# Supplemental Privacy Policy
**Last update: October 31st 2025**
This privacy policy applies to the processing of personal data by Ververica GmbH, Herzogspitalstrasse 24, 80331 München, Germany. (“**we**”, “**us**”, “**ours**") in relation to your interest in, or attendance at, Fluss Forward or Stream Forward or Ververica Academy Apache Flink Bootcamp (an “**Event**”). This privacy policy supplements our website privacy policy, available [here](https://www.ververica.com/privacy-policy).
## 1. The data we collect about you
We may collect, use, store and transfer different kinds of personal data about you as follows:
1. **Identity Data** includes first name, maiden name, last name, or similar identifier.
1. **Contact Data** includes billing address, email address and telephone numbers, including the Contact Data of your next of kin or emergency contact.
1. **Event Data** includes additional information we need for the purposes of the events you may take part in such as dietary requirements and food allergies, travel itineraries and accommodation information.
1. **Profile Data** includes your feedback and survey responses.
1. **Marketing and Communications Data** includes your preferences in receiving marketing from us and our third parties and your communication preferences.
1. **Image Data **includes your image in photos or video from the Event for use in internal and external communications and marketing.
## 2. Purposes for which we will use your personal data
We will use the information that we collect about you for the following purposes:
1. **Performance of a contract with you and manage your relationship with us:** To register you as a new customer or process the booking of the Event, or to improve our products/services, marketing or customer relationships.
1. **Legitimate interests:** We may use your personal data where it is necessary to conduct our business and pursue our legitimate interests. For example, to fulfil and monitor our legal responsibilities. We make sure we consider and balance any potential impact on you and your rights (both positive and negative) before we process your personal data for our legitimate interests. We do not use your personal data for activities where our interests are overridden by the impact on you (unless we have your consent or are otherwise required or permitted to by law).
1. **Legal obligation:** We may use your personal data where it is necessary for compliance with a legal obligation that we are subject to.
1. **For general administration and organization of our events:** We may contact you to provide you with information about the Event, such as event updates, possible changes, cancellation or similar information, for planning and logistics, to invoice you, in the event of an emergency, and general administration of your attendance (such as creating a delegate list for the Event).
1. **Enhancing our events:** We may film and photograph the Event which will be used to market our services and to promote future events on our website, social media channels and in marketing materials. We may also contact you for your feedback or review after the Event you have attended or to assess the activity of our attendees at the Event
## 3. Third party
We may share your personal information with other third parties where this is necessary for legal or regulatory reasons, or where it is in our legitimate interests, in order to facilitate us to organise this Event. These third parties may include: our auditors or external financial or legal advisors, regulatory authorities, government authorities and/or law enforcement officials, if mandated by law or if needed for the protection of our legitimate interests in compliance with applicable laws; our suppliers, business partners, sub-contractors or business support service providers; and our agents who organise the Event on our behalf. Our agents may contact you to ask for further information in relation to this Event (such as hotel booking and arrangement of logistics), any personal information provided to our agents by you will be processed in accordance with our agents’ privacy policy (if applicable).
## 4. Direct marketing
Subject to obtaining your specific consent, or where otherwise permitted by applicable law in your jurisdiction, or by allowing our Event sponsors to scan your Event badge to obtain your contact details, we or our Event sponsors may use your name, phone number, residential address, email address and fax number (which may incorporate personal data) to provide notices, surveys, product alerts, related communications and other marketing and promotional materials to you relating to goods and services offered by us or our Event sponsors. If you would like to discontinue receiving this information, you may update your email preferences by using the “Unsubscribe” link found in emails we or our Event sponsors send to you.
## 5. How long will we retain your personal data
We will retain your personal data for the purposes described in this privacy policy where we have an ongoing legitimate business need to do so. In certain circumstances, we will need to keep your personal data for legal reasons after our relationship has ended. The specific retention periods depend on the nature of the personal data and why it is collected and processed, and the nature of the legal requirement. When we have no ongoing legitimate business need or legal reason to process your personal data, we will either delete or anonymize it or, if this is not possible, then we will securely store your personal data and isolate it from any further processing until deletion is possible.
## 6. Time limit to respond
We try to respond to all legitimate requests within one month. Occasionally it could take us longer than a month if your request is particularly complex or you have made a number of requests. In this case, we will notify you and keep you updated.
## 7. Contact details
We have appointed a data protection officer (DPO). If you have any questions about this privacy policy or our data protection practices please contact:
Attention: Data Protection Officer
c/o Mindspace, Herzogspitalstrasse 24, D-80331 München
E-mail address: [dataprotection@ververica.com](mailto:dataprotection@ververica.com)
For individuals in the EEA, Ververica GmbH is the relevant "data controller" for the purposes of EEA data protection law.
---
---
title: "Streaming Sovereignty"
description: ""
lastUpdated: 2026-07-09T11:23:49.000Z
source_url:
html: "https://www.ververica.com/asset-library/fsi-streaming-sovereignty-one-pager"
md: "https://www.ververica.com/asset-library/fsi-streaming-sovereignty-one-pager.md"
---
# What Other Vendor-Managed Platforms Hide
**The Illusion of Control**
Regulators are not asking whether your vendor claims compliance. They are asking whether YOU can prove control.
## "Managed" Means Vendor-Controlled. Here's What That Costs You.
You outsourced operations. They took control. Vendor-managed streaming platforms hide dependencies that surface during audits, outages, and exit negotiations. This one-pager exposes the trade-offs no vendor puts in the pitch deck.
As we wrote in [Data Sovereignty Is Existential Most Platforms Treat It Like a Feature](https://www.ververica.com/blog/data-sovereignty-is-existential-most-platforms-treat-it-like-a-feature?hsLang=en), true sovereignty requires architectural guarantees — not contractual promises. This one-pager makes that argument visual.
### The Convenience
Managed streaming platforms sell simplicity. Provision in minutes. Scale on demand. No infrastructure headaches.
What they don't sell: the control you surrender to get it.
- **Hidden control planes.** Provisioning, scaling, monitoring, and access management flow through infrastructure you cannot audit. Your data stays in-region. The system controlling it does not.
- **Metadata leakage. **Topic names, schema registries, consumer group offsets, and telemetry cross jurisdictional boundaries. Under DORA and GDPR, that is a compliance exposure. Our [Zero Trust Theater](https://www.ververica.com/blog/zero-trust-theater-and-why-most-streaming-platforms-are-pretenders?hsLang=en) analysis explains why most platforms claiming "Zero Trust" cannot survive an actual audit.
- **No real exit.** Proprietary APIs, vendor-specific tooling, platform-coupled state. Your "exit strategy" is a multi-year migration buried in a contract addendum.
## What This One-Pager Reveals
A visual breakdown of the control trade-offs hidden inside vendor-managed streaming platforms. Built for leaders evaluating AWS Managed Flink, Confluent Cloud, or Azure Event Hubs.
Inside the one-pager:
- **"What they say" vs. "What you get"**: Side-by-side comparison of vendor promises against operational reality
- **The sovereignty gap**: Where managed platforms break data residency, operational control, and technical sovereignty
- **The lock-in anatomy**: How proprietary APIs, coupled state, and closed tooling eliminate your exit options
- **The Ververica alternative**: How BYOC, self-managed, and on-premise deployment models deliver structural control
Get the visual disqualification tool that exposes what "**managed**" actually means for your streaming infrastructure.
##
## Ready to Go Deeper?
- **Assess your posture:** Use the [Streaming Sovereignty Checklist](https://www.ververica.com/streaming-sovereignty-checklist-for-financial-services-industry?hsLang=en) to evaluate your platform against what regulators actually demand
- **Score your platform:** Apply the [Sovereignty Evaluation Framework](https://www.ververica.com/sovereignty-evaluation-framework-for-financial-services?hsLang=en) for a structured 26-requirement technical assessment
- **Read the full guide:** The [FSI Streaming Sovereignty Pillar Page](https://www.ververica.com/fsi-sovereignty-playbook?hsLang=en) covers governance, deployment, Zero Trust, and sovereign AI in depth
---
---
title: "Home page"
description: "The original creators of Apache Flink. Ververica delivers enterprise stream processing with 2x faster performance, 40% lower TCO, and sub-10ms latency."
lastUpdated: 2026-09-08T13:52:19.000Z
source_url:
html: "https://www.ververica.com/home"
md: "https://www.ververica.com/home.md"
---
# Critical won’t wait. Neither can you.
Delivery Assurance for mission-critical real-time data. Built by the original creators of Apache Flink®.
- Forrester Wave Leader, Q4 2025.
- Sovereign by design.
- Engineered in Europe.
- **2X — Faster Processing**: Than open-source Apache Flink
- **40% — Lower TCO**: More from the same infrastructure
- **<10MS — End-to-End Latency**: From event ingestion to action
- **100B+ — Events per Day**: Proven at scale
## Trusted in Production
## 3 reasons.
no fluff.
Why Ververica
We created Apache Flink. Not adopted it. Not forked it. Created it. 10+ years of production-grade streaming.
The #1 contributor to the Flink codebase. Forrester Wave Leader, Q4 2025.
Every event tracked. Every transformation auditable.
SOC 2 Type II. ISO 27001. GDPR. DORA.
Column-level lineage from source to action. Compliance built into the architecture, not bolted on after the audit.
2x throughput over open-source Flink. Sub-10ms latency. 100% API compatible.
Deploy on Fully Managed Cloud, BYOC, or Self-Managed. No vendor lock-in. No data egress. Your cloud, your rules.
## Banking Runs on Ververica.
### Fraud Detection
Score 2B+ transactions per day. Block fraud in under 150ms.
### Real-Time Payments
Instant settlement. Exactly-once processing. Peak-hour resilience.
### AML Monitoring
Continuous monitoring. 60% fewer false positives. Adaptive thresholds.
### Risk Management
Real-time VaR. Counterparty exposure. Continuous stress testing.
### Regulatory Reporting
T+0 reporting. Automated validation. Immutable audit trail.
### Core Modernization
Strangler fig migration. Zero downtime. Dual-run validation.
### Customer Personalization
Act on customer behavior as it occurs. Serve the right offer in under 50ms.
### Mainframe Offloading
Cut MIPS costs by 40% or more without replacing the mainframe.
### Fintech Monitoring
Real-time portfolio risk. Instant wealth management signals.
## Four Pillars.
One Platform.
### Stream
Processing
2x faster than open-source Flink. 40% lower TCO. 100% API compatible. Enterprise compute built by the team that created Flink.
### Data
Movement
100+ connectors. Flink CDC. Every source, every format. Zero custom code.
### Streamhouse
Architecture
Unified batch and stream. One SQL dialect. Lakehouse economics, streaming freshness.
### Real
Time AI
Feature engineering on live data. Sub-100ms inference. Full model lineage.
## Three Steps.
Milliseconds
Apart.
How It Works
### Connect
Ingest data from any source. Kafka, databases, APIs, IoT devices, cloud services. No custom connectors required.
### Process
VERA engine processes streams in real time. Apply business logic, run analytics, execute AI models. Sub-10ms latency.
### Act
Route results to any destination. Trigger alerts, update systems, feed dashboards. Decisions happen now, not later.
## Competitive
comparison
| Feature | Ververica | Open Source | AWS Managed Flink |
| --- | --- | --- | --- |
| Throughput | 6.9B records/sec | 3.4B records/sec | Not published |
| Latency (p99) | 8ms | 45ms | 50-100ms |
| Recovery Time | <30 seconds | 2-5 minutes | 1-3 minutes |
| DORA Compliance | Built in | N/A | N/A |
| Deployment Options | Cloud, BYOC, Self-Managed | Self-managed only | Cloud only |
_Building a platform to provide Security-as-a-Service_
### Booking.com
Booking.com, a leading travel ecosystem serving both partners and travelers, faced challenges with processing security data streams and orchestrating Flink applications with stateful upgrades and multi-tenancy requirements. Their previous approach proved cumbersome and inadequate for their needs.
**Result:** To address these issues, Booking.com selected Ververica Platform to overcome their challenges. The decision to choose Ververica was driven by its ability to enable Booking.com's security teams to manage their own Flink applications independently, freeing up the Platform team to focus on maintaining the overall solution.
- **10x**: More Flink Applications
- **20x**: Faster Deployment
## Forrester
Named a Leader in The Forrester Wave: Streaming Data Platforms, Q4 2025. Not a participation trophy. Recognition of what runs in production, at scale, across industries.
---
---
title: "VVC and BYOC Support and Maintenance Services Terms"
description: "Explore Ververica Cloud Managed Service Support and Maintenance Services, including error reporting, response times, and user obligations. "
lastUpdated: 2026-04-21T12:18:22.000Z
source_url:
html: "https://www.ververica.com/product/deployment/cloud/support-terms"
md: "https://www.ververica.com/product/deployment/cloud/support-terms.md"
---
# Support and Maintenance Services Terms
Ververica Cloud: Managed Service & Bring Your Own Cloud
## 1. DEFINITIONS
1. **"Error"** means a reproducible defect in the Ververica Cloud Services that
1. degrades or impairs User’s use of the Ververica Cloud Services and causes such services not to operate substantially in accordance with the
1. applicable specifications, instructions or other documentation provided by Ververica and
1. is reported via Support Tool. For the avoidance of doubt, an Error does not include any User-specific issue in relation to a User’s use of Ververica Cloud Services in conjunction with such User’s own or its third-party environment, systems, components, interfaces, etc., unless otherwise agreed by Ververica.
1. **"Documentation"** means Ververica Cloud Services documentation, published by Ververica and accessible at[ https://docs.ververica.com](https://docs.ververica.com) and/or other locations on the Ververica Website.
1. **"Business Day"** means Monday through Friday excluding public holidays in supported time zones (Central European Time and Pacific Time).
1. **"Business Hours"**means 9:00 am to 5:00 pm on a Business Day in following time zones:
1. Central European Time in Berlin, Germany, for Europe, Middle East and Africa Users;
1. Pacific Time in San Jose, California, for United States Users.
1. **"Extended Business Hours"** means 24x7x365 including public holidays.
1. "Support Services" means the maintenance and support services purchased by User and described in [Support Services Description,](https://www.ververica.com/deployment/cloud/support)
1. **"Support Tool"** means the third-party internet platform designated by Ververica for the User to open up an account and initiate and receive Support Services.
1. **"Modification" **is modification on top of Ververica Cloud Services that corrects the Error, or a procedure, when applied in the normal operation of the Product, corrects the effect of an Error.
1. **"Update"** means a revision of the Ververica Cloud Services made generally available by Ververica to Users to correct Errors in the services or to maintain the operation of the services in accordance with the Documentation.
1. **"Designated Support Contact"** means the technical support person(s) within User's organization designated by User to act as the contact for the Support and Maintenance Services described herein.
1. Unless otherwise expressly defined, all capitalised terms used in this document shall have the same meanings as defined in the Terms of Service agreed between the User and Ververica.
## 2. SUPPORT
1. **Support**. Ververica will provide support to the User by providing answers and additional information by qualified Ververica personnel to questions raised via Support Tool related to use and operation of the Ververica Cloud Services, including basic instruction or assistance.
1. **Support levels:** Ververica offers (three) 3 levels of paid Support Services plans for Ververica Cloud Services: Basic, Business and Enterprise. Basic, Business plans are limited by Business Hours, while Enterprise plan has Extended Business Hours support availability.
1. **Support Channels:** Ververica shall provide the Support Services through its online[ Support Tool](https://www.ververica.com/portal). Following submission of a support request by the User, Ververica will communicate with User using the Support Tool. Support Services will be provided in English.
1. **Hours of operation**: User may submit support requests through Support Tool twenty-four (24) hours a day, seven (7) days per week. Ververica will address such requests as per service level commitments set for in below _**Clause 3(c) **_for the User’s support plan.
## 3. MAINTENANCE
1. **Target Initial Response Times.** Ververica shall use commercially reasonable efforts to respond to Errors in accordance with the Target Initial Response Times that will be determined by the Priority Levels set out below in the time periods described in this document. The Target Initial Response Times depend on the level of the support plan (Basic/Business/Enterprise) purchased by the User.
1. **Commencement of the Target Initial Response Times.** The Target Initial Response Times will be triggered once User's has reported an Error via the Support Tool, it being understood that in case User has chosen "Basic" or "Business" support plan and has reported an Error outside Business Hours, the Target Initial Response Times will be triggered and Ververica will commence providing services to resolve Errors as per _**Section 3(d)**_ below, once the Business Hours of the next Business Day have commenced. The actual time required to fully resolve the issue, if full resolution occurs, may be longer than the Target Initial Response Time. User understands and agrees that full resolution of an Error is not guaranteed and may not occur.
1. **Classification**. The classification of any Error among Priority Levels shall be reasonably determined by Ververica in accordance with the definitions specified below.
For Users using "free" level of support, free of charge, the Support and Maintenance Services described herein are provided on a "best effort" basis, and Ververica does not guarantee a response within any response timeframe.
1. **Resolving Errors.** Ververica shall use commercially reasonable efforts to resolve Errors in accordance with the provisions set out below.
1. **Error reporting.** User shall report the Error to Ververica via the Support Tool and indicate proposed Priority of Error. Upon receipt of such report, Ververica shall perform the following steps.
1. Ververica will assess the Priority Level of the Error based on the Error description. Appropriate Priority Level is assigned and the User is informed of this change.
1. Ververica will use commercially reasonable efforts to
1. allocate dedicated engineering resource(s) to assessing and correcting the Error, during the time when support is available according the purchased support plan, until the Error is resolved, and
1. provide User with regular updates, unless otherwise indicated in response, until the Error is resolved and
1. notify User once the Error is resolved.
## 4. UPDATES
1. **Update Policy**. Ververica determines whether and when to develop, release and apply any Updates. Ververica reserves the right to determine at its sole discretion whether a new feature will be releases as an Update. Ververica further reserves the right at its sole discretion to change and/or remove certain features of the current Product under any Updates.
1. **Modifications and Updates**: Ververica will use commercially reasonable efforts to provide an Modification designed to solve or workaround reported Error, in accordance with the table in _**Section 3**_. If an Error has been corrected in a Update, an Modification may be provided in the form of a temporary fix or procedure for Error, until a Update containing the Modification is available. Ververica will make Updates available to User if, and when Ververica makes any such Updates generally available to all of its Users.
1. **Exclusions.** Ververica is not obligated to provide Support Services to User if:
1. any Product or portion thereof that was not used in accordance with Ververica’s instructions;
1. any Product or portion thereof that is altered, modified, or converted by User or any third party in a manner that is not in accordance with the Documentation;
1. any defect in the Product or portion thereof due to User's equipment malfunctioning,
1. the Error is caused by User’s negligence, hardware malfunction, the configuration of the platform or datacenter, network latency or causes beyond the reasonable control of Ververica or
1. User has not paid the Support Services fees when due.
## 5. USER OBLIGATIONS
The service standards set forth in this Support and Maintenance Terms assume that User as applicable, meet the following minimum system standards:
1. **User Obligations**. Except as otherwise agreed between the parties in a separate written agreement, User is responsible for
1. maintenance and management of its computer network(s), servers, and software, and any equipment or services related to maintenance and management of the foregoing; and
1. correctly configuring its systems in accordance with any instructions provided by Ververica, as may be necessary for provision of
1. access to the features and functions of the Product.
1. User has made reasonable efforts to resolve the Error before reporting the Error to Ververica, including having the Error reviewed by the Designated Support Contact;
1. User has installed all Updates, if relevant; and
1. User has provided Ververica with sufficient enough information about the Error. This includes any reproducible test scenarios Ververica requests.
1. **Reporting of Errors.** User must promptly notify Ververica in the event an Error occurs.
1. **Cooperation**. User will fully cooperate and assist Ververica in responding to Errors and providing Support and Maintenance Services, including
1. allowing full and free access, remotely and physically, to relevant hardware, software, and other information; and
1. making at least one of its Designated Support Contact(s) available for questions and communication during the time when support is available according the purchased support plan.
1. **Non-Performance by User**. The obligations of Ververica set forth in these Support and Maintenance Terms will be excused to the extent any failures to meet such obligations result in whole or in part from User's or User's Designated Support Contacts’ failure(s) to meet the foregoing requirements.
---
---
title: "Ververica Use Cases"
description: "Ververica Use Cases"
lastUpdated: 2026-03-31T10:29:34.000Z
source_url:
html: "https://www.ververica.com/use-case"
md: "https://www.ververica.com/use-case.md"
---
_No content._
---
---
title: "Events Terms and Service"
description: "Agree to the Event Terms and Service when purchasing tickets for Ververica Events, and stay informed about attendance, refunds, and event status updates."
lastUpdated: 2026-06-23T08:22:50.000Z
source_url:
html: "https://www.ververica.com/events/terms-and-service"
md: "https://www.ververica.com/events/terms-and-service.md"
---
# Event Terms and Service
**Last update: March 4th 2025**
By purchasing a ticket and attending the event, you expressly agree to the Event Terms and Service[,](https://www.ververica.com/academy/terms-of-service) [Privacy Policy](https://www.ververica.com/privacy-policy) and the [Supplemental Privacy Policy](https://www.ververica.com/events/supplemental-privacy-policy) to the event.
## Ticket Purchases and Event Confirmation
1. All ticket purchases are subject to the minimum attendance requirement for the event to proceed.
1. Your ticket purchase reserves your spot at the event, pending final confirmation.
1. The event organizer will make a final decision regarding the event's status no later than three (3) weeks before the scheduled event date.
1. The event organizer reserves the right to cancel the event if the minimum ticket sales requirement is not met.
## Refund and Ticket Transfer Policy - General Terms
### 1. Refund Terms and Schedule
We understand that plans can change. Our refund policy for event cancellations is as follows:
1. Full Refund (100%): Available for cancellations submitted no later than 1 day before the event.
1. No Refund (0%): No refund will be provided for cancellations made on the day of the event.
### 2. How to Request a Refund
To request a refund, please contact our team at [events@ververica.com](mailto:events@ververica.com) with your invoice or recipe reference number and the date you wish to cancel.
### 3. Additional Terms
1. The cancellation date will be determined by the date we receive your written cancellation request.
1. Refunds will be processed back to the original form of payment within 10 business days.
1. No-shows will not be eligible for a refund.
1. In the event of exceptional circumstances, management reserves the right to review refund requests on a case-by-case basis.
### 4. Ticket Transfer Terms
Please be advised that tickets are non-transferable after purchase. This means:
1. Tickets cannot be transferred to other individuals.
1. The name on the ticket must match the attendee's identification.
1. Tickets are valid only for the original purchaser.
### 5. Rationale For Our Policy
This strict no-transfer policy is in place to:
1. Ensure the security and integrity of our event
1. Prevent unauthorized ticket reselling or scalping
1. Maintain accurate attendee records for communication and safety purposes
1. Comply with our venue and insurance requirements, if any
1. Comply with all applicable local, national, and international laws and regulations, if any
### 6. Identification Requirements
All attendees may be required to present valid photo identification matching the name on the ticket at the time of entry. Individuals without matching identification may be denied entry without refund.
### 7. Special Circumstances
In the rare case of exceptional circumstances, please contact our customer service team at [events@ververica.com](mailto:events@ververica.com) at least 5 business days before the event. Any exception to this policy is at the sole discretion of management and will be evaluated on a case-by-case basis.
### 8. Alternative Options
If you are unable to attend the event:
1. You may be eligible for a refund according to our Refund General Terms
Please refer to our separate Refund General Terms for details on cancellation terms and refund eligibility.
### 9. Refund Policy - Event Cancellation
We will use the information that we collect about you for the following purposes:
1. In the event of cancellation due to insufficient ticket sales:
1. All ticket holders will receive a full refund
1. Refunds will be processed within seventy-two (72) hours of the cancellation announcement
1. Refunds will be issued to the original payment method used for purchase
1. Notification Process:
1. All ticket holders will be notified of the event status no later than three (3) weeks before the scheduled event date
1. Notification will be sent to the email address provided during ticket purchase
1. The notification will include details about the refund process if applicable
### 10. Additional Terms
1. By purchasing a ticket, you agree to these terms and conditions.
1. The event organizer reserves the right to modify these terms with appropriate notice to ticket holders.
### 11. Contact Information
For questions regarding these terms and conditions or the event status, please contact: Ververica at events@ververica.com (edited)
---
---
title: "Customer 360"
description: "Unlock a unified, comprehensive view of your customers. "
lastUpdated: 2026-03-31T10:30:11.000Z
source_url:
html: "https://www.ververica.com/use-case/customer-360"
md: "https://www.ververica.com/use-case/customer-360.md"
---
_No content._
---
---
title: "Banking Hub "
description: "Real-time fraud detection, payments, AML monitoring, and regulatory reporting for banks. Powered by Apache Flink with sub-10ms latency."
lastUpdated: 2026-07-15T07:45:23.000Z
source_url:
html: "https://www.ververica.com/banking"
md: "https://www.ververica.com/banking.md"
---
# Real-Time Stream Processing Built for Banking.
Fraud detection in under 10ms. Instant payments at 6.9B records/sec. Continuous AML monitoring, risk management, and regulatory reporting. All on one platform, built by the creators of Apache Flink.
- **<10ms — Sub-10ms latency**
- **6.9B — records/sec**
- **DORA — DORA Compliant**
## Trusted in Production
## Batch Processing
Is a Liability
In Modern Banking
The Problem
### Fraud settles before jobs finish.
AML alerts arrive 24 hours late. Regulatory reports
miss the deadline. Customers receive yesterday's offers.
### The financial cost.
Billions in undetected fraud, millions in
compliance fines, irreversible customer attrition.
### Built for a slower world.
Batch was built for a slower world. Banking moved on. Your infrastructure did not.
## Banking Solutions
### Fraud Detection
Score 2B+ transactions per day. Block fraud in under 150ms.
### Real-Time Payments
Instant settlement. Exactly-once processing. Peak-hour resilience.
### AML Monitoring
Continuous monitoring. 60% fewer false positives. Adaptive thresholds.
### Risk Management
Real-time VaR. Counterparty exposure. Continuous stress testing.
### Regulatory Reporting
T+0 reporting. Automated validation. Immutable audit trail.
### Core Modernization
Strangler fig migration. Zero downtime. Dual-run validation.
### Customer Personalization
Act on customer behavior as it occurs. Serve the right offer in under 50ms.
### Mainframe Offloading
Cut MIPS costs by 40% or more without replacing the mainframe.
### Fintech Monitoring
Real-time portfolio risk. Instant wealth management signals.
## Why Banks Run On Ververica
### Sub-10ms Latency
Fraud, payments, and risk decisions execute in under 10 milliseconds. Not aspirational. Measured in production across tier-1 banks.
### 6.9B Records/Sec Throughput
The VERA engine processes 6.9 billion records per second. Peak volumes during market events and payment surges do not degrade performance.
### 2x Faster Than Open-Source Flink
VERA engine delivers double the throughput of standard Apache Flink at 52% lower resource consumption. Built by the team that created Flink.
### 40% Lower TCO
Measured total cost of ownership reduction versus legacy stream processing stacks. Fewer clusters. Less operational overhead. Same workloads.
### Exactly-Once Processing
Financial transactions demand zero data loss and zero duplicates. Ververica guarantees exactly-once semantics at scale. No exceptions.
### Multi-Cloud Deployment
Deploy on AWS, Azure, GCP, or on-premises. BYOC mode keeps all data in your environment. Engineered in Europe. Sovereign by design.
_CUSTOMER STORY_
### ING BANK
ING Bank deployed Ververica to process financial events in real time across its global operations. The result: fraud detection that acts before transactions settle, not after.
**Result:** Fraud detection that acts before transactions settle, not after. 2B+ events per day. Fraud detection across 40 countries. Sub-second decision latency.
- **2B+**: Events scored per day
- **>1MS**: Sub-second decision latency
## Frequently Asked Questions
### What is real-time stream processing for banking?
Real-time stream processing analyzes financial data the instant it arrives, without waiting for batch windows. Banks use it for fraud detection, payment processing, AML monitoring, and regulatory reporting. Ververica processes 6.9B records/sec with sub-10ms latency on the VERA engine.
### How does Ververica differ from open-source Apache Flink?
Ververica was founded by the creators of Apache Flink. The VERA engine delivers 2x the throughput at 52% lower resource consumption. Ververica adds enterprise security, multi-tenancy, automated operations, and 24/7 support. It is Flink, built for production banking workloads.
### Can Ververica meet DORA regulatory requirements?
Yes. Ververica supports DORA compliance through ICT risk management capabilities, continuous monitoring, incident detection, and operational resilience testing. SOC 2 Type II, ISO 27001, and GDPR compliance are built in. Deployment options include BYOC for full data sovereignty.
### What deployment options are available for banks?
Banks can deploy Ververica Cloud (fully managed), BYOC (your cloud, our platform), or self-managed (your infrastructure). BYOC is the most common choice for regulated institutions. All data remains in your environment. No vendor access to production data.
### How long does implementation take for banking use cases?
Typical banking deployments reach production in 8 to 12 weeks. Fraud detection and real-time payments are the most common first use cases. Ververica provides pre-built connectors for Kafka, mainframe CDC, and core banking systems. Professional services teams specialize in financial services.
### Does Ververica support exactly-once processing for financial transactions?
Ververica guarantees exactly-once processing semantics. Every financial transaction is processed once and only once, even during failures or restarts. This is non-negotiable for payments, settlements, and regulatory reporting. The guarantee holds at full throughput.
---
---
title: "Preview Program"
description: "Explore Ververica's Unified Streaming Data Platform through Private and Public Preview phases, offering early access to features and opportunities."
lastUpdated: 2026-04-21T12:19:16.000Z
source_url:
html: "https://www.ververica.com/previews"
md: "https://www.ververica.com/previews.md"
---
# Ververica's Unified Streaming Data Platform Preview Program
New releases in the Ververica Streaming Data Platform follow a structured rollout process consisting of multiple stages. The Private Preview and Public Preview phases provide customers early access to new features and products, enabling them to explore upcoming capabilities while contributing valuable feedback. This iterative approach helps enhance the quality and reliability of our offerings before they reach full production readiness.
## Private Preview
During the Private Preview phase, new products and features are made available only to a select group of users by invitation.
## Public Preview
During the Public Preview phase, new products and features are accessible to all users for testing and feedback.
These offerings are primarily intended for non-production environments, though customers may run production-like workloads to evaluate performance under real-world conditions.
If you’re interested in accessing Public Preview offerings, please contact our [sales team](https://www.ververica.com/contact).
## General Availability
Once a feature or product is fully refined and deemed stable for production environments, it reaches General Availability status. The duration of the Private Preview and Public Preview phases depends on user adoption and the resolution of issues identified during testing.
## Pricing for Preview Offerings
During the Preview phase, Ververica provides free access to preview offerings. The specific access methods and requirements will be determined by Ververica’s guidelines in effect at the time.
## Preview Offering Terms
By using Private Preview and Public Preview features, you agree that Ververica may contact you for feedback to help improve the product.
Preview offerings are provided for testing and evaluation purposes. While we continuously refine them based on user input, they may have functionality limitations, and their progression to General Availability is not guaranteed. Based on evaluation results and customer adoption, certain features may be modified, delayed, or discontinued.
Preview offerings are exclusively available to subscribed customers and are not covered by the [Ververica Service Level Agreement](https://www.ververica.com/deployment/managed-services/service-level-agreement). For complete details on the terms governing preview offerings, availability, and usage, please refer to the [Ververica Preview Policy](https://www.ververica.com/preview-policy), [Ververica Terms of Service](https://www.ververica.com/terms-of-service), and other relevant policies (if applicable).
---
---
title: "Conferences"
description: "Find Ververica at industry conferences worldwide. Meet the Apache Flink creators, see live demos, and attend our sessions."
lastUpdated: 2026-05-26T09:51:39.000Z
source_url:
html: "https://www.ververica.com/events/conferences"
md: "https://www.ververica.com/events/conferences.md"
---
# Meet Ververica at Industry Conferences
The team that created Apache Flink. At the booth, on the stage, in the hallway track. Live demos. Architecture discussions. Direct access.
## What We Bring
Why Ververica
VERA engine processing 6.9 billion records per second. Streamhouse architecture in action. Flink SQL on live streams. Not slides. Running systems.
Bring your architecture diagram. Sit down with a Ververica engineer. Get direct feedback on your streaming data design. 30-minute sessions at the booth.
Talk with with Apache Flink Committers and Original creators. Ask about roadmap, internals, or your specific production challenge.
---
---
title: "What is VERA?"
description: "Explore VERA, a high-performance engine optimizing Apache Flink for seamless real-time and batch processing."
lastUpdated: 2026-04-29T13:18:33.000Z
source_url:
html: "https://www.ververica.com/ecosystem-introduction/what-is-vera"
md: "https://www.ververica.com/ecosystem-introduction/what-is-vera.md"
---
# What is VERA?
Discover VERA, Ververica's high-performance engine that optimizes Apache Flink for seamless real-time and batch data processing
> **INFO:** VERA (Ververica Runtime Assembly) is Ververica's cloud-native, ultra-high-performance engine that powers Ververica's Unified Streaming Data Platform. The VERA engine optimizes Apache Flink® and is designed to simplify complex stream processing, making real-time data accessible and actionable for a wider audience. VERA enhances Flink's performance, improves user experience, and addresses key pain points like latency and operational complexity in data stream processing, especially within event-driven architecture contexts. With VERA, you can connect, process, analyze, and govern your data in one ultra-high performance streaming data solution. Created to solve both batch and real-time streaming use cases, VERA makes it easy for you to harness insights from your data at any volume and scale.
Businesses constantly seek ways to derive immediate insights from their ever-growing streams of data. While traditional batch processing is able to solve some use cases, the demand for real-time decision-making is paving the way for advanced stream processing technologies. At the forefront of this evolution is VERA (Ververica Runtime Assembly), a cloud-native engine that serves as the core of [Ververica's Unified Streaming Data Platform](https://www.ververica.com/product?hsLang=en). VERA revolutionizes Apache Flink, making both powerful real-time stream and batch processing accessible to a broader audience, extending beyond specialized technical experts.
## The Genesis of VERA: Addressing Stream Processing Challenges
For over a decade, Apache Flink has been a leading solution for stream processing. However, as data scales exponentially and systems become increasingly distributed, the complexities associated with managing and operationalizing open-source Flink have grown. Many organizations lack the internal resources and specialized expertise required to build and maintain the intricate supporting architectures for complex real-time solutions.
Ververica recognizes these critical pain points. While Flink is the de-facto gold standard streaming project, all projects have limitations. VERA was created to address challenges including Flink's historical single-tenant design, high operational complexity and costs, the "black box" behavior described by developers, and to address an architecture that has not fully evolved to support modern workloads and cloud environments. VERA democratizes stream processing, maintaining 100% compatibility with Flink while solving these known open source limitations.
## VERA's Core Purpose and Functionality
VERA’s primary purpose is to simplify the complexities of data stream processing, enabling businesses to operationalize streaming data with ease. It allows users to seamlessly connect, process, analyze, and govern their data within a single, high-performance streaming data solution. VERA optimizes Apache Flink, enhancing its performance and significantly improving the overall user experience.
The capabilities of VERA are built upon three fundamental pillars, designed to provide a unified and efficient approach to real-time data management:
- **Streaming Data Movement:** This pillar tackles the challenge of disparate data sources (like relational databases such as Postgres or MySQL) that hold critical business information. VERA utilizes Flink Change Data Capture (CDC) to absorb diverse streaming data and events, transforming them into a uniform, actionable format. This process involves loading and transforming data, real-time processing to make it actionable, and delivering the processed data to various destination systems while maintaining data lineage and security. This ensures easy access, formatting, processing, and storage of data, supporting future decision-making, a unified real-time data view, and application development with support for Java, Python, or SQL.
- **Real-Time Stream Processing:** At its heart, VERA focuses on extracting immediate meaning and insights by processing data in real time, eliminating the historical lag inherent in batch processing. VERA’s architecture decouples storage and compute layers, enabling it to deliver both stream processing and batch processing for stateful computations over data streams. It efficiently manages Flink application execution and integrates seamlessly with Flink APIs, empowering developers to process and analyze vast amounts of data and extract real-time insights. This unified approach facilitates fast, reliable decisions based on the freshest available information, as data can be acted upon immediately upon arrival, regardless of its format.
- [**Streamhouse**](https://www.ververica.com/what-is-streamhouse?hsLang=en) **(Streaming Lakehouse)**: This innovative pillar combines Apache Flink for stream processing with [Apache Paimon™](https://www.ververica.com/what-is-apache-paimon?hsLang=en) on the streaming storage layer. Streamhouse provides a storage solution that merges the benefits of real-time streaming with the cost-effectiveness and query capabilities of traditional Lakehouse batch processing. It allows users to leverage nearly unlimited storage within their stream processing framework, query petabytes (or even exabytes) of data cost-effectively, and perform both real-time and near real-time stream processing from a single engine. This empowers informed decision-making by leveraging both current and historical data.
## Key Features and Advantages of VERA
VERA offers a multitude of features and advantages that position it as a leading stream processing framework:
- **Ultra-High Performance:** VERA is engineered for exceptional speed, capable of processing billions of events per second with sub-second latency. It demonstrates performance **up to 2x faster than self-managed open-source Flink**.
- **Infinite Scalability and Elasticity:** With its architecture that separates compute and storage layers, VERA reduces costs and significantly enhances performance, enabling it to scale infinitely to meet demand.
- **High Availability and Robust Fault Tolerance**: VERA boasts a 99.99% uptime SLA. Its advanced fault-tolerant features, including tiered state and faster checkpoints, ensure uninterrupted operation even in the face of failures, simplifying complexities often found in large stateful applications.
- **Cloud-Native Design:** VERA is built to run natively in modern cloud environments, leveraging the benefits of cloud infrastructure for resilience and scalability.
- **100% Apache Flink Compatibility:** VERA maintains full compatibility with Apache Flink, preventing vendor lock-in and allowing existing Flink users to easily transition and benefit from VERA's optimizations. This commitment ensures a seamless evolution of Flink for modern workloads.
- **Simplified Operations and Reduced Cost:** By abstracting away much of the operational complexity associated with open-source Flink, VERA reduces the need for extensive internal resources and expertise, lowering operational costs and increasing ROI.
- **Developer-Friendly Experience:** VERA aims to provide a more intuitive and streamlined experience for developers, allowing them to focus more on business outcomes rather than infrastructure management.
- **Unified Batch and Stream Processing:** VERA supports continuous processing for both batch and real-time pipelines, allowing for instant access to data and extraction of insights as soon as data becomes available. This addresses the increasing need for converged architectures that handle both historical and real-time data within a single system.
- **Security and Data Governance:** VERA prioritizes security, streamlines data access management, and supports multi-tenancy and robust data governance policies.
### VERA and Event-Driven Architecture
VERA is inherently aligned with an event-driven architecture. In an event-driven system, real-time events drive business processes and decisions. VERA's ability to ingest, process, and analyze data streams in real-time makes it an ideal engine for building responsive and scalable event-driven applications. It transforms raw events into uniform datasets, enabling immediate action and informed decisions as soon as data arrives. This is crucial for modern applications that demand immediate reactions to changes in data, such as fraud detection, personalized recommendations, and real-time analytics dashboards.
## The Future of Stream Processing with VERA
VERA democratizes stream processing by simplifying its inherent complexities. The goal is to enable users to effortlessly access both fresh and historical data, facilitating well-informed business decisions. VERA is designed to seamlessly handle both batch and real-time streaming data use cases.
In the near future, users will experience a streamlined process: simply select their deployment method (on-premise or cloud), choose their data sources, fine-tune the solution, and immediately begin to see results, regardless of the specific use case. This innovative approach is also poised to significantly reduce operational costs and enhance ROI, as VERA provides a managed solution that handles updates, feature innovations, and continuous monitoring, effectively eliminating the need for burdensome self-management.
## Conclusion
VERA represents a significant leap forward in the realm of data stream processing. By optimizing Apache Flink and delivering a cloud-native, high-performance engine, Ververica has created a solution that addresses the critical needs of modern enterprises. Whether it’s for stream processing with Apache Flink, building an event-driven architecture, or achieving a unified view of real-time and historical data through Streamhouse, VERA empowers organizations to unlock the full potential of their streaming data, enabling faster insights and more agile business operations.
## FAQ
### What is VERA in the context of stream processing?
VERA (Ververica Runtime Assembly) is a cloud-native, ultra-high-performance engine that optimizes Apache Flink for unified streaming and batch data processing on the Ververica platform.
### How does VERA improve performance compared to open source Apache Flink?
VERA enhances Flink’s speed, provides sub-second latency, and offers up to 2x better performance and scalability by decoupling compute and storage and introducing advanced state management features.
### Is VERA fully compatible with Apache Flink APIs and jobs?
Yes, VERA guarantees 100% compatibility with Apache Flink, enabling seamless migration without vendor lock-in or code rewrites.
### What are the main advantages of using VERA?
Key benefits include ultra-fast processing, infinite scalability, high availability (99.99% SLA), simplified operations, strong security and governance, and unified support for both real-time and batch pipelines.
### How does VERA support event-driven architectures?
VERA enables real-time ingestion, processing, and analysis of data streams, making it ideal for event-driven applications like real-time analytics, fraud detection, and personalized recommendations.
---
---
title: "vs Open Source Flink"
description: ""
lastUpdated: 2026-07-09T10:12:57.000Z
source_url:
html: "https://www.ververica.com/apache-flink-vs-ververica"
md: "https://www.ververica.com/apache-flink-vs-ververica.md"
---
# Apache Flink® / Ververica One-Pager
Download this one-page reference sheet: "Apache Flink vs. Ververica" to learn more about the differences between the open-source project and enterprise-grade solution.
In today’s data-driven landscape, managing and processing large-scale streaming data is essential to staying competitive. While Apache Flink offers a powerful platform for real-time stream processing, its complexities can be a barrier, often requiring deep technical expertise and significant resources.
That's where Ververica can help.
While 100% compatible with and built on Apache Flink, Ververica offers additional features, benefits, and capabilities that remove the operational overhead and complexity associated with data streaming. In addition to being the original creators of Apache Flink, in this one-page reference guide, you will find:
- A chart of open source vs. enterprise capabilities
- 4 key takeaways to consider for any data streaming project
- Notable differentiations between Flink and Ververica
- ...and more!
---
---
title: "Streaming Sovereignty Self Assessment Checklist"
description: ""
lastUpdated: 2026-07-09T11:23:36.000Z
source_url:
html: "https://www.ververica.com/data-sovereignty/streaming-sovereignty-self-assessment-checklist-for-financial-industry"
md: "https://www.ververica.com/data-sovereignty/streaming-sovereignty-self-assessment-checklist-for-financial-industry.md"
---
# Streaming Sovereignty Self Assessment Checklist for Financial Services Industry
## Executive Summary
This self-assessment checklist helps FSI organizations identify gaps between regulatory requirements (DORA, NIS2, GDPR, AI Act) and current platform capabilities across five critical areas.
---
---
title: "Terms of Service"
description: "Ververica Terms of Service outlining user obligations and access. Register an Account for stateful stream processing and analytics with Apache Flink."
lastUpdated: 2026-04-21T12:17:32.000Z
source_url:
html: "https://www.ververica.com/terms-of-service"
md: "https://www.ververica.com/terms-of-service.md"
---
# Terms of Service
**Last update: August 14th 2025**
Welcome to Ververica!
The Websites [https://www.ververica.com](https://www.ververica.com) and [https://www.ververica.cloud](https://www.ververica.cloud) (“**Websites**”) are owned and operated by Ververica GmbH, a limited liability company incorporated in Germany (“**Ververica**”). Through the Websites, Ververica provides Ververica Platform and Ververica Cloud Services, among others (collectively, “**Platform and Services**”). These Terms of Service (“**Terms**”) are a legally binding agreement between you as a registered user of the Platform and Services (“**you**”, “**your**” and “**User**”) and Ververica as the provider of the Platform and Services (“**we**”, “**us**”, “**our**” and “**Ververica**”; the User and Ververica together the “**Parties**” and each a “**Party**”).
The Terms apply to the use of the Platform and Services. This includes mobile and tablet versions, as well as any other version of the Platform and Services accessible via desktop, mobile, tablet, social media or other devices.
## 1. USER ACCOUNT AND ACCEPTANCE OF TERMS
1. These Terms govern your access and use of your user account **(“Account”)** with Ververica for the Websites and the Platform and Services. By registering the Account and/or using any of the Platform and Services, you agree to be bound by these Terms. If you do not agree to any and all clauses of these Terms, you must not continue with the account registration process and must not use any part of the Platform and Services. The Parties agree that the general obligations in electronic commerce in Section 312i para. 1 sentence 1 no. 1-3 of the German Civil Code (Bürgerliches Gesetzbuch) shall not apply.
1. You represent and warrant that you are an entrepreneur within the meaning of Section 14 of the German Civil Code, i.e. a natural or legal person or a partnership with legal capacity who, at the time of entering into these Terms, is acting in the exercise of its commercial or independent professional activities.
1. Children under the age of 13 are prohibited from using the Platform and Services, therefore shall not register an Account with us. For those users under the age of 18 (or any higher age if the age of majority is higher than 18 pursuant to the laws applicable to the User) and over the age of 13, it is the responsibility of parents and/or legal guardians of the User to determine whether use of the Platform and Services is appropriate for such User.
1. If you are using the Platform and Services on behalf of your employer or another entity, you hereby represent and warrant that you have full legal authority to bind your employer or such entity to these Terms. Accordingly, all references in these Terms to “you”, “your” or “User” shall be deemed to include your employer or such entity, except where the context may otherwise require. If you do not have such authority, then you may not use the Platform and Services on behalf of your employer or such entity and you must discontinue all use of the Platform and Service immediately.
1. You represent and warrant that all registration information you submit is accurate and truthful and that your use of the Platform and Services does not violate any applicable law or regulation. Ververica may, in its sole discretion, refuse to offer the Platform and Services in its entirety or any part thereof to any user and change its eligibility criteria at any time. This provision is void where prohibited by law and the right to access the Platform and Services is revoked in such jurisdictions.
1. By using any part of the Platform and Services, you represent and warrant that you have full right, power and authority to enter into these Terms and to fully perform all of your obligations hereunder. You further represent and warrant that you have no legal incapacity or contractual restriction that would prevent you from entering into these Terms.
1. We may in our sole discretion refuse to register your Account. Without prejudice to the generality of the foregoing, we may refuse to do so when your Account was previously terminated due to a breach of these Terms or when we reasonably consider you likely to breach any of the representations and warranties contained in these Terms.
1. By registering an Account, you are responsible for maintaining the confidentiality of your password and other Account information and you are fully responsible for all activities that occur under your Account. You agree to
1. immediately notify Ververica of any unauthorized use of your password or Account or any other breach of security and
1. ensure that you log out of your Account at the end of each session.
You may never use another user’s Account without Ververica’s prior authorization. Ververica is not liable for any loss or damage arising from your failure to comply with these Terms.
## 2. VERVERICA PLATFORM
1. Ververica Platform is an integrated platform for stateful stream processing and streaming analytics with the open-source Apache Flink. It enables organizations of any size to derive immediate insight from their data and serve internal and external stakeholders.
1. Ververica offers the Ververica Platform through [www.ververica.com](https://www.ververica.com/?hsLang=en) (**“Ververica Platform Website”**) as a Community Edition and a Stream Edition.
1. Use of the Community Edition is free of charge (any free-of-charge product or service in the Platform and Services, including but not limited to the Preview (as described below), is referred to as **“Free Version”**) but may still require you to acquire or apply for a free-of-charge license, as further set forth under the corresponding license agreements, subject to the terms and conditions (including but not limited to restrictions on the use or purpose of use of such Free Version) of such license agreements. The User can request a free trial of the Stream Edition of the Ververica Platform through the Ververica Platform Website or through our contact forms (insofar also a Free Version), before purchasing the Stream Edition.
## 3. VERVERICA CLOUD SERVICES
1. Ververica offers cloud services as further described on and provided through [www.ververica.cloud](https://www.ververica.com/deployment/managed-service?hsLang=en) (“**Ververica Cloud Website**”), pursuant to these Terms, our [Privacy Policy](https://www.ververica.com/privacy-policy?hsLang=en), purchase orders (if any), and the [Ververica Cloud Service Level Agreementand](https://www.ververica.com/deployment/managed-services/service-level-agreement?hsLang=en) [Support and Maintenance Services Terms](https://www.ververica.com/deployment/managed-service/support/terms?hsLang=en) which are incorporated by reference herein and legally binding upon you and us.
1. The Ververica Cloud Service means the services described below:
1. **Ververica Cloud Managed Service (“Managed Service”)**. Managed Service is a fully managed cloud service providing Ververica Cloud workspaces as a service, that fully and dynamically manages workspaces and all of its underlying cloud resources, deployed through Supported Cloud Provider Services, available in multiple cloud regions.
1. **Ververica Cloud Bring Your Own Cloud (“BYOC”)**. BYOC consits of BYOC Control Plane and BYOC Data Plane. BYOC Control Plane is fully managed service running in Ververica’s Cloud Account. BYOC Data Plane are Ververica Cloud workspaces running in User’s Cloud Account on Supported Cloud Provider Services.
Any access to and/or use of the Managed Service or BYOC through application programming interfaces (APIs) and/or command-line interface (CLI) tools shall be deemed equivalent to direct access to and/or use of Managed Service or BYOC and shall be governed by the corresponding terms of this Agreement.
1. Registration and access: To access the Ververica Cloud Services, the User must register and setup an Account through the Ververica Cloud Website on the cloud services portal. User must keep the registration information accurate and complete throughout the use of the Platform and Services. User is responsible for the security of User Account credentials including without limitation user name and passwords, and is responsible for all activities that occur under or using such credentials. In case of unauthorized Account use, User shall immediately contact Ververica support.
1. Subject to the requirements of Section 14, Ververica has the right to introduce or remove features, functionalities, applications or conditions to the existing or future versions of the Ververica Cloud Services. All new features, functionalities, applications, conditions, modifications, upgrades and alterations shall be governed by these Terms as well.
1. Ververica Cloud Managed Services may be offered in either or both types of services in terms of pricing and billing methods: Pay-As-You-Go and Reserved Capacity. For compute resources, Pay-As-You-Go is available and means that services are billed based on User’s actual usage of resources (“**Pay-As-You-Go**”), while Reserved Capacity may also be available which means that services are provided as a fixed allocation of resources, billed for all resources allocated (“**Reserved Capacity**”). For networking resources, services are billed based on User’s actual usage of resources for all offering types.
1. Pay-As-You-Go services allow User to access Ververica Cloud Services based on a usage-based pricing model. The provisioning of resources is done on demand, and success of provisioning is subject to availability and thus is not guaranteed. User will be charged according to the resources consumed, such as compute and networking resources. Billing and payment shall be made in line with the provisioning of these Terms.
Our Reserved Capacity services provide User with a specific amount of compute resources reserved exclusively for the User, for which User shall pay the price regardless whether User uses all of such amount of resources. BYOC currently only supports Pay-As-You-Go billing method. However, Ververica reserves the right, in its sole discretion and with reasonable prior notice, to add or modify BYOC billing models in the future.
1. Usage Limits and Resources Allocation for Managed Service
1. When you choose the Managed Service, both Pay-As-You-Go and Reserved Capacity services are subject to usage limits described in our documentation, available on the Ververica Cloud Website.
1. Exceeding these limits may results in service limitations without prior alert. It’s Users responsibility to monitor usage to stay within allocated limits.
1. Free Trial for Managed Service:
If you choose the Managed Service, you will be able to access a free trial of the cloud services before purchasing the services (insofar also a “Free Trial”). However, if you choose the BYOC, this Clause will not apply to you.
1. Free Trial: Our Pay-As-You-Go services free trial allows User without providing a payment method for a thirty-day (30) trial period (to use Managed Service, the “**Free Trial Period**”). User is eligible for a free trial upon registration of the Account, which starts immediately after User finishes the registration process. If User has not provided us with a valid payment method during the Free Trial Period, the free trial services will be suspended for a period of seven (7) days (the “**Period of Suspension**”) after the free trial period ends. Once the User account is suspended, User’s workspaces will no longer be accessible, and all User’s deployments and/or session clusters will be terminated; however, User’s data and metadata will remain intact. After the Period of Suspension ends, if User still have not provided us with any valid payment method, Ververica shall have the right, in its sole and absolute discretion, to delete all data in User’s account. User hereby agrees and acknowledges that such data deletion may be irreversible and shall occur at User’s sole risk.
1. Free Credit: As part of the free trial, User is eligible to receive a specific amount of free credit that User can use to explore Managed Service. The free credit amount will be clearly stated during ordering process for Managed Service. Free credit amount expiration is independent from free trial period expiration. Free credit amount expires at the end of the month following the month in which User’s free trial period starts.
1. We reserve rights to suspend offering free trials and credit for newly registered Users without further notice. In such a case, payment method will be required after registration of the Account in order for User to be able to use Managed Service.
1. Billing terms:
1. Billing applies at the user account level. Unless otherwise provided to the contrary, User is billed by hours for all the services used, and is charged at the end of current billing period.
1. Billing accrues hourly, with a monthly-in-arrears invoicing cycle.
1. Billing period for a certain service starts upon the commencement of such service to User, or immediately after the end of previous billing period, as the case may be. Billing period ends at the end of month as part of regular billing cycle (UTC time).
1. Billing Information: User is responsible for providing accurate billing information, including name, last name, address, credit card number (if applicable), and expiration date, tax id (if required for registration in the applicable territory). Inaccurate or incomplete information may lead to delays in processing your invoice or payment, or lead to suspension or cancelation of your service or Account.
1. Invoices for services provided will be issued on a regular monthly billing cycle.
1. Ververica reserves the right to end current User billing period and issue an invoice before regular monthly billing cycle, if assessed to be reasonably necessary by Ververica.
1. After an invoice is issued, it is due and payable, and User is immediately charged. User must ensure sufficient funds or credit in the provided payment method to allow the payment of the invoice.
1. Rounding policy and methods:
1. In case of Pay-as-you-go services, our billing system applies rounding of quantity of compute and networking services used units to be billed for all Pay-as-you-go services under User’s Account per billing period. The method our billing system uses for usage quantity to be billed is rounding up to the next whole integer value.
1. In case of Reserved Capacity services, out billing system applies rounding of quantity of networking services used units to be billed for all Reserved Capacity services under User’s Account. The method our billing system uses for usage quantity to be billed is rounding up to the next whole integer value.
1. All invoices are stated in currency specified in the invoice. User is responsible for any applicable taxes, including sales tax, value-added tax (VAT), or other similar taxes and levies as required by law. Taxes will be added to your invoice if applicable.
1. Ververica does not store any of the User's payment details. They are stored on the payment processing platform acceptable to Ververica and provided by the third-party payment processors, such as Stripe (collectively, the "**Payment Processors**"). User Payment details are removed from such payment processing platform after User Account is closed.
1. After account closure Ververica may need to keep certain information an additional period of time for legal and legitimate business purposes such as
1. User’s contact information (e.g. name, email address, billing address) and invoices, payment receipts, applicable discounts and tax informaition that Ververica issued to the User for tax and accounting purposes
1. If applicable, Ververica may also retain records of communication with User as well as other records (e.g. record of User account closure) for purpose of dispute resolution.
1. Ververica keeps User’s billing records for purpose of resolving potential billing disputes.
1. According to the German Fiscal Code, Ververica needs to keep issued invoices in the payment process platform provided by the Payment Processors for a duration of 10 years.
1. Foreign Currency Terms of Service
1. The Payment Processor may not provide currency conversion services, in which case the exchange rates and related fees are determined by the respective User's financial institution.
1. Users are responsible for verifying and understanding the currency exchange rates, fees and any additional costs associated with international transactions.
1. In case of payment discrepancies due to currency conversion, users should contact their financial institutions for resolution. We are not liable for any discrepancies, losses or fees incurred during currency conversion or international transactions.
1. If a User subscribes to the Platform and Services through a third-party marketplace (such as AWS Marketplace, Microsoft Azure Marketplace, collectively the "**Third-Party Marketplace**") , the billing policies of that Third-Party Marketplace will apply. Clauses (h)-(i) above do not apply to such User.
1. Pricing and Rate Changes: To the extent permitted by law, we reserve the right to change our pricing and rates for the Ververica Cloud Services. Any such changes will be communicated to User in advance by at least 30 days’ public announcement on the Ververica Cloud Website and/or email notice, and the new rates will apply to billing periods subsequent to the current billing period, unless otherwise indicated in such announcement and notice. You may elect to accept such changes of price and rates by continue to user such services after the effective date of such changes, or to reject and cease to use such services before the effective date of such changes.
1. Subscription Transition, Account Status, and Termination for BYOC Service:
1. Grant of Grace Period : Upon the expiration of your BYOC subscription, Ververica will grant your account a grace period of thirty (30) days (the “**Grace Period**”). During the Grace Period, User’s account will remain fully functional.
1. Account Suspension : If User fails to renew User’s subscription prior to the expiration of the Grace Period, User account will be suspended upon the conclusion of the Grace Period. Once User’s account is suspended, User’s workspaces will no longer be accessible, and all User’s deployments and/or session clusters will be terminated; however, User’s data and metadata will remain intact.
1. Suspension Period and Data Deletion : If User fail to renew User’s subscription within thirty (30) days from the date User account was suspended (the “**Suspension Period**”), Ververica shall have the right, in its sole and absolute discretion, to delete all data in User’s account. User hereby agree and acknowledge that such data deletion may be irreversible and shall occur at your sole risk.
1. Fees for Grace Period Usage : Unless otherwise agreed, the Grace Period is not free of charge. If User renews User’s subscription during or after the Grace Period, User will be required to pay applicable fees corresponding to the actual number of days utilized during the Grace Period as well as any usage of the Ververica Cloud Service during such period.
1. Ververica reserves the right to modify and/or terminate the Grace Period and/or Suspension Period in its sole discretion.
1. Preview: Ververica may, from time to time, offer the preview release version of Ververica Unified Streaming Data Platform which has not yet reached general availability ("**Preview**"). For details on the rules and requirements governing Preview offerings, please refer to the [Ververica Preview Policy](https://www.ververica.com/preview-policy?hsLang=en).
## 4. PROHIBITED ACTIVITIES
1. You agree not to use the Platform and Services in a negligent, fraudulent or unlawful manner. You also agree not to engage in any conduct or action that damages the image, interests or rights of Ververica. In addition, the following activities are prohibited, unless with our written permission or such restrictions are prohibited by law, in particular the German Copyright Act (Urheberrechtsgesetz) such as the right to interoperability or to create a backup copy:
1. Use the Platform and Services for any commercial purposes outside the scope of the purposes explicitly permitted in these Terms and related guidelines (if any) made available by Ververica.
1. Access, monitor, reproduce, distribute, transmit, broadcast, stream, display, sell, license, copy or otherwise exploit any content of the Platform and Services, including, but not limited to, the use of any robot, spider, scraper or other automated means or any manual process for any purpose not in accordance with these Terms or without our express written permission.
1. Violate the restrictions of any robot exclusion headers on the Websites and Platform and Services, or circumvent other measures employed to prevent or limit access to the Platform and Services.
1. Take any action that imposes, or may impose, in our reasonable discretion, an unreasonable or disproportionately large load on our infrastructure.
1. Establish a deep link to any part of the Websites for any purpose without our express written permission.
1. Attempt to modify, translate, adapt, edit, decompile, disassemble or reverse engineer any software program used by us.
1. Circumvent, disable or otherwise interfere with security-related features of the Websites or features that prevent or restrict the use or copying of any content.
1. Free Versions shall not be used for commercial purposes (including the use for performance to your customers) but may only be used for personal educational purpose. This is further set forth in details under the corresponding license agreements/policy of such Free Versions.
1. Ververica is entitled to delete content provided by the User in connection with the Platform and Services or by third parties who the User allows to use the Platform and Services and/or to disable access to such content if and to the extent that, based on Ververica’s reasonable judgement, the content does not meet the requirements of these Terms.
1. In addition, Ververica is entitled to completely or partially disable the User’s access and/or that of third parties who the User allows to use the Platform and Services to the Platform and Services and/or to suspend the provision of the Platform and Services under these Terms if the User does not fulfill its payment obligations as specified in these Terms in part or in full or materially breaches other obligations under these Terms, or it is necessary to disable the access due to legal requirements.
## 5. USER’S RESPONSIBILITIES
1. Without restriction of Ververica’s obligation to provide the Platform and Services, by using the Platform and Services you accept personal responsibility for the results of your use of the Platform and Services and for any actions taken through the Platform and Services. Ververica does not guarantee any outcome, benefit or failure as a result of your use of the Platform and Services. You acknowledge and agree that your ultimate success or failure to use the Platform and Services will be the result of your own actions, your particular situation and other circumstances beyond Ververica’s control. Without restriction of Ververica’s obligation to provide the Platform and Services, by visiting the Websites and accessing the content available on the Websites you accept personal responsibility for the results of the use of the information and content available on the Websites. Ververica does not guarantee the results of actions advised or not advised by these Websites and the content available on the Websites. Ververica provides resources and content for informational purposes only. You acknowledge and agree that your ultimate success or failure in using the information and content available on the Websites will be the result of your own efforts, your particular situation and a number of other circumstances that are beyond Ververica’s control.
1. You are responsible towards Ververica for all actions and omissions by employees and third parties acting on your behalf, as well as for third parties who you allow to use the Platform and Services to the same extent as for your own actions or omissions. In particular, you are fully responsible for ensuring that third parties who you allow to use the Platform and Services, such as your affiliates pursuant to Section 15 et seq. of the German Stock Corporation Act (Aktiengesetz), comply in full with these Terms. You must obtain a specific agreement from Ververica to enable third parties, including affiliates, to use the Platform and Services. Furthermore, you warrant that all persons you allow to use the Platform and Services have rights of representation in relation to you, including the right to make legally relevant declarations within the context of the rights of access and use granted to them.
1. When using the Platform and Services, you warrant that you will comply with all applicable laws, including product liability, product safety, e-commerce, data protection, tax, sanctions laws, export and import control laws, including U.S. and international export and import control laws, as well as the U.S. Children’s Online Privacy Protection Act. Ververica shall not be liable for the exportability of the Platform and Services or obtaining an approval required for an export to any particular country or for any delays caused by applicable export procedures, unless this is caused by a culpable violation of Ververica’s obligations under these Terms.
1. You acknowledge that the Platform and Services may contain components, technologies and/or services which are subject to the laws or decisions regarding sanctions, export controls, embargoes and/or other trade restriction requirements, of the United Nations or countries in which the Platform and Services are provided. You represent and warrant that you will not use, export or re-export, sell, re-sell, license, distribute, make available or transfer or cause or facilitate the transfer of the Platform and Services, including any component or part thereof, directly or indirectly to
1. any country or destination subject to comprehensive export controls, sanctions or other restrictions, or
1. any individual or entity listed on any applicable sanction lists (including without limitation the U.S. Treasury Department’s list of Specially Designated Nationals, the U.S. Commerce Department’s Denied Persons List, Entity List) or any other parties not eligible to receive them, as such lists may be updated from time to time.
1. You further warrant that you will not use, export or re-export, sell, re-sell, divert or otherwise transfer the Platform and Services, including any component or part thereof, for use in activities that involve any of the following:
1. the development, production, use or stockpiling of nuclear activities of any kind, chemical or biological weapons or missiles, unmanned aerial vehicles, or microprocessors for military use, or any terrorist activities, nor in any facilities that are engaged in activities relating to such weapons or applications;
1. large-scale and systematic surveillance operated by a government;
1. the development and use of government-operated social scoring systems; or
1. instruments for exercising repressive control by a government, especially the systematic discrimination and oppression of ethnic or other minorities.
1. You agree that if Ververica reasonably believes that you are in breach of any of the terms and conditions contained in the above Sections 5(d) and 5(e) that alone shall be sufficient grounds for further action by Ververica, including, without limitation, cancellation of any subscriptions or denial of future sales and services, without any liability or obligation to you. In addition, you hereby indemnify Ververica and its affiliates, directors, officers and employees for all costs, expenses, damages, claims, charges, penalties, fines and other losses that arise in connection with any breach by you of such Sections 5(d) and 5(e).
## 6. INVESTIGATION AND ENFORCEMENT
1. Ververica shall have the right to investigate any potential breach or violation of these Terms and to report any activities that Ververica reasonably considers to be in violation of these Terms or any applicable laws or regulations in any jurisdiction to the relevant enforcement agencies, regulators, government bodies, and any other appropriate third parties
1. Ververica shall have the right to access, disclose and/or remove any content you published on or submitted to Ververica or to the Platform and Services in connection therewith or to comply with applicable law, legal process or lawful government requests, or in respect of any claims or potential claims brought against Ververica, or its shareholders, subsidiaries or affiliates.
### 7. FEES AND PAYMENTS
1. Except in the case of Free Versions, you may be required to pay a fee (“Fee”) for your use of the Platform and Services. Details of any Fee are set forth on the corresponding webpages of the Platform and Services. The Fee shall be paid through the payment processing platform provided by the Payment Processors and acceptable to Ververica at the time of payment, which Ververica reserves the right to change at any time at our sole discretion. You agree to abide by any relevant terms of service and any other legal agreement governing your payment processing via those Payment Processors.
1. In the event that your payment fails for any reason (e.g., due to a declined card), the transaction you submitted will be placed on hold until the issue is successfully resolved. If you have any payment-related questions, you may contact us and we will endeavor to assist.
1. Your payment data will be processed and kept securely and for the sole purpose of processing the purchase of the use of the Platform and Services. Ververica reserves the right to contract any payment platform available on the market which processes your data for the sole purpose of processing the purchase of the use of the Platform and Services. Any personal information contained in the payment data (if any) will be processed in accordance with the Privacy Policy.
1. In the event of late payments, unless otherwise agreed, Ververica reserves the right to suspend User’s access to the Platform and Services until all due payments have been made. Ververica will inform the User well in advance about any suspension. For the avoidance of doubt, the suspension neither interrupts the term nor the User’s further payment obligations.
### 8. INTELLECTUAL PROPERTY AND COPYRIGHT
1. The content and information available on or contained in the Platform and Services (including, but not limited to, data, information, text, music, sound, photos, graphics, videos, maps, icons, illustrations, software or other material) as well as the infrastructure used to provide such content and information are protected by copyrights, trademarks and/or other intellectual property rights owned and controlled by Ververica or by third parties who have licensed or provided their material to the platform. With the exception of the rights explicitly granted under these Terms, both Parties and their third-party suppliers and licensors remain the holders of all rights. All rights to the Platform and Services, also covering all future developments, will in particular remain with Ververica, its third-party suppliers and licensors.
1. When you download, use or purchase any edition of the Platform and Services and we conclude a valid agreement under the Terms, unless otherwise provided to the contrary, Ververica grants you a personal, worldwide, royalty-free, non-assignable, non-exclusive, revocable license to use the Platform and Services that Ververica provides to you for the purposes agreed by the Parties (e.g. in the user account registration process or on the product details page), however only for internal business purposes (including testing) or personal educational purpose in the case of Free Versions. You may not copy, modify, distribute, sell or rent any part of the Platform and Services or the included software, or reverse engineer or attempt to extract the source code of such software, unless with our written permission or such restrictions are prohibited by law, in particular the German Copyright Act such as the right to interoperability or to create a backup copy.
1. You may grant your employees and other third parties acting on your behalf access to your Account. In that case, you shall ensure that such employees and other third parties comply with these Terms and you remain liable for any breaches of these Terms by such employees and other third parties as if they were your own.
1. You grant Ververica a worldwide, perpetual, irrevocable, transferable, sub-licensable, royalty-free license to use any suggestion, recommendation, feature request, or other feedback related to the Platform and Services provided by or on behalf of you and your employees, and to incorporate any of the above into the Platform and Services.
1. Ververica will respond to all enquiries, complaints and claims relating to alleged infringement by breach or violation of the provisions contained in international copyright and intellectual property laws and regulations. Ververica respects the intellectual property of others and expects users to do the same. If you believe, in good faith, that any material provided on the Websites infringes your intellectual property right or copyright, please submit your request via our contact information, with the following information:
1. Identification of the intellectual property right or copyright that is allegedly infringed. All relevant registration numbers or a statement of ownership of the work should be included.
1. A statement that specifically identifies the location of the infringing material in sufficient detail so that Ververica can find it on the website.
1. Your name, address, telephone number and email address.
1. A statement by you that you have a good faith belief that use of the allegedly infringing material is not authorized by the owner, or its agents, or the law.
1. A statement by you, made under penalty of perjury, that the information in your notice is accurate and that you are the owner or authorized to act on the owner’s behalf.
1. An electronic or physical signature of the owner or the person authorized to act on the owner’s behalf.
## 9. INDEMNIFICATION
1. You agree to defend and indemnify Ververica from and against any claims, causes of action, demands, recoveries, losses, damages, fines, penalties or other costs or expenses of any kind or nature, including, but not limited to, reasonable legal and accounting fees, brought by third parties as a result of
1. a breach of these Terms or the documents referenced herein,
1. a violation of any law or the rights of a third party, or
1. use of Platform and Services by you or an affiliate of you within the meaning of Section 15 of the German Stock Corporation Act.
1. This duty of indemnification does not apply if you are not responsible for the occurrence of the relevant claims, damage or costs etc.
### 10. DATA PROTECTION AND INFORMATION SECURITY
1. The Parties will comply with all applicable data protection and privacy laws and regulations. Any personal data you provide in connection with your registration of the Account and your use of the Platform and Services will be used in accordance with our Privacy Policy. To the extent that Ververica is processing personal data provided by you on your behalf when you use the Platform and Services, a Data Processing Addendum will apply to such data processing activities between the Parties.
1. You will inform your end-users (i.e. the “Data Subjects”) in accordance with applicable requirements (such as Articles 13 and 14 GDPR) as only you as the data controller are in direct contact with the Data Subjects. You are responsible and guarantee to obtain and maintain valid consents from all the Data Subjects as may be necessary under applicable law (including data protection, privacy or data processing laws and regulations) to process their personal data in the manner and for the purposes set forth in these Terms.
1. Ververica is committed to ensuring the security, confidentiality, and integrity of its customers’ information. To achieve this goal, Ververica has implemented a range of comprehensive and reasonable information security controls, with which you shall comply to be able to use the Platform and Services. However, you are also responsible for implementing your own information security controls to safeguard your data while using the Platform and Services, including without limitation protecting your access to Ververica Cloud Services. In addition, you are solely responsible for verifying the security of your own code that is uploaded to and executed with Ververica Cloud Services. This verification process should ensure that the code is free from any known vulnerabilities and that it has not performed any malicious actions either inside or outside of Ververica’s infrastructure and environment. This security verification of code is essential to maintain the overall security and integrity of Ververica Cloud Services. Ververica may suspend or terminate Ververica Cloud Services to you in the event that there are reasonable indications that you have failed to ensure the security of your code or your data.
## 11. CONFIDENTIAL INFORMATION
1. “Confidential Information” means information, whether in oral, written or other form that you or Ververica (“**Discloser**”) or, where applicable, your/its respective officers, directors, advisers, employees or agents (collectively, your/its “**Representatives**”) discloses to Ververica or you, respectively (“**Recipient**”) or, where applicable, your/its Representatives, including without limitation: internal policies, business plans, capitalization tables, budgets, and financial statements; costs, prices, and marketing plans; contracts and licenses; employee, customer, supplier, shareholder, partner or investor lists; technology, know-how, business processes, trade secrets and business models; notes, sketches, flow charts, formulas, blueprints, and elements thereof; and source code, object code, graphical design, user interfaces and other intellectual property, including that of any customer, supplier or other third party. Notwithstanding the foregoing, Confidential Information shall not include information that:
1. is or becomes generally available to the public other than as a result of a disclosure or other fault by Recipient or any of its Representatives,
1. was rightfully in Recipient’s possession free of any obligation of confidentiality at or subsequent to the time such portion was communicated pursuant to these Terms, or
1. was developed by Recipient independently of and without reference to any information communicated hereunder. Furthermore, a disclosure by Recipient or its Representatives of Confidential Information of Discloser,
1. in response to a valid order by a court or other governmental or regulatory body,
1. otherwise required by law,
1. or necessary to establish the rights of either Party under these Terms, shall not be considered to be a breach of these Terms by such Recipient;
1. provided, however, that, if legally permitted, Recipient shall provide prompt prior written notice thereof to Discloser to enable Discloser to seek a protective order or otherwise prevent such disclosure; that, in the event that such protective order or other protection is denied and that Recipient is nonetheless legally compelled to disclose such information, Recipient shall limit the extent of such disclosure solely to the extent required by such order or law; and that Recipient shall use its reasonable best efforts to ensure that such disclosed information is treated strictly confidentially by the recipients thereof.
1. The Recipient shall return or irretrievably delete (as reasonably instructed by the Discloser) any and all Confidential Information upon the first to occur of
1. the termination of these Terms or
1. written request by the Discloser.
1. The Recipient shall not be required to delete or erase such copies of Confidential Information that are stored on backup media or backup servers until such time as the backup copies are scheduled to be deleted in accordance with recognized IT security procedures, provided that the Recipient will not use any such retained Confidential Information for other than back-up purposes.
1. Ververica is entitled to publicize the cooperation with the User in a manner customary in the market during the term of the Parties’ agreement and to name the User as a reference. In doing so, Ververica is entitled to use the User’s company/company name/designation and logo for its own advertising measures. This includes reference to the User in a suitable form (for example on Ververica’s website as well as on social media and other marketing materials). Upon request, the User shall make its logo available to Ververica in digital form in a timely manner. The User shall have the same right towards Ververica.
1. These obligations of confidentiality under this section shall survive the termination of the agreement between the Parties by a term of three (3) years.
## 12. LIMITATION OF LIABILITIES
1. Ververica shall be responsible for ensuring that the Platform and Services operate as specified in these Terms. Ververica does not assume any liability for any damages resulting from a usage of the Platform and Services not in accordance with the specifications of these Terms.
1. Ververica will be liable for damages and futile expenses only to the extent such damages or expenses are due to
1. intentional or grossly negligent conduct of Ververica or
1. Ververica’s breach of a material contractual duty.
1. “Material Contractual Duties” or “Cardinal Obligations” are the contractual obligations protecting User’s material interests under these Terms, i.e. obligations that characterize the Platform and Services and on which User may rely. In the event of a just slightly negligent breach of a Material Contractual Duty by Ververica, its legal representatives or vicarious agents, Ververica’s liability shall be limited to the damage or loss which is foreseeable and typical of the contract at the time of conclusion of these Terms.
1. The foregoing limitations shall not affect liability for damages resulting from an injury to life, body, or health. The same applies to claims resulting from warranty breaches and claims under the German Product Liability Act (Produkthaftungsgesetz).
1. Neither Party will be liable for failure or delay in performance of its obligations under these Terms to the extent caused by circumstances beyond its reasonable control, including acts of God, natural disasters, terrorism, riots, or war. Ververica will provide Free Versions “as is” and is not obliged to guarantee specific functions or other requirements of Free Versions, including with regard to availability. Ververica can provide an updated or modified version at any time at its sole discretion, without prior notice and without specifying any reasons. Ververica excludes any warranty or liability for and in connection with use of Free Versions. Ververica’s liability for intent and gross negligence and in the case of fraudulent concealment of defects remains unaffected.
1. All exclusions and limitations of liability set out in this Section 12 also apply to Ververica’s affiliates, members of the executive board, directors, employees, agents, subcontractors, sub-suppliers and other persons assisting Ververica.
## 13. THIRD PARTIES
1. Through your use of the Platform and Services you may encounter links to third party sites or be able to interact with third party sites. These third parties may charge a fee for the use of certain content or services provided on or through their websites. Therefore, you should investigate as you deem necessary or appropriate before proceeding with any transaction with any third party to determine whether a fee will be incurred.
1. Where Ververica provides details of fees or charges for such third-party content or services, such information is provided for convenience and information purposes only. Any interaction with third party sites and applications is at your own risk. Ververica is in no way responsible for such third-party websites.
## 14. CHANGES
1. Ververica may amend these Terms for legitimate reasons, in particular for legal or security reasons. This does not apply to Fees. Ververica will notify the User of any amendment at least thirty (30) days prior to its proposed entry into force.
1. If the User fails to object in text format to an amendment before the proposed effective date, the User will be deemed to have accepted the amendment. Ververica may only introduce amendments that would create new obligations for the User or make its existing obligations more onerous if the User gives its express consent.
1. Ververica may make amendments at shorter notice if
1. Ververica is subject to a legal or regulatory obligation that precludes compliance with the thirty (30) day deadline,
1. Ververica needs to amend the Terms to avert an unforeseen and imminent threat to its business operations, or
1. the amendments are only of editorial nature. In the case of amendments made at short notice, the User will be entitled to terminate these Terms for cause if the amendment is as a whole disadvantageous for the User, i.e. if it changes the relationship between performance and Fees to the User’s disadvantage.
1. In all other cases, amendments will only be effective if agreed between the Parties in text form. This will also apply to any amendment or supplement to the requirement of text form.
## 15. TERMINATION
1. Both Parties may terminate their agreement under these Terms at any time with two (2) weeks’ notice to the end of the month by notifying each other in writing (including by email). Ververica may suspend or terminate all or part of the Free Versions at any time in its sole discretion and offer you the provision of the Platform and Services against the payment of a Fee.
1. Ververica may suspend the provision of the Platform and Services or any parts thereof immediately on written notice to the User where Ververica reasonably suspects that the provision of the Platform and Services or the use of the Platform and Services by the User may result in a violation of any applicable laws, including laws on export or import control.
1. The right to give notice of termination for cause in accordance with Section 314 of the German Civil Code without observing a notice period remains unaffected. The right to claim damages remains unaffected by any notice of termination.
1. Upon termination or expiration of the agreement under these Terms, the User’s Account will be terminated, meaning you will no longer have access to the Platform and Services. Ververica will delete your data within thirty (30) days after the termination or expiration of the agreement unless statutory provisions require a further retention.
## 16. DISPUTES
1. In the event of any dispute, claim or controversy arising out of or relating to these Terms, or the breach, termination, enforcement, interpretation or validity thereof or the use of the Platform and Services, you agree to initiate a formal dispute proceeding by sending us a communication through our contact information. Ververica may choose to send you a written offer after receiving your initial communication.
1. If we offer and send you a settlement offer and you do not accept the offer, or we are unable to resolve your dispute satisfactorily and you wish to continue the dispute process, you may submit to the competent courts of Germany at the domicile of Ververica.
## 17. FINAL PROVISIONS
1. Unless explicitly agreed otherwise, Ververica will provide the Platform and Services to you as activities (services).
1. These Terms are governed by the laws of Germany without giving effect to the principles of conflicts of law thereof. Use of the Ververica Platform and Services are not authorized in any jurisdiction that does not give effect to all provisions of these Terms. Exclusive place of jurisdiction for all disputes between the Parties shall be the courts of Germany at the domicile of Ververica.
1. Our compliance with these Terms is subject to existing laws and legal process, and nothing contained in these Terms limits our right to comply with law enforcement or other governmental or legal requests or requirements relating to your use of our Platform and Services or information provided to or collected by us in connection with such use.
1. There are no oral amendments to these Terms. Any amendments require the agreement of the Parties in text form. The same applies to any agreement on waiver of this form requirement.
1. Unless otherwise specified in these Terms, you shall not assign or otherwise transfer any rights or obligations under these Terms without Ververica’s permission. Ververica may assign, novate and/or transfer rights and obligations under these Terms, in whole or in part, to
1. any of its affiliates or
1. to a third party in connection with a restructuring.
1. These Terms will be binding on the Parties and their respective successors and permitted assigns. Any assignment in contravention of this section is void.
1. If any section of these Terms is held invalid, illegal or unenforceable, the validity, legality and enforceability of the remaining provisions shall not in any way be affected or impaired. Our failure to enforce or delay in enforcing any provision of these Terms at any time does not waive our right to enforce the same or any other provision in the future.
1. Any rights not expressly granted herein are reserved.
1. If you have questions or concerns about these Terms, please contact us through our contact page or by using the contact information below:
**Ververica GmbH**
Herzogspitalstrasse 24
80331 München
E-Mail: [info@ververica.com](mailto:info@ververica.com)
---
---
title: "Ververica Academy ToS"
description: "Learn about Ververica Academy's Terms of Use, user responsibilities, and prohibited activities. Register for educational content and training services."
lastUpdated: 2026-04-29T09:15:20.000Z
source_url:
html: "https://www.ververica.com/academy/terms-of-service"
md: "https://www.ververica.com/academy/terms-of-service.md"
---
# Ververica Academy Terms of Service
**Last update: July 17th 2023**
The website [https://www.ververica.academy](https://www.ververica.com/?hsLang=en) and systems based on it or supporting it, as specified by Ververica from time to time (collectively, “**Ververica Academy**”), are owned and/or operated by Ververica GmbH, a limited liability company incorporated in Germany (“**Ververica**”). Through the Ververica Academy, Ververica provides Ververica Academy training services, among others (collectively, “**Academy Services**”). These Terms of Use for Ververica Academy (“**Terms**”) are a legally binding agreement between you as a registered user of the Academy Services (“**you**”, “**your**” and “**User**”) and Ververica as the provider of the Academy Services (“**we**”, “**us**”, “**our**” and “**Ververica**”; the User and Ververica together the “**Parties**” and each a “**Party**”).
The Terms apply to the use of the Academy Services. This includes mobile and tablet versions, as well as any other version of the Academy Services accessible via desktop, mobile, tablet, social media, or other devices.
## 1. USER ACCOUNT AND ACCEPTANCE OF TERMS
1. These Terms govern your access and use of your user account (“**Account**”) with Ververica for the Ververica Academy and the Academy Services. By registering for the Account and/or using any of the Academy Services, you agree to be bound by these Terms. If you do not agree to all clauses of these Terms, you must not continue with the account registration process and must not use any part of the Academy Services. The Parties agree that the general obligations in electronic commerce in Section 312i para. 1 sentence 1 no. 1-3 of the German Civil Code (Bürgerliches Gesetzbuch) shall not apply.
1. You represent and warrant that you are an entrepreneur within the meaning of Section 14 of the German Civil Code, _i.e._ a natural or legal person or a partnership with legal capacity who, at the time of entering into this agreement, is acting in the exercise of its commercial or independent professional activities, including where you are a natural person who is entering these Terms and will be using the Academy Services for purposes that predominantly are within your trade, business or profession.
1. Children under the age of 13 are prohibited from using the Academy Services, therefore shall not register an Account with us. For those users under the age of 18 (or any higher age if the age of majority is higher than 18 pursuant to the laws applicable to the User) and over the age of 13, it is the responsibility of parents and/or legal guardians of the User to determine whether use of the Academy Services is appropriate for such User.
1. If you are using the Academy Services on behalf of your employer, you hereby represent and warrant that you have full legal authority to bind your employer to these Terms. Accordingly, all references in these Terms to “you”, “your” or “User” shall be deemed to include your employer, except where the context may otherwise require. If you do not have such authority, then you may not use the Academy Services on behalf of your employer and you must discontinue all use of the Academy Service immediately.
1. You represent and warrant that all registration information you submit is accurate and truthful and that your use of the Academy Services does not violate any applicable law or regulation. Ververica may, in its sole discretion, refuse to offer the Academy Services in its entirety or any part thereof to any user and change its eligibility criteria at any time. This provision is void where prohibited by law and the right to access the Academy Services is revoked in such jurisdictions.
1. By using any part of the Academy Services, you represent and warrant that you have the full right, power, and authority to enter into these Terms and to fully perform all of your obligations hereunder. You further represent and warrant that you have no legal incapacity or contractual restriction that would prevent you from entering into these Terms.
1. We may in our sole discretion refuse to register your Account. Without prejudice to the generality of the foregoing, we may refuse to do so when your Account was previously terminated due to a breach of these Terms or when we reasonably consider you likely to breach any of the representations and warranties contained in these Terms.
1. By registering an Account, you are responsible for maintaining the confidentiality of your password and other Account information and you are fully responsible for all activities that occur under your Account. You agree to:
1. immediately notify Ververica of any unauthorized use of your password or Account or any other breach of security and
1. ensure that you log out of your Account at the end of each session. You may never use another user’s Account without Ververica’s prior authorization. Ververica is not liable for any loss or damage arising from your failure to comply with these Terms.
## 2. VERVERICA ACADEMY
1. Ververica Academy ([www.ververica.academy](http://www.ververica.academy)) is an online digital environment that facilitates the delivery of educational content, enabling users to learn various subjects or skills at their own pace. Key functionalities may include, but are not limited to: Course Content, Assessment and Tracking, Interactive Elements, Certifications and Badges, and Personalized Learning Paths.
1. In delivering Ververica Academy and/or the Academy Services, solutions and services providers listed below may also be used or engaged:
1. NorthPass, by Gainsight ([https://www.northpass.com](https://www.northpass.com)) is a cloud-based online learning platform designed for interactive learning and training courses.
1. HubSpot ([https://www.hubspot.com](https://www.hubspot.com)) is Customer Relationship Management (CRM) platform that includes software, integrations, and resources for marketing, sales, content management, and customer service.
1. Credly ([https://info.credly.com](https://info.credly.com)) is an end-to-end solution for creating, issuing, and managing digital credentials.
1. Stripe ([https://stripe.com](https://stripe.com)) is a technology company that provides software allowing businesses to receive payments and manage transactions over the internet.
1. Ververica offers the Ververica Academy through [www.ververica.academy](http://www.ververica.academy) (“**Ververica Academy Website**”).
1. Use of certain part of the Ververica Academy Website and certain courses, functions and/or other services thereon designated by Ververica as “free” is free of charge, while some others may only be used for a fee.
1. For the avoidance of doubt, the Ververica Academy Website may also contain content provided by third parties. Ververica bears no obligation or liability for any such content provided by any third party, and you shall evaluate any potential risk and consequence of accessing such content before clicking relevant links and assume any and all obligations and liabilities arising therefrom or in connection therewith.
## 3. PROHIBITED ACTIVITIES
1. You agree not to use the Academy Services in a negligent, fraudulent, or unlawful manner. You also agree not to engage in any conduct or action that damages the image, interests, or rights of Ververica. In addition, the following activities are prohibited, unless with our written permission or such restrictions are prohibited by law, in particular the German Copyright Act (Urheberrechtsgesetz) such as the right to interoperability or to create a backup copy:
1. Use the Academy Services for any commercial purposes outside the scope of the purposes explicitly permitted in these Terms and related guidelines (if any) made available by Ververica.
1. Access, monitor, reproduce, distribute, transmit, broadcast, stream, display, sell, license, copy or otherwise exploit any content of the Academy Services, including, but not limited to, the use of any robot, spider, scraper or other automated means or any manual process for any purpose not in accordance with these Terms or without our express written permission.
1. Violate the restrictions of any robot exclusion headers on the Ververica Academy Website and Academy Services, or circumvent other measures employed to prevent or limit access to the Academy Services.
1. Take any action that imposes, or may impose, in our reasonable discretion, an unreasonable or disproportionately large load on our infrastructure.
1. Establish a deep link to any part of the Ververica Academy for any purpose without our express written permission.
1. Attempt to modify, translate, adapt, edit, decompile, disassemble or reverse engineer any software program used by us.
1. Circumvent, disable, or otherwise interfere with security-related features of the Ververica Academy Website or features that prevent or restrict the use or copying of any content.
1. Engage in any activity that violates applicable laws, regulations, or the rights of others.
1. Attempt to gain unauthorized access to the Ververica Academy or any related systems or networks.
1. Use the Ververica Academy to upload, transmit, or distribute any content that is unlawful, harmful, defamatory, or infringing upon intellectual property rights.
1. Interfere with the proper functioning of the Ververica Academy or disrupt other users' access or experience.
1. Engage in any form of data mining, scraping, or extraction of information from the Ververica Academy without our explicit consent.
1. Ververica is entitled to delete content provided by the User in connection with the Academy Services or by third parties who the User allows to use the Academy Services and/or to disable access to such content if and to the extent that, based on Ververica’s reasonable judgement, the content does not meet the requirements of these Terms.
1. In addition, Ververica is entitled to completely or partially disable the User’s access and/or that of third parties who the User allows to use the Academy Services to the Academy Services and/or to suspend the provision of the Academy Services under these Terms if the User does not fulfill its payment obligations as specified in these Terms in part or in full or materially breaches other obligations under these Terms, or it is necessary to disable the access due to legal requirements.
## 4. USER’S RESPONSIBILITIES
1. Without restriction of Ververica’s obligation to provide the Academy Services, by using the Academy Services you accept personal responsibility for the results of your use of the Academy Services and for any actions taken through the Academy Services. Ververica does not guarantee any outcome, benefit, or failure as a result of your use of the Academy Services. You acknowledge and agree that your ultimate success or failure in using the Academy Services will be the result of your own actions, your situation and other circumstances beyond Ververica’s control. Without restriction of Ververica’s obligation to provide the Academy Services, by visiting the Ververica Academy Websites and accessing the content available on the Ververica Academy Websites you accept personal responsibility for the results of the use of the information and content available on the Ververica Academy Websites. Ververica does not guarantee the results of actions advised or not advised by these Websites and the content available on the Ververica Academy Websites. Ververica provides resources and content for informational purposes only. You acknowledge and agree that your ultimate success or failure in using the information and content available on the Ververica Academy Websites will be the result of your own efforts, your particular situation and a number of other circumstances that are beyond Ververica’s control.
1. You are responsible towards Ververica for all actions and omissions by your employees acting on your behalf. Furthermore, you warrant that all your employees you allow to use the Academy Services have rights of representation in relation to you, including the right to make legally relevant declarations within the context of the rights of access and use granted to them.
1. When using the Academy Services, you warrant that you will comply with all applicable laws, including product liability, product safety, e-commerce, data protection, tax, sanctions laws, export and import control laws, including U.S. and international export and import control laws, as well as the U.S. Children’s Online Privacy Protection Act. Ververica shall not be liable for the exportability of the Academy Services or obtaining an approval required for an export to any country or for any delays caused by applicable export procedures unless this is caused by a culpable violation of Ververica’s obligations under these Terms.
1. You acknowledge that the Academy Services may contain components, technologies and/or services which are subject to the laws or decisions regarding sanctions, export controls, embargoes and/or other trade restriction requirements, of the United Nations or countries in which the Academy Services are provided. You represent and warrant that you will not use, export or re-export, sell, re-sell, license, distribute, make available or transfer or cause or facilitate the transfer of the Academy Services, including any component or part thereof, directly or indirectly to:
1. any country or destination subject to comprehensive export controls, sanctions or other restrictions, or
1. any individual or entity listed on any applicable sanction lists (including without limitation the U.S. Treasury Department’s list of Specially Designated Nationals, the U.S. Commerce Department’s Denied Persons List, Entity List) or any other parties not eligible to receive them, as such lists may be updated from time to time.
1. You further warrant that you will not use, export or re-export, sell, re-sell, divert or otherwise transfer the Academy Services, including any component or part thereof, for use in activities that involve any of the following:
1. The development, production, use or stockpiling of nuclear activities of any kind, chemical or biological weapons or missiles, unmanned aerial vehicles, or microprocessors for military use, or any terrorist activities, nor in any facilities that are engaged in activities relating to such weapons or applications; or
1. large-scale and systematic surveillance operated by a government; or
1. the development and use of government-operated social scoring systems; or
1. instruments for exercising repressive control by a government, especially the systematic discrimination and oppression of ethnic or other minorities.
1. You agree that if Ververica reasonably believes that you are in breach of any of the terms and conditions contained in the above Sections 4(d) and 4(e) that alone shall be sufficient grounds for further action by Ververica, including, without limitation, cancellation of any subscriptions or denial of future sales and services, without any liability or obligation to you. In addition, you hereby indemnify Ververica and its affiliates, directors, officers and employees for all costs, expenses, damages, claims, charges, penalties, fines, and other losses that arise in connection with any breach by you of such Sections 4(d) and 4(e).
## 5. INVESTIGATION AND ENFORCEMENT
1. Ververica shall have the right to investigate any potential breach or violation of these Terms and to report any activities that Ververica reasonably considers to be in violation of these Terms or any applicable laws or regulations in any jurisdiction to the relevant enforcement agencies, regulators, government bodies, and any other appropriate third parties.
1. Ververica shall have the right to access, disclose and/or remove any content you published on or submitted to Ververica or to the Academy Services in connection therewith or to comply with applicable law, legal process, or lawful government requests, or in respect of any claims or potential claims brought against Ververica, or its shareholders, subsidiaries or affiliates.
## 6. FEES AND PAYMENTS
1. Except in the case of items/areas that are designated as “free”, you may be required to pay a fee (“**Fee**”) for your use of the Academy Services. Details of any Fee are set forth on the corresponding webpages of the Academy Services. The Fee may be paid through the following payment methods subject to the availability at the time of the payment: Credit/debit card (Visa, Master, Discover, Amex, Diners, etc.).
1. Payments will be processed through a payment processor such as Stripe. Payment for your use of the Academy Services will be charged to your credit/debit card once the payment process is completed. Once the transaction has been processed and payment for the use of the Academy Services has been completed, we will send an electronic receipt to the User’s email address. If the User purchases use of the Academy Services, the User will receive a license token (only if a token is required), via the User’s email address upon completion of the payment process. If you find any inconsistencies in your billing, please contact us via our contact details or file a complaint via the customer service of the relevant payment processor.
1. If your card is declined, you will receive an error message. No payment will be charged to your card and no order will be processed. There may be a pending transaction on your account until your card issuing bank withdraws the authorization. This usually takes two (2) to five (5) working days. Your card may be declined for a number of reasons such as insufficient funds, AVS (Address Verification System) mismatch or an incorrect security code. If your payment is declined, you will need to provide an alternative payment method or provide another card on which the payment can be charged and processed.
1. Your payment data will be processed and kept securely and for the sole purpose of processing the purchase of the use of the Academy Services. Ververica reserves the right to contract any payment platform available on the market which processes your data for the sole purpose of processing the purchase for the use of the Academy Services.
1. In the event of late payments, Ververica reserves the right to suspend User’s access to the Academy Services until all due payments have been made. Ververica will inform the User well in advance about any suspension. For the avoidance of doubt, the suspension neither interrupts the term nor the User’s further payment obligations.
## 7. INTELLECTUAL PROPERTY AND COPYRIGHT
1. The content and information available on or contained in the Academy Services (including, but not limited to, data, information, text, music, sound, photos, graphics, videos, maps, icons, illustrations, software or other material) as well as the infrastructure used to provide such content and information are protected by copyrights, trademarks and/or other intellectual property rights owned and controlled by Ververica or by third parties who have licensed or provided their material to the platform. With the exception of the rights explicitly granted under these Terms, both Parties and their third-party suppliers and licensors remain the holders of all rights. All rights to the Academy Services, also covering all future developments, will remain with Ververica, its third-party suppliers and licensors.
1. When you download, use or purchase any courses or other content on the Academy Services and we conclude a valid agreement under the Terms, unless otherwise provided to the contrary, Ververica grants you a personal, worldwide, royalty-free, non-assignable, non-exclusive, revocable license to use such courses or other contents that Ververica provides to you for the purposes agreed by the Parties (e.g. educational purpose, or other purposes agreed in the purchasing process, or on the course/content details page). You may not copy, reproduce, modify, distribute, sell, rent or otherwise transfer any part of the Academy Services or the included courses or other contents, or reverse engineer or attempt to extract the resources or source code of such courses or other contents, unless with our written permission or such restrictions are prohibited by law, in particular the German Copyright Act such as the right to interoperability or to create a backup copy.
1. You grant Ververica a worldwide, perpetual, irrevocable, transferable, sub-licensable, royalty-free license to use any suggestion, recommendation, feature request, or other feedback related to the Academy Services provided by or on behalf of you and your employees, and to incorporate any of the above into the Academy Services.
1. Ververica will respond to all enquiries, complaints and claims relating to alleged infringement by breach or violation of the provisions contained in international copyright and intellectual property laws and regulations. Ververica respects the intellectual property of others and expects users to do the same. If you believe, in good faith, that any material provided on the Ververica Academy Websites infringes your intellectual property right or copyright, please submit your request via our contact information, with the following information:
1. Identification of the intellectual property right or copyright that is allegedly infringed. All relevant registration numbers or a statement of ownership of the work should be included.
1. A statement that specifically identifies the location of the infringing material in sufficient detail so that Ververica can find it on the website.
1. Your name, address, telephone number and email address.
1. A statement by you that you have a good faith belief that use of the allegedly infringing material is not authorized by the owner, or its agents, or the law.
1. A statement by you, made under penalty of perjury, that the information in your notice is accurate and that you are the owner or authorized to act on the owner’s behalf.
1. An electronic or physical signature of the owner or the person authorized to act on the owner’s behalf.
## 8. INDEMNIFICATION
1. You agree to defend and indemnify Ververica from and against any claims, causes of action, demands, recoveries, losses, damages, fines, penalties or other costs or expenses of any kind or nature, including, but not limited to, reasonable legal and accounting fees, brought by third parties as a result of:
1. a breach of these Terms or the documents referenced herein,
1. a violation of any law or the rights of a third party, or
1. use of Academy Services by you or an affiliate of you within the meaning of Section 15 of the German Stock Corporation Act.
1. This duty of indemnification does not apply if you are not responsible for the occurrence of the relevant claims, damage or costs etc.
## 9. DATA PROTECTION AND INFORMATION SECURITY
1. The Parties will comply with all applicable data protection and privacy laws and regulations. Any personal data you provide in connection with your registration of the Account and your use of the Academy Services will be used in accordance with our Privacy Policy. To the extent that Ververica is processing personal data provided by you on your behalf when you use the Academy Services, a Data Processing Addendum will apply to such data processing activities between the Parties.
1. You will inform your end-users (i.e. the “**Data Subjects**”), if applicable, in accordance with applicable requirements (such as Articles 13 and 14 GDPR) as only you as the data controller are in direct contact with the Data Subjects. You are responsible and guarantee to obtain and maintain valid consents from all the Data Subjects as may be necessary under applicable law (including data protection, privacy or data processing laws and regulations) to process their personal data in the manner and for the purposes set forth in these Terms.
1. Ververica is committed to ensuring the security, confidentiality, and integrity of its customers’ information. To achieve this goal, Ververica has implemented a range of comprehensive and reasonable information security controls, with which you shall comply to be able to use the Academy Services. However, you are also responsible for implementing your own information security controls to safeguard your data while using the Academy Services, including without limitation protecting your access to Academy Services. In addition, you are solely responsible for verifying all content you uploaded to and/or disseminate with the Academy Services. This verification process should ensure that such content is free from any known vulnerabilities and that it has not performed any malicious actions either inside or outside of Ververica’s infrastructure and environment, and such contents are compliant with all applicable laws. This security verification of your content is essential to maintain the overall security, order, and integrity of the Academy Services. Ververica may suspend or terminate the Academy Services to you in the event that there are reasonable indications that you have failed to ensure the security of your content or your data.
## 10. CONFIDENTIAL INFORMATION
1. “**Confidential Information**” means information, whether in oral, written or other form that you or Ververica (“**Discloser**”) or, where applicable, your/its respective officers, directors, advisers, employees or agents (collectively, your/its “**Representatives**”) discloses to Ververica or you, respectively (“**Recipient**”) or, where applicable, your/its Representatives, including without limitation: internal policies, business plans, capitalization tables, budgets, and financial statements; costs, prices, and marketing plans; contracts and licenses; employee, customer, supplier, shareholder, partner or investor lists; technology, know-how, business processes, trade secrets and business models; notes, sketches, flow charts, formulas, blueprints, and elements thereof; and source code, object code, graphical design, user interfaces and other intellectual property, including that of any customer, supplier or other third party. Notwithstanding the foregoing, Confidential Information shall not include information that:
1. is or becomes generally available to the public other than as a result of a disclosure or other fault by Recipient or any of its Representatives; or
1. was rightfully in Recipient’s possession free of any obligation of confidentiality at or subsequent to the time such portion was communicated pursuant to these Terms; or
1. was developed by Recipient independently of and without reference to any information communicated hereunder. Furthermore, a disclosure by Recipient or its Representatives of Confidential Information of Discloser:
1. in response to a valid order by a court or other governmental or regulatory body; or
1. otherwise required by law; or
1. necessary to establish the rights of either Party under these Terms, shall not be considered to be a breach of these Terms by such Recipient; or
1. These obligations of confidentiality under this section shall survive the termination of the agreement between the Parties by a term of three (3) years.
## 11. LIMITATION OF LIABILITIES
1. Ververica shall be responsible for ensuring that the Academy Services operate as specified in these Terms. Ververica does not assume any liability for any damages resulting from a usage of the Academy Services not in accordance with the specifications of these Terms.
1. Ververica will be liable for damages and futile expenses only to the extent such damages or expenses are due to:
1. intentional or grossly negligent conduct of Ververica or
1. Ververica’s breach of a material contractual duty. “Material Contractual Duties” or “Cardinal Obligations” are the contractual obligations protecting User’s material interests under these Terms, i.e. obligations that characterize the Academy Services and on which User may rely. In the event of a just slightly negligent breach of a Material Contractual Duty by Ververica, its legal representatives or vicarious agents, Ververica’s liability shall be limited to the damage or loss which is foreseeable and typical of the contract at the time of conclusion of these Terms.
1. The foregoing limitations shall not affect liability for damages resulting from an injury to life, body, or health. The same applies to claims resulting from warranty breaches and claims under the German Product Liability Act (Produkthaftungsgesetz).
1. Neither Party will be liable for failure or delay in performance of its obligations under these Terms to the extent caused by circumstances beyond its reasonable control, including acts of God, natural disasters, terrorism, riots, or war.
1. Ververica will provide the Academy Services “as is” and is not obliged to guarantee specific functions or other requirements of the Academy Services, including with regard to availability. Ververica can provide an updated or modified version at any time at its sole discretion, without prior notice and without specifying any reasons. To the extent permitted by applicable laws, Ververica excludes any warranty or liability for and in connection with use of the Academy Services. Ververica’s liability for intent and gross negligence and in the case of fraudulent concealment of defects remains unaffected.
1. All exclusions and limitations of liability set out in this Section 11 also apply to Ververica’s affiliates, members of the executive board, directors, employees, agents, subcontractors, sub-suppliers, and other persons assisting Ververica.
## 12. THIRD PARTIES
1. 1. Through your use of the Academy Services you may encounter links to third party sites or be able to interact with third party sites. These third parties may charge a fee for the use of certain content or services provided on or through their websites. Therefore, you should investigate as you deem necessary or appropriate before proceeding with any transaction with any third party to determine whether a fee will be incurred.
1. 2. Where Ververica provides details of fees or charges for such third-party content or services, such information is provided for convenience and information purposes only. Any interaction with third party sites and applications is at your own risk. Ververica is in no way responsible for such third-party websites.
## 13. CHANGES
1. Ververica may amend these Terms for legitimate reasons, in particular for legal or security reasons. This does not apply to Fees. Ververica will notify the User of any amendment at least thirty (30) days prior to its proposed entry into force.
1. If the User fails to object in text format to an amendment before the proposed effective date, the User will be deemed to have accepted the amendment. Ververica may only introduce amendments that would create new obligations for the User or make its existing obligations more onerous if the User gives its express consent.
1. Ververica may make amendments at shorter notice if:
1. Ververica is subject to a legal or regulatory obligation that precludes compliance with the thirty (30) day deadline,
1. Ververica needs to amend the Terms to avert an unforeseen and imminent threat to its business operations, or
1. the amendments are only of editorial nature. In the case of amendments made at short notice, the User will be entitled to terminate the agreement for cause if the amendment is as a whole disadvantageous for the User, i.e. if it changes the relationship between performance and Fees to the User’s disadvantage.
1. In all other cases, amendments will only be effective if agreed between the Parties in text form. This will also apply to any amendment or supplement to the requirement of text form.
## 14. TERMINATION
1. We reserve the right to suspend or terminate your access to the entire Academy Services or any part thereof at any time and for any reason, without prior notice or liability, provided that unless otherwise provided to the contrary under this Section 14, you shall be entitled to the refund of the Fees you paid for the terminated Academy Services that are not rendered, unused and not expired as of the date of termination on a _pro rata_ basis. Upon termination, you shall no longer have access to your account or any associated content. Sections 7 (Intellectual Property and Copyright), 10 (Confidential Information) and 11 (Limitation of Liabilities) of these Terms of Service shall survive any termination.
1. Ververica may suspend the provision of the Academy Services or any parts thereof immediately on written notice to the User where Ververica reasonably suspects that the provision of the Academy Services or the use of the Academy Services by the User may result in a violation of any applicable laws, including laws on export or import control. For the avoidance of doubt, you will not be entitled to any refund or credit of any Fees or other paid amounts in this case.
1. Upon termination or expiration of the agreement under these Terms, the User’s Account will be terminated, meaning you will no longer have access to the Academy Services. Ververica will delete your data within thirty (30) days after the termination or expiration of the agreement unless statutory provisions require a further retention.
1. Ververica may terminate your access to the entire Academy Services or any part thereof immediately with a notice if you violate any clause of these Terms. If we terminate your access due to your violation of these Terms of Use, or any reason not attributable to Ververica, you will not be entitled to any refund or credit of any Fees including unused subscription fees or other paid amounts.
## 15. DISPUTES
1. In the event of any dispute, claim or controversy arising out of or relating to these Terms, or the breach, termination, enforcement, interpretation, or validity thereof or the use of the Academy Services, you agree to initiate a formal dispute proceeding by sending us a communication through our contact information. Ververica may choose to send you a written offer after receiving your initial communication.
1. If we offer and send you a settlement offer and you do not accept the offer, or we are unable to resolve your dispute satisfactorily and you wish to continue the dispute process, you may submit to the competent courts of Germany at the domicile of Ververica.
## 16. FINAL PROVISIONS
1. Unless explicitly agreed otherwise, Ververica will provide the Academy Services to you as activities (services).
1. These Terms are governed by the laws of Germany without giving effect to the principles of conflicts of law thereof. Use of the Ververica Academy Services are not authorized in any jurisdiction that does not give effect to all provisions of these Terms. Exclusive place of jurisdiction for all disputes between the Parties shall be the courts of Germany at the domicile of Ververica.
1. Our compliance with these Terms is subject to existing laws and legal process, and nothing contained in these Terms limits our right to comply with law enforcement or other governmental or legal requests or requirements relating to your use of our Academy Services or information provided to or collected by us in connection with such use.
1. There are no oral amendments to these Terms. Any amendments require the agreement of the Parties in text form. The same applies to any agreement on waiver of this form requirement.
1. Unless otherwise specified in these Terms, you shall not assign or otherwise transfer any rights or obligations under these Terms without Ververica’s permission. Ververica may assign, novate and/or transfer rights and obligations under these Terms, in whole or in part, to:
1. any of its affiliates or
1. to a third party in connection with a restructuring. These Terms will be binding on the Parties and their respective successors and permitted assigns. Any assignment in contravention of this section is void.
1. If any section of these Terms is held invalid, illegal or unenforceable, the validity, legality and enforceability of the remaining provisions shall not in any way be affected or impaired. Our failure to enforce or delay in enforcing any provision of these Terms at any time does not waive our right to enforce the same or any other provision in the future.
1. Any rights not expressly granted herein are reserved.
1. If you have questions or concerns about these Terms, please contact us through our contact page or by using the contact information below: **Ververica GmbH** Ververica GmbH, Chausseestrasse 20, 10115 Berlin E-Mail: [info@ververica.com](mailto:info@ververica.com)
---
---
title: "VVC and BYOC Support Services Plans"
description: "Ververica offers comprehensive support services plans for Ververica Cloud Managed Services, including 24/7 observability and tailored consultancy. "
lastUpdated: 2026-04-29T13:12:25.000Z
source_url:
html: "https://www.ververica.com/product/deployment/cloud/support"
md: "https://www.ververica.com/product/deployment/cloud/support.md"
---
# Support Services Plans
Ververica Cloud: Managed Service & Bring Your Own Cloud
## Support Services Plans
Ververica has implemented 24/7 year round observability of all Ververica Cloud services. Our Support staff will be automatically alerted in case of anomalies or issues.
As a Ververica customer, you have a wide range of support options at your disposal. Whether it's about finding answers to your questions or getting guidance with critical issues, our team is here to help.
Ververica provides **Free** level support for all registered customers using the Ververica Cloud Managed Service deployment option with Pay as you go and/or Reserved Capacity offering types. This level of support is provided via the Support Portal, and is for problems related to using and accessing Ververica Cloud Managed Service. Target response time is provided on a best-effort basis.
This page provides detailed overview of all suport services provided by Ververica.
For support services terms please refer to [Support Services Terms](https://www.ververica.com/deployment/cloud/support-terms).
**Support plans coverage includes fixing any issue related to Ververica Cloud Services**
Ververica offers additionally consultancy services that go beyond Ververica Cloud Services support plans coverage. Here, our engineers will provide holistic, customer solution tailored consultancy.
| Feature | Business | Enterprise |
| --- | --- | --- |
| | Recommended for both non-production and
production applications | Recommended for critical applications |
| Services and Features covered by support | All | All |
| Support availability | Business hours coverage:
Monday - Friday
9.00 am - 6.00 pm | 24/7 coverage |
| Severity Target Response Times | (P1), (P2)
Within 4 business hours
(P3), (P4)
Within 1 business day | (P1), (P2)
Within 1 hour
(P3),
Within 4 business hours
(P4)
Within 1 business day |
| Portal based support: Support | ✓ | ✓ |
| Pricing per month | 10% of monthly costs | 30% of monthly costs |
---
---
title: "FairMoney Case Study"
description: "OKX Did Not Want To Leave AWS. It Simply Needed A Better Flink On AWS"
lastUpdated: 2026-09-14T09:21:50.000Z
source_url:
html: "https://www.ververica.com/case-study/fairmoney"
md: "https://www.ververica.com/case-study/fairmoney.md"
---
# FairMoney
How FairMoney Reshaped Risk Model Development at Africa‘s Leading Digital Bank With Ververica Platform.
FairMoney evaluated several stream-processing platforms before selecting Ververica Platform (VVP) running Apache Flink®, on a self-operated deploy- ment on Amazon EKS. The deciding factor was fit: unlike alternatives that would have required rebuilding the processing architecture from scratch,
Ververica Platform let FairMoney keep its existing Flink-based job logic largely unchanged while gaining direct control over configuration, at a ma- terially better cost structure than a per-job managed service.
---
---
title: "Academy Bootcamp"
description: ""
lastUpdated: 2026-07-02T17:53:26.000Z
source_url:
html: "https://www.ververica.com/academy/bootcamp"
md: "https://www.ververica.com/academy/bootcamp.md"
---
# Apache Flink Bootcamp
**Online and Free!**
Nine modules. Taught by the team that wrote Flink. Go from Flink user to production-ready stream processing engineer.
## The Bootcamp
An intensive program for engineers who already use Apache Flink and want to run it in production. Nine modules cover architecture, state management, exactly-once processing, Flink SQL, and workflow design. Every concept is paired with a practical exercise. Every exercise maps to a real production pattern.
No marketing fluff. No recycled Flink documentation. The curriculum is taught by engineers who contribute to the Apache Flink project and operate it at enterprise scale.
## What You Get
Architecture to workflow design. Every concept built on the previous one. Linear progression through the full stack.
Production-grade coding exercises. Evaluated by Ververica engineers. Not multiple-choice theater.
60 minutes per day. Five time zones. Direct access to trainers who write Flink code for a living.
Capacity is capped per session. No 500-student webinars. Questions get answered.
## Curriculum
### Module 1: Apache Flink Architecture and Runtime
Cluster components, job submission, deployment modes, DataStream API, resource management.
### Module 2: Basic DataStream API Transformations
Filter, map, flatMap functions, rich functions, RichCo functions.
### Module 3: Event Time and Watermarks
Time ordering, windowing, watermark generation, late event handling, aggregations, window types.
### Module 4: State Management and Serialization
State handling, HashMap and RocksDB state backends, serialization concepts.
### Module 5: Failure Handling and Exactly-Once Processing
Failover strategies, high availability, checkpoints, exactly-once semantics.
### Module 6: Enrichment and Skew
Enrichment patterns, streaming joins, Streamhouse joins, performance optimization.
### Module 7: Flink SQL
SQL semantics, interval and temporal joins, changelog streams, dynamic tables.
### Module 8: Table API and DataStream Integration
Table API usage. Interop with DataStream pipelines.
### Module 9: Workflow Design
Job and workflow separation, components, segmentation, bridging.
## Prerequisites
Who Should Attend
### Programming
One to two years of Java or a comparable language. Basic SQL.
### Flink Experience
Hands-on API work. Job deployment and management. Event time and state concepts understood.
### System Knowledge
Stream processing fundamentals. Distributed systems experience. Basic cloud platform familiarity. ETL and data pipeline exposure.
## Format
Hybrid Online Self-Paced. Fixed start and end dates. Course unlocks on day one at 10:00 CET through the Ververica Academy platform. Linear progression. No skipping ahead.
Live Office Hours. 60 minutes daily. Multiple time zones: 08:00 PST | 11:00 EST | 16:00 GMT | 17:00 CET | 21:30 IST |
Monday includes additional 16:00 PST and 19:00 EST sessions dedicated to environment setup and troubleshooting.
Discord Community. Dedicated channel for the cohort. Peer-to-peer learning. Trainer support between office hours.
## Technical Requirements
To access your course, if you don't already have a Ververica Academy Account, you will need to create one first. The full course will be available starting the first day of the course at 10:00 CET. Once logged in, head to your Dashboard (top navigation bar) and click "Start" on the course. The course is linear, so you'll complete each module before moving to the next. Be sure to check out the Welcome Module it has all the technical setup details and office hours information you'll need.
## Frequently Asked Questions
### Who runs the bootcamp?
Ververica engineers who contribute to Apache Flink and operate the Ververica Platform at enterprise scale. The same people who write the code teach the course. Trainers rotate across modules based on deep specialization in architecture, SQL, state management, and production operations.
### How much Java do I need to know?
One to two years of Java or a comparable language. You will write code every day. If you have never handled generics, lambdas, or concurrent programming in Java, plan for additional background study. The program provides review material but the pace is set for experienced developers.
### What happens if I miss a live office hours session?
Sessions are recorded and posted to the Discord channel. Written questions get answered between sessions. The program accommodates multiple time zones with daily options. Miss one, catch the next. Do not skip all of them.
---
---
title: "VVC and BYOC Service Level Agreement"
description: "Discover Ververica Cloud Managed Service - Service Level Agreement for service availability. Learn about uptime guarantees, claims process, and exclusions."
lastUpdated: 2026-04-21T12:19:36.000Z
source_url:
html: "https://www.ververica.com/product/deployment/cloud/service-level-agreement"
md: "https://www.ververica.com/product/deployment/cloud/service-level-agreement.md"
---
# Service Level Agreement
**Last update: December 12th 2024**
Ververica Cloud: Managed Service & Bring Your Own Cloud
This Ververica Cloud Service Level Agreement (“**SLA**”) describes the service availability commitment for the Ververica Cloud Service (“**Service**”) under the Terms of Service (“**Terms of Service**”) between Ververica GmbH (“**Ververica**”, “**our**”, “**us**”, “**we**”) and User (“**you**”, “**your**”). This SLA is applicable only to the Data Plane services of the Managed Service and does not apply to the Control Plane services of the Managed Service, nor to the Bring Your Own Cloud and Ververica Platform Self-Managed deployment options.
Specifically, this SLA only applies to your ordered Services, where Services are used for a fee, and shall not apply to any free Services or trial Services provided by Ververica.
## 1. DEFINITIONS
1. “**Downtime**” means a period of time when all the running instances in your Service have no external connectivity or cannot be operated.
1. “**Downtime Period**” means a period of one or more consecutive minutes of Downtime. Partial minutes or intermittent Downtime period of less than one minute of Downtime will not be counted as Downtime Period.
1. “**Service Guarantee**” shall have the meaning set forth in Section 2 of this SLA.
1. “**Monthly Service Fee**” means the total monthly Services fees paid by you for the Services.
1. “**Monthly Uptime Percentage**” means the total number of operating minutes in calendar month, minus the summary of minutes of Downtime of all Downtime Periods occurred in such month, divided by the total number of minutes in such month.
1. “**Error**” means a reproducible defect in the Ververica Cloud Services that
1. degrades or impairs User’s use of the Ververica Cloud Services and causes such services not to operate substantially in accordance with the applicable specifications, instructions or other documentation provided by Ververica and
1. is reported via Support Tool.
For the avoidance of doubt, an Error does not include any User-specific issue in relation to a User’s use of Ververica Cloud Services in conjunction with such User’s own or its third-party environment, systems, components, interfaces, etc., unless otherwise agreed by Ververica.
1. “**Documentation**” means Ververica Cloud Services documentation, published by Ververica and accessible at https://docs.ververica.com/ and/or other locations on the Ververica Website.
1. “**Updates**” means a revision of the Ververica Cloud Services made generally available by Ververica to Users to correct Errors in the services or to maintain the operation of the services in accordance with the Documentation. Updates are announced in timely manner and should not cause any noticeable impact, but may sometimes could cause short period of Downtime or degraded Service performance.
1. “**Service Credit**” means the percentage of the Monthly Service Fee for the affected Service that is credited to you for a validated claim following our service credit claim process under Section 3.
1. Unless otherwise provided in this SLA, all capitalized terms used but not defined in this SLA shall have the same meanings as defined in the Terms of Service.
## 2. SERVICE LEVEL AGREEMENT
Ververica will use commercially reasonable efforts to provide a Monthly Uptime Percentage of no less than 99.5% each billing month in connection with your use of the Service (the “Service Guarantee”). If we fail to meet the Service Guarantee then, subject to the terms and conditions of this SLA, you shall be entitled to claim a Service Credit in accordance with Section 3 herein. The Service Guarantee does not apply to any events described in the Section 4 (SLA Exclusions.)
## 3. CLAIMS AND PAYMENT PROCESS
1. If you believe that the Service Guarantee in connection with your use of the Service is not met in a billing month, then you may file a claim for Service Credit in accordance with this Section, by submitting a support ticket in Support Portal. Your claim support ticket must include at least the following information:
1. A detailed description of the incident, configurations used, including the logs or messages for request failure documenting the errors and claimed outage;
1. The date, time, time zone and duration of the Downtime;
1. Information relating the affected instances, including the affected instance IDs;
1. Any other information that we reasonably ask you to provide to support your claim.
1. Ticket subject line “SLA Service Credit Claim”
1. To be eligible for Service Credit, your claim for a Service Credit must be received by us within five (5) calendar days after the last day of the month in which the Service does not meet the Service Level. Your failure to submit the claim within this time will be deemed to be an irrevocable waiver of your right to claim and receive such Service Credit. Once we receive your claim, we will review and evaluate your claim and may require your co-operation in conducting a joint investigation to ascertain whether the Service Guarantee has been breached and if so, the cause of the failure. We will make a good faith determination if a Service Credit is to be provided to you in our sole discretion and will inform you the result as soon as reasonably practicable. We will use commercially reasonable effort to process your claim and provide the Service Credit to you as early as possible.
1. If we, after our good faith review of your claim, determine that a Service Credit must be provided to you, the Service Credit to be provided will be the following:
1. Service Credits will be provided in the form of a credit applied to your future use of the Ververica Cloud Services only, and will be applied to the use of the Services taking place within one (1) billing month immediately after the billing month in which we issue you such Service Credits, after which period any unused Service Credits shall expire without any further compensation.
1. Service Credits may not be transferred or exchanged for cash or other forms of payment.
1. Service Credit provided for any billing month for a particular Service or Service resource will not, under any circumstance, exceed 30% of your Monthly Service Fee for that affected Service or Service resource, as applicable, in that billing month.
1. We will issue the Service Credit to you within one billing month following the month in which your request is confirmed.
1. Service credits are not refundable and can only be used toward future billing charges.
1. Service credits are exclusive of any applicable taxes charged to you or collected by us. Service Credits will not entitle you to any refund or other payment from us.
1. You agree that, to the extent permitted by law, any decision or determination made by us relating to your claim for any Service Credit shall be final and binding on you.
## 4. SLA EXCLUSIONS
The Downtime caused by or due to following events shall not be taken into account when calculating the Monthly Uptime Percentage:
1. suspension or termination described in Terms of Service;
1. events that are outside of our reasonable control, including any events of force majeure such as earthquakes, epidemic, downtime of the relevant submarine communication cables, failure of telecommunications infrastructure or systems, riots, hostile actions by third parties (such as network intrusion or denial of service attacks) etc.;
1. events that result from any actions or inactions on your part in connection with your use of the Service;
1. events that arise out of your or any third parties’ (not under our direct control) equipment, software, and/or technology;
1. events that result from your failure to adhere to any required configurations for the use of the Service;
1. events that result from your illegal or unlawful use of the Service, events that result from your breach of any of the terms and conditions of the Ververica Terms of Service;
1. events that result from your non-payment of any charges payable to us;
1. events that result from critical accidents or failure of the relevant internet service provider(s);
1. scheduled downtime;
1. downtime caused by the use of Beta Services and/or Beta Features;
1. your generated Services load (network, compute and storage usage) that exceeds the resource limits (network, compute and storage) of the given Service.
1. that results from the use of services or software provided by a third party and not within our primary control. This includes as well issues resulting from inadequate network bandwidth or issues and failures of cloud platform provider services on which the Ververica Cloud Services run.
1. events that result from the disabling of High Availability (HA) by you.
## 5. ADDITIONAL TERMS
1. In the event of any inconsistency between yours and our system records relating to your claim, unless the discrepancy is caused by any material error or malfunction of our system, our system record shall at all times prevail and be the final and conclusive reference for calculating the Service Credits to be provided to you.
1. The Service Credits provided in this SLA are your sole and exclusive remedy for any failure in the performance of the Service and we shall not be liable to you or any person claiming through you for any direct, indirect, consequential or incidental damages or losses or expenses whatsoever, including but not limited to, loss of profits or business and irrespective of whether the claim arises in contract, tort (including negligence), or otherwise.
1. We reserve the right to change the terms of this SLA anytime by posting an amended and restated version of this SLA on the Ververica Cloud Website. Your continued use of the service after the publication of the amended SLA shall be deemed as your acceptance of the amended SLA.
1. This SLA shall constitute part of your agreement for your purchase and use of the Service.
## 6. APPLICABILITY OF OTHER TERMS AND CONDITIONS
1. This SLA is an integral part of the overall agreement (“Agreement”) with regard to your use of Services between Ververica GmbH and you, of which all terms, conditions and obligations specified in the documents comprising the Agreement, including the Terms of Service, Privacy Policy, purchase orders, Support and Maintenance Services Terms, this SLA and any other relevant terms, policies or agreements agreed in writing between both parties, are applicable and binding on both parties.
1. In the event of any conflict or inconsistency between the provisions of this SLA and any other terms and conditions within the Agreement, this SLA shall prevail, unless stated otherwise in writing by both parties.
1. By using Services provided by us, you acknowledge and agree to comply with all terms and conditions outlined in the Agreement, including those specified in this SLA.
---
---
title: "Sovereignty playbook for FSI"
description: "Sovereignty playbook for FSI"
lastUpdated: 2026-04-16T11:53:11.000Z
source_url:
html: "https://www.ververica.com/data-sovereignty/fsi-sovereignty-playbook"
md: "https://www.ververica.com/data-sovereignty/fsi-sovereignty-playbook.md"
---
# What Regulators Demand and Vendors Can't Deliver.
**Comprehensive guide to data sovereignty for FSI.**
[DORA](https://www.digital-operational-resilience-act.com/) is now law. Since January 17, 2025, approximately 22,000 European financial entities must comply with the [Digital Operational Resilience Act](https://www.eba.europa.eu/publications-and-media/press-releases/european-supervisory-authorities-designate-critical-ict-third-party-providers-under-digital). This regulation harmonizes ICT risk management, third-party oversight, and operational resilience requirements across the EU's entire financial services sector.
The penalties for non-compliance are substantial. Financial institutions face fines up to 10% of annual turnover or EUR 10 million. Senior managers carry personal liability up to EUR 1 million. In November 2025, European regulators designated [19 critical ICT third-party providers](https://www.eba.europa.eu/activities/digital-operational-resilience-act-dora), including AWS, Google, and Microsoft, for direct supervisory oversight, signaling that cloud-dependent infrastructure now faces direct regulatory scrutiny.
DORA is not isolated. The [NIS2 Directive](https://digital-strategy.ec.europa.eu/en/policies/nis2-directive) strengthens cybersecurity requirements across critical sectors. The [EU AI Act](https://artificialintelligenceact.eu/), effective August 2, 2025, imposes additional compliance obligations on high-risk AI systems in financial services, with fines up to EUR 35 million or 7% of global turnover. GDPR enforcement continues to intensify, with EUR 1.2 billion in fines issued across Europe in 2024 alone according to [DLA Piper's GDPR Fines Survey](https://www.dlapiper.com/en-pl/insights/publications/2026/01/dla-piper-gdpr-fines-and-data-breach-survey-january-2026).
This convergence of regulations creates a clear message: data sovereignty is no longer optional for financial services. As we mention in [Data Sovereignty Is Existential Most Platforms Treat It Like a Feature](https://www.ververica.com/blog/data-sovereignty-is-existential-most-platforms-treat-it-like-a-feature?hsLang=en), regulators demand governed streaming, deployment freedom, and Zero Trust security. Most streaming platform vendors deliver one or two of these capabilities. Financial institutions need all three.
This playbook provides a decision framework for evaluating streaming platforms against sovereignty requirements. It explains what regulators actually demand, why vendor-managed platforms struggle to comply, and what FSI organizations should require from their [streaming infrastructure](https://www.ververica.com/what-is-stream-processing?hsLang=en).
## Understanding Data Sovereignty for FSI
Data sovereignty for financial services means maintaining complete control over where data resides, how it flows, who can access it, and how it is governed, while meeting regulatory requirements for audit, resilience, and third-party risk management.
### What Data Sovereignty Actually Means in 2026
Data sovereignty extends beyond data residency. While data residency focuses on geographic location, sovereignty encompasses:
- **Infrastructure control**: Who owns and operates the systems processing your data
- **Audit access**: Whether regulators can inspect systems and data flows
- **Third-party oversight**: How dependencies on external providers are managed
- **Exit capability**: Whether you can migrate without losing functionality or facing prohibitive costs
For FSI organizations, sovereignty is a regulatory requirement, not a preference. [DORA Article 28](https://eur-lex.europa.eu/legal-content/EN/TXT/?uri=CELEX%3A32022R2554) mandates that financial entities ensure their ICT service providers comply with regulatory standards, conduct due diligence, and maintain exit strategies.
### Why FSI Faces Unique Sovereignty Requirements
Financial services operates under heightened scrutiny because failures create systemic risk. A major bank's inability to process payments affects not just the institution but the broader economy. Regulators design requirements to prevent concentration of risk in single providers and ensure resilience across the sector.
The November 2025 designation of 19 critical ICT providers reflects this concern. When AWS, Google, or Microsoft experience outages, the impact cascades across thousands of financial institutions. Regulators now require enhanced oversight, incident reporting, and resilience testing for these concentrated dependencies.
### Tier 1 vs Tier 2 Sovereignty Requirements
Not all financial institutions face identical requirements. Sovereignty needs scale with systemic importance.
**Tier 1 FSI (G-SIBs, Central Banks):**
The [29 Global Systemically Important Banks](https://www.fsb.org/2025/11/2025-list-of-global-systemically-important-banks-g-sibs/) and central banks face the strictest requirements:
- Complete infrastructure control, often requiring on-premises deployment
- Unrestricted audit access for regulators
- Domestic or regional data residency with no exceptions
- Annual resolution planning with detailed recovery procedures
- Zero tolerance for vendor lock-in
**Tier 2 FSI (Regional Banks, Payment Processors, Asset Managers):**
Institutions with significant but not systemic importance require:
- Compliant third-party management under DORA Article 28
- Clear exit strategies and data portability guarantees
- Proportionate resilience testing based on operational complexity
- Full audit trail capability for regulatory reporting
- Option for on-premises or hybrid deployment
### The Sovereignty Spectrum
Deployment models exist on a spectrum from least to most sovereign:
The appropriate model depends on regulatory requirements, risk appetite, and operational capability. Many Tier 2 institutions find BYOC provides adequate sovereignty while reducing operational burden compared to full on-premises deployment.
**Key takeaway:** Sovereignty is not binary. FSI organizations must match deployment models to their specific regulatory requirements and systemic importance.
## Why Most Streaming Platforms Fail Sovereignty Requirements
The streaming data category has evolved beyond core messaging and processing into complete platforms offering governance, observability, and AI support. However, most vendors struggle to deliver the specific sovereignty capabilities FSI organizations require.
### The Streaming Governance Gap
Enterprise-grade governance for batch data is mature. Databricks Unity Catalog, for example, provides automatic lineage tracking, dynamic access policies, and comprehensive audit trails for batch workloads. The tooling is established and well-understood.
Streaming governance is different. In real-time streaming environments, tracking data origin, movement, and transformation is exceptionally difficult. Unlike batch systems that log discrete jobs with clear timestamps, streaming data flows continuously without persistent checkpoints.
DORA mandates real-time lineage and incident reporting. Financial entities cannot wait for batch analysis to understand what happened. When an incident occurs, regulators expect immediate visibility into data flows, access patterns, and system states.
This creates a gap. Most streaming platforms were designed for throughput and latency, not governance. Governance features are often added later, resulting in incomplete coverage or architectural limitations.
### Vendor-Managed Platforms and DORA Compliance Gaps
Vendor-managed streaming platforms (fully managed SaaS offerings) present specific challenges for DORA compliance. For a visual breakdown of what "managed" actually costs you in control, see [The Control Illusion: What Vendor-Managed Platforms Hide](https://www.ververica.com/fsi-streaming-sovereignty-one-pager?hsLang=en).
**Audit Rights (DORA Article 28)**
ICT providers must accept regular security audits from financial entities and their regulators. Vendor-managed platforms may limit inspection access due to multi-tenant architecture, proprietary systems, or operational concerns. Financial entities cannot audit what the vendor controls.
**Subcontracting Requirements**
DORA requires financial entities to assess risks from subcontractors in the ICT supply chain. Cloud platforms have complex dependency chains: the streaming vendor depends on the cloud provider, which depends on hardware vendors, network providers, and data center operators. This opacity creates compliance complexity.
**Exit Strategies**
DORA mandates clear exit strategies. Proprietary vendor platforms create steep migration costs and risk of losing functionality when switching providers. Vendor lock-in is a compliance risk, not just a commercial concern.
### The Control Illusion
Some vendor-managed platforms offer "enterprise" or "dedicated" tiers that appear to provide more control. These often include:
- Dedicated compute resources
- Enhanced security features
- Premium support
- Compliance certifications
These features improve security posture but do not fundamentally change the sovereignty model. The vendor still controls the infrastructure. Regulators still cannot directly audit systems. Exit costs remain high. For a deeper analysis of why these platforms are engaging in "Zero Trust theater," read [Zero Trust Theater: Why Most Streaming Platforms Are Pretenders](https://www.ververica.com/blog/zero-trust-theater-and-why-most-streaming-platforms-are-pretenders?hsLang=en)
For Tier 1 FSI, dedicated tiers are insufficient. For Tier 2 FSI, they may create a false sense of compliance that fails under regulatory scrutiny.
### Specific Vendor Limitations
**Cloud-Native Managed Services:**
Cloud provider managed streaming services are tightly coupled to their ecosystems:
- Single cloud lock-in by design
- Limited multi-cloud or hybrid capability
- Governance tools may lag behind standalone vendors
- Exit paths require significant re-architecture
**Standalone Managed Platforms:**
Standalone streaming vendors offer more features but introduce different concerns:
- Deep expertise required for operation and scaling
- Essential connectors and governance features often gated behind premium tiers
- Premium pricing for compliance-critical capabilities
- Privacy and compliance requirements remain a major challenge to scaling
### The Vendor Lock-in Problem
Proprietary features create migration difficulty. When a vendor's governance model, schema registry, or connector ecosystem differs from open standards, switching providers means rebuilding, not migrating.
For FSI, this creates regulatory risk. If a vendor relationship deteriorates, costs change unexpectedly, or regulatory requirements shift, the institution may face years of migration work and millions in costs.
**Key takeaway:** Vendor-managed platforms offer convenience but create sovereignty trade-offs that FSI organizations must evaluate carefully against regulatory requirements.
## The Three Pillars of FSI Streaming Sovereignty
True sovereignty for FSI streaming infrastructure requires three capabilities simultaneously. Most vendors deliver one or two. Financial institutions need all three.
### Pillar 1: Governed Streaming
Governed streaming means real-time data lineage, schema enforcement, and compliance monitoring purpose-built for streaming workloads, not batch governance retrofitted.
**Why It Matters:**
FSI has enterprise-grade governance for batch data, but streaming data is mostly ungoverned. [Real-time fraud detection](https://www.ververica.com/use-case/fraud-detection?hsLang=en), compliance monitoring, and payment processing require streaming-native governance: catalogs, RBAC, data lineage, and audit trails designed for real-time data flows.
**Core Requirements:**
**DORA Mandate:**
DORA requires real-time incident reporting and data lineage capabilities for approximately 22,000 EU financial entities. When regulators ask what happened, "we'll run a batch analysis" is not an acceptable answer.
**The Gap:**
Batch-first governance platforms like Unity Catalog were designed for discrete jobs. Applying them to continuous streaming creates gaps in coverage. Streaming-native governance must capture metadata in motion, not after the fact.
### Pillar 2: Deployment Freedom
Deployment freedom means the ability to deploy streaming infrastructure where regulatory, security, and architectural requirements demand, whether that is vendor-managed cloud, BYOC, or on-premises.
**Why It Matters:**
Financial services firms cannot always use vendor-managed cloud platforms. DORA requires audit access, exit strategies, and third-party risk management that many SaaS offerings cannot satisfy. Different FSI segments have different requirements:
- Tier 1 FSI (central banks, G-SIBs) often require on-premises deployment
- Tier 2 FSI typically needs BYOC for balance of control and convenience
- Regulatory requirements vary by jurisdiction and institution type
**Deployment Options:**
[**BYOC (Bring Your Own Cloud)**](https://www.ververica.com/deployment/bring-your-own-cloud?hsLang=en)**:**
BYOC enables organizations to run the data plane within their own cloud VPC while the vendor operates the control plane. This provides:
- Data never leaves customer-controlled infrastructure
- Customer owns cloud account and network configuration
- Vendor access limited to management functions
- Compliance with data residency requirements
- Reduced operational burden compared to full self-management
[**On-Premises**](https://www.ververica.com/deployment/self-managed?hsLang=en)**:**
On-premises deployment provides complete infrastructure control:
- No external data exposure
- Full audit access for regulators
- Maximum sovereignty for Tier 1 requirements
- Higher operational complexity and internal expertise requirements
**The Problem with Cloud-Only:**
Vendors offering only managed cloud deployment automatically disqualify themselves for Tier 1 FSI use cases. Cloud-only also limits options for institutions facing emerging regulatory requirements or future changes in sovereignty needs.
**Key Requirement:**
The platform must provide consistent functionality across deployment models. An institution should not lose governance, security, or operational capabilities when choosing BYOC or on-premises over managed cloud.
### Pillar 3: Zero Trust Security
Zero Trust security means identity-centric protection with continuous verification, not perimeter-based defense that assumes internal networks are trusted. For an in-depth analysis of how most streaming platforms fail to deliver genuine Zero Trust security, read [Zero Trust Theater: Why Most Streaming Platforms Are Pretenders](https://www.ververica.com/blog/zero-trust-theater-and-why-most-streaming-platforms-are-pretenders?hsLang=en).
**Why It Matters:**
The perimeter-based defense model that served financial institutions for decades is now insufficient. When attackers breach the perimeter (often through social engineering or compromised credentials), they move freely within trusted networks. The [2025 Verizon Data Breach Investigations Report](https://www.verizon.com/business/resources/reports/dbir/) confirms that individuals remain the weak link, whether clicking malware or being socially engineered to provide credentials.
**Zero Trust Principles for FSI:**
Based on the [NIST Zero Trust Architecture (SP 800-207)](https://csrc.nist.gov/pubs/sp/800/207/final):
**FSI-Specific Requirements:**
- Multi-factor authentication for all access
- Fine-grained access controls for streaming data
- Secrets management for credentials and keys
- Private network connections (PrivateLink, VPC peering)
- Comprehensive audit logging
- Real-time anomaly detection
**The Problem with Bolt-On Security:**
Some platforms add security features incrementally as market demands shift. This results in inconsistent coverage, architectural limitations, and gaps that sophisticated attackers exploit. Zero Trust must be embedded throughout the platform architecture, not layered on afterward.
**Key takeaway:** FSI streaming sovereignty requires governed streaming, deployment freedom, and Zero Trust security simultaneously. Achieving one or two is insufficient for regulatory compliance.
## Sovereign AI for FSI
Artificial intelligence is transforming financial services, but AI workloads in regulated industries face unique sovereignty requirements. The data that trains models, the models themselves, and the decisions they produce must all remain within compliance boundaries.
### Why AI Workloads Require Sovereign Streaming Data
Financial crime costs the global economy up to $2 trillion annually according to [UN estimates](https://www.unodc.org/unodc/en/money-laundering/overview.html). Between $800 billion and $2 trillion is laundered globally each year, representing 2-5% of global GDP. Yet only 0.1% of illicit funds are ultimately recovered, and only 1% of suspicious transaction reports are actually investigated.
The gap exists partly because legacy systems cannot process data fast enough. AI-enabled real-time monitoring delivers alerts or blocks actions within 2 seconds on average. Legacy systems require several minutes for the same decisions. When detecting fraud or money laundering, those minutes matter.
[Real-time AI](https://www.ververica.com/use-case/ai-ml?hsLang=en) for fraud detection, AML, and credit scoring requires:
- Streaming data infrastructure for continuous processing
- Sovereignty-compliant data handling throughout the AI pipeline
- Governance for both training data and model outputs
- Audit trails covering model decisions and their rationale
### EU AI Act Implications
The [EU AI Act](https://artificialintelligenceact.eu/), effective August 2, 2025, classifies AI systems used in credit scoring, fraud detection, and financial decision-making as high-risk. These systems must:
- Document data origins, transformations, and quality metrics
- Provide explainability for decisions
- Undergo bias audits and fairness testing
- Maintain audit trails of model versions and training data
Violations carry fines up to EUR 35 million or 7% of global annual turnover.
For FSI, this means AI governance requirements now extend to streaming data pipelines. The data flowing into models must be traceable. The models themselves must be versioned and auditable. The decisions they produce must be explainable.
### FSI AI Use Cases Requiring Sovereign Streaming
[**Real-Time Fraud Detection**](https://www.ververica.com/use-case/fraud-detection?hsLang=en)**:**
Transaction-level analysis in milliseconds, behavioral pattern recognition, cross-channel fraud correlation. Data cannot leave the jurisdiction for processing. Decisions must be logged with complete rationale.
**Anti-Money Laundering (AML):**
Real-time transaction monitoring across complex networks. Pattern detection for structuring, layering, and integration. Integration with external data sources (telecommunications signals, device telemetry). The average laundering operation spans 5-7 years before discovery; real-time streaming shortens detection windows.
**Credit Scoring:**
Real-time credit decisioning with alternative data integration. Fair lending compliance monitoring. Explainability requirements for adverse actions under Consumer Duty obligations.
### The Real-Time Imperative
Sovereign streaming provides the foundation for compliant AI in regulated industries: real-time data access, governance throughout the pipeline, and audit trails that satisfy both AI Act and existing financial services regulations.
**Key takeaway:** AI in FSI requires sovereign streaming infrastructure that maintains compliance from data ingestion through model training to decision output.
## Evaluating Streaming Platforms for Sovereignty
FSI organizations evaluating streaming platforms for sovereignty should apply a structured decision framework. This section provides practical evaluation criteria for security, compliance, and architecture leaders. For a scored, requirement-by-requirement assessment tool, use the [Sovereignty Evaluation Framework.](https://www.ververica.com/fsi-streaming-platform-evaluation-framework?hsLang=en)
### What Must Be Controlled by the Customer
At minimum, FSI organizations should control:
If the vendor controls any of these elements in ways that limit customer visibility or regulatory access, the platform may not meet sovereignty requirements.
### Where Auditability Breaks Down
Auditability failures typically occur at these points:
**Multi-tenant isolation:** In shared infrastructure, can regulators audit your specific data flows without accessing other customers' data? Can you prove isolation?
**Subcontractor chains:** Does the vendor disclose all subprocessors? Can you assess risk from fourth parties (the vendor's vendors)?
**Proprietary systems:** Are critical components built on proprietary technology that cannot be inspected or understood independently?
**Incident response:** When incidents occur, does the vendor provide raw data or only filtered reports? Can regulators access systems directly?
### Deployment Flexibility Checklist
### Red Flags in Vendor Assessments
**Governance gated by tier:** If essential governance features (lineage, audit trails, RBAC) require premium pricing, the vendor treats compliance as upsell rather than baseline requirement.
**Cloud-only deployment:** Vendors offering only managed cloud cannot serve Tier 1 FSI and limit future flexibility for Tier 2.
**Proprietary lock-in:** Significant proprietary extensions to open-source foundations (Kafka, Flink) create exit barriers that conflict with DORA requirements.
**Vague subcontracting:** Inability or unwillingness to disclose the full ICT supply chain indicates potential DORA Article 28 compliance gaps.
**Limited audit access:** Restrictions on security audits, penetration testing, or regulatory inspection rights suggest sovereignty limitations.
### Decision Framework
**For Tier 1 FSI (G-SIBs, Central Banks):**
1. Require on-premises or fully isolated deployment
1. Verify complete audit access for regulators
1. Confirm zero proprietary lock-in
1. Ensure full governance capabilities in air-gapped environments
1. Validate exit path to self-managed open source
**For Tier 2 FSI (Regional Banks, Payment Processors):**
1. BYOC deployment with data plane in customer VPC
1. Governance and audit capabilities at baseline tier
1. Clear exit strategy with defined migration path
1. Contractual terms aligned with DORA Article 28
1. Option to move to on-premises if requirements change
**Key takeaway:** Evaluate streaming platforms against specific sovereignty requirements, not generic feature lists. What works for a technology company may not meet FSI regulatory obligations.
## How Ververica Delivers FSI Sovereignty
Ververica provides the only [streaming platform](https://www.ververica.com/product?hsLang=en) that delivers all three sovereignty pillars: governed streaming, deployment freedom, and Zero Trust security, without compromise.
### Founded by the Creators of Apache Flink
Ververica was founded by the original creators of Apache Flink. This heritage provides technical authority that licensed technology cannot match. The engineering team that built Flink from its foundation continues to develop the Ververica platform, delivering optimizations and capabilities that reflect more than a decade of hands-on development.
This matters for FSI because depth of expertise translates to better support for complex, regulated workloads. When compliance requirements change or edge cases emerge, Ververica's team understands the technology at its core.
### Full Deployment Spectrum
Critical distinction: Ververica provides identical functionality across all deployment models. Governance, security, and operational capabilities do not degrade when moving from managed to BYOC to on-premises. This consistency enables FSI organizations to choose deployment based on regulatory requirements, not feature availability.
### VERA Engine Performance
The [VERA engine](https://www.ververica.com/vera?hsLang=en), Ververica's optimized Flink runtime, delivers:
- 2x performance compared to open-source Flink
- 40% lower total cost of ownership
- Elastic scaling across millions of cores
Performance matters for FSI because real-time processing cannot tolerate latency spikes during peak loads. [Fraud detection](https://www.ververica.com/use-case/fraud-detection?hsLang=en), payment processing, and compliance monitoring require consistent sub-second response times regardless of volume.
### Zero Vendor Lock-in
Ververica maintains 100% compatibility with Apache Flink. Applications developed on Ververica run on standard Flink without modification. This provides:
- Exit path to self-managed open source at any time
- No proprietary extensions that create migration barriers
- Alignment with DORA exit strategy requirements
- Future flexibility as requirements evolve
### Enterprise Governance
Ververica's governance capabilities are built for regulated industries:
- **Catalogs**: Centralized metadata management for streaming jobs, tables, and connectors
- **RBAC**: Role-based access control for streaming pipelines and data
- **Audit Trails**: Who accessed what streaming data, when, and why
- **Data Lineage**: Track data flow from source through processing to destination in real time
- **Multi-Tenancy**: Secure workspace isolation for teams and business units
These capabilities are available at baseline, not gated behind premium tiers.
### Zero Trust Architecture
Ververica embeds Zero Trust principles throughout the platform:
- Continuous verification for all access requests
- Fine-grained access controls at data and job level
- Secrets management integration
- Private network connections
- Comprehensive audit logging
- Anomaly detection and alerting
### Enterprise Proven
Ververica serves mission-critical workloads at scale:
- Major banks processing real-time payments and fraud detection
- Alibaba processing billions of events per second
- Intesa Sanpaolo, ING, Netflix, Uber, Airbus, Booking.com
- 35,000+ jobs running on single clusters
- 10+ petabytes ingested per day
- 10 trillion records ingested per day at enterprise scale
### Compliance Ready
Ververica maintains certifications aligned with FSI requirements:
- SOC 2 Type II
- ISO 27001
- GDPR compliance by design
**Key takeaway:** Ververica delivers governed streaming, deployment freedom, and Zero Trust security simultaneously, with the technical depth and enterprise scale FSI requires.
## Conclusion: The Path to Sovereignty
Data sovereignty is no longer optional for financial services. **DORA**, **NIS2**, **GDPR**, and the **EU AI Act** create overlapping requirements that demand governed streaming, deployment freedom, and Zero Trust security. Most streaming platform vendors deliver one or two of these capabilities. FSI organizations need all three.
The vendor landscape presents a clear pattern. Cloud-only platforms cannot serve Tier 1 FSI. Vendor-managed platforms face audit, subcontracting, and exit challenges under DORA. Proprietary lock-in conflicts with regulatory requirements for clear exit strategies. Premium pricing for compliance features treats sovereignty as an upsell rather than a baseline requirement.
### Next Steps for FSI Organizations
1. **Assess current sovereignty posture**: Evaluate existing streaming infrastructure against the three-pillar framework
1. **Map regulatory requirements**: Identify which DORA, NIS2, and AI Act provisions apply to your organization
1. **Evaluate vendor sovereignty**: Apply the decision framework to current and prospective vendors
1. **Plan deployment path**: Determine whether managed, BYOC, or on-premises best fits your requirements
1. **Build exit capability**: Ensure contracts and architecture support migration if needed
### The Three Pillars, One Platform
[Ververica](https://www.ververica.com/?hsLang=en) delivers governed streaming, deployment freedom, and Zero Trust security on a single platform built by the creators of Apache Flink. No vendor lock-in. No sovereignty compromises. No compliance gaps.
## The Three Pillars, One Platform
Ververica delivers governed streaming, deployment freedom, and Zero Trust security on a single platform built by the creators of Apache Flink. No vendor lock-in. No sovereignty compromises. No compliance gaps.
See [How Ververica Delivers Sovereignty for Financial Services](https://www.ververica.com/how-ververica-delivers-sovereignty-for-financial-services-industry?hsLang=en) for the full technical details, deployment models, and real-world FSI case studies.
## FAQ
### What does data sovereignty mean for financial services in 2026?
Data sovereignty extends beyond data residency. It encompasses infrastructure control (who owns and operates systems processing your data), audit access (whether regulators can inspect systems and data flows), third-party oversight (how dependencies on external providers are managed), and exit capability (whether you can migrate without losing functionality or facing prohibitive costs). DORA Article 28 mandates that financial entities ensure their ICT service providers comply with regulatory standards and maintain exit strategies.
### What are the three pillars of FSI streaming sovereignty?
The three pillars are: (1) Governed Streaming: real-time data lineage, schema enforcement, and compliance monitoring purpose-built for streaming workloads; (2) Deployment Freedom: the ability to deploy streaming infrastructure where regulatory requirements demand, whether vendor-managed cloud, BYOC, or on-premises; (3) Zero Trust Security: identity-centric protection with continuous verification, not perimeter-based defense. Most vendors deliver one or two; financial institutions need all three.
### Why do vendor-managed streaming platforms fail DORA compliance?
Vendor-managed platforms face three key DORA compliance challenges: (1) Audit Rights: DORA Article 28 requires providers accept regular security audits, but vendor-managed platforms may limit inspection access due to multi-tenant architecture; (2) Subcontracting: DORA requires assessing risks from subcontractors in the ICT supply chain, but cloud platforms have complex, opaque dependency chains; (3) Exit Strategies: DORA mandates clear exit strategies, but proprietary vendor platforms create steep migration costs and vendor lock-in.
### What are the sovereignty differences between Tier 1 and Tier 2 FSI?
Tier 1 FSI (G-SIBs, Central Banks) face the strictest requirements: complete infrastructure control often requiring on-premises deployment, unrestricted audit access, domestic data residency with no exceptions, and zero tolerance for vendor lock-in. Tier 2 FSI (Regional Banks, Payment Processors, Asset Managers) require compliant third-party management under DORA Article 28, clear exit strategies, proportionate resilience testing, and the option for on-premises or hybrid deployment.
---
---
title: "Privacy Policy"
description: "Discover how Ververica collects, uses, and protects your personal data in compliance with GDPR, ensuring transparency and security across all services."
lastUpdated: 2026-09-11T09:46:19.000Z
source_url:
html: "https://www.ververica.com/privacy-policy"
md: "https://www.ververica.com/privacy-policy.md"
---
# Privacy Policy
**Last update: August 1st 2025**
## 1. NAME AND CONTACT DETAILS OF THE CONTROLLER AS WELL AS OPERATIONAL DATA PROTECTION OFFICER
This data privacy policy shall apply to data processing activities by the following controller:
Ververica GmbH (hereinafter referred to as “**Ververica**”), Herzogspitalstrasse 24, 80331 München, Germany.
For any data protection-related inquiries, please contact us at [dataprotection@ververica.com](mailto:dataprotection@ververica.com).
## 2. COLLECTION AND STORAGE OF PERSONAL DATA AS WELL AS THE NATURE AND PURPOSE OF THEIR PROCESSING
1. When Visiting Ververica’s Websites This data privacy policy applies for Ververica’s following websites, and your consent to our use of cookies (see section 4 below) applies to the same websites:
[www.ververica.com](https://www.ververica.com), [www.flink-forward.org,](https://www.flink-forward.org) [www.ververica.cloud](https://www.ververica.cloud), [app.ververica.cloud](https://app.ververica.cloud), [www.ververica.academy](https://www.ververica.academy), [docs.ververica.com](https://docs.ververica.com/), [asia.flink-forward.org](https://asia.flink-forward.org/), [streamhouse.com](https://streamhouse.com/), [fluss-forward.org](https://www.fluss-forward.org/) [stream-forward.org](https://stream-forward.org/) (each a “**Website**”) When calling our Website, the browser used on your end device will automatically send information to the server of our Website. This information is temporarily stored in a so-called log file. The following information is recorded without any action on your end and stored until automated erasure after 6 months:
- internet protocol address of the requesting computer
- date and time of the access
- name and URL of the file retrieved
- website from which the access takes place (referrer URL)
- browser used and, if applicable, the operating system of your computer and the name of your access provider
1. The data mentioned are processed by us for the following purposes:
- ensuring smooth establishment of the Website’s connection
- ensuring comfortable use of our Website
- evaluation of system safety and stability, as well as
- other administrative purposes
1. The legal basis for these data processing activities is Article 6(1)(f) of the General Data Protection Regulation (“**GDPR**”). Our legitimate interests follow from the purposes listed above for data collection. Furthermore, we use cookies and analysis services when you visit our Website. More detailed explanations on this can be found in sections 4 and 5 of this data privacy policy.
1. Subscribing to our Newsletter If you have explicitly consented pursuant to Article 6(1)(a) GDPR, we will use your email address to send you our newsletter at regular intervals. If you acquire any goods or services from us and provide your email address for this, such address may be used by us for sending out a newsletter subsequently. In this case, the newsletter is only used to send out direct marketing for own similar goods or services. The legal basis for sending out the newsletter due to sale of goods or services shall be § 7 para. 3 of the Gesetz gegen den unlauteren Wettbewerb (the Act Against Unfair Competition) in conjunction with Article 6(1)(f) GDPR in such a case. Our legitimate interests follow from the interest in direct marketing vis-à-vis our existing customers. Unsubscription is possible at any time, independently of whether the newsletter was sent based on consent or based on our legitimate interest in direct marketing, e.g. by using a link at the end of each newsletter. As an alternative, you may also send your unsubscription request to us at any time by email to: [info@ververica.com](mailto:info@ververica.com). The only costs resulting from this are the transfer costs according to the basic rates. The personal data required for sending out the newsletter shall be erased as soon as they are no longer required for achieving the purpose of their collection and as far as no other legal authorization basis applies for further processing, such as for customer management purposes. Your email address for sending out the newsletter will be stored until you revoke your consent or until you object to submission of the newsletter.
1. When Using our Contact Form and Email Contact If there are any questions, we offer the option of contacting us using a form provided on the Website. A valid email address must be indicated there, so that we will know where the query comes from and to answer such. Further information can be provided freely. Alternatively, contact via the provided email address is possible. In such a case, your personal data transmitted in the email will be stored. Data processing activities for the purpose of contacting is carried out according to Article 6(1)(f) GDPR. Our legitimate interests follow from our interest in responding to inquiries. If the contact is targeted at the conclusion of a contract, Article 6(1)(b) GDPR shall be the legal basis for processing. As far as no other legal basis is applicable in regard to any further processing of your personal data, the personal data collected by us for the above purposes shall be erased after completion of the request submitted by you.
1. Downloading of Free Material We provide free download files on our Website, such as whitepapers, software trial versions and other marketing material. As part of the download, we ask for personal data such as name, first name, organization, and email address. The legal basis for data processing is Article 6(1)(b) GDPR. Your data will be automatically deleted upon termination of the customer relationship, unless another legal basis for any further processing of such data is applicable.
1. When Making Purchases on Website At Ververica, we value your privacy and are committed to protecting your personal data when you make purchases on our website. This Privacy Policy outlines how we collect, use, disclose, and protect the information you provide to us during the purchase process, in compliance with the General Data Protection Regulation (GDPR).
1. Information Collection: When you make a purchase on our Websites, we may collect certain personal data such as your name, billing and shipping addresses, contact details, payment information (except cardholder data) and transaction history. We may collect this information to process your order, deliver products/services, and communicate with you regarding your purchase.
1. Data Usage and Storage: We use the personal data you provide solely for the purpose of fulfilling your purchase order. This may include verifying your identity, processing payments, arranging delivery, and providing customer support. We retain your information only as long as necessary to complete the transaction and comply with legal obligations.
1. Third-Party Service Providers: To ensure smooth and secure purchase transactions, we may engage trusted third-party service providers. These providers may have access to your personal data only to the extent necessary to perform their services for us. We carefully select and enter into agreements with these providers to ensure they adhere to the same level of privacy and data protection standards as required by the GDPR.
1. Data Security: We implement appropriate technical and organizational measures to safeguard your personal data against unauthorized access, alteration, disclosure, or destruction. We use secure payment gateways and encryption protocols to protect your financial details during the purchase process.
1. Marketing Communications: We may use your email address to send you transactional and service-related communications, such as order confirmations and shipping updates. With your explicit consent, we may also send you marketing communications about our products, promotions, and special offers. You can unsubscribe from marketing communications at any time by following the instructions provided in the email or contacting our customer support.
1. Data Subject Rights: Under the GDPR, you have the right to access, rectify, and delete the personal data we hold about you. If you would like to exercise any of these rights or have questions regarding our privacy practices, please contact our Data Protection Officer using the contact details provided at the end of this policy. We regularly review and update our privacy practices to ensure compliance with applicable laws and provide transparency about our data processing activities. By making a purchase on our Websites, you acknowledge and consent to the collection, use, and storage of your personal data as described in this Paragraph e.
1. When using our Ververica Academy Services We engaged Northpass, by Gainsight (https://www.northpass.com, “**Northpass**”) to provide certain services constituting or supporting our Ververica Academy training services, among others (collectively, “**Academy Services**”), including but not limited to the provision of learning management platform. You may be redirected to Northpass’s website, mobile applications and/or other online systems to manage and use relevant parts of the Academy Services. In that case Northpass may have its own and separate Privacy Policy with you which differs from this Privacy Policy of Ververica. You shall carefully read such separate Privacy Policy documents bearing in mind that Ververica does not decide nor contribute to such documents and related processing of personal data, therefore cannot be liable for such documents and any processing activities of personal data thereunder. We engaged Credly (https://info.credly.com, “**Credly**”) to provide certain services constituting or supporting the Academy Services, including but not limited to the provision of learning management platform and digital credentialing. You may be redirected to Credly's website, mobile applications and/or other online systems to manage and use relevant parts of the Academy Services. In that case Credly may have its own and separate Privacy Policy with you which differs from this Privacy Policy of Ververica. You shall carefully read such separate Privacy Policy documents bearing in mind that Ververica does not decide nor contribute to such documents and related processing of personal data, therefore cannot be liable for such documents and any processing activities of personal data thereunder. We engaged Stripe (https://stripe.com, “**Stripe**”) to provide payment processing services. You may be redirected to Stripe's website, mobile applications and/or other online systems to render your payments and manage your payment information, including cardholder information, which is not collected nor processed by Ververica. In that case Stripe may have its own and separate Privacy Policy with you which differs from this Privacy Policy of Ververica. You shall carefully read such separate Privacy Policy documents bearing in mind that Ververica does not decide nor contribute to such documents and related processing of personal data, therefore cannot be liable for such documents and any processing activities of personal data thereunder.
## 3. PASSING ON DATA
We shall only pass on your personal data to third parties (“**Recipients**”) if we are entitled to do so under the provisions of data protection law. Below we inform you about the circumstances in which this may be the case. We can pass on your personal data to Recipients, if:
- you have explicitly given consent to such for one or more specific purposes (Article 6(1)(a) GDPR);
- processing is necessary for the performance of a contract to which you are a party or in order to take steps at your request prior to entering into a contract (Article 6(1)(b) GDPR); processing is necessary for compliance with a legal obligation to which we are subject (Article 6(1)(c) GDPR);
- processing is necessary for the purposes of the legitimate interests pursued by us or by a third party, except where such interests are overridden by your interests or fundamental rights and freedoms which require protection of personal data (Article 6(1)(f) GDPR);
- we work together with the following third parties as data processor in accordance with Article 28 GDPR:
- Amazon Web Services, Inc.
- Zendesk, inc.
In particular, we pass on personal data to the following (categories) of Recipients:
- Providers of tools used on our Website (for more details see section 5 of this data privacy policy)
- Hosting providers other than providers of the tools used on our Website
Specifically, we pass on personal data to the following listed third-party providers in order to create accounts, assign learning courses, and issue digital learning credentials:
- HubSpot (https://www.hubspot.com) is Customer Relationship Management (CRM) platform that includes software, integrations, and resources for marketing, sales, content management, and customer service.
- NorthPass, by Gainsight (https://www.northpass.com) is a cloud-based online learning platform designed for interactive learning and training courses.
- Credly (https://info.credly.com) is an end-to-end solution for creating, issuing, and managing digital credentials.
Specifically, the personal data shared to the above listed third-party providers is:
- First Name
- Last Name
- Email Address
We intend to transfer the personal data to third countries. In particular, we may transfer personal data to countries outside the EEA, in particular the USA. There is no adequacy decision by the EU-Commission with regards to most of these countries, in particular the USA. Our data transfers into such countries are covered by standard contractual clauses. You may obtain more details on the transfer of your personal data and a copy of the used standard contractual clauses from our data protection officer.
## 4. COOKIES
We use cookies on our Website. These are small files that your browser will create automatically and that are stored on your end device (laptop, tablet, Smartphone or similar) when you visit our Website. Cookies do not cause any damage to your end device, contain no viruses, Trojans, or other harmful software.
The cookie is used to store information that results from the respective context of the specifically used end device.
Use of cookies serves to make use of our offer more pleasant for you. We use session cookies in order to recognize that you have visited individual pages of our Website before. They will be deleted automatically after you leave our Website.
Furthermore, we also use temporary cookies to optimize user friendliness which are stored on your end device for a certain specified period. When you visit our Website again in order to use our services, it will be automatically recognized that you have visited us before and which input and settings you have made so that you will not have to enter them again.
We also use cookies in order to statistically record use of our Website and to evaluate it for the purpose of optimizing our offer to you (see section 5). These cookies enable us to recognize that you have visited us before if you visit our Website again. These cookies are deleted automatically after two years in each case.
Where the storage or access to cookies on your end device is necessary in order for us to be able to provide our Website or the services provided thereon and expressly requested by you (strictly necessary cookies), we do not require your consent for this. Where this is not the case, we will ask for your consent. Most browsers accept cookies automatically. You may, however, configure your browser so that no cookies will be stored on your computer or that you will always be informed before a new cookie is set up. Complete deactivation of cookies may, however, render you unable to use all functions of our website.
## 5. WEBSITE TOOLS
1. Cookiebot We use the consent management service Cookiebot, provided by Usercentrics A/S, Havnegade 39, 1058 Copenhagen, Denmark (Usercentrics). This allows us to obtain and manage consent from Website users for data processing. The processing is necessary for the fulfillment of a legal obligation to which we are subject (Art. 6 (1)(c) GDPR). For this purpose, the following data is processed with the help of cookies:
- Your IP address (the last three digits are set to '0')
- Date and time of consent
- Browser information
- URL from which the consent was sent
- An anonymous, random, and encrypted key
- Your end-user consent status, as proof of consent.
1. The key and consent status are stored in the browser for 12 months using the "CookieConsent" cookie. This preserves your cookie preference for subsequent page requests. With the help of the key, your consent can be proven and tracked. If you enable the "Collective Consent" service feature to enable consent for multiple web pages through a single end-user consent, the service will also store a separate, random, unique ID with your consent. If all the following criteria are met, this key is stored in the third-party cookie "CookieConsentBulkTicket" in your browser in encrypted form:
- You enable the collective consent feature in the service configuration.
- You allow third-party cookies via browser settings.
- You have disabled "Do not track" via browser settings.
- You accept all or at least certain types of cookies when you give consent.
1. Usercentrics is a recipient of your personal data and acts as a processor for us. Your personal data will be deleted on an ongoing basis after 12 months or immediately after termination of the contract between us and Usercentrics. Please refer to to Cookiebot’s privacy policy for more details:
https://www.cookiebot.com/en/privacy-policy/
1. Analytics
1. Google Analytics This Website uses Google Analytics, a web tracking service provided by Google Ireland Limited, Gordon House, Barrow Street, Dublin 4, Ireland ("**Google**"). The purpose of our use of the tool is to enable the analysis of your user interactions on the Website and to use the statistics and reports obtained to improve our offer and make it more interesting for you as a user. We collect the interactions between you as a user of the Website and our Website primarily with the help of cookies, device/browser data, IP addresses and Website activities. Google Analytics also collects your IP addresses to ensure the security of the service and to provide us, as the Website provider, with information about the country, region, or location from which the respective user originates (so-called "**IP location determination**"). However, we use the anonymization function ("**IP masking**"), i.e. that Google truncates the IP addresses by the last octet within the EU/EEA. We have concluded a data processing agreement with Google. The information generated by the cookie and the IP addresses about your use of this Website are usually transferred to a Google server in the USA or in other countries (including countries which do not provide an adequate level of data protection) and processed there. For these cases, Google has contractually undertaken to enter into so-called standard contractual clauses with the data recipients in third countries. For more information on international data transfers please refer to section 3 of this data privacy policy. The legal basis for the collection and further processing of the information (which takes place for a maximum of 14 months) is your given consent (Art. 6 (1)(a) GDPR). The revocation of your consent is possible at any time, without affecting the permissibility of the processing until the revocation. The easiest way to revoke your consent is to use our Consent Manager, or to click here to install the opt-out browser add-on, which can also be accessed via the following link: https://tools.google.com/dlpage/gaoptout?hl=en/. Please refer to Google’s privacy policy for more details: www.google.de/intl/de/policies/privacy/.
1. HubSpot We use the services HubSpot, 25 First Street, 2nd Floor, Cambridge, MA 02141, USA, a software company from the USA (“**HubSpot**”). HubSpot is a service platform. The service is an integrated software solution that allows us to manage customer data and cover various aspects of our online marketing. This includes, among other things, the analysis of landing pages and reporting. In the process, cookies are stored on the end device used by you. We use HubSpot to analyze the use of our Website. This allows us to constantly optimize our Website and make it more user-friendly. We also use information to determine which of our services are of interest to customers and newsletter subscribers and to contact them for advertising purposes. In addition, we use the analysis to optimize our Website for you. In the process, the following personal data may be collected, for example:
- IP address
- Geographical location
- Type of browser
- Duration of the visit
- Pages viewed
1. However, we only use your IP address in a shortened version. This means that the IP address of the user is shortened by HubSpot within member states of the European Union or in other contracting states of the Agreement on the European Economic Area. The collected information is stored on servers in the European Union. However, personal data are also transferred to the USA and other third countries. For more information on international data transfers please refer to section 3 of this data privacy policy. The cookies have a usual lifetime of 13 months. In addition, we delete the personal data collected via HubSpot as soon as the purpose for which it was collected has been achieved, unless deletion conflicts with legal retention periods. The data processing is based on your consent pursuant to Art. 6 (1)(a) GDPR. You can revoke your consent at any time. Please follow this link. Please refer HubSpot’s privacy policy for more details: https://legal.hubspot.com/privacy-policy
1. Google Tag Manager We use the Google Tag Manager, a service provided by Google Ireland Limited, Gordon House, Barrow Street, Dublin 4, Ireland. The Google Tag Manager is a tool that allows us to integrate tracking or statistical tools and other technologies on our website. The Google Tag Manager itself does not create user profiles, does not store cookies, and does not perform any independent analyses. It only serves to manage and play out the tools integrated via it.
1. Reo.Dev We use the services of ReoDotDev Inc (108W. 13th Street, Suite 100, Wilmington, New Castle county, Zip 19801, Delaware, USA) to analyze the use of our Website. This helps us understand which of our services are of interest to users and improve our product offering In the process, the following personal data may be collected, for example:
- IP address
- Geographical location
- Type of browser
- Duration of the visit
- Pages viewed
1. Please refer ReoDotDev's privacy policy for more details: [https://www.reo.dev/privacy-policy](https://www.reo.dev/privacy-policy)
1. DoubleClick for GoogleAds This Website uses the online marketing tool DoubleClick from Google Ireland Limited, Gordon House Barrow Street Dublin 4, Ireland (hereinafter: “**Google**”). DoubleClick uses cookies to serve ads that are relevant to users, to improve campaign performance reports, or to prevent a user from seeing the same ads more than once. Via a cookie ID, Google records which ads are displayed in which browser and can thus prevent them from being displayed more than once. In addition, DoubleClick can use cookie IDs to record so-called conversions that are related to ad requests. This is the case, for example, when a user sees a DoubleClick ad and later calls up the advertiser's website with the same browser and buys something there. According to Google, DoubleClick cookies do not contain any personal data. Due to the marketing tools used, your browser automatically establishes a direct connection with the Google server. We have no influence on the scope and further use of the data collected by Google through the use of this tool and therefore inform you according to our state of knowledge: Through the integration of DoubleClick, Google receives the information that you have called up the corresponding part of our Website or clicked on an ad from us. If you are registered with a Google service, Google can assign the visit to your account. Even if you are not registered with Google or have not logged in, there is the possibility that Google learns your IP address and stores it. You can prevent participation in this tracking process in several ways:
1. by setting your browser software to suppress third-party cookies which will result in you not receiving third-party ads;
1. by disabling conversion tracking cookies by setting your browser to block cookies from the domain www.googleadservices.com (https://www.google.de/settings/ads). This setting will be deleted when you delete your cookies;
1. by permanent disabling in your Firefox, Internet Explorer or Google Chrome, or any other applicable browsers (more information available under http://www.google.com/settings/ads/plugin )
1. Your personal data can also be transferred for further processing to the USA or other third countries which do not provide an adequate level of data protection. For more information on international data transfers please refer to section 3 of this data privacy policy. The legal basis for the processing of your data is your consent, Art. 6 (1)(a) GDPR). Please refer to Google’s privacy policy for more details: https://policies.google.com/privacy.
## 6. SOCIAL MEDIA
This Website offers the possibility to share content on social networks (Facebook, Twitter. LinkedIn and Reddit). This is realized through sharing buttons on our Website. These are integrated into our Website via HTML-links and are inactive at first, but they will get activated once you click on them. If you click on one of the buttons, a new window of your browser opens and calls up the page of the respective social media platform on which you can (if necessary, after entering your login data) e.g. click a like or share button. Only then a network connection to the respective social media platform will be established and cookies of the respective social media platform will be stored on your computer. This will enable the social media platform to receive certain information about you and your visit to our Website, such as the IP address, your user account with the social media platform, and the Website you have visited. This can lead to your personal data being transferred for further processing to the USA or other third countries which do not provide an adequate level of data protection. For more information on international data transfers please refer to section 3 of this data privacy policy.
The legal basis for the processing of your personal data in this regard is your consent under Art. 6 (1)(a) GDPR which you provide by clicking on the respective sharing button.
Please see below for more details about the respective social media platform:
1. Facebook: Facebook Inc., 1601 S. California Ave, Palo Alto, CA 94304, USA; privacy policy available at https://www.facebook.com/privacy/policy/?entry_point=data_policy_redirect&entry=0
1. X: X Corp., 1355 Market St, Suite 900, San Francisco, CA 94103; privacy policy available at https://twitter.com/en/privacy
1. LinkedIn: LinkedIn Ireland Unlimited Company, Wilton Plaza, Wilton Place, Dublin 2, Ireland; privacy policy available at https://www.linkedin.com/legal/privacy-policy
1. Reddit: Reddit Ireland Limited, Georges Quay Plaza, Floor 2 - 101, Dublin D02 F856, Ireland; privacy policy available at https://www.reddit.com/policies/privacy-policy
## 7. RIGHTS OF THE DATA SUBJECT
You have the right:
1. to demand information regarding the processing of your personal data by us and a copy of the personal data undergoing processing in accordance with Article 15 GDPR. In particular, you may request information on the purposes of the processing, the categories of personal data, the (categories of) recipients to whom your data have been or are disclosed, the envisaged storage period or, if not possible, the criteria used to determine that period, the existence of the right to rectification, erasure, restriction of processing or objection, the right to lodge a complaint, the source of your data to the extent that these were not collected from you, and the existence of automated decision-making, including profiling and any meaningful information on its details; where personal data are transferred to a third country or to an international organisation, you have the right to be informed of the appropriate safeguards relating to the transfer;
1. in accordance with Article 16 GDPR, obtain the rectification of any inaccurate personal data stored by us or completion of such data without undue delay.
1. in accordance with Article 17 GDPR, obtain the erasure of your personal data stored by us, unless the processing is required for exercising the right of freedom of expression and information, for compliance with a legal obligation, for reasons of public interest, for archiving purposes in the public interest, scientific or historical research purposes or statistical purposes, or for the establishment, exercise or defense of legal claims;
1. in accordance with Article 18 GDPR, obtain the restriction of processing of your personal data, to the extent that the accuracy of the data is contested by you, processing is unlawful, but you oppose erasure, we no longer need the personal data, but you still require them for the establishment, exercise or defense of legal claims, or you have objected to processing pursuant to Article 21 GDPR pending the verification whether our legitimate grounds override yours;
1. in accordance with Article 20 GDPR, demand to receive your personal data that you have provided to us in a structured, commonly used and machine-readable format or to demand transmission to another controller;
1. in accordance with Article 7 (3) GDPR, to withdraw your consent once given to us towards us at any time. This has the consequence that we may no longer continue the data processing activities that were based on this consent in future but that the withdrawal of consent does not affect the lawfulness of processing based on consent before its withdrawal, and
1. in accordance with Article 77 GDPR, lodge a complaint with a supervisory authority. Usually, you may contact the supervisory authority at your habitual residence or place of work or our registered office for this.
## 8. RIGHT TO OBJECT
As far as your personal data are processed based on legitimate interests in accordance with Article 6(1)(f) GDPR, you have the right to object to processing of your personal data in accordance with Article 21 GDPR, to the extent that there are grounds relating to your particular situation. We will no longer process the personal data unless
1. we demonstrate compelling legitimate grounds for the processing which override your interests, rights and freedoms, or
1. for the establishment, exercise or defense of legal claims.
Where personal data are processed for direct marketing purposes, you have the right to object at any time to processing of personal data concerning you for such marketing. If you want to exercise your withdrawal right or right to object, simply send us an email to [dataprotection@ververica.com](mailto:dataprotection@ververica.com).
## 9. FURTHER INFORMATION
In accordance with Art. 13 (2)(e) GDPR we would like to inform you about the following: Unless stated otherwise in this data privacy policy, the provision of personal data is neither a statutory nor contractual requirement, nor a requirement necessary to enter into a contract, and you are not obliged to provide the personal data.
## 10. DATA SECURITY
Within the website visit, we use SSL/TLS with at least TLS 1.2. Whether an individual Website is transmitted encrypted or not is evident by the closed display of the key or lock symbol in the lower status bar of your browser. Apart from this, we use appropriate technical and organizational security measures in order to protect your data from accidental or willful manipulation, partial or complete loss, destruction or unauthorized access by third parties. Our security measures will be improved continually according to the technological developments.
## 11. TOPICALITY AND CHANGES OF THIS DATA PRIVACY POLICY
This data privacy policy is currently valid as of 10 July 2023. Further development of our Website and offers through it or changed statutory or authority specifications may require changes to this data privacy policy. You may call and print the respective current data privacy policy at any time on the website at https://www.ververica.com/privacy-policy.
---
---
title: "Sovereignty Evaluation Framework - Checklis"
description: ""
lastUpdated: 2026-04-17T06:14:04.000Z
source_url:
html: "https://www.ververica.com/data-sovereignty/streaming-sovereignty-self-assessment-technical-audit"
md: "https://www.ververica.com/data-sovereignty/streaming-sovereignty-self-assessment-technical-audit.md"
---
# A Technical Evaluation Framework for Streaming Platform Sovereignty Compliance
## How to Use This Checklist
For each requirement, answer the assessment questions using **Yes**, **No**, or **Partially**. The compliance status updates automatically based on your answers. Use this during vendor evaluations to identify sovereignty gaps systematically.
---
---
title: "Ecosystem Introduction"
description: "Your Guide to the Ververica's Unified Streaming Data Platform Ecosystem "
lastUpdated: 2026-04-15T12:04:18.000Z
source_url:
html: "https://www.ververica.com/ecosystem-introduction"
md: "https://www.ververica.com/ecosystem-introduction.md"
---
# Ecosystem Introduction
**Your Guide to the Ververica's Ecosystem**
### What is Apache Flink®?
Discover Apache Flink, a powerful framework for real-time stream processing and analytics, enabling event-driven applications and dynamic decision-making.
### Beginner's Guide to Real-Time Data Processing
Unlock real-time, fault-tolerant data pipelines using stream processing with Apache Flink. Discover key concepts, tools, and more with Ververica
### What is Apache Paimon™?
Explore Apache Paimon, the open-source, stream-native data lakehouse format. Learn how it powers real-time updates, unified analytics with Ververica.
### What is Apache Fluss™?
Learn more about Apache Fluss, the open-source, unified streaming storage layer designed to optimize real-time data processing.
### What is VERA?
Discover VERA, Ververica's high-performance engine that optimizes Apache Flink for seamless real-time and batch data processing
### What is Streamhouse?
Streamhouse unifies batch and stream processing on data lakes, enabling real-time insights and cost-effective analytics for businesses.
### Stream Processing vs. Batch Processing
Apache Flink blends batch and stream. Ververica delivers the enterprise tools to run unified data workloads reliably, efficiently, and at scale.
---
---
title: "What is Streamhouse?"
description: "Streamhouse unifies batch and stream processing on data lakes, enabling real-time insights and cost-effective analytics for businesses."
lastUpdated: 2026-04-15T12:54:35.000Z
source_url:
html: "https://www.ververica.com/ecosystem-introduction/what-is-streamhouse"
md: "https://www.ververica.com/ecosystem-introduction/what-is-streamhouse.md"
---
# What is Streamhouse?
Streamhouse unifies batch and stream processing on data lakes, enabling real-time insights and cost-effective analytics for businesses.
### Bridging the Gap Between Real-Time and Historical Data
> **INFO:** Streamhouse, a streaming lakehouse concept introduced by Ververica, unifies batch and stream processing on a data lake. It combines Apache Flink® for compute with Apache Paimon™ for stream-native storage to deliver near real-time results, cost-efficiency, and simplified data architectures. Essentially, it allows businesses to leverage the benefits of a data lake (cost, scalability) with the speed and real-time capabilities of stream processing, making current and historical data immediately accessible for analytics and event-driven architecture.
Businesses are constantly seeking more efficient and cost-effective ways to harness their vast amounts of data. The traditional divide between batch processing for historical data and stream processing for real-time insights often leads to complex, siloed, and expensive data architectures. This is where Streamhouse, also known as Streaming Lakehouse, emerges as a transformative solution. At its core, Streamhouse is Ververica's innovative approach that unifies batch and stream processing, allowing organizations to achieve near real-time results on their data lake while maintaining cost-efficiency and simplifying their data infrastructure.With Streamhouse, businesses can get the best of both worlds: accessing the power and cost-effectiveness of their traditional Data Lakehouse at the speed of real-time streaming. With Streamhouse, you can fill the gap between traditional streaming and batch architectures, getting stream processing capabilities while maintaining (near) real-time results on the Data Lake.
## Why Streamhouse? The Evolution of Data Architectures.
For years, organizations have grappled with the challenges of managing increasingly large and diverse datasets. The rise of machine learning (ML), artificial intelligence (AI), and the escalating demand for real-time decision-making intensify the need for immediate data insights. Traditionally, this led to two distinct data paradigms:
- **Data Warehouses:** Optimized for structured data and complex analytical queries, but often expensive and not well-suited for unstructured data or real-time ingestion.
- **Data Lakes:** Excellent for storing vast amounts of raw, diverse data at low cost, but typically required separate processing engines for different data types and lacked strong ACID (Atomicity, Consistency, Isolation, Durability) guarantees.
- **Real-Time Streaming Architectures:** Built for low-latency processing and immediate insights, essential for event-driven architecture, but can be expensive and resource-intensive to maintain at scale.
While Data Lakehouses bridge the gap between data warehouses and data lakes, offering cost-effective storage with analytical capabilities, they still primarily focus on batch processing and struggle to deliver real-time insights effectively. This creates a significant void: businesses need a solution that seamlessly unifies real-time and batch processing without compromising on performance, cost, or complexity.
This unaddressed need is the key driver behind the Streamhouse evolution. Ververica recognizes that to truly empower businesses, a solution is required that provides fast, fresh data while leveraging the cost benefits of data lakes. Streamhouse capabilities address these limitations, simplifying architecture, reducing operational complexity and infrastructure costs, and empowering businesses to harness the full potential of their data. As explored in the [Streamhouse Evolution blog](https://www.ververica.com/blog/streamhouse-evolution?hsLang=en), it is about moving beyond the "deadlock" of separate systems to a cohesive, unified platform.
## What is Streamhouse? The Core Concept
The Streamhouse concept is straightforward yet revolutionary: it combines the best aspects of traditional Data Lakehouses with the agility and speed of real-time streaming. It's designed to process and analyze vast amounts of data in real-time while simultaneously allowing for deep analytical queries on historical data, all within a single, integrated platform.
At its technical heart, Ververica’s Streamhouse capabilities leverage a powerful combination of open-source technologies:
- **Apache Flink for Unified Compute**: Apache Flink is a powerful Open Source stream processing framework for data stream processing and distributed stateful computations on large-scale data streams. In Streamhouse, Flink serves as the unified compute engine, capable of processing both continuous streams and historical batch data. This allows for flexible and powerful stream processing with Apache Flink.
- **Flink Change Data Capture (CDC) for Unified Ingestion**: Flink CDC enables efficient and real-time capture of data changes from various operational databases (like MySQL or Postgres) directly into the Streamhouse. This ensures that data is ingested and made available for processing almost instantaneously.
- **Apache Paimon for Unified Lakehouse Storage**: Apache Paimon provides a streaming storage layer that allows Flink to perform stream processing directly on the data lake. Paimon offers ACID transactions, schema evolution, and efficient data versioning, bringing data warehouse capabilities to the low-cost, scalable data lake. Its role is crucial in enabling the unified approach to data management within Streamhouse.
This powerful synergy allows Streamhouse to bridge the cost/latency gap, providing near real-time results on the data lake by merging the cost-efficiency of data lakes with the speed of real-time data.
## Key Benefits
Ververica’s Streamhouse is part of the Unified Streaming Data Platform, and features several key value propositions that make it a compelling technology to address modern data challenges:
- **Significant Latency Improvement**: Streamhouse offers a substantial reduction in latency, transforming high-latency batch jobs (which might take days) to near real-time results (within minutes). This dramatic improvement is crucial for businesses that rely on fresh data for timely decisions.
- **Flexibility with Flink SQL**: By leveraging Flink SQL, users gain the flexibility to seamlessly transition between Streamhouse capabilities and pure real-time streaming based on their evolving business requirements. This adaptability ensures that the solution can grow and change with an organization's needs.
- **Cost-Effectiveness and ROI Assessment**: Streamhouse provides a more efficient, cost-effective, and low-risk method for system upgrades. It allows businesses to assess suitability and ROI by running operations and gauging results before committing to full real-time streaming, offering a balanced approach between cost and latency.
- **Seamless Migration**: The unified Flink engine and Flink SQL facilitate seamless migration, minimizing the effort involved in upgrading from traditional Lakehouse architectures to Streamhouse and potentially to full real-time streaming pipelines.
- **Optimized Performance and Resource Efficiency**: Streamhouse can significantly cut costs compared to always-on real-time streaming for use cases where minute-level data latency is acceptable. Furthermore, employing streaming preprocessing within Streamhouse yields **five times better write** performance and **eight times better query performance** compared to traditional batch Lakehouses..
- **Enhanced Data Freshness:** By continuously processing and updating data on the data lake, Streamhouse ensures that analytical queries always reflect the freshest available information, making it an ideal choice for data stream processing needs.
- **Simplified Architecture**: Consolidating batch and stream processing into a single platform reduces architectural complexity, making systems easier to build, maintain, and scale.
## Common Data Processing Patterns Enabled by Streamhouse
Because Streamhouse combines the capabilities of Apache Flink, Flink CDC, and Apache Paimon, it enables a variety of crucial data stream processing patterns directly on the data lake. These patterns are designed to provide near real-time results and significantly reduce engineering maintenance efforts:
- **Event Deduplication:** Eliminating duplicate events is critical for data quality. Streamhouse achieves this using Apache Paimon's deduplicate and first-row merge engines, ensuring data integrity.
- **Table Widening**: The partial-update merge engine in Paimon allows users to update specific columns of a record through multiple updates without resorting to expensive streaming joins, streamlining data enrichment processes.
- **Out-of-Order Event Handling:** Real-world data often arrives out of sequence. Streamhouse addresses this by allowing users to specify sequence fields and sequence groups, guaranteeing data correctness even when events arrive late.
- **Automatic Aggregations:** For business analysis, Streamhouse supports automatic aggregations, making it easier to derive summary insights from large datasets.
- **Time Travel Capabilities:** Leveraging snapshots and tags, Streamhouse allows users to query previous versions of data, which is invaluable for auditing, debugging, and historical analysis.
- **CDC Data Lake Ingestion with Schema Evolution:** Streamhouse provides robust integration with CDC connectors for various databases, automatically handling schema changes as data evolves, ensuring seamless data ingestion into the data lake.
- **Data Enrichment with Lookup Joins:** Streamhouse supports data enrichment by building RocksDB indexes within Paimon for improved performance and allowing asynchronous lookups with retries for late-arriving records.
## Building Real-Time Data Views with Streamhouse
One of the most compelling applications of Ververica’s Unified Streaming Data Platform Streamhouse capabilities is its ability to facilitate the creation of real-time data views. This is achieved through a streamlined, three-stage pipeline: ingestion, aggregation, and visualization.
- **Ingestion:** Data from diverse sources, including message queues like Kinesis and Kafka, or relational databases via Flink CDC, is efficiently ingested into the Streamhouse environment. This data is then stored in Paimon tables. Notably, "Append Only" Paimon tables can even replace message queues for intermediate data ingestion, offering a more persistent and queryable storage layer.
- **Aggregation:** Once ingested, data is joined and processed to build aggregated data tables. For instance, you can calculate revenue per country by joining order and customer data. Paimon's features, such as merge-engine=aggregation and changelog-producer=full-compaction, enable automatic aggregation and efficient change log management, ensuring that your aggregated views are continuously updated.
- **Visualization:** The processed and aggregated data is then presented to users in real-time. This can be achieved by integrating with popular business intelligence (BI) tools or by utilizing the Paimon Java API to build custom web applications that stream updates continuously, providing truly live dashboards and reports.
The benefits of using Streamhouse for real-time data views are extensive, including continuous real-time processing, efficient storage on cheap services like S3 with data warehouse properties, simplified data ingestion via Flink CDC, enhanced performance thanks to Ververica's VERA engine (which offers 2x better performance for real-time data processing), and remarkable flexibility in visualization. This process is detailed in the [Building Real-Time Data Views with Streamhouse blog](https://www.ververica.com/blog/building-real-time-data-views-with-streamhouse?hsLang=en).
## Streamhouse and the Broader Data Landscape
The Streamhouse concept represents a significant step towards a truly unified data architecture. By bringing stream processing capabilities directly to the data lake, it eliminates the need for separate systems for real-time and historical analytics. This convergence is vital for organizations moving towards an event-driven architecture, where immediate reactions to changes in data are paramount.
The integration of Apache Flink as the compute engine and Apache Paimon as the storage layer positions Streamhouse as a robust and scalable stream processing technology and addition to the Unified Streaming Data Platform. It allows businesses to gain instant access to insights, power real-time applications, and conduct deep historical analysis without the complexities and costs associated with maintaining disparate systems.
## Conclusion
Streamhouse is more than just a new buzzword; it's a practical and powerful technological concept for the modern data challenges. By combining the strengths of Apache Flink for stream processing with the cost-efficiency and analytical capabilities of data lakes via Apache Paimon, Ververica has crafted a [platform that truly unifies data stream processing](https://www.ververica.com/product?hsLang=en). It enables businesses to move from batch-oriented insights to a world of real-time decision-making, all while simplifying their data infrastructure and optimizing costs. For any organization looking to achieve true data agility and harness the full potential of its streaming and historical data, exploring the components of the Unified Streaming Data Platform, including Streamhouse is an essential next step.
---
---
title: "Forrester Report 2025"
description: ""
lastUpdated: 2026-04-01T12:40:13.000Z
source_url:
html: "https://www.ververica.com/forrester-report-2025"
md: "https://www.ververica.com/forrester-report-2025.md"
---
_No content._
---
---
title: "Fintech Monitoring"
description: "Real-time wealth management analytics and compliance monitoring powered by Apache Flink. Sub-10ms latency. 6.9B records/sec. Built by Flink's creators."
lastUpdated: 2026-06-15T09:48:01.000Z
source_url:
html: "https://www.ververica.com/banking/fintech-monitoring"
md: "https://www.ververica.com/banking/fintech-monitoring.md"
---
# Real-Time Monitoring for Fintech at Scale
Wealth management and compliance demand continuous visibility. Portfolio metrics, compliance signals, and customer analytics update as events occur.
## Batch Monitoring
Is Blind Monitoring
Fintech platforms generate millions of events per second. Portfolio rebalancing signals, compliance triggers, transaction anomalies. Batch pipelines evaluate this data hours later. By then, regulatory windows close, clients miss opportunities, and risk exposure compounds.
The cost of delayed compliance detection in financial services: $4.7 billion in regulatory fines in 2025 alone. Batch monitoring does not monitor. It audits the past.
## Core Capabilities
### Real-Time Portfolio Analytics
Track portfolio valuations, risk exposures, and rebalancing signals across thousands of accounts simultaneously. VERA engine computes metrics as market data and transaction events arrive. Not at end-of-day.
### Automated Compliance Monitoring
Evaluate every transaction against regulatory rules in real time. MiFID II suitability checks, KYC triggers, concentration limits, and reporting thresholds. Violations surface in milliseconds, not morning reports.
### Customer Behavior Analytics
Process clickstreams, transaction patterns, and engagement signals across channels. Build real-time customer profiles for personalization, churn prediction, and lifetime value scoring. All computed inline at stream speed.
### Anomaly Detection and Alerting
Detect deviations from baseline patterns across accounts, transactions, and system metrics. Statistical models and ML scoring execute within the pipeline. Alerts fire in real time with full event context.
## Key Reasons To choose Ververica
Why Ververica
From event ingestion to metric computation in under 10 milliseconds. Compliance signals, portfolio updates, and anomaly alerts propagate in real time across production fintech deployments.
The VERA engine sustains 6.9 billion records per second. Market data bursts, month-end reconciliation, regulatory reporting peaks. Throughput holds constant.
Measured total cost of ownership reduction compared to self-managed Apache Flink. VERA engine efficiency reduces compute. Managed operations reduce engineering overhead.
Every transaction, every compliance check, every portfolio calculation processed once and only once. No duplicates. No gaps. Even during failover and scaling events.
## Under the Hood
Most platforms patch batch onto streaming and call it unified. We built unified from the ground up. The VERA engine maintains per-account state across millions of concurrent keys, with incremental checkpointing and optimized operators designed for scale. State snapshots complete without pausing a single event. Fault tolerance with zero latency impact. That's not a feature. That's a foundation.
Compliance rules deploy as configurable operators within the Job Graph. Updates propagate without pipeline restarts. MiFID II suitability, concentration limits, KYC triggers, custom regulatory logic: evaluated against every event, in real time, without exception. Audit trails capture every decision with full lineage, from source event to compliance outcome. Regulators want proof. We deliver it.
The Streamhouse architecture unifies real-time and historical data, updating portfolio valuations, risk metrics, and fee calculations as markets move. Clickstreams, transactions, and engagement signals converge into live customer profiles: scored for personalization, churn prediction, and lifetime value the moment they arrive. ML models execute inside the pipeline. Sub-100ms inference means action before the next event lands. Finally, a financial infrastructure that thinks in real time, at scale, every time.
## Frequently Asked Questions
### How does Apache Flink enhance fintech metrics for wealth management?
Apache Flink processes market data and transaction events as they occur, computing portfolio valuations, performance attribution, and risk metrics in real time. VERA engine delivers these computations at sub-10ms latency across millions of accounts. Advisors and clients see current positions instead of waiting for overnight batch calculations.
### What are the data storage options for real-time compliance monitoring?
Ververica uses a Streamhouse architecture combining Apache Fluss for real-time streaming storage and Apache Paimon for historical lakehouse storage. Kafka or Kinesis handle event ingestion. This architecture supports both real-time compliance checks and historical lookback queries required for regulatory audits and investigations.
### How can Ververica optimize fintech monitoring operations?
Ververica reduces operational overhead through managed infrastructure, auto-scaling, and built-in observability. The VERA engine delivers 2x throughput at 40% lower TCO compared to self-managed Flink. Built-in governance provides RBAC, audit logging, and namespace isolation required for multi-tenant fintech environments.
### Can Flink coexist with existing wealth management systems?
Yes. Ververica integrates with existing order management systems, custodians, CRM platforms, and data warehouses through 200+ native connectors and CDC support. The platform runs alongside legacy batch systems during migration. Existing workflows continue while real-time capabilities are added incrementally.
### What compliance frameworks does the platform support?
Ververica supports MiFID II transaction reporting, KYC/AML monitoring, concentration limit tracking, best execution analysis, and DORA operational resilience requirements. The platform is SOC 2 Type II and ISO 27001 certified. GDPR compliance is built into the architecture with data residency controls and right-to-deletion support.
### How does Ververica handle scaling during peak periods?
The VERA engine auto-scales based on event throughput and processing backpressure. Month-end reporting, market volatility spikes, and regulatory filing deadlines trigger automatic resource allocation. Throughput of 6.9B records/sec holds constant during scaling operations with no processing gaps or duplicate events.
---
---
title: "What is Apache Paimon™?"
description: "Explore Apache Paimon, the open-source, stream-native data lakehouse format. Learn how it powers real-time updates, unified analytics with Ververica."
lastUpdated: 2026-04-15T12:39:59.000Z
source_url:
html: "https://www.ververica.com/ecosystem-introduction/what-is-apache-paimon"
md: "https://www.ververica.com/ecosystem-introduction/what-is-apache-paimon.md"
---
# What is Apache Paimon™?
Explore Apache Paimon, the open-source, stream-native data lakehouse format. Learn how it powers real-time updates, unified analytics with Ververica.
## What is Apache Paimon?
> **INFO:** Apache Paimon is an open-source, stream-native data lakehouse format. It's designed to bring real-time data stream processing capabilities directly to your data lake, enabling efficient updates, consistent changelogs, and powerful analytical queries on continuously changing data. It integrates tightly with Apache Flink®, allowing you to build unified pipelines for both streaming and batch workloads.
In the world of big data, processing and analyzing vast amounts of information in real time is a key challenge. Traditional data systems struggle to handle both historical data and continuous data streams effectively.
This is where Apache Paimon comes in. Paimon acts as a stream-native data lakehouse that allows for real-time updates directly within your data lake. For companies using Apache Flink to process data streams, Apache Paimon is a foundational tool that is included as part of Ververica's [Streamhouse](https://www.ververica.com/streamhouse?hsLang=en) architecture.
## The Genesis of Apache Paimon
Apache Paimon was created due to the recognition of a critical need in the stream processing framework landscape. While Apache Flink has evolved into a powerful unified engine for both batch and streaming data, a direct, queryable storage layer for intermediate and final tables in a streaming context was lacking. While powerful, Flink's "Dynamic Tables" aren't directly queryable, which limits the immediate accessibility of continuously updated data.
As a result, FLIP-188 ("Introduce Built-in Dynamic Table Storage,") was proposed as an initiative that eventually evolved into Apache Paimon. The fundamental idea is both simple and profound: _provide Apache Flink with a robust storage layer that leverages a table format, allowing intermediate data in dynamic tables to be directly accessible and queryable._ This concept aligns perfectly with the expanding "Lakehouse" paradigm, which combines the flexibility and scalability of data lakes on affordable storage (like S3) with the structured querying and optimization typically found in data warehouses. While other technologies like Apache Iceberg™, Delta Lake, and Apache Hudi also embrace the Lakehouse approach, Paimon's unique strength lies in its **stream-first design.** This makes it exceptionally suitable for continuous updates and real-time analytics, as detailed in the recent blog: [Apache Paimon: The Streaming Lakehouse](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse?hsLang=en).
Ververica integrated Paimon as a key ecosystem component, particularly in our Streamhouse architecture, because Paimon provides a robust, stream-native storage layer that significantly enhances Flink's capabilities for real-time data processing and advanced analytics. This strategic integration allows Ververica to offer comprehensive solutions for enterprises seeking modern, zero-trust-compliant data infrastructures.
## A Stream-Native Data Lakehouse
Apache Paimon is an open-source table format designed to enable the construction of a real-time Lakehouse architecture with both streaming and batch operations. It combines the benefits of a data lake format with a Log-Structured Merge-tree (LSM) structure, bringing real-time streaming updates directly into the data lake.
Key characteristics that define Apache Paimon include:
- **Unified Data Lakehouse Storage:** Paimon serves as a single storage layer that bridges the gap between batch and streaming data. It offers the scalability and flexibility of data lakes alongside the structured querying and schema enforcement of data warehouses. This unification simplifies data architectures, reducing complexity and operational overhead.
- **Real-Time Ingestion with CDC Support:** Paimon excels at real-time ingestion, with strong support for Flink Change Data Capture (CDC). This enables incremental updates, allowing data changes from operational databases to be continuously written to Paimon tables, ensuring data freshness.
- **Unified Workloads (Batch and OLAP):** Paimon is optimized for both analytical queries (OLAP) and batch processing, making it versatile for diverse workloads within a single system. This means you can run long-running historical queries alongside real-time analytical dashboards.
- **Tight Integration with Apache Flink:** Apache Paimon integrates tightly with Apache Flink. Flink can seamlessly use Paimon as both a source (to read data) and a sink (to write data). This deep integration empowers Flink jobs to process data in real time, incrementally update Paimon tables, and query those tables for immediate analytical insights. This makes stream processing with [Apache Flink](https://www.ververica.com/what-is-apache-flink?hsLang=en) significantly more powerful and flexible.
## Core Features and Capabilities of Apache Paimon
Apache Paimon’s design incorporates several powerful features that make it an ideal choice for data [stream processing](https://www.ververica.com/stream-processing-with-apache-flink-beginners-guide?hsLang=en) and building a modern data lakehouse:
- **Real-Time Updates with Primary Key Tables:** Paimon supports primary-key tables that enable real-time streaming updates of large amounts of data. This is crucial for maintaining data freshness, with queryable updates often available within minutes or even at sub-minute latency, depending on checkpoint intervals. Paimon offers various "merge engines" (like deduplicate, partial-update, aggregate, or first-row) to handle multiple records with the same primary key, providing flexibility in how updates are applied.
- **Flexible Updates with Merge Engines:** A key strength of Paimon lies in its support for rich merge engines. This allows users to define how records are updated, whether by keeping the last row, performing partial updates (updating only specific columns), or aggregating records. This flexibility is vital for complex data stream processing scenarios.
- **Change-Tracking Updates with Changelog Producers:** Paimon supports "changelog producers" that generate correct and complete changelogs from any data source. This is essential for downstream consumers to always see correct results and for building an accurate event-driven architecture.
- **Append-Only Tables:** For use cases that only require data insertion (e.g., log data synchronization) and do not need update or delete operations, Paimon offers append-only tables. These tables provide large-scale batch and streaming processing capabilities efficiently.
- **Data Lake Capabilities:** Inheriting the advantages of a data lake, Paimon provides low-cost storage, high reliability, and scalable metadata management. It supports features like Time Travel, allowing users to query previous versions of data by leveraging snapshots, and Full Schema Evolution, adapting to changes in data structure without disrupting pipelines.
- **Query Data Skipping:** Paimon enhances query performance through indexes (like min/max) that filter irrelevant files, leading to faster data retrieval.
- **Resource-Efficient Automatic Data Compaction:** To optimize read and write speeds, Paimon automatically and asynchronously combines smaller files into larger ones through a process called compaction. This prevents "small file" problems common in data lakes, resulting in faster queries and improved performance.
- **Robust Upsert Support:** Paimon's use of LSM trees and various merge engines, including the powerful partial update merge engine, allows for efficient upserts (updates or inserts) directly on the Lakehouse. This can eliminate the need for costly streaming joins on primary keys, making streaming ETL more cost-effective.
- **True Streaming Reads:** Paimon provides safeguard mechanisms and a consumer-id mechanism to ensure true streaming reads. This means downstream consumers can reliably track changes, even when data files expire or are deleted due to snapshot management.
## Apache Paimon in the Ververica Ecosystem
Within the Ververica ecosystem, Apache Paimon plays a pivotal role in enabling a truly [Unified Streaming Data Platform](https://www.ververica.com/product?hsLang=en). It seamlessly integrates with other key components like Apache Flink (the core processing engine) and Flink CDC (for real-time data ingestion).
Foundation for Streamhouse: As described in the "[The Streamhouse Evolution](https://www.ververica.com/blog/streamhouse-evolution?hsLang=en)", Apache Paimon is the streaming storage layer for Ververica's Streamhouse architecture. This combination allows for a single, cohesive platform for both real-time stream processing and historical analysis on the data lake.
**Enhanced Flink Capabilities:** Paimon directly extends Apache Flink's capabilities by providing a persistent, transactional, and queryable storage layer for its dynamic tables. This allows Flink jobs to not only process data in motion but also to maintain and query the state of that data efficiently in a cost-effective data lake.
**Building Real-Time Data Views:** Paimon is instrumental in building real-time data views. Data from various sources is ingested (often via Flink CDC) into Paimon tables, aggregated by [Apache Flink](https://www.ververica.com/what-is-apache-flink?hsLang=en), and then made available for real-time visualization through BI tools or custom applications. This end-to-end streaming pipeline eliminates recurrent batch jobs, as elaborated in the Building Real-Time Data Views with Streamhouse blog.
**Data Sovereignty and Governance:** Paimon aligns with Ververica's focus on data sovereignty and compliance by keeping data storage within the customer's cloud environment. It also enforces granular access policies and integrates with cloud-native security tools, ensuring that organizations retain full control over their data.
**Scalability and Cost Efficiency:** Paimon is designed to handle massive-scale data workloads and supports hybrid or multi-cloud environments. Its optimization for streaming significantly reduces costs associated with traditional batch-processing architectures by leveraging cheap object storage while maintaining performance.
**Developer-Friendly Design:** Paimon supports tools and APIs familiar to developers working with Apache Flink, making it easier to adopt within the Ververica Unified Streaming Data Platform and simplifying the operational complexity of managing data stream processing pipelines.
## Use Cases and Applications
The capabilities of Apache Paimon open up a wide array of use cases, particularly in scenarios demanding both real-time data freshness and cost-effective storage:
- **Real-Time ETL:** Transforming and loading data continuously into a data lake for immediate consumption.
- **Real-Time Data Warehousing:** Building a data warehouse that is continuously updated with fresh data, enabling real-time analytics and reporting.
- **Streaming Data Marts**: Creating specialized, continuously updated data marts for specific business functions.
- **Feature Stores for AI/ML:** Providing fresh data features for machine learning models by continuously updating tables that serve as feature stores.
- **Backfilling and Historical Analysis:** Combining real-time updates with the ability to query historical snapshots for auditing, debugging, or retrospective analysis.
- **Change Data Capture (CDC) into Data Lake:** Leveraging Flink CDC to ingest changes from transactional databases into the data lake in real time for unified analytics.
Apache Paimon is particularly beneficial for businesses looking to upgrade high-latency batch jobs to near real-time, assess the ROI of stream processing, or seamless migration of existing Lakehouse workloads to a streaming-first paradigm.
## Conclusion
Apache Paimon represents a significant leap forward in data stream processing and data lake architectures. By providing a stream-native, unified storage layer for Apache Flink, it effectively bridges the long-standing gap between real-time and historical data. Its robust features, tight integration with Flink, and role within [Ververica's Streamhouse](https://www.ververica.com/streamhouse?hsLang=en) architecture empower organizations to build highly scalable, cost-efficient, and responsive data pipelines. For businesses seeking to harness the full power of their streaming data, achieve true event-driven architecture, and unlock immediate insights from their data lakes, Apache Paimon stands as a pivotal component, leading the way towards a future where stream processing with [Apache Flink](https://www.ververica.com/what-is-apache-flink?hsLang=en) on a data lake is not just a possibility, but an accessible and efficient reality.
## FAQ
### What makes Paimon stream-first vs Iceberg or Delta?
Apache Paimon is designed for continuous, low-latency ingestion and updates with a streaming-first architecture, prioritizing real-time reads/writes, primary-key upserts, LSM-based compaction, and CDC-friendly changelogs, whereas Iceberg and Delta are optimized primarily for batch-heavy analytics and snapshot-driven workflows. Paimon’s focus on real-time stream compaction and freshness makes it better suited to high-frequency updates and millisecond-to-seconds decisioning, while Iceberg and Delta generally excel at large-scale batch analytics and broader snapshot/time-travel capabilities.
### How does Paimon work with Apache Flink (source/sink, CDC, streaming reads)?
Paimon integrates deeply with Apache Flink as both a source and sink, supporting real-time ingestion (including Flink CDC) into primary-key or append-only tables and enabling true streaming reads via changelog producers and snapshot-aware mechanisms. This integration allows Flink jobs to write CDC streams (e.g., from databases or Kafka) into Paimon, perform incremental processing, and read back latest state or changelogs continuously with low latency for operational and analytical use cases.
### Does Paimon support primary keys, upserts, partial updates?
Yes. Paimon supports primary-key tables with multiple merge engines (deduplicate, partial-update, aggregate, first-row), enabling efficient upserts and flexible column-level updates; it also supports upsert mode for non-PK tables via upsert keys and optional sequence fields for deterministic merges. The partial-update merge engine lets multiple messages incrementally complete a record under the same primary key, and streaming queries can combine partial-update with specific changelog producers to ensure correctness.
### What latency can Paimon achieve for streaming reads/writes?
Paimon is engineered for low-latency streaming pipelines, achieving near-real-time ingestion and consumption when paired with Flink, with latency driven by checkpoint intervals, compaction settings, and changelog configuration; its architecture targets lower streaming latency than batch-first formats due to stream-optimized write/read paths and LSM-based compaction. In practice, deployments use Paimon’s Flink connector metrics to monitor source and sink latency and tune for sub-minute to seconds-level end-to-end freshness in continuous workloads.
### What engines query Paimon tables (Flink, Spark, Trino, StarRocks, Doris)?
Beyond Apache Flink, Paimon tables can be queried by Apache Spark, Trino, StarRocks, Apache Doris, and Apache Hive, enabling a multi-engine lakehouse where streaming updates are immediately consumable across SQL and OLAP engines. This broad interoperability lets teams use Flink for ingestion and incremental processing while serving analytics via Spark, Trino, StarRocks, or Doris without data duplication.
---
---
title: "Data sovereignty"
description: "Data sovereignty"
lastUpdated: 2026-04-16T11:24:59.000Z
source_url:
html: "https://www.ververica.com/data-sovereignty"
md: "https://www.ververica.com/data-sovereignty.md"
---
# Your Real-Time Data Doesn't Belong in American Cloud Hands
Ververica is the only enterprise streaming platform built in Europe, for Europe. Apache Flink® born in Berlin. VERA engine governed by EU regulations. Your data stays under your control, in your jurisdiction, beyond foreign surveillance.
## They Told You Cloud Was Borderless. They Lied.
### Data has nationality.
### And yours is probably American 🇺🇸 by default.
When your streaming platform runs on AWS, Azure, or GCP:
- Your data is subject to US surveillance laws ([CLOUD Act](https://www.justice.gov/criminal/cloud-act-resources), [FISA 702](https://www.congress.gov/crs-product/R48592)), even in EU regions
- American intelligence agencies can access it without notifying you
- Your GDPR compliance is theater when the platform provider has US headquarters
- EU data centers don't protect you when the company answers to US jurisdiction
**Confluent? Databricks? Kinesis?** American companies. US jurisdiction. **Great tech. Wrong passport.**
It's not paranoia. It's the law. The CLOUD Act gives US authorities jurisdiction over data controlled by US companies, _regardless of where it's stored._
You didn't build your European business to hand your most sensitive data to a foreign government. But that's exactly what happened.
## Here's what it requires
What Real Data Sovereignty Looks Like
### European Corporate Entity
Not a US subsidiary with EU offices. A European company, governed by European law. When regulators knock, they're talking to Europeans.
### No US Legal Jurisdiction
Your data, your platform, your contract — none of it touches US law. No CLOUD Act exposure. No FISA vulnerability. If the NSA wants your data, they ask you. Not us.
### Full Deployment Control
- Self-managed: Your EU infrastructure, your servers, your control
- BYOC: European cloud providers only (OVH, T-Systems, Scaleway)
- Managed Service: EU data centers, EU contracts, EU operations teams
### Apache Flink®: Born in Berlin
Created at TU Berlin by our founders. European innovation from day one. The team that invented Flink still leads it.
### Auditable, Compliant Stack
Every dependency vetted for NIS2 supply chain security. No phone-home to US servers. Complete data lineage for GDPR Article 30 and DORA audit trails.
When regulators ask, "Can you prove this data never left the EU?" you can say **YES.**
## Your Data Sovereignty Checklist
| Feature | Ververica | US Platforms |
| --- | --- | --- |
| EU corporate entity | ✓ | ✗ |
| No US legal jurisdiction | ✓ | ✗ |
| EU-only deployment options | ✓ | ✗ |
| European technology origins | ✓ | ✗ |
| Auditable supply chain | ✓ | ✗ |
| No telemetry to US infrastructure | ✓ | ✗ |
## If You're in These Industries, This Isn't Optional
If your regulator would flinch at "Our real-time platform is American," keep reading.
DORA mandates third-party risk management. If your regulator asks why transaction data touches US infrastructure, what's your answer?
Patient data sovereignty under GDPR Article 9. Clinical trials and genomic research can't be exposed to foreign governments.
NIS2 essential entities. Sovereign data requirements for national security. Procurement favors EU providers.
Network telemetry = national security. Real-time subscriber analytics for hundreds of millions of EU citizens.
## FAQ
### Can't we just use AWS EU regions with data residency controls?
No. AWS is a US company subject to the CLOUD Act. Data residency ≠ data sovereignty. Read your AWS contract, it says US authorities can access your data regardless of storage location.
### What about Confluent Cloud in EU regions?
Confluent is a US corporation. Subject to US law. Your data sits in Frankfurt. The legal jurisdiction is California.
### Does this cost more than US platforms?
Ververica delivers 40% lower TCO. But the real question: What's the cost of regulatory non-compliance? Of being the next Schrems case study? The cheapest option is the one that doesn't shut down your business.
### What if we need global deployment?
Data sovereignty doesn't mean isolation. Run Ververica globally with EU data in EU regions. The difference: You control where each workload runs. With US platforms, it's all under US legal control.
---
---
title: "Code of Conduct"
description: "Attend Ververica events with confidence, knowing we promote inclusivity, respect, and a harassment-free environment for all participants."
lastUpdated: 2026-04-21T12:23:59.000Z
source_url:
html: "https://www.ververica.com/events/code-of-conduct"
md: "https://www.ververica.com/events/code-of-conduct.md"
---
# Code of Conduct
**Last update: March 4th 2025**
## 1. Overview
All attendees, contributors, speakers, sponsors, volunteers and other guests (whether paid or otherwise) at Ververica events (whether organized or hosted by) are required to abide by the below code of conduct, which will be in effect throughout attendance for the selected event period (whether online and in-person, as well as in all one-on-one engagements). Cooperation from all participants is expected to ensure a safe and productive environment for everyone and we expect participants to follow these rules at all sites of the event venue and related social events.
## 2. Purpose
The primary goal of this Code of Conduct is to be inclusive across all event participants and embrace the most varied and diverse backgrounds possible. As the organizer, we are committed to providing a friendly, safe and welcoming environment for all attendees, regardless of gender, sexual orientation, ability, ethnicity, socioeconomic status and religion (or lack thereof).
This Code of Conduct outlines our expectations for all event participants, as well as the consequences for unacceptable behavior. We ask for all attendees to help create a safe and positive experience for everyone.
## 3. Open Source / Culture / Tech Citizenship
We encourage an open source / culture / tech citizenship mentality, whereby all participants recognize and strengthen the relationships between their actions and effects on others. Communities mirror the societies in which they exist and positive actions are essential to counteract the many forms of inequality and abuses of power that exist in society.
## 4. Expected Behavior
Participate in an authentic and active way. In doing so, you contribute to the health and longevity of this community. Exercise consideration and respect in your speech and actions. Attempt collaboration before conflict. Refrain from demeaning, discriminatory, or harassing behavior and speech. Be mindful of your surroundings and of your fellow participants. Alert community leaders if you notice a dangerous situation, someone in distress, or violations of this Code of Conduct, even if they seem inconsequential.
## 5. Unacceptable Behaviors
Unacceptable behaviors include: intimidating, harassing, abusive, discriminatory, derogatory or demeaning speech or actions by any participant in our community engagements online, at our events and in one-on-one communications. In case the event venue might be shared with members of the public, please be respectful to all patrons of these locations.
## 6. Anti-Harassment Policy
Ververica Academy is dedicated to providing a harassment-free experience for everyone. We do not tolerate harassment of participants in any form. Attendees violating these rules may be sanctioned or expelled without a refund, at the discretion of the event organizer.
Harassment includes offensive, harmful or prejudicial verbal comments related to gender, sexual orientation, race, religion, disability; inappropriate use of nudity and / or sexual images in public spaces (including presentation slides); deliberate intimidation, stalking or following, unwanted photography or recording, sustained disruption of talks or other events, inappropriate physical contact, and unwelcome sexual attention. Participants asked to stop any harassing behavior are expected to comply immediately.
Sexual language and imagery will not be tolerated throughout the entire event period. Participants should also refrain from using sexualized images, activities, or other material. Staff (including volunteers) should not use sexualized clothing or otherwise create a sexualized environment.
## 7. Consequences of Unacceptable Behavior
Unacceptable behavior from any community member, including sponsors and those with decision-making authority, will not be tolerated. Anyone asked to stop unacceptable behavior is expected to comply immediately. If a participant engages in unacceptable behavior, the organizers may take action they deem appropriate, up to and including a temporary ban or permanent expulsion from the community or event without warning (and without refund in the case of a paid participation).
## 8. Contact Details
If you feel you have been falsely or unfairly accused of violating this Code of Conduct, or if you are subject to or witness unacceptable behavior, you can contact the event team via [academy@ververica.com](mailto:academy@ververica.com)
---
---
title: "What is Apache Flink"
description: "Apache Flink is the leading open-source stream processing framework for real-time analytics, event-driven applications, and data pipelines. "
lastUpdated: 2026-04-15T12:48:24.000Z
source_url:
html: "https://www.ververica.com/ecosystem-introduction/what-is-apache-flink"
md: "https://www.ververica.com/ecosystem-introduction/what-is-apache-flink.md"
---
# What is Apache Flink®?
Learn more about the leading technology for processing both unbounded (streaming) and bounded (batch) data.
## Apache Flink, the leading stream processing framework.
> **INFO:** Apache Flink is a powerful Open Source stream processing framework for data stream processing and distributed stateful computations on large-scale data streams. Unlike traditional batch processing, Flink operates on data continuously as it arrives, enabling real-time processing with low latency. This makes Flink a cornerstone of modern event-driven architecture, streaming analytics, and real-time data pipelines in many organizations.
In this comprehensive guide, explore what Apache Flink is, how it works, and its key applications in **event-driven applications**, **real-time analytics**, and **data pipelines**. In addition, learn about common use cases like fraud detection, anomaly detection, rule-based alerts, business process monitoring, dynamic pricing, Extract, Transform, and Load (ETL), and streaming Artificial Intelligence and Machine Learning (AI/ML), including explanation of each and how Flink empowers these scenarios.
Flink’s design provides **in-memory speed and scalability** for handling high-throughput event streams. It manages events with **exactly-once state consistency** and offers powerful primitives for processing time, (event-time windows, and watermarks) and for maintaining application state across events. In practice, this means Flink applications can perform complex operations like aggregations, joins, pattern detection, machine learning inference, etc. on the fly, producing instantaneous results as new data events come in.
The ability to handle unbounded streams in real time while also managing bounded (batch) data sets makes Flink a powerful solution suited for a range of scenarios. Below, we explain how Flink is used in event-driven systems, streaming analytics, and data pipelines, with real-world examples and use cases.
## Apache Flink in Event-Driven Applications
In an **event-driven application**, systems react to events (such as user actions, sensor readings, financial transactions, etc.) as they occur. Instead of processing data in periodic batches, event-driven architectures continuously stream events through processing logic to trigger immediate actions or downstream processes. Apache Flink is often the “brain” in these architectures, ingesting event streams, evaluating conditions or patterns, and responding in **milliseconds**. Flink’s **low-latency, stateful stream processing capabilities** allow developers to implement **complex event logic** that remembers past events, correlates multiple event streams, and maintains counters or profiles, all in real time.
**Why Flink for Event-Driven Architecture?** Event-driven systems require processing incoming events reliably and quickly. Flink provides exactly-once processing guarantees (meaning an event will never be lost or processed twice, even in failures) and can scale to millions of events per second with horizontal clustering. Its event-time processing ensures out-of-order events can be handled correctly (which is important in distributed event sources), and its state management lets you create sophisticated **event pattern detectors** and alerting rules. In short, Flink can detect **anomalies**, trigger **alerts**, or update **aggregates** the moment relevant events happen. This makes it ideal for mission-critical applications where immediate reaction can prevent loss or capitalize on an opportunity.
### Key Event-Driven Use Cases Powered by Flink:
- **Real-Time Fraud Detection:** Fraud detection is a significant challenge across finance, e-commerce, insurance and more, requiring identification of fraudulent transactions hidden in vast data streams. Apache Flink enables organizations to analyze events like credit card swipes, logins, or money transfers as they happen, comparing against patterns of legitimate behavior to catch anomalies. By correlating event streams and applying machine-learning models or rules, Flink can flag suspicious activities in milliseconds, helping businesses **prevent fraud losses before they occur.** For example, Flink might detect a sequence of transactions or account events indicative of fraud and immediately block the transaction or alert security teams. Real-world users leverage Flink for fraud detection to adapt to evolving fraudster tactics with millisecond anomaly detection. _(See_ [_Fraud Detection use case_](https://www.ververica.com/use-case/fraud-detection?hsLang=en) _for more details.)_
- **Anomaly Detection & Security Alerts:** Beyond financial fraud, many systems need to detect **anomalies** in streaming data – from IT security breaches to equipment sensor faults. Flink’s stream processing can compute statistics or apply ML models on sliding windows of events to recognize unusual patterns instantly. For instance, in cybersecurity (SIEM systems), Flink can ingest logs from servers, network devices, etc., and perform **real-time complex event processing** to identify signs of an attack or policy violation. It processes security events at ingestion time to enable immediate detection of anomalies or intrusions. This proactive approach means potential threats trigger alerts or automated responses within seconds, rather than hours or days after analysis. Flink’s **event-driven architecture** excels here by correlating events across disparate sources in real time, something traditional batch-based monitoring can’t easily do. _(See_ [_Security Information and Event Management (SIEM) use case_](https://www.ververica.com/use-case/security-information-and-event-management?hsLang=en) _for more details.)_
- **Rule-Based Alerting:** Many business applications rely on **rule-based alerting**, where certain combinations of events or threshold conditions should trigger a notification or action. Apache Flink includes a library for **Complex Event Processing (CEP)** that lets developers define event pattern rules (for example, "if Event A is followed by Event B within 2 minutes, and Event C has not occurred, raise an alert"). Flink will continuously look for these patterns in the event stream and fire alerts the moment a rule is satisfied. This is used in scenarios like monitoring transactions for specific sequences (e.g., multiple failed logins followed by a high-value transaction) or IoT sensor networks (e.g., if temperature > X and pressure > Y within 5 seconds, signal an alarm). Because Flink’s CEP rules can be updated and evaluated on live data, businesses can respond to operational conditions instantly with automated workflows. For example, a Flink application can send a real-time notification to operators when certain business process steps are delayed or abnormal. Flink’s ability to trigger notifications and alerts on defined patterns in real time has been used to implement dynamic **rule-based alerting** in fraud prevention systems and others. _(See_ [_Real-Time Fraud Detection Using Complex Event Processing_](https://www.ververica.com/blog/real-time-fraud-detection-using-complex-event-processing?hsLang=en) _for more details.)_
- **Real-Time Business Process Monitoring:** Companies often use Flink to monitor end-to-end **business processes** by tracking events from multiple systems that make up a workflow. Consider an e-commerce order fulfillment process: an order placed event, a payment processed event, a warehouse shipment event, delivery confirmation, etc. These might each originate from different services or databases. Flink can ingest all these event streams and join or correlate them by Order ID (maintaining state for each active order), thereby reconstructing the live status of each order through its lifecycle. If a step is missing or delayed (e.g., payment received but no shipment event after X minutes), Flink can detect the discrepancy and raise an alert or initiate a compensating action. This kind of **business process monitoring** ensures visibility into complex workflows in real time. It also provides live metrics (throughput, latency per step, etc.) for operational dashboards. By leveraging Flink for such monitoring, organizations gain a live pulse of their business operations and can react quickly to bottlenecks or failures. In essence, Flink enables a **digital twin of your business** processes via event streams, facilitating agility and responsiveness.
Apache Flink’s strength in event-driven scenarios lies in its ability to **process incoming events immediately and contextually.** It keeps relevant state (such as user session data, running counts, or machine learning features) in memory, so each new event can be analyzed in light of prior events. This allows applications like fraud detection to not just inspect one transaction in isolation, but compare it to historical patterns or combine it with related events (e.g. multiple accounts logging in from the same device) before deciding to flag it. As a result, organizations can move from reactive post-hoc analysis to **proactive event-driven action**, catching problems in-flight. Real-time streaming with Flink lets you “stop suspicious activity in its tracks”, whether that’s halting a fraudulent transaction or preventing damage to equipment after anomaly signals. In summary, Flink provides the real-time nervous system for event-driven applications, powering use cases from fraud prevention and IoT monitoring to user engagement triggers, by responding to events as they happen.
## Apache Flink for Real-Time Data Analytics Applications
Another major use of Apache Flink is in **real-time data analytics**, which is deriving insights and making data-driven decisions continuously from streaming data. Traditional analytics often meant pulling data into a data warehouse and running batch queries or reports (which could take hours or days). With Flink’s stream processing, analytics can happen **on the fly**, allowing dashboards, algorithms, or users to see up-to-the-moment information and trends. Flink essentially turns queries into long-running applications that constantly update their results as new data arrives, enabling what’s known as **streaming analytics** or real-time business intelligence.
**Streaming Analytics vs. Batch Analytics:** In batch analytics, you might compute yesterday’s sales total or last hour’s sensor averages after collecting all the data. In contrast, Flink lets you compute metrics continuously – e.g., a running count of sales in the last 5 minutes that updates every second, or an alert if sensor readings deviate from the norm right now. This not only reduces the latency of insight (from hours to seconds) but also allows automated actions in response to analytics (closing the loop from analytics to operation). Flink achieves this via features like event-time windows (which aggregate over sliding or tumbling time periods), incremental aggregation algorithms, and [Flink SQL](https://www.ververica.com/blog/apache-flink-sql-past-present-and-future?hsLang=en)/Table API for writing continuous queries.
Common patterns where Flink is applied in analytics include **real-time dashboards**, **alerts on KPI thresholds**, **trend detection**, and **personalization**. Because Flink can join multiple data streams, it’s possible to enrich live data with reference data (e.g., joining user events with customer profiles) to get deeper insights in real time.
### Key Analytics Use Cases Leveraging Apache Flink
- **Dynamic Pricing Optimization:** In dynamic pricing, businesses adjust prices or rates in real time based on current demand, supply, and other factors. This is common in industries like ride-hailing, food delivery, airline tickets, and e-commerce flash sales. Apache Flink enables dynamic pricing by continuously analyzing streams of events such as user requests, driver availability, inventory levels, competitor pricing, and even external signals like weather or traffic. With Flink, raw data from these streams is **transformed instantly into actionable insights that guide pricing in real time**. For example, a ride-sharing platform can use Flink to calculate surge pricing multipliers per city in real time by analyzing trip request rates and driver supply on a minute-by-minute basis. As conditions change (a sudden spike in demand or a big drop in available drivers for example), the Flink job updates the pricing recommendations immediately. The outcome is optimal resource allocation, more balanced supply-demand matching, and improved revenue – [studies show](https://www.mckinsey.com/industries/retail/our-insights/how-retailers-can-drive-profitable-growth-through-dynamic-pricing) companies using dynamic pricing see an average 5% increase in profit margin per product or service sold. Flink’s ability to integrate historical data (e.g., typical demand patterns) with live feeds ensures pricing decisions are data-driven and responsive rather than static or intuition-based. _(See_ [_Dynamic Pricing use case_](https://www.ververica.com/use-case/dynamic-pricing?hsLang=en) _for more details.)_
- **Customer 360 and Personalization:** Modern enterprises strive for a **360-degree view of the customer**, aggregating all customer interactions and data points to better understand and serve each person. Apache Flink is a key technology in building these real-time customer analytics systems. By streaming in data from various touchpoints (website clicks, mobile app events, purchases, support tickets, social media, etc.) and joining it with historical customer data, Flink helps create a live unified profile for each customer. This unified stream can drive personalized recommendations, targeted marketing, or tailored user experiences in real time. For instance, an online retail platform might use Flink to continuously update a customer’s profile with what they're browsing and buying, then use that to recommend products or content immediately (rather than in the next day’s email). With every interaction, Flink **turns customer data into valuable, actionable insights** for the business. The result is a **data-rich, holistic view** of each customer that enhances decision-making and personalization strategies on the fly. Companies using Flink to gain a Customer 360 can engage customers in real time with context-aware offers, detect churn signals as they happen, or route high-value customers to special handling, all based on streaming analytics. Additionally, Flink’s stateful processing allows applying business rules or machine learning models per customer in real time (for example, calculating a live customer lifetime value or propensity score as events stream in). _(See_ [_Customer 360 use case_](https://www.ververica.com/use-case/customer-360?hsLang=en) _for more details.)_
- **Real-Time Dashboards & Operational Analytics:** Many organizations use Flink to power live dashboards and monitor key performance indicators (KPIs) continuously. Instead of waiting for end-of-day reports, operations teams can watch metrics updated second-by-second. For example, Flink might drive a dashboard of website activity (like current active users and clicks per second), application performance (real-time error rates, latency percentiles), or business metrics (orders per minute, revenue today vs. yesterday in real time). Flink jobs can aggregate event streams and output results to a dashboarding system or database that backs a visualization. Because Flink windows and aggregations can maintain summaries with each new event, the dashboard shows trends and anomalies instantly. This real-time visibility enables faster response to issues and data-driven business decisions. If a metric goes out of bounds, teams can be alerted immediately (tying into the rule-based alerting mentioned earlier). **Business process monitoring** (discussed above) is a special case of this, where the dashboard might reflect the state of each process instance. Another example is Internet of Things (IoT) analytics: Flink can analyze data from thousands of IoT sensors in real time to track metrics like machine utilization, environmental readings, or fleet vehicle locations, giving companies up-to-the-moment insight into their operations. (See [Using Real-Time Data to Optimize the Electric Vehicle Industry](https://www.ververica.com/blog/driving-efficiency-using-real-time-data-to-optimize-the-ev-industry?hsLang=en) blog post)
- **AI-Driven Analytics and Recommendations:** Apache Flink is often used in conjunction with **machine learning (ML)** to enhance analytics. In streaming recommendation engines (like content or product recommendations on platforms), Flink can continuously update recommendations based on recent user behavior. For instance, Flink might maintain a running model of trending topics or popular items and immediately suggest them to users while trends are hot. In financial trading analytics, Flink can incorporate ML models to detect market anomalies or predict price movements on streaming tick data. What sets Flink apart is its ability to handle **both historical and real-time data** together – you might feed models with historical features but update those features with live data as time progresses. Moreover, Flink’s integration with ML libraries (e.g., Flink ML or external APIs) allows scoring of events in real time (such as classifying an event or forecasting a metric) and then acting on that prediction within the stream. A concrete example is **real-time anomaly detection using ML**: Flink can calculate anomaly scores for each incoming reading (like credit card transaction or sensor value) via an ML model, and if the score indicates an outlier, immediately flag it. This blends analytics with automated action. _(See_ [_AI/ML use case_](https://www.ververica.com/use-case/ai-ml?hsLang=en) _for how Flink supports real-time machine learning pipelines.)_
Apache Flink’s rich analytic capabilities (event-time windows, aggregations, joins, SQL, machine learning algorithms, etc.) make it a versatile engine for extracting insight from streams. It essentially brings the power of SQL and dataframes to unbounded live data. Importantly, Flink’s **stateful streaming** means you can do things like join a stream with a reference dataset or keep running counts indefinitely – enabling analytics that are not possible with stateless systems. Many companies have built **real-time analytics platforms** on Flink that feed both internal users (through live metrics and alerts) and external users (through personalized content or adaptive experiences). By processing data continuously, organizations can move from after-the-fact analysis to continuously updated intelligence and gain a competitive edge by responding to information the moment it’s available. One example of this is Chinese e-commerce giant Alibaba, who uses Apache Flink to power search and recommendation use cases, processing **over one trillion events per day** and over **470 million transactions per second** during peak events – a [testament to Flink’s ability to handle extreme scale](https://www.alibabacloud.com/blog/why-did-alibaba-choose-apache-flink-anyway_595190) in streaming analytics.
## Apache Flink in Data Pipelines and Streaming ETL
The third major arena for Apache Flink is building **data pipelines**, in particular, streaming **ETL (Extract, Transform, Load)** processes that move and transform data in real time. ETL traditionally uses batch processing tools. During the process, data is extracted from sources, stored, then transformed and loaded into targets (like data warehouses or data lakes) in periodic batches. This results in high latency (data is hours or days old by the time it’s available for use) and often complex architectures with staging tables or multiple processing layers. Flink offers a better approach with continuous ETL. With Flink, data flows from sources to targets with transformations applied on the fly, so that **data is available in seconds instead of days**. As a result, organizations can simplify architectures by eliminating unnecessary interim storage and get up-to-the-moment data in their analytical systems.
**Streaming ETL and Data Integration:** Apache Flink excels at integrating data from disparate systems in real time. Via **Change Data Capture (CDC)**, Flink can consume streams from databases, including every insert/update/delete as they occur, message queues like Apache Kafka, sensors, log files, or APIs, and then transform and harmonize these streams before delivering to a sink, such as a data warehouse, data lake, search index, or another service. Because Flink pipelines run continuously, data is fed through as soon as it’s generated. This means no more waiting for nightly batch jobs, instead, reports and data-driven applications can use data that’s only seconds old. In scenarios where data is siloed across different systems, Flink can serve as the **unifying layer**, merging streams into one common data model. For example, a company can stream customer data from a Customer Relationship Manager (CRM), clickstream data from web logs, and transaction data from a billing system, all into Flink, which can join/enrich these in real time and load into a unified database or feature store. This process effectively creates a live **single source of truth**. One immediate benefit is that decisions are based on the latest information, not stale snapshots of older data. **Real-time ETL isn't just an upgrade, it's imperative for staying competitive and taking timely, informed actions in today’s instant-feedback world. **_(See_ [_ETL use case_](https://www.ververica.com/use-case/extract-transform-load?hsLang=en)_to learn more.)_
Flink’s approach to streaming ETL addresses several limitations of traditional ETL:
- **Ultra-Low Latency:** Traditional ETL processes data in batches, introducing delays since data must be collected and stored before processing. In contrast, **Apache Flink enables real-time ETL**, allowing applications to **ingest, transform, and act on data instantly without having to store it first.** This means as soon as an event occurs in a source system, it can be in the target system moments later. For businesses, this could mean having up-to-the-second inventory levels, or immediately propagating a new customer signup to all relevant systems.
- **Simplified Architecture:** Legacy ETL pipelines often involve multiple stages (bronze, silver, gold data layers, etc.) and intermediate storage, which add complexity and cost. Flink’s **event-driven pipeline** can perform on-the-fly transformations and filtering, reducing the need for staging areas or multiple passes over the data. In other words, you can do **continuous transformation** as data streams through the pipeline, using one system (Flink) rather than a chain of tools. This simplifies data architecture and reduces maintenance. [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product?hsLang=en) (which is 100% compatible with Flink) highlights that by removing batch layers and moving to streaming, you eliminate redundant storage and achieve more efficient, lean data pipelines.
- **Scalability and Efficiency:** Flink is built to handle high volume streams and can scale out horizontally. Traditional ETL jobs often hit scalability issues or require expensive scaling of database engines to handle large batch jobs. Flink pipelines can run on commodity clusters and scale linearly for throughput. Moreover, continuous processing spreads out the workload over time (instead of peaking during batch windows), often leading to better resource utilization. Flink’s incremental processing also means it can handle late-arriving data or out-of-order events gracefully (via event time handling), ensuring correctness without needing complex reprocessing logic.
- **Data Freshness and Quality:** By delivering data continuously, Flink ensures that downstream systems are always operating on **fresh data**. This significantly improves the quality of analytics and machine learning, which benefit from fresh, up-to-date information. For example, an analytics dashboard fed by a Flink pipeline will reflect the latest business conditions, instead of batch processing which will result in delayed insights. Similarly, a machine learning model retrained using a Flink pipeline can incorporate today’s data and adapt faster. (See [_Why Streaming ELT Fuels Next-Gen Machine Learning_](https://www.ververica.com/blog/why-streaming-etl-fuels-next-gen-machine-learning?hsLang=en) blog post)
### Key Data Pipeline Use Cases with Flink:
- **Real-Time ETL and Change Data Capture:** A classic use case is replicating database changes in real time to other systems. Apache Flink can connect to databases via Change Data Capture (CDC) connectors that emit every change event (like insert/update/delete). Flink jobs then stream these changes to a destination. For instance, you might capture changes from a production MySQL database and use Flink to stream them into a cloud data warehouse for search analytics. Along the way, Flink can transform the data (including filter columns, mask sensitive data, join with reference data, etc.). This pipeline ensures the target is continuously synced with the source with minimal lag (seconds instead of hours or days). Compared to hourly dumps or nightly ETL, this is a game-changer for data freshness. Many companies use Flink in this way to maintain real-time replicas of transactional data for reporting or to offload analytical queries from primary databases. Change Data Capture with Flink allows maintaining an up-to-date **data lake or data warehouse** without lengthy batch import jobs.
- **Unified Data Streams for Analytics:** Apache Flink often sits between data producers and consumers as a real-time transformation layer. For example, imagine a data source receiving raw events like clicks or page views from a website. Downstream, there are multiple consumers, including one system that wants to count page views per minute, and another that needs to store events, while yet another wants to detect certain sequences for monitoring. Instead of each consumer doing redundant processing, a Flink job can consume the raw stream from data source, perform several transformations (for example: parse logs, enrich with geo-information, or filter irrelevant events), and then publish refined streams to new sinks for each use. This **streaming data pipeline** offloads common transformation logic to Flink and provides each consumer with a clean, processed stream. It’s essentially the streaming equivalent of an ETL workflow, but continuously running. The benefit is consistency, as all consumers see the same clean data, and low latency. Such pipelines are used in **customer analytics**, where events from multiple channels are unified and cleaned in real time, then fed to various teams/apps. [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product?hsLang=en) emphasizes real-time **data movement and processing at millisecond latencies**, so you can make decisions and take action instantly on your data.
- **Machine Learning Model Pipelines (Streaming AI/ML):** As organizations adopt AI and ML, data pipelines feeding those models become critical. Apache Flink is increasingly used to build **real-time ML** pipelines for both model training and model serving. For training, Flink can stream data into feature stores or directly into an online training process (for example, updating a model incrementally with new data, a concept known as online learning). This ensures models are always learning from the latest data rather than being retrained only on static batches. More commonly, Flink is used for **feature engineering in real time**. Flink can compute features from raw data streams (such as aggregating user behavior over a window, or joining a stream with another to get context) and feed those features to an ML model service. This enables **real-time predictions**, where as soon as an event arrives, the model can score it with up-to-date features. An example of this is real-time fraud scoring. When a transaction event comes in, a Flink job might aggregate the user’s past 5 minute spending, count of transactions, location info, etc. (features), then call a model to get a fraud probability, and finally act on that (block or allow), all within a second. Flink’s ability to handle the data plumbing for ML in real time keeps models effective and responsive. In fact, [Ververica’s AI/ML use case](https://www.ververica.com/use-case/ai-ml?hsLang=en) highlights that Flink **processes data in real time, enabling you to ingest, process, and deliver insights to models as events occur**, ensuring your AI/ML systems always operate on up-to-date data. Moreover, Flink’s integration with **AI pipelines** means it can also take the outputs of models and trigger downstream actions (like automated alerts or decisions), enabling autonomous decisioning. For example, Flink can work with an “[Agentic AI](https://www.ververica.com/blog/outrun-fraudsters-with-agentic-ai-and-ververica?hsLang=en)” approach where the system not only detects an anomaly but also automatically investigates and creates an alert or recommendation, using both real-time and historical data._(See_ [_AI/ML use case_](https://www.ververica.com/use-case/ai-ml?hsLang=en) _to learn how Flink supports live data for machine learning.)_
- **Event-Driven Microservices & Data Sharing:** In modern microservice architectures, there’s often a need to share data changes between services in real time (to avoid each service working in isolation on stale data). Flink can serve as the backbone for an **event-driven data mesh,** where each important data change is broadcast as an event and Flink pipelines route and transform these events to other services that need them. For instance, when a user updates their profile in a User service, a Flink pipeline can capture that event and immediately propagate the change to a Recommendation service’s database and to a Marketing analytics system. This pattern ensures eventual consistency across services in seconds, and Flink’s processing can handle retries, transformations, and ordering concerns centrally. Similarly, for **IoT data pipelines**, Flink can collect streams from devices, perform streaming analytics (including filtering and aggregating), and deliver processed streams to different consumers. For example, it can trigger alerts for anomalies (as discussed), update real-time digital twins dashboards, and store raw data in a cluster for later analysis, all simultaneously. The pipeline concept here is “write once, deliver to many” via transformations that Flink is uniquely positioned to create.
In summary, Apache Flink enables building **real-time data pipelines** that are more efficient, simpler, and faster than traditional ETL pipelines. With Flink, **data is continuously in motion**, flowing from sources to destinations with minimal delay, and with all necessary processing done en route. This means businesses don’t have to choose between having up-to-date data and having complex processing, instead, Flink delivers both. ROI is expressed as more timely analytics, more responsive applications, and the ability to do things that were previously impractical, like constantly updating machine learning models or maintaining live replicas of data. Companies adopting Flink-based pipelines report improved agility as they can integrate new data sources quickly and react to new information immediately. In a world where data value decays over time, moving to real-time pipelines ensures you get the **maximum value from your data when it’s most relevant**, rather than after the fact.
## Conclusion
Apache Flink has emerged as a leading technology for **stream processing** in the era of big data and real-time demands. By providing a platform for **event-driven, real-time computations** at scale, Flink enables organizations to transition from batch-oriented thinking to streaming-first architectures. Whether it’s powering complex event-driven applications (like catching fraud or triggering alerts within milliseconds), driving **real-time analytics** (like live dashboards, dynamic pricing, and personalized experiences), or streamlining **data pipelines** (real-time ETL and continuous machine learning data feeds), Flink delivers the speed, scalability, and reliability required. It abstracts away much of the difficulty of handling streams (such as fault tolerance, ordering, state management) and lets developers focus on business logic, whether that is defining event patterns, completing analytic aggregations, or creating transformation workflows.
The impact of adopting Apache Flink is transformative. Businesses become more **responsive** to events (turning streams of data into instant action), more **insightful** (gaining visibility into live trends and behaviors), and more **unified** in their data infrastructure (with a single engine handling batch and stream processing). Case studies from industry leaders underscore Flink’s versatility, for example, financial institutions using Flink to detect fraud in real time, tech companies using it to deliver real-time customer 360 analytics, ride-sharing apps optimizing prices dynamically, and many enterprises overhauling legacy ETL with streaming pipelines for fresher data.
In the broader landscape of stream processing frameworks, Flink is known for its **state-of-the-art architecture** and robust features (such as exactly-once semantics and event-time processing) that set it apart. It has a thriving open-source community and is the backbone behind commercial, enterprise-grade offerings including [Ververica's Unified Streaming Data Platform](https://docs.ververica.com/introduction/about-ecosystem/apache-flink/) that further simplify building streaming applications. For any organization looking to implement **event-driven architecture**, real-time analytics, or modern data pipelines, Apache Flink is a proven choice that can handle the demands of **stream processing with Apache Flink** at scale. Embracing Flink means your business can process, analyze, and act on NOW data, gaining a critical edge in today’s fast-paced, data-driven world. Ververica enhances Apache Flink with proprietary innovations like the [VERA](https://www.ververica.com/what-is-vera?hsLang=en) engine (delivering up to 2x performance improvement) and [Streamhouse](https://www.ververica.com/streamhouse?hsLang=en) (enabling real-time data warehouse capabilities directly on streaming data). These technologies, combined with our team's deep expertise as Flink's original creators, make Ververica the premier choice for organizations deploying Apache Flink at enterprise scale.
## Open Source Apache Flink vs Ververica Platform
| Feature | Ververica Platform | Open Source Apache Flink |
| --- | --- | --- |
| Core Engine | Apache Flink + VERA engine (2x performance) | Standard Apache Flink |
| Deployment | Fully managed cloud or self-managed with automation | Self-managed, manual setup |
| Performance | Up to 2x faster with VERA optimization | Standard throughput |
| Operations | Auto-scaling, monitoring, alerts included | Manual cluster management |
| Support | 24/7 expert support from Flink creators | Community forums |
| Enterprise Features | SSO, RBAC, compliance (SOC2, ISO 27001), SLAs | Basic features |
| Best For | Production workloads, enterprise scale | POCs, small deployments, learning |
## FAQ
### What makes Apache Flink unique among stream processing frameworks?
Apache Flink stands out because of its powerful real-time processing capabilities, especially its ability to handle stateful computations accurately with **exactly-once guarantees.** Flink efficiently processes both **real-time streaming data and batch data** in a unified system, making it highly versatile. Its advanced event-time handling ensures accurate results **even with out-of-order data** streams.
### When should you use Apache Flink vs. other streaming technologies?
Apache Flink is ideal when your business needs **real-time insights** with guaranteed accuracy and consistency. It's particularly suited for **complex, stateful applications** such as fraud detection, real-time analytics, and real-time machine learning.
### How do you optimize Flink jobs for low latency and high throughput?
To optimize Flink jobs, consider tuning **task parallelism,** optimizing **state backends**, configuring **efficient checkpoint intervals**, and leveraging Flink’s **built-in windowing mechanisms.** Ensuring your data streams are partitioned evenly and using the right state storage options (like RocksDB) can also significantly enhance performance.
### What tools are available for monitoring Flink jobs and clusters?
Several effective tools exist for monitoring Flink jobs and clusters, including **Flink's built-in web dashboard**, which provides comprehensive job and cluster metrics. Additionally, external monitoring systems such as **Prometheus**, **Grafana**, and commercial platforms like [**Ververica's Unified Streaming Data Platform**](https://www.ververica.com/product) offer advanced monitoring capabilities, real-time alerts, and detailed performance analytics.
### How does real-time data streaming with Flink drive business decision-making?
Real-time data streaming with Flink enables immediate data analysis and actionable insights, allowing businesses to make faster, more informed decisions. This capability **improves responsiveness**, helps identify **opportunities** and threats as they occur, and **enhances customer experiences** through real-time personalization and timely interventions.
---
---
title: "Fluss White papre"
description: "Apache Fluss® is an open-source, lakehouse-native storage layer designed to unify the fragmented infrastructure that real-time analytics, Machine Learning (ML) pipelines, and AI systems require. This paper traces the architecture that makes that possible, from the storage engine internals to the stateless compute model to the unified feature and context store. "
lastUpdated: 2026-09-04T07:25:11.000Z
source_url:
html: "https://www.ververica.com/asset-library/fluss-white-paper"
md: "https://www.ververica.com/asset-library/fluss-white-paper.md"
---
# Apache Fluss®: The Foundation of the Unified Streaming Lakehouse
A Lakehouse-native streaming storage for real-time analytics, context engineering, and AI.
## Apache Fluss
Apache Fluss® is an open-source, lakehouse-native storage layer designed to unify the fragmented infrastructure that real-time analytics, Machine Learning (ML) pipelines, and AI systems require.
This paper traces the architecture that makes that possible, from the storage engine internals to the stateless compute model to the unified feature and context store.
## Real-time AI systems demand infrastructure you don't have.
No organization builds a real-time AI data platform from scratch. They arrive at it through a sequence of expanding ambitions: streaming ingestion, then analytics, then event processing, then ML features, then AI systems.
Each stage adds a new specialized system. A message broker. A stream processor. An online store. An offline store. A synchronization layer. Every boundary between the systems is a seam where data silently diverges.
## Storage for real-time analytics.
What if a single storage layer could collapse all requirements at once? The synchronization problem doesn't get managed. It disappears. No data divergence, one unified solution.
---
---
title: "What is Stream Processing"
description: "Unlock real-time, fault-tolerant data pipelines using stream processing with Apache Flink. Discover key concepts, tools, and more with Ververica"
lastUpdated: 2026-04-15T12:43:14.000Z
source_url:
html: "https://www.ververica.com/ecosystem-introduction/stream-processing-with-apache-flink-beginners-guide"
md: "https://www.ververica.com/ecosystem-introduction/stream-processing-with-apache-flink-beginners-guide.md"
---
# How to "Do" Stream Processing with Apache Flink®
Unlock real-time, fault-tolerant data pipelines using stream processing with Apache Flink. Discover key concepts, tools, and more with Ververica
## A Beginner's Guide to Real-Time Data Processing
> **INFO:** To “do” stream processing with Apache Flink, you build applications that continuously process unbounded data streams. You define Sources to ingest data, apply Transformations to process it (e.g., filter, aggregate, join using Flink's DataStream API or Flink SQL), and direct the results to Sinks (e.g., a database or another message queue). Flink ensures fault tolerance via checkpointing and handles event time for accurate results.
Using [Ververica's Unified Streaming Data Platform](https://www.ververica.com/product?hsLang=en) enhances this by providing enterprise-grade capabilities for simplified deployment, monitoring, and scaling. Ververica is powered by VERA, the engine that revolutionizes Flink by boosting Flink's performance. In addition, the Ververica ecosystem includes Apache Paimon, which enables real-time updates on data lakes, and Apache Fluss, which provides unified, low-latency storage for analytical queries on streaming data.
Whether from website clicks or sensor readings, financial transactions or social media updates, data is constantly being generated. To meet modern business demands, the ability to process this continuous stream of information in real time and extract immediate insights has become a necessity. This is where stream processing comes in and [Apache Flink](https://www.ververica.com/what-is-apache-flink?hsLang=en) stands as a leading stream processing framework at its forefront.
This guide will introduce you to Apache Flink, explain how to do stream processing with Apache Flink, and highlight the key differences and advantages of using Ververica's Unified Streaming Data Platform enterprise-grade capabilities, including the VERA engine, Apache Paimon, and Apache Fluss, to build a robust real-time data and stream processing solution.
## What is Apache Flink?
At its core, [Apache Flink](https://www.ververica.com/what-is-apache-flink?hsLang=en) is an open-source, distributed stream processing framework designed for high-performing, fault-tolerant, and stateful computations over unbounded (continuous) and bounded (batch) data streams. Unlike traditional systems that process data in fixed chunks or "batches," Flink processes data as it arrives, enabling real-time responses to dynamic events.
Here's what makes Apache Flink a unique and powerful choice for data stream processing:
- **Unified Batch and Stream Processing:** Flink famously treats batch data as a finite stream. This "stream-first" approach means you can use the same APIs and programming model for both real-time streams and historical datasets, simplifying development and maintenance.
- **Stateful Computations:** Many real-world applications need to remember information about past events to process current ones (e.g., counting unique users over time, tracking session activity). Flink offers robust, fault-tolerant state management, ensuring that your application's memory of past events is reliable, even if something goes wrong.
- **Fault Tolerance:** Flink guarantees that your data processing will be accurate even in the face of machine failures. It achieves this through a mechanism called "checkpointing," which periodically saves the state of your application. If a failure occurs, the job can restart from the last successful checkpoint, ensuring exactly-once processing semantics, meaning each event is processed precisely once, avoiding duplicates or data loss.
- **Event Time Processing:** Data events often don't arrive in the exact order they occurred. Flink's "event time" processing and "watermarks" allow it to correctly process events based on their actual occurrence time, even if they arrive late or out of order, which is critical for accurate real-time analytics.
## Introduction to Apache Flink Stream Processing (for Beginners)
To understand how to "do" stream processing with Apache Flink, let's look at its basic building blocks.
At the most simplistic level, a Flink stream processing application consists of three main parts:
**1) Sources:** These are where data streams originate. Flink can connect to a wide variety of data sources that produce continuous streams, such as:
- **Message Queues:** Apache Kafka, Apache Pulsar, AWS Kinesis.
- **Databases**: Using Change Data Capture (CDC) connectors to read real-time changes from databases like MySQL, PostgreSQL, or Oracle.
- **File Systems:** Reading new files as they appear in directories.
**2) Transformations:** This is the core logic where you process your data. Flink provides a rich set of operators to transform, filter, aggregate, and enrich your data streams. Some common transformations include:
- **Map**: Apply a function to each individual element in the stream (e.g., convert temperature from Kilograms to Pounds).
- **Filter**: Selectively keep or discard elements based on a condition (e.g., only process transactions over $10).
- **KeyBy**: Group elements by a specific key. This is essential for stateful operations or aggregations on specific groups (e.g., count of sales per product ID).
- **Windowing**: Process data within specific time boundaries.
- **Tumbling Windows:** Fixed-size, non-overlapping windows (e.g., sum sales every 5 minutes).
- **Sliding Windows:** Fixed-size, overlapping windows (e.g., sum sales over the last 5 minutes, updated every 1 minute).
- **Joins**: Combine data from two or more streams (e.g., join user click data with user profile data).
- **Aggregations**: Compute sums, counts, averages, min/max over windows or groups.
**3) Sinks:** These are where the processed data streams are sent. Flink can write data to various destinations, including:
- **Message Queues:** Sending processed events back to Kafka or other queues.
- **Databases**: Updating real-time dashboards or operational databases.
- **File Systems/Object Storage:** Storing processed data for later analysis (e.g., on S3, HDFS).
- **Dashboards/Monitoring Tools:** Directly feeding data to visualization tools.
**Programming Flink:** You can write Apache Flink applications using its DataStream API (in Java or Scala for fine-grained control) or Flink SQL, which allows you to process streams using standard SQL queries, making stream processing more accessible to a wider audience familiar with relational databases.
## Apache Flink Use Cases and Best Practices
Apache Flink excels in scenarios where real-time responsiveness, high throughput, and data accuracy are paramount.
### Real-World Apache Flink Use Cases:
- **Real-Time Fraud Detection:** Flink can analyze financial transactions as they happen, using [Complex Event Processing (CEP)](https://www.ververica.com/blog/real-time-fraud-detection-using-complex-event-processing?hsLang=en) to detect suspicious patterns (e.g., multiple transactions from different locations within seconds) and trigger immediate alerts or blocks. Ververica provides detailed insights into real-time fraud detection using Flink and CEP.
- **Customer 360 & Personalization:** By processing customer interactions like clicks, purchases, and browsing history in real-time, Flink helps build a unified, continuously updated view of each customer, enabling personalized recommendations and dynamic pricing. An example of this is seen in real-time feature engineering for e-commerce, like [KartShoppe's use case](https://www.ververica.com/blog/kartshoppe-real-time-feature-engineering-with-ververica?hsLang=en).
- **IoT Analytics & Predictive Maintenance:** Flink can ingest massive streams of sensor data from industrial machinery or smart devices, detect anomalies, and predict equipment failures before they occur, optimizing maintenance schedules.
- **Real-Time ETL (Extract, Transform, Load):** Modern ETL pipelines are moving from batch to stream. Flink performs [continuous transformations on data as it moves](https://www.ververica.com/use-case/extract-transform-load?hsLang=en) from source to destination, eliminating batch delays and providing fresh data for analytics.
- **Security Information and Event Management (SIEM):** Flink is used to process security logs in real-time [detecting threats, policy violations, and unusual activities](https://www.ververica.com/use-case/security-information-and-event-management?hsLang=en) as they unfold, enabling immediate incident response.
- **Airlines & Logistics:** Optimizing operations by correlating real-time events like flight delays, gate changes, and baggage handling. Flink enables [real-time insights for airlines](https://www.ververica.com/case-study/airbus?hsLang=en) with Complex Event Processing.
### Best Practices for Apache Flink Applications:
- **Understand Event Time:** Design your application around event time and watermarks for accurate results, especially with out-of-order data.
- **Manage State Efficiently:** For stateful jobs, understand how Flink manages state, choose appropriate state backends, and optimize state serialization to ensure performance and fault tolerance.
- **Parallelism Tuning:** Configure the parallelism of your Flink job to match your available resources and the volume of your data. Too little means bottlenecks, too much can waste resources.
- **Monitor Backpressure:** Regularly monitor for backpressure indicators, as this signals that parts of your pipeline are slowing down, which impacts latency and throughput.
- **Leverage Flink SQL:** For simpler transformations and aggregations, Flink SQL often provides a faster development cycle and is more accessible to data analysts.
## Open Source Apache Flink vs. Ververica’s Unified Streaming Data Platform Enterprise-Grade Capabilities
While open-source Apache Flink is incredibly powerful and “free” to use, running it at scale in a production enterprise environment comes with its own set of challenges.
### Challenges with Open Source Apache Flink:
- **Operational Complexity:** Deploying, upgrading, scaling, and managing Flink clusters, especially in cloud environments, requires significant DevOps expertise.
- **Monitoring & Debugging:** Setting up comprehensive monitoring, alerting, and debugging tools for distributed Flink applications can be complex and time-consuming.
- **State Management at Scale:** While Flink handles state, optimizing its performance for very large, highly concurrent stateful applications can be challenging without deep expertise.
- **High Availability & Disaster Recovery:** Ensuring seamless failover and disaster recovery in self-managed Flink setups requires careful planning and robust infrastructure.
- **Security & Governance:** Implementing enterprise-grade security features, access controls, and data governance policies across Flink deployments can be intricate.
- **Total Cost of Ownership (TCO):** The operational overhead and the need for specialized engineering teams can lead to a higher TCO than initially perceived.
### Ververica Platform Capabilities for Stream Processing
Ververica's Unified Streaming Data Platform addresses these challenges head-on, providing an integrated, enterprise-ready solution for stream processing with Apache Flink. In addition to being 100% compatible with open-source Flink, it also transforms the power of Flink into a managed, [production-ready offering](https://www.ververica.com/apache-flink-vs-ververica?hsLang=en) with features designed to simplify operations and accelerate value, including:
- **Application Lifecycle Management:** Simplifies the deployment, versioning, and scaling of Flink applications. You can quickly deploy jobs, manage updates, and scale resources up or down with ease.
- **Monitoring and Observability:** Provides a user-friendly interface for tracking job metrics, resource utilization, and debugging, offering deep insights into your stream processing pipelines.
- **High Availability and Fault Tolerance:** Streamlines the setup and management of resilient Flink clusters, ensuring your critical data stream processing applications are always available.
- **Enterprise Security:** Offers end-to-end encryption, flexible access control, and integrates with cloud-native security tools, aligning with [zero-trust principles](https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment?hsLang=en).
- **Cost Efficiency & Performance at Scale:** Complements Flink's high-performance runtime with autoscaling and capacity planning capabilities, ensuring optimal resource utilization and reducing TCO, sometimes reporting **40% lower TCO** than alternative Flink solutions [as mentioned in the VERA whitepaper](https://www.ververica.com/vera/whitepaper?hsLang=en).
- **Turn-Key Solution:** Comes with all required dependencies for cloud and on-premise deployments, providing a highly available stream processing runtime and an integrated development environment for Flink SQL.
## Enhancing Performance and Capabilities: VERA, Apache Paimon, and Apache Fluss
Ververica's Unified Streaming Data Platform extends Apache Flink's capabilities even further with innovative components like the VERA engine, Apache Paimon, and Apache Fluss, creating a comprehensive ecosystem for advanced data stream processing.
### VERA Engine: Revolutionizing Apache Flink's Performance
The VERA engine (Ververica Runtime Assembly) is Ververica's cloud-native, ultra-high-performance runtime that sits at the core of the Unified Streaming Data Platform. VERA optimizes open-source Apache Flink to deliver unprecedented speed and efficiency:
- **Ultra-High Performance:** VERA is designed for extreme throughput and low latency, capable of processing billions of events per second with millisecond-level delays. This makes stream processing flink significantly faster than open source Flink and any alternatives.
- **Optimized Stateful Computations:** VERA includes an advanced state engine ("Gemini") that replaces standard Flink state backends like RocksDB, delivering superior performance in state-intensive, large-scale stream processing environments. This is crucial for applications that manage vast amounts of continuous state.
- **Cloud-Native & Elastic Scale:** VERA separates compute and storage, allowing for effortless scaling of large stateful applications, ensuring consistent performance even as data volumes fluctuate.
### Apache Paimon: The Stream Native Data Lakehouse
For persisting and querying streaming data efficiently, Apache Paimon is a game-changer. As a stream-native data lakehouse format, Paimon enables Apache Flink to continuously write and update data directly on a cost-effective data lake (like S3), forming the foundation of [Ververica's Streamhouse concept](https://www.ververica.com/streamhouse?hsLang=en).
- **Real-Time Updates:** Paimon allows Flink jobs to perform real-time upserts and updates on data lake tables, ensuring that analytical queries always reflect the freshest data with low latency.
- **Unified Batch and Stream Access:** Paimon tables can be accessed by both stream processing jobs (for continuous updates) and batch queries (for historical analysis), creating a single source of truth for all data.
- **Cost-Efficient Storage:** It leverages affordable object storage while offering data warehouse-like properties (ACID transactions, schema evolution), making large-scale data stream processing more economical.
### Apache Fluss: Unified Streaming Storage for Next-Gen Analytics
Apache Fluss is a groundbreaking unified streaming storage layer designed specifically for high-performance, low-latency analytical access to streaming data. It integrates deeply with Apache Flink to simplify analytical pipelines:
- **Sub-Second Latency Analytics:** Fluss offers sub-second latency for both writing streaming data and querying it, making it ideal for real-time dashboards and interactive analytics.
- **Eliminates Intermediaries:** Fluss can replace the need for separate message queues (like Kafka) and traditional OLAP systems for analytical workloads, simplifying your architecture and reducing costs.
- **Columnar Reads & Projection Pushdown:** Its columnar format and intelligent "projection pushdown" feature optimize read performance, fetching only necessary data and significantly boosting analytical query throughput.
## Conclusion
Stream processing with [Apache Flink](https://www.ververica.com/what-is-apache-flink?hsLang=en) represents the modern approach to handling data, moving beyond the limitations of traditional batch processing to embrace real-time insights and event-driven architecture. For beginners looking to dive into this exciting field, Apache Flink offers a powerful and flexible stream processing framework.
While open-source Flink provides immense capabilities [Ververica's Unified Streaming Data Platform](https://www.ververica.com/product?hsLang=en) transforms it into an enterprise-ready solution, simplifying operations, ensuring reliability, and providing advanced tooling. When combined with the performance acceleration of the [VERA engine](https://www.ververica.com/vera?hsLang=en), the unified streaming storage capabilities of Apache Paimon (for your [Streamhouse](https://www.ververica.com/streamhouse?hsLang=en)), and the low-latency analytical power of Apache Fluss, Ververica's Unified Streaming Data Platform offers a comprehensive ecosystem to build, deploy, and manage the most demanding data stream processing applications, truly unlocking the value of real-time data for any enterprise.
## FAQ
### What is stream processing with Apache Flink?
Stream processing with Apache Flink is a method of analyzing and acting on data in real time as it arrives, using Flink's distributed engine to process continuous data streams.
### How does Apache Flink differ from batch processing?
Apache Flink processes data as it flows in (real time), while batch processing handles fixed groups of data at scheduled intervals, making Flink ideal for instant analytics and decision-making.
### What are the main components of an Apache Flink streaming application?
Key components include Sources (data inputs), Transformations (operations like filtering and aggregating), and Sinks (outputs such as databases or dashboards).
### How does Apache Flink achieve fault tolerance and exactly-once processing?
Flink uses checkpointing and advanced state management to recover from failures, ensuring each event in the stream is processed exactly once.
### What are common use cases for Apache Flink stream processing?
Typical applications include real-time fraud detection, IoT analytics, personalized recommendations, security monitoring, and real-time ETL for data pipelines.
---
---
title: "BYOC ToS"
description: "Review the terms governing your subscription to Ververica Cloud's Bring Your Own Cloud Services, outlining user responsibilities, data management, and more"
lastUpdated: 2026-04-14T17:56:23.000Z
source_url:
html: "https://www.ververica.com/product/deployment/byoc/terms-of-service"
md: "https://www.ververica.com/product/deployment/byoc/terms-of-service.md"
---
# Terms of Service
**Last update: December 8th, 2025**
Ververica Cloud: Bring Your Own Cloud
If User has entered into an Order Form with Ververica GmbH that includes a subscription for Ververica Cloud Bring Your Own Cloud Services offering, User’s access to and use of the BYOC Services (as defined below) is governed by these BYOC Terms of Service (“**BYOC Terms**”), which apply in addition to the general [Ververica Terms of Service](https://www.ververica.com/terms-of-service?hsLang=en) (the “**Terms**”) and are incorporated into the Agreement by and between User and Ververica GmbH. All capitalized terms used herein without definition will have the same meanings set forth in the Terms.
## 1. DEFINITIONS
For the purposes of these Ververica Cloud Bring You Own Cloud Terms, the below terms are defined as follows:
1. “BYOC Services” means Ververica Cloud Bring Your Own Cloud Services.
1. “Cloud Environment” means a cloud environment hosted by a Supported Cloud Provider.
1. “Supported Cloud Provider” means a third party cloud hosting or similar services provider approved and supported by Ververica GmbH.
1. “Agent Service” means a service that connects from User’s Cloud Environment to Veverica Cloud. Agent service is used to manage Ververica services running in User’s Cloud Environment and is managed by User via helm/kubectl tooling.
1. “Ververica Software” means Ververica BYOC Services software packages, distributed via public Ververica software repository to be deployed in User’s Cloud Environment.
## 2. GENERAL
1. If set forth on an applicable Order Form, in order to enhance User’s use of the Software, User hereby enters into a subscription for BYOC Services. User shall provision the Software in the User’s Cloud Environment with sufficient access to allow Ververica to access, manage, provision and monitor the Software. Subject to User’s compliance with the Agreement and payment of all applicable fees, Ververica will use commercially reasonable efforts to access the Software and provide to Users the BYOC Services as set forth in the applicable Order Form, which shall consist generally of Ververica providing to User solely through the User’s Cloud Environment, the Support Services, upgrading of the Software.
## 3. USER RESPONSIBILITIES
1. User acknowledges and agrees that User is responsible for assuring that Ververica has timely access to the User’s Cloud Environment for the software stated in related Ververica Documentation, including all applicable credentials for accessing Supported Cloud Provider Services and that User, and not Ververica, shall be solely responsible and liable for any delay in implementation, deployment or performance of BYOC Services that is caused to any extent by User’s delay or failure to provide such access.
1. User acknowledges and agrees that User is responsible for:
1. securing the User’s Cloud Environment;
1. backing up and securing User’s data under User’s control within the User Cloud Environment;
1. management and upgrades of Ververica Agent Service as per Ververica Documentation release lifecycle policies or in case of any emergency, industry-level vulnerability;
1. managing all Cloud Resources in User’s Cloud Environment as specified via Ververica Documentation;
1. making sure there is enough User Cloud allocated resources; and
1. making sure there is no alternation nor changes to Ververica Software in User’s Cloud Environment, unless expressly permitted by Ververica.
## 4. VERVERICA RESPONSIBILITIES
1. Ververica acknowledges and agrees that, as between the Parties and except to the extent caused by the action or intentional or negligent inaction of User or User’s users, including without limitation any customizations or configurations of the Software by User or anything specified to be User’s responsibility, Ververica is primarily responsible for:
1. the operation of elements of the Ververica Services residing within the Ververica Cloud Environment, excluding the Agent Service and
1. implementing reasonable technical and organizational measures designed to protect the security of the foregoing.
## 5. SHARED RESPONSIBILITIES MODEL
1. User acknowledges that the BYOC Services are implemented in a manner that divides the responsibility for the Software between the User’s Cloud Environment and the Ververica Cloud Environment, and that accordingly each Party must undertake certain technical and organizational measures in order to protect the Software, the Services and User’s data in accordance with this Section 5.
1. This division of responsibility is described further in Ververica’s Shared Responsibility Model, and may be updated and amended from time to time. Without limiting the foregoing, User acknowledges and agrees that:
1. in order to utilize the BYOC Services, User must have an account for Supported Cloud Provider Services;
1. Ververica does not host the User’s Cloud Environment into which the Software is deployed or in which User’s data may be stored;
1. the BYOC Services are not designed to archive or permanently retain User’s data, but merely to provide an environment to facilitate User’s processing of User’s data within the Users Cloud Environment;
1. provision and maintain required access in regards to Users Cloud Resources and Ververica software to be deployed and managed within User’s cloud account per Ververica documentation.
1. Ververica and the BYOC Services do not provide backup services or disaster recovery to enable recovery of User’s data. Accordingly, Ververica is not responsible for any loss, destruction, alteration, or corruption of User’s data, except to the extent caused by the gross negligence or willful misconduct of Ververica.
## 6. USERS DATA
1. User understands and agrees that, in using the Services, the User shall provide Ververica with such data (“**Required Operational Data**”) as Ververica may reasonably request from time to time to enable Ververica to provide and operate the BYOC Services (including, without limitation, support and troubleshooting). The Required Operational Data shall at least include: (i) Telemetry data – such as metrics related to resource utilization (e.g., CPU, memory, disk, and service usage metrics) generated by the User’s deployment of the BYOC Services; and (ii) System logs – such as infrastructure- and service-level logs (including Kubernetes or other infrastructure-related logs and Ververica service logs), which are required for troubleshooting, monitoring, and ensuring the correct operation of the BYOC Services.
Additional Required Operational Data may be described in the applicable Ververica Documentation or otherwise communicated to the User during the course of service use.
1. Ververica will use such data solely for all problem resolution purposes, including but not limited to:
1. providing User with safe and stable BYOC Services, such as troubleshooting or debugging for the BYOC Services;
1. responding to User’s queries, feedback, claims or disputes;
1. complying with applicable law, legal process, or lawful government request, or in respect of any claims or potential claims brought against Ververica or affiliates.
For clarity, Ververica will have no access to, and the User expressly does not grant Ververica any right or permission to access, the underlying infrastructure of the User’s environment—including, without limitation, virtual machines, host systems, network configurations, or any Kubernetes cluster infrastructure managed by the User. User retains sole and exclusive responsibility for the security, configuration, maintenance, and operation of such infrastructure.
1. If the aforementioned data includes personal data, you can refer to our Privacy Policy to understand how we use and protect user personal data. To avoid any doubts, Ververica is the controller of personal data only when it collects personal data and determines the purposes and means of processing that personal data. For example, when User registers an account with us or provides contact information in order to receive customer support, we are the controller of that data. When User host their own services on Ververica Cloud, we act as a data processor with respect to that data.
## 7. SECURITY
1. Ververica and User will, consistent with industry standard practices, implement and maintain administrative and technical safeguards and other security measures in respect of the BYOC Services.
## 8. EFFECT OF TERMINATION
1. The terms of Sections 3 and 4 of these BYOC Terms will survive the expiration or termination thereof for any reason in accordance with their terms.
**Ververica GmbH**
Herzogspitalstrasse 24
80331 München
E-Mail: [info@ververica.com](mailto:info@ververica.com)
---
---
title: "Ververica Preview Policy"
description: "Discover Ververica's Preview Program Policy, outlining terms for using its beta features, confidentiality obligations, and responsibilities."
lastUpdated: 2026-04-21T12:19:27.000Z
source_url:
html: "https://www.ververica.com/preview-policy"
md: "https://www.ververica.com/preview-policy.md"
---
# Ververica Preview Policy
**Last update: May 14th 2025**
This Ververica Preview Policy (“**Preview Policy**”) applies to the use by the entity client on whose behalf this Preview Policy is accepted (“**Client**”) of the Preview (as defined below) provided by Ververica GmbH (“**Ververica**”). The individual agreeing to this Preview Policy represents and warrants that it is authorized to accept this Preview Policy on behalf of its entity as an authorized representative of such entity.
By clicking the “Accept” button or by downloading, installing, accessing or using any function of the Preview, the Client agrees to be bound by the terms of this Preview Policy. If the Client does not agree to the terms of this Preview Policy, the Client may not use the Preview.
Ververica reserves the right to alter, modify, add to or otherwise vary this Preview Policy by notice in writing to the Client at any time. The Client shall be bound by this Preview Policy so amended, and such other terms as may be incorporated by reference. In any event, if the Client continues to download, install, access and/or use the Preview after such notice, the Client shall be deemed to have accepted the amendment.
## 1. DEFINITIONS
1. “Confidential Information” means any information, technical data or know-how, including without limitation, that which relates to Ververica’s computer software programs, documentation, specifications, source code, object code, research, inventions, processes, designs, drawings, engineering, products, services, customers, benchmark tests, markets, prices, or finances, which is identified as confidential either orally or in writing at the time of disclosure, or, in the alternative, should reasonably be considered Confidential Information. Confidential Information will not include any information that:
1. has been or is obtained by the Client from an independent source without obligation of confidentiality,
1. is or becomes publicly available other than as a result of an unauthorized disclosure by the Client or its personnel, or
1. is independently developed by the Client without reliance in any way on the Confidential Information disclosed.
1. “Documentation” means Ververica’s standard user manuals generally made available to Clients which is available as an online version only. The Documentation constitutes an integral part of this Preview Policy and will be made available to the Client and, in any event, as part of the Preview.
1. “Preview”means any features, technologies, services, software, regions, or any other products made available to the Client by Ververica that are not yet generally available, including but not limited to any products, services, or features labeled as “beta”, “preview”, “pre-release”, or “experimental”. The Preview encompasses both Private Preview and Public Preview.
1. Private Preview means the Preview made available only to certain clients by invitation extended by Ververica.
1. Public Preview means the Preview made accessible to all clients in accordance with this Preview Policy.
## 2. LICENSE
1. Licenses.
1. Preview License. Subject to the terms and conditions of this Preview Policy, Ververica hereby grants to the Client a non-exclusive, non-transferable, non-sublicensable license to use the Preview solely in a non-production environment for the purposes of testing, research, and evaluation.
1. Documentation License. Subject to the terms and conditions of this Preview Policy, Ververica hereby grants to the Client a non-exclusive, non-transferable, non-sublicensable license to make copies of the Documentation provided by Ververica, solely for the Client’s internal use and solely for the purpose of exercising the rights granted in Section 2(a)(i). The Client acknowledges that no right is granted to modify, adapt, translate, publicly display, publish, create derivative works or distribute the Documentation.
1. Ververica may, at any time and in its sole discretion, add or modify restrictions under this License, including lowering or raising any usage limits pertaining to the access or use of any Preview.
1. Limitations. Subject to any mandatory rights granted to the Client under applicable law, the Client will not:
1. assign, sublicense, transfer, lease, rent or distribute any of its rights in the Preview;
1. port, translate, localize, modify, or create derivative works based on the Preview or Documentation in any manner whatsoever;
1. reverse assemble, decompile, reverse engineer, translate, or otherwise attempt to derive or obtain the source code, underlying ideas, algorithms, structure, or organization of the Preview;
1. copy or duplicate the Preview; or
1. publish any benchmark testing results regarding any Preview without Ververica’s prior written consent.
1. Open Source. The Client acknowledges that the Preview contains, is based on, or refers to open source components. This Preview Policy does not apply to those open source components. The use of such open source components is subject to the applicable open source license terms, which Ververica will provide to the Client when the Preview is made available.
1. Third-Party Restrictions. The Client will undertake all measures necessary to ensure that its use of the Preview complies in all respects with any contractual or other legally binding obligations of Ververica to any third party, provided that Ververica has notified Client with respect to such obligations.
1. Ownership and Reservation of Rights. Except for the licenses expressly granted to the Client under this Section 2, Ververica and its suppliers or licensors (as the case may be) retain all rights, title, and interests in and to the Preview, Documentation, and all copies thereof, including any improvements, modifications, or enhancements thereto, which shall remain the property of Ververica or its suppliers or licensors. No other rights, express or implied, are granted to the Client hereunder.
## 3. OBLIGATIONS OF CLIENT
1. The Client shall comply with all Documentation, policies, and guidelines related to the Preview provided to the Client, and shall be solely responsible for obtaining and installing all proper hardware and support software (including, but not limited to, operating systems, network devices and network systems)to ensure: (i) the appropriate installation of and training regarding the Preview; and (ii) the proper exercise of the licenses granted hereunder. Ververica shall have no responsibility or liability for any unavailability, failure of, nonconformity, or defect in the Preview that is caused by or related in any manner to the Client’s failure to obtain and maintain such software or hardware.
1. The Client will be solely responsible for creating and maintaining backups, security updates and compatible versions of all data used in connection with the Preview.
1. The Client shall undertake all measures necessary to ensure that its use of the Preview complies in all respects with applicable laws, statutes, regulations, ordinances or other rules promulgated by governing authorities having jurisdiction over the Client or the Preview.
## 4. FEEDBACK
1. The Client agrees to provide feedback to Ververica concerning the functionality and performance of Preview, at Ververica’s reasonable request, including but not limited to identifying potential errors and suggesting improvements (“**Feedback**”). All rights in such Feedback shall be owned by Ververica, and Ververica may use such Feedback for any purpose, including to improve or enhance its products. The Client shall not use any Feedback for any purpose other than its internal evaluation of Preview.
1. The Client shall warrant that: (i) the Feedback does not infringe any rights (including patents, copyright or trade secrets) of any third party; (ii) the Feedback is not subject to any license terms that would purport to require Ververica to comply with any additional obligations with respect to any of Ververica’s products or services that incorporates the Feedback.
1. The Client acknowledges that Ververica may obtain information and data from the Client in connection with its registration, installation, and use of the Preview. Ververica may also collect and process technical and related environmental or performance information regarding the Client’s use of the Preview (including but not limited to number of unique user log-ins, Internet protocol addresses, operating system), and use this information to support and troubleshoot issues, provide updates, analyze trends and improve Ververica’s products or services. The Client hereby agrees to comply with the Ververica’s [Privacy Policy](https://www.ververica.com/privacy-policy), and consent Ververica to collecting, maintaining, using, storing, processing and disclosing such information and data for the purposes described herein.
## 5. SUPPORT AND MAINTENANCE SERVICES
1. Ververica will have no obligation to provide or perform any support, maintenance and professional services for or on behalf of Client. Ververica is not responsible for any sort of problems or issues related to the use of Preview. Preview may be subject to reduced or different security, compliance and privacy commitments, as may be described in any additional notices provided with Preview. Certain named Preview may also be subject to additional terms as may be notified to the Client from time to time.
1. Ververica reserves the right to:
1. change or discontinue Preview at any time without notice;
1. choose not to release a Preview into general availability. Ververica shall under no circumstances be obligated to support, update, or upgrade the Preview.
1. Any support, maintenance, and professional services shall require the execution of a separate service agreement between the Parties.
## 6. NO FEES
1. The License will be granted free of charge. Ververica reserves the right to determine, at its sole discretion, the manner in which the Client obtains the License.
## 7. WARRANTY DISCLAIMER
1. Delivery. The Product will be delivered to the Client via a download link or through any other means or format as Ververica may determine in its sole discretion.
1. Disclaimer. PREVIEW IS NOT READY FOR GENERAL COMMERCIAL RELEASE AND MAY CONTAIN BUGS, ERRORS, DEFECTS, OR HARMFUL COMPONENTS AND IS SOLEY PROVIDED FOR LIMITED TESTING, RESEARCH, EVALUATION PURPOSES. PREVIEW IS DELIVERED “AS IS”, “WITH ALL FAULTS,” AND “AS AVAILABLE,”AND IS EXCLUDED FROM ANY SERVICE LEVEL AGREEMENTS AND LIMITED WARRANTIES APPLICABLE TO VERVERICA’S COMMERCIAL OFFERINGS. VERVERICA MAKES NO REPRESENTATIONS OR WARRANTIES OF ANY KIND, WHETHER EXPRESS, IMPLIED, STATUTORY, OR OTHERWISE REGARDING THE PREVIEW, DOCUMENTATION, AND RELATED SERVICES(IF ANY), INCLUDING, BUT NOT LIMITED TO, ANY WARRANTY THAT THE PREVIEW WILL BECOME GENERALLY AVAILABLE, BE UNINTERRUPTED, ERROR-FREE, OR FREE OF HARMFUL COMPONENTS, OR THAT ANY CONTENT, INCLUDING THE CLIENT’S CONTENT, WILL BE SECURE OR NOT OTHERWISE LOST OR DAMAGED. EXCEPT TO THE EXTENT PROHIBITED BY APPLICABLE LAWS AND/OR REGULATIONS, VERVERICA EXPRESSLY DISCLAIMS ALL WARRANTIES RELATED TO THE PREVIEW, DOCUMENTATION AND RELATED SERVICES(IF ANY), EXPRESS OR IMPLIED, INCLUDING, BUT NOT LIMITED TO, IMPLIED WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE, ACCURACY, SECURITY, NO INFRINGEMENT, QUIET ENJOYMENT, COURSE OF DEALING OR USAGE OF TRADE.
## 8. NONDISCLOSURE AND CONFIDENTIALITY
1. Nondisclosure Obligations. All Confidential Information provided to the Client by Ververica under this Preview Policy:
1. will not be copied, distributed, disclosed, or disseminated by the Client to anyone except its own employees, agents, or contractors (collectively, the “**Related Parties**”), who have a reasonable need to know such Confidential Information. The Client shall ensure that the Related Parties comply with the confidentiality obligations set forth herein and shall be jointly and severally liable for the acts and omissions of the Related Parties in connection with such obligations;
1. will be treated by the Client with the same degree of care as is used to protect the Client’s own information of similar importance, but in no event with less than reasonable care;
1. will not be used by the Client for its own purposes or any other purpose except as expressly permitted under this Preview Policy, without Ververica’s express written permission; and
1. will remain the property of Ververica and must be returned to Ververica or destroyed in accordance with Ververica’s instructions within thirty (30) days of the Client’s receipt of a written request from Ververica identifying the Confidential Information to be returned or destroyed, or upon expiration or termination of this Preview Policy.
1. Compelled Legal Disclosure. In the event the Client becomes legally compelled to disclose any Confidential Information, the Client will provide Ververica with prompt prior written notice of such requirement and the Client will reasonably cooperate in any effort by Ververica to petition the authority compelling such disclosure for an order that such disclosure not occur or that it occur pursuant to terms and conditions designed to ensure continued confidentiality or minimized disclosure.
1. The confidentiality provisions of this Sec. 8 shall survive termination or expiration of this Preview Policy.
## 9. INDEMNIFICATION
1. The Client will indemnify, defend, and hold harmless Ververica, its directors, officers, employees, and representatives from and against any and all losses, damages, liabilities, costs, and expenses (whether awarded by a court or agreed upon in settlement), as well as all reasonable and related attorneys’ fees and court costs, resulting from any third-party claim based on:
1. a breach by the Client of any term of this Preview Policy; or
1. if the alleged claim is based, in whole or in part, on any of the following:
1. any modification, servicing or addition made to the Preview or any part thereof by the Client;
1. the Client’s use of the Preview in a manner outside the scope of any rights granted or in violation of this Preview Policy;
1. the use of the Preview or any part thereof in combination with materials, devices, parts, software, or processes not provided or approved by Ververica;
1. Ververica’s compliance with the Client’s requirements or specifications, if any; or
1. the use of any version of the Preview other than the then-current, unaltered release available from Ververica.
## 10. LIMITATION OF LIABILITY
1. Notwithstanding any other provision of this Preview Policy, except as set forth in this Sec.10, the aggregate liability of Ververica, its employees, agents, affiliates, representatives or anyone acting on its behalf with respect to the Client for any and all claims arising from or in connection with the Preview or the use or inability to use the same shall, if not otherwise excluded or limited, be limited to, in aggregate, the greater of (a) the amount of fees you have paid to Ververica for the Preview during the calendar year, or (b) [USD100]. The preceding sentence shall not preclude the requirement by you to prove actual damages. All claims against Ververica in respect of any of the matters referenced in this Section must be filed within one (1) year from the date the cause of action arose.
## 11. AUDITS AND CERTIFICATION OF COMPLIANCE
1. Audits. Ververica will have the right to audit Client’s records to verify compliance with the terms of this Preview Policy, upon reasonable written notice. All such audits will be conducted during normal business hours.
1. Certification. Ververica reserves the right to require that Client certify as to its usage and compliance with this Preview Policy.
## 12. TERMINATION
1. Ververica may suspend or terminate the Client’s access to or use of any Preview at any time and for any reason. Ververica may at any time cease providing any or all of any Preview in its sole discretion and without notice. The Preview also may be unavailable and/or their performance may be negatively affected by scheduled and unscheduled maintenance.
1. Each individual Preview will automatically terminate upon the release of the general availability of the applicable Preview in any region or upon notice of termination by Ververica. Notwithstanding anything to the contrary in these Terms, either the Client or Ververica may terminate the use of any Preview by Client at any time for any reason upon notice to the other party.
1. Notwithstanding anything to the contrary in this Preview Policy, after the conclusion of the Client’s participation in use of a Preview for any reason, (a) the Client will not have any further right to access or use the applicable Preview; (b) the Client’s content and/or data used in the applicable Preview may be deleted or inaccessible; and (c) the Client will immediately return and destroy all Confidential Information and any other materials related to the applicable Preview as instructed by Ververica.
## 13. OTHERS
1. Copyright and Trademark Notices. The Client will duplicate all proprietary notices and legends of Ververica and its suppliers or licensors upon any and all copies of the Ververica Product, including any Documentation, made by the Client. The Client will not remove, alter or obscure any such proprietary notice or legend.
1. Marketing. The Client agrees that Ververica shall be entitled to refer to the cooperation with the Client and to use the name and logo of the Client for marketing purposes, e.g. on Ververica’ website.
1. This Preview Policy supplements the [Terms of Service.](https://www.ververica.com/terms-of-service) In the event of any conflict or inconsistency between this Preview Policy and the Terms of Service regarding Preview-related matters, this Preview Policy shall prevail. Matters not covered in this Preview Policy shall be governed by the Terms of Service. Each provision of this Preview Policy is independently binding, and the invalidity, illegality, or unenforceability of any part of a term shall not affect the enforceability of the remaining provisions.
---
---
title: "Data Processing Addendum (DPA)"
description: "This Addendum outlines Ververica's responsibilities as a processor of personal data under Data Protection Legislation."
lastUpdated: 2026-04-14T12:40:10.000Z
source_url:
html: "https://www.ververica.com/dpa"
md: "https://www.ververica.com/dpa.md"
---
# Data Processing Addendum
**Last update: January 8th 2024**
## 1. SCOPE AND APPLICATION
This Addendum will apply, if required by Data Protection Legislation (as defined below) and only to the extent that, in providing the Ververica Cloud Services to You, Ververica processes as a processor of personal data contained in or generated in relation to the data that you run on the Ververica Cloud Services, cause to interface with the Ververica Cloud Services, submit to or upload into the Ververica Cloud Services for processing under your Account (the “**Data**”). This Addendum forms part of the Terms of Service and capitalised terms not defined herein will have the meaning given in the Terms of Service. In the event and to the extent of a conflict between the other terms of the Terms of Service and this Addendum, this Addendum shall prevail.
## 2. DEFINITIONS
In this Addendum:
1. “**controller**”, “**data subject**”, “**personal data**”, “**process**”, “**processor**” and “**supervisory authority**” each has the meaning given in the GDPR.
1. “**Data Protection Legislation**” means, as applicable: (i) GDPR, and in each case, any related national laws, legislation, rules or regulations, related to privacy and data protection (including legislation made under or in relation to (i)). For clarity, a reference to Data Protection Legislation, includes a reference to Data Protection Legislation as amended, modified, extended, re-enacted, consolidated or replaced from time to time.
1. “**GDPR**” means Regulation (EU) 2016/679.
1. “**Standard Contractual Clauses**” means the standard contractual clauses annexed to the European Commission's Implementing Decision 2021/914/EU of 4 June 2021 on standard contractual clauses for the transfer of personal data to third countries pursuant to Regulation (EU) 2016/679 of the European Parliament and of the Council (or any subsequent decisions) or as referred to in Article 46 GDPR. A copy of the Standard Contractual Clauses can be obtained at https://ec.europa.eu/info/law/law-topic/data-protection/international-dimension-data-protection/standard-contractual-clauses-scc,or by contacting us at [help@ververica.cloud](mailto:help@ververica.cloud).
## 3. DESCRIPTION OF PROCESSING
For the purposes of this Addendum, You (the controller or processor) appoint Ververica as Your processor to process the Data, for the duration of the Terms of Service, for the purpose of providing the Ververica Cloud Services to You (the “**Permitted Purpose**”).
## 4. DATA PROCESSING
In processing the Data under the Terms of Service, Ververica shall:
1. only process the Data on Your documented instructions unless required otherwise by applicable law;
1. ensure that all personnel authorised by Ververica to process the Data are subject to suitable confidentiality obligations;
1. implement and maintain appropriate technical and organisational measures, designed to protect the Data processed by Ververica against a personal data breach affecting such Data arising from a breach of Ververica’s security (a “**Security Incident**”). Ververica may change those measures from time to time, but not so as to reduce the level of protection for Data. In the event of a confirmed Security Incident, Ververica shall notify You without undue delay and shall provide reasonable information and cooperation to You so that You can fulfil any data breach reporting obligations You may have under (and in accordance with the timescales required by) applicable Data Protection Legislation. Ververica shall further take any reasonably necessary measures and reasonably necessary actions to remedy or mitigate the effects of the Security Incident, and shall keep You informed of all material developments in connection with the Security Incident;
1. be generally authorised to engage third party subcontractors to process the Data for the Permitted Purpose, provided that Ververica
1. shall remain fully liable for any of its subcontractors;
1. shall maintain an up-to-date list of such subcontractors (if any), which it shall update with details of any change in such subcontractors at least 10 days’ before any such change; and
1. shall impose data protection terms on any subcontractor it appoints to process any Data, that require it to protect such Data to at least the standard required by applicable Data Protection Legislation. You may object to Ververica’s appointment or replacement of such a subcontractor before its appointment or replacement, provided such objection is based on reasonable grounds relating to data protection. In such event, Ververica will either not appoint or replace the relevant subcontractor or, if this is not possible, You may terminate the relevant Ververica Cloud Services and this Addendum to the extent it applies to the Ververica Cloud Services, but without prejudice to any fees or costs incurred by You for the Ververica Cloud Services before that termination and without prejudice to the Terms of Service, any other services provided to You, and any fees or costs in relation to those other services;
1. assist You to respond to data subjects’ requests to exercise their rights regarding any Data under applicable Data Protection Legislation by providing You with technical measures to enable You, to the extent consistent with the functionality of the Ververica Cloud Services and Ververica’s role as a processor, to access, rectify, erase, restrict or export Data directly (and You agree that, taking into account the nature of the processing, this paragraph reflects the extent to which it is possible for Ververica to provide You with such assistance). If a data subject, supervisory authority or any other party directly approaches Ververica with any request, query or complaint regarding any Data, Ververica shall, promptly notify You accordingly or notify that person that they should approach You instead;
1. If Ververica believes or becomes aware that its processing of the Data is likely to result in a high risk to the data protection rights and freedoms of data subjects, promptly inform You and provide reasonable cooperation to You (at Your expense) in connection with any data protection impact assessment that You may be required under applicable Data Protection Legislation to undertake for Your use of Ververica Cloud Services;
1. at Your choice, delete or return all Data in Ververica’s possession or control following the termination of the Terms of Service. This requirement shall not apply to the extent that Ververica is required or permitted by applicable law to retain some or all of the Data, or Data archived on back-up systems, in which event Ververica shall securely isolate and protect such Data from any further processing except to the extent required by such law until deletion is possible; and
1. use independent qualified third-party security professionals and auditors, at Ververica’s selection and expense, to (at appropriate regular or irregular intervals) verify the adequacy of its security measures, including the security of the data centers from which Ververica provides the Ververica Cloud Services, and generating audit reports and certifications thereof (“**Report and Certification**”). Upon Your written request, and subject to Your execution of a non-disclosure agreement covering the Report and Certification (and verification that you are not a competitor of Ververica), Ververica will make available to you a summary copy of the Report and Certification demonstrating Ververica’s compliance with the obligations set forth in this Addendum. If the Standard Contractual Clauses apply to You, then You agree to exercise Your audit right by instructing Ververica to execute the audit as described in this section. If You desire to change this instruction, then You have the right to do so as set forth in the Standard Contractual Clauses which change shall be requested in writing (for clarity, nothing in the foregoing shall require Ververica to make available any data, material or information of any of Ververica’s other customers).
## 5. YOUR RESPONSIBILITIES
You agree:
1. To comply with your obligations under all applicable Data Protection Legislation in relation to Your use of Ververica Cloud Services for processing any personal data comprised within the Data.
1. That this Addendum, the Terms of Service, Your other applicable agreements with Ververica and Your configuration and use of the Ververica Cloud Services will together comprise Your complete and final documented instructions to Ververica on the processing of Data.
1. That You shall not give Ververica as Your processor any instructions, nor shall You use the Ververica Cloud Services in any way, that in any such case could infringe any Applicable Data Protection Legislation or could cause Ververica or any of its affiliates to infringe any Applicable Data Protection Legislation.
## 6. INTERNATIONAL TRANSFERS
If the processing of Data involves transfers out of the EEA, Ververica will take such measures as are necessary to ensure the transfer is in compliance with applicable Data Protection Legislation. Such measures may include (without limitation) transferring the Data to a recipient in a country that the European Commission has decided provides adequate protection for personal data, to a recipient that has achieved binding corporate rules authorisation in accordance with applicable Data Protection Legislation, or to a recipient that has executed Standard Contractual Clauses together with any supplementary measures that may be necessary.
## 7. MISCELLANEOUS
1. For clarity, the total aggregate liability of Ververica and all its affiliates, employees, agents, affiliates, representatives or anyone acting on its behalf together, arising from or in connection with the Terms of Service and/or this Addendum or any matter arising therefrom shall not exceed the maximum liability of Ververica as limited by the paragraphs under Clause 13 of the Terms of Service.
1. Ververica may modify the terms of this Addendum, for example to comply with applicable law or to implement any standard contractual clauses adopted by the European Commission or a supervisory authority under Article 28 of the GDPR, but it will not do so in a way that would reduce the protections required to be afforded to You under Article 28 of the GDPR. If it does so, it an amended and restated version on the Ververica Cloud Website, providing at least 15 days prior written notice of any material amendments to the Addendum to You (which may be posted on the Ververica Cloud Website or displayed in your Account). By continuing to use the Ververica Cloud Services after the receipt of written notification of such changes by Ververica, you agree to be bound by the amended and restated Addendum.
---
---
title: "VS Databricks"
description: ""
lastUpdated: 2026-03-24T13:08:58.000Z
source_url:
html: "https://www.ververica.com/databricks-vs-ververica"
md: "https://www.ververica.com/databricks-vs-ververica.md"
---
_No content._
---
---
title: "Ververica Cloud"
description: ""
lastUpdated: 2026-06-15T09:49:17.000Z
source_url:
html: "https://www.ververica.com/ververica-cloud"
md: "https://www.ververica.com/ververica-cloud.md"
---
# Ververica Cloud: Dual Data Pipelines Are Done
- **10x — Faster Deployment**
- **90% — Faster Diagnostics**
- **1 — Pipeline for Batch & Streaming**
- **40-60% — Cost Reduction**
## The Death of Dual Pipelines.
Why run two separate data platforms to represent one truth?
With Ververica's newest release, you can finally eliminate the pipeline architecture that creates duplication, drift, and operational risk in your cloud deployments. One managed platform for all your real-time data processing needs.
## New Features and Improvements
#### Eliminate pipeline duplication, reduce operational complexity, and rebuild trust in your data.
Fundamentally change how you build and operate your data pipeline. Stop managing separate streaming and batch systems. Replace fragile streaming ETL workflows with declarative SQL. Define what you want, and let Ververica's Unified Streaming Data Platform handle the execution.
## Available Now
Define tables once using SQL. The platform maintains them over time.
Declare how up-to-date data must be and let the platform choose the execution strategy.
Bounded refreshes are planned and scheduled automatically.
Always-on workloads are protected and batch work runs safely.
Streaming and Batch. One platform, one set of rules.
## Ready for one pipeline? Read the release notes.
### VERA Engine
### One Powerful Engine for Batch and Streaming
#### Meet VERA
VERA is the heart of Ververica’s Streaming Data Platform, the engine that operationalizes streaming data and optimizes open source Apache Flink®.
VERA allows you to connect, process, analyze, and govern your data in one ultra-high-performance streaming data solution with exactly-once semantics built in. Created to solve both batch and real-time streaming use cases, VERA makes it easy for you to harness insights from your data at any volume and scale.
### Streamhouse
### Unified Streaming and Analytics
#### Streamhouse
**The Problem:** Your legacy data architecture is faced with an impossible choice: real-time streaming OR cost-effective analytics. You run duplicate pipelines, streaming in Apache Flink, and batch ETL to warehouses. Two systems means double the maintenance, and a permanent lag between real-time and historical data.
**The Solution:** Streamhouse unifies streaming and batch with a lakehouse architecture. Stream your data directly into open lakehouse table formats such as Apache Paimon or Iceberg stored in S3, GCS, or Azure Data Lake. Query in streaming mode (for millisecond latency) or batch mode (for warehouse-scale analytics). Same table. Same SQL. Zero duplication. Easier management.
### New Connectors and Catalogs
Meet the new connectors that link your data sources and destinations, and catalogs that organize and govern your data assets with metadata and lineage tracking available with this release.
Explore the full [connector](https://docs.ververica.com/vvp/user-guide/sql-development/connectors/) and [catalog](https://docs.ververica.com/vvp/user-guide/sql-development/catalogs-databases/?highlight=catalog) libraries.
## VERA Engine Key Features
### Gemini State Backend
With 97% faster snapshots, state migrations that once took 20 minutes now take 30 seconds.
### Tiered Storage
With hot data in memory/SSD, and cold data in object storage, you'll never hit disk limits.
### Key/Value Separation for Joins
Access up to 2x faster streaming joins with low match rates.
### Dynamic Complex Event Processing (CEP)
Update fraud detection rules in your database table, and running jobs pick up the changes automatically with no job restart. Now you can react to threats in minutes, not days.
### CDAS/CTAS (Create Table As Select)
Move data with one SQL statement: CREATE TABLE target AS SELECT * FROM source and Ververica handles the rest: automatic schema inference, offset tracking, delivery guarantees, and seamless schema evolution.
### Unified Storage
Build one durable, cost-effective data layer on a lakehouse architecture. A single source of truth with no data duplication.
## Streamhouse Key Features
### Stream Directly to the Data Lake
With ACID transactions, automatic compaction, and native change data capture (CDC) support.
### Query Both Ways
Real-time dashboards and deep historical analytics on the same table.
### Multi-Engine Compatibility
Flink writes streams, while Spark, Presto, Trino, and your BI tools all operate on the same tables. No duplication, no data silos.
### Automatic Schema Evolution
Add columns or change types with no downtime or redeployment.
### Time Travel and Audit Trails
Query tables as of a specific timestamp or snapshot ID. Easily restore previous versions for debugging, auditing, or recovery.
### Unified Storage
Build one durable, cost-effective data layer. A single source of truth with no data duplication.
## New Connectors and Catalogs
### Delta Lake Connector
This connector provides a first-class, Unity Catalog–backed metadata layer for writing Flink batch and streaming data into Delta Lake tables, so you can manage Delta tables using fully qualified names (catalog.schema.table) with consistent governance across engines. By integrating natively with Flink and supporting exactly-once semantics for both batch and streaming workloads, the Catalog simplifies table management, eliminates filesystem-level configuration, and lays the foundation for reliable append and CDC-friendly write patterns, delivering a production-grade, lakehouse-aligned experience for data engineers.
### Databricks Unity Catalog Integration
Use the centralized metadata, governance, and access-control layer that allows Apache Flink jobs to discover, read from, and write to lakehouse tables (such as Delta Lake) using fully qualified names 9like catalog.schema.table) instead of managing table paths and metadata manually.
Unity Catalog acts as the authoritative metastore that provides consistent table definitions, permissions, and lineage, enabling governed, production-grade batch and streaming pipelines that integrate cleanly with the Databricks lakehouse ecosystem.
### Apache Iceberg Catalog Support
The Iceberg Catalog provides a first-class, centrally managed Apache Iceberg metadata layer into Ververica, enabling users to configure Iceberg backends once and reference tables consistently as catalog.database.table across all Flink SQL and job deployments. By aligning with the upstream Iceberg Flink catalog integration and integrating it into the native Ververica catalog experience, it eliminates repeated per-table configuration, improves discoverability and governance, and ensures consistent, reliable Iceberg table access across teams, environments, and deployment modes.
---
---
title: "VS AWS Managed Flink"
description: ""
lastUpdated: 2026-04-29T13:17:18.000Z
source_url:
html: "https://www.ververica.com/youre-overpaying-for-aws-flink"
md: "https://www.ververica.com/youre-overpaying-for-aws-flink.md"
---
# You're Overpaying for AWS Flink.
See how companies cut their streaming data costs by 40% or more without rewriting a single line of code.
## AWS Managed Flink: Convenient. Expensive. Trapped.
AWS Managed Service for Apache Flink looks affordable at first glance. The listed price is $0.11 per KPU-hour in US East (N. Virginia). Simple enough.
But that is not your real bill.
Your actual costs include storage fees at $0.10 per GB/month, mandatory orchestration overhead, and data transfer charges that add up fast. Every application you run requires an extra KPU just for AWS to manage it. That is an invisible tax on every workload.
The real surprise comes when you try to leave. Moving just one petabyte of data out of AWS costs around $90,000 in egress fees. Your data becomes hostage to the exit price.
**What is really costing you:**
- **Orchestration overhead:** Every application needs an extra KPU you do not use
- **Egress penalties:** AWS charges you to access your own data outside their network
- **Single-cloud lock-in:** No leverage to negotiate, no flexibility to optimize
## The Hidden Costs AWS Does Not Highlight
AWS packages open-source Apache Flink as a managed service. Which sounds great until you realize:
### You're locked to AWS
Multi-cloud? Only if you rebuild everything.
### The bill scales aggressively
Per KPU. Per GB ingested. Per GB transferred. Per snapshot. Per region. Plus support.
### Features lag months behind
Open-source Flink releases new features. AWS gets around to packaging them. Eventually.
### Egress fees are brutal.
Want to send data to Snowflake? That'll be $92K 🤯 per PB.
### Governance is bolted on.
Not built in. Hope your auditor is patient.
### The kicker?
We created Apache Flink. We know exactly how AWS is limiting you.
## Why Teams Switch to Ververica
The VERA engine delivers 40% lower total cost of ownership compared to other managed Apache Flink services. You get better performance while spending less. That is not a trade-off. That is an upgrade.
Deploy on AWS, Azure, or your own infrastructure. Multi-cloud flexibility means you are never locked into one vendor's pricing. When your contract comes up for renewal, you have options.
Ververica was founded by the original creators of Apache Flink at the Technical University of Berlin. When you have a question, you are talking to the people who wrote the code. No one knows Apache Flink better.
Your existing Flink applications work on Ververica without modification. Most customers are running in production within few weeks. No lengthy rewrite projects. No compatibility surprises.
## The Math Does Not Lie
Here is how AWS Managed Flink compares to Ververica for a typical enterprise workload:
| Feature | Ververica | AWS Managed Flink |
| --- | --- | --- |
| Created by Flink founders | ✓ | ✗ |
| Performance | VERA engine: 2x faster | Standard Flink |
| Deployment | Multi-cloud, hybrid, on-prem | AWS only |
| Cost structure | Transparent compute + storage | Per KPU + ingestion + egress + storage |
| Typical enterprise TCO | $100K-$130K/year | $180K-$240K/year |
| Egress fees | Optimized multi-cloud architecture | $0.09/GB (locks you in) |
| Vendor lock-in | Zero (100% Flink API compatible) | By design |
| Enterprise governance | Built into platform core | Basic (add-ons available) |
| Support | Direct from Flink creators | AWS support (3-10% of bill) |
| Best for | Enterprise production at scale | Getting started quickly in AWS |
### Do I need to rewrite my Flink applications?
No. Ververica is 100% Apache Flink API compatible. Your existing code runs unchanged. If it works on standard Flink, it works on Ververica.
### Can I still run on AWS?
Yes. You can deploy Ververica directly in your own AWS account using the [Bring-Your-Own-Cloud option](https://www.ververica.com/product/deployment/byoc). You can also choose Azure or on-premises deployment. The choice is yours.
### How long does migration take?
Most customers move from AWS Managed Flink to Ververica and reach production within 3 weeks. Since your code does not change, migration is primarily configuration and testing.
### What about support?
Ververica was founded by the team that created Apache Flink at the Technical University of Berlin. The engineers have been building and optimizing Flink since the beginning. Enterprise support includes direct access to Flink experts.
---
---
title: "Software"
description: "Build real-time features faster with Ververica. Event-driven architecture, real-time analytics, and stream processing for software companies."
lastUpdated: 2026-06-15T09:47:27.000Z
source_url:
html: "https://www.ververica.com/software"
md: "https://www.ververica.com/software.md"
---
# Ship Real-Time Features Without Building Infrastructure
Your users expect real-time. Building the infrastructure to deliver it burns months and millions. You build features. We run the platform.
## Key Reasons To choose Ververica
Why Ververica
Activity feeds that update in minutes. Dashboards that refresh on reload. Alerts that arrive after the damage is done. Users notice. Users leave.
A production-grade Flink cluster requires months of engineering time, dedicated operations staff, and ongoing maintenance. That is time not spent on product.
Your team builds a working prototype. Then it hits production load. Then it breaks at 10x. Then the on-call rotation burns out your best engineers on infrastructure instead of features.
## The math is clear. Build on managed infrastructure. Ship product.
Use Cases
### Real-Time Analytics
Process event streams and deliver live metrics to your users. Dashboards, reports, and KPIs that update continuously. No batch lag. No stale numbers. Analytics that reflect what is happening now.
### Event-Driven Microservices
Build services that react to events the moment they occur. Decouple systems with streaming pipelines instead of synchronous API chains. Eliminate cascading failures. Scale each service independently.
### ML Feature Stores
Compute features from streaming data in real time and serve them to ML models at inference time. Fresh features produce better predictions. Stale features produce stale results.
### Activity Feeds
Power real-time feeds for social, collaboration, and marketplace platforms. Process millions of events per second. Deliver ordered, deduplicated, personalized feeds with sub-10ms latency.
### Usage-Based Billing
Meter every API call, compute second, and storage byte in real time. Generate accurate usage records as consumption happens. Bill precisely. Eliminate month-end reconciliation surprises.
### Anomaly Detection
Monitor application metrics, user behavior, and system health in real time. Detect anomalies the moment patterns deviate. Alert operations teams before users file support tickets.
## Performance at Retail Scale
### 6.9B Records/Sec
VERA engine throughput. Your SaaS events, API calls, and user actions processed at scale no internal team can match.
### Sub-10ms Latency
From event to action. Real-time features that feel real-time.
### 2x Faster
Double the throughput of standard Apache Flink. Ship features on infrastructure that outperforms what your team would build.
### 40% Lower TCO
Compared to self-managed Flink. Redirect that budget to product engineering.
## Frequently Asked Questions
### How does Ververica compare to building our own Flink infrastructure?
Self-managed Flink requires dedicated infrastructure engineers, ongoing cluster management, and custom tooling. Ververica delivers a fully managed platform with 2x better performance and 40% lower TCO. Your team builds features instead of operating infrastructure.
### What programming languages does the platform support?
Ververica supports SQL, Java, and Python for writing streaming applications. All three use standard Apache Flink APIs. Your engineers work in familiar languages with full access to the Flink ecosystem and VERA engine optimizations.
### Can we integrate Ververica into our existing CI/CD pipelines?
Yes. The platform provides REST APIs and an SDK for programmatic deployment. Streaming jobs deploy through the same Git-based workflows your team uses for application code. GitHub Actions, GitLab CI, and Jenkins integrations are documented.
### How does pricing work for software companies?
Ververica offers consumption-based pricing that scales with your workload. No upfront capacity planning. No overprovisioning. Pay for the compute your streaming applications consume. Contact sales for volume pricing.
### Does Ververica support multi-tenant deployments?
Yes. The platform provides namespace isolation, resource quotas, and role-based access control. Run multiple teams and applications on a single deployment with strict isolation between tenants.
---
---
title: "Manufacturing"
description: "Real-time quality monitoring, predictive maintenance, and supply chain optimization for manufacturing. Process IoT data at 6.9B records/sec."
lastUpdated: 2026-06-15T09:47:38.000Z
source_url:
html: "https://www.ververica.com/manufacturing"
md: "https://www.ververica.com/manufacturing.md"
---
# Real-Time Intelligence for the Factory Floor
Thousands of sensors. Millions of events. Every production line, every machine, every checkpoint generating data. Defects caught. Downtime prevented. Throughput maximized.
## Key Reasons To choose Ververica
Why Ververica
A single production line generates millions of data points per hour. Temperature, vibration, pressure, torque, speed. Batch systems cannot ingest it all. Data gets sampled. Signals get lost.
When a defect is detected at final inspection, every unit produced since the defect originated is suspect. Minutes of detection delay translate to hours of rework, scrap, and warranty exposure.
A stopped production line costs thousands per minute. Reactive maintenance waits for failure. Predictive maintenance acts on data. The difference is real-time processing.
Parts shortages, logistics delays, and demand shifts propagate through the production schedule. By the time batch reports surface the problem, the line is already idle.
## Factories generate data at machine speed. Processing it on batch schedules is waste.
Use Cases
### Predictive Maintenance
Analyze vibration, temperature, and operational data from equipment sensors in real time. Detect degradation patterns before failure occurs. Schedule maintenance during planned windows. Eliminate unplanned downtime.
### Quality Monitoring
Process inspection data, sensor readings, and visual inspection results as they are generated. Detect quality deviations within seconds of occurrence. Stop defective production before it propagates downstream.
### Supply Chain Optimization
Ingest data from suppliers, logistics providers, and warehouse systems in a single streaming pipeline. Detect delays and shortages in real time. Adjust production schedules before the line runs out of parts.
### Energy Management
Monitor power consumption across every machine, line, and facility in real time. Detect energy anomalies. Optimize consumption patterns. Reduce energy costs by correlating usage with production output continuously.
### Production Line Optimization
Process OEE data, cycle times, and throughput metrics from every station in real time. Identify bottlenecks the moment they form. Adjust line parameters to maximize output without compromising quality.
### Digital Twin
Feed real-time sensor data into digital twin models. Run simulations against live production conditions. Test parameter changes on the digital model before deploying them to the physical line.
## Performance at Retail Scale
### 6.9B Records/Sec
VERA engine throughput. Benchmarked at enterprise scale. Every click, transaction, and inventory update processed.
### Sub-10ms Latency
From event ingestion to action. Pricing updates, fraud scores, and personalization signals delivered before the page loads.
### 2x Faster
Double the throughput of standard Apache Flink. Same workloads. Half the compute.
### 40% Lower TCO
Measured total cost of ownership reduction across compute, operations, and infrastructure. Fewer servers. Same results.
## Frequently Asked Questions
### Can Ververica process data from industrial IoT sensors and SCADA systems?
Yes. The platform ingests data from MQTT brokers, OPC-UA servers, Kafka topics, and industrial databases. Pre-built connectors and CDC capture handle standard manufacturing data sources without custom integration code.
### How fast can the platform detect quality defects on a production line?
VERA engine processes sensor and inspection data with sub-10ms latency. Quality rules execute against every data point in real time. Defect detection occurs within seconds of the deviation, not hours later at final inspection.
### What deployment options work for manufacturing environments with air-gapped networks?
Ververica offers self-managed deployment that runs entirely within your infrastructure. No external network access required. The platform operates behind factory firewalls with full functionality. SOC 2 Type II and ISO 27001 certified.
### How does predictive maintenance work with Ververica?
The platform processes equipment sensor data, including vibration, temperature, and operational parameters, in real time. ML models score degradation patterns continuously. Maintenance alerts fire when thresholds are crossed, before failure occurs.
### Can Ververica integrate with existing MES and ERP systems like SAP?
Yes. The platform connects to SAP, major MES platforms, and industrial databases through pre-built connectors, CDC, and REST APIs. Data flows bidirectionally. Production insights feed back into existing systems without replacing them.
---
---
title: "Platform Overview"
description: "The complete enterprise stream processing platform. VERA engine, Apache Fluss, and Streamhouse architecture 2x faster, 40% lower TCO than alternatives."
lastUpdated: 2026-06-15T09:49:42.000Z
source_url:
html: "https://www.ververica.com/product"
md: "https://www.ververica.com/product.md"
---
# Stream. Process. Act. Before the Moment Passes.
The streaming data platform built by the creators of Apache Flink. Sovereign by design. Engineered in Europe.
- Your data
- Your cloud
- Your rules
- **2x — Faster Processing**
- **40% — Lower TCO**
- **DORA — DORA Compliant**
## Mission-Critical Results
Customer Evidence
- **Events Scored Daily**: Single banking deployment
- **Detection Time**: From event to decision
- **TCO Reduction**: vs. previous infrastructure
- **Fewer False Positives**: ML on real-time data
## Ververica Platform Pillars
### Stream Processing
_Compute_
2x faster than open-source Flink. 40% lower TCO. 100% API compatible. Enterprise compute built by the team that created Flink.
### Real-Time AI
_AI_
AI on governed, real-time data. Continuous feature engineering, inference pipelines, and RAG and not stale batch predictions.
### Streaming Data Movement
_DATA MOVEMENT_
Flink CDC + 100+ connectors. Capture every change from every source the instant it happens — databases, queues, APIs, files. Zero-ETL. Zero batch windows. One pipeline, always current.
### Streamhouse Architecture
_ARCHITECTURE_
Unified batch + stream architecture. One platform replaces separate streaming and batch systems. Lakehouse economics, streaming freshness.
## We Created Apache Flink
### Leader in Forrester Wave™
Q4 2025 Streaming Data Platforms
### 10+ Years Experience
Running Flink In Prodcuction at scale across every industry
### #1 Flink Contributor
More commits than any other company
### 24/7 Enterprise Support
From the people who wrote the code
## Performance stats
key metrics
- **Faster**: Than open-source Flink
- **Lower TCO**: Same workload, less cost
- **Latency**: End-to-end processing
- **Events/Day**: Proven at scale
## Frequently Asked Questions
### What is Ververica?
Ververica is a real-time data platform built by the original creators of Apache Flink. It combines the Streamhouse unified architecture, Apache Fluss streaming storage, and enterprise-grade compute to deliver sub-millisecond analytics at scale. European-engineered. Sovereign by design. Deployed on any cloud or on-premises.
### What makes Ververica different from open-source Apache Flink?
The Ververica Platform delivers 2x throughput improvement and 40% lower TCO over open-source Flink while maintaining 100% API compatibility. Beyond performance, the platform includes autopilot operations, governance, compliance frameworks (GDPR, DORA, SOC 2), and three deployment models (managed cloud, BYOC, self-managed). Built by the original creators of Apache Flink.
### Is Ververica compatible with my existing Flink jobs?
Yes, with zero code changes. The Ververica Platform is 100% compatible with Apache Flink APIs, SQL, and connectors. Your existing Flink jobs run unchanged. Migration typically takes days, not months.
### Where can I deploy Ververica?
Two options: BYOC (our control plane in your AWS/Azure/GCP account), and Self-Managed (any Kubernetes cluster, including on-premises and air-gapped).
### What is Streamhouse™?
Streamhouse**™** is the unified architecture that combines streaming and batch processing into one platform. It uses Apache Fluss for real-time streaming storage and open table formats like Apache Paimon or Iceberg for long-term storage.
---
---
title: "VERA Engine"
description: "VERA engine delivers 2x the throughput of open-source Flink at 40% lower cost. Auto-optimized stream processing with sub-10ms latency."
lastUpdated: 2026-06-15T09:49:53.000Z
source_url:
html: "https://www.ververica.com/product/vera"
md: "https://www.ververica.com/product/vera.md"
---
# VERA Engine. Stream Processing, Supercharged.
Binary-compatible with Apache Flink. Every existing Flink job runs faster. Zero code changes.
- 2x the throughput
- 40% lower cost
- Sub-10ms latency
## What Is the VERA Engine?
VERA is Ververica's proprietary stream processing engine. It is binary-compatible with Apache Flink, meaning every existing Flink application runs on VERA without code changes. VERA delivers 2x throughput, 52% lower resource usage, and sub-10ms latency through adaptive query planning, optimized memory management, and operator fusion.
## Performance Advantages
Engine Behind the Platform
VERA processes double the volume of open-source Apache Flink on identical hardware. Benchmarked on production workloads, not synthetic tests. Same data, same jobs, twice the speed.
Total cost of ownership reduction across compute, operations, and infrastructure. Fewer nodes for the same workload. Lower cloud spend. Smaller operational team.
End-to-end processing latency at the 99th percentile under sustained load. From record ingestion to output delivery. Measured, not estimated.
Peak throughput on production-grade hardware. Processing at a scale that covers the largest enterprise workloads on the planet.
Same workload. Fewer CPUs. Less memory. Smaller cluster. The efficiency gains compound at scale.
## How Does VERA Achieve 2x Performance?
Five proprietary optimizations working together.
### Adaptive Query Planning
VERA analyzes data characteristics at runtime and adjusts execution plans continuously. Static query plans waste resources on changing data. Adaptive plans do not.
### Optimized Memory Management
Custom memory allocation reduces garbage collection pressure. Off-heap state storage eliminates JVM pauses. Predictable latency under sustained high throughput.
### Operator Fusion
VERA merges multiple operators into single execution units where safe. Fewer serialization boundaries. Fewer network shuffles. Less overhead per record.
### Advanced State Backend
Purpose-built state backend optimized for streaming access patterns. Faster state reads and writes. Incremental checkpointing with minimal I/O overhead.
### JIT Compilation
Just-in-time code generation for SQL queries and user-defined functions. Machine-optimized execution paths generated at deployment time, not interpreted at runtime.
## VERA Key Capabilities
### Binary Compatibility
Run any existing Apache Flink application on VERA. JARs, connectors, UDFs, and libraries. No recompilation. No code changes. Drop in and run faster.
### SQL and DataStream API
Full Flink SQL support for declarative stream processing. Full DataStream API for programmatic control. Both run on the same optimized engine.
### State Management
Maintain state across billions of keys with exactly-once guarantees. Queryable state for external access. State migration between application versions without downtime.
### Intelligent Auto-Scaling
VERA monitors throughput, backpressure, and resource utilization. Scales parallelism up during traffic spikes and down during quiet periods. No over-provisioning. No manual scaling.
### Event Time and Watermarks
Process events based on when they occurred, not when they arrived. Watermark tracking handles late and out-of-order data correctly across distributed processing.
### Distributed Checkpointing
Incremental checkpoints with minimal performance impact. Configurable intervals. Automatic recovery from any failure. Zero data loss guaranteed.
## VERA Engine vs.
Open-Source Apache Flink
| Feature | VERA Engine | Open-Source Flink |
| --- | --- | --- |
| Throughput | 6.9B records/sec | ~3.4B records/sec |
| Latency (p99) | Sub-10ms | 20-50ms |
| Resource Efficiency | 52% lower | Baseline |
| TCO | 40% lower | Baseline |
| Auto-Scaling | Built-in, adaptive | Manual or basic reactive |
| Query Optimization | Adaptive, runtime | Static plan |
| State Backend | Optimized, proprietary | RocksDB |
| Multi-Tenancy | Native | Not supported |
| Governance | RBAC, audit, lineage | Not included |
| Managed Operations | Full platform | DIY |
| Binary Compatibility | Full Flink API | N/A |
| Enterprise Support | 24/7, SLA-backed | Community |
## Frequently Asked Questions
### What is the VERA engine?
VERA is Ververica's proprietary stream processing engine, binary-compatible with Apache Flink. It delivers 2x throughput through adaptive query planning, optimized memory management, and operator fusion. Every Flink application runs on VERA without code changes.
### Is VERA a fork of Apache Flink?
No. VERA is binary-compatible with Flink, not a fork. It replaces critical execution paths with proprietary optimizations while maintaining full API compatibility. All Flink connectors, libraries, and applications run unchanged on VERA.
### Can I migrate from open-source Flink to VERA without code changes?
Yes. Take your existing Flink application JAR and deploy it on the Ververica Platform. No recompilation, no code changes, no connector rewrites. VERA applies all optimizations automatically. State snapshots from open-source Flink are compatible.
### How does VERA achieve 2x throughput?
Five optimizations: adaptive query planning adjusts execution at runtime, optimized memory management reduces GC pressure, operator fusion merges execution units, an advanced state backend accelerates reads and writes, and JIT compilation generates machine-optimized code.
### Does VERA support exactly-once processing?
Yes. VERA provides end-to-end exactly-once semantics through distributed checkpointing, two-phase commit sinks, and transactional state management. Every record is processed exactly once, even during failures and recovery.
### What programming languages does VERA support?
VERA supports Flink SQL, Java, Python, and Scala. SQL analysts and software engineers work on the same engine. All four interfaces produce applications that benefit from VERA's performance optimizations equally.
---
---
title: "Apache Fluss"
description: "Apache Fluss is the streaming storage layer purpose-built for real-time analytics. Unified stream and table storage for the Ververica Platform."
lastUpdated: 2026-07-09T05:51:36.000Z
source_url:
html: "https://www.ververica.com/product/fluss"
md: "https://www.ververica.com/product/fluss.md"
---
# The Storage Layer Streaming Deserved.
Apache Kafka® was built for event transport, not analytics. Apache Fluss™ was built for both. Proven at 3 PB scale, processing 40 GB/s with sub-second latency.
- Columnar streaming storage.
- Delta Joins that cut compute by 80%.
- Native Apache Iceberg tiering.
## What Is Apache Fluss?
A streaming storage system that makes data queryable the moment it arrives. Apache Arrow columnar format so you read only the columns you need. Delta Joins that eliminate terabytes of state from your Flink jobs.
## Key Statistics
- **Proven Scale**: Production deployment processing 40 GB/s
- **Less Compute**: CPU & memory reduction via Delta Joins
- **Checkpoints**: From 90 seconds down to 1 second
- **Data Freshness**: Sub-second ingestion to query
## The Problem
You're using Kafka for something it wasn't built for. Your Flink jobs read 100% of every Kafka message, even when they only need a few half the columns. Stream-to-stream joins pile up 100 TB+ of fragile state in RocksDB with 90-second checkpoints.
## 4 Key Capabilities
### Column Pruning
Apache Arrow columnar format, read only needed columns. Big network savings.
### Delta Joins
Read only changed rows and needed columns. 80% less CPU and memory, 1-second checkpoints.
### Native Iceberg Tiering
Hot data on NVMe/SSD, cold data auto-tiers to Apache Iceberg on object storage
### Union Read
One SQL statement across hot and cold data transparently
## Production Proof
You can't ignore
- 80% Less CPU & Memory
- 100 TB+ State Removed
- 30% Cost Reduction
- 1s Checkpoint Time
## Technical Specification
| Feature | Specification |
| --- | --- |
| Storage Format | Apache Arrow columnar + row-based log (dual format) |
| Query Interface | Flink SQL (streaming & batch), StarRocks, Spark |
| Data Freshness | Sub-second (single-digit millisecond typical) |
| Throughput | 40 GB/s proven in production (3 PB deployment) |
| State Management | Delta Joins: externalized from compute engine |
| Hot Storage | NVMe/SSD with primary key indexing (RocksDB) |
| Tiered Storage | Automatic tiering to Iceberg/Paimon on object storage |
| Column Pruning | Read only needed columns (Arrow columnar format) |
| Checkpoint Impact | 1-second checkpoints (down from 90s in comparable systems) |
| Compatibility | 100% Flink Table API / SQL compatible |
---
---
title: "Real-Time AI"
description: "Run AI and ML models at stream speed with Ververica. Real-time feature engineering, model inference, and AI-powered automation at sub-10ms latency."
lastUpdated: 2026-04-20T09:32:40.000Z
source_url:
html: "https://www.ververica.com/product/real-time-ai"
md: "https://www.ververica.com/product/real-time-ai.md"
---
# Real-Time AI. Intelligence at the Speed of Your Data.
Run ML models on every record as it arrives. Feature engineering, inference, and automated action. Sub-10ms latency. No batch scoring. No stale predictions.
- Sub-100ms inference latency.
- 93% fewer false positives.
- Full lineage from raw event to model prediction.
## What Is Real-Time AI on Ververica?
Real-Time AI on the Ververica Platform runs machine learning models directly inside stream processing pipelines. It covers feature engineering, model inference, A/B testing, and automated actions at sub-10ms latency. Supported frameworks include TensorFlow, PyTorch, ONNX, scikit-learn, XGBoost, and external model servers via REST or gRPC.
## Key Statistics
- **Inference Latency**: End-to-end from event to prediction
- **Feature Engineering**: Sub-second freshness, zero training-serving skew
- **Governed Lineage**: From raw event to model prediction
- **Fewer False Positives**: Fresh context vs. batch scoring
## Core Capabilities
### Real-Time Feature Engineering
Compute features from streaming data as events happen. Sub-second freshness.
### Continuous Model Inference
Deploy ML models directly in streaming pipelines. Hot model reloading.
### Streaming RAG Pipelines
Retrieval-Augmented Generation on real-time data. No periodic batch re-indexing.
### Governed AI
Full lineage from raw data to model prediction. EU AI Act compliance-ready.
## No batch windows.
No scheduling.
No waiting.
How It Works
### Stream Features
Raw events arrive from sources. The VERA engine computes features in real time: aggregations, joins, transformations, derived metrics. Feature values update with every new event.
### Score Models
Computed features feed directly into embedded models or external model servers. Every record receives a prediction. Fraud score, recommendation rank, anomaly probability, price adjustment. Inference runs at stream speed.
### Act on Predictions
Predictions trigger actions immediately. Block a transaction. Adjust a price. Send an alert. Update a dashboard. Route to a human reviewer. The action happens milliseconds after the prediction, not hours.
## Use Cases
### Fraud Scoring
Score every transaction in real time. Compute risk features from transaction history, account behavior, and device signals. Run fraud models inline. Block suspicious transactions in under 50 milliseconds. Banks process millions of transactions per second on this pattern.
### Dynamic Pricing
Adjust prices based on demand signals, inventory levels, and competitor data. Compute pricing features from streaming market data. Run pricing models on every relevant event. Push price updates to storefronts in real time.
### Predictive Maintenance
Process IoT sensor streams from manufacturing equipment. Compute degradation features from vibration, temperature, and pressure data. Score predictive models on every reading. Trigger maintenance alerts before equipment fails.
### Real-Time Recommendations
Personalize content, products, and offers as customers interact. Compute behavioral features from clickstream data. Score recommendation models on every page view. Deliver personalized results in the same request cycle.
### Anomaly Detection
Identify unusual patterns across network traffic, financial transactions, or system metrics. Compute statistical features over sliding windows. Score anomaly models on every data point. Alert operations teams in seconds, not hours.
### Intelligent Alerting
Replace static threshold alerts with ML-powered alerting. Models learn normal patterns and flag true anomalies. Reduce alert noise by 90%. Every alert that fires has a model-backed confidence score.
## Frequently Asked Questions
### What is real-time AI on the Ververica Platform?
Real-time AI runs machine learning models inside streaming pipelines. The VERA engine computes features and executes model inference on every record at sub-10ms latency. Supported frameworks include TensorFlow, PyTorch, ONNX, scikit-learn, and XGBoost, plus external servers via REST and gRPC.
### How fast is real-time model inference?
Embedded models run with sub-10ms inference latency per record inside the streaming pipeline. External model servers add network round-trip time, typically 5-20ms depending on model size and infrastructure. Total end-to-end latency from event to action remains under 50ms for most production workloads.
### Can I use my existing trained models?
Yes. Export your model in TensorFlow SavedModel, ONNX, TorchScript, or pickle format and load it into the streaming pipeline. No retraining required. No model conversion. If your model runs in Python or Java, it runs in the Ververica streaming pipeline.
### How does real-time feature engineering work?
The VERA engine computes features from streaming data as events arrive. Sliding window aggregations, cross-stream joins, running statistics, and derived calculations update with every new event. Features are always fresh, never stale batch computations.
### Does the platform support A/B testing for models?
Yes. Route traffic between model versions in real time based on configurable split ratios. Track performance metrics on live data. The platform monitors prediction accuracy, latency, and business outcomes per model version to support data-driven model promotion decisions.
---
---
title: "Deployment"
description: "Deploy Ververica your way. Fully managed cloud, BYOC for regulated industries, or self-managed on your infrastructure. Compare all options."
lastUpdated: 2026-07-01T08:39:55.000Z
source_url:
html: "https://www.ververica.com/product/deployment"
md: "https://www.ververica.com/product/deployment.md"
---
# Your Data. Your Cloud. Your Rules.
Two deployment models. One platform. Total sovereignty.
## Comparison Table
| Feature | BYOC | Self-Managed |
| --- | --- | --- |
| Time to production | Days | Days |
| Infrastructure management | Shared responsibility | Customer managed |
| Data residency | Your VPC / account | Your data center |
| Network isolation | Full VPC isolation | Air-gapped |
| Compliance scope | GDPR, DORA, NIS2, SOC 2 | Most demanding frameworks |
| Scaling | Automatic within your limits | Customer controlled |
---
---
title: "Governance"
description: "Enterprise governance for stream processing. Role-based access, audit logging, data lineage, and compliance controls built into the Ververica Platform."
lastUpdated: 2026-04-20T09:30:57.000Z
source_url:
html: "https://www.ververica.com/product/governance"
md: "https://www.ververica.com/product/governance.md"
---
# Your Data Is Ungoverned. Regulators Have Noticed.
**Built in, not bolted on.**
Most streaming platforms add governance as an afterthought. Ververica was built for regulated industries from day one. Every event tracked. Every transformation auditable.
- DORA
- GDPR
- SOC 2
- ISO 27001
- MiFID II
## What is Governance & Compliance by Ververica?
Ververica embeds governance into the streaming platform itself. Data lineage tracks every transformation. Schema management prevents breaking changes. Role-based access controls who sees what. Continuous audit trails satisfy DORA, GDPR, SOC 2, and industry-specific regulations.
## Banking Proof Points
- **Top-10 EU Banks**
- **Audit Coverage**
- **Data Sovereignty Gaps**
## Problem of The Governance Gap
Your batch pipelines have governance. Your data warehouse has lineage. But your streaming infrastructure? It's a black box. Regulators don't care that "streaming is different."
## Five Governance Capabilities.
| Feature | Description | Regulation |
| --- | --- | --- |
| Complete Data Lineage | Track every transformation, column-level lineage | DORA Article 11, GDPR Article 30, SOC 2 CC6.1 |
| Immutable Audit Trails | Every action logged, tamper-proof, cryptographic verification | DORA Article 12, SOC 2 CC7.2, MiFID II Article 16 |
| Role-Based Access Control | Fine-grained permissions, SSO/SAML, least privilege | SOC 2 CC6.3, ISO 27001 A.9, GDPR Article 25 |
| Automated Compliance Reporting | Pre-built dashboards, on-demand audit reports | DORA Article 15, SOC 2 CC4.1, GDPR Article 35 |
| AI Governance | Govern AI inputs/outputs, feature lineage, model drift monitoring | EU AI Act Article 14, GDPR Article 22, DORA Article 5 |
## Regulation Coverage
Digital Operational Resilience Act (financial entities)
General Data Protection Regulation (personal data)
Type II trust service criteria
Markets in Financial Instruments Directive
## Sovereign Infrastructure
### Data Sovereignty
European-headquartered (Munich), EU-only deployment, no US CLOUD Act exposure, BYOC and self-managed options
### Trust Center
SOC 2 Type II, ISO 27001, GDPR ready, HIPAA compliant, DORA resilient, CSA STAR certified
### DORA Readiness
Downloadable compliance checklist
---
---
title: "About"
description: "Ververica is the company founded by the original creators of Apache Flink. European-engineered in Munich, powering real-time data for global enterprises."
lastUpdated: 2026-04-16T07:14:13.000Z
source_url:
html: "https://www.ververica.com/about"
md: "https://www.ververica.com/about.md"
---
# We Created Apache Flink. Now We Are Perfecting It.
The company behind the most widely deployed stream processing framework in the world. Founded by researchers. Built by engineers. Trusted by enterprises processing trillions of records daily.
---
---
title: "Guides"
description: "Comprehensive guides on stream processing, Apache Flink, and real-time data architecture. From beginner tutorials to advanced implementation guides."
lastUpdated: 2026-03-18T13:47:24.000Z
source_url:
html: "https://www.ververica.com/guides"
md: "https://www.ververica.com/guides.md"
---
_No content._
---
---
title: "Academy"
description: "Free courses on Apache Flink and stream processing from the creators of the technology. Beginner to advanced certification paths."
lastUpdated: 2026-05-06T07:52:12.000Z
source_url:
html: "https://www.ververica.com/academy"
md: "https://www.ververica.com/academy.md"
---
# Ververica Academy. Learn from the Experts
**No vendor pitch decks. Free. Self-paced.**
The creators of Apache Flink built this curriculum. Every course draws from 10 years of production engineering. Built for engineers who ship.
- Auto scaling
- Auto-recovery
- SOC 2 Certified
- Zero-downtime Upgrades
- Multi-tenant Governance
- 2x Throughput
- 40% Lower TCO
- 100% Flink Compatible
## Why Ververica Academy?
Study at your own pace and convenience, with training created by the experts at Ververica.
### Boost Your Career
Enhance your career opportunities by gaining expertise in popular Apache Flink technologies, trends, and best practices.
### Flexible Learning
Whether you are upgrading your skills or exploring something new, learn Flink in a convenient and engaging learning environment.
### Digital Credentials
Demonstrate your newly acquired skills with badges earned upon successful course completion.
---
---
title: "Evaluation License Agreement"
description: "Evaluate Ververica's software with this Agreement. Get a non-exclusive license to test the product in a non-production environment for 30 days."
lastUpdated: 2026-04-21T12:21:26.000Z
source_url:
html: "https://www.ververica.com/evaluation-license-agreement"
md: "https://www.ververica.com/evaluation-license-agreement.md"
---
# Evaluation License Agreement
**Last update: January 8th 2024**
This Evaluation License Agreement (“**Agreement**”) is made as of the date of the acceptance of the terms of this Agreement (“**Effective Date**”) and is between Ververica GmbH ("**Ververica**"), located at Herzogspitalstrasse 24, 80331 München, Germany and the entity client on whose behalf this Agreement is accepted (“**Client**”) provided that the Client is not an individual private consumer under applicable law. The individual agreeing to this Agreement represents and warrants that it is authorized to accept this Agreement on behalf of its entity as an authorized representative of such entity.
By clicking the “Accept” button and/or downloading the Ververica Product, the Client agrees to be bound by the terms of this Agreement. If the Client does not agree to the terms of this Agreement, the Client may not use the Ververica Product.
## 1. DEFINITIONS
1. “Confidential Information” means any information, technical data or know-how, including without limitation, that which relates to Ververica’ computer software programs, documentation, specifications, source code, object code, research, inventions, processes, designs, drawings, engineering, products, services, customers, benchmark tests, markets, prices, or finances, which is identified as confidential either orally or in writing at the time of disclosure, or, in the alternative, should reasonably be considered Confidential Information. Confidential Information will not include any information that:
1. has been or is obtained by the receiving party from an independent source without obligation of confidentiality,
1. is or becomes publicly available other than as a result of an unauthorized disclosure by the receiving party or its personnel, or
1. is independently developed by the receiving party without reliance in any way on the Confidential Information disclosed.
1. “CPU” stands for “Central Processing Unit.” It is defined as the actual bare metal processing unit. One CPU contains at least one CPU Core but may contain more. Multi-Core or Hyperthreading processors are counted as one CPU.
1. “CPU Core” means the central billing unit of the Product enabling the Client to schedule applications (an abstraction over Flink jobs) up to the number of CPU Cores as licensed under this Agreement. A CPU Core refers to “cpu units” in Kubernetes (or equivalent resource managers). One CPU is equivalent to one AWS vCPU, 1 GCP core, 1 Azure vCore (or similar concepts for other cloud providers) or 1 Hyperthread on a bare-metal processor with Hyperthreading. The term “CPU Core” is specified in further detail in the Documentation.
1. “Ververica Product” means the Ververica software product ordered by Client pursuant to this Agreement.
1. “Documentation” means Ververica’ standard user manuals generally made available to Clients of the Ververica Product which is available as an online version only. The Documentation constitutes an integral part of this Agreement and will be made available to the Client upon request and, in any event, as part of the Ververica Product.
1. “Evaluation Term” means thirty (30) days from the date of download by Client.
1. “Group Companies” shall mean any companies that are directly, or indirectly through one or more intermediaries, controlled by the Client. As used in this definition, “control” shall mean ownership of more than 50% of the shares or more than 50% of the voting power.
1. “Node” is defined as one instance of the Ververica Product, running in one Java Virtual Machine.
## 2. GRANT OF RIGHTS
1. Licenses.
1. Evaluation License. Subject to the terms and conditions of this Agreement, Ververica hereby grants to Client, during the Evaluation Term, a non-exclusive, non-transferable (except as provided in Section 14(e), worldwide right and license (without a right to sublicense) to install and operate the Ververica Product solely in a non-production environment for internal evaluation of the suitability of the Ververica Product for Client’s business needs.
1. Volume Limitations. The right to install and operate the Ververica Product is limited to the number of, as applicable, CPU Cores, CPUs or Nodes as agreed between the Parties under this Agreement. In the absence of an individual arrangement between the Parties, the right to install and operate the Ververica Product is limited to 10 CPU Cores.
1. Documentation License. Subject to the terms and conditions of this Agreement, Ververica hereby grants to Client a non-exclusive, non-transferable (except as provided in Section 14(e), worldwide right and license (without a right to sublicense) to make copies of the Documentation provided by Ververica, solely for Client’s internal use and solely for the purpose of exercising the rights granted in Section 2(a)(i). Client acknowledges that no right is granted to modify, adapt, translate, publicly display, publish, create derivative works or distribute the Documentation.
1. Limitations. Subject to any mandatory rights of Client under applicable law, Client will not:
1. assign, sublicense, transfer, lease, rent or distribute any of its rights in the Ververica Product, provided, however, that the Client shall remain entitled to sublicense the Ververica Product to its Group Companies subject to the requirements and limitations under this Agreement and provided that Client is liable and responsible for such Group Companies and their compliance with this Agreement;
1. port, translate, localize, modify or create derivative works based upon the Ververica Product or Documentation in any manner;
1. reverse assemble, decompile, reverse engineer, translate or otherwise attempt to derive or obtain the source code, the underlying ideas, algorithms, structure or organization of the Ververica Product;
1. copy or duplicate the Ververica Product (other than to make one (1) copy for archival purposes only);
1. use the Ververica Product for the benefit of any third party including as part of any service bureau, time sharing or third party training arrangement; or
1. publish any benchmark testing results on any Product without Ververica’s written consent.
1. Open Source. The Client is advised that the Ververica Product contains and/or is based or refers to open source components. The terms of this Agreement are not applicable to those open source components. The use of those open source components is subject to the applicable open source license terms, which will be provided to the Client by Ververica when the Ververica Product is made available to the Client.
1. Third-Party Restrictions. Client will undertake all measures necessary to ensure that its use of the Ververica Product complies in all respects with any contractual or other legally binding obligations of Ververica to any third party, provided that Ververica has notified Client with respect to any such obligations.
1. Ownership and Reservation of Rights. Except for the licenses granted Client in this Section 2, Ververica or its licensors will retain all right, title and interest in and to the Ververica Product and all copies. Such right, title and interest will include ownership of, without limitation, all copyrights, patents, trade secrets and other intellectual property rights. Client will not claim or assert title to any portion of the Ververica Product or any copies. In the event Client modifies or authorizes the modification or translation of any Ververica Product, including any Documentation, Client hereby assigns all right, title and interest in any derivative work to Ververica and agrees to cooperate as reasonably requested by Ververica to perfect any such rights.
1. Preview: Ververica may, from time to time, offer the preview release version of Ververica Unified Streaming Data Platform which has not yet reached general availability (“**Preview**”). For details on the rules and requirements governing Preview offerings, please refer to the [Ververica Preview Policy](https://www.ververica.com//preview-policy).
## 3. OBLIGATIONS OF CLIENT
1. Client will be solely responsible for obtaining and installing all proper hardware and support software (including without limitation operating systems and network devices) and for proper installation of and training concerning the Ververica Product. Further details are specified in the Documentation.
1. Client will be solely responsible for maintaining all software and hardware (including without limitation network systems) that are necessary for Client to properly exercise the licenses granted hereunder. This includes, in particular, the minimum requirements specified in the Documentation.
1. Ververica will have no responsibility or liability under this Agreement for any unavailability, failure of, nonconformity, or defect in, any of the Ververica Product that is caused by or related in any manner to any failure of Client to obtain and maintain all such software or hardware.
1. Client will be solely responsible for creating and maintaining back-ups, security updates and compatible versions of all data used in connection with the Product.
1. Client will undertake all measures necessary to ensure that its use of the Ververica Product complies in all respects with applicable laws, statutes, regulations, ordinances or other rules promulgated by governing authorities having jurisdiction over Client or the Ververica Product.
## 4. SUPPORT AND MAINTENANCE SERVICES
1. Ververica will have no obligation to provide or perform any support and maintenance services for or on behalf of Client.
1. Any support and maintenance services shall require the execution of a separate service agreement between the Parties.
## 5. PROFESSIONAL SERVICES
1. Unless otherwise agreed between the parties in writing, Ververica will have no obligation to provide or perform any professional services for or on behalf of Client.
1. Any professional services shall require the execution of a separate service agreement between the Parties.
## 6. NO FEES
The Evaluation License will be granted free-of-charge.
## 7. WARRANTY DISCLAIMER
1. Delivery. The Product will be delivered to the Client via download link.
1. Disclaimer. THE PRODUCT IS DELIVERED “AS IS”. VERVERICA DISCLAIMS ALL WARRANTIES RELATED TO THE VERVERICA PRODUCT, DOCUMENTATION AND SERVICES, EXPRESS OR IMPLIED, INCLUDING, BUT NOT LIMITED TO, THE IMPLIED WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE, ACCURACY, SECURITY, NO INFRINGEMENT, QUIET ENJOYMENT, COURSE OF DEALING OR USAGE OF TRADE.
## 8. NONDISCLOSURE AND CONFIDENTIALITY
1. Nondisclosure Obligations. All Confidential Information exchanged between the parties pursuant to this Agreement:
1. will not be copied or distributed, disclosed, or disseminated in any way or form by the receiving party to anyone except its own employees, agents, or contractors, who have a reasonable need to know the Confidential Information;
1. will be treated by the receiving party with the same degree of care as is used with respect to the receiving party’s own information of like importance, but with no less than reasonable care;
1. will not be used by the receiving party for its own purposes or any other purpose except as set forth in this Agreement, without the express written permission of the disclosing party; and
1. will remain the property of and be returned to the disclosing party (along with all copies thereof) within thirty (30) days of receipt by the receiving party of a written request from the disclosing party setting forth the Confidential Information to be returned or upon expiration or termination of this Agreement.
Notwithstanding the above, the receiving party will disclose Confidential Information to agents and contractors only if such agent or contractor has signed a nondisclosure agreement that requires the agent or contractor to protect the Confidential Information in the same manner as required of the receiving party. The receiving party is jointly and severally liable for the acts and omissions of any of its agents or contractors.
1. Compelled Legal Disclosure. In the event the receiving party becomes legally compelled to disclose any Confidential Information, the receiving party will provide the disclosing party with prompt prior written notice of such requirement and the receiving party will reasonably cooperate in any effort by the disclosing party to petition the authority compelling such disclosure for an order that such disclosure not occur or that it occur pursuant to terms and conditions designed to ensure continued confidentiality or minimized disclosure.
1. Term. The confidentiality provisions of this Sec. 8 will survive termination or expiration of this Agreement.
## 9. INDEMNIFICATION
Client Indemnity. Client will indemnify, defend and hold harmless Ververica, its directors, officers, employees and representatives, from and against any and all losses, damages, liability, costs and expenses awarded by a court or agreed upon in settlement, as well as all reasonable and related attorneys’ fees and court costs, arising out of any third party claim arising out of a Client breach of any term of this Agreement or if the alleged claim arises, in whole or in part, from:
1. any modification, servicing or addition made to the Ververica Product or any part thereof by the Client;
1. any use of the Ververica Product by Client in a manner outside the scope of any right granted or in breach of this Agreement;
1. the use of such Ververica Product or any part thereof as a part or combination with any materials, devices, parts, software or processes not provided by or approved by Ververica;
1. Ververica’ compliance with Client’s requirements or specifications, if any; or
1. the use of other than the current, unaltered release of the Ververica Product or any part thereof available from Ververica.
## 10. LIMITATION OF LIABILITY
1. Remedies. Should the use of all or any portion of the Ververica Product be enjoined, or in the event Ververica wishes to minimize its potential liability under this Agreement (including without limitation to any of its third-party licensors), Ververica may at its sole and exclusive discretion, either:
1. substitute functionally equivalent, non-infringing versions of the Ververica Product(s) or any part thereof;
1. modify the infringing item so that it no longer infringes but remains reasonably functionally equivalent;
1. obtain for Client, at Ververica’ expense, the right to continue use of such item; or
1. Ververica may take back such infringing item or items, terminate this license in whole or in part.
## 11. AUDITS AND CERTIFICATION OF COMPLIANCE
1. Audits. Ververica will have the right to audit Client’s records related to Client’s payment obligations hereunder and to ensure compliance with the terms of this Agreement, upon reasonable written notice. Such audits may be conducted by Ververica personnel or by an independent third party auditor appointed by Ververica. Client will grant Ververica and/or an independent third party auditor appointed by Ververica reasonable access to its personnel, records and facilities for such purpose. All such audits will be conducted during normal business hours.
1. Certification. Ververica reserves the right to require that Client certify as to its usage and compliance with this Agreement. This applies, in particular, to the usage restrictions applicable to the number of CPU Cores.
1. Anonymous Usage Tracking. Ververica reserves the right to collect and store the IP addresses of devices used to access the Ververica Product as well as anonymous usage data regarding the Ververica Product (e.g., information on the product version used).
## 12. TERM AND TERMINATION
1. Term. This Agreement becomes effective on the Effective Date and is and shall run for the Evaluation Term. Upon expiration of the Evaluation Term, this Agreement shall terminate automatically without any further action being required.
1. Transfer to Production License. If Client wishes to license the Ververica Product after the Evaluation Term, or for purposes other than those set forth in this Agreement, Client may contact Ververica to request a production license.
1. Termination. Either party will have the right to terminate this Agreement if the other party is in material breach of any term or condition of this Agreement and fails to remedy such breach within thirty (30) days after receipt of written notice of such breach given by the non-breaching party.
1. Conditions of Termination. Following termination of this Agreement, for any reason, the license in the Ververica Product granted hereunder to Client will terminate and Client will discontinue the use of the Ververica Product and all Confidential Information that had been furnished to Client by Ververica pursuant to this Agreement. Client will immediately:
1. delete the Ververica Confidential Information from its computer storage or any other media, including, but not limited to, online and offline libraries;
1. return to Ververica, or at Ververica’ option, destroy, all copies of Ververica’ Confidential Information then in its possession.
1. Survival. Paragraphs 1, 2.3, 2.5, 3, 6 and 8 through 14 will survive termination or expiration of this Agreement.
## 13. PROPRIETARY RIGHTS
1. Copyright and Trademark Notices. Client will duplicate all proprietary notices and legends of Ververica and its suppliers or licensors upon any and all copies of the Ververica Product, including any Documentation, made by Client.
1. No Removal. Client will not remove, alter or obscure any such proprietary notice or legend.
## 14. GENERAL PROVISIONS
1. Notices. Any notice required to be sent under this Agreement will be in writing, delivered by hand or mailed by certified or express mail, return receipt requested, to the addresses of the parties listed herein.
1. Marketing. The Client agrees that Ververica shall be entitled to refer to the cooperation with the Client and to use the name and logo of the Client for marketing purposes, e.g. on Ververica’ website.
1. Force Majeure. Neither party will be responsible for delay or failure in performance resulting from acts beyond the control of such party. Such acts will include, but not be limited to: an act of God; an act of war; an act of terrorism; riot; an epidemic; fire; flood or other disaster; an act of government; a strike or lockout; a communication line failure; power failure or failure of the computer equipment on non-Ververica developed software.
1. Governing Law. This Agreement will be governed by and construed in accordance with the laws of Germany, excluding its conflicts of law rules. The U.N. Convention on the International Sale of Goods (CISG) will not apply to this Agreement in whole or in part. The parties agree that Berlin, Germany will be the exclusive venue for claims arising out of or in connection with this Agreement and all parties submit to the jurisdiction of the courts in Berlin, Germany.
1. Assignment. Ververica may, upon written notice to Client, assign this Agreement to another party who buys all or substantially all of Ververica’s business assets. Client will not assign this Agreement without the prior written consent of Ververica, which will not be unreasonably withheld.
1. Entire Agreement. This Agreement contains the entire understanding of the parties with respect to the matter contained herein and supersedes all prior and contemporaneous understandings. This Agreement may not be modified except in writing and signed by authorized representatives of Ververica and Client. Digital signatures are deemed to be equivalent to original signatures for purposes of this Agreement.
---
---
title: "Airbus Case Study"
description: "Transforming real-time intelligence at Airbus with Ververica. Streamlined operations, 24/7 service desk support, and enhanced visibility."
lastUpdated: 2026-08-20T09:19:42.000Z
source_url:
html: "https://www.ververica.com/case-study/airbus"
md: "https://www.ververica.com/case-study/airbus.md"
---
# Airbus
How Ververica Transformed Real-Time Intelligence at Airbus
Ververica was tasked with providing a solution to support Airbus, a leading aircraft manufacturer, in deploying their Apache Flink® jobs at scale. Their existing custom-built Java solution required manual handling of jobs and unexpected interruptions, making it difficult to maintain efficiency and keep costs low.
To overcome these obstacles, Ververica Platform was selected by Airbus for its ability to streamline real-time data processing without adding complexity to its existing technology stack.
Ververica offered a cost-effective, scalable solution, which supported Airbus in building robust real-time intelligence for the aviation market.
Download the case study to learn how Ververica helped Airbus achieve:
- Streamlined operations without maintenance.
- Quick, concise responses to queries via Ververica’s 24-7 service desk.
- Ease of visibility to all jobs and their current state & much more.
Overall, this contributed to greater stability of the real-time streaming pipeline, a necessary requirement to deliver a service with high-quality standards.
---
---
title: "Weibo Case Study"
description: "Learn how Weibo leverages Apache Flink and Ververica Platform for real-time data processing and Machine Learning at scale. Dive into their success story."
lastUpdated: 2026-07-15T06:46:50.000Z
source_url:
html: "https://www.ververica.com/case-study/weibo"
md: "https://www.ververica.com/case-study/weibo.md"
---
# Weibo
Learn how Weibo uses Apache Flink and Ververica Platform to unify offline and online data processing and run Machine Learning pipelines at scale.
This case study presents how social networking platform Weibo uses Apache Flink and Ververica Platform to run real time data processing and Machine Learning on their platform.
In the different sections of the case study, Weibo's Machine Learning platform is introduced. Its architecture is revealed, focusing on how Machine Learning pipelines are developed in real-time using Apache Flink and Ververica Platform on Alibaba Cloud. There is further insight into the company’s plans for Flink’s usage at Weibo and how open source technology has been utilized and adopted in the organization overall.
What you will learn from the case study:
- A deep dive into Weibo's Machine Learning platform, its components, and technology stack
- How Weibo uses Apache Flink for online Machine Learning
- How Weibo plans to further integrate and expand the usage of Apache Flink and Ververica Platform in the future
---
---
title: "AML Monitoring"
description: "Continuous anti-money laundering monitoring with sub-10ms detection. Reduce false positives and meet regulatory deadlines with real-time stream processing."
lastUpdated: 2026-06-15T09:46:41.000Z
source_url:
html: "https://www.ververica.com/banking/aml-monitoring"
md: "https://www.ververica.com/banking/aml-monitoring.md"
---
# Anti-Money Laundering Monitoring in Real Time
Batch AML monitoring generates alerts on yesterday's data. Real-time monitoring flags suspicious activity as it occurs.
## Batch AML Is a Compliance Failure
Waiting to Happen
Banks file SARs days after suspicious activity occurs. Investigators review stale alerts. Money moves through multiple hops before a single flag is raised. Regulators have noticed.
AML fines exceeded $5.1 billion globally in 2025. The penalty for slow detection is not just regulatory. It is reputational destruction. Batch monitoring does not catch launderers. It catches the evidence they left behind.
## Core Capabilities
### Continuous Monitoring
Evaluate every transaction against AML rules the instant it occurs. No batch windows. No overnight runs. Continuous, unbroken monitoring across all accounts, channels, and geographies.
### Behavioral Pattern Detection
Build real-time behavioral profiles for every customer. Detect deviations from established patterns as they happen. Structuring, layering, and integration phases are identified through streaming behavioral models.
### Network Analysis
Map transaction networks in real time. Identify hidden relationships between accounts, entities, and jurisdictions. Graph-based analysis executes continuously against the live transaction stream, not periodic snapshots.
### Automated SAR Triggers
Generate Suspicious Activity Report triggers automatically when thresholds breach. Pre-populate SAR fields with enriched transaction context. Reduce SAR preparation time from days to minutes.
## Key Reasons To choose Ververica
Why Ververica
Suspicious activity is flagged in under 10 milliseconds from transaction arrival. Alerts reach investigators while the activity is still in progress.
Real-time behavioral models with continuous context produce dramatically fewer false alerts. Investigators focus on genuine threats, not noise.
Every transaction is evaluated. No sampling. No thresholds below which transactions go unmonitored. Complete coverage is the regulatory baseline.
Automated SAR triggers with pre-populated context reduce filing preparation time by 85%. Compliance teams meet reporting deadlines without manual data gathering.
## Under the Hood
Ververica's AML monitoring platform maintains real-time behavioral profiles for every monitored entity using the VERA engine's stateful processing capabilities. Each customer profile tracks transaction velocity, geographic patterns, counterparty relationships, channel usage, and temporal behavior across configurable time windows. Profiles update with every transaction, providing always-current behavioral baselines without batch recomputation.
Network analysis operates on a streaming graph model where entities are nodes and transactions are edges. The graph updates continuously as new transactions arrive. Ververica's graph processing operators compute centrality, community detection, and shortest-path analysis in real time. This identifies mule networks, layering chains, and integration patterns that batch graph analysis misses entirely because the network has restructured before the batch runs.
The rule engine supports both deterministic threshold rules and probabilistic ML models executing in the same pipeline. Rules and models operate on the same enriched event stream, combining regulatory requirements with adaptive detection. Model updates deploy without pipeline restart. Rule changes propagate in seconds. The audit trail captures every decision, every input, and every rule version for regulatory examination.
## Frequently Asked Questions
### How does real-time AML monitoring reduce false positives?
Batch AML systems apply static rules to decontextualized data, generating massive false positive volumes. Ververica maintains continuous behavioral profiles that provide real-time context for every alert. Decisions incorporate current behavior against dynamic baselines, not static thresholds. Banks report 60% fewer false positives after deployment.
### Can Ververica monitor all transactions without sampling?
Yes. The VERA engine processes 6.9B records/sec. Every transaction is evaluated against every applicable rule and model without sampling or threshold-based exclusions. 100% transaction coverage is the regulatory expectation, and Ververica delivers it without performance degradation.
### How does network analysis work in real time?
Ververica maintains a continuously updated transaction graph where entities are nodes and transactions are edges. Graph algorithms for community detection, centrality analysis, and path finding execute against this live graph. Mule networks and layering chains are identified as they form, not after batch graph computation.
### What regulatory frameworks does this support?
Ververica's AML monitoring supports BSA/AML, EU AMLD6, FATF recommendations, and jurisdiction-specific requirements. The rule engine is configurable per jurisdiction. SAR, STR, and CTR triggers are automated. Audit trails capture every decision for regulatory examination with full data lineage.
### How quickly can AML monitoring be deployed?
Banks typically deploy production AML monitoring in 10 to 14 weeks. The platform includes pre-built AML rule templates, watchlist connectors (OFAC, EU, PEP), and case management integrations. Migration from batch AML systems runs in parallel, with dual-processing validation before cutover.
---
---
title: "Core Modernization"
description: "Modernize legacy core banking with real-time stream processing. Migrate from batch to event-driven architecture without disrupting operations."
lastUpdated: 2026-06-15T09:47:02.000Z
source_url:
html: "https://www.ververica.com/banking/core-modernization"
md: "https://www.ververica.com/banking/core-modernization.md"
---
# Modernize Core Banking Without the Big Bang
Rip-and-replace core banking modernization fails 70% of the time. Ververica enables incremental migration using the strangler fig pattern.
## Legacy Core Systems
Are the Bottleneck
Banks run core banking on systems built decades ago. Batch processing cycles dictate settlement times. Integration requires custom point-to-point connections. Every new product takes months to launch because the core cannot adapt.
Big bang replacements carry catastrophic risk. TSB's 2018 migration failure cost 1.9 billion pounds and years of customer trust. The cost of legacy is high. The cost of failed migration is higher.
## Core Capabilities
### Strangler Fig Pattern
Wrap legacy systems with a real-time event layer. Intercept batch inputs and outputs. Migrate functionality incrementally. The legacy system shrinks as the streaming layer grows. No cutover date. No risk cliff.
### CDC Integration
Capture every change from legacy databases in real time using Change Data Capture. Debezium connectors stream inserts, updates, and deletes from Oracle, DB2, and mainframe data stores into the Ververica pipeline.
### Event-Driven Service Layer
Build new banking services on event-driven architecture from day one. Account opening, loan origination, payment processing. Each service consumes and produces events. The core becomes a collection of independent, real-time services.
### Real-Time Sync
Maintain consistency between legacy and modern systems during migration. Bi-directional sync ensures both systems reflect the same state. Validation operators compare outputs continuously. Discrepancies trigger immediate alerts.
## Key Reasons To choose Ververica
Why Ververica
No service interruptions during migration. Legacy and modern systems run in parallel with continuous validation. Cutover happens per-service, not per-system.
New banking products deploy in weeks on the event-driven layer, not months through legacy change management. Business agility increases immediately.
Measured reduction in total cost of ownership as workloads migrate from legacy infrastructure. Mainframe MIPS, batch scheduling, and manual reconciliation costs decrease with each migrated capability.
First banking service migrated to real-time processing within 12 weeks. Subsequent services deploy faster as patterns and connectors are established.
## Under the Hood
Ververica's core modernization approach uses Change Data Capture as the bridge between legacy and modern architecture. Debezium connectors capture every database change from Oracle, DB2, IMS, and VSAM data stores with minimal impact on source system performance. Changes stream into the VERA engine as events, where they feed both the new event-driven services and validation operators that compare legacy and modern outputs.
The strangler fig implementation uses an event router that directs traffic between legacy and modern paths based on configurable routing rules. Initially, all traffic flows through the legacy path with the modern path shadowing for validation. As confidence grows, routing shifts traffic to the modern path per-service. The legacy path remains available for fallback. Each routing change is reversible in seconds.
State migration is handled through a combination of CDC backfill and streaming state bootstrapping. Historical data loads from legacy databases while the streaming pipeline processes live changes. The VERA engine's exactly-once guarantees ensure no data is lost or duplicated during the transition. Once backfill completes and the streaming state catches up, the modern service is authoritative. The entire process runs without service interruption.
## Frequently Asked Questions
### What is the strangler fig pattern for core banking?
The strangler fig pattern wraps legacy systems with an event-driven layer that intercepts inputs and outputs. New functionality is built on the streaming platform. Legacy functionality migrates incrementally. The legacy system handles a shrinking workload until decommission. No big bang. No risk cliff.
### How does CDC work with legacy banking databases?
Change Data Capture monitors transaction logs on legacy databases (Oracle, DB2, IMS, VSAM) and streams every insert, update, and delete as an event. Debezium connectors handle the capture with minimal source system impact. Events flow into Ververica for real-time processing and service migration.
### What happens if a migrated service fails?
The event router maintains fallback paths to legacy systems for every migrated service. If a modern service fails health checks, traffic routes back to the legacy path in seconds. No manual intervention required. Bi-directional sync ensures state consistency across both paths during any routing change.
### How long does a full core modernization take?
Full core modernization typically spans 18 to 36 months depending on system complexity and scope. The first service reaches production in 12 weeks. Each subsequent service deploys faster as patterns, connectors, and team expertise compound. Banks realize value incrementally from the first migrated service.
### Can Ververica work alongside existing core banking vendors?
Yes. Ververica operates as the event-driven processing layer alongside existing core vendors (Temenos, Finastra, FIS, TCS). It does not replace the core vendor. It replaces the batch processing model. Banks maintain existing vendor relationships while gaining real-time processing capabilities.
---
---
title: "Mainframe Offloading"
description: "Offload mainframe workloads to real-time stream processing. Reduce MIPS costs while enabling modern event-driven banking architecture."
lastUpdated: 2026-06-15T09:47:11.000Z
source_url:
html: "https://www.ververica.com/banking/mainframe-offloading"
md: "https://www.ververica.com/banking/mainframe-offloading.md"
---
# Offload Your Mainframe Without Replacing It
Mainframe replacement projects fail. Offloading works. Ververica captures mainframe data changes via CDC, replicates to stream processing, and shifts workloads.
## Mainframe Costs Are Growing.
Mainframe Skills Are Shrinking.
Banks spend $8 billion annually on mainframe operations. MIPS costs increase 4% year over year. The workforce that maintains these systems is retiring. New engineers do not learn COBOL.
Rip-and-replace migration carries a 70% failure rate for large-scale banking systems. The choice is not mainframe or cloud. It is controlled offloading or uncontrolled obsolescence. Every month of delay increases both cost and risk.
## Core Capabilities
### CDC Capture
Capture every change from mainframe databases (DB2, IMS, VSAM, IDMS) in real time using Change Data Capture. Zero impact on mainframe performance. Every insert, update, and delete streams into Ververica as an event.
### Stream Replication
Replicate mainframe data to modern infrastructure in real time. Cloud databases, data lakes, and streaming platforms receive consistent, ordered change streams. No batch ETL. No stale data.
### Gradual Migration
Move workloads one capability at a time. Reporting first. Then analytics. Then operational workloads. Each migration reduces MIPS consumption. The mainframe handles a shrinking set of responsibilities.
### Dual-Run Validation
Run legacy and modern workloads in parallel. Automated comparison operators validate that modern outputs match mainframe outputs exactly. Discrepancies trigger alerts before any cutover. Trust is built through continuous verification.
## Key Reasons To choose Ververica
Why Ververica
Measured MIPS consumption decrease as workloads offload to stream processing. Reporting, analytics, and read-heavy workloads migrate first, delivering immediate cost reduction.
Offloading runs alongside the live mainframe. No service interruptions. No maintenance windows. The mainframe continues operating while workloads shift.
Mainframe data available in modern systems in under 10 milliseconds. No overnight ETL. No data staleness. Downstream systems access current data at all times.
Platform cost recovered within 6 months through MIPS reduction alone. Subsequent workload migrations compound savings each quarter.
## Under the Hood
Ververica's mainframe offloading architecture uses purpose-built CDC connectors that read transaction logs from DB2, IMS, VSAM, and IDMS data stores. These connectors operate at the log level, capturing changes without adding query load to the mainframe. Change events include full before-and-after images, enabling downstream systems to reconstruct state without accessing the mainframe directly.
The VERA engine processes change events through transformation operators that convert mainframe-native formats (EBCDIC, packed decimal, COMP-3) to modern representations. Schema evolution is handled automatically as mainframe schemas change. The transformation layer maintains a registry of mainframe copybook definitions and maps them to target schemas. This eliminates manual data mapping for each migrated workload.
Dual-run validation operates as a streaming join between legacy mainframe output and modern system output. The comparison operator evaluates field-level equality, numeric tolerance, and temporal alignment. Results feed a validation dashboard that tracks match rates per workload, per field, and per time window. Migration cutover decisions are data-driven: when a workload achieves 100% match rate over a configurable validation period, it is cleared for production cutover. The legacy path remains available for instant rollback.
## Frequently Asked Questions
### How does mainframe offloading differ from mainframe replacement?
Replacement removes the mainframe entirely in a single migration. Offloading moves workloads incrementally while the mainframe remains operational. Each offloaded workload reduces MIPS costs immediately. The mainframe handles a shrinking set of responsibilities. Risk is distributed across many small migrations, not concentrated in one large event.
### What mainframe databases are supported?
Ververica supports CDC from DB2, IMS, VSAM, and IDMS. Connectors read transaction logs directly with zero query impact on the mainframe. CICS transaction feeds and MQ Series queues are also supported as input sources. Custom mainframe integrations are available through professional services.
### How is data consistency validated during migration?
Dual-run validation runs legacy and modern workloads in parallel and compares outputs field by field. The comparison operator checks value equality, numeric tolerance, and temporal alignment. Match rates are tracked per workload on a validation dashboard. Cutover occurs only after sustained 100% match rates over a configurable period.
### What is the typical MIPS reduction timeline?
Banks achieve 15% to 20% MIPS reduction within the first 6 months by offloading reporting and analytics workloads. Cumulative reduction reaches 40% to 50% within 18 months as operational workloads migrate. Each offloaded workload compounds savings immediately.
### Does offloading require mainframe application changes?
No. CDC connectors read database transaction logs without modifying mainframe applications. Existing COBOL programs, CICS transactions, and batch jobs continue running unchanged. The mainframe is unaware that offloading is occurring. This eliminates the need for mainframe development skills during the migration.
---
---
title: "Regulatory Reporting"
description: "Automate regulatory reporting with real-time stream processing. Meet DORA, Basel III/IV, and MiFID II deadlines with continuous data processing."
lastUpdated: 2026-06-15T09:47:16.000Z
source_url:
html: "https://www.ververica.com/banking/regulatory-reporting"
md: "https://www.ververica.com/banking/regulatory-reporting.md"
---
# Regulatory Reporting at the Speed Regulators Expect
DORA mandates real-time ICT incident reporting. Basel III/IV requires intraday risk computation. MiFID II demands T+1 transaction reporting.
## Regulatory Deadlines Are Accelerating.
Batch Reporting Is Not.
Banks compile regulatory reports from batch processes that run overnight or weekly. Data is stale before the report is filed. Manual reconciliation consumes thousands of analyst hours per quarter. Deadline pressure produces errors.
Regulators have lost patience with batch. DORA requires near-real-time incident reporting. BCBS 239 mandates timely and accurate risk aggregation. The penalty for late, inaccurate reporting is not a warning letter. It is capital surcharges, operational restrictions, and public enforcement actions.
## Core Capabilities
### Continuous Aggregation
Aggregate regulatory data in real time as transactions, positions, and events occur. No end-of-period batch compilation. Reports are always current. Filing is a snapshot of a continuously maintained dataset.
### Real-Time Reconciliation
Reconcile data across source systems continuously. Breaks and discrepancies surface in under 10ms, not during pre-filing validation. Reconciliation is a background process, not a quarterly crisis.
### Automated Report Generation
Generate regulatory reports automatically from streaming data. COREP, FINREP, MiFID II transaction reports, DORA incident reports. Template-driven generation with zero manual data gathering.
### Complete Audit Trail
Every data point, transformation, and aggregation is tracked with full lineage. Regulators can trace any reported number to its source transactions. Audit readiness is continuous, not a preparation exercise.
## Key Reasons To choose Ververica
Why Ververica
Automated continuous aggregation and report generation eliminate manual data gathering, reconciliation, and compilation. Compliance teams focus on analysis, not data assembly.
Reports reflect current data state at any moment. Filing can occur at T+0 for any reporting period. No waiting for batch completion or manual validation cycles.
Every reported number traces to source transactions through an immutable audit trail. Regulatory examinations access lineage data in real time. No post-hoc reconstruction.
Continuous reconciliation catches data quality issues before they reach reports. Banks using Ververica for regulatory reporting report zero restatements in the first year.
## Under the Hood
Ververica's regulatory reporting platform uses the VERA engine to maintain continuously updated regulatory aggregates across all required dimensions. Transaction-level data flows through classification, enrichment, and aggregation operators in real time. Regulatory calculations such as risk-weighted assets, liquidity coverage ratio, and net stable funding ratio compute as streaming aggregations that update with every position change and market movement.
The reconciliation engine operates as a streaming join across source systems, comparing data fields for consistency across core banking, trading, risk, and reference data platforms. Breaks are detected and classified in real time, triggering automated resolution workflows for known break types and escalation for novel issues. This eliminates the quarterly reconciliation sprint that consumes compliance team bandwidth.
Audit trail implementation uses an append-only event log that captures every input, transformation, and output with timestamps and processing metadata. Data lineage is queryable in real time: regulators or internal auditors can trace any reported figure to its constituent transactions through a lineage API. The lineage store is immutable and tamper-evident, providing the evidentiary standard required for regulatory examination. Report generation uses configurable templates that map streaming aggregates to regulatory filing formats (XBRL, XML, CSV) with automated validation against regulatory taxonomies.
## Frequently Asked Questions
### What regulatory frameworks does Ververica support?
Ververica supports DORA, Basel III/IV (including FRTB), MiFID II/MiFIR, BCBS 239, COREP, FINREP, and jurisdiction-specific requirements. The platform's template-driven reporting adapts to new regulatory requirements through configuration changes. Custom regulatory calculations deploy as streaming operators without platform changes.
### How does continuous reporting differ from batch reporting?
Batch reporting compiles data at period-end, running aggregation jobs that take hours or days. Ververica maintains regulatory aggregates continuously. The report is always current. Filing is a snapshot operation, not a computation exercise. This eliminates the multi-week preparation cycle that batch reporting demands.
### Can Ververica handle DORA incident reporting requirements?
Yes. DORA requires ICT incident classification and reporting within tight timeframes. Ververica detects and classifies ICT incidents in real time through continuous monitoring. Incident reports auto-populate with required data fields. Filing readiness is achieved within minutes of detection, well within DORA deadlines.
### How is data quality ensured for regulatory reports?
Continuous reconciliation validates data across all source systems in real time. Quality rules execute against every record as it flows through the pipeline. Breaks surface immediately, not during pre-filing validation. This ensures the data feeding regulatory aggregates is consistent and accurate at all times.
### What is the implementation approach for regulatory reporting?
Implementation begins with one regulatory domain (typically COREP/FINREP or transaction reporting) and expands. The first domain reaches production in 10 to 14 weeks. Source system connectors, regulatory calculation logic, and filing templates are configured per domain. Subsequent domains deploy faster as the data infrastructure is already in place.
---
---
title: "Retail"
description: "Power real-time retail experiences with Ververica. Dynamic pricing, inventory optimization, and personalization at 6.9B records/sec throughput."
lastUpdated: 2026-06-15T09:47:22.000Z
source_url:
html: "https://www.ververica.com/retail"
md: "https://www.ververica.com/retail.md"
---
# Real-Time Data for Retail That Moves at Customer Speed
Your customers act in milliseconds. Your data infrastructure should too. Ververica processes 6.9B records/sec so pricing, and personalization run at the speed of demand.
## Key Reasons To choose Ververica
Why Ververica
Stores, apps, marketplaces, fulfillment centers. Each channel generates data in isolation. Decisions arrive late. Customers leave.
Batch pipelines deliver recommendations hours after intent signals fire. By then, the cart is abandoned and the competitor has closed the sale.
Demand shifts in minutes. Legacy systems report in hours. The gap between those two numbers is lost revenue, dead stock, and empty shelves.
## Retail runs on velocity. Batch processing does not.
Use Cases
### Real-Time Inventory
Track stock across every warehouse, store, and fulfillment center in real time. Eliminate overselling. Eliminate stockouts. Every SKU accounted for, every second, across every channel.
### Dynamic Pricing
Adjust prices based on demand signals, competitor data, and inventory levels as they change. Not hourly. Not daily. Now. Protect margins and move product at the right price point.
### Customer Personalization
Act on clickstream, purchase history, and behavioral data the moment it arrives. Deliver product recommendations, offers, and content that match current intent, not yesterday's activity.
### Supply Chain Optimization
Process signals from suppliers, logistics partners, and weather systems in a single stream. Detect delays before they cascade. Reroute shipments before shelves go empty.
### Fraud Prevention
Score every transaction in real time against behavioral patterns and known fraud signals. Flag anomalies in sub-10ms. Block fraudulent orders before fulfillment begins.
### Demand Forecasting
Combine real-time sales data with external signals to generate demand predictions that update continuously. Feed purchasing, staffing, and logistics systems with forecasts that reflect current conditions.
## Performance at Retail Scale
### 6.9B Records/Sec
VERA engine throughput. Benchmarked at enterprise scale. Every click, transaction, and inventory update processed.
### Sub-10ms Latency
From event ingestion to action. Pricing updates, fraud scores, and personalization signals delivered before the page loads.
### 2x Faster
Double the throughput of standard Apache Flink. Same workloads. Half the compute.
### 40% Lower TCO
Measured total cost of ownership reduction across compute, operations, and infrastructure. Fewer servers. Same results.
## Frequently Asked Questions
### How does stream processing differ from batch processing for retail?
Batch processing collects data and runs it on a schedule, typically hourly or daily. Stream processing acts on each event as it arrives. For retail, this means pricing, inventory, and personalization update continuously instead of operating on stale snapshots.
### Can Ververica process data from all retail channels in one pipeline?
Yes. Ververica ingests data from POS systems, e-commerce platforms, mobile apps, marketplaces, and IoT sensors simultaneously. All channels feed into a unified streaming pipeline with sub-10ms processing latency.
### What scale of retail operations can the platform support?
VERA engine processes 6.9B records per second. That covers transaction volumes, clickstream data, and inventory events for retailers operating thousands of stores and millions of daily online sessions without performance degradation.
### How does Ververica integrate with existing retail technology stacks?
The platform connects to Kafka, databases via CDC, REST APIs, cloud storage, and data lakes out of the box. Pre-built connectors cover major retail platforms. No custom integration code required for standard sources and sinks.
### Is Ververica compliant with data privacy regulations for retail?
Ververica is SOC 2 Type II certified, ISO 27001 certified, and GDPR compliant. BYOC deployment keeps all customer data within your own cloud environment. No data leaves your infrastructure unless you route it there.
---
---
title: "Telecom"
description: "Real-time network monitoring, customer experience management, and fraud detection for telecom. Process 6.9B records/sec with sub-10ms latency."
lastUpdated: 2026-06-15T09:47:43.000Z
source_url:
html: "https://www.ververica.com/telecom"
md: "https://www.ververica.com/telecom.md"
---
# Stream Processing for Telecom Networks at Scale
Billions of network events per second. Millions of subscribers generating data simultaneously. Ververica processes it all at 6.9B records/sec with sub-10ms latency.
## Key Reasons To choose Ververica
Why Ververica
Every cell tower, every base station, every subscriber device generates continuous telemetry. Legacy systems collapse under the load. Sampling data means missing problems.
Edge computing, IoT devices, and network slicing multiply event volumes by orders of magnitude. Infrastructure built for 4G workloads cannot keep pace with 5G reality.
By the time batch analytics identifies a dissatisfied subscriber, they have already ported their number. Retention campaigns that arrive 48 hours late are campaigns that fail.
SIM swaps, subscription fraud, and international revenue share fraud execute in minutes. Daily fraud reports are post-mortems, not prevention.
## Telecom networks generate data at machine speed. Processing it on human timelines is not an option.
Use Cases
### Network Monitoring
Process CDRs, performance counters, and alarm data from every network element in real time. Detect degradation the moment it begins. Correlate events across radio, transport, and core layers in a single stream.
### Predictive Maintenance
Analyze equipment telemetry patterns to identify hardware failures before they cause outages. Schedule maintenance during low-traffic windows. Reduce mean time to repair by acting on predictions, not incidents.
### Churn Prevention
Score subscriber behavior in real time. Detect dissatisfaction signals from call drops, billing disputes, and usage pattern changes as they occur. Trigger retention actions within minutes, not days.
### Revenue Assurance
Reconcile CDRs, billing records, and interconnect data in real time. Detect revenue leakage the moment records diverge. Close the gap between service delivery and accurate billing.
### Fraud Detection
Score every SIM activation, international call, and data session against fraud patterns in sub-10ms. Block fraudulent activity before it generates cost. Eliminate the delay between fraud execution and detection.
### 5G Edge Processing
Process data at the network edge with low-latency streaming pipelines. Support network slicing, MEC applications, and IoT device management with real-time event processing where the data originates.
## Performance at Telecom Scale
### 6.9B Records/Sec
VERA engine throughput. CDRs, network events, and subscriber data processed without sampling or dropping events.
### Sub-10ms Latency
From network event to action. Fraud detection, alarm correlation, and subscriber scoring at wire speed.
### 2x Faster
Double the throughput of standard Apache Flink. Process 5G data volumes on infrastructure sized for 4G budgets.
### 40% Lower TCO
Measured total cost of ownership reduction. Fewer servers processing more data. Operations costs cut proportionally.
## Frequently Asked Questions
### Can Ververica process the data volumes generated by 5G networks?
Yes. VERA engine processes 6.9B records per second. That capacity covers CDRs, IoT telemetry, network performance counters, and subscriber events from 5G networks simultaneously without sampling or data loss.
### How does real-time fraud detection work for telecom?
Every event, including SIM activations, international calls, and data sessions, is scored against fraud models in sub-10ms. The system applies rules and ML models to detect patterns like SIM swap fraud and Wangiri attacks before they generate financial loss.
### Does Ververica integrate with existing BSS/OSS systems?
The platform connects to mediation platforms, billing systems, CRM, and network management tools through pre-built connectors and standard APIs. CDC connectors capture changes from existing databases without modifying source systems.
### What deployment options exist for telecom operators with data sovereignty requirements?
Ververica offers BYOC and self-managed deployment. Both keep all data within your own infrastructure. No subscriber data, CDRs, or network telemetry leaves your environment. SOC 2 Type II and ISO 27001 certified.
### How does the platform support network alarm correlation?
Ververica processes alarm streams from radio, transport, and core network layers in a single pipeline. It correlates related alarms, suppresses noise, and identifies root causes in real time, reducing alert volume by up to 90%.
---
---
title: "How It Works"
description: "See how the Ververica Platform processes 6.9B records/sec in three steps. Connect data sources, process in real time, deliver insights instantly."
lastUpdated: 2026-06-15T09:49:32.000Z
source_url:
html: "https://www.ververica.com/product/how-it-works"
md: "https://www.ververica.com/product/how-it-works.md"
---
# DECISIONS WHEN THEY MATTER. NOT A MILLISECOND LATER.
**HOW IT WORKS**
One unified, sovereign data platform. Every event ingested, processed, stored, served, and acted on before your batch job finishes loading. Built by the original creators of Apache Flink®.
## HOW VERVERICA WORKS
Stale data costs you. Fresh data runs you. Transform your data streams into business decisions in milliseconds. Build real-time workloads. Connect sources via 100+ connectors. Process events with SQL, Java, or Python. Query stored results instantly. Track every transformation with full governance and compliance. With Ververica, fresh data drives your business.
## Data Journey
Your data has a window. Miss it, and the machine breaks. The fraud clears. Your customer disappears. Your compliance fails. Ververica is built for that window. Exactly-once processing, fault tolerant, compliant and sovereign by design.
FOLLOW YOUR DATA TO DECISIONS ➔
ANY SOURCE. ANY FORMAT. ZERO CUSTOM CODE.
100+ connectors ingest the raw event data stream. Databases change. APIs fire. IoT sensors pulse. Capture it all with built-in change data capture (CDC). No custom plumbing required.
- Apache Kafka, Kinesis, Pub/Sub, Event Hubs
- PostgreSQL, MySQL, MongoDB, Oracle CDC
- Amazon S3, HDFS, Apache Iceberg, Delta Lake, Apache Paimon
- REST APIs, webhooks, custom protocols
PROCESS, TRANSFORM, AND ACT AT ANY SCALE.
Turn raw events into decisions at any scale and speed. Process billions of messages daily. Aggregate, join, and detect patterns across live data with exactly-once semantics. Route your data dynamically, execute event-driven applications on the runtime 2x faster than open source Apache Flink.
- Flink SQL and DataStream API
- Complex Event Processing (CEP)
- Autopilot scaling, recovery, and optimization
STORE ANYWHERE.
Get the compliance, flexibility, and redundancy your business requires, with no vendor lock-in. Use your existing storage technologies or our seamless solution. The choice is yours.
- Apache Fluss, HDFS, Apache Iceberg, Delta Lake, Apache Paimon, Amazon S3
- Ververica’s Streamhouse™ Reduce complexity and cost with unified storage, compute, and governance in one architecture
EXPOSE YOUR DATA WHETHER IN-STREAM OR STORED.
Processed, enriched data lands in the hands of your applications, dashboards, and APIs, always-fresh and on demand. Every consumer gets exactly the freshness they need without costly query re-runs.
- Aggregated state
- Materialized views
- Dynamic tables
EXECUTE DECISIONS THE MOMENT AN EVENT ARRIVES.
Adjust the price. Follow the market. Block the fraud. Route the order. Actions fire the instant conditions are met. All of your data governed, audited, and traceable to the very end.
- Automated decisions: From fraud prevention to dynamic pricing
- Signaling: Trigger actions both in digital and real world environments
- Monitoring and alerts: Build dashboards and autonomous systems
- Application feeds: Create inventory counts or leaderboards
## SEE WHAT OTHERS ARE BUILDING WITH VERVERICA
### Mainframe offloading
### Fraud detection
### Regulatory reporting
### Digital infrastructure
### User activity
### Media and entertainment
## Autopilot Operations
The Platform Runs Itself
### Auto-Scaling
Resources scale with your data volume. Handle 10x traffic spikes without manual intervention. Scale back down to save costs.
### Auto-Recovery
Failed jobs restart automatically from the last checkpoint. No data loss. No manual intervention. Sub-minute recovery times.
### Auto-Optimization
Ververica analyzes query plans and resource usage continuously. Automatic parallelism tuning, memory allocation, and checkpoint interval optimization.
### Auto-Upgrading
Platform updates with zero downtime. Rolling deployments. State preserved across upgrades. No maintenance windows.
- **Uptime SLA**
- **TCO reduction**
- **Detection time**
- **End-to-End Latency**
---
---
title: "Fully Managed Deployment"
description: "Zero-ops stream processing in the cloud. Ververica manages everything so you can focus on building real-time applications. Start in minutes."
lastUpdated: 2026-04-20T10:12:31.000Z
source_url:
html: "https://www.ververica.com/product/deployment/cloud"
md: "https://www.ververica.com/product/deployment/cloud.md"
---
# Fully Managed Streaming. Zero Ops
Production-grade Apache Flink without touching infrastructure. We operate. You build. First pipeline running in hours
## What is Ververica Cloud Deployment?
Ververica Cloud is a fully managed Apache Flink streaming platform. We provision, scale, patch, monitor, and secure the infrastructure. Full Ververica Platform included. Start with $400 in free credits and go to production in days, not months.
## Ververica Cloud in Numbers
- **SLA**
- **Latency**
- **Monitoring**
- **Lower TCO**
## Security and compliance
- SOC 2 Type II
- ISO 27001
- AES-256 encryption at rest
- TLS 1.3 in transit
- GDPR compliant
- HIPAA eligible
---
---
title: "BYOC Deployment"
description: "Stream processing in your cloud account. Data never leaves your VPC. Ververica manages the platform while you keep full control of your data."
lastUpdated: 2026-07-02T11:59:28.000Z
source_url:
html: "https://www.ververica.com/product/deployment/byoc"
md: "https://www.ververica.com/product/deployment/byoc.md"
---
# Your Cloud, Our Platform. Data Never Leaves Your VPC.
**Available on: AWS, Azure, Google Cloud (Soon)**
Ververica runs in your cloud account. You keep full data sovereignty. We manage the platform. Zero data egress. Zero shared tenancy.
## What is Ververica BYOC deployment?
Ververica BYOC deploys the streaming data plane inside your AWS, Azure, or GCP account (soon). Your data never crosses your network boundary. Ververica manages operations remotely through a secure control plane that only exchanges metadata.
## Data Sovereignty
### No US Cloud Act Exposure
European company headquartered in Munich, governed by EU law.
### GDPR Compliant by Architecture
Data processing in your account, your region.
### DORA Compliant by Design
ICT risk management with full visibility.
## Key Benefits
Customer-managed KMS for all data at rest. TLS 1.3 for all data in transit. You control key rotation, access policies, and audit logging.
Ververica handles upgrades, patching, scaling, and monitoring. Your team focuses on applications, not infrastructure. Platform SLA of 99.99%.
Data stays in your network. No cross-cloud data transfer fees. No bandwidth charges for moving data to a third-party environment.
Meet GDPR, DORA, PCI-DSS, HIPAA, and sector-specific requirements. Data residency in your jurisdiction. Audit trails for every operation. Your compliance team controls the evidence.
Data never leaves your cloud account. Processing, storage, and state management execute inside your VPC. No data egress. No exceptions.
## Features
- Single-tenant deployment
- Network isolation
- Use existing cloud credits
- Custom compliance
- Choose region/AZ
- BYOK encryption
---
---
title: "Self-Managed Deployment"
description: "Run Ververica on your infrastructure — any cloud, on-premises, or air-gapped. Full control with enterprise platform capabilities."
lastUpdated: 2026-04-20T10:00:23.000Z
source_url:
html: "https://www.ververica.com/product/deployment/self-managed"
md: "https://www.ververica.com/product/deployment/self-managed.md"
---
# Full Control. Any Infrastructure.
Deploy Ververica Platform on any Kubernetes cluster. Cloud, on-premises, or air-gapped. Your infrastructure, your rules, our enterprise support.
## What is Ververica Self-manged deployment?
Ververica Platform is the self-managed edition. Deploy on any Kubernetes cluster on cloud, on-premises, or air-gapped. You control infrastructure, networking, security, compliance. Ververica provides software, Helm charts, operator, and enterprise support.
## Statistics
- Any K8s Distribution
- Air-Gap Supported
- On-Prem Ready
- Full Control
## Supported K8s Distributions
- Amazon EKS
- Azure AKS
- Google GKE
- Red Hat
- OpenShift
- Rancher / RKE2
- Vanilla Kubernetes
## Platform Features
- Helm Charts & Operator Pattern
- Offline License & Air-Gapped Install
- Custom Network Configurations
- Enterprise RBAC & SSO
- Observability Integration
- Backup & Disaster Recovery
## Air-Gapped Use Cases
Why Self-Managed
On-premises for trading systems and transaction processing
Classified data in SCIFs and air-gapped networks
Sovereign data processing for national agencies. ITAR, FedRAMP
Sensitive patient data on-premises. HIPAA compliant
---
---
title: "Professional Services"
description: "Expert stream processing consulting from the creators of Apache Flink. Architecture design, migration, optimization, and training services."
lastUpdated: 2026-06-15T09:49:38.000Z
source_url:
html: "https://www.ververica.com/product/professional-services"
md: "https://www.ververica.com/product/professional-services.md"
---
# Expert Guidance from the Creators of Apache Flink
Architecture design. Migration execution. Performance optimization. Training and certification. Delivered by the engineers who built Apache Flink.
## Jump-Start and Boost Services
- Launch New Use Cases
- Flink Job Code Review
- Platform Installation
- Healthcheck
- Platform & Flink Training
- Flink Version Upgrades
## Adoption and Expansion Services
- Resident Engineer
- Platform & Flink Training
- Launch New Use Cases
- Custom Connectors
- CI/CD Integration
- Observability Integration
- Platform Upgrades
- Healthcheck
## Scale and Optimize Services
- Performance Tuning
- Platform & Flink Training
- Flink Job Code Review
- Architecture Design Review
## Professional Services
From the original creators of Apache Flink®.
### Architecture Consulting
Stream processing architecture decisions are expensive to reverse. Topology, state management, partitioning, and connector selection determine performance, cost, and operational complexity for years.
- Stream processing architecture design aligned to your workloads and SLAs
- Technology selection and integration patterns
- Capacity planning and resource sizing
- High availability and disaster recovery design
- Data governance and compliance architecture
- Reference architectures and implementation roadmaps
Our architects have designed stream processing systems at the largest banks, retailers, and technology companies in the world. They wrote the code that became Apache Flink.
### Migration Services
Migrating to stream processing, or migrating between platforms, carries risk. Data continuity, application compatibility, and operational readiness all require planning and execution discipline.
**Migration Paths We Execute:**
- Batch-to-streaming migration for real-time analytics and operations
- Open-source Flink to Ververica Platform for enterprise governance and VERA performance
- Spark Streaming to Ververica for lower latency and true stream processing
- Kafka Streams to Ververica for complex event processing and multi-source joins
- Cloud-to-cloud migration for infrastructure consolidation
- On-premises to BYOC for operational efficiency
**Migration Process**
1. Assessment of current workloads, dependencies, and SLAs
1. Migration plan with risk analysis and rollback procedures
1. Application porting and testing in parallel environment
1. Cutover execution with zero-downtime procedures
1. Post-migration validation and performance benchmarking
### Performance Optimization
Running stream processing and running it well are different problems. Throughput bottlenecks, state management overhead, garbage collection pauses, and serialization costs accumulate. Small inefficiencies compound at scale.
What We Optimize
- Throughput: Identify and eliminate processing bottlenecks
- Latency: Reduce end-to-end latency from source to sink
- Resource utilization: Lower CPU, memory, and storage consumption by up to 52% with VERA engine tuning
- State management: Optimize checkpoint intervals, state backends, and compaction
- Serialization: Reduce serialization overhead for high-volume workloads
- Scaling: Configure auto-scaling policies for variable load patterns
Optimization engagements typically deliver 30-50% resource reduction on existing workloads. Measured before and after. Not estimated.
## Engagement Models
Ongoing access to Ververica architects and engineers. Architecture reviews, design guidance, and technical advisory on demand. Quarterly business reviews. Named contacts.
Fixed-scope engagements for migrations, architecture design, or optimization projects. Defined deliverables, timelines, and success criteria.
A Ververica engineer embedded in your team. Full-time or part-time. Hands-on development, operations, and knowledge transfer. Duration matched to your project timeline.
## Frequently Asked Questions
### Do I need professional services to deploy Ververica?
No. BYOC and Self-Managed include documentation and support for self-service deployment. Professional services accelerate complex deployments, migrations, and architecture decisions.
### Can professional services work with my existing technology stack?
Yes. Our team integrates with your existing infrastructure, monitoring, identity, and CI/CD systems. We do not require you to replace working components. Engagements focus on stream processing, not rearchitecting your entire stack.
### What is the typical engagement duration?
Architecture consulting runs 2-4 weeks. Migrations range from 4-16 weeks depending on complexity. Optimization engagements typically complete in 1-2 weeks. Resident engineer placements run 3-12 months.
### Do you offer remote services?
Yes. All service categories are available remote. On-site delivery is available for organizations that require in-person engagement. Most engagements use a hybrid model with on-site kickoff and remote execution.
---
---
title: "Customer Stories"
description: "See how leading enterprises use Ververica for real-time stream processing. Customer stories from banking, retail, telecom, and manufacturing."
lastUpdated: 2026-03-18T13:44:00.000Z
source_url:
html: "https://www.ververica.com/customers"
md: "https://www.ververica.com/customers.md"
---
_No content._
---
---
title: "Events"
description: "Join Ververica at lab days, meetups, webinars, and conferences. Learn stream processing from the creators of Apache Flink. Register for upcoming events."
lastUpdated: 2026-05-26T10:22:41.000Z
source_url:
html: "https://www.ververica.com/events"
md: "https://www.ververica.com/events.md"
---
# Events. In Person. Online. On Demand.
Lab Days, meetups, webinars, and conferences. Technical content from the team that created Apache Flink. No sales pitches. Engineering depth only.
---
---
title: "Meetups"
description: "Join Apache Flink and stream processing meetups hosted by Ververica. Connect with the community, hear technical talks, and share experiences."
lastUpdated: 2026-05-27T07:00:02.000Z
source_url:
html: "https://www.ververica.com/events/meetups"
md: "https://www.ververica.com/events/meetups.md"
---
# Apache Flink and Stream Processing Meetups
Technical talks. Live demos. The people who build and operate stream processing in production. Free admission. Every time.
## What to Expect
### Technical Deep-Dives
A practitioner presents a real production use case, architecture decision, or open-source contribution. Code on screen. Numbers on the board.
### Demo or Lightning Talk
A shorter session. Product demo, new feature walkthrough, or community project showcase.
### Q&A
Open floor. Questions directed at speakers, Ververica engineers, or the room.
### Networking
Food and drinks provided. Conversations that start at the meetup often continue on Slack and in pull requests.
---
---
title: "Case Studies"
description: "Discover how organizations leverage Ververica Platform for stream processing needs. From booking.com to FinTech Studios, see real-world use cases."
lastUpdated: 2026-09-14T11:05:42.000Z
source_url:
html: "https://www.ververica.com/case-study"
md: "https://www.ververica.com/case-study.md"
---
# PROOF, NOT PROMISES.
**case studies**
Real teams. Real production workloads. Real results at stream scale. These are their stories.
## One Mount
> Ververica Platform Has Been Key To Deploying And Managing Our Flink Jobs. I Can’t Imagine Managing Our Multi-Tenant Stream Processing Architecture Without It.
> — Elad Hayun, Head of Core Group at XM Cyber
## Case Studies
### OKX
Migrated from AWS Flink to Ververica on AWS.
### FairMoney
The Seamless Integration With Our Existing Ecosystem
### Booking.com
From 20 Flink apps to 250 with zero added headcount.
### Airbus
Read how Airbus reclaimed engineering time with Ververica's managed platform.
### Fintech Studios
Zero to production-ready Flink in 30 days.
### One Mount Group
Millions of payments daily. Fraud caught in real time.
### Humn.ai
Real-time risk. Dynamic pricing.
### XM Cyber
100+ customer environments. 1TB per customer per day.
### VIPKid
100,000 lessons a day. 60% of help requests now resolved automatically.
### Weibo
100 billion model parameters. ML cycles cut from weekly to 10 minutes.
_Building a platform to provide Security-as-a-Service_
### Booking.com
Booking.com, a leading travel ecosystem serving both partners and travelers, faced challenges with processing security data streams and orchestrating Flink applications with stateful upgrades and multi-tenancy requirements. Their previous approach proved cumbersome and inadequate for their needs.
**Result:** To address these issues, Booking.com selected Ververica Platform to overcome their challenges. The decision to choose Ververica was driven by its ability to enable Booking.com's security teams to manage their own Flink applications independently, freeing up the Platform team to focus on maintaining the overall solution.
- **10x**: More Flink Applications
- **20x**: Faster Deployment
## Trusted in Production
---
---
title: "OKX Case Study"
description: "OKX Did Not Want To Leave AWS. It Simply Needed A Better Flink On AWS"
lastUpdated: 2026-09-14T09:25:51.000Z
source_url:
html: "https://www.ververica.com/case-study/okx"
md: "https://www.ververica.com/case-study/okx.md"
---
# OKX
Why OKX chose to migrate their data pipelines to Ververica from Amazon‘s Managed Service for Apache Flink®.
OKX handles the two challenges by migrating their streaming workloads to Ververica Platform in the Bring Your Own Cloud (BYOC) deployment on AWS. This maintains the workload on their AWS cloud instance, while offering total data sovereignty and access to an improved Flink backend engine and overall experience.
Ververica are the original creators of Apache Flink, and built the BYOC deployment to address exactly the challenges OKX faced.
---
---
title: "FinTech Studios Case Study"
description: "Unlock the power of real-time data and stream processing with FinTech Studios using Ververica Platform. Empower the finance industry of tomorrow."
lastUpdated: 2026-07-15T05:37:43.000Z
source_url:
html: "https://www.ververica.com/case-study/fintech-studios"
md: "https://www.ververica.com/case-study/fintech-studios.md"
---
# Fintech Studios
Powering the finance industry of tomorrow with real-time data.
Leveraging the power of stream processing and real-time data to empower a data-driven finance industry of tomorrow.
As a technology-first organization, FinTech Studios leverages Ververica Platform to ingest millions of research, news and regulatory sources in real-time and build an AI-based intelligent search and analytics platform for financial services professionals.
This case study explains:
- How FinTech Studios developed continuous delivery pipelines for Flink applications in production.
- How FinTech Studios deployed Ververica Platform and Apache Flink to build real-time streaming pipelines and ingest them to the company’s Machine Learning (ML) and Natural Language Processing (NLP) platform.
- How the company performs enrichment processes to the real time data in order to provide data-driven workflows for financial services professionals.
> _"With the help of Ververica Platform, we were able to move our Kubernetes-native, continuous delivery pipeline to production and push new features to our technology faster."_
_Senior Engineer, Fintech Studios_
---
---
title: "Booking.com Case Study"
description: "Discover how Booking.com utilized Ververica Platform to enhance security data processing, streamline Flink applications, and boost operational efficiency. "
lastUpdated: 2026-07-15T05:38:04.000Z
source_url:
html: "https://www.ververica.com/case-study/booking"
md: "https://www.ververica.com/case-study/booking.md"
---
# Booking.com
Building a platform to provide Security-as-a-Service. Delivering streaming-in security related data for processing
Booking.com, a leading travel ecosystem serving both partners and travelers, faced challenges with processing security data streams and orchestrating Flink applications with stateful upgrades and multi-tenancy requirements. Their previous approach proved cumbersome and inadequate for their needs.
To address these issues, Booking.com selected Ververica Platform to overcome their challenges. The decision to choose Ververica was driven by its ability to enable Booking.com's security teams to manage their own Flink applications independently, freeing up the Platform team to focus on maintaining the overall solution.
Download the case study to discover how Ververica supported Booking.com in achieving the following:
- Instant short-term wins that reduced downtime and quicker issue resolution.
- The ability to scale jobs, leading to operational efficiency
- Reduced deployment time and stateful upgrade time; from hours to a matter of minutes
- Invaluable support for Booking.com’s internal team, offering fast response times and access to Flink experts for guidance and assistance.
Overall, Ververica Platform proved to be an effective and transformative solution for Booking.com, providing seamless Flink application lifecycle management, scalability, and improved operational efficiency, ultimately enabling a more secure and reliable experience for their users and partners.
---
---
title: "Master Software License Agreement"
description: "Explore our Master Software License Agreement for Ververica GmbH Products. Understand licensing terms, support services, and fees. "
lastUpdated: 2026-04-21T12:18:56.000Z
source_url:
html: "https://www.ververica.com/msla"
md: "https://www.ververica.com/msla.md"
---
# Master Software License Agreement
**Last update: May 14th 2025**
IMPORTANT – CAREFULLY READ ALL THE TERMS AND CONDITIONS OF THIS MASTER SOFTWARE LICENSE AGREEMENT (THIS “**AGREEMENT**”). BY AGREEING TO AN ORDER FORM INCORPORATING THIS AGREEMENT, CLICKING “I ACCEPT”, OR PROCEEDING WITH THE INSTALLATION OF THE Ververica GmbH PRODUCTS, OR USING THE Ververica GmbH PRODUCTS YOU AS AN AUTHORIZED REPRESENTATIVE OF YOUR COMPANY ON WHOSE BEHALF YOU INSTALL AND/OR USE THE Ververica GmbH PRODUCTS (“**CLIENT**”) ARE INDICATING THAT YOU HAVE READ, UNDERSTAND AND ACCEPT THIS AGREEMENT WITH Ververica GmbH, AND THAT YOU AGREE TO BE BOUND BY ITS TERMS. IF YOU DO NOT AGREE WITH ALL OF THE TERMS OF THIS AGREEMENT, DO NOT INSTALL, COPY OR OTHERWISE USE THE Ververica GmbH PRODUCTS. THE EFFECTIVE DATE OF THIS AGREEMENT SHALL BE THE DATE THAT CLIENT ACCEPTS THIS AGREEMENT OR THE DATE SET FORTH IN THE ORDER FORM, WHICHEVER IS EARLIER.
This Master Software License Agreement shall serve as a framework agreement for the execution of Order Forms governing all licenses granted by Ververica GmbH to use the Ververica GmbH Products identified on each Order Form and, if applicable, the provision of Support and Maintenance Services identified on each Order Form. No Ververica GmbH Products will be furnished to Client and no Support and Maintenance Services will be provided by Ververica GmbH by virtue of the Master Software License Agreement alone but will require the issuance of a mutually agreed upon signed and dated Order Form making express reference to this Agreement.
## 1. DEFINITIONS
1. **“Agreement”** means this Master Software License Agreement, the Documentation, the Support and Maintenance Terms attached hereto as Appendix A, the Order Form(s), any other Appendices or Exhibits attached hereto, and any mutually executed amendment(s) hereto that references this Master Software License Agreement.
1. **“Confidential Information”** means any information, technical data or know-how of either party which is disclosed orally, visually or in writing and which is identified as confidential at the time of disclosure or which, given the circumstances of disclosure, should reasonably be considered Confidential Information. Without limiting the generality of the foregoing, Confidential Information of Ververica GmbH includes, without limitation, information which relates to Ververica GmbH’ computer software programs, documentation, specifications, source code, object code, research, inventions, processes, designs, drawings, engineering, products, services, customers, benchmark tests, markets, prices, or finances. Confidential Information will not include any information that:
1. has been or is obtained by the receiving party from an independent source without obligation of confidentiality,
1. is or becomes publicly available other than as a result of an unauthorized disclosure by the receiving party or its personnel, or
1. is independently developed by the receiving party without reliance in any way on the Confidential Information disclosed.
1. **“CPU”** stands for “Central Processing Unit.” It is defined as the actual bare metal processing unit. One CPU contains at least one CPU Core but may contain more. Multi-Core or Hyperthreading processors are counted as one CPU.
1. **“CPU Core”** means the central billing unit of the Product enabling the Client to schedule applications (an abstraction over Flink jobs) up to the number of CPU Cores as licensed under this Agreement and specified in the Order Form. A CPU Core refers to “cpu units” in Kubernetes (or equivalent resource managers). One CPU is equivalent to one AWS vCPU, 1 GCP core, 1 Azure vCore (or similar concepts for other cloud providers) or 1 Hyperthread on a bare-metal processor with Hyperthreading. The term “CPU Core” is specified in further detail in the Documentation.
1. **“Ververica GmbH Product(s)”** or **“Products”** means the Ververica GmbH software product ordered by Client pursuant to any Order Form.
1. **“Documentation”** means Ververica GmbH’ standard user manuals generally made available to Clients of the Ververica GmbH Product which is available as an online version only. The Documentation constitutes an integral part of this Agreement and will be made available to the Client upon request and, in any event, as part of the Ververica GmbH Product.
1. **“Group Companies“** shall mean any companies that are directly, or indirectly through one or more intermediaries, controlled by the Client. As used in this definition, “control” shall mean ownership of more than 50% of the shares or more than 50% of the voting power.
1. **“Node”** is defined as one instance of the Ververica GmbH Product, running in one Java Virtual Machine.
1. **“Order Form(s)”** means individually or collectively any document that is executed by an authorized signatory of both parties and that references this Agreement and specifies the Ververica GmbH Products licensed by Client and the Support and Maintenance Services, if applicable, to be provided by Ververica GmbH to the Client
1. **“Order Form Term”** means the period from the effective date of each Order Form until the expiration date of the Order Form, unless terminated earlier in accordance with the terms of this Agreement.
1. **“Support and Maintenance Services”** means Ververica GmbH Support and Maintenance services as more fully described in the Ververica GmbH Support and Maintenance Terms, available in Appendix A of this document.
## 2. GRANT OF RIGHTS
1. Licenses.
1. _Product License_. Subject to Client’s payment of the applicable Fees (as defined below) and the terms and conditions of this Agreement, including any restrictions in any Order Form, Ververica GmbH hereby grants to Client, during the Order Form Term, a limited, personal, non-exclusive, non-transferable (except as provided in Section 14(f)), worldwide right and license (without a right to sublicense) to install and operate the Ververica GmbH Products solely for Client’s internal use and not for the benefit of any of any third party. Subject to the Volume Limitations set forth in the Order Form and the other terms of this Agreement, Group Companies may use the Ververica GmbH Products however Client remains jointly and severally liable for each such Group Company’s compliance with all terms and conditions of this Agreement.
1. _Volume Limitations._ The right to install and operate the Ververica GmbH Products is limited to the number of CPU Cores, CPUs or Nodes set forth in each Order Form.
1. _Documentation License_. Subject to the terms and conditions of this Agreement, Ververica GmbH hereby grants to Client a non-exclusive, non-transferable (except as provided in Section 14(f)), worldwide right and license (without a right to sublicense) to make copies of the Documentation provided by Ververica GmbH, solely for Client’s internal use and solely for the purpose of exercising the rights granted in Section 2(a)(i). Client acknowledges that no right is granted to modify, adapt, translate, publicly display, publish, create derivative works or distribute the Documentation.
1. _Evaluation Software and Preview_. The terms of this Agreement shall not apply to any Ververica GmbH Product, or portion of any Ververica GmbH Product, identified in the download form or by the kind of license key made available by Ververica GmbH as “Evaluation Software,” “Preview” or a similar designation. The use of any such software products/services shall be governed by a separate applicable agreement/policy and not this Agreement.
1. Limitations. Client will not, and will not permit any third party to:
1. assign, sublicense, lease, rent or distribute or otherwise transfer the Ververica GmbH Products (or any copies thereof);
1. port, translate, localize, alter, modify or create derivative works based upon the Ververica GmbH Products in any manner;
1. reverse assemble, decompile, reverse engineer, or otherwise attempt to derive or obtain the source code, the underlying ideas, algorithms, structure or organization of the Ververica GmbH Products;
1. copy or duplicate the Ververica GmbH Products (other than to make one (1) copy for archival purposes only);
1. use the Ververica GmbH Products for the benefit of any third party including as part of any service bureau, time sharing or third party training arrangement; or
1. publish any benchmark testing results on any Product without Ververica GmbH’ written consent.
1. Open Source. The Client is advised that the Ververica GmbH Product contains and/or is based or refers to open source components. The terms of this Agreement are not applicable to those open source components. The use of those open source components is subject to the applicable open source license terms, which will be provided to the Client by Ververica GmbH when the Ververica GmbH Product is made available to the Client, such as in a readme file of the Ververica GmbH Products.
1. Ownership and Reservation of Rights. Except for the licenses granted Client in this Section 2, Ververica GmbH or its licensors will retain all right, title and interest in and to the Ververica GmbH Products and all copies. Such right, title and interest will include ownership of, without limitation, all copyrights, patents, trade secrets and other intellectual property rights. Client will not claim or assert title to any portion of the Ververica GmbH Products or any copies thereof. In the event Client modifies or authorizes the modification or translation of any Ververica GmbH Product, including any Documentation, Client hereby assigns all right, title and interest in such modification or translation (including all intellectual property rights therein) to Ververica GmbH and agrees to cooperate as reasonably requested by Ververica GmbH to perfect any such rights.
## 3. OBLIGATIONS OF CLIENT
1. Except as set forth in any Order Form, Client will be solely responsible for obtaining and installing all proper hardware and support software (including without limitation operating systems and network devices) and for proper installation of and training concerning the Ververica GmbH Products. Further details are specified in the Documentation.
1. Client will be solely responsible for maintaining all software and hardware (including without limitation network systems) that are necessary for Client to properly exercise the licenses granted hereunder. This includes, in particular, the minimum requirements specified in the Documentation.
1. Ververica GmbH will have no responsibility or liability under this Agreement for any unavailability, failure of, nonconformity, or defect in, any of the Ververica GmbH Products that is caused by or related in any manner to any failure of Client to comply with the terms of this Agreement (including this Section 3) and/or the Documentation. Client will be solely responsible for creating and maintaining back-ups, security updates and compatible versions of all data used in connection with the Product.
1. Client will undertake all measures necessary to ensure that its use of the Ververica GmbH Products complies in all respects with applicable laws, statutes, regulations, ordinances or other rules promulgated by governing authorities having jurisdiction over Client or the Ververica GmbH Products.
## 4. TECHNICAL SUPPORT SERVICES
1. Unless expressly agreed otherwise under the applicable Order Form, Ververica GmbH will, during the Order Form Term, provide Support and Maintenance Services to the Client with respect to the Ververica GmbH Products as licensed under the respective Order Form
1. Any Support and Maintenance Services will be performed pursuant to the Support and Maintenance Services Terms attached hereto as Exhibit A which shall form an integral part of this Agreement.
## 5. PROFESSIONAL SERVICES
1. Client may request that Ververica GmbH provide certain professional services related to Client’s use of the Ververica GmbH Product, including, by way of example, installation, configuration or customization of the Ververica GmbH Product, and training of Client personnel regarding use of the Ververica GmbH Product. If Ververica GmbH agrees to provide such professional services, the parties will enter a separate agreement describing the terms of such professional services. Ververica GmbH has no obligation to provide such professional services under the terms of this Agreement.
## 6. FEES
1. Fees. Client will pay to Ververica GmbH fees listed in any Order Form (collectively, the “**Fees**”). All fees are payable in United States Dollars.
1. Non-Refundable. All Fees are non-refundable, except as set forth in Sec. 9.5, and all orders are non-cancelable.
1. Due Dates. Fees are due within thirty (30) days of the date of any invoice. Ververica GmbH reserves the right to charge interest on any amounts due under this Agreement which are not paid within thirty (30) calendar days of their due date at the lower of:
1. one and one half percent (1.5%) per month and
1. the highest interest rate permitted by applicable law.
1. Taxes. The Fees do not include any taxes. Unless Ververica GmbH is provided with a valid tax exemption certificate, Client will pay or promptly reimburse Ververica GmbH for all federal, state, local, foreign or other taxes on the Products of any kind whatsoever, exclusive only of taxes based on Ververica GmbH’ net income. If all or any part of any payment owed to Ververica GmbH under this Agreement is withheld, based upon a claim that such withholding is required pursuant to the tax laws of any country or its political subdivisions and/or any tax treaty between the U.S. and any such country, such payment shall be increased by the amount necessary to result in a net payment to Ververica GmbH of the amounts otherwise payable under this Agreement
1. Disputed Charges. Client must notify Ververica GmbH in writing of any dispute or disagreement with invoiced charges within thirty (30) days after the date of invoice. Absent such notice, Client will be deemed to have agreed to the charges as invoiced after the expiration of such time period.
## 7. DELIVERY AND PRODUCT WARRANTY
1. Delivery. The Product will be delivered to the Client via download link. In addition, Ververica GmbH will make available a unique license key to the Client as required to access the Product. The Product is deemed accepted when Ververica GmbH makes the Products available to Client for download.
1. Limited Warranty.
1. From the date of initial delivery of any Ververica GmbH Product, namely the date when the download link is made available to the Client, and for a period of thirty (30) days thereafter Ververica GmbH represents and warrants that the Ververica GmbH Product will materially conform to with the applicable Documentation provided by Ververica GmbH.
1. Client’s sole and exclusive remedy, and Ververica GmbH sole and exclusive liability for any breach of the warranty set forth in subsection (i) above is for Ververica GmbH, in its sole discretion, to either fix the Product to remedy the defect or to refund to Client the applicable Fees for such Product, provided that Client promptly notifies Ververica GmbH of such defect within the thirty (30) day warranty period.
1. The warranty described in subsection (i) above will not apply to:
1. any Ververica GmbH Product or portion thereof that was not used in accordance with Ververica GmbH’ instructions (including the Documentation);
1. any Ververica GmbH Product or portion thereof that is altered, modified, or converted by Client or any third party in a manner that is not in accordance with the Documentation;
1. any defect in the Ververica GmbH Product or portion thereof due to Client’s equipment malfunctioning, or
1. any combination of the Ververica GmbH Products with software, hardware or other technology not provided by Ververica GmbH under this Agreement or specified by Ververica GmbH as interoperable with the Ververica GmbH Products.
1. Disclaimer. EXCEPT AS EXPRESSLY SET FORTH ABOVE IN THIS SECTION 7 THE PRODUCTS AND SUPPORT AND MAINTENANCE SERVICES ARE PROVIDED TO CLIENT ON AN “AS IS” BASIS, with any and all faults, and without any warranty of any kind. Ververica GmbH expressly disclaims all representations, warranties and conditions whether express, implied, statutory, or otherwise, including without limitation, the implied warranties of merchantability, fitness for a particular purpose, SATISFACTORY QUALITY, and non-infringement of third party rights. Ververica GmbH does not warrant that the operation of the PRODUCTS will be uninterrupted or error-free, or that defects in the PRODUCTS will be corrected. Some jurisdictions may not allow the exclusion and/or limitation of implied warranties or conditions, or allow limitations on how long an implied warranty lasts, so the above limitations or exclusions may not apply to CLIENT. In such event, Ververica GmbH warranties and conditions with respect to the PRODUCTS will be limited to the greatest extent permitted by applicable law in such jurisdiction.
## 8. NONDISCLOSURE AND CONFIDENTIALITY
1. Nondisclosure Obligations. All Confidential Information exchanged between the parties pursuant to this Agreement:
1. will not be copied or distributed, disclosed, or disseminated in any way or form by the receiving party to anyone except its own employees, agents, or contractors, who have a reasonable need to know the Confidential Information;
1. will be treated by the receiving party with the same degree of care as is used with respect to the receiving party’s own information of like importance, but with no less than reasonable care;
1. will not be used by the receiving party for its own purposes or any other purpose except as set forth in this Agreement, without the express written permission of the disclosing party; and
1. will remain the property of and be returned to the disclosing party (along with all copies thereof) within thirty (30) days of receipt by the receiving party of a written request from the disclosing party setting forth the Confidential Information to be returned or upon expiration or termination of this Agreement.
1. Notwithstanding the above, the receiving party may disclose Confidential Information to agents and contractors only if such agent or contractor is bound by a duty of confidentiality to protect the Confidential Information in the same manner as required of the receiving party. The receiving party is jointly and severally liable for the acts and omissions of any of its agents or contractors.
1. Compelled Legal Disclosure. In the event the receiving party becomes legally compelled to disclose any Confidential Information, the receiving party will provide the disclosing party with prompt prior written notice of such requirement and the receiving party will reasonably cooperate in any effort by the disclosing party to petition the authority compelling such disclosure for an order that such disclosure not occur or that it occur pursuant to terms and conditions designed to ensure continued confidentiality or minimized disclosure.
## 9. INDEMNIFICATION
1. Indemnification Obligations. Ververica GmbH will, at its own expense, defend Client and/or settle any suit or proceeding that is instituted against Client by any third party claiming that the Ververica GmbH’ Products infringe any copyrights, patents or trademarks, or misappropriate any trade secrets of a third party, and Ververica GmbH will pay all damages finally awarded therein against Client or agreed upon in settlement by Ververica GmbH, subject to the limitations set forth in Sec. 10 below.
1. Indemnification Exclusions. The foregoing provisions will not apply if the alleged claim arises, in whole or in part, from:
1. any modification, servicing or addition made to the Ververica GmbH Products or any part thereof by any person other than Ververica GmbH;
1. any use of the Ververica GmbH Products by Client in any manner not authorized by this Agreement;
1. the use of such Ververica GmbH Products or any part thereof as a part or combination with any materials, devices, parts, software or processes not provided by or approved by Ververica GmbH in writing;
1. Ververica GmbH’ compliance with Client’s requirements or specifications, if any;
1. the use of other than the then-current, unaltered release of the Ververica GmbH Products or any part thereof available from Ververica GmbH; or
1. any open source software or other third party software.
1. Client Indemnity. Client will indemnify, defend and hold harmless Ververica GmbH, its directors, officers, employees and representatives, from and against any and all losses, damages, liability, costs and expenses awarded by a court or agreed upon in settlement, as well as all reasonable and related attorneys’ fees and court costs, arising out of Client’s breach of this Agreement or violation of applicable law.
1. Indemnification Process. The foregoing indemnification obligations are conditioned on the indemnified party:
1. notifying the indemnifying party promptly in writing of such action,
1. reasonably cooperating and assisting in such defense and
1. giving sole control of the defense and any related settlement negotiations to the indemnifying party.
1. Remedies. Should the use of all or any portion of the Ververica GmbH Products be enjoined, or in the event Ververica GmbH reasonably believes the Client’s use of the Products may be enjoined, Ververica GmbH may at its sole and exclusive discretion, either:
1. substitute functionally equivalent, non-infringing versions of the Ververica GmbH Product(s) or any part thereof;
1. modify the infringing item so that it no longer infringes but remains reasonably functionally equivalent;
1. obtain for Client, at Ververica GmbH’ expense, the right to continue use of such item; or
1. Ververica GmbH may take back such infringing item or items, terminate this license with respect to the infringing items, and refund to Client any pre-paid, but unused fees for the remainder of the applicable Order Form Term.
## 10. LIMITATION OF LIABILITY
1. Disclaimer of Consequential Damages. Under no circumtances will Ververica GmbH’ be liable to Client or any third party for any incidental, consequential, indirect, special or punitive damages or liabilities of any kind (including for loss of data, loss of profits, revenue, or business) or other loss arising out of or in connection with this Agreement or the Ververica GmbH Products, regardless of the legal theory upon which any claim for damages is based AND even if Ververica GmbH has been advised of the possibility of such damages.
1. Limitation of Damages. Without limiting the foregoing, in no event will Ververica GmbH’ total cumulative liability under and in connection with this Agreement for all damages, losses and causes of action (regardless of the form of action, whether in contract, tort (including negligence), strict liability, product liability, or otherwise, and including any indemnity obligations under Sec. 9 above) exceed the fees paid by Client to Ververica GmbH in the twelve (12) months immediately preceding the event giving rise to the liability.
1. Failure of Essential Purpose. THE PARTIES AGREE THAT THESE LIMITATIONS SHALL APPLY EVEN IF THIS AGREEMENT OR ANY LIMITED REMEDY SPECIFIED HEREIN IS FOUND TO HAVE FAILED OF ITS ESSENTIAL PURPOSE.
1. Jurisdictional Issues. Some jurisdictions may not allow the exclusion or limitation of incidental, special, consequential, or other damages, so the above limitations or exclusions may not apply to CLIENT. In such event, the liability Ververica GmbH will be limited to the greatest extent permitted by applicable law in such jurisdiction.
## 11. AUDITS AND CERTIFICATION OF COMPLIANCE
1. Audits. During the term of this Agreement and for one (1) year thereafter, Ververica GmbH will have the right, on ten (10) days’ prior written notice to Client, to audit Client’s records related to Client’s payment obligations hereunder and to ensure compliance with the terms of this Agreement. Such audits may be conducted by Ververica GmbH personnel or by an independent third party auditor appointed by Ververica GmbH. Client will grant Ververica GmbH and/or an independent third party auditor appointed by Ververica GmbH reasonable access to its personnel, records and facilities for such purpose and will reasonably cooperate with Ververica GmbH in such audit. All such audits will be conducted during normal business hours. If the audit reveals any non-compliance, including any use of the Products beyond that authorized under this Agreement, without limiting Ververica GmbH other remedies arising from such unauthorized use, Client shall promptly:
1. cease such unauthorized use;
1. pay Ververica GmbH any additional fees due to the extent Client’s use of the Products has exceeded the usage limits set forth in the Order Form; and
1. reimburse Ververica GmbH reasonable, documented costs incurred in conducting such audit.
1. Certification. In addition to the audit right set forth above, Ververica GmbH reserves the right during the term of this Agreement to request that Client provide written certification as to its usage and compliance with this Agreement.
## 12. TERM AND TERMINATION
1. Term. This Agreement becomes effective on the Effective Date and will continue until terminated as set forth below.
1. Termination of Convenience. Either party will have the right to terminate this Agreement for convenience at any time with one month’s written notice, provided, however, that any such termination for convenience shall leave any and all Order Forms unaffected. In such case, this Agreement will be in effect as long as any Order Forms are in effect.
1. Order Form Term. The Order Form Term shall be agreed upon in the respective Order Form. If no such term is agreed in the respective Order Form, any such Order Form shall have an Order Form Term of twelve (12) months from the effective Date of the respective Order Form, and the Order Form Term shall automatically be extended by consecutive extension terms of twelve (12) months, unless terminated by either party in writing with three (3) months written notice prior to the end of the initial or any extension term.
1. Termination for Cause. Either party will have the right to terminate this Agreement and any or all Order Forms if the other party is in breach of any material term or condition of this Agreement and fails to remedy such breach within thirty (30) days after receipt of written notice of such breach given by the non-breaching party.
1. Conditions of Termination. Following termination of the applicable Order Form, for any reason, the license in the Ververica GmbH Products granted hereunder to Client will terminate and Client will discontinue the use of the Products and all Confidential Information that had been furnished to Client by Ververica GmbH pursuant to this Agreement. Client will immediately:
1. delete the Ververica GmbH Products and Confidential Information from its computer storage or any other media, including, but not limited to, online and off-line libraries;
1. return to Ververica GmbH, or at Ververica GmbH’ option, destroy, all copies of Ververica GmbH’ Products and Confidential Information then in its possession; and
1. pay all amounts due and remaining payable hereunder.
1. Survival. Paragraphs 1, 2.3, 2.5, 3, 6 and 8 through 14 will survive termination or expiration of this Agreement and any Order Form.
## 13. PROPRIETARY RIGHTS
1. Copyright and Trademark Notices. Client will duplicate all proprietary notices and legends of Ververica GmbH and its suppliers or licensors upon any and all copies of the Ververica GmbH Products, including any Documentation, made by Client.
1. No Removal. Client will not remove, alter or obscure any such proprietary notice or legend.
## 14. GENERAL PROVISIONS
1. Government Rights. The Products licensed to Client under this Agreement are “commercial computer software” as that term is described in DFAR 252.227-7014(a)(1). If acquired by or on behalf of a civilian agency, the U.S. Government acquires this commercial computer software and/or commercial computer software documentation subject to the terms of this Agreement as specified in 48 C.F.R. 12.212 (Computer Software) and 12.11 (Technical Data) of the Federal Acquisition Regulations (“**FAR**”) and its successors. If acquired by or on behalf of any agency within the Department of Defense (“**DOD**”), the U.S. Government acquires this commercial computer software and/or commercial computer software documentation subject to the terms of this Agreement as specified in 48 C.F.R. 227.7202 of the DOD FAR Supplement and its successors.
1. Export. Client acknowledges that the laws and regulations of the United States of America and foreign jurisdictions may restrict the export and re-export of certain commodities and technical data of United States of America origin, including the Products. Client agrees that it will not export or re-export the Products without the appropriate United States or foreign government licenses or permits.
1. Notices. Any notice required to be sent under this Agreement will be in writing, delivered by hand or mailed by certified or express mail, return receipt requested, to the addresses of the parties, and shall be deemed given upon personal delivery, or five (5) business days after sent by certified or express mail.
1. Marketing. The Client agrees that Ververica GmbH shall be entitled to refer to the cooperation with the Client as a customer and to use the name and logo of the Client for marketing purposes, e.g. on Ververica GmbH’ website.
1. Force Majeure. Neither party will be responsible for delay or failure in performance resulting from acts beyond the control of such party. Such acts will include, but not be limited to: an act of God; an act of war; an act of terrorism; riot; an epidemic; fire; flood or other disaster; an act of government; a strike or lockout; a communication line failure; power failure or failure of the computer equipment on non-Ververica GmbH developed software.
1. Governing Law. This Agreement will be construed and enforced in all respects in accordance with the laws of the state of California, without reference to its choice of law rules. Except as set forth below in this Section, the federal and state courts seated in San Francisco, California, will have sole and exclusive jurisdiction for all purposes in connection with any action or proceeding that arises from, or relates to, this Agreement, and each party hereby irrevocably waives any objection to such exclusive jurisdiction. Notwithstanding anything in this Agreement to the contrary, Ververica GmbH may seek injunctive or other equitable relief in any court of competent jurisdiction to protect any actual or threatened misappropriation or infringement of its intellectual property rights or those of its licensors, and Client hereby submits to the exclusive jurisdiction of such courts and waives any objection thereto on the basis of improper venue, inconvenience of the forum or any other grounds. The United Nations Convention on Contracts for the International Sale of Goods is expressly excluded from this Agreement and this Agreement will not be governed or interpreted in any way by referring to any law based on the Uniform Computer Information Transactions Act (UCITA).
1. Assignment. Client shall not assign this Agreement or transfer any of its rights hereunder, or delegate the performance of any of its duties or obligations arising under this Agreement, whether by merger, acquisition, sale of assets, operation of law, or otherwise, without the prior written consent of Ververica GmbH. Any purported assignment in violation of the preceding sentence is null and void. Subject to the foregoing, this Agreement shall be binding upon, and inure to the benefit of, the successors and assigns of the parties thereto.
1. Waiver and Modifications. No waiver will be implied from conduct or failure to enforce rights. No waiver will be effective unless in a writing signed on behalf of the party against whom the waiver is asserted. If any term of this Agreement is found invalid or unenforceable that term will be enforced to the maximum extent permitted by law and the remainder of this Agreement will remain in full force. This Agreement may not be modified except in writing and signed by authorized representatives of Ververica GmbH and Client.
1. Independent Contractors. The parties are independent contractors and nothing contained herein shall be construed as creating an agency, partnership, or other form of joint enterprise between the parties.
1. Entire Agreement. This Master Software License Agreement, together with any Order Forms and related Exhibits and Appendices, contains the entire understanding of the parties with respect to the matter contained herein and supersedes all prior and contemporaneous understandings, whether written or oral. In the event of a conflict between this Master Software License Agreement and the terms and conditions set forth on the Order Form and/or the applicable exhibits or appendix, the terms of the Order Form and applicable exhibit(s) will prevail if they are expressly identified as superseding the applicable term of this Master Software License Agreement.
##
**Support and Maintenance Services Terms**
These Support and Maintenance Terms are an addendum to, and are hereby incorporated into, the Master Software License Agreement to which they are attached.
## 1. DEFINITIONS
Certain capitalized terms used in the Technical Service Terms will have the meanings set forth below. Capitalized terms used in these Technical Service Terms, that are not otherwise defined in these Technical Service Terms, have the meaning set forth in the Agreement:
1. **“Designated Support Contact” **means the technical support person(s) within Client’s organization designated by Client to act as the contact for the Support and Maintenance Services described herein. Client may designate up to three (3) Designated Support Contacts and may change a Designated Support Contact upon fifteen (15) days prior written notice to Ververica.
1. **“Error” **means a reproducible defect in the Ververica’s Product that
1. degrades or impairs Client’s use of the Product and causes such the Product not to operate substantially in accordance with the applicable specifications, instructions or other documentation provided by Ververica and
1. is reported to Ververica by the Designated Support Contact.
1. **“Extended Business Hours”** means 24x7x365 including public holidays.
1. **“General Business Hours”** means 9 a.m. to 6 p.m. Central European Time Monday through Friday excluding public holidays in Berlin, Germany.
1. **“New Products”** are releases of new products which Ververica generally makes available to its customers at additional fee. Such New Products are distinguished from the Product governed by the Agreement by a different SKU (stock keeping unit).
1. **“Updates and Upgrades”** are releases of the Product for repairs or enhancements which Ververica generally makes available to its customers at no additional fee. An Update includes, in particular “patches” and “hotfixes” and enhancements and is typically determined by a change of the second digit of the version number (e.g. from version 1.1. to 1.2). An Upgrade may also include enhanced features and is typically determined by a change of the first digit of the version number (e.g. from version 1.1. to 2.0).
## 2. SUPPORT
1. **Support. **During the Work Statement Term, Ververica will provide support to the Client by providing answers and additional information by qualified Ververica personnel to questions raised via email from Designated Support Contacts related to use and operation of the Product, including basic instruction or assistance.
1. **Support Tool.** The availability of the Support Tool depends on the service category (Gold/Silver/Bronze) ordered by the Client under the Work Statement. Client’s Designated Support Contact(s) may request Support and/or report Errors via email as follows:
1. **Contact Details.** The contact details are made available by Ververica in the Documentation.
## 3. MAINTENANCE
1. Target Initial Response Times. Ververica shall use commercially reasonable efforts to respond to Errors in accordance with the Target Initial Response Times that will be determined by the Priority Levels set out below in the time periods described below. The Target Initial Response Times depend on the service category (Gold/Silver/Bronze) ordered by the Client under the Work Statement.
1. Commencement of the Target Initial Response Times. The Target Initial Response Times will be triggered once Client’s Designated Support Contact(s) has reported an Error via email during the applicable operating hours of the Support Tool it being understood that in case Client has chosen Support and Maintenance Services of the category “Silver” and has reported an Error outside General Business Hours, the Target Initial Response Times will be triggered and Ververica will commence providing services to resolve Errors as per Section 3(d) below, once the General Business Hours of the next day have commenced.
1. Classification. The classification of any Error among Priority Levels shall be reasonably determined by Ververica in accordance with the definitions specified below.
1. Resolving Errors. Ververica shall use commercially reasonable efforts to resolve Errors in accordance with the provisions set out below.
1. Priority Level 1 and 2 Errors. To receive emergency assistance for Priority Level 1 and 2 Errors, Client shall report the Error to Ververica via the Support Tool and indicate that Client is having a Priority Level 1 or 2 Error. Upon receipt of such report, Ververica shall perform the following steps.
1. Ververica will assess the Priority Level of the Error based on the Error description. In case the Error does not fulfill the Priority Level 1 or 2 requirements, appropriate Priority Level is assigned and the Client is informed of this change.
1. In case the Error is categorized as a Priority Level 1 or 2 Error, Ververica will use commercially reasonable efforts to
1. allocate dedicated engineering resource(s) to assessing and correcting the Error until the Error is resolved, and
1. provide Client with regular updates, unless otherwise indicated in response, until the Error is resolved.
1. Priority Level 3 and 4 Errors. Following Ververica’s initial response to any Priority Level 3 and 4 Error(s), Ververica will use commercially reasonable efforts to
1. allocate dedicated engineering resource(s) to assessing and correcting such Error(s) during General Business Hours until the Error is resolved, and
1. promptly notify Client once the Error is resolved.
## 4. UPGRADES, NEW PRODUCTS, SCOPE OF SUPPORT AND MAINTENANCE SERVICES
1. Release Policy. Ververica determines whether and when to develop, release and apply any Updates and Upgrades and/or New Product. Ververica reserves the right to determine at its sole discretion whether a new feature will be releases as an Update and/or Upgrade or as a New Product. Ververica further reserves the right at its sole discretion to change and/or remove certain features of the current Product under any Updates and Upgrades.
1. Updates and Upgrades. Ververica shall make available any Updates and Upgrades generally made available by Ververica to its customers to the Client at no additional fee. Client is required to implement any such Updates and Upgrades made available by Ververica.
1. New Products. Ververica may offer any New Products generally made available by Ververica to its customers to Client at additional fee subject to the execution of a corresponding Work Statement between the parties.
1. Supported Versions and Components. Technical Support is limited to certain specific versions of the Product and/or its components as specified in detail in the Documentation.
1. Exclusions. Technical Support will not be provided to:
1. any Product or portion thereof that was not used in accordance with Ververica’s instructions;
1. any Product or portion thereof that is altered, modified, or converted by Client or any third party in a manner that is not in accordance with the Documentation;
1. any defect in the Product or portion thereof due to Client's equipment malfunctioning, or
1. any combination of the Products with software, hardware or other technology not provided by Ververica under this Agreement or specified by Ververica as interoperable with the Products.
## 5. CLIENT OBLIGATIONS
The service standards set forth in this Support and Maintenance Terms assume that Client and/or its Designated Support Contact(s), as applicable, meet the following minimum system standards:
1. Client Obligations. Except as otherwise agreed between the parties in a separate written agreement, Client is responsible for
1. maintenance and management of its computer network(s), servers, and software, and any equipment or services related to maintenance and management of the foregoing; and
1. correctly configuring its systems in accordance with any instructions provided by Ververica, as may be necessary for provision of access to the features and functions of the Product.
1. Reporting of Errors. Client must promptly notify Ververica in the event an Error occurs.
1. Cooperation. Client will fully cooperate and assist Ververica in responding to Errors and providing Support and Maintenance Services, including
1. allowing full and free access, remotely and physically, to relevant hardware, software, and other information; and
1. making at least one of its Designated Support Contact(s) available for questions and communication
1. during General Business Hours for Priority Level 3 and 4 Errors and
1. any time for Priority Level 1 and 2 Errors.
1. Non-Performance by Client. The obligations of Ververica set forth in these Support and Maintenance Terms will be excused to the extent any failures to meet such obligations result in whole or in part from Client’s or its Designated Support Contacts’ failure(s) to meet the foregoing requirements.
---
---
title: "Ververica MCP"
description: ""
lastUpdated: 2026-06-23T08:45:40.000Z
source_url:
html: "https://www.ververica.com/mcp"
md: "https://www.ververica.com/mcp.md"
---
# Your AI Coding Assistant Can't Touch Your Streaming Platform. Until Now.
- Natural Language Deployment Creation
- Log-Aware Debugging
- Deployment Lifecycle Management
- Import / Export Across Workspaces
- Context-Aware Platform Access
## Introducing Ververica’s Model Context Protocol Server (Preview)
### Native Large Language Models (LLM) Integration for Your Unified Streaming Data Platform
Ververica's Unified Streaming Data Platform Self-Managed version 3.0 isn't an upgrade; it's a complete reimagining of what a unified streaming platform can do for real-time data teams. After listening to data engineers overwhelmed by deployment complexity, operation teams battling production issues at 3 AM, and architects losing sleep over governance and compliance audits, we built Ververica Platform 3.0 to tackle these challenges head-on.
## Ververica MCP
## Ververica MCP Server
Most data platforms treat AI assistants as external tools, helpful for code generation but disconnected from the platform where code runs. The result is friction, context loss, and time-consuming manual validation. With Ververica's MCP server, your AI assistant becomes an extension of your streaming data platform itself, with full visibility and control over deployments, scripts, artifacts, and logs.
## Why It Matters
Accelerate development and deployment cycles. From prompt to running job in seconds.
Reduce operational overhead. No manual API calls, no dashboard navigation required.
Simplify debugging your workflows. AI analyzes logs and proposes fixes automatically.
Minimize Configuration Drift. Get consistent deployments across every environment.
Enable AI-Native Streaming Operations. Conversational platform management becomes your new standard.
---
---
title: "Mandatory information"
description: "Discover Ververica GmbH's mandatory information, including contact details, managing directors and trade register details."
lastUpdated: 2026-07-16T10:29:07.000Z
source_url:
html: "https://www.ververica.com/mandatory-information"
md: "https://www.ververica.com/mandatory-information.md"
---
# Pflichtangaben - Mandatory information
**Last update: 07 February 2026**
### Pflichtangaben gemäß § 35a GmbHG
Ververica GmbH
c/o Mindspace
Herzogspitalstrasse 24
D-80331 München
E-Mail: [info@ververica.com](mailto:info@ververica.com)
###
Geschäftsführer / Managing Directors:
Alexander Walden
Junhua Wang
Hai Yiu Cheung
###
Registereintrag / Trade Register
Eingetragen im Handelsregister.
Registergericht: Amtsgericht München
Registernummer: HRB 309285
### Umsatzsteuer-ID / VAT ID
Umsatzsteuer-Identifikationsnummer nach §27a Umsatzsteuergesetz:
DE296479687
---
---
title: "VS Confluent"
description: ""
lastUpdated: 2026-03-24T13:08:26.000Z
source_url:
html: "https://www.ververica.com/confluent-vs-ververica"
md: "https://www.ververica.com/confluent-vs-ververica.md"
---
_No content._
---
---
title: "Real-Time Payments"
description: "Process instant payments at scale with sub-10ms latency. Ververica's stream processing platform handles 6.9B records/sec for modern payment rails."
lastUpdated: 2026-06-15T09:47:06.000Z
source_url:
html: "https://www.ververica.com/banking/real-time-payments"
md: "https://www.ververica.com/banking/real-time-payments.md"
---
# Instant Payments Demand Instant Processing
SEPA Instant requires 10-second end-to-end. FedNow demands real-time clearing. Legacy batch systems cannot keep pace. Ververicas infrastructure matches the mandate.
## Legacy Payment Systems
Were Built for a Slower Era
Most bank payment systems run on batch cycles. Transactions queue for hours. Settlement windows span days. Customers wait. Competitors with real-time infrastructure capture deposits.
SEPA Instant, FedNow, and PIX have made real-time settlement a regulatory and competitive requirement. Banks running batch payment infrastructure face both compliance risk and customer attrition. The cost of delay is market share.
How Fast are your payments?
## Core Capabilities
### Event-Driven Processing
Process each payment event the instant it arrives. No queuing. No batch windows. ISO 20022 messages flow through validation, enrichment, and routing in a single continuous pipeline.
### Real-Time Enrichment
Enrich payment messages with account data, sanctions lists, FX rates, and routing rules in real time. Lookups execute against streaming state stores with sub-millisecond access. No external database round-trips.
### Instant Settlement
Execute clearing and settlement logic within the stream. Position updates, balance adjustments, and ledger entries process atomically with exactly-once guarantees. Settlement happens at stream speed.
### Cross-Border Orchestration
Route payments across SWIFT, SEPA, FedNow, and domestic rails based on real-time conditions. Currency conversion, compliance checks, and correspondent banking logic execute inline with the payment flow.
## Key Reasons To choose Ververica
Why Ververica
Payment validation, enrichment, fraud check, and routing in under 10 milliseconds. Measured in production, not lab conditions.
Peak payment volumes during month-end, payroll cycles, and holiday periods do not degrade latency. The VERA engine scales linearly.
Five nines uptime. Payment processing does not stop for maintenance, deployments, or infrastructure failures. Rolling upgrades with zero downtime.
Every payment settles once and only once. No duplicate postings. No missing transactions. Guaranteed across failures and restarts.
## Under the Hood
Ververica's payment processing architecture runs on the VERA engine with dedicated state backends optimized for financial transaction workloads. Each payment message flows through a directed acyclic graph of operators: parsing, validation, enrichment, screening, routing, and settlement. Operators execute in parallel where dependencies allow, minimizing end-to-end latency.
State management uses partitioned key-value stores backed by RocksDB with incremental checkpointing. Account balances, position data, and routing tables are maintained as streaming state, updated atomically with each transaction. This eliminates the need for external database lookups during payment processing. State snapshots occur asynchronously, ensuring consistent recovery without impacting throughput.
The platform supports ISO 20022 natively, with schema validation and message transformation built into the processing pipeline. Migration from legacy ISO 8583 formats is handled through inline message conversion operators. The system maintains dual-format support during migration periods, processing both formats simultaneously without separate pipelines or infrastructure.
## Frequently Asked Questions
### How does Ververica handle SEPA Instant requirements?
SEPA Instant mandates 10-second end-to-end processing. Ververica completes payment validation, fraud screening, and settlement in under 10 milliseconds. This leaves substantial margin for network latency and downstream processing. Banks achieve compliance from day one of deployment.
### What payment message formats are supported?
Ververica supports ISO 20022, ISO 8583, SWIFT MT and MX, and custom proprietary formats natively. Message parsing and validation execute inline with the stream. Migration between formats is handled through built-in conversion operators that run both formats simultaneously during transition periods.
### Can payment processing scale during peak volumes?
The VERA engine scales linearly with added resources. Peak events like month-end payroll, holiday spending, and market volatility do not degrade latency. The platform sustains 6.9B records/sec throughput. Auto-scaling provisions additional capacity within seconds when load increases.
### How is exactly-once processing guaranteed for payments?
Ververica uses distributed snapshots with two-phase commit across source and sink connectors. Every payment processes once and only once, even during failures. Balance updates, ledger entries, and settlement records are atomically consistent. No manual reconciliation is required after recovery.
### What is the typical implementation timeline?
Banks typically reach production payment processing in 8 to 12 weeks. Pre-built connectors for SWIFT, SEPA, and core banking systems accelerate integration. Ververica's professional services team includes payment domain specialists who have deployed at multiple tier-1 banks.
---
---
title: "Sovereignty Checklist for Financial Industry"
description: "Sovereignty Checklist for Financial Industry"
lastUpdated: 2026-07-09T11:26:09.000Z
source_url:
html: "https://www.ververica.com/data-sovereignty/streaming-sovereignty-checklist-for-financial-services-industry"
md: "https://www.ververica.com/data-sovereignty/streaming-sovereignty-checklist-for-financial-services-industry.md"
---
# Streaming Sovereignty Checklist for Financial Services Industry
What Regulators Demand (And Your Platform Can't Deliver)
## Is Your Streaming Platform Ready for Regulatory Scrutiny?
If your regulator asked you to prove end-to-end control over your real-time streaming data, could you answer: Where does personal data flow? Who can access it? How would you delete it on request?
Most FSI organizations would struggle. With **DORA now in effect** and **NIS2 transposed across EU member states**, supervisors are scrutinizing real-time data processing with increasing rigor.
### Key Findings
Our analysis of FSI streaming infrastructure reveals critical gaps:
## What's Inside the Checklist
This self-assessment covers **5 critical areas** with specific requirements, assessment questions, and common gaps:
- **Data Governance Requirements**
- **Sovereignty & Deployment Requirements**
- **Security & Zero Trust Requirements**
- **AI/ML Governance Requirements**
- **Operational Excellence Requirements**
###
## Who Should Use This Checklist
- **CTOs & VPs of Engineering** to evaluate platform compliance gaps
- **Chief Architects** to assess sovereignty requirements
- **Compliance Officers** to prepare for regulatory audits
- **Platform Engineers** to iddentify technical remediation needs
### The Cost of Inaction
Gaps in streaming governance represent real business risks:
- **Audit findings** delaying projects and consuming resources
- **Supervisory scrutiny** constraining growth and innovation
- **Architectural debt** becoming increasingly expensive
- **Competitive disadvantage** as peers achieve compliance
The cost of remediation increases with delay.
---
---
title: "One Mount Group Case Study"
description: "Discover how One Mount Group utilizes Ververica Platform and Apache Flink for real-time fraud detection in VinID, Vietnam's consumer app. "
lastUpdated: 2026-07-15T05:38:34.000Z
source_url:
html: "https://www.ververica.com/case-study/one-mount-group"
md: "https://www.ververica.com/case-study/one-mount-group.md"
---
# One Mount Group
Detecting fraudulent transactions in real-time for OneU, Vietnam’s consumer application trusted by millions of users.
One Mount Group harnesses Ververica’s Unified Streaming Data Platform to power real-time fraud detection for its consumer application, OneU.
By leveraging Ververica Platform: Self-Managed as a Platform-as-a-Service (PaaS), One Mount Group has streamlined the deployment and management of its real-time applications, allowing its tech team to operate with greater efficiency.
By partnering with Ververica, One Mount Group effectively addresses real-time scalability and high availability challenges while ensuring compliance with strict Service Level Agreement (SLA) requirements.
Additionally, One Mount Group’s internal teams achieved operational efficiency and standardized the deployment and operation of Flink jobs across the organization.
---
---
title: "XM Cyber Case Study"
description: "Discover how XM Cyber partnered with Ververica Platform to build a robust multi-tenant Flink architecture for real-time, scalable cyber security solutions."
lastUpdated: 2026-07-15T05:38:48.000Z
source_url:
html: "https://www.ververica.com/case-study/xm-cyber"
md: "https://www.ververica.com/case-study/xm-cyber.md"
---
# XM Cyber
Building a robust multi-tenant platform for the future of tomorrow.
XM Cyber, a leading hybrid cloud security company founded by top executives from the Israeli cyber intelligence community, is a technology leader in its approach to cyber risk.
XM Cyber utilizes its Apache Flink® (Flink) applications to ensure unlimited scaling for customers, in real-time, regardless of data volumes (up to 1 terabyte every 24 hours for each of its customers).
When deciding how to deploy a multi-tenant Flink architecture with the capability to scale, XM Cyber turned to Ververica, the Original Creators of Apache Flink®, and its solution, Ververica Platform, to help manage the Flink jobs that form part of its industry-leading security solutions.
Real-time stream processing is critical for XM Cyber to maintain high performance and security within its Cyber Security solutions. Utilizing stream processing enables XM Cyber to respond to data changes and potential threats before they happen. Integrated with Ververica Platform, XM Cyber’s streaming architecture has evolved to be a true multi-tenant model.
Download the case study to discover how Ververica Platform supported XM Cyber in achieving:
- Unlimited flexibility and scaling - handling terabytes of data from it’s customers
- The low latency requirement without resource over allocation
- Reduced running costs and engineering overheads and more
---
---
title: "Fluss Private Preview"
description: "Join the private preview of Ververica Platform with Apache Fluss integration. Experience unified streaming: ingest, process, store, and query in one place."
lastUpdated: 2026-07-15T09:02:16.000Z
source_url:
html: "https://www.ververica.com/product/fluss/private-preview"
md: "https://www.ververica.com/product/fluss/private-preview.md"
---
# Complete Your Streamhouse™ with Apache Fluss™
Experience the industry's first unified streaming data platform with columnar, queryable storage. Transform ingestion, processing, and querying into one cohesive system.
## Infrastructure Challenge
Traditional streaming platforms process data quickly but lack queryable storage. Adding databases and caches solves one problem while creating others: more infrastructure to manage, more data to move, and more delays between event and insight.
## Common Challenges
Separate tools for ingestion, processing, caching, and querying multiply operational costs and complexity.
Shuttling data between systems introduces latency, reduces freshness, and increases costs.
External databases and batch processes prevent you from querying data as it arrives.
## How It Works
Data flows into Ververica Platform and moves through three integrated stages. Apache Flink processes streaming data with exactly-once guarantees and sub-second latency. Apache Fluss stores results in columnar format while maintaining a unified log and cached table representation. You query data immediately using standard SQL, with sub-second response times on continuous updates.
The architecture removes the need for external databases, caches, and data movement pipelines. Processing and storage happen in one platform, keeping data fresh and queryable without adding infrastructure.
## Why Teams Choose Ververica Platform
### Unified Streaming Infrastructure
Consolidate ingestion, processing, and storage into one platform. Ververica eliminates separate databases and caches, reducing operational overhead by 40%. Your team builds streaming applications instead of managing tool chains.
### Immediate Queryability
Query streaming data with sub-second latency. Apache Fluss reflects every incoming change instantly, enabling dashboards and analytics that update as events happen. No batch delays, no stale caches, no waiting.
### Simplified Architecture
Replace five separate systems with one unified platform. Ververica handles everything from data ingestion through Apache Flink processing to queryable storage with Apache Fluss. Fewer tools mean lower costs, simpler operations, and faster development.
## Platform Capabilities
### Apache Fluss Integration: Columnar, Queryable Storage
- Treats streams as tables with unified log and cached representation
- Columnar storage optimized for analytical workloads with efficient access patterns
- Native support for modern formats including Lance and LanceDB
- Seamless tiering between hot data and lakehouse storage
### Apache Flink Processing
- Exactly-once processing guarantees with automatic checkpointing
- Sub-second event latency at enterprise scale
- Unified batch and streaming APIs with SQL support
- Kubernetes-native deployment with automated operations
### Zero-State Streaming Analytics
- Query real-time and historical data without external state stores
- Eliminate database dependencies for streaming applications
- Unified view across continuous and batch data sources
- Real-time feature store capabilities for AI and ML workloads
### Enterprise Operations
- Automated scaling and resource management
- Built-in security with RBAC and compliance controls
- 24/7 support from the team that created Apache Flink
- Deploy on AWS, Azure, GCP, or self-managed infrastructure
---
---
title: "Asset Library"
description: "Browse and download one-pagers, reference sheets, whitepapers, guides, and more. "
lastUpdated: 2026-09-04T07:24:48.000Z
source_url:
html: "https://www.ververica.com/asset-library"
md: "https://www.ververica.com/asset-library.md"
---
# Asset Library
**One-pagers, reference sheets, whitepapers, guides.**
## Data sovereignty assets
### Data Sovereignty
The only enterprise stream processing platform built in Europe. Keep real-time data under EU jurisdiction, beyond US surveillance.
### FSI Streaming Sovereignty One-Pager
You outsourced operations. They took control. Vendor-managed streaming platforms hide dependencies that surface during audits, outages, and exit negotiations. This one-pager exposes the trade-offs no vendor puts in the pitch deck.
### Sovereignty Self-Assessment Checklist
If your regulator asked you to prove end-to-end control over your real-time streaming data, could you answer: Where does personal data flow? Who can access it? How would you delete it on request?
### Sovereignty Playbook
Comprehensive guide to data sovereignty for FSI. Learn what DORA demands, why most streaming platforms fail.
### Sovereignty Evaluation Framework
Technical evaluation framework for FSI organizations to audit streaming platform sovereignty across deployment, governance, security, AI/ML, and operations
### How Ververica Delivers Sovereignty
Discover how Ververica empowers financial services with architectural sovereignty, offering flexible deployment options and enhanced governance.
### Finance Service Industry Proofsheet
Financial Service Institutions don't get to choose between speed and control. Download this proofsheet and see how five FSI organizations achieve streaming sovereignty with Ververica.
## Banking industry assets
### Finance Industry Reference Sheet
Discover how Ververica empowers financial institutions to leverage real-time data for faster decisions and better customer experiences.
### Mainframe Offloading One-Pager
Modernize your mainframe operations and reduce costs. Download our one-page guide on leveraging Ververica's solutions for real-time data processing and insights.
## Other industry and technology assets
### Ververica vs OS Apache Flink® Info Sheet
While 100% compatible with and built on Apache Flink, Ververica offers additional features, benefits, and capabilities that remove the operational overhead and complexity associated with data streaming.
### Online Gambling & Gaming Industry One-Pager
When timing, user engagement, fraud protection, and personalization are critical to your bottom line, every millisecond matters.
### VERA: The Path to Cloud-Native Apache Flink White Paper
Get a technical introduction to Ververica's Runtime Assembly (VERA), the powerful engine that powers Ververica's Unified Streaming Data Platform.
### Apache Fluss®: The Foundation of the Unified Streaming Lakehouse
This paper traces the architecture that makes that possible, from the storage engine internals to the stateless compute model to the unified feature and context store.
### Low-Code Streaming Pipelines with SQL Ebook
Download the practical guide to building production-grade Flink SQL pipelines with Ververica Platform, from interactive SQL to governed production deployments.
---
---
title: "Fraud Detection"
description: "Detect financial fraud in under 10ms with Ververica's stream processing platform. 6.9B records/sec throughput powered by the VERA engine."
lastUpdated: 2026-06-15T09:46:37.000Z
source_url:
html: "https://www.ververica.com/banking/fraud-detection"
md: "https://www.ververica.com/banking/fraud-detection.md"
---
# Detect Fraud in Real Time, Not After the Fact
Batch fraud detection finds losses. Real-time fraud detection prevents them. With Ververica fraud is identified, scored, and blocked before the transaction clears.
## Batch Fraud Detection
Is a Post-Mortem
Most banks still detect fraud in overnight batch runs. By morning, the money is gone. Alerts fire on transactions that cleared 8 hours ago. Investigation teams chase cold trails.
The global cost of financial fraud exceeded $485 billion in 2025. Batch processing does not detect fraud. It documents it.
What stops you from real-time?
## Core Capabilities
### Pattern Detection
Identify complex fraud patterns across millions of concurrent sessions. Multi-hop transaction chains, velocity checks, and behavioral anomalies. All evaluated in real time against streaming data.
### ML Model Scoring
Execute machine learning models inline with transaction streams. Real-time feature engineering, model inference, and score aggregation. No batch pre-computation. Models score live data at sub-10ms latency.
### Complex Event Processing
Correlate events across accounts, channels, devices, and time windows. Detect coordinated attacks that span multiple entities. Windowed pattern matching at 6.9B records/sec throughput.
### Adaptive Rules Engine
Deploy and update fraud rules without restarting pipelines. Business analysts define rules. The platform applies them to live streams instantly. No deployment cycles. No downtime.
## Key Reasons To choose Ververica
Why Ververica
From transaction ingestion to fraud decision in under 10 milliseconds. Measured in production across tier-1 banks during peak volumes.
The VERA engine sustains 6.9 billion records per second. Black Friday, month-end, market volatility. Throughput does not degrade.
Zero duplicate alerts. Zero missed transactions. Every event is processed once and only once, even during node failures and cluster rebalancing.
Models execute inline with the stream. No round-trip to external scoring services. Feature computation and inference in the same pipeline at full throughput.
## Under the Hood
Ververica's fraud detection runs on the VERA engine, a proprietary extension of Apache Flink built for stateful stream processing at extreme scale. The engine maintains per-session state across billions of concurrent keys with RocksDB-backed state management and incremental checkpointing. State snapshots occur without pausing processing, ensuring zero-latency impact during fault tolerance operations.
ML models deploy as user-defined functions within the Flink job graph. Feature engineering and inference execute in the same JVM process as the stream operator. This eliminates network round-trips to external model servers. Models accept TensorFlow SavedModel, ONNX, and PMML formats. Hot-swapping models requires no pipeline restart.
The complex event processing layer uses a custom NFA (nondeterministic finite automaton) implementation optimized for high-cardinality pattern matching. It evaluates thousands of concurrent patterns across sliding, tumbling, and session windows simultaneously. Combined with Ververica's adaptive rule engine, fraud analysts can modify detection logic in production without engineering involvement.
## Frequently Asked Questions
### How fast can Ververica detect fraud?
Ververica detects fraud in under 10 milliseconds from transaction ingestion to decision. This includes feature computation, ML model inference, rule evaluation, and pattern matching. The latency holds at peak throughput of 6.9B records/sec across production deployments.
### What machine learning frameworks are supported?
Ververica supports TensorFlow SavedModel, ONNX, and PMML model formats for inline inference. Models execute within the stream processing pipeline with no external service calls. Hot-swapping models in production requires no pipeline restart and causes no processing gaps.
### How does this differ from batch fraud detection?
Batch fraud detection runs on historical data, typically hours or days old. Ververica processes transactions as they occur. Fraud is detected and blocked before settlement. The difference is between documenting losses and preventing them. Real-time detection cuts fraud losses by 60% or more.
### Can fraud rules be updated without downtime?
Yes. The adaptive rules engine accepts rule changes in production without pipeline restarts. Business analysts define rules through a management interface. Changes propagate to the processing layer in seconds. No engineering deployment cycles required.
### Does Ververica guarantee exactly-once processing for fraud detection?
Ververica guarantees exactly-once semantics across the entire fraud detection pipeline. Every transaction is evaluated once and only once. No duplicates. No gaps. This holds during node failures, network partitions, and cluster rebalancing operations.
---
---
title: "Blog"
description: ""
lastUpdated: 2026-03-26T12:06:57.000Z
source_url:
html: "https://www.ververica.com/blog"
md: "https://www.ververica.com/blog.md"
---
# engineering. Product. Apache Flink. No Filler.
Technical depth from the team that built Apache Flink. Architecture decisions, performance benchmarks, production patterns, and product announcements. Published when there is something worth reading.
---
---
title: "Demo"
description: ""
lastUpdated: 2026-04-21T16:03:04.000Z
source_url:
html: "https://www.ververica.com/demo"
md: "https://www.ververica.com/demo.md"
---
# See Ververica Platform Run Your Streaming Workloads
**Request a Demo**
A technical walkthrough with the creators of Apache Flink. Bring a use case. Leave with an architecture.
- **>10ms — Sub-10ms latency**
- **40 — Proven at ING Bank**
- **DORA — DORA Compliant**
## A Process Built for Technical Evaluation
### Schedule
Pick a 30-minute slot. We confirm within one business day.
### Scope
A 15-minute pre-call to understand your workload, stack, and goals. We tailor the demo.
### Demo
Live walkthrough of the platform against a scenario that matches your use case.
### Next steps
Architecture notes, a proof-of-concept plan, or pricing, depending on your stage.
## Frequently Asked Questions
### How long does the demo take?
Thirty minutes for the core walkthrough, plus a 15-minute scoping call beforehand. Longer sessions available on request.
### Do I need Flink expertise to join the demo?
No. The demo is calibrated to your team. We run sessions for platform teams new to Flink as well as teams already in production.
### Can we use our own data or workload in the demo?
Yes. Share a workload description during scoping. We prepare a relevant scenario and, where appropriate, can run against sample data that matches your shape.
### What deployment options are covered?
Fully managed Ververica Cloud, self-managed Ververica Platform, and bring-your-own-cloud. We walk through the operational and commercial differences.
### Is this a sales call?
A solutions engineer runs the session. Pricing only comes up if you ask.
---
---
title: "Legal Center"
description: ""
lastUpdated: 2026-06-23T08:23:46.000Z
source_url:
html: "https://www.ververica.com/legal-center"
md: "https://www.ververica.com/legal-center.md"
---
# Support and Legal Center
## Support Plans and Terms
### Ververica Platform: Self-Managed
- Support Services Plans
- Support and Maintenance Services Terms
### Ververica Cloud: Managed Service
- Support Services Plans
- Support and Maintenance Services Terms
- Service Level Agreement
### Ververica Cloud: BYOC
- Support Services Plans
- Support and Maintenance Services Terms
- Service Level Agreement
- Terms of Service
## Legal Center
### License agreements
- Master Software License Agreement
- Evaluation License Agreement
### General
- Privacy Policy
- Terms of Service
- Data Processing Addendum
- Imprint
- Mandatory Information
- Academy Terms of Service
- Preview Policy
### Events
- Supplemental Privacy Policy
- Terms and Service
- Code of Conduct
---
---
title: "Dynamic Pricing"
description: "Optimize your pricing in real time. "
lastUpdated: 2026-03-31T10:30:54.000Z
source_url:
html: "https://www.ververica.com/use-case/dynamic-pricing"
md: "https://www.ververica.com/use-case/dynamic-pricing.md"
---
_No content._
---
---
title: "Real-Time ETL"
description: "Stop delaying decisions waiting for slow data. "
lastUpdated: 2026-03-31T10:31:33.000Z
source_url:
html: "https://www.ververica.com/use-case/extract-transform-load"
md: "https://www.ververica.com/use-case/extract-transform-load.md"
---
_No content._
---
---
title: "Gambling and Gaming One Pager"
description: ""
lastUpdated: 2026-04-21T11:58:37.000Z
source_url:
html: "https://www.ververica.com/asset-library/gaming-industry-powered-by-ververica"
md: "https://www.ververica.com/asset-library/gaming-industry-powered-by-ververica.md"
---
# Win Big by Acting Fast
Do You Operate in a Fast-Paced, High-Volume Digital Environment? Download this one-page guide to learn how Ververica can help put the odds in your favor with real-time data that supports right-now decisions.
When timing, user engagement, fraud protection, and personalization are critical to your bottom line, every millisecond matters.
Ververica builds scalable, low-latency data applications so you can act on your data instantly, securely, and at scale.
Download this must-read if your business provides:
- Gaming
- Online gambling
- Sports betting
- Racing
- Content streaming
- ...or other highly-regulated or "risky" industry
---
---
title: "Contact"
description: ""
lastUpdated: 2026-06-15T09:49:06.000Z
source_url:
html: "https://www.ververica.com/contact"
md: "https://www.ververica.com/contact.md"
---
# Let’s Talk Stream Processing
**Contact us**
Technical depth from the team that built Apache Flink. Architecture decisions, performance benchmarks, production patterns, and product announcements. Published when there is something worth reading.
### Get in touch
Complete the form below, and our team will get in touch with you shortly.
## Trusted by Engineering Teams Worldwide
## Frequently Asked
Questions
### How quickly will I get a response?
We respond to all inquiries within one business day. Technical questions are routed directly to engineering. Sales inquiries receive a response within 4 hours during European business hours.
### Can I get a live demo of the platform?
Yes. Book a demo through our [demo request page](https://ververica.com/demo). A Ververica engineer walks you through the platform in a live environment. No slides. Running systems.
### Is there a free trial available?
Yes. The Ververica Cloud free trial gives you full platform access with $400 in credits. No credit card required. Start at [app.ververica.com.](https://app.ververica.cloud/authenticate/sign-up)
### Where is Ververica located?
Headquarters in Munich, Germany. Additional offices in Frankfurt, Berlin, Barcelona, Spain and London, England. Engineering is distributed across Europe. We serve customers globally.
---
---
title: "Finance Service Industry Proofsheet"
description: "Discover how top-tier financial institutions achieve streaming sovereignty and real-time operational control. Download our guide on moving beyond legacy batch limitations."
lastUpdated: 2026-07-09T11:26:12.000Z
source_url:
html: "https://www.ververica.com/data-sovereignty/finance-service-industry-proofsheet"
md: "https://www.ververica.com/data-sovereignty/finance-service-industry-proofsheet.md"
---
# Finance Service Industry Proofsheet
Financial Service Institutions don't get to choose between speed and control. Download this proofsheet and see how five FSI organizations achieve streaming sovereignty with Ververica.
## Download the FSI Industry Report
In an era where every second counts, financial institutions are breaking free from the constraints of legacy batch systems. By choosing streaming sovereignty, industry leaders are successfully shifting mission-critical operations from fraud detection to risk reporting, from delayed, end-of-day processes to immediate, real-time intelligence. This transition isn't just about speed; it is about reclaiming full control over your data, compliance, and infrastructure.
Our latest report, "FSI Leaders Who Chose Control Over Compromise," details how major banks, insurance providers, and payment platforms have successfully modernized their architectures. You will gain exclusive insights into the non-negotiable strategies these organizations used to secure their data, ensure regulatory compliance, and achieve sub-second latency, all while maintaining the deployment flexibility required by today’s complex financial landscape.
Ready to see how your organization can achieve similar outcomes? Complete the form below to receive the full technical report and discover the blueprint for implementing a future-proof, event-driven streaming platform. Take the first step toward reclaiming your operational sovereignty and turning real-time data into a competitive advantage.
---
---
title: "VERA Whitepaper"
description: ""
lastUpdated: 2026-04-21T11:58:12.000Z
source_url:
html: "https://www.ververica.com/asset-library/vera-whitepaper"
md: "https://www.ververica.com/asset-library/vera-whitepaper.md"
---
# VERA: The Path to Cloud-Native Apache Flink®
Download the white paper "VERA: The Path to Cloud-Native Apache Flink" for a technical introduction to Ververica Runtime Assembly (VERA)
In today’s data-driven landscape, managing and processing large-scale streaming data is essential to staying competitive. While Apache Flink® offers a powerful platform for real-time stream processing, its complexities can be a barrier, often requiring deep technical expertise and significant resources.
That’s where Ververica’s Runtime Assembly (VERA) comes in. VERA is a cloud-native, ultra-high-performance engine that powers Ververica’s Streaming Data Platform, making stream processing accessible to all—not just the experts. By addressing key pain points like latency, scalability, and operational complexity, VERA enhances Flink’s performance and simplifies the user experience.
In this white paper, you will find:
- An introduction to the VERA architecture
- The reasoning behind why Ververica built the VERA engine
- How VERA tackles 5 key challenges of OS Apache Flink
- A brief journey through the democratization of stream processing
- Results of our performance comparison between VERA’s state engine (Gemini) and the open-source Apache Flink state engine (RocksDB)
- Insights into how VERA remains open core and 100% Apache Flink compatible, while evolving Flink to run natively in modern cloud environments
- How VERA simplifies the complexities of fault tolerance while providing better support for large stateful applications
---
---
title: "Resources"
description: "Resources"
lastUpdated: 2026-03-23T12:17:31.000Z
source_url:
html: "https://www.ververica.com/resources"
md: "https://www.ververica.com/resources.md"
---
_No content._
---
---
title: "Gartner Report 2025"
description: ""
lastUpdated: 2026-04-01T12:39:43.000Z
source_url:
html: "https://www.ververica.com/gartner-report-2025"
md: "https://www.ververica.com/gartner-report-2025.md"
---
_No content._
---
---
title: "FF ToS"
description: "Review the essential terms and conditions for attending Flink Forward, including registration, payment, cancellations, and responsibilities of attendees."
lastUpdated: 2026-03-20T13:56:56.000Z
source_url:
html: "https://www.ververica.com/events/terms-and-service/flink-forward"
md: "https://www.ververica.com/events/terms-and-service/flink-forward.md"
---
# Attendee Terms & Conditions
**Last update: March 4th 2025**
## 1. Terms of Service
These terms and conditions for registration and attendance at the Flink Forward Barcelona 2025 event (“**Event**”) organized by Ververica (“**Event Terms**") are binding without qualification or exception, on all persons registered to attend or actually in attendance at our Events (“**Registrant**,” “**you**”). By registering for or attending the Event, each Registrant agrees:
1. to be bound by and shall be deemed to have accepted these Event Terms, which the Registrant has read and understood
1. to review and comply fully with all posted instructions onsite at the Event, as well as Flink Forward’s Code of Conduct and Health and Safety Guidelines, which will be updated from time to time in Ververica’s sole discretion and taking into account the recommendations and requirements of the Centers for Disease Control and Prevention, World Health Organization, federal, state, and local governments, local public health agencies, and
1. they have obtained the consent of their employer, to the extent their employer may so require, prior to registering for the Event and becoming bound by these Event Terms
If the Registrant is not authorized or does not agree to any of these Event Terms, the Registrant shall not attend the Event.
## 2. Payment Information & Terms
Full payment of the Event registration fee must be provided upon submission of the registration form. Full payment must be received at time of purchase. Any Registrants who have not submitted full payment prior to the Event will be charged the day-of rate and required to submit full payment prior to gaining access or entry to the Event. Orders placed on behalf of multiple attendees for group registrations must be current on all group registration fees in order for any member of the group to gain access or entry to the Event.
Please read and understand our transfer and cancellation policies for all registration types.
## 3. Registration Rates and Discount
It is your responsibility to confirm the price displayed at checkout is the price you expect and agree to pay prior to completing the purchase. Upon submission of a complete registration form, the purchase and rate paid are final. We are unable to adjust, return, or refund previously purchased tickets for any reason, except as stated in our “Cancellations/Refund Policy”
Ververica may offer a discount code as part of a limited-time sale. That code may only be applied towards the designated type of individual or group registration, and the value will not transfer to another type of individual or group registration. Ververica honors only one discount code per ticket per Event. Discount codes cannot be applied retroactively.
## 4. Registration Confirmation and Scope of Terms
Upon submission of registration, the Registrant will receive a confirmation of the registration via email. Additional rules may apply at the physical Event venue. Nothing in these Event Terms is designed to censor anyone’s speech or conduct on public property.
## 5. Cancellations/Refund Policy
We understand that life happens; thus, for the Flink Forward Barcelona 2025 conference ticket purchases.
Refunds are permitted according to the following schedule:
1. Refund requests made before 23:59, 29 September 2025 CET will receive a full refund
1. Any requests made after 23:59, 29 September 2025 CET are not eligible for a refund.
We will accept ticket transfers to your nominated person If you are eligible with our provided criteria, please notify us in writing hello@flink-forward.org. If you qualify for a refund, the amount refunded will be based on the actual fees paid for the registration(s) canceled and will be returned to your original payment method.
## 6. Ticket Transfers
If your plans change, you may transfer your ticket, as long as:
1. the ticket is being transferred to another individual
1. we are informed in writing at least 3 calendar days before the Event
To request a ticket transfer, please email [hello@flink-forward.org](mailto:hello@flink-forward.org) with a copy of your ticket number or email confirmation, along with the new attendee’s name, email, title, company, and phone number. You must show that you are the original Registrant or authorized by the original Registrant to make changes to the registration.
## 7. Agenda Changes; Postponement or Cancellation of Event
From time to time, we may make updates to the Event agenda, which may include cancellation of or changes to certain Event activities. While the Event speakers and agenda are confirmed at the time of publishing, there may be substitutions, alterations, or cancellations of the speakers or agenda due to circumstances beyond the control of Ververica. Accordingly, we cannot and do not guarantee any specific speaker, performing artist, entertainment, or other components of the Event agenda. We reserve the right to alter or modify the advertised speakers or agenda, and we will not refund registration fees, provide alternative compensation, or otherwise be liable to you based on these changes. Ververica will take reasonable efforts to update our Website with any substitutions or alterations as soon as reasonably possible.
Ververica is not responsible for any damage or loss as a result of alteration, substitution, delay, postponement, rescheduling, or cancellation of an Event. Ververica will not be considered in breach of these Event Terms or otherwise liable to you, except as specifically provided in this provision, if an Event is delayed, cancelled, rescheduled, or postponed, in whole or in part, as a result of government-ordered closures of venues, services, and other spaces, government-issued shelter-in-place and quarantine orders, government and agency restrictions and recommendations place on individuals and groups of individuals, any law or action taken by a government or public authority, health and travel restrictions, floods, fires, wars, epidemics and pandemics (including without limitation COVID-19 coronavirus), illness, accidents, internet and third party application connectivity, interruption or failure of utility service, electronic or communications failure, war, explosion, fire, flood, drought, earthquake, or other natural disaster, terrorist attack, riots, civil war, loss of electricity, labor or trade dispute, strike, industrial action or lockout, non-performance by service providers and subcontractors, delays by you, and other impediments to performance caused directly or indirectly by any event or circumstances outside Ververica’s reasonable control, that make Ververica’s performance illegal, impossible, inadvisable, or commercially impractical as determined in Ververica’s reasonable discretion. If an Event is delayed, cancelled, rescheduled, or postponed for these or any other reasons, your sole remedy shall be that we will provide you with access to the rescheduled Event or a similar replacement Event, at a later date to be determined by Ververica. Ververica will take reasonable efforts to notify you of any interruptions to the Event as soon as reasonably possible.
## 8. Authorization for Recordings by Ververica and Event Sponsors
Ververica, Event sponsors, and other authorized third parties may from time to time take photos and videos at the Event, which Ververica and those third parties may later use in any format or medium for promotional purposes, or which may otherwise be used, published or posted by a third party, including without limitation, via online posting on a third party or Ververica/Flink Forward website. By participating or attending the Event, each Registrant agrees that he or she may appear in these photos and videos, and authorizes, and agrees to hold Ververica harmless from, their use in this fashion. The views expressed by any Event attendee, speaker, exhibitor or sponsor are not necessarily those of Ververica or its affiliates.
## 9. Special Assistance
You are responsible for advising us regarding any special access, accommodations, or other assistance you require at the time you register for our Event, and we will assist you as best we can. In the event your attendance at our Event requires the granting of a visa, you agree Ververica is not responsible for ensuring the granting of your visa and will not issue a refund if your visa is not granted.
---
---
title: "Low-Code Streaming Pipelines With SQL E-book"
description: "Download this practical guide to building production-grade Flink SQL Pipelines with Ververica Platform. Get a path from interactive SQL development to production Flink applications including dynamic tables, watermarks, windows, temporal joins, SQL Deployments, savepoints, and governance"
lastUpdated: 2026-07-15T12:22:25.000Z
source_url:
html: "https://www.ververica.com/asset-library/low-code-streaming-pipelines-with-sql-e-book"
md: "https://www.ververica.com/asset-library/low-code-streaming-pipelines-with-sql-e-book.md"
---
# Low-Code Streaming Pipelines With SQL
Download this free ebook to learn how to build production-grade FlinkSQL pipelines with Ververica Platform
Streaming is no longer reserved for teams with deep Java expertise. Business and product teams want fresher metrics, operational triggers, and faster delivery cycles, and most transformation logic already starts life as SQL. Flink SQL makes that logic declarative, event-time aware, and production-ready. Ververica Platform takes it the rest of the way: from interactive query authoring to managed Deployments with savepoints, autoscaling, and governance built in. Developers develop business value. Infrastructure teams keep the lights on.
In this ebook, learn:
- How Flink SQL models streams as dynamic tables, and why that mental model matters
- The building blocks of low-code pipelines: connectors, watermarks, windows, and temporal joins
- Three production-proven patterns: clean and route events, real-time enrichment, and KPI aggregation pipelines
- The path from SQL editor to SQL Deployment, including stateful upgrades and savepoints
- How Autopilot autoscaling keeps pipelines backpressure-free while cutting costs
- Governance guardrails: namespaces, templates, UDFs, and artifact management for reusable pipelines
- A clear escalation path for when SQL is enough, and when to drop to Table API or DataStream
- An implementation checklist to launch your first use case
---
---
title: "Imprint"
description: "Ververica GmbH is the responsible entity for all content on the site."
lastUpdated: 2026-07-16T10:27:00.000Z
source_url:
html: "https://www.ververica.com/imprint"
md: "https://www.ververica.com/imprint.md"
---
# Impressum/Imprint
**Last update: 07 February 2026**
## Verantwortlicher i. S. d. § 5 TMG für alle Inhalte:
Ververica GmbH
c/o Mindspace
Herzogspitalstrasse 24
D-80331 München
E-Mail:[info@ververica.com](mailto:info@ververica.com)
## Vertreten durch:
Alexander Walden
Junhua Wang
Hai Yiu Cheung
## Registereintrag:
Eingetragen im Handelsregister.
Registergericht: Amtsgericht München
Registernummer: HRB 309285
## Umsatzsteuer-ID:
Umsatzsteuer-Identifikationsnummer nach §27a Umsatzsteuergesetz:
DE296479687
## Online-Streitbeilegung gemäß Art. 14 Abs. 1 ODR-VO:
Die Europäische Kommission stellt unter [eine Plattform](https://webgate.ec.europa.eu/odr/main/index.cfm?event=main.home.show&lng=DE) zur außergerichtlichen Online-Streitbeilegung (sog. OS-Plattform) bereit. Die Ververica GmbH ist zur Teilnahme an einem Streitbeilegungsverfahren vor einer Verbraucherschlichtungsstelle weder bereit noch verpflichtet.
---
---
title: "Security Information and Event Management"
description: "Supercharge your cybersecurity intelligence and incident response. "
lastUpdated: 2026-03-31T10:32:23.000Z
source_url:
html: "https://www.ververica.com/use-case/security-information-and-event-management"
md: "https://www.ververica.com/use-case/security-information-and-event-management.md"
---
_No content._
---
---
title: "Sovereignty Evaluation Framework"
description: "Sovereignty Evaluation Framework"
lastUpdated: 2026-07-09T11:26:05.000Z
source_url:
html: "https://www.ververica.com/data-sovereignty/fsi-streaming-platform-evaluation-framework"
md: "https://www.ververica.com/data-sovereignty/fsi-streaming-platform-evaluation-framework.md"
---
# The Sovereignty Evaluation Framework for Financial Services Industry
What Regulators Demand (And Your Platform Can't Deliver)
## Can Your Streaming Platform Pass a Sovereignty Audit?
When your fraud detection system runs on infrastructure you don't control, in jurisdictions you can't verify, with data flows you can't audit, you have a sovereignty violation waiting to be discovered.
With **DORA now in effec**t since January 2025, **NIS2 enforced across the EU**, and data residency requirements tightening globally, regulators are scrutinizing real-time data processing infrastructure with increasing rigor. Most streaming platforms fail the test. As we argued in [Data Sovereignty Is Existential and Most Platforms Treat It Like a Feature](https://www.ververica.com/blog/data-sovereignty-is-existential-most-platforms-treat-it-like-a-feature?hsLang=en), sovereignty is a structural requirement not a feature to be added later.
### The Problem: Sovereignty Is an Architecture Issue
Most streaming platform vendors cannot meet FSI sovereignty requirements. This isn't a capability gap: it's an architecture problem.
> **INFO:** For a visual breakdown of how vendor-managed platforms create a false sense of control, see The Control Illusion: What Vendor-Managed Platforms Hide.
And for a deeper analysis of why "Zero Trust" has become marketing theater for most vendors, read Zero Trust Theater: Why Most Streaming Platforms Are Pretenders.
> **NOTE:** And for a deeper analysis of why "Zero Trust" has become marketing theater for most vendors, read Zero Trust Theater: Why Most Streaming Platforms Are Pretenders.
### What's Inside the Evaluation Framework
This technical guide provides a **26-requirement evaluation framework** across five critical sovereignty domains, plus a detailed assessment of how Ververica's architecture addresses each requirement.
> **TIP:** For a detailed look at Ververica's deployment models, governance, and Zero Trust architecture, see How Ververica Delivers Sovereignty for Financial Services.
## Who Should Use This Framework
- **CTOs & VPs of Engineering** to evaluate concrete sovereignty requirements
- **Chief Architects** Identify gaps during platform selection
- **Compliance Officers** Document due diligence for DORA, NIS2, and GDPR
- **Platform Engineers** Evaluate technical sovereignty posture
- **Procurement and Risk Teams** Assess vendor risk and exit strategy
## The Cost of Getting It Wrong
Sovereignty gaps in your streaming infrastructure create compounding business risks:
- **Regulatory findings** that delay projects and consume executive attention
- **Supervisory scrutiny** that constrains growth and innovation
- **Vendor lock-in** that erodes negotiating position and increases costs
- **Data residency violations** with potential fines and reputational damage
- **Architecture debt** that becomes exponentially expensive to remediate
---
---
title: "How Ververica Delivers Sovereignty"
description: "Sovereignty Evaluation Framework"
lastUpdated: 2026-07-09T11:26:15.000Z
source_url:
html: "https://www.ververica.com/data-sovereignty/how-ververica-delivers-sovereignty-for-financial-services-industry"
md: "https://www.ververica.com/data-sovereignty/how-ververica-delivers-sovereignty-for-financial-services-industry.md"
---
# How Ververica Delivers Sovereignty for Financial Services Industry
We Claim It and We Can Prove It. Does Your Provider Can?
## Ververica Platform Architecture
> **INFO:** For a detailed analysis of why sovereignty is now an existential requirement for financial services and not a feature read Data Sovereignty Is Existential, Most Platforms Treat It Like a Feature.
Ververica delivers complete deployment freedom (on-premises, BYOC, or managed cloud) with identical capabilities across all three.
This isn't a tier game where sovereignty costs you features. It's architectural sovereignty by design. Engineered in Europe. Sovereign by design.
> **INFO:** For a visual comparison of how vendor-managed platforms differ from these models and what "managed" actually costs you in control see The Control Illusion: What Vendor-Managed Platforms Hide.
### Apache Flink Foundation: No Lock-In
No Lock-In. No Latency. No Compromise.
Ververica is built on Apache Flink, the open-source stream processing framework we created. This isn't a marketing wrapper around proprietary code. It's genuine open-source foundations with enterprise capabilities layered on top:
- 100% compatible with open-source Apache Flink APIs (no proprietary extensions required)
- Applications can be migrated to self-managed Flink if needed
- Standard DataStream and SQL APIs preserve investment in application code
- Active open-source community supports long-term viability
Ververica enhances Flink with enterprise capabilities such as Autopilot optimizations, governance features, and operational tooling, while maintaining full compatibility with the open-source ecosystem.
### Native Governance Architecture
Governance in Ververica is streaming-native, not an afterthought:
These governance capabilities are designed to support requirements from BCBS 239 (data lineage and traceability), GDPR (data classification and deletion), and DORA (audit trails and incident documentation).
> **NOTE:** For a deep analysis of why most streaming platforms claiming "Zero Trust" are actually engaging in security theater, read Zero Trust Theater: Why Most Streaming Platforms Are Pretenders.
### Zero Trust Security Architecture
Key Architecture Principle: Ververica's BYOC deployment was engineered with Zero Trust principles. The architecture is designed to help customers maintain data governance ownership and retain data sovereignty, with data hosted in cloud environments controlled by them.
Ververica's security architecture implements Zero Trust principles throughout:
- **Verify Explicitly:** Every request authenticated via enterprise IdP integration (SAML, OIDC). MFA support. Short-lived credentials for all access.
- **Least Privilege:** Fine-grained RBAC with namespace isolation. Job-level permissions. No implicit admin access.
- **Assume Breach:** Pluggable TLS certificates enable custom encryption meeting enterprise security policies. Network isolation with Private Link support. Customers control their encryption configuration in self-managed and BYOC deployments.
### Enterprise Operational Architecture
Ververica provides enterprise-grade operational capabilities required for FSI environments:
- **High Availability**: Multi-AZ deployment supported via Kubernetes. Automatic JobManager failover. Zero-downtime upgrades available.
- **Autoscaling**: Autopilot with stable and adaptive resource management. Automatic scaling based on workload, SLO rules, or schedules. Response times depend on workload characteristics and infrastructure configuration.
- **Disaster Recovery:** Checkpoint-based recovery from durable storage. Snapshots, checkpoint/savepoint resume, and state skip capabilities. Configurable RTO/RPO based on checkpoint frequency.
- **Observability:** Native metrics, logging, and tracing. Integration with Prometheus, Grafana, and enterprise APM tools.
### Real-World FSI Implementations
The following case studies demonstrate how financial services organizations have leveraged Ververica to address sovereignty and operational challenges.
#### Global Bank - Mainframe Offloading
**Challenge**: A major global bank faced critical challenges with its legacy mainframe infrastructure: rising MIPS costs, 8+ hour nightly batch cycles composed of 30 tightly coupled steps, and dependency on proprietary COBOL-based systems. System instability threatened SLAs, and finding talent for legacy technologies became increasingly difficult.
**Solution**: Strategic data offloading using Ververica Platform powered by Apache Flink. Rather than a risky rip-and-replace, the bank maintained the mainframe as a secure source of truth while shifting computationally intensive workloads to modern streaming infrastructure. Critical COBOL business logic was refactored to Java, with data extracted via JDBC and processed in real-time.
**Results:**
- 90% reduction in mainframe MIPS consumption
- 60% faster batch processing (8+ hours reduced to ~3 hours)
- Over $1M annual cost savings
- Deployment from design to production in under 3 weeks
**Sovereignty Relevance:** This case demonstrates that sovereignty includes the ability to progressively exit closed, proprietary environments. By decoupling from mainframe dependency, the bank regained control over critical workflows, achieved workload portability, and established technological reversibility.
Reference: [Global Bank Achieves 90% Cost Savings with Mainframe Offloading!](https://www.ververica.com/blog/global-bank-achieves-90-cost-savings-with-mainframe-offloading?hsLang=en)
## Evaluate Your Platform
- **Quick assessment**: Use the [Streaming Sovereignty Checklist](https://www.ververica.com/streaming-sovereignty-checklist-for-financial-services-industry?hsLang=en) to evaluate your current platform's sovereignty posture against what regulators actually demand
- **Structured evaluation**: Apply the [Sovereignty Evaluation Framework](https://www.ververica.com/fsi-streaming-platform-evaluation-framework?hsLang=en) a 26-requirement scored assessment across five sovereignty domains.
---
---
title: "VIPKid Case Study"
description: "Discover how VIPKid uses Ververica Platform to enhance online education with real-time feedback and optimizations facilitating over 100,000 lessons per day."
lastUpdated: 2026-07-15T05:39:00.000Z
source_url:
html: "https://www.ververica.com/case-study/vipkid"
md: "https://www.ververica.com/case-study/vipkid.md"
---
# XM Cyber
Building a robust multi-tenant platform for the future of tomorrow.
XM Cyber, a leading hybrid cloud security company founded by top executives from the Israeli cyber intelligence community, is a technology leader in its approach to cyber risk.
XM Cyber utilizes its Apache Flink® (Flink) applications to ensure unlimited scaling for customers, in real-time, regardless of data volumes (up to 1 terabyte every 24 hours for each of its customers).
When deciding how to deploy a multi-tenant Flink architecture with the capability to scale, XM Cyber turned to Ververica, the Original Creators of Apache Flink®, and its solution, Ververica Platform, to help manage the Flink jobs that form part of its industry-leading security solutions.
Real-time stream processing is critical for XM Cyber to maintain high performance and security within its Cyber Security solutions. Utilizing stream processing enables XM Cyber to respond to data changes and potential threats before they happen. Integrated with Ververica Platform, XM Cyber’s streaming architecture has evolved to be a true multi-tenant model.
Download the case study to discover how Ververica Platform supported XM Cyber in achieving:
- Unlimited flexibility and scaling - handling terabytes of data from it’s customers
- The low latency requirement without resource over allocation
- Reduced running costs and engineering overheads and more
---
---
title: "Ververica Platform Self-Managed 3.x"
description: ""
lastUpdated: 2026-06-15T09:49:27.000Z
source_url:
html: "https://www.ververica.com/ververica-platform-3-x"
md: "https://www.ververica.com/ververica-platform-3-x.md"
---
# Ververica Platform: Self-Managed 3.x
- **10x — Faster Deployment**
- **90% — Faster Diagnostics**
- **97% — Faster Snapshots**
- **40-60% — Cost Reduction**
## One Major Release
Powered by Three Years of Customer Feedback
Ververica's Unified Streaming Data Platform Self-Managed version 3 isn't an upgrade; it's a complete reimagining of what a unified streaming platform can do for real-time data teams. After listening to data engineers overwhelmed by deployment complexity, operation teams battling production issues at 3 AM, and architects losing sleep over governance and compliance audits, we built Ververica Platform 3 to tackle these challenges head-on.
## Powered by the VERA Engine
#### Enterprise-grade performance, now available in Ververica platform self-managed version 3
VERA is the heart of Ververica’s Streaming Data Platform, the engine that operationalizes streaming data and optimizes open source Apache Flink. VERA allows you to connect, process, analyze, and govern your data in one ultra-high-performance streaming data solution. Created to solve both batch and real-time streaming use cases, VERA makes it easy for you to harness insights from your data at any volume and scale.
## Infrastructure Improvements
With 97% faster snapshots, state migrations that once took 20 minutes now take 30 seconds.
With hot data in memory/SSD, and cold data in object storage, you'll never hit disk limits.
Access up to 2x faster streaming joins with low match rates.
Update fraud detection rules in your database table, and running jobs pick up the changes automatically with no job restart. Now you can react to threats in minutes, not days.
Move data with one SQL statement: CREATE TABLE target AS SELECT * FROM source - and Ververica handles the rest: automatic schema inference, offset tracking, delivery guarantees, and seamless schema evolution.
### Streamhouse
### Unified Streaming and Analytics
#### Now available in Ververica Platform 3 as part of the VERA engine
**The Problem:** Your legacy data architecture is faced with an impossible choice: real-time streaming OR cost-effective analytics. You run duplicate pipelines, streaming in Apache Flink, and batch ETL to warehouses. Two systems means double the maintenance, and a permanent lag between real-time and historical data.
**The Solution:** Streamhouse unifies streaming and batch with a lakehouse architecture. Stream your data directly into open lakehouse table formats such as Apache Paimon or Iceberg stored in S3, GCS, or Azure Data Lake. Query in streaming mode (for millisecond latency) or batch mode (for warehouse-scale analytics). Same table. Same SQL. Zero duplication. Easier management.
### Developer Efficiency
### Ship Faster, Break Less
**Before Ververica: **Data engineers spend more time fighting the platform than building pipelines. Typos in SQL? Find out at runtime. Need to test? Deploy to production and hope it goes well. Tracking deployment versions? Keep your own spreadsheet.
**With Ververica:** Full validation catches errors before deployment. Sandbox test with mock data to ensure you are production-ready. Utilize auto-versioning with one-click rollback. Lose zero work with auto-save.
### Operational Excellence
### Diagnose Problems in 60 Seconds (Instead of 45 Minutes)
**Before 3:** Ops teams live in log files, Kubernetes dashboards, and hope for the best. Any failed deployment results in 45 minutes of detective work across pods, namespaces, and external tools.
**With 3:** With one glance, your health dashboard pinpoints exactly what's wrong, where, and why, all in under 60 seconds. Get real-time notifications, centralized logs, and full visibility, no kubectl required.
### Data Governance
### Compliance Audits in Days, Not Months
**Before 3:** Questions like "Show us how Personally Identifiable Information (PII) flows through your system" results in weeks of grep'ing SQL files and drawing diagrams in Lucidchart. Column-level tracking? Forget it.
**With 3:** Arm your compliance officer with complete lineage graphs in 30 seconds. Click a column, and see the entire upstream and downstream flow. Export to JSON/CSV for auditors.
### Elasticity
### The Platform That Scales Itself
**Before 3:** Scaling is manual. Traffic spiked at 9 AM? Someone has to notice, calculate new parallelism, trigger a savepoint, and redeploy. You pay for peak capacity 24/7 or suffer degraded performance.
**With 3:** Meet the platform that scales itself. Autopilot 2.0 monitors CPU, memory, and latency across any source. Adaptive mode handles unpredictable spikes. Stable mode locks in optimal configuration, while scheduled tuning follows business cycles.
---
---
title: "VVP Support Services Plans"
description: "Ververica offers comprehensive support services plans for Ververica Platform Self-managed, including 24/7 observability and tailored consultancy. "
lastUpdated: 2026-04-21T12:17:58.000Z
source_url:
html: "https://www.ververica.com/product/deployment/self-managed/support"
md: "https://www.ververica.com/product/deployment/self-managed/support.md"
---
# Support Services Plans
Ververica Platform: Self-managed
This page provides a detailed overview of the support services by Ververica. As a Ververica customer, you have a wide range of support options at your disposal. Whether it’s about finding answers to your questions or getting guidance with critical issues, our team is here to help.
Ververica provides four support levels to accommodate specific customer needs depending on your business requirements. The levels are described below.
| Feature | Bronze | Silver | Gold |
| --- | --- | --- | --- |
| Support availability | Business hours coverage:
Monday - Friday
9.00 am - 6.00 pm | Business hours coverage:
Monday - Friday
9.00 am - 6.00 pm | 24/7 production support |
| Severity Target Response Times | (P1)
Within 8 business hours
(P2)
Next business day
(P3)
up to 3 business days
(P4)
up to 7 business days | (P1), (P2)
Within 4 business hours
(P3)
Within 8 business hours
(P4)
up to 24 business hours | (P1), (P2)
Within 1h (7x24)
(P3)
Within 4 business hours
(P4)
up to 24 business hours |
| Portal based support: Support | ✓ | ✓ | ✓ |
---
---
title: "What is Apache Fluss"
description: "Apache Fluss is a streaming-native lakehouse storage engine for Apache Flink. Achieve sub-second latency and stream-table duality at scale."
lastUpdated: 2026-05-15T08:09:07.000Z
source_url:
html: "https://www.ververica.com/ecosystem-introduction/what-is-apache-fluss"
md: "https://www.ververica.com/ecosystem-introduction/what-is-apache-fluss.md"
---
# What is Apache Fluss™?
Learn more about Apache Fluss, the open-source, unified streaming storage layer designed to optimize real-time data processing.
> **INFO:** Apache Fluss is an open-source, unified streaming storage layer designed to optimize real-time data processing with Apache Flink®. It bridges the gap between streaming and analytical storage by providing a single, high-performance platform for both real-time updates and historical queries on data.
In order to get immediate insights from ever-growing data volume, modern enterprises face a constant challenge: **how to efficiently store and query vast streams of information in real-time, while also retaining the ability to perform deep historical analysis**. Traditional architectures often consist of disparate systems for messaging, stream processing, and long-term storage. As a result, these separate systems introduce complexity, latency, and significant operational overhead.
This is precisely the critical gap that Apache Fluss aims to close. Fluss is an open-source project that acts as a unified streaming storage layer, and is built for next-generation data analytics and to revolutionize real-time data processing with Apache Flink.
Fluss is built in column format instead of log format, and fills a missing gap in streaming technologies. It is a streaming storage layer that resembles a data warehouse while also being native to Flink. It allows decisions based on both historical and current data at the millisecond level because you don’t have to re-read the entire data set to get the relevant data out each time.
## Why Fluss and Columnar Streaming Reads Are Essential for Analytics
Fluss is built as a columnar streaming reads, retrieving data by **columns** instead of rows. This approach significantly boosts performance in analytics scenarios, including:
- **Targeted Data Access:** Only the necessary columns are read, reducing data transfer and processing time. For example, in a dataset with 50 columns, if analytics only require 3, columnar reads avoid loading irrelevant data.
- **Optimized Compression:** Columnar formats store similar data types together, enabling better compression ratios and faster decompression during reads.
- **Accelerated Query Speed:** Processes analytics queries like aggregations and filters directly on columns, leading to significant speedups compared to row-based processing.
## The Evolution of Data Storage: Why Fluss is Essential
For years, the backbone of event-driven architecture and data [stream processing](https://www.ververica.com/stream-processing-with-apache-flink-beginners-guide?hsLang=en) has largely relied on message queues like Apache Kafka®. However, these systems are not designed to serve as a primary analytical storage layer. This limitation creates a significant bottleneck for applications demanding both high-throughput writes and low-latency analytical reads directly on streaming data. Challenges include:
- **High Network Costs and Bottlenecks:** Kafka's architecture often necessitates extensive data movement across networks, **leading to considerable infrastructure costs and performance issues**, particularly when scaling for comprehensive real-time analytics.
- **Missing Columnar Streaming Storage:** There is a gap in the ecosystem for a streaming storage solution that natively supports a columnar format, which is essential for fast analytical queries and efficient data compression. Existing solutions struggle to transform to meet these rigorous needs.
- **Complex and Disconnected Pipelines:** Integrating message queues, stream processing frameworks like Apache Flink, and separate OLAP (Online Analytical Processing) systems for analysis often results in complex, multi-layered pipelines that are difficult to manage, debug, and optimize.
Recognizing these longstanding challenges, a team of experts with deep knowledge of Apache Flink began work on a new project to create a dedicated streaming storage layer that is tuned for today's stream processing demands. This effort created Fluss, which is a current incubator project for the Apache Software Foundation.
Fluss is named from the German word for 'river,' symbolizing the continuous data flow it's built to handle. Fluss marks a significant advance toward a fully unified platform for both batch and streaming data, because it allows for seamless data management from the point of ingestion through to when that data is analyzed. To learn more, read the blog: "[Fluss: Unified Streaming Storage For Next-Generation Data Analytics.](https://www.ververica.com/blog/introducing-fluss?hsLang=en)"
## A Unified Streaming Storage Solution
As a high-performance, scalable, and fully integrated storage system, Fluss is designed to power real-time analytics. It combines the best attributes of streaming and analytical storage, providing a unified layer that eliminates the need for separate message queues and additional OLAP systems in many analytical workflows. At its core, Fluss:
- **Offers Unified Batch and Stream Processing:** Fluss provides a singular platform that handles both batch and streaming data seamlessly. This integration is crucial for optimizing infrastructure for sophisticated AI, ML, and analytical workloads, allowing businesses to perform efficient historical processing alongside live data streams.
- **Bridges the Gap for Real-time Analytics:** Fluss directly addresses the shortcomings of traditional architectures by offering a storage layer optimized for continuous updates and lightning-fast analytical queries on streaming data. This is particularly beneficial for applications where low latency is paramount.
- **Streamlines Data Pipelines:** By integrating natively with Apache Flink, Fluss simplifies complex data pipelines. **It removes the necessity for intermediate Kafka topics, reducing infrastructure costs,** enhancing scalability, and improving overall performance for high-throughput, low-latency analytics.
To meet use cases that rely on fast and efficient analytics (like powering dashboards, detecting anomalies, or training machine learning models), **columnar data formats** are essential.
- Kafka’s **log-based design** is suited for transporting events but falls short when deep analysis or rapid insights are required.
- Systems like **Fluss** fill this gap by offering **columnar streaming reads**, enabling immediate, high-performance access to data for analytical workloads while maintaining compatibility with streaming use cases.
In short, while Kafka excels as a message broker for streaming events, its **row-based log format** limits its utility for analytics. For analytics at scale and speed, a columnar storage and processing layer like Fluss becomes crucial.
The key differentiators Fluss offers are:
- Supports large scale data in motion and allow that data to flow faster (just like a river)
- Bridges compute and data lakes
- Delivers data faster, with less delay and millisecond level latency
**With Fluss, the line between storing data and making decisions with that data becomes indistinguishable.**
Apache Fluss is production-ready, running internally with the team that developed it prior to it becoming an open-source project, demonstrating its readiness and robust capabilities. Its status as an Apache project underscores its commitment to open-source collaboration and community-driven development, further solidifying its role as a key stream processing framework component. This important step was announced in the recent blog: [Fluss Is Now Open Source.](https://www.ververica.com/blog/fluss-is-now-open-source?hsLang=en)
## Core Features and Advantages of Fluss
Fluss is packed with innovative features that set it apart as a premier streaming storage solution, making stream processing with Apache Flink even more powerful. Some of these features include:
### Sub-Second Latency
- **What it Does:** Delivers sub-second latency for both streaming reads and writes.
- **Why it Matters:** Critical for time-sensitive applications like monitoring systems and financial platforms, ensuring instant data availability for actionable insights.
### Stream-Table Duality with Updates and Changelogs
- **What it Does:** Supports stream-table duality, providing changelogs for efficient updates and consistent data flow.
- **Why it Matters:** Enables accurate real-time and historical insights within a unified system.
### Ad-hoc, Interactive Queries
- **What it Does:** Provides a fully queryable storage layer for direct inspection of data.
- **Why it Matters:** Simplifies debugging, reduces development complexity, and enables immediate access to live insights without additional processing layers.
### Unified Batch and Stream
- **What it Does:** Seamlessly combines batch and streaming data processing.
- **Why it Matters:** Optimizes infrastructure for AI, ML, and analytics workloads, allowing smooth transitions between historical and real-time processing.
### Projection Pushdown
- **What it Does:** Optimizes streaming reads by fetching only the required fields.
- **Why it Matters:** Minimizes data transfer, improves query performance up to 10x, and reduces network costs.
### Columnar Streaming Reads
- **What it Does:** Stores and processes data in a columnar format for streaming reads.
- **Why it Matters:** Improves compression efficiency and accelerates analytics, making it suitable for high-volume, real-time applications.
### Integration with Lakehouses
- **What it Does:** Supports bi-directional communication with lakehouse tiered storage systems like [Apache Paimon](https://www.ververica.com/what-is-apache-paimon?hsLang=en) and Apache Iceberg.
- **Why it Matters:** Enables efficient initialization of streaming jobs from batch sources, and ensures seamless synchronization between batch and streaming data.
### Seamless State Initialization and Synchronization
- **What it Does:** Fluss allows a streaming job to load state directly from batch sources.
- **Why it Matters:** This capability enables seamless state initialization and synchronization between batch and streaming data, providing a truly unified data experience.
### Simplified Pipeline Architecture
- **What it does:** With its native integration with Apache Flink, **Fluss eliminates the need for intermediate Kafka topics** and additional OLAP systems.
- **Why it matters:** This dramatically simplifies pipeline architecture and **reduces infrastructure costs while enhancing scalability.**
## Fluss in the Ververica Unified Streaming Data Platform
Fluss is not just a standalone technology; it's a critical component that enhances the capabilities of [Ververica's Unified Streaming Data Platform.](https://www.ververica.com/product?hsLang=en) By providing a scalable, unified batch, and streaming data solution, Fluss addresses key challenges in real-time data processing and storage within the Ververica ecosystem.
- **Enhancing Flink's Capabilities:** Fluss complements Apache Flink's powerful stream processing capabilities by providing the missing piece: **an optimized storage layer for real-time analytics.** This allows users to leverage Apache Flink for both computation and a direct, high-performance storage solution.
- **Driving Real-Time Intelligence:** Fluss is designed to power complex real-time intelligence pipelines, enabling organizations to build highly responsive systems that react instantly to data changes. This is fundamental for modern event-driven architecture and applications that demand immediate insights.
- **Cost Efficiency and Performance:** By streamlining the architecture and optimizing for real-time analytics, **Fluss significantly reduces operational overhead and infrastructure costs** compared to traditional multi-system approaches. Its sub-second latency and columnar reads contribute directly to superior performance, making data [stream processing](https://www.ververica.com/stream-processing-with-apache-flink-beginners-guide?hsLang=en) more efficient than ever before.
- **Foundation for AI/ML Workloads:** The unified batch and streaming capabilities, combined with real-time updates, make Fluss an ideal foundation for feeding fresh data to [AI and ML models](https://www.ververica.com/use-case/ai-ml?hsLang=en), accelerating model training and inference.
In addition, Fluss equips businesses to stay competitive, adapt quickly, and future-proof investments through scalable, efficient, and modern data solutions. Key results include:
### Stay Competitive
- **How it Helps:** Fluss gives you a technological edge by enabling faster, smarter decisions.
- **What is the Impact:** Fluss processes and delivers data instantly, enabling your teams to respond to events like market changes, system alerts, or customer actions in real time.
### Adapt Quickly
- **How it Helps:** Fluss provides seamless integration and fast data flow.
- **What is the Impact:** You can adapt to changing market conditions and customer needs quickly.
### Future-Proof Your Investments
- **How it Helps:** Fluss provides a scalable, adaptable, and forward-looking data infrastructure designed to support evolving technology trends and business needs.
- **What is the Impact:** Fluss is part of an essential part of a forward-looking data strategy. By providing a platform that evolves with technological advancements and business demands, Fluss empowers organizations to make investments that deliver long-term value and adaptability.
### Simplify Your Data Architecture
- **How it Helps:** By combining real-time and historical data handling into one platform, Fluss eliminates the need for separate systems
- **What is the Impact:** reducing operational complexity and ensuring compatibility with future data demands.
### Seamless Integration With Emerging Technologies
- **How it Helps:** By supporting advanced AI, machine learning, and analytics workloads, your business can leverage cutting-edge tools and methodologies
- **What is the Impact:** No need to overhaul your data architecture.
### Built For Scalability
- **How it Helps:** Fluss is designed to scale with growing data volumes.
- **What is the Impact:** Fluss ensures that your business can handle increasing workloads as operations expand without sacrificing performance.
### Compatibility With Modern Data Ecosystems
- **How it Helps:** Fluss integrates seamlessly with popular data lakehouse systems (like [Apache Paimon](https://www.ververica.com/what-is-apache-paimon?hsLang=en) and Apache Iceberg).
- **What is the Impact:** Fluss ensures that your business can adapt to the latest data management paradigms without disrupting existing workflows.
### Open-Source Flexibility With Commercial Support
- **How it Helps:** Fluss is operated on open-source principles and flexibility in combination with Ververica’s expert help.
- **What is the Impact:** Fluss ensures your business retains control and avoids vendor lock-in while benefiting from Ververica’s commercial enhancements and support.
### Optimize Resources
- **How it Helps:** Delivers efficient data processing and reduced network costs
- **What is the Impact:** Fluss provides a cost-effective solution, especially for data-intensive industries like finance, retail, and technology.
## Use Cases Transformed by Fluss
The introduction of Fluss opens up new possibilities and transforms existing use cases across various industries:
- **Real-time Dashboards and Monitoring Systems:** Powering dashboards with sub-second latency, providing up-to-the-minute views of business operations, system health, and key performance indicators.
- **Streaming ETL and ELT:** Streamlining the [Extract, Transform, Load](https://www.ververica.com/use-case/extract-transform-load?hsLang=en) processes by enabling continuous data movement and transformation directly within the streaming storage layer.
- **Real-time Intelligence Pipelines:** Building sophisticated pipelines for [fraud detection](https://www.ververica.com/use-case/fraud-detection?hsLang=en), [personalized recommendations](https://www.ververica.com/use-case/customer-360?hsLang=en), anomaly detection, and [other](https://www.ververica.com/use-case?hsLang=en) applications that require immediate decision-making based on live data.
- **Streaming Data Warehouses:** Serving as the real-time data layer on the Lakehouse, allowing for continuously updated data warehouses that support both streaming-first architectures and traditional batch queries.
- **Operational Analytics:** Enabling direct data inspection for debugging and troubleshooting live applications, reducing time-to-insight for operational teams.
Fluss's ability to provide real-time updates makes it a natural fit for scenarios where data freshness is critical, ensuring that decisions are always based on the most current information.
## The Road Ahead
The decision to open-source Fluss and donate it to the Apache Software Foundation marks a significant milestone. This commitment ensures that Fluss will benefit from community-driven development, fostering innovation and wider adoption. As the project continues to evolve, capabilities will expand and further solidify Fluss’s position as a leading solution for unified streaming storage. Ververica remains committed to supporting and contributing to Fluss, ensuring its continued integration and optimization within [Ververica’s Unified Streaming Data Platform.](https://www.ververica.com/deployment?hsLang=en)
Apache Fluss represents a pivotal innovation in the world of stream processing and data analytics. By addressing the critical need for a unified, high-performance streaming storage layer, it simplifies complex data architectures, **reduces costs**, and accelerates the delivery of real-time insights. Its deep integration with Apache Flink makes stream processing with Apache Flink more powerful and efficient than ever before. For organizations striving to build agile, event-driven architecture and unlock the full potential of their data stream processing capabilities, Fluss offers a clear path forward, streamlining the journey **from raw data to actionable intelligence**.
## FAQ
### How is Fluss different from Apache Flink?
Flink is a stream processing engine for building and running pipelines, while Fluss is a storage/serving layer that keeps materialized views over streams for fast queries and lookups.
### What problems does Fluss solve?
Fluss reduces stack complexity by replacing a patchwork of stream processor + message bus + cache + OLAP store with a single streaming data layer that provides consistent, sub‑second reads.
### Can Fluss handle late or out‑of‑order events?
Yes, Fluss is designed to work with time‑aware processing (e.g., event‑time and watermarks) so derived tables stay consistent as late data arrives.
### What are typical use cases for Fluss?
Common uses include real‑time dashboards, fraud/risk scoring, personalization, operational analytics, leaderboards, and fast dimension lookups for streaming joins.
---
---
title: "Apache Fluss™ Private Preview "
description: "Join the Apache Fluss™ Private Preview. Evaluate this pre-release streaming data technology in a non-production environment. Collaborative participation required. Review our full terms to get started.1"
lastUpdated: 2026-06-18T09:13:22.000Z
source_url:
html: "https://www.ververica.com/apache-fluss-private-preview"
md: "https://www.ververica.com/apache-fluss-private-preview.md"
---
# Apache Fluss™ Private Preview - Terms of Participation
These Terms of Participation (“**Terms**”) govern your organisation’s participation as an organisation invited by Ververica to participate (“**Participant**”) in the Apache Fluss Private Preview Program (the “**Program**”) operated by Ververica GmbH, Herzogspitalstraße 24, 80331 Munich, Germany (“**Ververica**”). By accessing the preview, the Participant accepts these Terms. These Terms constitute the entire agreement between the parties regarding the Program and are not conditional on any existing commercial relationship between them. Where the Participant also holds a separate platform agreement or MSLA with Ververica, these Terms govern the Program specifically and prevail over that agreement to the extent of any conflict on Program-related matters.
## 1. PROGRAM & ACCESS
Ververica grants the Participant a limited, non-exclusive, non-transferable, revocable licence to access a non-production deployment of Apache Fluss running within the Ververica Platform, solely for evaluation, testing, and collaborative product validation during the preview period. Access is provided **free of charge** and confers no right to General Availability (GA) software, future releases, or any production entitlement.
## 2. PREVIEW NATURE
Apache Fluss is open-source software undergoing incubation at the Apache Software Foundation and is pre-release within the Program. The Participant acknowledges it may contain bugs, errors, or security vulnerabilities; that features, APIs, and operational workflows may change or be withdrawn; and that it must not be used for production, business-critical, or SLA-backed workloads.
## 3. PARTICIPANT COMMITMENTS
Participation is collaborative and requires active engagement throughout the approx. six-month Program, including:
1. Technical engagement of roughly 3–5 hours per week, including active testing of representative Fluss workloads and timely bug reports and feedback;
1. Attendance at scheduled working sessions (weekly during onboarding, moving to biweekly), monthly executive reviews, and milestone and roadmap reviews;
1. Nomination of a technical sponsor and an executive/business sponsor for the engagement.
**Non-Engagement.** Where a Participant fails to meet the engagement commitments set out in this Section 3 in any material respect for a continuous period of four (4) weeks, Ververica may, on written notice, treat such failure as grounds for termination of the Participant’s access under Section 11. Ververica will use reasonable endeavours to raise non-engagement informally before exercising this right.
## 4a) FEEDBACK
The Participant may provide suggestions, comments, and feedback on the preview (“Feedback”). Ververica may use Feedback without restriction or obligation, including to develop and improve its products, and the Participant grants Ververica a perpetual, irrevocable, royalty-free licence to do so.
## 4b) BENCHMARKING
The Participant shall not, without Ververica’s prior written consent, conduct, publish, or disclose to any third party any performance benchmarking, competitive analysis, or comparative testing of the preview software against any other product or service. Any benchmarking conducted internally for the Participant’s own evaluation purposes shall be treated as Confidential Information and subject to the obligations in Section 5 and 6. Ververica reserves the right to review and approve any proposed publication of benchmarking results prior to disclosure, such approval not to be unreasonably withheld.
## 5. CONFIDENTIALITY
Each party (“Discloser”) may disclose non-public information to the other (“Recipient”) in connection with the Program (“Confidential Information”). The preview software, related documentation, and all non-public technical, commercial, and product information disclosed by Ververica are Ververica’s Confidential Information. The Recipient shall: (a) hold Confidential Information in strict confidence using at least the same degree of care it uses for its own confidential information (and no less than reasonable care); (b) use Confidential Information solely for the purposes of the Program; and (c) not disclose Confidential Information to any third party without the Discloser’s prior written consent (which may be given by email from an authorised representative). Confidential Information does not include information that is or becomes publicly available through no fault of the Recipient, was already known to the Recipient free of restriction, or is independently developed by the Recipient without reference to the Discloser’s information. These obligations survive termination of these Terms for three (3) years.
## 6. COMMUNICATIONS AND PUBLIC ANNOUNCEMENTS
Neither Party shall make any public announcement, press release, social media post, conference presentation, or other external communication that references the other Party’s participation in the Program, the existence of the Program, or any features or capabilities of the preview software, without the other Party’s prior written approval of the content and timing of such communication. For the avoidance of doubt, this restriction applies to the Participant’s employees, contractors, and any representatives attending working sessions under Section 3. Ververica may issue a joint announcement regarding the Program at a time of its choosing, and the Participant agrees to cooperate reasonably in preparing and approving such announcement within five (5) business days of request. This clause shall survive termination of the Participant’s participation for a period of twelve (12) months or until Ververica publicly announces general availability of Apache Fluss, whichever is earlier.
## 7. DATA, OWNERSHIP & SECURITY
The Participant retains ownership of its data and workloads and is responsible for ensuring that no sensitive, regulated, or production-critical data is used with the preview unless expressly agreed in writing. The Participant is responsible for the security of its own environments and credentials.
## 7a) DATA PROTECTION
Each party shall comply with all applicable data protection and privacy laws in connection with the Program, including the EU General Data Protection Regulation (2016/679) (“GDPR”) where applicable. Any personal data provided by the Participant in connection with registration or use of the preview will be processed by Ververica in accordance with Ververica’s Privacy Policy, available at www.ververica.com. To the extent that Ververica processes personal data on behalf of the Participant as a processor in the course of the Program, the parties shall enter into a Data Processing Addendum (“DPA”) on terms compliant with applicable data protection law prior to any such processing commencing. The Participant is responsible for informing its own data subjects of any processing of their personal data in connection with the Program and for obtaining any consents required by applicable law. The Participant shall not submit to the preview environment any personal data of data subjects who have not been appropriately informed, unless a DPA is in place and the processing is otherwise lawful.
## 7b) INTELLECTUAL PROPERTY
Each party retains all right, title, and interest in and to its own intellectual property existing prior to or developed independently of the Program. Nothing in these Terms transfers any intellectual property rights from one party to the other. The licence granted in Section 1 is limited strictly to evaluation and testing for the purposes of the Program and does not confer any right to use the preview software for commercial purposes, to sublicence it, or to develop derivative works based upon it. The Participant retains ownership of its own data and workloads submitted to the preview environment. Ververica retains all rights in the preview software, documentation, and any improvements or developments made to them, including those informed by Feedback provided under Section 4.
## 7c) INDEMNIFICATION
Each party (“Indemnifying Party”) shall defend, indemnify, and hold harmless the other party and its affiliates, officers, directors, and employees from and against any third-party claims, losses, damages, costs, and reasonable legal fees arising out of or relating to: (a) the Indemnifying Party’s material breach of these Terms; (b) the Indemnifying Party’s violation of applicable law; or (c) in the case of the Participant, any use of the preview software in a manner not authorised by these Terms. This indemnity does not apply to the extent that the claim arises from the other party’s own negligence or wilful misconduct.
## 8. SECURITY VULNERABILITY DISCLOSURE
If the Participant discovers or reasonably suspects a security vulnerability in the preview software or associated infrastructure, the Participant shall: (a) notify Ververica promptly and in any event within forty-eight (48) hours of discovery, by contacting security@ververica.com or such other address as Ververica may notify; (b) provide sufficient detail to allow Ververica to assess and reproduce the vulnerability; (c) not disclose the vulnerability to any third party or take any action to exploit it until Ververica has confirmed remediation or given written consent to disclosure; and (d) cooperate reasonably during investigation and remediation. Ververica shall acknowledge receipt within twenty-four (24) hours and provide an initial assessment within five (5) business days. Nothing in this clause limits Ververica’s obligations under applicable law regarding security incident notification.
## 9. NO WARRANTY & NO SLA
THE PREVIEW SOFTWARE IS PROVIDED “AS IS” AND “AS AVAILABLE” WITHOUT WARRANTIES OF ANY KIND, WHETHER EXPRESS, IMPLIED, OR STATUTORY, INCLUDING IMPLIED WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE, OR NON-INFRINGEMENT. Production support SLAs and availability guarantees do not apply.
## 10. LIMITATION OF LIABILITY
TO THE MAXIMUM EXTENT PERMITTED BY LAW, VERVERICA SHALL NOT BE LIABLE FOR ANY INDIRECT, INCIDENTAL, SPECIAL, CONSEQUENTIAL, OR PUNITIVE DAMAGES, OR FOR ANY LOSS OF DATA, REVENUE, PROFITS, OR BUSINESS INTERRUPTION ARISING FROM PARTICIPATION IN THE PROGRAM. Nothing in these Terms excludes liability that cannot be excluded by law.
## 11. TERM & TERMINATION
These Terms apply for the duration of the Program, which shall commence on the date these Terms are first accepted by the Participant and run for approximately six (6) months unless extended or terminated earlier in accordance with this Section 11. Either party may terminate participation at any time on written notice. On termination or expiry, the Participant shall cease use of the preview software; confidentiality, Feedback, and liability provisions survive, as do the Benchmarking Section 4.b), Communications Section 6), and Security Disclosure Section 7 provisions.
## 12. GENERAL
These Terms constitute the entire agreement regarding the Program and supersede prior discussions relating to it. They are governed by the laws of Germany, excluding conflict-of-law rules. “Apache Fluss”, “Apache Flink”, “Apache Iceberg”, and “Apache Paimon” are trademarks of the Apache Software Foundation.
---
---
title: "Risk Management"
description: "Monitor and manage financial risk in real time with Ververica. Continuous exposure tracking, stress testing, and regulatory risk reporting at stream speed."
lastUpdated: 2026-06-15T09:46:45.000Z
source_url:
html: "https://www.ververica.com/banking/risk-management"
md: "https://www.ververica.com/banking/risk-management.md"
---
# Manage Financial Risk in Real Time, Not Hindsight
End-of-day risk reports tell you what already happened. Real-time risk management tells you what is happening now.
## End-of-Day Risk
End-of-Day Blindness
Most banks compute risk positions at market close. Between opens, exposures accumulate unchecked. Limit breaches go undetected for hours. Intraday volatility spikes create losses that appear only in the next morning's report.
The 2025 Basel III/IV requirements demand real-time risk monitoring. Banks running batch risk systems face regulatory non-compliance and uncontrolled exposure. The cost of stale risk data is measured in capital reserves and regulatory penalties.
What stops you from real-time?
## Core Capabilities
### Real-Time Exposure Tracking
Compute portfolio exposure continuously as trades execute, markets move, and positions change. No waiting for end-of-day batch runs. Exposure data is current to the millisecond.
### Continuous VaR Calculation
Value at Risk computed in real time across all asset classes and portfolios. Monte Carlo, historical, and parametric VaR methods execute against streaming market data and live positions.
### Multi-Source Aggregation
Aggregate risk data from trading systems, market feeds, credit systems, and operational risk platforms in a single streaming pipeline. One unified view. No manual reconciliation.
### Automated Limit Breach Detection
Monitor trading limits, counterparty exposure, concentration risk, and regulatory thresholds continuously. Breaches trigger alerts in under 10ms. Automated escalation follows predefined workflows.
## Key Reasons To choose Ververica
Why Ververica
From market event to updated risk metric in under 10 milliseconds. Portfolio VaR, exposure, and limit checks execute at stream speed.
Risk positions update with every trade and market tick. No batch windows. No gaps between computation cycles. 24/7 monitoring across all time zones.
Real-time risk visibility enables tighter capital allocation. Banks holding excess reserves due to stale risk data recover capital for deployment.
Every position, every counterparty, every asset class. No sampling. No materiality thresholds. Complete risk visibility is the regulatory standard.
## Under the Hood
Ververica's risk management platform uses the VERA engine to maintain continuously updated risk state across all positions, counterparties, and portfolios. Position state is partitioned by portfolio and instrument, enabling parallel VaR computation across thousands of portfolios simultaneously. Market data streams merge with position updates in real time, triggering immediate recomputation of affected risk metrics.
Monte Carlo VaR executes as a streaming operator with pre-computed scenario matrices updated on configurable intervals. The engine maintains scenario state in memory, applying perturbations to live positions as they change. Historical VaR uses a streaming window over market data with configurable lookback periods. Both methods produce results within the sub-10ms latency envelope, not through approximation, but through the VERA engine's ability to maintain and query large state stores without disk I/O during normal operation.
Limit monitoring operates as a stateful stream operator that evaluates every position change against hierarchical limit structures. Limits cascade from enterprise to division to desk to trader to instrument. Breach detection is instantaneous because the limit state is maintained in memory and updated atomically with each position change. Pre-breach warnings trigger at configurable thresholds, enabling proactive risk reduction before hard limits are hit.
## Frequently Asked Questions
### How does real-time VaR differ from batch VaR computation?
Batch VaR computes once at end of day using stale position and market data. Ververica computes VaR continuously as positions and markets change. The risk metric reflects the current portfolio state at any given moment. This eliminates the blind spots between batch runs where exposure accumulates unchecked.
### What VaR methodologies are supported?
Ververica supports Monte Carlo, historical, and parametric VaR methods. All three execute as streaming operators against live position and market data. Monte Carlo uses pre-computed scenario matrices applied to real-time positions. Historical VaR operates over configurable lookback windows. Banks can run multiple methods simultaneously.
### Can Ververica handle multi-asset class risk aggregation?
Yes. The platform aggregates risk across equities, fixed income, FX, commodities, derivatives, and structured products in a single streaming pipeline. Cross-asset netting, correlation computation, and portfolio-level metrics execute in real time. No separate systems per asset class.
### How does this support Basel III/IV compliance?
Ververica enables real-time computation of regulatory capital metrics including credit risk, market risk (FRTB), and operational risk. Continuous monitoring satisfies intraday risk management requirements. Output feeds directly into regulatory reporting systems with full audit trails.
### What is the implementation timeline for risk management?
Production deployment typically requires 12 to 16 weeks. The timeline varies based on the number of source systems, asset classes, and risk methodologies. Pre-built connectors for market data feeds, trading systems, and risk reporting platforms accelerate integration.
---
---
title: "Customer Personalization"
description: "Deliver personalized banking experiences in real time. Use stream processing to act on customer behavior as it happens, not after batch runs."
lastUpdated: 2026-06-15T09:46:55.000Z
source_url:
html: "https://www.ververica.com/banking/customer-personalization"
md: "https://www.ververica.com/banking/customer-personalization.md"
---
# Personalize Every Banking Interaction in Real Time
Batch personalization delivers yesterday's offer to today's customer. Real-time personalization acts on behavior as it occurs.
## Batch Personalization
Is Already Irrelevant
Banks build customer segments from overnight batch runs. By the time an offer reaches a customer, the moment has passed. The customer who browsed mortgage rates at 10am gets a mortgage offer at 3pm the next day. Fintechs act in seconds.
Customers do not compare banks to banks anymore. They compare banks to every real-time digital experience they encounter. Batch personalization is not slow. It is invisible.
## Core Capabilities
### Real-Time Event Processing
Process every customer interaction the instant it occurs. App opens, transaction completions, page views, ATM visits, call center contacts. Each event updates the customer context immediately.
### Continuous Profile Enrichment
Customer profiles update with every interaction, not after nightly batch jobs. Behavioral attributes, product affinities, life stage indicators, and risk scores recompute in real time. The profile is always current.
### Next-Best-Action Engine
Determine the optimal action for each customer in real time. Product offers, service interventions, retention triggers, and financial guidance decisions execute against live behavioral data, not stale segments.
### Cross-Channel Orchestration
Coordinate personalization across mobile, web, ATM, branch, and call center in real time. The customer receives a consistent, contextual interaction regardless of channel. State follows the customer, not the channel.
## Key Reasons To choose Ververica
Why Ververica
Next-best-action decisions execute in under 10 milliseconds from event arrival. The offer is ready before the page loads.
Real-time personalization delivers 3x higher offer acceptance compared to batch-segmented campaigns. Relevance drives conversion.
Banks deploying real-time personalization report 45% higher cross-sell rates within the first year. Timing and context drive adoption.
Real-time targeting eliminates irrelevant offers. Marketing spend concentrates on customers with demonstrated, current intent.
## Under the Hood
Ververica's personalization platform maintains per-customer state across hundreds of behavioral attributes using the VERA engine's high-performance state backend. Each customer profile is a continuously updated entity that reflects every interaction in real time. Profile state is partitioned by customer ID, enabling parallel computation across tens of millions of active profiles without cross-partition coordination.
Feature engineering executes as streaming operators that compute behavioral signals from raw events. Recency, frequency, monetary value, channel preferences, product affinity scores, and life stage indicators update with every event. These features feed directly into next-best-action models that score in the same pipeline. The entire path from raw event to personalized decision executes without leaving the VERA engine's processing graph.
Cross-channel orchestration uses a shared state layer that tracks customer context across all channels simultaneously. When a customer starts a mortgage application on mobile, the branch advisor sees updated context in real time. The call center agent has the same view. Offer suppression, frequency capping, and channel preference routing all execute against this shared state. Consistency is guaranteed by the VERA engine's exactly-once semantics across all concurrent channel interactions.
## Frequently Asked Questions
### How does real-time personalization differ from batch segmentation?
Batch segmentation groups customers into static segments updated overnight. Real-time personalization acts on individual customer behavior as it occurs. The decision reflects what the customer is doing now, not what their segment did last week. This produces 3x higher conversion rates versus batch approaches.
### What data sources feed the personalization engine?
Ververica ingests events from mobile apps, web sessions, transaction systems, ATM networks, call centers, CRM platforms, and third-party enrichment services. All sources merge into a unified customer event stream. Profile attributes compute from the combined view in real time.
### Can this integrate with existing marketing platforms?
Yes. Ververica outputs personalization decisions to any marketing automation platform, CRM, or customer engagement system via Kafka, REST APIs, or direct database writes. The platform handles the real-time decisioning. Existing tools handle the delivery. No rip-and-replace required.
### How is customer privacy handled?
All personalization processing runs within the bank's own infrastructure using BYOC deployment. No customer data leaves the bank's environment. GDPR consent management integrates with the event stream. Consent changes propagate in real time. Profile data is purged immediately upon withdrawal.
### What is the typical ROI timeline?
Banks report measurable revenue impact within 90 days of production deployment. Offer conversion rate increases of 2x to 3x are typical in the first quarter. Implementation requires 10 to 14 weeks. The revenue uplift from real-time personalization typically exceeds platform cost within the first six months.
---
---
title: "Streamhouse"
description: "Streamhouse unifies streaming and batch in one architecture. Combine VERA engine, Apache Fluss, and Apache Paimon for end-to-end real-time analytics."
lastUpdated: 2026-06-11T04:53:56.000Z
source_url:
html: "https://www.ververica.com/product/streamhouse"
md: "https://www.ververica.com/product/streamhouse.md"
---
# Streamhouse™. Dual pipelines are done.
**One query. Stream and table. Doesn't matter.**
The streaming lakehouse from the original creators of Apache Flink®. One architecture for streams and tables, real-time and historical, ingestion and analytics. One SQL engine. One governed source of truth.
## What Is Streamhouse?
Streamhouse™ treats every stream as a queryable table and every table as a subscribable stream. One architecture runs ingestion, real-time processing, historical analytics, and AI inference on one governed set of data. Built on Apache Flink® for compute, Apache Fluss™ for low-latency streaming storage, and open table formats for the lake. Union Read crosses both tiers in a single query. Sub-second freshness when the business needs it. Lake economics when it does not.
## One query. Stream and table. Doesn't matter.
STREAMHOUSE™ STACK
| Feature | Technology |
| --- | --- |
| Compute | VERA / Apache Flink® |
| Streaming storage | Apache Fluss™ |
| Lakehouse storage | Any open table format (e.g. Iceberg) |
| Ingestion | Flink CDC |
| Query interface | Flink SQL |
| Governance | Built in |
## One house. Four layers. Zero compromise.
Streamhouse Architecture
### MATERIALIZED TABLES ON VERA
APPLICATION + COMPUTE
Declarative SQL. Freshness-driven refresh. VERA runs stream and batch on one engine, 2x faster than open-source Apache Flink®.
### APACHE FLUSS™
STREAMING STORAGE
Low-latency columnar streaming storage. Real-time KV and log, columnar
tables, lakehouse-native architecture.
### OPEN TABLE FORMATS
LAKEHOUSE STORAGE
Your object store. Your format. Tiering and Union Read cross streaming and lake storage in one query.
### AUTOPILOT + WORKFLOW SCHEDULER
OPERATIONS
Autopilot scales parallelism in real time. The Workflow Scheduler triggers batch on a freshness threshold or cron. Deterministic capacity, no surprises.
## What holds Streamhouse™ up.
## Two stacks. Twice the cost. Half the answers.
Dual pipelines multiply everything that can break. Streaming for real-time. Lakehouse for analytics. Two pipelines. Two storage layers. Two query engines. Two governance models. Two on-call rotations. Data drifts. Costs compound. Engineers leave.
Lakehouses are too slow for what comes next. Iceberg and Delta tables are minutes-to-hours fresh. Acceptable for BI. Fatal for fraud detection, real-time pricing, and agentic AI. Batch was never going to power the next decade.
Pure streaming is too expensive for history. Keeping 90 days of data hot in Kafka is a budget line item nobody wants. And Kafka is not queryable. You cannot SELECT against a topic. So you build a separate lake to compensate. Now you have two systems again.
## Numbers. Not narratives.
The "WHY" You should have it.
- **WRITE PERFORMANCE**: Faster writes than a traditional batch lakehouse.
- **QUERY PERFORMANCE**: Faster analytical queries with streaming preprocessing.
- **COMPUTE THROUGHPUT**: VERA against open-source Apache Flink®
- **CHEAPER THAN KAFKA**: Apache Fluss™ stateless compute and tiered storage
## Pick a stack. Pick a compromise.
| Feature | STREAMING ONLY | CLASSIC LAKEHOUSE | STREAMHOUSE™ |
| --- | --- | --- | --- |
| Freshness | Sub-second | Minutes to hours | Sub-second to seconds |
| Historical queries | Expensive replay | Yes | Yes, in the same query |
| Storage cost | High, hot retention | Low | Low, automatic tiering |
| Query interface | Custom consumers | SQL, batch only | Flink SQL, stream and batch |
| Governance | Separate from lake | Lake only | One control plane |
| Lock-in | Vendor runtime | Open formats | Open all the way down |
---
---
title: "Integrations"
description: "Connect to data sources and destinations. Kafka, databases, cloud services, ML platforms, and more — all natively integrated with Ververica."
lastUpdated: 2026-04-20T09:35:53.000Z
source_url:
html: "https://www.ververica.com/product/integrations"
md: "https://www.ververica.com/product/integrations.md"
---
# Connect Everything. Stream Everywhere.
100+ pre-built connectors. Every major database, message queue, data warehouse, and cloud service. Plug in and stream. No custom code required.
- 100+ Connectors
- 40+ CDC Sources
- SQL Configuration
- E2E Exactly-Once
## How Does Ververica Connect to My Systems
100+ pre-built connectors for message queues, databases, data lakes, cloud services, and REST APIs. Write integrations in Flink SQL or DataStream API. Every connector works with the Ververica Platform and plugs into the Streamhouse Architecture.
## connectors categories
- Message Queues
- Databases (CDC)
- Relational Databases
- Data Lakes & Table Formats
- Data Warehouses
- Search & Analytics
- NoSQL
- Cloud Storage & Files
## Partner Ecosystem
EKS, Kinesis, Redshift, S3
AKS, Event Hubs, Synapse, ADLS
GKE, Pub/Sub, BigQuery, GCS
Managed Kafka and PostgreSQL
## Features
### Exactly-once E2E delivery
### Automatic schema evolution
### Independent connector parallelism
### Event-time watermark strategies
---
---
title: "Careers"
description: "Join the team that created Apache Flink. Engineering, product, sales, and marketing roles at Ververica. Munich HQ with remote-friendly culture."
lastUpdated: 2026-04-16T08:00:47.000Z
source_url:
html: "https://www.ververica.com/careers"
md: "https://www.ververica.com/careers.md"
---
# Join a World-Class Team
We are looking for the brightest people to work on fundamental problems that matter in practice. Take a look at our open positions and meet the team!
## Why work with us?
We enjoy working with people who share our values and love challenges. Take a look at some of the reason why joining Ververica should be your next decision.
### Growth Opportunities
Your ambition and contributions are valued here. Together, we grow and succeed.
### Flexibility
Let’s face it life happens. We get it. That’s why we offer flexible working hours to help you balance your personal needs, along with health insurance and other essential benefits.
### Customize Your Tech
Choose the gear that helps you work best. Let us know your preferences, and we’ll provide the tech that keeps you comfortable and productive.
### Relocation Assistance
Don’t worry we support your relocation, if needed, and take care of any necessary paperwork to make the process smooth.
### Great Team
Success is most rewarding when we achieve it together. We collaborate, share ideas, and celebrate every win as one team.
## Hiring Process
1. **Submit your CV**
2. **Skills Assessment**
3. **HR/ Technical interview**
4. **Final Interview**
5. **Job offer**
## Current Openings
---
---
title: "Partners"
description: "Join the Ververica Partner Program. Reseller, technology, and consulting partnerships for stream processing and Apache Flink solutions."
lastUpdated: 2026-03-18T13:46:09.000Z
source_url:
html: "https://www.ververica.com/partners"
md: "https://www.ververica.com/partners.md"
---
_No content._
---
---
title: "X-Stream Lab"
description: "Hands-on workshops with the creators of Apache Flink. Build real-time applications in guided lab sessions. View upcoming lab days and register."
lastUpdated: 2026-06-09T12:58:47.000Z
source_url:
html: "https://www.ververica.com/events/x-stream-lab"
md: "https://www.ververica.com/events/x-stream-lab.md"
---
# X-Stream Lab. Hands-On Stream Processing Workshops
Write code. Deploy applications. Break things and fix them. Guided by the engineers who run Apache Flink daily.
## What Are X-Stream Labs
Full-day workshops. Small groups. Ververica engineers at the whiteboard and in the code alongside you.
Every lab day is structured around a production-grade project. You build a working application from ingestion to output. Your hands on the keyboard, deploying to a live Ververica Platform environment.
Groups are capped at 30 participants. Questions get answered. Problems get debugged. Nobody falls behind.
## X-Stream Lab Topics
### Hands-On Expertise
Build a streaming application from the ground up following a real use case.
### Real-Time Concepts
Get a practical introduction to key concepts in stream processing and real-time data.
### Network with Peers
Connect with other data professionals, share insights, and build valuable relationships.
### Real Life Adoption
Work through a complete scenario that reflects a real-world stream processing use case from ingestion to output.
---
---
title: "Webinars"
description: "Live and on-demand webinars on Apache Flink and stream processing. Technical deep-dives, product demos, and industry use cases from Ververica experts."
lastUpdated: 2026-05-27T06:59:20.000Z
source_url:
html: "https://www.ververica.com/events/webinars"
md: "https://www.ververica.com/events/webinars.md"
---
# Stream Processing Webinars
Technical depth. No filler. Live sessions and on-demand recordings from Ververica engineers and production practitioners.
## Watch. Learn. Build.
Past webinars
Dual Pipelines Are Done | Ververica's Streamhouse & Materialized Tables
Streaming at Scale: Unity’s Flink & Paimon Data Platform
Whole Lotta Stream: The Streamhouse Architecture at Fresha
Evolution of Yelp's Data Infrastructure to Streamhouse
Data Lineage in Data Streaming
Driving Energy Transformation with Real Time Data
Webinar: Fluss 0.7 - A New Stream of Possibilities
---
---
title: "Humn.ai Case Study"
description: "Discover how Humn.ai leveraged Ververica Platform and Apache Flink to enhance real-time risk assessment and dynamic pricing for commercial fleet insurance."
lastUpdated: 2026-07-15T05:38:20.000Z
source_url:
html: "https://www.ververica.com/case-study/humn-ai"
md: "https://www.ververica.com/case-study/humn-ai.md"
---
# Humn.ai
Machine Learning-based models to quantify commercial fleet exposure at individual insured asset risk in real-time.
Humn.ai uses Ververica Platform and Apache Flink to build a Machine Learning-based platform producing dynamic risk assessment models and real-time pricing for tomorrow’s insurance industry.
Humn.ai deployed Ververica Platform with Apache Flink to harden production Flink jobs seamlessly and quickly.
They developed a Machine Learning-based platform that is Kubernetes-native and implements ML-based algorithms for calculating the risk of vehicles in real-time. The risk scores for each insured asset is calculated dynamically and then updates a premium variable part of the insurance policy in real-time.
This case study includes:
The challenges Humn.ai faced with their previous technology stack and how Apache Flink helped in resolving them
The results achieved by deploying Ververica Platform and Apache Flink to production
A detailed overview of Humn.ai's experience using Ververica Platform
"When we migrated to Kubernetes with Ververica Platform it was much easier for our developers to define and configure jobs, as well as manage and monitor them in an integrated and efficient manner."
Alberto Romero, Co-founder and CTO, Humn.ai
---
---
title: "Real-Time Isn't A Feature You Bolt On. It's The Whole Solution"
description: "Real-time fraud detection isn't a feature; it's the solution. See how Ververica, Apache Flink, and Noventiq help banks stop fraud instantly on AWS."
lastUpdated: 2026-07-22T06:59:28.000Z
source_url:
html: "https://www.ververica.com/blog/real-time-isnt-a-feature-you-bolt-on-its-the-whole-solution"
md: "https://www.ververica.com/blog/real-time-isnt-a-feature-you-bolt-on-its-the-whole-solution.md"
---
There's a special kind of pain in knowing exactly what went wrong, just slightly too late to do anything about it. I see it every day as the Head of Strategic Alliances at Ververica, and it's often not even a technology problem. The technology exists. It's the gap between what enterprises know they need and what actually ends up being built that’s the issue.
My colleagues at [Noventiq](https://noventiq.com/) wrote about such a problem in their recent blog: “[Real-Time Fraud Detection and Streaming Intelligence for Financial Services on AWS](https://blog.aws.noventiq.eu/real-time-fraud-detection-and-streaming-intelligence-for-financial-services-on-aws)”, and they nailed it. Consider the impact: card fraud losses hit $33.83 billion in 2023. Projections for the next decade run to ~$404 billion. Batch processing catches all of it, eventually, which is a bit like your bank ringing to say your card's been cloned and then adding "anyway, hope you enjoyed Sydney."
So the case for real-time makes itself. Everyone wants it. Everyone nods along in the meeting. Someone says "customer-centric," someone else writes it down, and then it dies in a steering committee like everything else that ever showed promise.
The interesting bit is what actually makes real-time work once it leaves the slide deck. Because that's where most streaming projects quietly die. No funeral, no lessons learned, just a Confluence page nobody opens again.
Reacting to one event as it lands is easy. Any queue does it. The hard part, the bit worth actual money, is holding state across millions of events and still making the **right call in milliseconds**.
Take fraud. One transaction on its own tells you nothing. It's the financial equivalent of judging someone by their dating profile, which, while technically is data and information, can also be mostly lies. What matters is the correlation of this transaction against the last fifty from that account, the device it came from, the pattern over the last ten minutes, and whether any of it looks normal for that customer. Some people genuinely do drop two grand on gym gear in January. That's not fraud. It's optimism, and it'll be refunded by March.
That's stateful stream processing, and it's genuinely hard at scale. Your state has to stay consistent. It has to survive a failure without dropping events or, worse, counting them twice, because "we charged you once, possibly" is not a phrase that ends well for anyone. And it has to stay fast exactly when volumes spike, which is precisely the moment your system decides it's had enough and would like to speak to its manager.
This is the problem [Apache Flink®](https://www.ververica.com/apache-flink-vs-ververica) was built to solve, and it's why Ververica exists. As the original creators of Flink, we know it best, and so if it breaks, that's on us. No supplier to blame, no throat but our own to clear. With Ververica, you get exactly-once processing. Event-time handling, so late data doesn't wander in an hour later and quietly torch your results. A [supercharged engine](https://www.ververica.com/product/vera) that handles state that scales into terabytes and stays queryable in real time, while maintaining 100% compatibility with open source Flink. All so when a bank stops a fraudulent payment before it clears, that's this stuff doing the work behind the scenes and getting exactly none of the credit. (Story of my life.)
## Where Aws And Noventiq Come In
Flink is an engine, and a very good one at that. But an engine on its own just sits there being expensive and slightly smug. It needs somewhere to run, and someone who can get it into a regulated bank without setting off every alarm, sprinkler and compliance officer in the building. It needs to be part of a solution.
**That's the partnership.**
AWS brings the platform around it. MSK and Kinesis pull in events from core banking, payments and digital channels. SageMaker serves the risk models. Bedrock writes the investigative summaries and compliance narratives, a job so soul-destroying that handing it to a machine is arguably the most ethical thing on this list. S3, Redshift and Glue hold the reporting layer the regulators want to see. Ververica sits in the middle doing the stateful processing, the event detection, the enrichment and the windowed analytics.
Noventiq is the reason it actually ships. They’ve been an [AWS Premier Partner](https://aws.amazon.com/partners/programs/) since 2013, with 250-plus certifications, and real scars from doing governance and compliance work that would make most people quietly change careers. Handing a Tier-1 bank a streaming engine is one thing. Getting it through their security review, their data sovereignty rules and their change process is another sport entirely. That process moves at the speed of continental drift and has roughly the same sense of humour. Noventiq knows how to work with it without losing the will to live.
The numbers back it up. Sub-second fraud decisions at the 95th percentile. [Mainframe MIPS](https://www.ververica.com/banking/mainframe-offloading) costs down 80 to 90 percent when batch jobs move to streaming, the kind of saving that makes a CFO go misty-eyed and start using your first name. Reliability north of 99.5 percent.
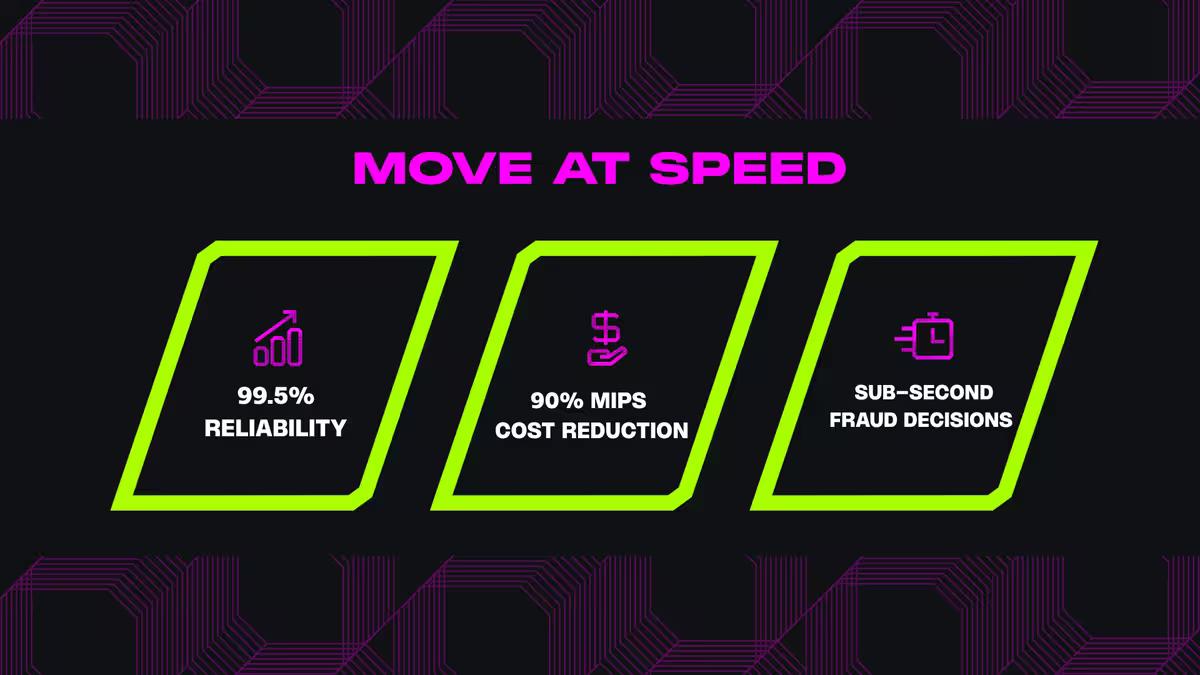
## Fraud Is The Start, Not The Finish
And once the streaming layer's in, it keeps paying you back, which puts it ahead of most things in banking.
The rolling behavioural profiles that catch fraud are the same ones that power [Customer 360, personalization](https://www.ververica.com/banking/customer-personalization) and churn prediction. The continuous processing that feeds your compliance reports is the same processing that lets you retire those ruinously expensive mainframe batch jobs and the small priesthood employed to keep them alive. You build the hard part once, then reuse it everywhere. Best return in the building, and it doesn't even take a bonus.
And you don't have to bet the farm on day one, mostly because someone in risk would have a stroke. Run it yourself on your own AWS setup with [Ververica Platform self-managed option](https://www.ververica.com/product/deployment/self-managed), both hands on the wheel. Or use Ververica Platform in the [Bring Your Own Cloud](https://www.ververica.com/product/deployment/byoc) deployment, where your sensitive data never leaves your environment but we still run the control plane. We meet you where you are, no judgement, even if where you are is "held together by a batch job written by a man who retired in 2011."
## Let's Talk
If you're fighting fraud, drowning in compliance, or watching a mainframe bill climb every quarter like it's got something to prove, I'd like to hear about it. We start with a use-case workshop, pin down one real scenario, prove it in a pilot with KPIs you can actually measure, then scale from there.
Find me on [LinkedIn](https://www.linkedin.com/in/chorsnell/) or [reach out to the team](https://www.ververica.com/contact). The joint solution is also on the [AWS Marketplace](https://aws.amazon.com/marketplace/pp/prodview-omseyib3eraya).
Batch tells you what you lost. Streaming lets you stop it. That's the whole point.
## More Resources
- [Built for This. Ververica in Action.](https://www.youtube.com/playlist?list=PLaDktj9CFcS-wjSiLbEALJSOs5wXbc2fb) Real features. Real use cases. Real demos. Every video in this playlist shows Ververica Platform doing exactly what it's built to do, demonstrated in precisely the way real users actually use it.
- Running fraud detection on batch jobs and wondering what you're missing?
- Read this:[https://www.ververica.com/blog/real-t…](https://www.youtube.com/redirect?event=video_description&redir_token=QUFFLUhqbV9LZWVvMllvOFVsbUdwOEtzN01HTkJZdUc4UXxBQ3Jtc0ttQUpjRXY0UWI3OTlYLTFDT0RfOVR3VFdnYTNKNjRheUJvbWlRaWIwUURLWDRycjV2bDl3b2tzQjM0Q1JoQTNhU3NGVDdkdm1BMlFBRWZMaF9WWWRoWXk2bVRYV2VTV2ZxQ1paUGM5M1pMWXFvbDhmMA&q=https%3A%2F%2Fwww.ververica.com%2Fblog%2Freal-time-fraud-detection-using-complex-event-processing&v=GZLbbJNCY-c)
- Evaluating stream processing for financial services?
- Start here: [https://www.ververica.com/banking/fra...](https://www.youtube.com/redirect?event=video_description&redir_token=QUFFLUhqa0luM0VUVnYtQWViRXNsNXd3aXBEN2oxVDA4Z3xBQ3Jtc0trakZISGFMYXpEQ0Z3ejZwMVBrVjZpRVN0dm8wc3Z1LS1SajZwU2VqRjc0WXZCMVFOM0JCNGJDd2NQQjZiNnRKUC1FN240bHJHYUhRY0s5Sk5ubTFDVjBDOGtIX3ktWThzYXNZSnNJMGZoMVg2djNxQQ&q=https%3A%2F%2Fwww.ververica.com%2Fbanking%2Ffraud-detection&v=GZLbbJNCY-c)
- [Global Bank Achieves 90% Cost Savings with Mainframe Offloading!](https://www.ververica.com/blog/global-bank-achieves-90-cost-savings-with-mainframe-offloading)
- [Outrun Fraudsters with Agentic AI and Ververica](https://www.ververica.com/blog/outrun-fraudsters-with-agentic-ai-and-ververica)
Contact us [https://www.ververica.com/contact](https://www.ververica.com/contact)
---
---
title: "Announcing The Private Preview Program For Apache Fluss™ On Ververica Platform"
description: "Announcing the Private Preview for Apache Fluss on Ververica Platform. A streaming storage layer unifying batch and streaming for real-time analytics & AI."
lastUpdated: 2026-07-15T09:06:02.000Z
source_url:
html: "https://www.ververica.com/blog/announcing-the-private-preview-program-for-apache-fluss-on-ververica-platform"
md: "https://www.ververica.com/blog/announcing-the-private-preview-program-for-apache-fluss-on-ververica-platform.md"
---
> The Lakehouse Was Built For Yesterday. Fluss Is Built For Tomorrow.
For a decade, streaming compute has moved faster than streaming storage. Apache Flink® unifies batch and streaming at the compute layer, and most teams settle the storage question by gluing systems together. It works but it means the same data lives in three or four places, and both the bill and the complexity grow underneath.
That old pattern has run its course. Today we are announcing a Private Preview for [Apache Fluss on Ververica Platform](https://www.ververica.com/product/fluss), working with a small group of customers to build the missing piece that will take business-critical and [AI use cases](https://www.ververica.com/product/real-time-ai) to the next level.
## What Fluss Does And How It Completes The Streamhouse™ Vision
Fluss is a streaming storage layer for real-time analytics. The idea is straightforward: a single layer that unifies streaming and batch, serving real-time and historical data in a single, fully-queryable copy of data.
Fluss makes the live stream itself queryable, like a table. You write an event once, and that single copy serves your applications, analytics, and AI models at the same time, fresh within a second. Recent data stays fast in Fluss. Older data tiers automatically to low-cost lakehouse storage, and a single query reads across both using [union reads](https://fluss.apache.org/docs/streaming-lakehouse/overview/#:~:text=Union%20Reads%3A%20Compute%20engines%20that%20perform%20queries%20on%20the%20table%20will%20read%20the%20union%20of%20the%20real%2Dtime%20streaming%20data%20and%20Lakehouse%20data.%20Currently%2C%20only%20Flink%20supports%20union%20reads%2C%20but%20more%20engines%20are%20on%20the%20roadmap.). No duplicate pipelines to reconcile. No replay tax. No gap between what happened and what you know.
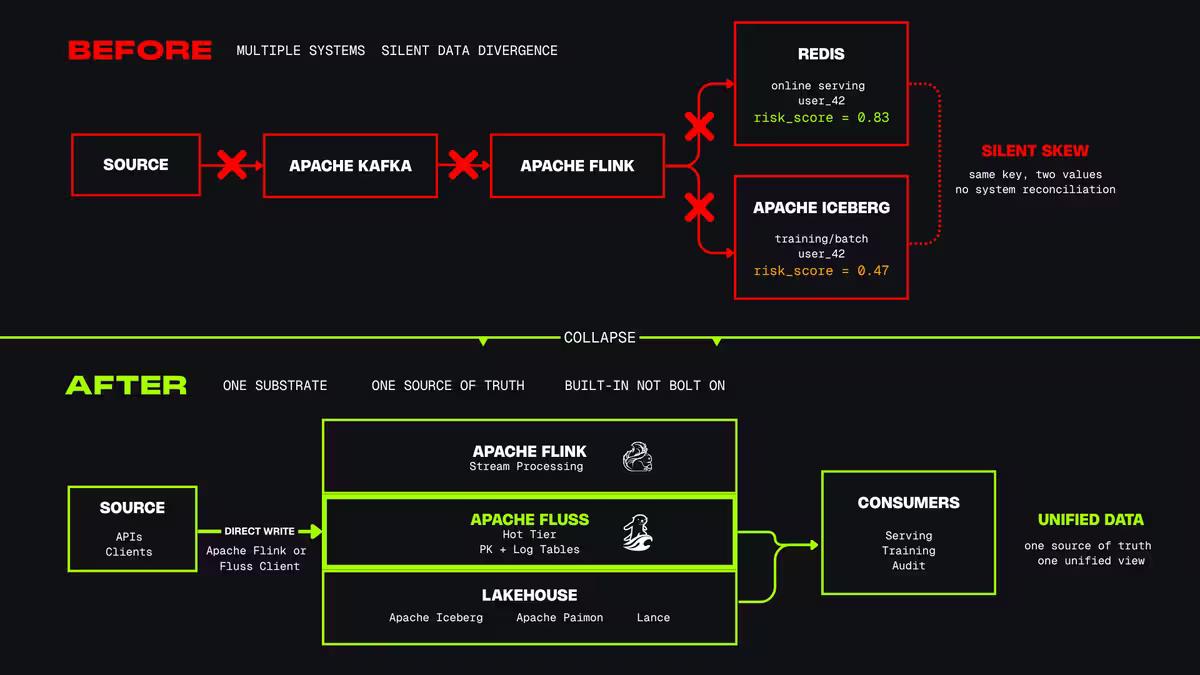
Fluss is the storage foundation of the [Streamhouse™](https://www.ververica.com/streamhouse), our architecture where one copy of data serves every workload. Streamhouse is Ververica's architecture for bridging the lakehouse and streaming worlds, so real-time and historical data stop living as separate systems. We have written before about [why batch lakehouses fall short](https://www.ververica.com/blog/stop-recomputing-everything-the-case-for-streaming-lakehouses) and how Streamhouse closes that gap.
It is built around a single guiding principle: **one copy of data, serving every workload. **These workloads include streaming ingestion, low-latency operational analytics, batch processing, machine learning features, and AI context; all without incurring a **multiple systems tax** that conventional architectures accumulate. Streamhouse combines an open-source streaming storage layer (**Apache Fluss**), an open lakehouse tier (like Apache **Paimon™** or Apache **Iceberg®**), a unified batch-and-stream processing engine (**VERA**, 100% compatible with Apache Flink**®**), declarative data pipelines (**Materialized Tables**), a freshness-aware workflow scheduler, and an autoscaling service (**Autopilot**) into a single operational substrate. We covered the architecture in full when we [brought Fluss to Ververica Platform](https://www.ververica.com/blog/introducing-apache-fluss-on-ververicas-unified-streaming-data-platform), and the Private Preview is how we turn it into a production-grade product.
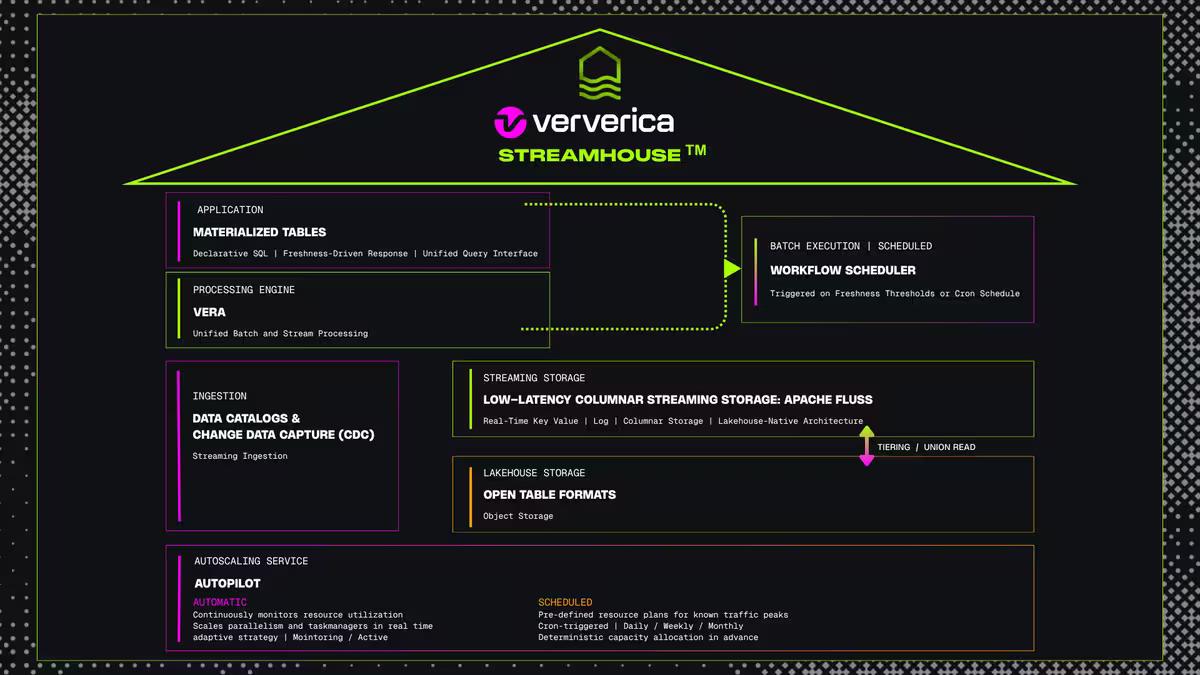
## Why It Matters
The most immediate use case Fluss solves are the high-performance workloads enterprises already run. Fraud scoring, recommendation engines, live pricing, and real-time risk can run off one governed table instead of a stack of reconciled systems. Stateful jobs stop dragging terabytes through every checkpoint. Batch and streaming pipelines collapse into a single definition, so the two stop disagreeing and nobody spends the morning working out which number to report to the regulator.
But where we think Fluss will have the biggest impact is in AI use cases. AI silently degrades when training data and serving data live in separate systems and drift apart. Experts call this [training-serving skew](https://developers.google.com/machine-learning/guides/rules-of-ml#training-serving_skew). Fluss addresses this by providing a unified source for both real-time signals and historical context. Computing features once and serving them for both offline training and online inference from the same table, agents read current, authoritative context instead of stale snapshots, so they reason against what is true _now, _not yesterday’s news. We foresee this being especially impactful in banking, healthcare, manufacturing and insurance.
Real-time AI does not work without real-time storage that is governed, fresh, and reproducible. That is the building block Fluss provides, and why Ververica is placing it as the center of what comes next.
## The Fluss Private Preview
The Fluss Private Preview is a framework to build a market-ready product hand-in-hand with users tackling today’s real-world problems. We are bringing managed Apache Fluss to Ververica's Unified Streaming Data Platform, and we are shaping what it becomes with the people who run it. Ververica offers enterprise robustness and world-class Fluss know-how, working directly with each program participant so their real needs decide how the GA product is built.
We are running it with a small, hand-selected group of companies whose workloads sit where Fluss makes the biggest difference. Several enterprises approached Ververica early on, describing the exact problems Fluss solves, and reinforcing that Ververica is reading the market needs correctly. These same enterprises will gain an early mover advantage as part of the Fluss Private Preview, directly influencing what ships at GA.
Streaming compute had its breakthrough years ago. Storage just caught up to it. A handful of companies are building with us what comes next, and in the near future it will be available for all.
While the world buffers, we act.
[**Become part of the production proof: register for the private preview.**](https://www.ververica.com/product/fluss/private-preview#register)
## More Resources
- [https://www.ververica.com/blog/introducing-the-era-of-zero-state-streaming-joins](https://www.ververica.com/blog/introducing-the-era-of-zero-state-streaming-joins)
- [https://www.ververica.com/blog/from-kappa-architecture-to-streamhouse-making-lakehouses-real-time](https://www.ververica.com/blog/from-kappa-architecture-to-streamhouse-making-lakehouses-real-time)
- [https://open.substack.com/pub/ipolyzos/p/from-events-to-real-time-profiles](https://open.substack.com/pub/ipolyzos/p/from-events-to-real-time-profiles?r=anqog&utm_campaign=post-expanded-share&utm_medium=web)
- [https://fluss.apache.org/blog/taobao-instant-commerce-real-time-decision](https://fluss.apache.org/blog/taobao-instant-commerce-real-time-decision/)
- [https://fluss.apache.org/blog/fluss-for-ai](https://fluss.apache.org/blog/fluss-for-ai/)
- [https://fluss.apache.org/blog/column-pruning-streaming-storage](https://fluss.apache.org/blog/column-pruning-streaming-storage/)
- [https://www.lancedb.com/blog/fluss-integration](https://www.lancedb.com/blog/fluss-integration)
- [https://www.youtube.com/watch?v=3c5RgJFTsMM](https://www.youtube.com/watch?v=3c5RgJFTsMM)
- [https://www.youtube.com/watch?v=pnrW5r-4mIQ](https://www.youtube.com/watch?v=pnrW5r-4mIQ)
---
---
title: "SQL now stands for Streaming Query Language"
description: "SQL has evolved beyond static data analysis. It’s now the \"Streaming Query Language,\" providing a declarative, efficient, and user-friendly way to perform continuous computation on unbounded data."
lastUpdated: 2026-07-15T12:51:18.000Z
source_url:
html: "https://www.ververica.com/blog/sql-now-stands-for-streaming-query-language"
md: "https://www.ververica.com/blog/sql-now-stands-for-streaming-query-language.md"
---
For four decades, SQL was the language for data at rest. Tables sat still. Queries swept across them. Results came back. Driver connection closed. Done. Great to analyze what happened yesterday. Not so good to tell what is happening right now.
That era is over. Digital businesses need fresh data to trigger decisions and improve customer experience now. No more day -1 refresh; milliseconds matter in a fast-paced economy.
The most consequential shift in data engineering over the past few years is not a new framework, not a new format, not a new vendor. It is a redefinition of three letters everyone thought they understood. SQL is no longer just _Structured Query Language_. SQL is the **Streaming Query Language**: the most friendly way to express continuous computation over unbounded data.
DataStream APIs in Java remain for use cases that require managing streaming building blocks such as time, state, and a DLQ. But they are no longer the only option available. For other use cases, a language-based approach would be faster to write, easier to use, and more elegant. The exact intentions around SQL were built for that. The question is how much you can build on it. Ververica was built to answer this question.
## Declarative Is The Unlock
SQL on streams enforces the same contract it has always used on tables: a declarative one. You declare **what** the result is. The engine executes the **how**: incrementally, with continuous correctness, as new events arrive. No delay, no buffer.
- A column projection: _SELECT customer_score FROM survey_
- A windowed aggregation: _TUMBLE(TABLE stream, DESCRIPTOR(time), INTERVAL '10' SECOND)_
- A stream-to-table enrichment: _JOIN ... FOR SYSTEM_TIME AS OF ..._
- Deduplication, top-N per key, and pattern matching: CEP with _MATCH_RECOGNIZE_ helps build complex data logic.
The intent of the pipeline becomes its source code. Watermarks, state lifecycles, operator chaining, checkpoint coordination: the runtime owns all of it. Developers can operate and build on data, semantics, and business jargon.
## Agility, By Default
SQL pipelines are short, but no less powerful and scalable. A non-trivial enrichment-and-aggregation job can be coded in a few lines. Short codes are fast to write, review, understand, and change.
Developers use a declarative language to deliver on daily requests:
- A new dimension to track means adding a column to the _SELECT_ statement.
- One-minute granularity instead of hourly means changing the window definition.
- Late events arriving 15 minutes out instead of 5 means adjusting the watermark strategy with _WATERMARK ... INTERVAL '15' MINUTE_ in the table DDL.
The change is straightforward, human-readable. The time from prototyping to deployed pipelines collapses from sprints to hours. Declarative helps companies innovate easily and remain flexible in capturing business opportunities.
A new project follows a blueprint: connect to data sources, implement the business logic, and sink the output. This is a repeatable model that helps companies to standardize the way of working.
This is what "low-code" means in a serious engineering context. Not a drag-and-drop beautiful UI. SQL provides a high-level abstraction that reduces complexity and leaves you in full control of the semantics, without sacrificing the power of the core engine's capabilities.
## The Optimizer Carries The Weight
Flink SQL is not a thin parser on top of a weaker execution path. It runs through a real optimizer built on Apache Calcite, with rule and cost-based planning that applies pushdowns, pruning, and subquery rewriting, among other steps to improve performance. The optimizer sees the full query and plans across CPU, memory, network, and I/O.
That is why Flink SQL is not second-class next to Java-based DataStream jobs. SQL and Table API queries are optimized holistically, translated into a single program, and executed on the same Flink runtime. The difference is in the authoring model, not in execution power.
The conclusion is clean. Flink SQL sits on the same execution substrate as DataStream jobs, where it matters: a single optimized program, regular DataStream execution after translation, and an optimizer that sees the whole relational plan rather than only the operator a developer handwrote. SQL removes glue code while the engine keeps the force.
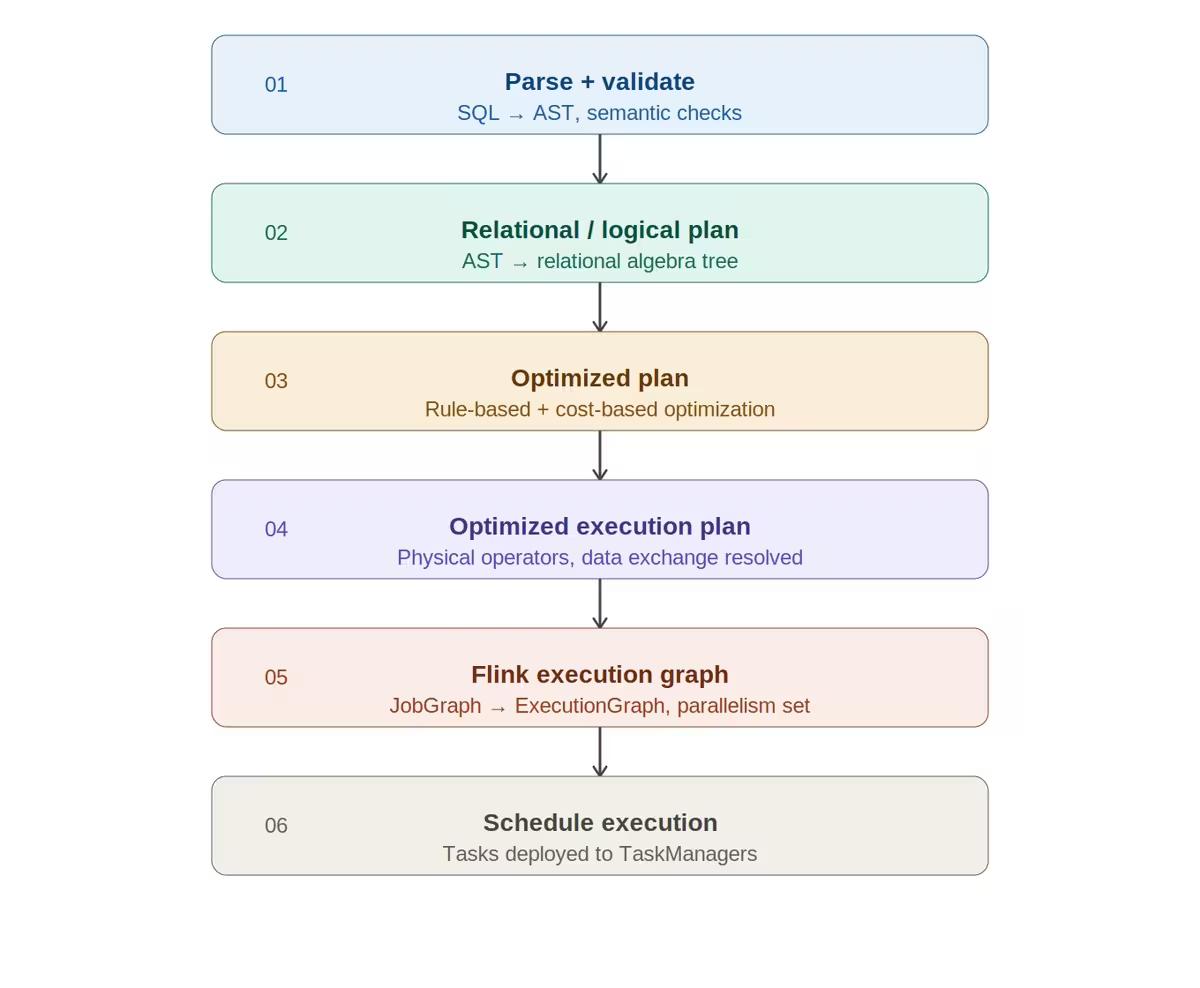
Flink SQL compiles to the same features that run the most demanding streaming workloads in the world. Every property the platform is known for is intact:
- **Exactly-once semantics** through distributed snapshotting and aligned checkpoints.
- **Stateful processing at scale** with scalable-backend state, incremental checkpoints, and configurable retention.
- **Resilience** through automatic recovery from the latest checkpoint after task or node failure.
- **Horizontal scalability and parallelism** through the same distributed processing architecture.
- **Event-time processing** in Flink SQL using DDL watermarks, late-event filtering, and source-idleness timeouts
## Catalogs and SQL, The Winning Combination
To improve data democratization, users and developers need to be self-sufficient when finding business information. Catalogs are the go-to place for building streaming applications, providing a navigation map to find organization-wide data assets, such as tables, views, and functions.
A topic registered as a table is discoverable, queryable, and governable. The same transaction table supports multiple use cases: real-time fraud scoring, nightly reconciliation, ad hoc analysis, and enriched push notifications. One schema means one source of truth.
Catalogs for streaming enable cross-data governance:
- **Reusability becomes structural.** Datasets defined once are consumed everywhere. The "rebuild the same join three times in three pipelines" anti-pattern dies.
- **Governance stops being a secondary priority.** Access controls, masking policies, and retention rules attach to catalog objects, not to individual jobs. Business logic lives in the source code; governance lives in the Catalog.
- **Lineage becomes transversal.** Every input and every output of every SQL job is a catalog-registered object. Lineage is a property of the system, not a documentation task afterward.
SQL on streams becomes architectural and foundational, while the catalog provides the entry point
> **TIP:** Want to go deeper?
Learn how to build, deploy, and manage production-grade Flink SQL pipelines with Ververica Platform in our free ebook.
[Download the Free Ebook →]
## Practical Flink SQL Patterns
Flink SQL directly covers common streaming patterns: connector DDL, metadata columns, watermarks, lookup enrichment, window aggregation, continuous analytics, and model inference.
### Connector configuration in SQL
```sql
CREATE TABLE Orders (
order_id STRING,
customer_id BIGINT,
total DECIMAL(12, 2),
proc_time AS PROCTIME(),
event_time TIMESTAMP_LTZ(3) METADATA FROM 'timestamp',
WATERMARK FOR event_time AS event_time - INTERVAL '5' SECOND
) WITH (
'connector' = 'kafka',
'topic' = 'orders',
'properties.bootstrap.servers' = 'broker:9092',
'format' = 'json'
);
```
Connector options live in DDL. Source definition, watermarking, and format selection stay in one place.
### Enrichment lookup joins
```sql
SELECT o.order_id, o.total, c.country, c.zip
FROM Orders AS o
JOIN Customers FOR SYSTEM_TIME AS OF o.proc_time AS c
ON o.customer_id = c.id;
```
That is enrichment without a separate enrichment service.
### Aggregation over event time
```sql
SELECT
window_start,
window_end,
customer_id,
SUM(total) AS revenue_5m
FROM TABLE(
TUMBLE(TABLE Orders, DESCRIPTOR(event_time), INTERVAL '5' MINUTES)
)
GROUP BY window_start, window_end, customer_id;
```
That is a streaming metric, updated in real-time, not a nightly job.
### ML inference in SQL
```sql
/** MODEL DDL **/
CREATE MODEL fraud_model
INPUT (total DECIMAL(12, 2), revenue_1h DECIMAL(12, 2), txn_count_5m BIGINT)
OUTPUT (prediction STRING)
WITH (
'provider' = 'openai',
'task' = 'completions',
'system_prompt' = 'Predict whether the transaction is fraudulent based on total, revenue_1h, and txn_count_5m. Return only the prediction.'
);
/** REAL-TIME MODEL CALL **/
SELECT *
FROM ML_PREDICT(
TABLE FeatureStream,
MODEL fraud_model,
DESCRIPTOR(total, revenue_1h, txn_count_5m)
);
```
An LLM service scoring inside the same query surface as the rest of the pipeline.
### CEP - Complex Event Processing
```
SELECT *
FROM Orders
MATCH_RECOGNIZE (
PARTITION BY customer_id
ORDER BY event_time
MEASURES
A.order_id AS first_order,
C.order_id AS third_order,
C.total - A.total AS escalation
PATTERN (A B C) WITHIN INTERVAL '10' MINUTES
DEFINE
B AS B.total > A.total,
C AS C.total > B.total
);
```
Detect three escalating orders from the same customer within 10 minutes in real time.
## Developer Experience with Ververica Platform
SQL unlocks a new paradigm that spans from application development to running jobs in production. Ververica Platform was built to deliver enterprise-grade readiness for running Apache Flink jobs in highly demanding organizations. On top of the open-source code, it provides a unique development environment for SQL, allowing developers to build fast and securely, and SREs to run and monitor Flink applications.
**Debug SQL against real data**
Build, then verify. Developers can validate the logic against live streaming data before hitting deployment. The SQL Editor, an IDE for real-time data, consumes actual events, watermarks, state, and outputs right in the editor. Everything is understandable and transparent, reaching total correctness, confirmed at the source
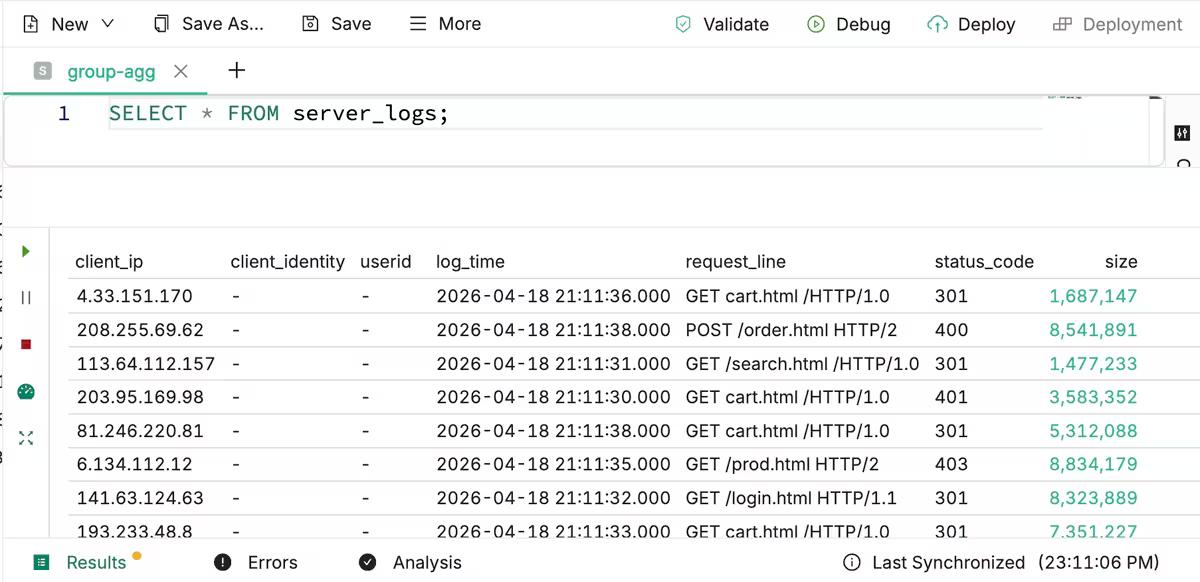
**Catalog-native development**
The built-in VVP Catalog ships with the platform. Packaged catalogs cover Apache Hive Metastore, JDBC, Schema Registry, Iceberg, and Fluss, among others. Ververica consumes metadata from the most common Catalogs and exposes it for testing and production environments. Every registered table is referenceable by name across catalogs and databases. Schemas, formats, and connection settings are resolved automatically, not in the application code, setting a clear separation between who manages the metadata and who manages the business logic.
**Code assistance built for streaming SQL**
The SQL Editor offers schema-aware auto-completion and surfaces errors inline. It suggests columns directly from the catalog and provides helpful hints for time attributes and watermarks where necessary. Furthermore, the editor is intelligent enough to distinguish between regular and temporal joins and to provide prompts accordingly. Code assistance improves speed and correctness for Flink jobs.
**Lineage**
Ververica provides an automated, transversal lineage feature that inherently captures the data flow of every SQL job, transforming lineage from a manual documentation task into a system property. Through an interactive lineage explorer, users can visualize data dependencies down to the column level, facilitating rigorous governance, compliance auditing, and rapid impact analysis. Visual graph elements, including connector information, modification timestamps, and author details, allow users to jump directly to specific catalog objects or deployments, thereby streamlining root cause analysis and troubleshooting.
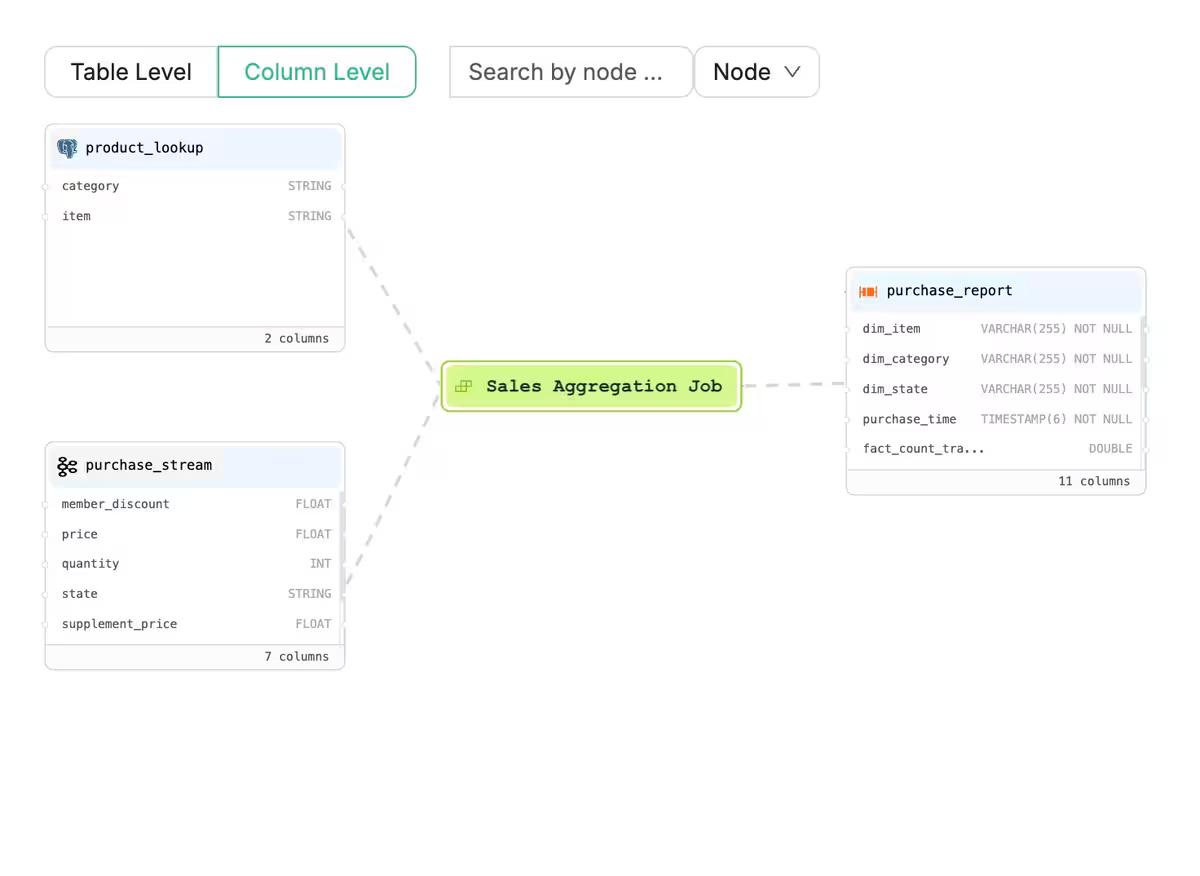
The point is not that SQL on Flink is possible on Ververica. SQL on Flink has been possible for years. Ververica makes it the path of least resistance: for the engineer writing the query, the team reviewing it, and the platform running it in production.
## When SQL Makes Sense
Flink SQL excels in declarative, standards-based stream and batch processing where logic is defined as continuous queries on dynamic tables. Primary applications include real-time aggregations, data enrichment through lookups or temporal joins, and ETL pipelines that utilize robust connectors for repositories such as Kafka, JDBC, Paimon, and standard file systems. Removing the requirement for Java or Python code effectively lowers the entry barrier for analysts and data engineers.
Workloads where Flink SQL is a good fit:
- **Streaming ETL and continuous transformations**: reading from Kafka, CDC sources, or file systems and writing to downstream sinks with declarative SQL logic (filters, projections, joins, aggregations).
- **Real-time aggregations and dashboards feeding**: windowed aggregations (tumble, hop, session, cumulate via Window TVF), GROUP BY with mini-batch optimization, and TopN computations.
- **Data enrichment via joins**: temporal joins against versioned dimension tables, lookup joins against external databases (JDBC, MongoDB, Redis), and interval joins between two streams.
- **Bounded batch jobs on a schedule**: periodic ETL, historical backfills, and reconciliation runs where the same SQL runs in BATCH mode on VVP 3 with the Workflow Scheduler.
- **Democratizing access to streaming**: enabling data engineers, analysts, and domain experts who know SQL but not Java/Python to build and operate streaming pipelines without a JVM development cycle.
- **Multi-system integration with catalogs**: leveraging Kafka Schema Registry, Paimon, Fluss, Hive, PostgreSQL, Oracle, or Iceberg catalogs for zero-DDL table discovery and cross-system pipelines.
- **Pattern detection with MATCH_RECOGNIZE**: CEP-style event pattern matching expressible in SQL (e.g., fraud sequences, session detection).
- **Rapid prototyping and iteration**: using the SQL Editor with session clusters for preview, validation, and quick feedback loops before promoting to production.
For workloads requiring complex custom state management, advanced event patterns beyond those covered by MATCH_RECOGNIZE, or fine-grained control over parallelism and resource isolation, the DataStream API remains the more appropriate choice.
## The Shift
Streaming spent most of its history as a specialist discipline. Toolchains were powerful, exclusive, and concentrated within small teams, becoming permanent bottlenecks between event producers and consumers and widening the gap.
SQL on streams, anchored to a shared catalog and metadata, dissolves the bottleneck. Pipelines become readable, reviewable, and evolvable artifacts. Flink remains a serious runtime as ever. Governance and lineage stop being a “nice-to-have” and become byproducts of the platform's wiring.
The three letters did not change. What they mean did.
SQL is now the Streaming Query Language for businesses running in low-latency mode.
## Ready to Build Production-Grade Flink SQL Pipelines?
This article covered the basics. Our free ebook walks through the complete journey from interactive SQL development to production deployments, including dynamic tables, watermarks, temporal joins, savepoints, autoscaling, and governance.
[**[Download the Ebook →]**](https://www.ververica.com/asset-library/low-code-streaming-pipelines-with-sql-e-book)
## Additional Resources
[Start your Flink SQL journey today.](https://www.ververica.academy/app/courses/0fa57e52-5b72-4005-a054-9aed278cbca4)
[Join our hands-on X-Stream Labs workshops](https://www.ververica.com/events/x-stream-lab)
[The Dataflow Model](https://research.google/pubs/the-dataflow-model-a-practical-approach-to-balancing-correctness-latency-and-cost-in-massive-scale-unbounded-out-of-order-data-processing/)
---
---
title: "Why Dashboards Keep Missing What Matters"
description: "Why do dashboards stay green during turbine failures? They rely on averages. Learn how streaming architectures enable real-time fault detection and prevent costly downtime."
lastUpdated: 2026-07-09T05:46:28.000Z
source_url:
html: "https://www.ververica.com/blog/the-turbine-was-fine-until-it-wasnt-why-dashboards-keep-missing-what-matters-author-peter-sari"
md: "https://www.ververica.com/blog/the-turbine-was-fine-until-it-wasnt-why-dashboards-keep-missing-what-matters-author-peter-sari.md"
---
More than a thousand sensors in a wind turbine. Drivetrain temperature. Blade pitch. The data is there. The decisions are not.
Operators watch dashboards built across three timescales. Supervisory Control and Data Acquisition ([SCADA](https://csrc.nist.gov/glossary/term/supervisory_control_and_data_acquisition)) telemetry rolls up to 10-minute averages. Vibration spectra arrive on hourly or daily reports. Asset performance gets reviewed weekly, monthly, or after a failure. Each layer is useful. None of them see what is about to happen.
The pattern is familiar. A turbine performs inside every threshold. The dashboard stays green. A bearing fails anyway. Multi-million dollar damage occurs before the first alert flashes.
Disruptions and faults are not anomalies. They are part of the operation. A cloud crosses a solar farm. A tree drops on a power line. A bearing enters distress. Assets fail every day, and operators handle them after the fact. Speed of detection separates a managed event from a catastrophe.
The interval between fault and response is where catastrophes live. [Ververica](https://www.ververica.com/) removes the interval. Sensor data, context, and inference run as one continuous stream, sub-second end to end. Detection happens at the speed the equipment changes, not the speed the dashboard refreshes. Informed decisions are made earlier and faster. Fixes move from emergency repairs to scheduled tasks. Outages averted. Ververica puts the operator more in control.
## The Limits Of Average
The default sampling rate for SCADA in commercial wind turbines is 10-minute averages of 1 Hz signals. **Operators work on information that reduces 600 samples to four metrics; mean, max, min and standard deviation.**
Limiting data points saves bandwidth and storage, but it hides almost everything that matters for early fault detection. A faulty bearing does not raise its average temperature for weeks. It produces brief, intermittent oscillations. The averaging erases them. The operator sees nothing. The fault is already forming.
A [2023 SAGE review by Pandit, Astolfi and colleagues](https://journals.sagepub.com/doi/10.1177/0309524X221124031) said it plainly. Abnormal vibration and anomalous electrical behavior are very hard to detect from data averaged over 10 minutes. The signal exists. The pipeline destroys it.
Operators compensate with parallel condition monitoring systems. Vibration spectra. Oil particle analysis. Acoustic emission. Parallel systems mean extra cost. Cost to cut, or not even invest in in the first place. Worse, they sit on separate infrastructure, separate dashboards, separate review cycles. Correlation happens manually, after the fact, by an engineer working on vibes.
The pattern is not unique to wind. The same problem hits every plant type. Grid operators report the same gap between SCADA polling cycles, which run at 1, 10, or 20 seconds, and phasor measurement units that sample at 10 to 20 Hz. The high-resolution signal sees voltage peaks and frequency excursions the slower system averages away.
## Rules Catch What You Already Know
Threshold-based alarms are the operator's standard tool. Gearbox oil temperature above the manufacturer’s limit. Generator winding above the insulation class rating. Vibration RMS above the alarm setpoint. Each rule encodes a known failure mode.
The problem is everything else.
A misaligned main bearing transfers thrust load to the gearbox. Internal clearances grow. Planetary alignment drifts. None of these states cross a threshold. They emerge from a relationship between variables: rotor speed, temperature gradients, subtle shifts in power curve residuals.
A [study of this topic](https://www.sciencedirect.com/science/article/abs/pii/S1474034624003240) found that fixed-threshold methods produce both missed detections and false positives. The operating envelope of a turbine is not a box. It is a moving surface. It changes with wind, season, age, and load history.
Rules are expensive to maintain. Every new turbine model brings new thresholds. Every site has its own quirks. Every false alarm erodes operator trust in the system that raised it.
## What Machine Learning Actually Does
The shift from rules to learned models does not replace engineering judgment. It recognizes patterns an engineer cannot enumerate.
A model trained on healthy operating data learns the relationship between hundreds of variables across the operating envelope. When the turbine deviates, the model flags it, even when no single variable crosses a threshold.
The published results are concrete. Regression models for generator bearing temperature, built on power output, nacelle temperature, and shaft speed, flagged catastrophic bearing failures 25 days early. LSTM autoencoders on vibration data reported outlier detection around 97% on real wind farm data. Other studies forecast remaining useful life weeks out, accurate to within hours.
These approaches share a requirement traditional architectures cannot meet. They need data at the resolution where the signal lives. Joined across components. Joined with weather and operating context. Processed continuously, not in nightly batches. This is where data streaming changes the equation.
Rules and learned models are not alternatives. The mature architecture runs both, on the same stream. [Complex event processing (CEP)](https://nightlies.apache.org/flink/flink-docs-stable/docs/libs/cep/) catches multi-step patterns operators already know. Two consecutive overtemperature readings inside a window. Two turbines on one site crossing a wind threshold within a minute. Learned models catch the rest. Each surfaces what the other misses.
This is the architecture Ververica was built for. One engine. One stream. CEP patterns and trained models running side by side against the same sensor data, with the same event-time semantics, the same state, the same delivery guarantees. Rules and models stop being separate systems.
## You Already Have A Streaming Stack
Fair assumption. Spark Structured Streaming runs micro-batch jobs. A feature store holds the model inputs. Three mature tools, already in the building.
That stack does not do what multi-million dollar industrial equipment requires.
A trigger interval of a few seconds to minutes is blindness by design, repeated forever. The bearing does not wait for the next batch boundary. Event-time correlation across sensor, weather, and maintenance streams is exactly the join Spark does poorly, and Kafka does not do at all. The feature store splits your logic in two. One code path computes features for training Another recomputes them at serving time. When they silently drift over time, your model misses a fault and nobody notices.
Flink was built for this shape of problem. True one-event-at-a-time processing. Native event-time semantics with watermarks: a late sensor reading lands in the right window instead of the wrong one. Managed keyed state per asset, held in the engine, not in a database you query on every event. One feature definition, computed once, used for the backtest and the live score. CEP rules and the learned models run in the same job, against the same stream, with the same delivery guarantees.
## The Architecture Problem
A typical wind farm monitoring stack looks like this:
- SCADA writes to a historian.
- Vibration data lands in a separate condition monitoring database.
- Weather data comes from a third source.
- Maintenance logs sit in an asset management system.
- Reporting happens in a BI tool that pulls from all of them on a schedule.
A model that needs to correlate signals across these systems in real time cannot. This architecture is the failure. The data exists. It does not arrive together. It does not arrive fresh.
Streaming changes the topology. Sensor data, weather feeds, control system events, and maintenance records flow into one continuous pipeline. Models score each turbine continuously, against its current context, against the rest of the fleet. Anomalies surface within seconds, not days. Engineers receive ranked alerts with the contributing signals attached, not a wall of green punctuated by an unexplained red.
The same architecture supports the historical work. Models train on years of data. Backtests run against the full event history. The lakehouse holds what happened. The stream holds what is happening. Both share one definition of the data.
One pipeline ingests sensor events. Multiple detectors run on the same stream in parallel: a health scoring window keyed by asset, a power curve deviation tracker, a yaw alignment monitor, a grid frequency monitor keyed by site, and a CEP engine watching for known multi-event patterns. Outputs feed one dashboard, one alert feed, one control loop.
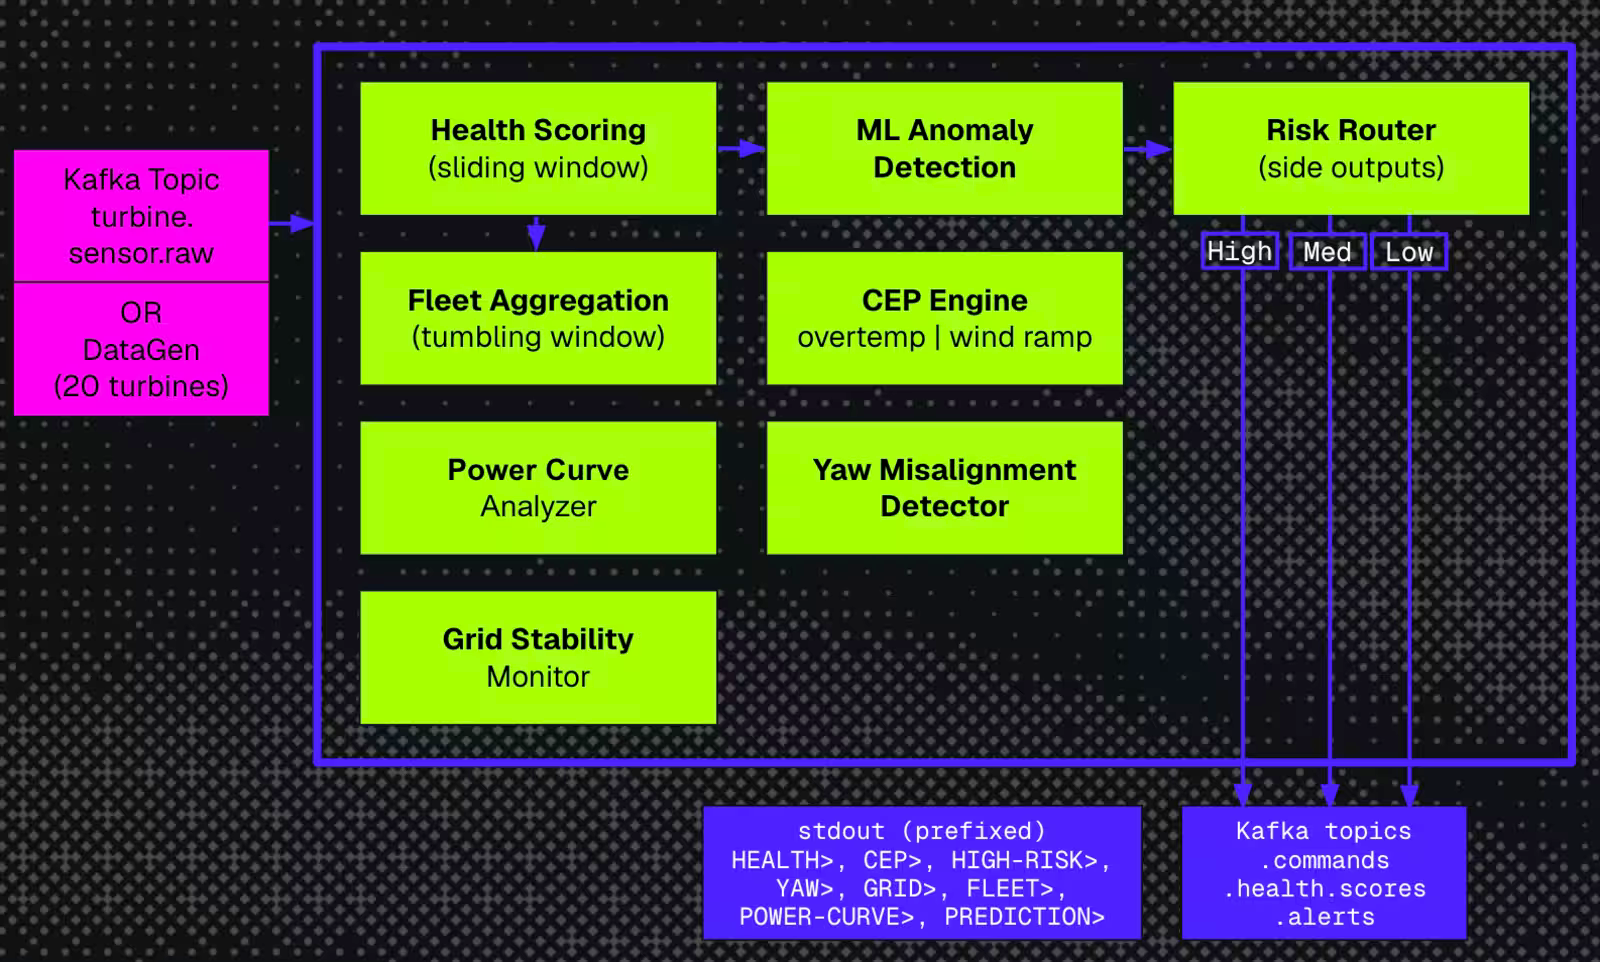
## The Number That Matters
Most write the argument as a cost question. A failure carries a measurable cost. State it as a consequence.
A single onshore gearbox failure costs $250,000 to $300,000 in repair. Gearbox failure rates run around 0.154 events per turbine per year. Annual main bearing failure rates are in the range of 3 to 6%. Crane mobilization adds $350,000 per week. Offshore vessels run $150,000 to $300,000 per day, with a month of mobilization typical. One case study reported $820,000 in lost revenue across three turbines over 28 months from main bearing failures alone.
A bearing run to failure transfers loads to the gearbox. The gearbox ingests the cost. A blade liberation event can damage the tower. Insurance responds.
Against those numbers, one avoided catastrophic failure pays for a streaming pipeline and a fleet of trained models.
The calculation is not niche. It applies wherever assets are expensive, downtime is expensive, and failure modes are too subtle for rules to pre-enumerate. Wind. Hydro. Power transmission. Petrochemicals. Heavy industry. Rail. Data centers. Same structure. Same cost. Same arithmetic.
## What To Build, Not What To Buy
For data and platform engineers, the practical question is what changes in the architecture.
Four things, in order.
**First, data resolution.** Move the high-frequency signals off the historian and into the stream. The 10-minute average is a reporting artifact, not a monitoring strategy. The model needs the underlying samples.
**Second, integration.** Sensor streams, weather feeds, control events, and maintenance history have to share one event time, one schema, one access pattern. Joins happen at the platform layer, not in the dashboard.
**Third, feedback.** The model surfaces a candidate fault. The technician confirms or rejects it. That label flows back to training. Without the loop, the model decays. With it, the model gets better than the engineer who built it.
**Fourth, action.** The mature system does not stop at alerting. High-confidence predictions trigger commands the control layer executes: reduce RPM, ramp down power, feather blades. Side outputs route by risk class. Medium-confidence events enter the maintenance queue. The loop closes without waiting for a human to read the dashboard.
None of this is exotic. It is what mature streaming architectures look like. The shift is treating the monitoring stack as one continuous system, not three disconnected ones.
## From Observation To Action
The wind industry accepts that retrospective analysis is not enough. Every operator has a bearing failure story. Every operator has a dashboard that stayed green through a costly failure.
The question is not whether to move to continuous, learned monitoring. The question is how fast the data arrives, how cleanly the signals join, and how quickly the model output reaches the engineer who can act.
This is the work [Ververica's Unified Streaming Data Platform](https://www.ververica.com/) exists to support. Built on Apache Flink® and powered by the [VERA](https://www.ververica.com/product/vera) engine, it processes sensor data, control events, and contextual feeds as one continuous stream. Sub-100 milliseconds inference. Full lineage from event to alert. Real-time and historical workloads in one engine. Grid operators already detect and act on faults inside 50 milliseconds. The wind farm case is the same problem at a slower timescale.
The dashboard told you the turbine was fine. The data told a different story. The architecture decides which one you hear first.
## More Resources
Read how the [VERA stream processing engine](https://www.ververica.com/product/vera) supports industrial monitoring that captures, analyzes, and acts on data in real time.
Don't wait for a catastrophic event. [Book a fully tailored demo](https://www.ververica.com/demo) now.
---
---
title: "The Sovereignty Tax. What Cloud-Only Vendors Won't Tell Tier 1 Banks"
description: "Cloud-only vendors often fall short for Tier 1 banks that require strict data sovereignty. Discover why Ververica’s on-prem streaming platform is the critical choice for regulated financial workloads.1"
lastUpdated: 2026-07-09T05:49:02.000Z
source_url:
html: "https://www.ververica.com/blog/the-sovereignty-tax-what-cloud-only-vendors-wont-tell-tier-1-banks"
md: "https://www.ververica.com/blog/the-sovereignty-tax-what-cloud-only-vendors-wont-tell-tier-1-banks.md"
---
Cloud-only vendors gave up on top financial services providers. Ververica doesn’t.
That is not a positioning statement. It is what actually happened. A European Global Systemically Important Bank (G-SIB) switched to Ververica after their previous streaming vendor dropped on-prem support entirely, leaving a systemically important institution without a sovereign deployment path mid-program. Their response, stated plainly during a business review: "It would be a big issue if we stop on-prem Ververica Platform."
That institution now runs corporate payments at 266 transactions per second against a 5-second service level agreement, and its on-prem accounting system processes over 100 billion euros in Single Euro Payments Area (SEPA) payment orders monthly, all utilizing an on-premise OpenShift with multi-datacenter disaster recovery. A major London hedge fund operates five Ververica Platform instances on bare-metal OpenShift, processing securities restrictions in real-time where failure to act means fines measured in millions. Another important clearing organization based in the United States is in its production build-out of a three-data-center, with approximately 5,000-CPU Ververica environment for real-time profit and loss and margin workflows.
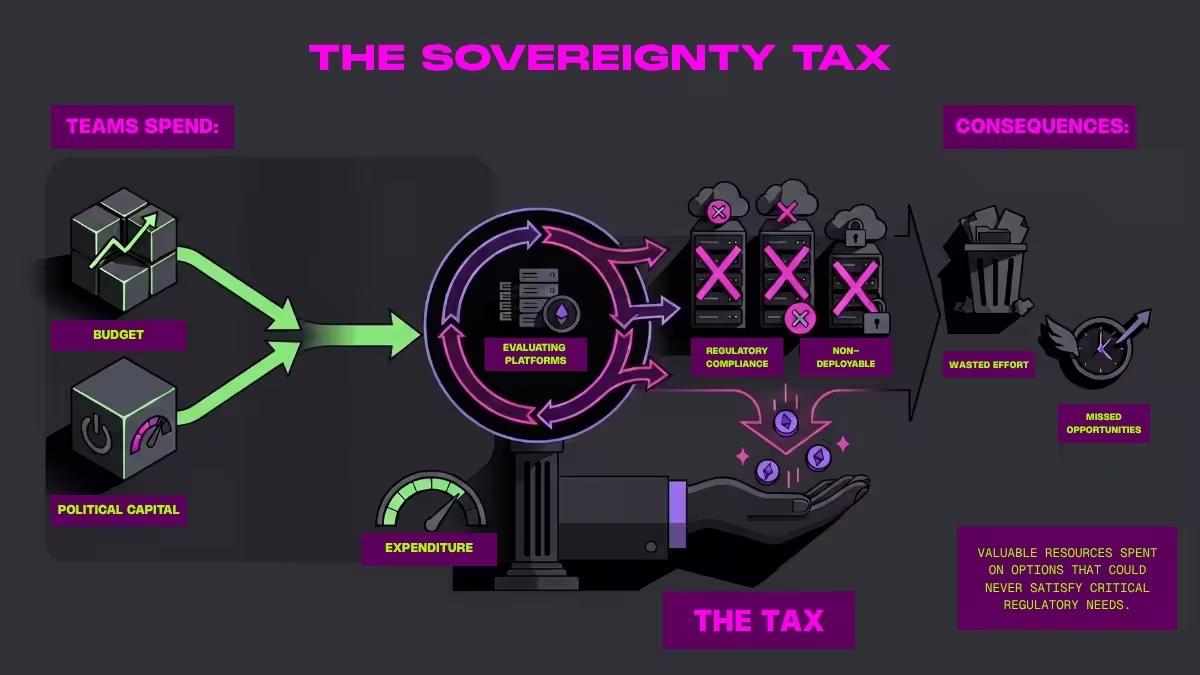
## Sovereignty Is Mandatory, Not Optional
For top tier banks, clearing houses, and major insurers, on-prem capability is not nostalgia. It is a compliance boundary shaped by converging regulatory pressure.
DORA Article 28 [(Regulation (EU) 2022/2554, applicable from January 2025)](https://eur-lex.europa.eu/eli/reg/2022/2554/oj/eng) requires financial entities to maintain contractual rights of audit and access over Information and Communication Technology (ICT) third-party providers, and mandates documented exit strategies for critical ICT services, a requirement that platforms built on proprietary APIs and data formats fail structurally. The [Network and Information Security Directive 2](https://nis2directive.eu/what-is-nis2/) (NIS2) increases management accountability for cybersecurity resilience. [GDPR](https://gdpr.eu/what-is-gdpr/) and related residency controls tighten obligations around where sensitive data is processed and accessed. The [Payment Card Industry Data Security Standard](https://www.pcisecuritystandards.org/) (PCI DSS) scopes cardholder data environments to specific infrastructure boundaries, creating direct dependencies on where payment workloads run and who can access that infrastructure.
There is an additional exposure vendor-managed platforms rarely surface: when a vendor operates your control plane, their support personnel typically retain operational access to production infrastructure that may cross jurisdictions. Under DORA's supervisory expectations and GDPR's cross-border transfer obligations (Chapter V), this is a structural compliance concern that must be examined explicitly, and not treated as an edge case.
On-prem at scale is hard. Most vendors chose not to solve it. That is a deliberate product decision, and it disqualifies them for a specific class of regulated workload. For the financial services industry, cloud-first is not a modernization strategy; it is a sovereignty-never decision.
## Why Evaluations Break Down
In the financial services and banking industry, the issue is usually not product quality. It is an operating-model fit.
AWS Managed Service for Apache Flink® is a fully-managed cloud service with no on-prem deployment path. Confluent Cloud (IBM) is cloud-only, with no meaningful on-prem Flink capability. Both are engineered for cloud-native operating models, but **structurally incompatible** with institutions that must own their control plane. Databricks, which is cloud-native by design with no true on-prem offering, is similarly optimized for vendor-managed infrastructure. For regulated workloads requiring institution-owned control planes, each creates a structural fit gap, not a temporary limitation, but an architectural consequence of how they were built.
How to screen data platform vendors for potential risk:
- If control plane ownership stays with the vendor, sovereignty risk rises.
- If private or isolated network patterns are constrained, security sign-off slows.
- If governance evidence depends on provider-controlled systems, audit burden shifts to exception handling.
This is the **sovereignty tax**: teams spend budget and political capital evaluating platforms that were never deployable for their regulatory profile and needs.
## Five Architecture Questions That Determine Fit
Architecture teams in highly-regulated industries like financial services should evaluate streaming platforms using five control questions:
1. **Deployment control**: Can it run fully on-prem with institution-owned control planes?
2. **Network posture**: Can critical workloads run without public internet exposure, including air-gapped patterns?
3. **Governance model**: Are Role-Based Access Control (RBAC), audit trails, lineage, and tenancy controls native and customer-operated?
4. **Security model**: Does it support [Zero Trust](https://csrc.nist.gov/pubs/sp/800/207/final) enforcement with enterprise identity and private connectivity that is demonstrable to a CISO without relying on vendor-controlled attestation?
5. **Operational resilience**: Can teams meet strict SLA boundaries with high availability, disaster recovery, predictable restart behavior, and enterprise support?
These are baseline controls, not advanced features.** A platform that cannot answer all five affirmatively is NOT a sovereign streaming platform.**
## What Deployment Reality Looks Like
Several top-tier enterprises in the financial industry utilize [Ververica Platform](https://www.ververica.com/) today. The enterprises behind these stories asked us not to use their name explicitly. That's common in industries where infrastructure decisions are sensitive. What we can share is still important: their relatable challenges, the approach, and the very real outcomes.
### European G-sib: On-prem, Multi-datacenter, At Scale
After a previous streaming vendor dropped on-prem support, this institution moved to Ververica. The environment runs on on-premise OpenShift with bare-metal workers and a secondary DR site. Corporate payments processes 266 transactions per second at peak against a 5-second SLA. DB2 mainframe replication covers 250 tables to Apache Kafka and MongoDB, a workload the team describes internally as “critical”. DORA compliance is managed entirely within their own infrastructure controls.
That same environment underpins the institution's accounting modernization system, which processes over 100 billion euros in SEPA payment orders monthly across 30+ banking systems, all within an infrastructure the institution itself controls. With this architecture in place, they solve a massive [customer 360 use case](https://www.ververica.com/banking/customer-personalization), achieving 3x throughput improvement over their prior architecture. (600 messages per second versus 200.) The end result: core operational infrastructure, running with complete sovereignty.
[Watch ](https://www.youtube.com/watch?v=4AjW0xy3ygE)Fulvio Pascotto, Data Architect Lead and Raffaele Saggino, Senior IT Infrastructure Architect from Intesa SanPaolo present: _Intesa Sanpaolo’s Journey to Cloud: Is Batch Processing Still Relevant?_ from the Flink Forward stage.
### Major London Hedge Fund: Bare-Metal On-Prem
This Financial Conduct Authority (FCA) regulated quantitative fund runs five separate Ververica Platform instances across bare-metal OpenShift, with 99.9% of production workloads on-prem and no cloud dependency. Their security model goes beyond standard RBAC: a custom Kerberos proxy sits in front of Ververica Platform to integrate with internal authentication infrastructure. The primary use case is real-time securities restrictions processing. When the system identifies a security the firm cannot trade, it must act **immediately**. Failure means fines measured in millions. Their most demanding workloads specifically use Ververica Platform, powered by the [VERA](https://www.ververica.com/product/vera) engine, precisely where the performance gains matter most.
For relevant information, at the Flink Forward Berlin 2024 conference, Marshall Wace software engineers Mohsin Niazi and Robin Stephenson presented on the firm's transition to real-time streaming architectures. Their session covered the company's journey of migrating their data infrastructure to leverage Apache Flink. [Watch the recording here. ](https://www.ververica.academy/courses/3d163483-5040-4d60-b5b3-755c3277edf7/activities/43766bf6-2cb6-40f1-8833-f1274d03d4da?__hstc=37051071.3f79c8a76d306c37b8e83048d6ba2e20.1782238713512.1782238713512.1782238713512.1&__hssc=37051071.1.1782238713512&__hsfp=4e99603902fd0375f842dcf71cb6c2ba&_gl=1*jjtwbx*_gcl_au*NzEwOTIyMDQzLjE3ODIyMzg3MTM.*_ga*MTk3Njc4OTUxMS4xNzgyMjM4NzEz*_ga_KYJX5Z3LS2*czE3ODIyMzg3MTIkbzEkZzAkdDE3ODIyMzg3MTIkajYwJGwwJGg0MTEzODA5OTc.)
### United States-based Systemically Important Clearing Organization: Production Build-out
A systemically important clearing organization in the United States is in production build-out of a three-data-center environment running approximately 5,000 CPUs for real-time P&L and margin workflows. The institution runs self-managed Kubernetes, and retains full ownership of the control plane, a mandatory requirement for infrastructure sovereignty at clearing-house scale, and one only Ververica offers.
## What Ververica Delivers
Ververica Platform is built for institutions that cannot compromise on control. It delivers the full capability of a production-grade streaming platform, including governance, deployment flexibility, operational depth, AI/ML support, and VERA-powered performance, entirely within institution-controlled infrastructure. No cloud dependency. No vendor access to the control plane. Just the capabilities regulated institutions need, deployed on their terms. The specifics:
- **Streaming-native governance**: RBAC, multi-tenant controls, audit logs retained for 180 days with direct streaming to SIEM via Kafka, enterprise SSO via SAML 2.0 and OIDC, and column-level data lineage across catalogs, tables, and jobs for SQL deployments. Enterprise tooling, including job management UI, CI/CD pipeline integration, and catalog connectors that operate entirely within institution-controlled infrastructure.
- **Deployment freedom**: Full on-prem and air-gapped patterns based on institutional risk policy, not vendor infrastructure constraints.
- **Zero Trust alignment**: Zero Trust requires continuous verification at every access point rather than trusting anything inside the network perimeter. That distinction matters when auditors ask whether the security posture holds inside the control plane, not just at the edge. Ververica integrates with enterprise identity, private networking, and policy enforcement models to support that verification.
- **Operational depth**: Kubernetes-oriented operations, full lifecycle controls, and 24/7 expert support. For institutions requiring hands-on deployment support, Ververica [Professional Services](https://www.ververica.com/product/professional-services) covers Security and Compliance Implementation, Platform High Availability and Disaster Recovery, Apache Flink® migration from legacy tools, Architecture Design, and embedded Resident Engineer engagements, all scoped for sovereign environments.
- **AI/ML on-prem**: On-premise deployment does not require sacrificing AI capabilities. Ververica supports real-time inference, streaming feature stores, and vector database integrations deployable entirely within institution-controlled infrastructure, enabling fraud detection AI models at scale without cloud dependency.
- **VERA performance**: The VERA engine runs up to 2x faster than open-source Flink while maintaining 100% API compatibility. On-prem deployments benefit from the optimized SQL engine with 50%+ faster processing, 30%+ lower resource consumption, and 90% faster job recovery.
## Where Financial Services Industry Leaders Go From Here
If you lead architecture, risk, or data engineering in Tier 1 or Tier 2 Financial or Banking Industry enterprise, evaluate control fit first and convenience features second.
Start with the [**Sovereignty Assessment Checklist**](https://www.ververica.com/data-sovereignty/streaming-sovereignty-checklist-for-financial-services-industry) to identify governance and deployment gaps in your current stack. Then use the [**Technical Guide to BYOC + On-Prem for FSI**](https://www.ververica.com/data-sovereignty/fsi-sovereignty-playbook) to map a deployable architecture for your institution's risk model. If you are ready to walk through your specific environment, Ververica's architecture team is available to do that with you directly.
For organizations that have reached the architecture review stage, [Ververica's SOC 2 Type II certification](https://trust.ververica.com/) (achieved on the first audit attempt) covers a sustained review period rather than a point-in-time assessment and provides the vendor assurance documentation that procurement and security teams require as part of any regulated workload evaluation.
If your current data pipeline cannot meet the required control boundaries without recurring exceptions, the issue is not a matter of roadmap timing. It is an architectural mismatch.
Ververica is the only streaming platform combining full on-prem deployment, streaming-native governance, and Zero Trust security. No other vendor offers all three without giving up institutional control. Cloud-only platforms made a deliberate choice: optimize for vendor-managed infrastructure. Ververica made the opposite choice. For regulated financial institutions, that difference is not a roadmap consideration. It is the decision.
## More Resources
- Ververica Banking Hub: [https://www.ververica.com/banking](https://www.ververica.com/banking)
- Data Sovereignty Playbook: [https://www.ververica.com/data-sovereignty/fsi-sovereignty-playbook](https://www.ververica.com/data-sovereignty/fsi-sovereignty-playbook)
- Streaming Platform Evaluation Framework: [https://www.ververica.com/data-sovereignty/fsi-streaming-platform-evaluation-framework](https://www.ververica.com/data-sovereignty/fsi-streaming-platform-evaluation-framework)
- How Ververica Delivers Sovereignty for Financial Services Industry: [https://www.ververica.com/data-sovereignty/how-ververica-delivers-sovereignty-for-financial-services-industry](https://www.ververica.com/data-sovereignty/how-ververica-delivers-sovereignty-for-financial-services-industry)
- Streaming Sovereignty Checklist For Financial Services: [https://www.ververica.com/data-sovereignty/streaming-sovereignty-checklist-for-financial-services-industry](https://www.ververica.com/data-sovereignty/streaming-sovereignty-checklist-for-financial-services-industry)
---
---
title: "Sovereign By Design. No Exceptions."
description: "Ververica is sunsetting its Cloud Managed Service to prioritize sovereign, BYOC deployments. We are doubling down on what regulated industries demand: zero trust, full data residency, and control."
lastUpdated: 2026-06-15T10:06:32.000Z
source_url:
html: "https://www.ververica.com/blog/sovereign-by-design-no-exceptions"
md: "https://www.ververica.com/blog/sovereign-by-design-no-exceptions.md"
---
## REAL-TIME AI RUNS INSIDE YOUR TRUST BOUNDARY
As the original creators of Apache Flink®, Ververica has spent 11 years building with and selling to the organizations scaling real-time AI in production. The conversation is consistent across financial services, healthcare, energy, telecom, and manufacturing.
Zero trust is table stakes. Full sovereignty is non-negotiable. Streaming runs inside customer cloud accounts, data centers, and sovereign regions. It cannot safely operate anywhere else.
This is not a market trend. It is the architecture that regulated industries require by law, by procurement mandate, and by design.
## THE BUYERS WHO DEFINE THE CATEGORY HAVE ALREADY DECIDED
Every customer who starts with a managed deployment eventually migrates to BYOC or self-managed once their use case proves out and governance requirements surface. The promotion was always the destination.
The buyers who define real-time AI do not permanently run production streaming on multi-tenant infrastructure. They require sovereign deployments, built on zero trust, with full data residency and audit control. We have listened, and we are building for that exclusively.
Where the investment goes:
[**VERVERICA PLATFORM ON BYOC**](https://www.ververica.com/product/deployment/byoc)
Inside the customer's own cloud account, with their own keys, their own VPC, their own audit trail. Production-hardened, designed for regulated buyers from day one. Standing up a BYOC environment is as fast as any proof of concept today, on your terms, in your infrastructure.
[**VERVERICA PLATFORM SELF-MANAGED**](https://www.ververica.com/product/deployment/self-managed)
On-premise, inside customer infrastructure. The default for the most demanding sovereignty requirements: full data residency, complete operational control, air-gapped environments.
[**VERVERICA STREAMHOUSE™**](https://www.ververica.com/product/streamhouse)
Streaming-native lakehouse on customer-owned object storage. Governed by default, no compute lock-in.
These are the products regulated enterprises buy. These are the products that win the category.
## A DISCIPLINED PRODUCT DECISION
Acting on this conviction means making a clear choice. On 30 June 2026, Ververica Cloud Fully Managed Deployment is transitioning to make way for what comes next.
This is not a retreat from the cloud. BYOC _**IS**_ the cloud, deployed where customers have the governance to run it. And this is not a disruption for any customer: every paid workload transitions to BYOC with full support, on a timeline you, the customer, controls.
Serverless will return, rebuilt around the needs of the practitioners who define where real-time streaming goes next.
Vendors phase out products quietly when they have something to hide. We are saying this loudly because the reasoning is sound, and because what comes next is worth the wait.
Bold. Sovereign. Real-time. The category goes to the vendor with the conviction to build what the buyer requires.
---
---
title: "Real-time AI in SQL and Expert-Level Control In Ververica Cloud and BYOC"
description: "We’ve set the new baseline: governed, absolute truth, delivered at speed. Real-time AI belongs in SQL, the lakehouse in the runtime, control with the operator. This is the new baseline."
lastUpdated: 2026-05-20T13:40:35.000Z
source_url:
html: "https://www.ververica.com/blog/real-time-ai-in-sql-and-expert-level-control-in-ververica-cloud-and-byoc"
md: "https://www.ververica.com/blog/real-time-ai-in-sql-and-expert-level-control-in-ververica-cloud-and-byoc.md"
---
Ververica created [Apache Flink®](https://www.ververica.com/apache-flink-vs-ververica). We wrote the standard. And for over a decade, we have been solving what others couldn't: the edge cases that break other data platforms. Now, we’re raising the bar again with new features for our [Fully-Managed Cloud](https://www.ververica.com/product/deployment/cloud) and [BYOC](https://www.ververica.com/product/deployment/byoc) deployments of [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/): AI-Native SQL. A more robust lakehouse ingestion path. Operator-level control that puts power in the hands of production teams.
This release sets the new baseline for data streaming platforms: governed, absolute truth, delivered at the speed of now for cloud deployments.
## SQL Becomes AI-Native
Calling AI from a streaming pipeline used to mean writing UDFs, managing HTTP clients, and handling retries by hand. The updated [VERA engine](https://www.ververica.com/product/vera) introduces seven new AI functions that run natively in Flink SQL. Configure your model provider once. The pipeline does the rest.Seven functions, zero custom plumbing:
- **AI_CLASSIFY** routes text into categories of your choosing with a confidence score.
- **AI_SENTIMENT** scores polarity and labels input as positive, negative, or neutral.
- **AI_EXTRACT** pulls structured fields from unstructured text against a JSON Schema you define.
- **AI_SUMMARIZE** compresses long text to a length you specify.
- **AI_EMBED** turns text into vectors for similarity and semantic retrieval.
- **AI_TRANSLATE** handles mutual translation across more than 10 languages with automatic source detection.
- **AI_MASK** identifies and masks sensitive fields automatically. In stream.
The last one is particularly important for regulated workloads serving industries like [finance](https://www.ververica.com/banking). With **AI_MASK**, sensitive data gets redacted in motion, not after a batch runs hours later. That’s the difference between a fully compliant pipeline and a violation waiting to be audited.
For years, batch and streaming engines have made you choose: approximate counts that are fast and wrong, or exact counts that are slow and expensive. Ververica refuses this trade. A native Bitmap type with cardinality functions delivers exact deduplication in stream. Unique visitors, distinct events, audience overlap. All counted, not estimated, at speed.
## Flink CDC YAML: More Sources, Smarter Routing, Safer Failure Modes
- **Postgres and MongoDB sources** get full YAML support: [**Apache**](https://www.ververica.com/ecosystem-introduction/what-is-apache-paimon) [**Paimon™**](https://www.ververica.com/ecosystem-introduction/what-is-apache-paimon) is now a first-class source inside **Apache Flink Change Data Capture (CDC) YAML**, closing the loop on the [**Streamhouse™**](https://www.ververica.com/ecosystem-introduction/what-is-streamhouse) pattern.
- **Catalog-aware references: **YAML jobs can reference source and sink tables already registered in your catalog. No more duplicating definitions across pipeline configs and catalog entries.
- **Regex-based routing: **Standard regular expressions now drive Route table logic. Table merging and database sharding stop being a custom code problem.
- **Dirty data handling: **JSON parsing now isolates malformed records instead of killing the job. **Empty schema fault tolerance** lets Apache Kafka® CDC YAML create tables with empty schemas when no source data is present. Jobs start. They wait. They do not fail before they begin.
These are not vanity updates. They are the changes that decide whether your pipeline survives its first production weekend.
## Connector Enhancements
This release includes new connectors for **CosmosDB** and **MongoDB Catalog**. The Kafka Canal-JSON format now parses source-database index events and exposes raw key and value as metadata, and Flink removes redundant consumer groups. The Paimon Sink supports cross-partition upsert. MongoDB sinks support partial update with better ObjectId handling. Redis gets stronger cluster mode and batched writes. Elasticsearch picks up explicit doc_as_upsert and a connection timeout parameter.
## Operational Depth For Those Who Know What Difficult Looks Like
Serious streaming users require per-operator control to finely tune their deployments. Ververica offers it **now**.
This is where the VERA engine gets serious about giving fine-grained control to those who run streaming jobs at scale.
- **Expert Mode for resource allocation: **Dynamic resource allocation now supports per-Slot-Sharing-Group configuration. For complex deployments, this is the difference between linear scaling and a wall at 60% utilization.
- **Operator-level state TTL: **A single uniform TTL punishes both ends of the spectrum. Fast operators bloat state. Slow operators lose history. Now you configure TTL per operator. Logistics data keeps its memory. High-velocity operators stay lean.
- **State compatibility for SQL deployments: **Resume from the latest state and VERA detects schema and topology changes automatically. The results? Less downtime. Less re-bootstrapping. Less manual surgery.
- **JDK 17 **support arrives in VERA, making it available across all deployment modes. Pick the new vera-4.5-jdk17-flink-1.20 engine version when your operators, libraries, and downstream tooling are ready.
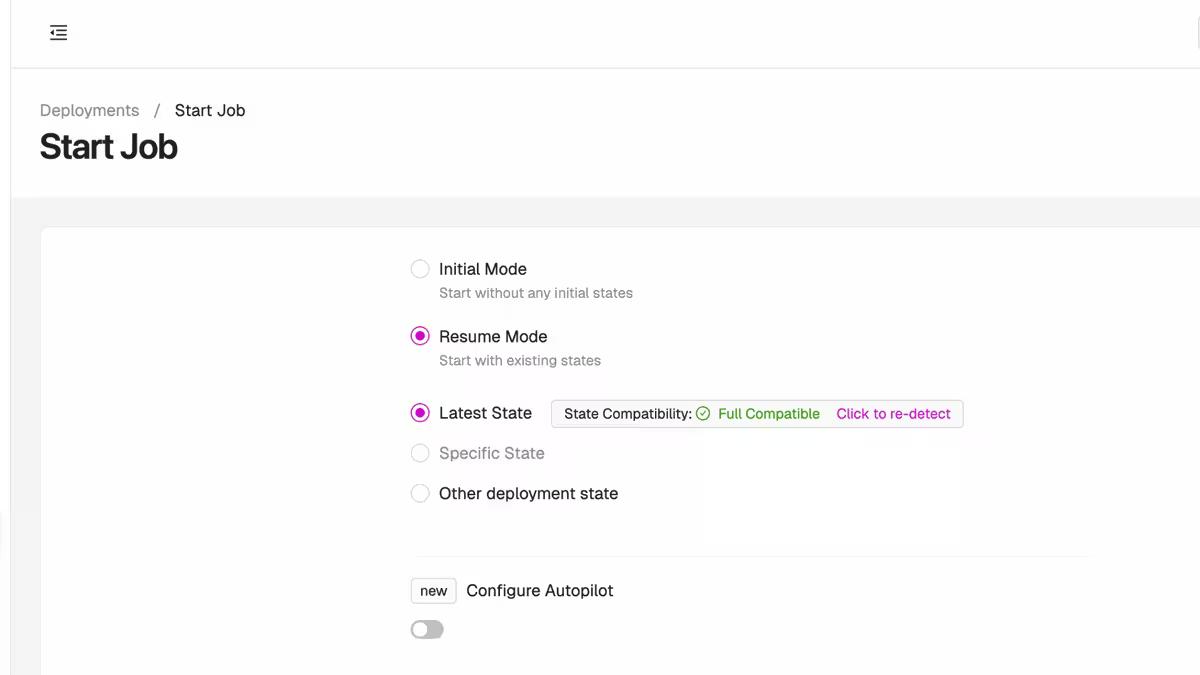
## SQL Console
Until now, ad-hoc SQL queries in Ververica’s Managed Cloud and BYOC deployments meant creating a streaming job, waiting for it to start, and reading the result from the deployment logs. The new SQL Console gives ad-hoc work a dedicated environment. Run **CALL**, **DDL**, **DQL**, **DML**, and **EXPLAIN** in the same place. Create and manage catalogs and tables. Operate on Paimon tables directly. Inspect execution plans without leaving the script.
It also closes the gap with Apache Spark™ and Delta Lake on data lake operations. For teams using SQL as their primary control surface, the operator running an incident at midnight no longer needs a deploy to ask a question.
## This is the New Baseline
Real-time AI belongs in SQL. The lakehouse belongs in the runtime. Control belongs with the operator.
For regulated industries, the math is simple. You need all of your data governed, masked, retained, and queryable. This release provides it all.
## Resources
- [https://www.ververica.com/product/deployment/byoc](https://www.ververica.com/product/deployment/byoc)
- [https://www.ververica.com/product/deployment/cloud](https://www.ververica.com/product/deployment/cloud)
- [Release notes](https://docs.ververica.com/introduction/product-updates/)
---
---
title: "While the World Buffers, We Act."
description: "We tore down the facade. With No Mercy Magenta and a new voice we challenge 'real-time' pretenders. We are the authoritative operator for sovereign, low-latency AI. The world is buffering. We are not."
lastUpdated: 2026-07-09T05:50:38.000Z
source_url:
html: "https://www.ververica.com/blog/while-the-world-buffers-we-act"
md: "https://www.ververica.com/blog/while-the-world-buffers-we-act.md"
---
[Video](https://cdn.sanity.io/files/6b38iw1w/production/dcf068d98e2a0d6d2af20a234b85f112f726b244.mp4)
We don't write "we're excited to announce" anymore. We're not excited. We're on time.
Today Ververica looks different. The logo is sharper. The color is louder. The words are fewer. The magenta is called No Mercy Magenta. It is not a mood. It is a policy.
This is not a refresh. A refresh repaints the facade. We tore down the facade.
## **The Decision**
For too long we played the good corporate citizen. Respectful. Accommodating. Waiting for the market to notice what we'd built. We defined the standard for stream processing. We perfected it. Then we stood quietly in the corner while louder vendors sold "real-time" platforms that weren't.
That ends now.
We have the technology. We have the pedigree. We have the proof. It is time we acted like it.
## **What We Actually Believe**
Real-Time AI for a world in motion. Say it once, then prove it.
Most "real-time" platforms are pretenders. We will say it plainly, because the benchmarks say it for us. Millisecond latencies are not a slogan. They are a shipped number.
Data sovereignty is not a nice-to-have. It is existential. Engineered in Europe. Sovereign by design. Your data, your jurisdiction, your rules. Not a feature flag. A foundation.
AI without governed truth is expensive noise. Models are only as honest as the streams feeding them. We deliver the only asset that matters to AI at scale: data you can trust, completely, at the speed the decision is made.
## **The New Voice**
Read the old Ververica blog. Count the "whilsts." Count the hedges. Count the adjectives stacked three deep because one would not hold. Count how many sentences end in an apology disguised as a CTA.
We counted. It was ugly.
The new voice has rules. Short sentences. Active verbs. Subject, verb, object. No "leverage." No "unlock." No "seamless." No "journey." No "empower." No em-dashes, because machines love them and we are not machines. If we cannot name the latency, we do not say real-time. Numbers or silence.
We do not ask for attention. We assume it. That is the difference between persuasion and authority. We inform. We demonstrate. We prove.
## **The Posture**
We are challengers now. Not humble innovators waiting to be discovered. Not the polite European alternative. The opinionated, surgically focused operator that regulated industries choose when the cost of latency is measured in fines, outages, and fraud.
Surgical domination, not a land grab. We do not need to be loved by everyone. We need to be indispensable to the right ones: banks, insurers, telcos, public infrastructure. The customers who live and die by compliance and governance. The customers who understand what a missed millisecond costs.
If being vocal, visible, and opinionated makes us polarizing, good. Polarizing is a sign the stake is in the ground.
## **What You Will See**
You will see a harder logo. You will see magenta and lime on dark matter. You will see one message per page, one claim per sentence, one number per benchmark. You will see fewer blog posts and more proof. You will see us name competitors when they are wrong. You will see us publish latency numbers without caveats. You will see us show up at events with fewer slides and sharper ones.
You will not see "please consider." You will not see "we'd love to explore." You will not see "excited to announce." You will see "available now," "demo here," "configure parallelism," "issue identified, resolution in two hours."
## **The Commitment**
No hedging. No half-measures. No looking back.
We are building a category-defining company. That requires category-defining conviction, a category-defining voice, and a category-defining willingness to be wrong out loud rather than vague in safety.
The world is buffering. We are not.
## **Let's Go.**
> _Fabian Wilckens is Chief Revenue Officer at Ververica. Michael Misurell directs the brand. Ververica is the real-time data streaming company behind Apache Flink_®_ and Apache Fluss, engineered in Europe, sovereign by design._
---
---
title: "Stop Recomputing Everything: The Case for Streaming Lakehouses"
description: "Batch lakehouses create compliance blindspots & delayed insights from stale data. The Streamhouse™ replaces batch processing with continuous data flow, ensuring AI/risk models run on real-time data."
lastUpdated: 2026-05-04T10:54:22.000Z
source_url:
html: "https://www.ververica.com/blog/stop-recomputing-everything-the-case-for-streaming-lakehouses"
md: "https://www.ververica.com/blog/stop-recomputing-everything-the-case-for-streaming-lakehouses.md"
---
A risk manager at a major bank watches a corporate client draw hard on their credit line all morning. Multiple large transfers. A spike in card activity. A missed loan payment. The risk dashboard should reflect this escalating exposure right now. It does not. It pulls from last night's batch run. By the time the system catches up, the exposure has already compounded.
This is not an edge case. It is the default outcome of how most data platforms operate today.
And it is about to get worse. Organizations deploy AI models for fraud detection, credit scoring, anomaly detection, and regulatory compliance. Every model is only as reliable as the data it reasons over. A fraud model running on data that is eight hours stale does not detect fraud. It detects history. A compliance engine fed by last night's batch run creates an 18-hour blindspot. Violations accumulate undetected. The architecture that feeds AI is as important as the model itself. Stale data in means unreliable AI out. No model sophistication compensates for that.
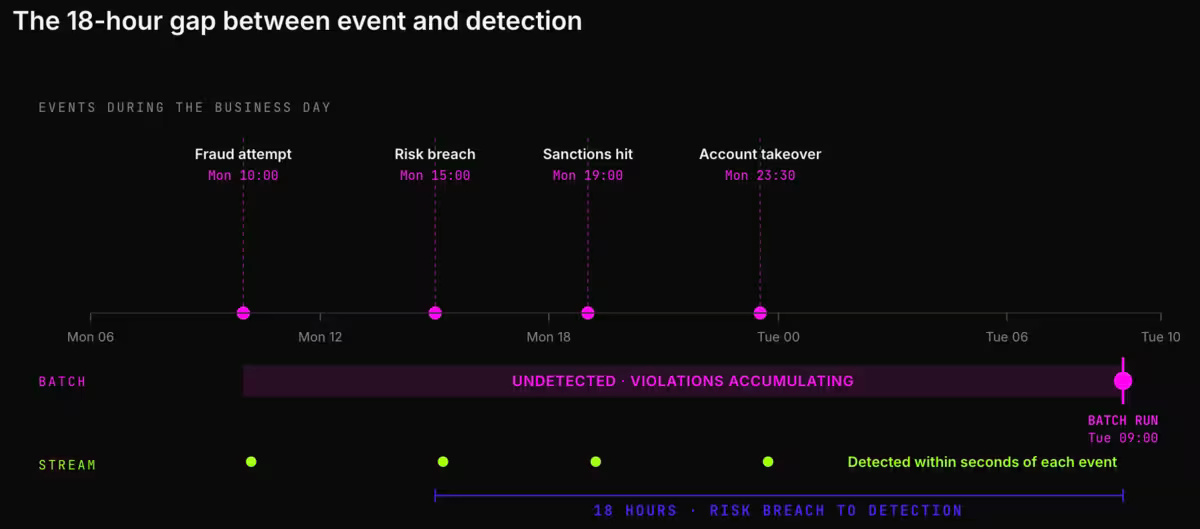
Data platforms face three demands. Lower end-to-end latency across every pipeline layer. Cost-efficient streaming without sacrificing freshness. Stream-batch unification on one consistent architecture. Batch cannot satisfy all three. The Streamhouse™ does.
Apache Paimon, a streaming-native table format built on a Log-Structured Merge-tree (LSM-tree) model, runs this architecture in production today. Apache Fluss™ extends it further. A streaming storage system built for real-time analytics and AI workloads. Fluss decouples the streaming layer from the table format. The same architecture works with Apache Iceberg, Paimon, Lance, or (soon) Hudi. The result: a fully open, unified platform. Streaming and batch are not parallel systems to reconcile. They are a single architecture expressed at different points on a freshness continuum.
This post examines the Streamhouse through open table formats. Open table formats deliver a low-cost path to near-real-time latency. A separate post covers the full architecture with Apache Fluss extending to Apache Iceberg.
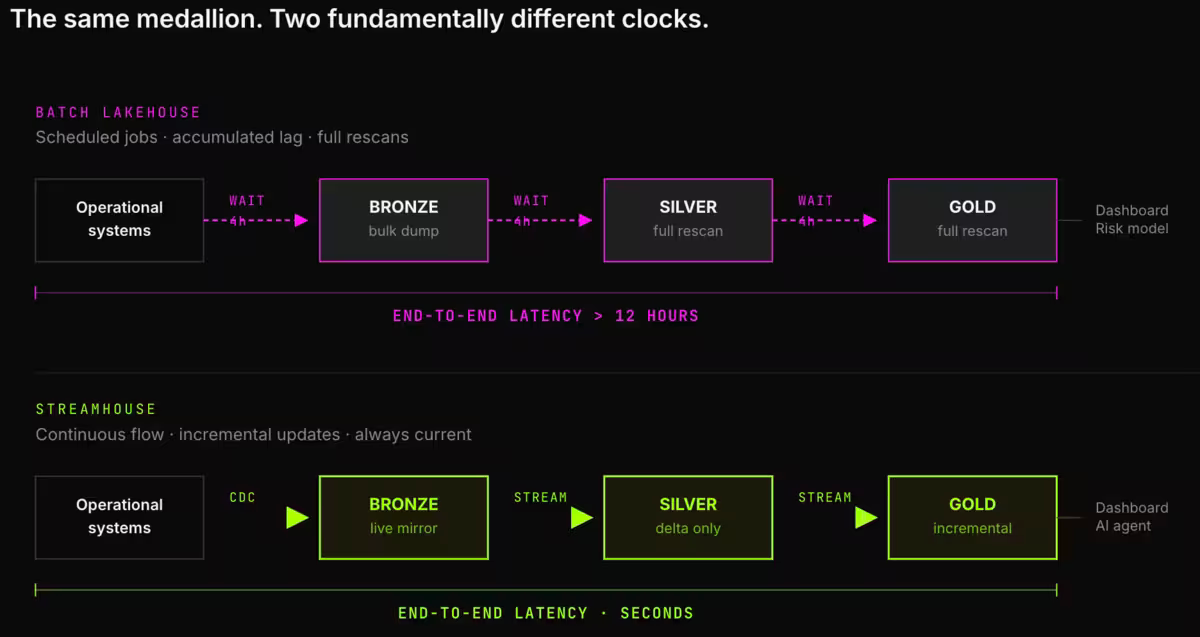
## Background: What a Data Lakehouse Actually Is
The data lakehouse emerged from two decades of architectural evolution.
Data warehouses offered structure and reliability. They lacked flexibility and scale. Data lakes offered cheap, flexible storage. They lacked governance and query reliability. The lakehouse unified both. Warehouse guarantees applied to lake scale and openness. Store everything. Query anything. Trust the results.
Apache Iceberg, Delta Lake, and Apache Hudi made this practical. They brought ACID transactions, schema enforcement, and time-travel capabilities to object storage. The lakehouse became the dominant architecture for modern data platforms.
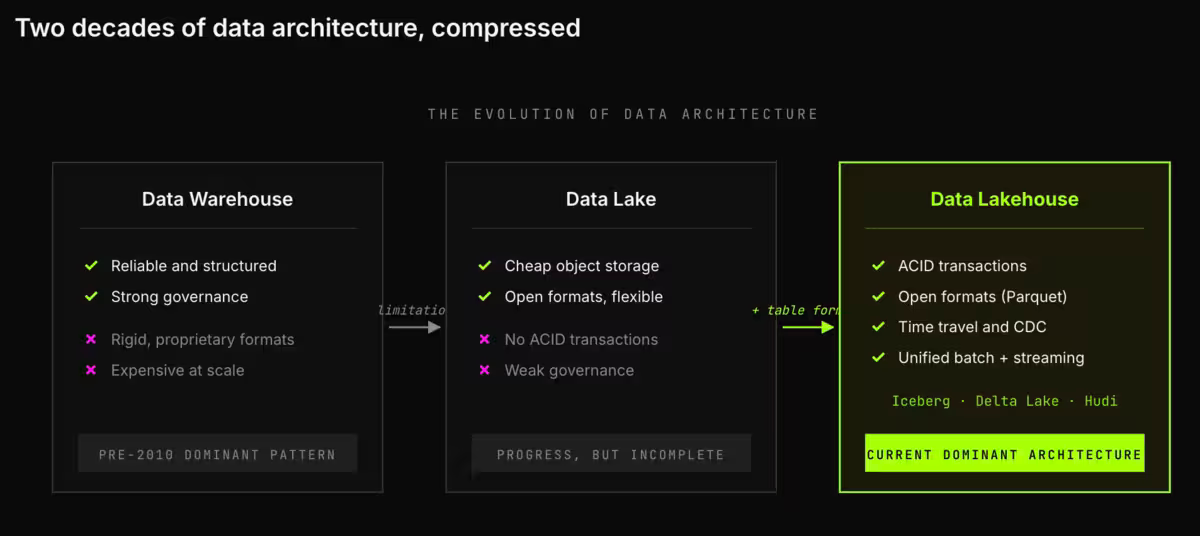
Most implementations carried one constraint forward from the batch era.
## **The Core Limitation: Batch Lakehouses Run on Stale Data**
Most lakehouses today use the medallion architecture. Three logical layers at increasing levels of refinement:
- **Bronze:** Raw, unprocessed data from source systems.
- **Silver:** Cleaned, enriched, joined datasets built from Bronze.
- **Gold:** Curated, aggregated business metrics built from Silver.
The structure is sound. The update mechanism is the problem.
Each layer refreshes through scheduled batch jobs. Raw data accumulates. At a fixed interval, hourly or daily, a job reads everything, transforms it, and writes it downstream. Then the next job does the same. By the time a business event propagates from Bronze to Gold, hours have passed.
### Three Compounding Consequences
**1. Delayed insights.** Batch pipelines introduce a fixed lag between event and reflection. If Silver runs every four hours and Gold runs after that, end-to-end latency exceeds one business day under ideal conditions. Decision-makers operate on a historical view. Not the current one.
**2. Expensive, redundant recomputation.** A batch job that updates total outstanding loan balance rescans the entire historical dataset. It recomputes the aggregate from scratch. The number of new records arriving does not change the work done. A dataset holds 90 days of transaction history. 1,000 new records land today. The batch job still reads and processes all 90 days. Datasets grow. Overhead grows with them. A pipeline that ran in two hours in year one runs in eight hours by year three. Same schedule. Same logic. Four times the cost.
**3. Orchestration overhead and fragility.** Batch pipelines require schedulers, dependency chains, retry logic, monitoring, and engineers to maintain all of it. A failure in the Bronze job blocks Silver. Silver blocks Gold. Gold blocks every downstream dashboard and application. More pipelines mean a larger, more brittle dependency web.
Delayed insights produce decisions based on yesterday's data. Redundant recomputation drives pipeline costs up every year with no corresponding gain. A single scheduler failure propagates to every consumer.
## **Most "Real-Time" Platforms Are Not Real-Time**
Most platforms marketed as real-time are micro-batch systems dressed in streaming language. They ingest events quickly. They still process them in small scheduled windows. The marketing says streaming. The architecture says batch with a shorter interval.
The distinction matters. A fraud signal that arrives 15 minutes late is not real-time. It is a fast batch job. A compliance alert that fires after the trading window closes is not monitoring. It is an audit finding. A credit risk score computed on a four-hour-old snapshot is not dynamic. It is yesterday's answer delivered slightly faster.
> Real-time means the system processes each event as it arrives, updates state incrementally, and propagates changes downstream within seconds. Not minutes. Not "near real-time with an asterisk". Seconds.
Any architecture that accumulates data before processing operates in batch mode. Frequency does not change that.
## **The Streamhouse: Continuous Data Flow Across All Layers**
The Streamhouse replaces periodic batch processing with continuous, incremental pipelines.
Events flow through Bronze, Silver, and Gold as they arrive. Each new event triggers only the computation required to incorporate that change. The system maintains running state. It applies incremental updates. The difference: a database that processes individual transactions, versus one that reloads its contents from backup every night.
Raw events, enriched datasets, and business metrics evolve in near real time. They reflect the current state of source systems.
### The Data Continuity Pattern: How the Layers Stay in Sync
Data continuity is the defining concept. Each layer of the medallion architecture stays automatically and continuously in sync with the layers below it as events flow through the system.
In a batch architecture, synchronisation is a scheduled, manual concern. If the Silver job has not run today, Silver is stale. Gold is also stale. In a Streamhouse, synchronisation is structural. Changes propagate downstream automatically, layer by layer, as they arrive. Four patterns make this work.
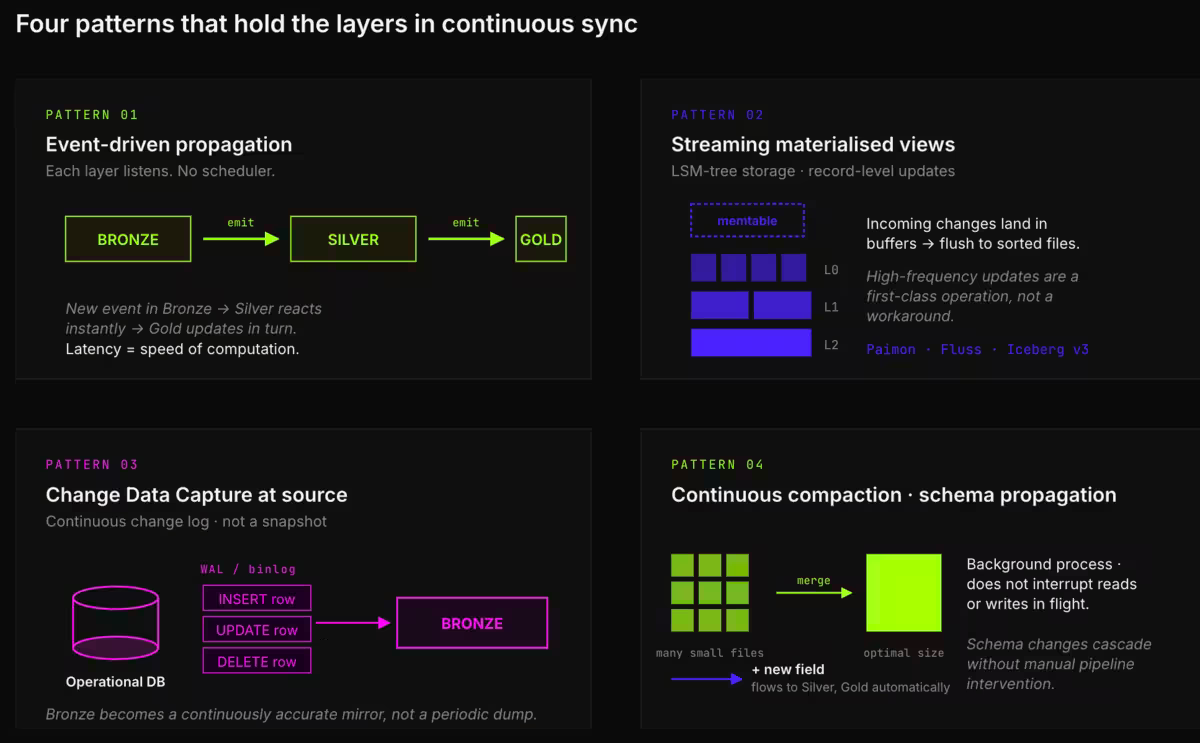
#### Pattern 1: Event-Driven Layer Propagation
Each layer listens for changes from the layer below. It does not wait to be told when to run. A new event in Bronze triggers Silver pipelines immediately. When Silver updates, Gold responds. Updates cascade automatically. No scheduler. No manual trigger. No accumulated wait time.
Computation speed determines latency. Not cron frequency.
#### Pattern 2: Streaming Materialised Views
Traditional data lake file formats were designed for immutable writes. You append new data. Updating an existing record meant rewriting entire files or partitions. Continuous, record-level updates were prohibitively expensive.
A Streamhouse built on streaming table formats like Apache Paimon operates differently. Incoming changes land in fast in-memory buffers and flush to sorted, compact files. Background compaction merges them over time. High-frequency updates are a first-class operation. Not a workaround.
When a customer's credit utilisation changes, the change propagates immediately. No surrounding data gets rewritten. No read-time debt accumulates. Incremental, high-frequency updates across all three lakehouse layers become practical.
#### Pattern 3: Change Data Capture (CDC) at the Source
Data continuity begins upstream of the lakehouse itself. Change Data Capture (CDC) streams database changes, inserts, updates, deletes, out of operational systems the moment they occur. No bulk exports. No schedules.
CDC converts Bronze from a periodic data dump into a continuously accurate mirror of source systems. Bronze receives a precise, ordered log of every change as it happens. This removes the first and largest source of latency in traditional lakehouse pipelines.
#### Pattern 4: Continuous Compaction and Schema Propagation
High-frequency streaming writes produce many small files. Good for freshness. Bad for query performance over time. The Streamhouse runs continuous background compaction. Small files merge into optimally sized ones without interrupting incoming updates or downstream queries.
Schema propagation matters too. When a source schema changes, a new field or a revised data type, that change flows downstream to Silver and Gold automatically. No manual pipeline updates. No downstream failures. In batch architectures, schema changes halt pipelines and require coordinated intervention. In a Streamhouse, the system handles them by design.
These four patterns ensure Bronze, Silver, and Gold are not independent tables that share a naming convention. They are a single, continuously evolving dataset viewed at different levels of refinement. Always in sync. Always current.
## **Concrete Example: Building a Real-Time Financial Platform**
Take a major commercial bank. One of the most demanding environments for any data architecture.
The platform generates a constant stream of events. Payment transactions, card activity, account updates, money transfers, stock market data, mobile banking interactions. Thousands to millions per minute.
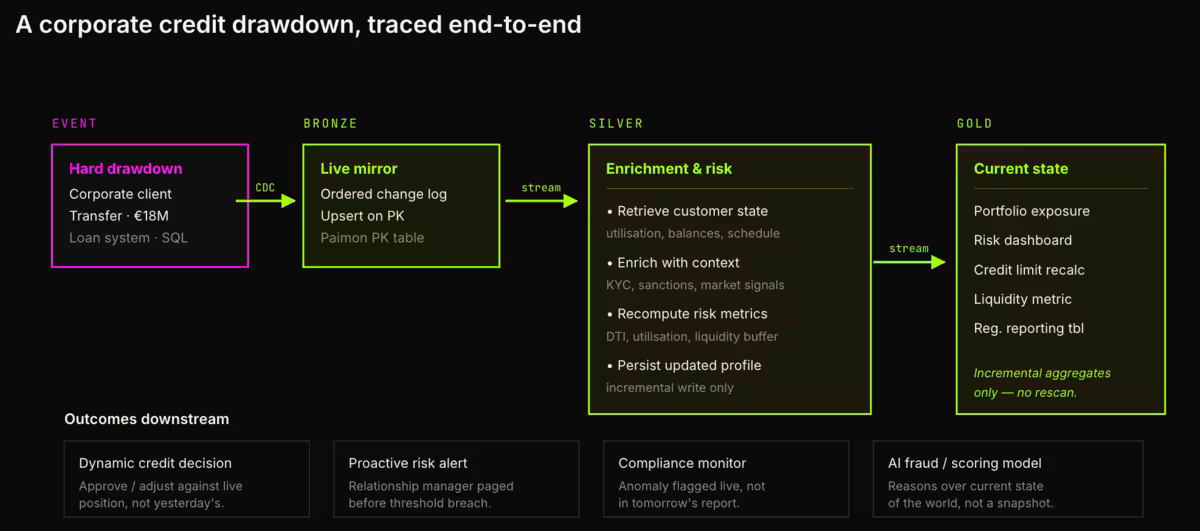
### Bronze: Continuous Event Ingestion
Bronze operates as a continuous receiver, driven by CDC. Events arrive from operational systems in real time. Loan drawdowns, card transactions, balance updates, credit limit revisions. They arrive as append-only event streams or CDC logs that capture every source database change in order. Upserts keep Bronze as a continuously accurate reflection of source systems. Updated within seconds of each change.
### Silver: Real-Time Customer and Risk Intelligence
Silver turns raw events into structured, enriched datasets. Event-driven propagation makes the difference here.
The moment a new event lands in Bronze, Silver pipelines process it. The pipeline maintains a continuously updated financial health profile for every customer. That profile is the foundation of dynamic credit risk assessment.
When a significant withdrawal event propagates from Bronze to Silver, the pipeline:
- Retrieves the customer's current state: live credit utilisation, outstanding balances, upcoming payment schedule, recent transfer history. Maintained as an incrementally updated profile.
- Enriches the event with contextual signals: compliance flags, Know Your Customer (KYC) status, sanctions checks, relevant market indicators.
- Recalculates risk metrics: debt-to-income ratio, credit utilisation rate, liquidity buffer.
- Writes the updated profile. Immediately available to Gold and downstream applications.
A single event triggers the process. Only changed data gets updated.
The practical outcomes:
- **Dynamic credit decisions.** Approve or adjust credit limits against the customer's actual financial position at the time of the request. Not yesterday's snapshot.
- **Proactive risk alerts.** Surface customers approaching critical risk thresholds as their behaviour evolves throughout the day. Relationship managers act before exposure compounds.
- **Continuous compliance monitoring.** Flag unusual activity as it happens. Not in the next morning's report.
### Gold: Continuously Maintained Business Metrics
Gold is where dashboards, risk applications, regulatory reporting tools, and executive teams consume data.
In a batch architecture, Gold updates at most once per day. Portfolio risk dashboards reflect yesterday's positions. For a bank managing large credit exposures, the gap between current data and day-old data is a risk and compliance gap.
In a Streamhouse, Gold aggregates update incrementally as events flow through Silver. The compute model is fundamentally different.
Yesterday, 90 loan transactions were processed. Net outstanding balance: -€100M. Today, 10 new transactions arrive totalling +€5M.
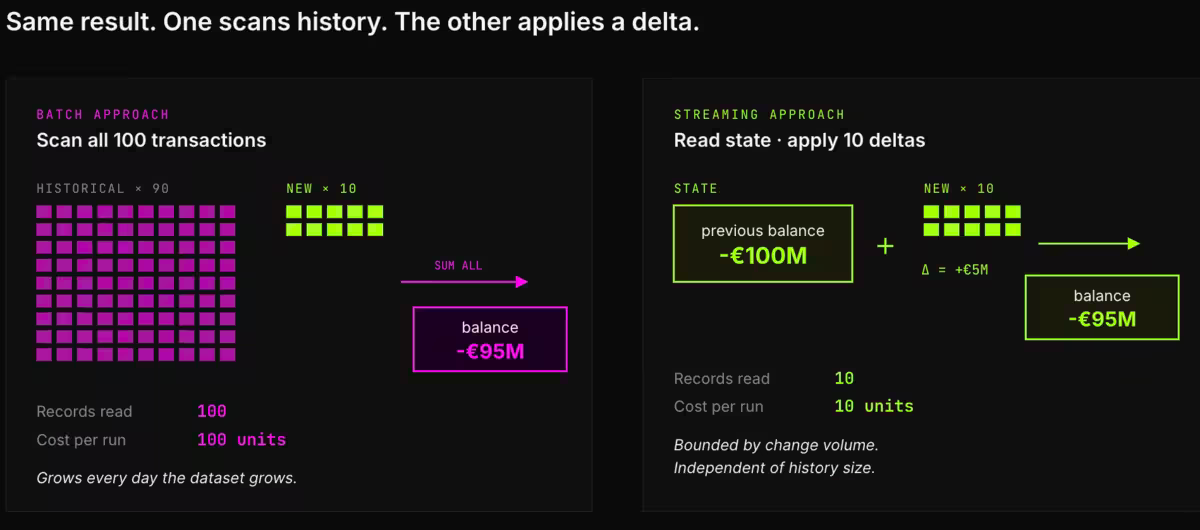
**Batch approach:** Load all 100 transactions. Sum from scratch. Result: -€95M. Batch scans the same 90 historical records again, as it did yesterday and the day before.
**Streaming approach:** Retrieve existing state (-€100M). Apply today's delta (+€5M). Result: -€95M. No historical rescan. Processing time scales with the 10 new transactions. Not the 100 total.
The result is identical. Streaming costs far less compute. At production scale, where datasets span years and aggregates cover millions of records, the difference translates directly into infrastructure cost and pipeline run time. A batch job rescanning 500GB of historical data daily costs the same every day it runs. A streaming pipeline processing 5GB of daily incremental changes costs a fraction of that. That fraction does not grow as the historical dataset grows.
Credit exposure, portfolio risk distributions, liquidity gap metrics, and loan performance indicators all reflect the bank's actual position at the current moment. Not the prior close of business.
## **The Cost Case for Streaming on the Lakehouse**
Streaming lakehouses cost less to operate. Total Cost of Ownership (TCO) is structurally lower than batch.
**Compute scales with change, not with history.** In a batch system, pipeline cost is a function of dataset size. Dataset size only grows. In a streaming system, compute cost is a function of incoming change volume. Change volume is bounded. Historical dataset size is not. An organisation with three years of transaction history pays the same streaming compute cost per day as it did in year one. A batch pipeline rescanning that full history does not.
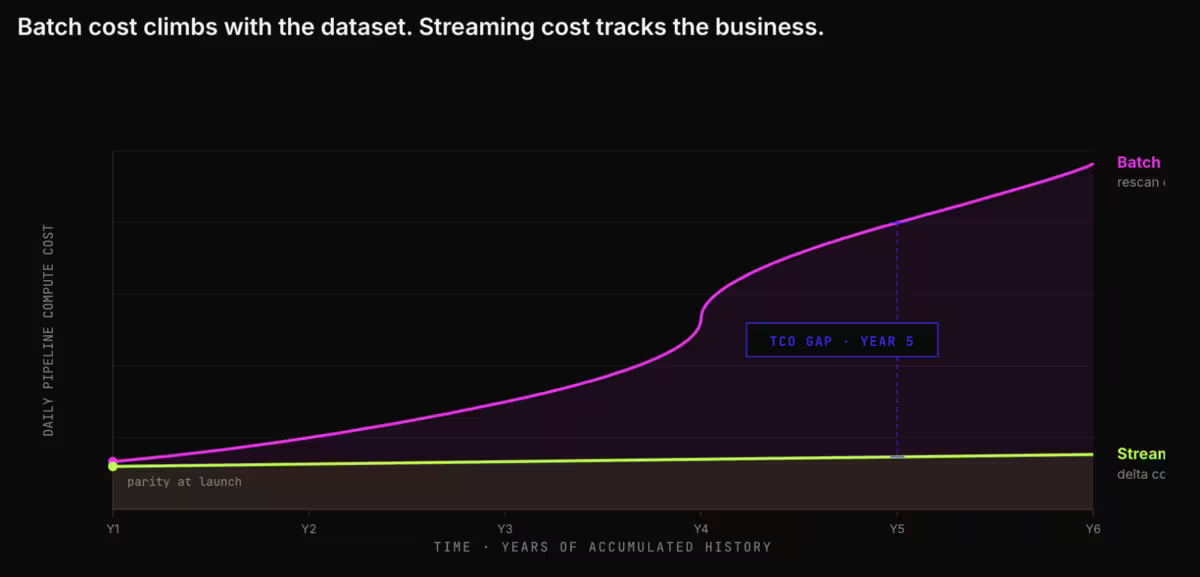
**Infrastructure is right-sized and consistent.** Batch architectures require large compute clusters that spin up, process everything at maximum speed, and spin down. The job must finish within the batch window. Peak-load sizing becomes mandatory. Streaming architectures run continuously at a lower, steadier resource level. Predictable to budget. Cheaper to operate.
**Operational overhead drops.** The four data continuity patterns each remove distinct categories of operational cost: orchestration infrastructure, manual schema migration, bulk export jobs, and engineering hours spent recovering from pipeline dependency failures.
The primary cost factors unique to streaming are 24/7 infrastructure uptime and background compaction. Modern streaming engines handle both in production. At meaningful data volumes, these costs are a fraction of the compute savings from removing historical rescans.
## **Sovereignty and Compliance: Architecture Is Not Neutral**
For regulated industries, where data flows is not only a technical decision. It is a regulatory one.
The Digital Operational Resilience Act (DORA) requires financial institutions to demonstrate operational resilience in real time. The General Data Protection Regulation (GDPR) mandates control over where personal data resides and how it moves. MiFID II demands transaction reporting with strict timeliness requirements. Basel IV tightens capital adequacy calculations that depend on current exposure data. Not yesterday's snapshot.
A batch architecture creates compliance blindspots. An 18-hour gap between event and detection is not an operational inconvenience. It is a regulatory liability. Streaming closes that gap. The streaming platform itself must also meet the sovereignty bar.
Ververica is the only enterprise streaming platform built in Europe, for European levels of compliance demand. Our architecture satisfies the strictest residency and sovereignty requirements anywhere. Your data stays under your control. In your jurisdiction. Beyond foreign surveillance.
Ververica's platform supports multiple deployment models. Managed cloud. Private Virtual Private Clouds (VPCs). Air-gapped Kubernetes environments. Zero-Trust implementations. This structural approach aligns with the governance demands of DORA, GDPR, and MiFID II.
Most US hyperscaler-native streaming platforms cannot make that guarantee. For a European bank, a Middle Eastern sovereign wealth fund, or any institution where data residency is a board-level concern, the architecture choice is a jurisdictional choice. The Streamhouse on Ververica satisfies both.
## **What the Streamhouse Runs**
Continuous data flow plus in-sync layers opens a different category of applications. Not faster versions of existing capabilities. Categories of products that batch pipelines cannot produce.
Fraud detection systems that operate on current data. Credit risk models that score against the customer's actual position, not a day-old approximation. Compliance engines that monitor in real time, closing the blindspot that batch architectures create by design. Recommendation engines that reflect what is happening now. Portfolio rebalancing systems that act on live market conditions. AI agents that reason over the actual state of the world. Not yesterday's snapshot.
AI models are only as good as the data underneath them. The Streamhouse keeps that data current, governed, and continuously propagated. That is what makes real-time AI real.
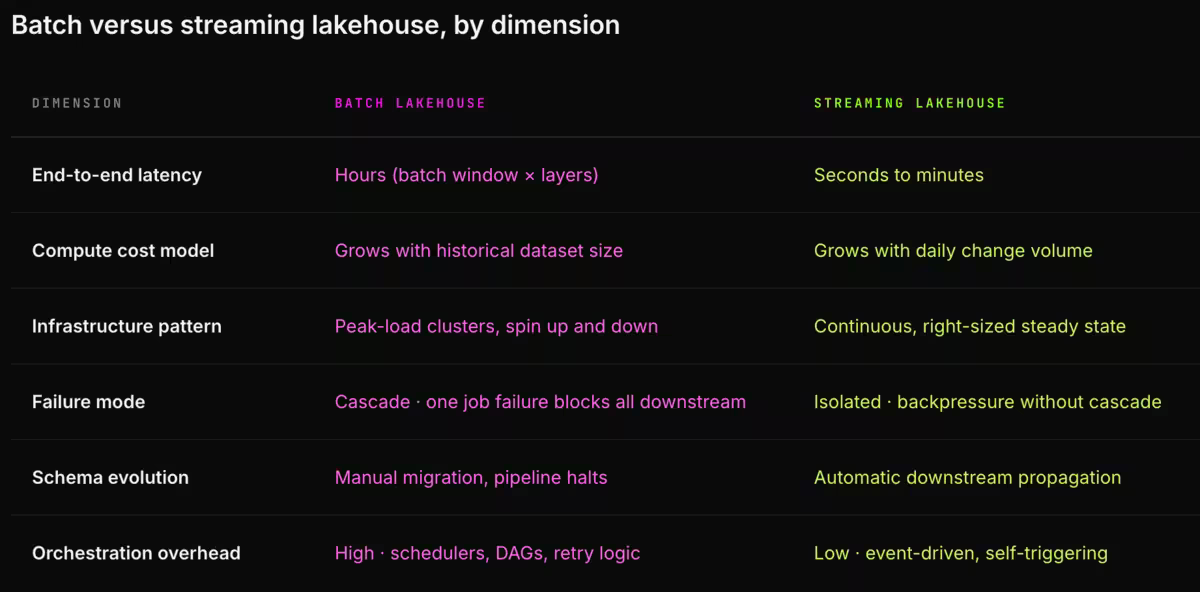
## **Conclusion: The Lakehouse Evolves**
The lakehouse architecture solved real limitations of traditional data warehouses and first-generation data lakes. Organizations now depend on near-real-time intelligence for risk management, compliance, AI, and customer operations. The batch-first lakehouse has reached its limits.
The Streamhouse extends the lakehouse model. Same layered structure. Same reliability guarantees. Continuous data flow and automated layer synchronization replace the rigid batch cycle. Bronze, Silver, and Gold become a living system. Always current. Always consistent. Always cascading. The four data continuity patterns hold them together.
Credit exposure, portfolio risk, liquidity metrics. All reflecting current positions. AI models reasoning over governed, real-time data. Not stale snapshots dressed in dashboards. That is the competitive edge.
## Real-World Streaming Lakehouse Deployments
These patterns are not theoretical. Organisations across industries have adopted Streamhouse architectures to address exactly these challenges. The following talks provide concrete implementation perspectives from engineering teams who built and operate these systems at scale:
- [Yelp](https://www.youtube.com/watch?v=iYc9RXGZ7w0): Real-time business intelligence across its marketplace.
- [Fresha](https://www.youtube.com/watch?v=ftKFRGFtsG0): Real-time booking and operational data for the world's largest beauty and wellness marketplace.
- [Unity3D](https://www.youtube.com/watch?v=uhQalBGVUYw): High-volume game telemetry and analytics at scale.
- [Lalamove](https://www.youtube.com/watch?v=MiPnd1s1tuM): Real-time operations and driver matching for on-demand logistics.
- [TikTok](https://www.youtube.com/watch?v=tQCxZjYgl5U): Petabyte-scale streaming data pipelines for content recommendations and platform analytics.
- [Shopee](https://www.youtube.com/watch?v=yNZ37uVLda8): Real-time inventory, pricing, and fraud signals across one of the largest e-commerce platforms.
_Apache Flink® and Apache Fluss™ are trademarks of the Apache Software Foundation. Streamhouse™ is a trademark exclusively licensed to Ververica GmbH_
---
---
title: "The Data Platform Bar Has Risen. Ververica Has Set It: Introducing Ververica Platform 3.1"
description: ""
lastUpdated: 2026-05-14T06:02:50.000Z
source_url:
html: "https://www.ververica.com/blog/the-data-platform-bar-has-risen-ververica-has-set-it-introducing-ververica-platform-3-1"
md: "https://www.ververica.com/blog/the-data-platform-bar-has-risen-ververica-has-set-it-introducing-ververica-platform-3-1.md"
---
## The Hard Part Was Never The Stream. Ververica Platform 3.1 Proves It.
In 2026, the hardest part of stream processing isn't the stream processing. It's everything other vendors don't tell you about.
It’s the surrounding ecosystem, the reliability, and the need for governance. The enterprise-grade infrastructure required to make complex systems truly trustworthy, not just to your engineers, but to the organizations that have the most to gain from real-time data.
Ververica created Apache Flink. We wrote the standard. And for over a decade, we have been solving what others couldn't: exactly-once fault tolerance, terabyte-scale state management, the edge cases that break anyone else. Then we created [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/), and now, we’ve further improved the Platform with additional features.
Our expertise is not a footnote. It is a foundation, and what we’re shipping now continues to build on that same core:
A data platform where your teams move faster. Your compliance team sleeps soundly. And your business trusts every insight that comes out of the pipeline.
No hedging. No half-measures. No compromise.
This is governed, absolute truth, delivered at the speed of now.
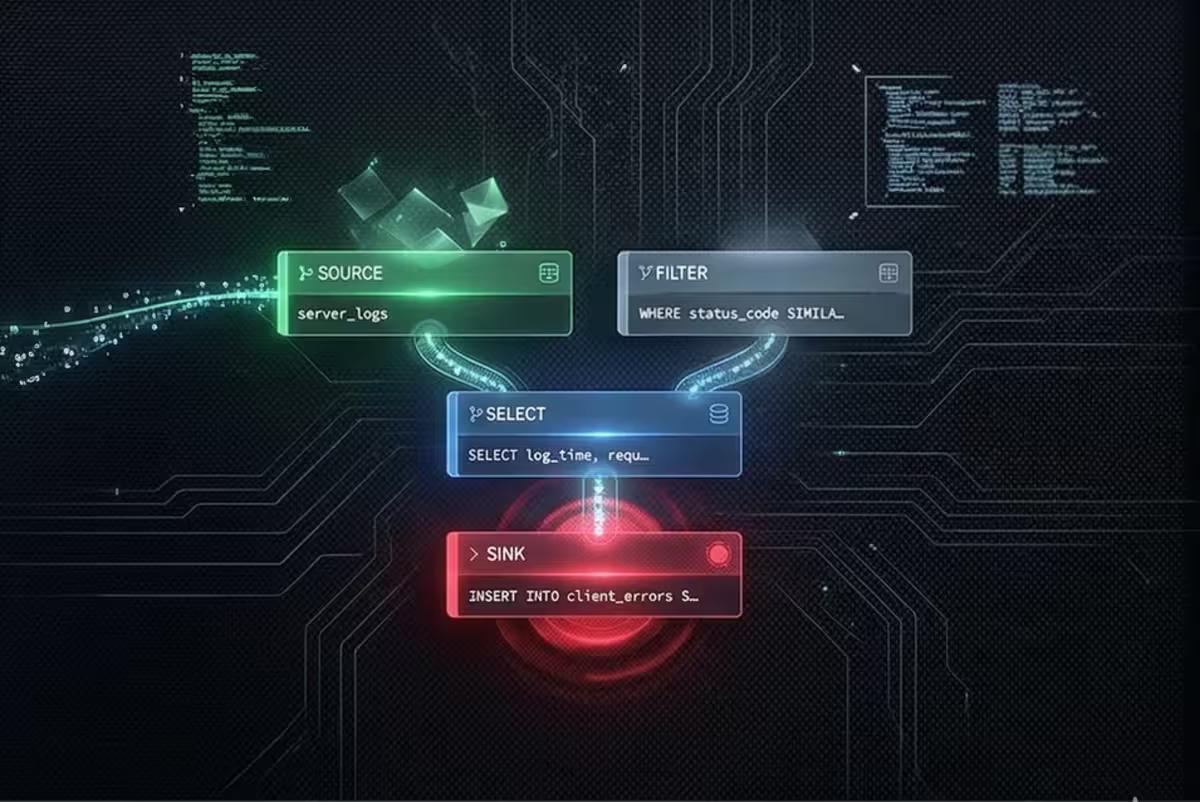
## This Is What Enterprise-Grade Actually Looks Like
Ververica has a long history of building an enterprise-ready platform that even the most regulated enterprises rely on. The features in this new release are no exception. Every feature was built with a single question in mind: _What does it take for a regulated enterprise to trust this platform in production?_
The answer is the full stack of operational, security, and compliance capabilities that large organizations require before they can move fast with confidence.
Here are the new features we are delivering today:
### Kubernetes-Native Operations: Stream Processing As A First-Class Citizen
Your infrastructure teams run Kubernetes. Ververica does too, natively. The Ververica Kubernetes Operator lets your teams manage the full platform directly through _kubectl_ and Helm. No separate toolchain, and no web UI required for automation. The platform fits into the operational patterns your engineers already use. Stream processing becomes a first-class citizen in your infrastructure stack.
What this means for your business:
- CI/CD pipelines that deploy and version streaming jobs like any other application
- Automated monitoring and scaling through the tooling your team already owns
- Simpler version management and rollbacks
### Governance, Traceability, and Security Built-In
Ververica’s Audit Logs and API Tokens improve governance, traceability, and secure CI/CD automation, because compliance isn't a business constraint. It's a competitive advantage that Ververica is built to address. Let’s dig in:
#### Effortless Compliance with Audit Logs
Regulated industries have to address one specific question before adding any new technology: _“Will we be able to audit it?”_
The answer is now a resounding yes.
Ververica Audit Logs capture the events required by all of your security and compliance policies, and store them where your teams can retrieve, query, and retain them for as long as your policy requires. No workarounds. No exporting logs to a third-party system and hoping they stitch together nicely. For industries running under DORA, GDPR, SOC 2, PCI DSS, or any framework that demands evidence of data access and control, this is foundational.
#### Secure Machine-To-Machine Authentication
API Tokens enable secure, automated access to the Ververica Platform without requiring user interaction. The newly introduced flow for API Token Management allows you to give each workflow, integration, and CI/CD pipeline its own scoped identity. Each token is bound to a namespace and assigned a specific role (viewer, editor, or owner), and you can create, use, or revoke them at any time to comply with least-privileges policies. This makes it easy to integrate Ververica’s Unified Streaming Data Platform into automated workflows while maintaining strict access control and security.
### VERA Engine: Now Compatible With Java 17 And Built For How Engineers Actually Work
The [VERA engine](https://www.ververica.com/vera) doesn't wait. Neither do we.
By customer demand, our proprietary Platform engine VERA is now compatible with JDK 17, the recommended runtime for Flink 2.0, because staying current isn't optional when your pipelines are mission-critical. This updated VERA version also adds native support for the bitmap type and related functions, and is purpose-built for real-time deduplication scenarios at scale.
The engine is smarter. The developer and engineering experience is sharper. The result is a data platform your teams will actually want to use.
This is what it looks like when the people who built Flink keep building.
### Expanded Connectors and Catalogs: Your Data Lives Everywhere. Ververica Does Too.
Real-time data isn't confined to a single system. Neither is Ververica.
We continue expanding the connector and catalog ecosystem with highly-requested capabilities in this latest version:
- MongoDB Catalog
- Azure CosmosDB Connector
#### MongoDB Catalog
No more hand-crafting DDL for every collection. The MongoDB Catalog connects your databases directly to Flink SQL, so databases map to databases, collections map to tables, schemas infer automatically. Your data is ready to query before you've finished your coffee.
#### Azure CosmosDB Connector
Your Flink pipelines now write directly to Azure Cosmos DB with no middleware, no workarounds. Built on the AsyncSink framework with the Cosmos DB Java SDK v4 async client, it delivers at-least-once semantics with the throughput your pipelines demand. Point it at your NoSQL API endpoint and ship.
**No lock-in. No latency. No data left behind.**
### A CLI That Developers Will Actually Use
Developer ease and productivity aren’t bonus features or nice-to-haves. They are where adoption lives or dies.
For that reason, we are releasing the Ververica Command Line Interface (vvctl) that gives your developers a familiar interface, similar to kubectl, for every platform resource. This makes it seamless for human developers to operate, but also opens the door to automated, real-time monitoring and operation directly from the terminal, and makes it much easier to integrate with your existing CI/CD flows.
We often see that developers don’t want to click through a UI to understand what a streaming job is doing, but rather prefer to query it, pipe it, and script it. vvctl allows you to do exactly that, fitting how modern engineering teams actually work.
## Platform Operations, Tightened.
Shipping fast means nothing if you can't operate at scale. These additional features give your platform and infrastructure teams sharper visibility, safer credential handling, and more flexible state recovery. These are the controls that turn a capable platform into a production-grade one.
### Blob Credentials Using Mounted Files
Hardcoded credentials in config files aren't security, they're a liability waiting to surface. Mount your storage credentials as files instead, each key stored separately and loaded automatically by the platform. Built for environments where credentials rotate frequently or live outside the cluster. Secure by design, not by hope.
### Loading Savepoints From Custom Locations
State doesn't care where it lives, and now, neither does Ververica Platform. Load a savepoint from any accessible storage location, including deployments migrated from Ververica Platform 2.0, directly through the UI or Kubernetes Operator. Pick up exactly where you left off, no matter where "left off" happens to be.
### Resource Usage Tracker
Running infrastructure across teams without visibility isn't operations, it's guesswork. The Resource Usage Tracker gives you per-namespace CPU core consumption over time, exportable as CSV via a single API endpoint. Chargeback, optimization, transparency: now you have the data to back every conversation.
## Raising The Bar With Ververica Platform 3.1
For years, the industry has debated capability. _“Can stream processing do it? Is it fast enough? Reliable enough?” _
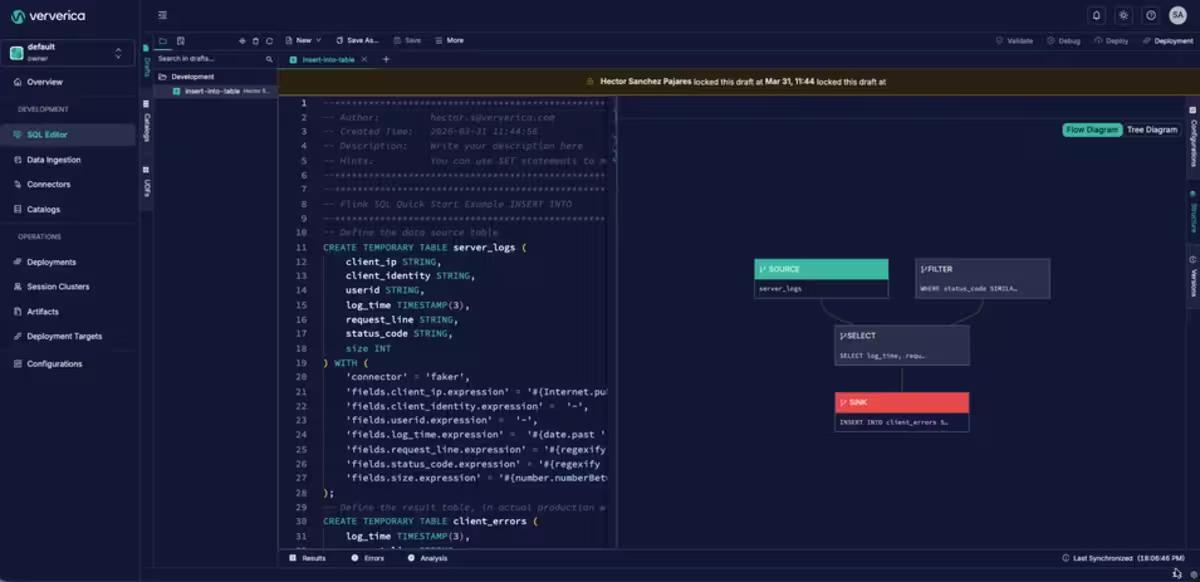
That conversation is over. Ververica has the answers to these important questions:
- Can you deploy your data platform the way you deploy everything else?
- Can you audit it?
- Can you secure it?
- Can your developers work with it without learning a new paradigm?
This release says yes to it all.
We have the technology. We have the pedigree. We have the proof.
## What Deployment Is Best For You?
One solution, multiple deployments. We’re on our way to full feature parity. Here is the exact picture of the new Individual features available in Ververica’s Unified Streaming Data Platform by deployment model:
---
---
title: "Your AI Coding Assistant Can't Touch Your Streaming Platform. Until Now"
description: ""
lastUpdated: 2026-05-14T04:50:54.000Z
source_url:
html: "https://www.ververica.com/blog/your-ai-coding-assistant-cant-touch-your-streaming-platform-until-now"
md: "https://www.ververica.com/blog/your-ai-coding-assistant-cant-touch-your-streaming-platform-until-now.md"
---
Introducing Ververica’s Model Context Protocol (MCP) Server (Preview): Native Large Language Models (LLM) Integration for Your Unified Streaming Data Platform.
You're using Claude, Cursor, or Copilot to write code. They're good at generating SQL, debugging scripts, and building deployment configurations. But when it comes to your streaming data platform? They're completely blind.
Your AI assistant can't see your deployments. Can't validate your SQL against your actual schema. Can't create jobs, manage artifacts, or check logs. It's writing code in a vacuum, disconnected from the platform where that code will actually run.
So you're stuck copying and pasting between your AI tool and your data platform. Context switching. Manual validation. Hoping the AI-generated code actually works when you deploy it.
That friction ends today.
## Ververica MCP Server: Your Platform, Now in Natural Language
The Ververica MCP server gives your AI coding assistant direct, secure access to [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product) through the Model Context Protocol.
What if managing Ververica was as simple as having a conversation? With the MCP server, it is.
The MCP server connects directly to Ververica’s [on-premise and cloud deployments](https://www.ververica.com/deployment) via API, giving your LLMs secure, contextual access to your environments. The result? You can create, manage, debug, and migrate deployments using natural language.
No more switching tabs. No more manual API calls. No more hunting through logs.
Just ask.
## Key Features
### 1. Natural Language Deployment Creation
Generate Apache Flink® SQL drafts from plain-language prompts, automatically create deployments, and configure parameters all conversationally.
Example prompt:
_"Create a deployment that reads from Kafka topic orders, aggregates revenue by region, and writes results to Elasticsearch."_
Your AI assistant:
- Generates the Flink SQL draft
- Creates the deployment with appropriate configuration
- Validates the SQL against your platform schema
- Reduces time from idea to running job
### 2. Deployment Lifecycle Management
Start deployments, monitor job state and health, retrieve runtime status, and access deployment metadata, all via natural language.
For example:
_"Start the revenue aggregation job and monitor its status."_
The AI handles the platform mechanics. You stay in flow.
### 3. Log-Aware Debugging
Full programmatic access to deployment logs means the LLM can now analyze failures, identify root causes, and propose or apply fixes automatically.
Example workflow:
_"Debug the failed SQL deployment in workspace prod-us-east."_
The AI:
- Pulls deployment logs
- Identifies the error (e.g., schema mismatch, missing connector)
- Proposes a corrected SQL script
- Optionally redeploys with the fix
Faster resolution. Zero manual log inspection.
### 4. Import / Export Across Workspaces
Export deployments from one of your Ververica Cloud deployment workspaces/namespaces into another, or even into your Ververica Self-Managed Platform deployment namespaces all with simple prompts.
For example:
_"Export the fraud detection deployment from dev and import it to staging."_
The AI handles context switching, workspace authentication, and configuration transfer. Seamless migration and environment cloning using conversational commands.
This works across deployment methods of Ververica’s Unified Streaming Data Platform, including Ververica Self-Managed Platform and Ververica Cloud, enabling cross-environment replication (dev → staging → prod) without manual configuration drift.
### 5. Context-Aware Platform Access
The MCP server supports both Ververica Self-Managed Platform and Ververica Cloud deployments, providing a unified conversational interface across environments with secure API-based interaction.
Your AI assistant understands:
- Which workspace you're working in
- Which Platform deployment you're targeting
- Your deployment topology and data schemas
- Your operational constraints
It's not just generating code, it's operating your streaming data platform.
## How It Works
The MCP server runs locally via vvctl mcp start. No extra ports. No network exposure. Just stdio communication between your AI assistant and Ververica.
Configure it once in your client:
```json
{
"mcpServers": {
"ververica": {
"command": "vvctl",
"args": ["mcp", "start"]
}
}
}
```
Supported clients: Claude Desktop, Claude Code, Cursor, Copilot, Cline, Windsurf, VS Code, and 10+ other AI coding assistants.
Once configured, your AI assistant has full platform context. It can see your workspaces, deployments, and schemas. It can generate SQL that's validated against your actual tables. It can create deployments and check logs when something fails.
Your AI moves from "code generator" to "platform-aware development partner."
## What You Can Do Right Now
These are just a few examples of what becomes possible:
- **Create deployments conversationally** Ask the LLM in your own words. It will create the SQL draft and deployment from it.
- **Start and monitor deployments** No CLI commands. No dashboard switching. Just natural language.
- **Debug failed SQL deployments** The LLM has full access to logs, so it can debug and fix errors easily.
- **Import / Export deployments between workspaces** Transfer data between different deployment methods of the Unified Streaming Data Platform, migrate configurations across environments, clone workspaces—all by typing your prompt.
## Capability Table
Curious about what capabilities Ververica’s MCP offers?
## Why This Matters
Most data platforms treat AI assistants as external tools, helpful for code generation but disconnected from the platform where code runs. The result is friction, context loss, and time-consuming manual validation.
Ververica's MCP server collapses that gap. Your AI assistant becomes an extension of your streaming data platform itself, with full visibility and control over deployments, scripts, artifacts, and logs.
The benefits:
- **Accelerates development and deployment cycles:** From prompt to running job in seconds
- **Reduces operational overhead:** No manual API calls, no dashboard navigation
- **Simplifies debugging workflows:** AI analyzes logs and proposes fixes automatically
- **Minimizes configuration drift:** Consistent deployments across environments
- **Enables AI-native streaming operations**: Conversational platform management becomes the new standard
This changes the development workflow:
- Draft SQL in natural language → AI generates and validates it against your platform
- Debug a failing deployment → AI pulls logs, identifies the issue, proposes a fix
- Create a new streaming job → AI generates the script, creates the deployment, and starts it
- Switch between dev and prod workspaces → AI handles context changes automatically
You stay in flow. The AI handles the platform mechanics.
## Experimental, But Forward-Looking
The MCP feature is currently experimental, so we don't recommend using it in production environments yet. But we're releasing the preview now because the future of data platform development is AI-native, and we're building for that future today.
As LLMs become more capable, platform integration becomes critical. Code generation isn't enough. Your AI needs to understand your deployment topology, your data schemas, your operational constraints. Ververica’s MCP server is the bridge.
Try it. Break it. Tell us what's missing while we build the infrastructure for AI-native streaming operations together.
## Get Started
Prerequisites:
- Ververica CLI (vvctl) installed
- An AI coding assistant that supports MCP (Claude Desktop, Cursor, Copilot, etc.)
- Access to Ververica’s Unified Streaming Data Platform Self-Managed Platform or Fully-Managed Cloud deployment
Setup:
1. Configure the MCP server in your client using the vvctl mcp start command
1. Authenticate with your Ververica account
1. Start building with full platform context
Read the documentation: [docs.ververica.com/api/cli/mcp-server](https://docs.ververica.com/api/cli/mcp-server/)
## The Bottom Line
Your AI coding assistant should understand your streaming platform, not just generate code in isolation. The Ververica MCP server makes that possible: natively, securely, and locally.
This is experimental infrastructure for AI-native data platform development, allowing for conversational management of Ververica’s Unified Streaming Data Platform deployments using natural language.
Try it, and help us shape where it goes next!
## More Resources
- [Read the Docs](https://docs.ververica.com/api/cli/mcp-server)
- [Install vvctl](https://docs.ververica.com/api/cli/)
- [Contact us](https://www.ververica.com/contact)
[Ververica's Model Context Protocol: Conversational AI In Stream Processing](https://www.youtube.com/watch?v=kbubzza_uJE)
---
---
title: "Zero Trust Theater and Why Most Streaming Platforms Are Pretenders"
description: "# Zero Trust Theater and Why Most Streaming Platforms Are Pretenders ## “Zero Trust” used to mean something. It described a foundational security model where nothing inside the network perimeter was implicitly trusted. Every request regardless of origin had to be authenticated, authorised, and verified. It was an operational architecture that demanded deep, pervasive control over the entire data plane. Now the term has been weaponised by marketing. It is a logo on a sales slide, a checkbox on a compliance form, a vague corporate promise that someone, somewhere, completed a security review before the product shipped. The architecture of perpetual verification has been hollowed out into branding. **And your vendor knows it.** ****The exact same inflation has happened to “streaming platform.” Everyone in the modern data ecosystem is eager to claim the title. Virtually every vendor now has a product with the word “stream” in its name. But claiming it and building it are two fundamentally different things. What the market is full of is a particular species of software the “streaming pretender” that can talk about streaming, market streaming, and occasionally demo streaming, but falls apart the moment you ask it to do real, production-grade work at planetary scale. Or, worse, it technically performs the single function advertised a quick-start tutorial or a simple pipeline but in a way that becomes economically or operationally useless once you leave the controlled, benign environment of a conference keynote or a sandbox account. These platforms either cannot sell what they are genuinely capable of doing, or they cannot actually do what they sell. And sometimes, in a remarkable display of product-market dissonance, they fail to achieve both at once. This matters more now than it did five years ago because the regulatory environment has completely shifted. Regulation is no longer a theoretical risk that can be deferred to a later product roadmap. GDPR is old news. The Digital Operational Resilience Act (DORA) is now in force. NIS2 imposes operational resilience requirements across critical infrastructure. As we laid out in [Data Sovereignty Is Existential Most Platforms Treat It Like a Feature](/blog/data-sovereignty-is-existential-most-platforms-treat-it-like-a-feature), the industry has weaponised “sovereignty” as marketing language. **Your vendor calls it compliance. Regulators call it theater.** If a platform cannot be deployed and operated precisely where a customer’s data is legally required to live and prove that control to an external auditor under pressure then the polish on its marketing page is irrelevant. Such a platform is not an infrastructure asset; it is a legal and operational liability. It is theatre, not engineering. A real streaming platform one that can survive the audits, the scale, and the three A.M. outage calls must possess three non-negotiable properties. We must establish these boundaries before the word “platform” loses all remaining meaning in the data space. ## 1\\. Continuous Compute with Real State The platform must do **continuous compute with real state**. This is the fundamental distinction between a true stream processor and a fast batch engine. A real platform operates on _event time_ the time the event actually occurred not _processing time_ the time the system happens to pick it up. The idea that “every few minutes is fine for most use cases” is a concession to an underlying architecture that cannot handle continuous data flow. A real platform must handle **backpressure** gracefully, preventing catastrophic cascade failures. It must provide **exactly-once semantics** where they actually matter: not in a lab environment, but in production, during a partial system failure, at three in the morning when a downstream system is experiencing a brownout. It must manage **long-lived state** that survives total failure and orchestrated restarts without the operator having to rebuild the universe or lose the computation’s progress. Anything that requires a cron job, a manual restart, or risks double-counting data is a batch engine pretending to be a stream processor. ## 2\\. Usable Data Storage The platform must store processed data in a way that remains **immediately and reliably usable**. If the vendor’s primary answer to the storage question is a variant of “we dump it into cheap object storage and figure out how to access it later,” they have not solved the problem of durable, accessible state. They are deferring it. This deferral guarantees manual reprocessing, data duplication across systems, and data drift between the processing and storage layers. If an engineer must build another ETL pipeline just to make the first pipeline’s output readable by a BI tool, then the storage layer is not infrastructure. It is delayed pain, with the added insult of a high cloud bill. Effective streaming infrastructure must unify storage and processing to ensure low-latency access and prevent unmanageable, siloed data copies. ## 3\\. Control That Survives an Audit The platform must give the customer **control that survives an audit**. This is the heart of the sovereignty discussion. The questions are straightforward, but the answers from most vendors are evasive: Where exactly does the data plane run? Who controls the runtime environment? Who holds the encryption keys? Who patches, upgrades, and isolates the system without calling a vendor’s support line? **If proving sovereignty requires a call to your vendor’s support team, you don’t have sovereignty. You have a dependency.** For any regulated enterprise particularly in finance or government the ability to demonstrate institutional control over data and execution environment is non-negotiable. Anything below these three properties is merely theatre. For a deeper look at what true sovereignty means for financial services, including the three pillars regulators actually evaluate, read our [FSI Streaming Sovereignty Pillar Page.](/fsi-sovereignty-playbook) We can observe how this theatre plays out across the market. **Confluent Cloud’s Flink Offering** is a prime example: a query engine in streaming clothes. On paper, they license Apache Flink. In practice, the entire experience is built around submitting constrained SQL statements to a managed service. Developers are not deploying Flink jobs as independently versioned, traceable artifacts. They are asking a proprietary service to run a pre-defined set of queries on their behalf. There is zero support for shipping custom JAR files containing application-specific logic. That limitation alone should end the discussion for anyone who has operated Apache Flink in anger. If an organisation cannot package its own logic, version it, test it in CI, and deploy it with a full CI/CD pipeline, it does not have a general-purpose stream processor. It has a stream-enabled query engine with an aggressive marketing page. The system talks only to Kafka topics hosted inside Confluent Cloud. Not a customer’s self-managed Kafka. Not a cluster in a different region. Everything must live within the Confluent perimeter the customer’s data flexibility ends precisely where their vendor’s billing begins. **That’s lock-in with a compliance label.** **Databricks** has a different but equally significant problem. Databricks is genuinely excellent at large-scale batch and analytical processing. But their core offering, Spark Structured Streaming, is explicitly **micro-batching**. When a system processes data every thirty seconds, or every minute, that is not streaming. That is fast batch. Calling it streaming does not change the execution model any more than calling a bus a taxi changes its route. More critically for the sovereignty conversation: Databricks is an exclusively managed cloud service. Customers cannot take the platform and run it on-premise. They cannot drop it into a sovereign private cloud. If a company’s regulatory reality dictates that the data plane must be under explicit institutional control, then “we are very secure in the cloud” is a category mismatch, not an answer. **That’s compliance theatre.** A third market phenomenon is the **diskless Kafka wave**. Systems like WarpStream push all data directly to object storage. The pitch is compelling: stateless compute, cheap scaling, nice economics on paper. The central tradeoff is latency even the vendors are upfront that this class of system is designed for relaxed-latency workloads where a delay of a few seconds does not matter. But this architecture exposes a deep flaw in how the industry thinks about data. It optimises for cheaper storage without asking: what happens to the data once it lands there? If data is streamed into object storage but is not immediately queryable in place, the platform has not solved a problem; it has created future work. The system has turned its storage layer into an operational to-do list for downstream teams. This gap is why every major vendor is racing to bolt transactional tables onto streams. Confluent’s Tableflow is the canonical example: take Kafka topics, convert to Parquet, publish as Iceberg tables. Useful, absolutely. But the user still maintains two systems, an asynchronous conversion step, and lag between the “real” state in the stream and the “queryable” state in the table. They have not eliminated complexity; they have rearranged it. Who does this redundant architecture truly serve? Certainly not the developers building critical business functionality on top of it. The big mistake most streaming platforms make and one that many buyers unwittingly reward is the obsession with **speed**. Speed is sexy. Speed sells. Speed benchmarks well. But speed is rarely the actual problem. The real problem is **efficiency**. Can the work be done without duplicating data across three systems and five pipelines? Once efficiency is addressed, the real problem becomes **access**. Can a user get to their data where it lands, in the format they need, without building yet another pipeline? If a platform cannot provide immediate, efficient access to data where it lands, everything downstream becomes a chain of duplication: duplicate pipelines, duplicate state stores, duplicate logic, duplicate bugs. That is not technological progress. That is architectural debt with a well-funded marketing budget. This is the problem the **Streamhouse** concept was built to solve. The goal is not to force a message broker to pretend to be a database, or coerce a data lake to pretend to be a real-time stream processor. The idea is to stop forcing enterprise users to construct and maintain two separate architectures one for streaming, one for analytics and spend their careers maintaining the fragile, expensive seam between them. **Apache Flink** provides the real stream processing engine: stateful, continuous, programmable, with exactly-once guarantees that hold under pressure. **Apache Paimon** provides the storage layer, built from the ground up for streaming semantics within a familiar, open lakehouse architecture. The customer writes data once, processes it continuously, and queries it immediately without the expense, complexity, and lag of rebuilding or copying it. But the part that matters most the part that transforms this from technology into a real platform is the operational reality: **you run it where you need to run it.** Ververica’s roots are in running Flink as mission-critical software. Our teams created Flink. We have spent the better part of a decade learning how it fails, how it scales, and what it takes to operationalise it for institutions where “it mostly works” is not an acceptable SLA. In the Ververica Unified Streaming Data Platform, jobs are treated as code packaged, versioned, and deployed as traceable artifacts with full CI/CD pipelines and rollback semantics. Not pasted into a proprietary SQL editor and hoped for the best. Deployment is not an afterthought. The platform supports self-managed **on-premise** deployments, **private cloud** installations, and full **Bring-Your-Own-Cloud (BYOC)** deployments built on true Zero Trust principles where the customer’s data stays entirely within their environment. Ververica never sees or touches it. For a detailed look at how these deployment models work in practice, including real-world FSI case studies, see [How Ververica Delivers Sovereignty for Financial Services](/how-ververica-delivers-sovereignty-for-financial-services-industry). **VERA**, our cloud-native engine, provides faster recovery and the ability to scale stateful applications without operational fragility all within your sovereignty perimeter. Built-in data lineage not just table-level, but **field-level column lineage** that traces how individual data attributes flow through transformations and audit-grade traceability are not “nice enterprise features.” They exist because without them, a customer simply cannot answer the questions European regulators are already asking. This is not theoretical. A Tier 1 European bank running Ververica processes over **5 billion events daily** with full jurisdictional lineage, and cut compliance audit preparation from **six weeks to under five days**. That is what sovereignty looks like when it is engineering, not marketing. If you want to cut through the noise, ask boring, fundamental questions. Where does the data plane run? Who controls the runtime? Can I deploy real logic packaged, versioned, tested not just SQL? Can I access my data without copying it into a second system? Can I explain this architecture to a legal auditor without hand-waving? If the answers are vague, conditional, or unavailable, the platform is not real. Confluent Cloud, Amazon MSK, Azure Event Hubs they all make the same sovereignty-breaking choice: centralised control planes you can’t audit, in jurisdictions you can’t control. **That’s lock-in with a compliance label.** Streaming is not a SQL endpoint. It is not a dashboard. It is not a vendor’s promise that “most users do not need that level of control.” It is fundamental infrastructure. And infrastructure either holds up under scale, regulatory pressure, and failure or it does not. Most of what is sold as streaming today does not. **That is the difference between a platform and a performance.** Audit your sovereignty posture now. Download the FSI Data Sovereignty Readiness Checklist to evaluate your streaming platform against DORA, NIS2, and national residency requirements ## Audit Your Sovereignty Posture Now - **Quick assessment:** Download the [FSI Data Sovereignty Readiness Checklist](/streaming-sovereignty-checklist-for-financial-services-industry) to evaluate your streaming platform against DORA, NIS2, and national residency requirements - **Structured evaluation:** Apply the [Sovereignty Evaluation Framework](/fsi-streaming-platform-evaluation-framework), a 26-requirement scored assessment across five sovereignty domains - **Full decision guide:** Read the [FSI Streaming Sovereignty Pillar Page](/fsi-sovereignty-playbook) for a comprehensive framework covering governance, deployment, Zero Trust, and sovereign AI for financial services"
lastUpdated: 2026-03-17T13:39:59.000Z
source_url:
html: "https://www.ververica.com/blog/zero-trust-theater-and-why-most-streaming-platforms-are-pretenders"
md: "https://www.ververica.com/blog/zero-trust-theater-and-why-most-streaming-platforms-are-pretenders.md"
---
## “Zero Trust” used to mean something.
It described a foundational security model where nothing inside the network perimeter was implicitly trusted. Every request regardless of origin had to be authenticated, authorised, and verified. It was an operational architecture that demanded deep, pervasive control over the entire data plane.
Now the term has been weaponised by marketing. It is a logo on a sales slide, a checkbox on a compliance form, a vague corporate promise that someone, somewhere, completed a security review before the product shipped. The architecture of perpetual verification has been hollowed out into branding. **And your vendor knows it.**
The exact same inflation has happened to “streaming platform.”
Everyone in the modern data ecosystem is eager to claim the title. Virtually every vendor now has a product with the word “stream” in its name. But claiming it and building it are two fundamentally different things. What the market is full of is a particular species of software the “streaming pretender” that can talk about streaming, market streaming, and occasionally demo streaming, but falls apart the moment you ask it to do real, production-grade work at planetary scale. Or, worse, it technically performs the single function advertised a quick-start tutorial or a simple pipeline but in a way that becomes economically or operationally useless once you leave the controlled, benign environment of a conference keynote or a sandbox account.
These platforms either cannot sell what they are genuinely capable of doing, or they cannot actually do what they sell. And sometimes, in a remarkable display of product-market dissonance, they fail to achieve both at once.
This matters more now than it did five years ago because the regulatory environment has completely shifted. Regulation is no longer a theoretical risk that can be deferred to a later product roadmap. GDPR is old news. The Digital Operational Resilience Act (DORA) is now in force. NIS2 imposes operational resilience requirements across critical infrastructure. As we laid out in [Data Sovereignty Is Existential Most Platforms Treat It Like a Feature](https://www.ververica.com/blog/data-sovereignty-is-existential-most-platforms-treat-it-like-a-feature), the industry has weaponised “sovereignty” as marketing language. **Your vendor calls it compliance. Regulators call it theater.**
If a platform cannot be deployed and operated precisely where a customer’s data is legally required to live and prove that control to an external auditor under pressure then the polish on its marketing page is irrelevant. Such a platform is not an infrastructure asset; it is a legal and operational liability. It is theatre, not engineering.
A real streaming platform one that can survive the audits, the scale, and the three A.M. outage calls must possess three non-negotiable properties. We must establish these boundaries before the word “platform” loses all remaining meaning in the data space.
## 1. Continuous Compute with Real State
The platform must do **continuous compute with real state**. This is the fundamental distinction between a true stream processor and a fast batch engine. A real platform operates on _event time_ the time the event actually occurred not _processing time_ the time the system happens to pick it up. The idea that “every few minutes is fine for most use cases” is a concession to an underlying architecture that cannot handle continuous data flow.
A real platform must handle **backpressure** gracefully, preventing catastrophic cascade failures. It must provide **exactly-once semantics** where they actually matter: not in a lab environment, but in production, during a partial system failure, at three in the morning when a downstream system is experiencing a brownout. It must manage **long-lived state** that survives total failure and orchestrated restarts without the operator having to rebuild the universe or lose the computation’s progress. Anything that requires a cron job, a manual restart, or risks double-counting data is a batch engine pretending to be a stream processor.
## 2. Usable Data Storage
The platform must store processed data in a way that remains immediately and reliably usable. If the vendor’s primary answer to the storage question is a variant of “we dump it into cheap object storage and figure out how to access it later,” they have not solved the problem of durable, accessible state. They are deferring it.
This deferral guarantees manual reprocessing, data duplication across systems, and data drift between the processing and storage layers. If an engineer must build another ETL pipeline just to make the first pipeline’s output readable by a BI tool, then the storage layer is not infrastructure. It is delayed pain, with the added insult of a high cloud bill. Effective streaming infrastructure must unify storage and processing to ensure low-latency access and prevent unmanageable, siloed data copies.
## 3. Control That Survives an Audit
The platform must give the customer **control that survives an audit**. This is the heart of the sovereignty discussion. The questions are straightforward, but the answers from most vendors are evasive: Where exactly does the data plane run? Who controls the runtime environment? Who holds the encryption keys? Who patches, upgrades, and isolates the system without calling a vendor’s support line?
**If proving sovereignty requires a call to your vendor’s support team, you don’t have sovereignty. You have a dependency.** For any regulated enterprise particularly in finance or government the ability to demonstrate institutional control over data and execution environment is non-negotiable. Anything below these three properties is merely theatre.
> **INFO:** For a deeper look at what true sovereignty means for financial services, including the three pillars regulators actually evaluate, read our FSI Streaming Sovereignty Pillar Page.
We can observe how this theatre plays out across the market.
**Confluent Cloud’s Flink Offering** is a prime example: a query engine in streaming clothes. On paper, they license Apache Flink. In practice, the entire experience is built around submitting constrained SQL statements to a managed service. Developers are not deploying Flink jobs as independently versioned, traceable artifacts. They are asking a proprietary service to run a pre-defined set of queries on their behalf.
There is zero support for shipping custom JAR files containing application-specific logic. That limitation alone should end the discussion for anyone who has operated Apache Flink in anger. If an organisation cannot package its own logic, version it, test it in CI, and deploy it with a full CI/CD pipeline, it does not have a general-purpose stream processor. It has a stream-enabled query engine with an aggressive marketing page.
The system talks only to Kafka topics hosted inside Confluent Cloud. Not a customer’s self-managed Kafka. Not a cluster in a different region. Everything must live within the Confluent perimeter the customer’s data flexibility ends precisely where their vendor’s billing begins. **That’s lock-in with a compliance label.**
**Databricks** has a different but equally significant problem. Databricks is genuinely excellent at large-scale batch and analytical processing. But their core offering, Spark Structured Streaming, is explicitly **micro-batching**. When a system processes data every thirty seconds, or every minute, that is not streaming. That is fast batch. Calling it streaming does not change the execution model any more than calling a bus a taxi changes its route.
More critically for the sovereignty conversation: Databricks is an exclusively managed cloud service. Customers cannot take the platform and run it on-premise. They cannot drop it into a sovereign private cloud. If a company’s regulatory reality dictates that the data plane must be under explicit institutional control, then “we are very secure in the cloud” is a category mismatch, not an answer. **That’s compliance theatre.**
A third market phenomenon is the **diskless Kafka wave**. Systems like WarpStream push all data directly to object storage. The pitch is compelling: stateless compute, cheap scaling, nice economics on paper. The central tradeoff is latency even the vendors are upfront that this class of system is designed for relaxed-latency workloads where a delay of a few seconds does not matter.
But this architecture exposes a deep flaw in how the industry thinks about data. It optimises for cheaper storage without asking: what happens to the data once it lands there? If data is streamed into object storage but is not immediately queryable in place, the platform has not solved a problem; it has created future work. The system has turned its storage layer into an operational to-do list for downstream teams.
This gap is why every major vendor is racing to bolt transactional tables onto streams. Confluent’s Tableflow is the canonical example: take Kafka topics, convert to Parquet, publish as Iceberg tables. Useful, absolutely. But the user still maintains two systems, an asynchronous conversion step, and lag between the “real” state in the stream and the “queryable” state in the table. They have not eliminated complexity; they have rearranged it. Who does this redundant architecture truly serve? Certainly not the developers building critical business functionality on top of it.
The big mistake most streaming platforms make and one that many buyers unwittingly reward is the obsession with **speed**. Speed is sexy. Speed sells. Speed benchmarks well.
But speed is rarely the actual problem.
The real problem is **efficiency**. Can the work be done without duplicating data across three systems and five pipelines? Once efficiency is addressed, the real problem becomes **access**. Can a user get to their data where it lands, in the format they need, without building yet another pipeline?
If a platform cannot provide immediate, efficient access to data where it lands, everything downstream becomes a chain of duplication: duplicate pipelines, duplicate state stores, duplicate logic, duplicate bugs. That is not technological progress. That is architectural debt with a well-funded marketing budget.
This is the problem the **Streamhouse** concept was built to solve.
The goal is not to force a message broker to pretend to be a database, or coerce a data lake to pretend to be a real-time stream processor. The idea is to stop forcing enterprise users to construct and maintain two separate architectures one for streaming, one for analytics and spend their careers maintaining the fragile, expensive seam between them.
**Apache Flink** provides the real stream processing engine: stateful, continuous, programmable, with exactly-once guarantees that hold under pressure. **Apache Paimon** provides the storage layer, built from the ground up for streaming semantics within a familiar, open lakehouse architecture. The customer writes data once, processes it continuously, and queries it immediately without the expense, complexity, and lag of rebuilding or copying it.
But the part that matters most the part that transforms this from technology into a real platform is the operational reality: **you run it where you need to run it.**
Ververica’s roots are in running Flink as mission-critical software. Our teams created Flink. We have spent the better part of a decade learning how it fails, how it scales, and what it takes to operationalise it for institutions where “it mostly works” is not an acceptable SLA. In the Ververica Unified Streaming Data Platform, jobs are treated as code packaged, versioned, and deployed as traceable artifacts with full CI/CD pipelines and rollback semantics. Not pasted into a proprietary SQL editor and hoped for the best.
Deployment is not an afterthought. The platform supports self-managed **on-premise** deployments, **private cloud** installations, and full **Bring-Your-Own-Cloud (BYOC)** deployments built on true Zero Trust principles where the customer’s data stays entirely within their environment. Ververica never sees or touches it. For a detailed look at how these deployment models work in practice, including real-world FSI case studies, see [How Ververica Delivers Sovereignty for Financial Services](https://www.ververica.com/how-ververica-delivers-sovereignty-for-financial-services-industry).
**VERA**, our cloud-native engine, provides faster recovery and the ability to scale stateful applications without operational fragility all within your sovereignty perimeter. Built-in data lineage not just table-level, but **field-level column lineage** that traces how individual data attributes flow through transformations and audit-grade traceability are not “nice enterprise features.” They exist because without them, a customer simply cannot answer the questions European regulators are already asking.
This is not theoretical. A Tier 1 European bank running Ververica processes over **5 billion events daily** with full jurisdictional lineage, and cut compliance audit preparation from **six weeks to under five days**. That is what sovereignty looks like when it is engineering, not marketing.
If you want to cut through the noise, ask boring, fundamental questions. Where does the data plane run? Who controls the runtime? Can I deploy real logic packaged, versioned, tested not just SQL? Can I access my data without copying it into a second system? Can I explain this architecture to a legal auditor without hand-waving?
If the answers are vague, conditional, or unavailable, the platform is not real.
Confluent Cloud, Amazon MSK, Azure Event Hubs they all make the same sovereignty-breaking choice: centralised control planes you can’t audit, in jurisdictions you can’t control. **That’s lock-in with a compliance label.**
Streaming is not a SQL endpoint. It is not a dashboard. It is not a vendor’s promise that “most users do not need that level of control.” It is fundamental infrastructure. And infrastructure either holds up under scale, regulatory pressure, and failure or it does not.
Most of what is sold as streaming today does not.
**That is the difference between a platform and a performance.**
Audit your sovereignty posture now. Download the FSI Data Sovereignty Readiness Checklist to evaluate your streaming platform against DORA, NIS2, and national residency requirements
## Audit Your Sovereignty Posture Now
- **Quick assessment:** Download the [FSI Data Sovereignty Readiness Checklist](https://www.ververica.com/streaming-sovereignty-checklist-for-financial-services-industry) to evaluate your streaming platform against DORA, NIS2, and national residency requirements
- **Structured evaluation:** Apply the [Sovereignty Evaluation Framework](https://www.ververica.com/fsi-streaming-platform-evaluation-framework), a 26-requirement scored assessment across five sovereignty domains
- **Full decision guide:** Read the [FSI Streaming Sovereignty Pillar Page](https://www.ververica.com/fsi-sovereignty-playbook) for a comprehensive framework covering governance, deployment, Zero Trust, and sovereign AI for financial services
---
---
title: "No False Trade-Offs: Introducing Ververica Bring Your Own Cloud for Microsoft Azure"
description: "Ververica introduces BYOC for Azure, delivering enterprise-grade streaming data orchestration without compromising control, security, or costs."
lastUpdated: 2026-03-17T13:41:01.000Z
source_url:
html: "https://www.ververica.com/blog/no-false-trade-offs-introducing-ververica-bring-your-own-cloud-for-microsoft-azure"
md: "https://www.ververica.com/blog/no-false-trade-offs-introducing-ververica-bring-your-own-cloud-for-microsoft-azure.md"
---
## Azure customers demand it. In 2026, Ververica delivers.
[Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product), powered by [VERA](https://www.ververica.com/vera), the cloud-native engine that revolutionizes [Apache Flink®](https://www.ververica.com/what-is-apache-flink), is now available directly inside your Azure infrastructure with [Bring Your Own Cloud (BYOC)](https://www.ververica.com/deployment/bring-your-own-cloud) deployment.
## Your Environment, Our Platform
Most "managed services" force a choice: control or convenience. That's a false trade-off built on old assumptions. BYOC doesn't ask you to pick. You get enterprise-grade streaming data orchestration without surrendering data residency, network security, or cloud spending control.
While others make you choose, Ververica delivers both. For data teams building real-time systems on Azure, this changes everything.
## Cloud Economic and Security Problems: Three Constraints, One Solution.
Organizations running stream processing workloads on Azure don’t face technical challenges. They face institutional truths:
- **Data residency and compliance aren’t optional.**
Regulated industries can’t afford ambiguity. Data must stay within specific geographic boundaries and security perimeters. Moving streaming workloads to external SaaS platforms doesn’t just create compliance risk, it results in compliance failure.
- **Cloud economics aren’t negotiable.**
Enterprises commit millions to Azure consumption agreements and negotiate preferential pricing for a reason. Other managed data platforms ask them to pay full SaaS list prices while their existing Azure commitments sit unused. That’s not a technical limitation, it's a bad deal.
- **Zero-trust architecture isn’t a suggestion.**
Security teams don’t mandate network isolation and prohibit external data egress because they’re cautious. They do it because breaches are a “when, not if” situation. Traditional Saas models that require data to leave your corporate perimeters don’t just fail to comply with zero-trust principles, they violate them entirely.
Built for industries where real-time decisions and compliance requirements are business-essential: **Financial Services. Healthcare. Telecom. Government.** These aren’t edge cases. These are industries where stream processing is mission-critical. Where latency costs money. Where governance isn’t a feature, it’s the foundation of the business itself. You don’t need workarounds. You need what only Ververica’s Bring Your Own Cloud delivers.
## How BYOC Works: Your Infrastructure, Managed by Ververica
Ververica’s BYOC deployment runs entirely inside your Azure subscription. We manage the platform operations through a secure control plane connection.
No ambiguity. No exceptions. No data egress.
- **Your Azure environment = Your control.**
The VERA-powered stream processing cluster deploys in your Azure environment, in your selected region. Data stays in your Azure Blob Storage. Processing happens on your compute resources. You retain full control over network configuration, IAM policies, and resource access.
- **Ververica's control plane = Your operational advantage.**
Through a secure control plane connection, Ververica orchestrates your compute resources, manages your stream processing jobs, monitors deployment and cluster health, performs operational tasks, and handles software upgrades.
The connection is designed and purpose built for zero-trust security: Your cluster connects to Ververica's control plane **only** for deployment management. No stream processing data leaves your environment. Ever.
**This is the architecture enterprises demand:** The operational simplicity of a managed service, with the security and cost benefits of a self-hosted infrastructure.
**This isn’t a compromise between two bad options. This is both, finally done right.**
## Three Core Benefits of BYOC
### Benefit One: Zero-Trust Security and Absolute Data Residency
BYOC doesn’t adopt zero-trust security principles. It enforces them by design and architecture.
Your data never leaves your Azure environment. Not “most data”. Not “processing data.” **All data.** Your event streams, state checkpoints, processing results all stay in your Blob Storage, governed by your access policies and your encryption keys.
The cluster operates entirely within your network. BYOC runs inside your Azure environment, so no additional secure access over the internet is required. Network access to Ververica's control plane is outbound-only and limited to deployment management APIs.
**No inbound connections. No data egress. Full compliance with data sovereignty requirements.**
This isn’t simply a feature, it’s the very foundation.
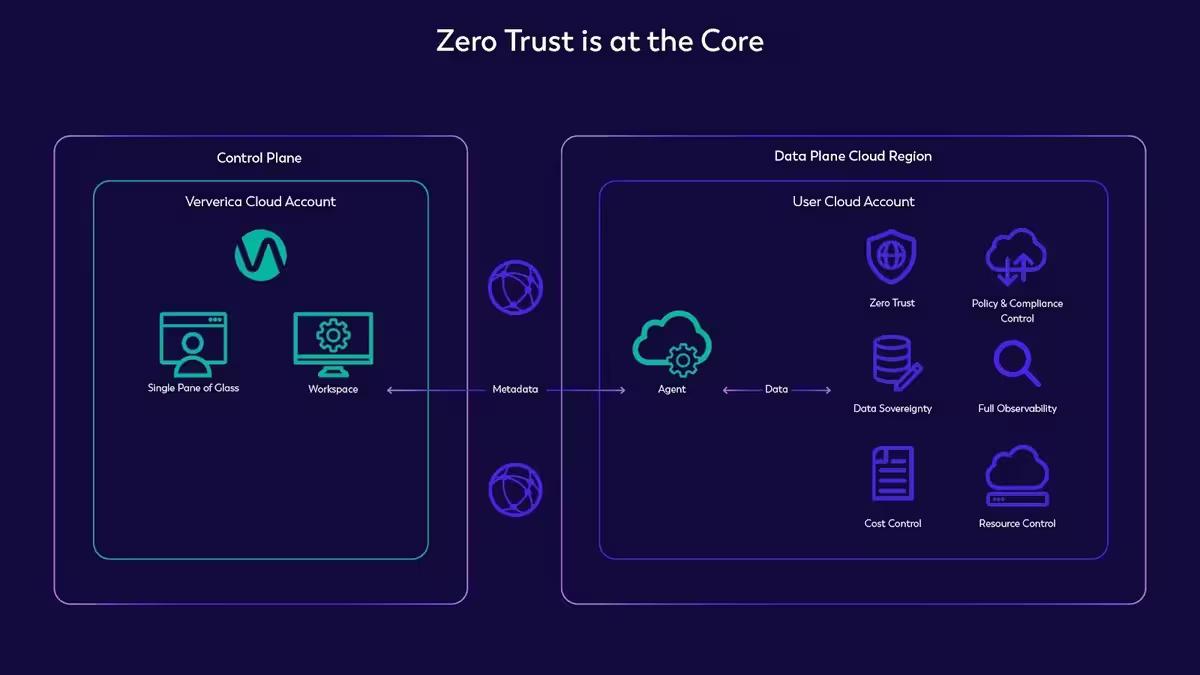
## Benefit Two: Cloud Cost Optimization Through Azure Spend
BYOC lets you apply your Azure consumption commitments and negotiated discounts to your stream processing infrastructure. You consume your own Azure resources (compute, storage, and networking) at your contracted rates.
Not third-party Saas list pricing. **Your pricing.**
For enterprises with large Azure commitments, this approach eliminates the absurd economics of paying external SaaS vendors while leaving your previously committed Azure spend on the table.
Billing runs through Azure Marketplace, consolidating your stream processing platform subscription with existing Azure procurement and invoicing. This means you have one vendor relationship and one invoice, with no procurement friction.
## Benefit Three: Native Integration with Azure Services
BYOC deployments integrate directly with Azure-native services within your network. Your stream processing workloads connect to Azure Event Hubs for event ingestion, Azure Blob Storage for lakehouse architectures, and Azure PostgreSQL, and MySQL for enrichment and sinks.
All connectivity happens within your Azure environment. No public internet traversal. No unnecessary data transfer costs. No architectural compromises because your data platform lives somewhere else. This is what native integration really means.
## Flexible Pricing Through Azure Marketplace
Ververica Cloud BYOC is available through Azure Marketplace with flexible commitment options. We don’t force you into pricing models that don’t match your business reality.
- **Pay-As-You-Go:** Usage-based pricing with no upfront commitment. Scale when you need to. Pay for what you actually use.
- **Monthly and Annual Plans:** Predictable pricing for steady-state workloads. No surprises. No overage penalties.
- **Multi-Year Commitments:** Volume discounts for long-term strategic deployments. Reward commitment with economics that make sense.
All subscriptions consolidate into your existing Azure billing. Payments process through your Microsoft commercial agreements. No procurement theater. No separate invoicing headaches.
Ververica makes this easy, with one platform, one marketplace, and one bill.
## Built on VERA: Performance at Scale
BYOC deployments run on [VERA](https://www.ververica.com/vera), Ververica's proprietary engine built by the original creators of [Apache Flink](https://www.ververica.com/what-is-apache-flink). We didn’t just optimize Flink for cloud-native performance. We perfected it.
- Up to 2x faster processing compared to open-source Flink. Not just in benchmarks. In production.
- Native support for lakehouse architectures with [Apache Paimon](https://www.ververica.com/what-is-apache-paimon). Real-time analytics on cost-effective storage without architectural gymnastics.
- Dynamic complex event processing capabilities. Pattern detection and stream reasoning that adapts in real time, not in the next batch window.
Whether you're processing millions of events per second for [fraud detection](https://www.ververica.com/use-case/fraud-detection), building real-time [customer 360 analytics](https://www.ververica.com/use-case/customer-360), or powering [agentic AI systems](https://www.ververica.com/use-case/ai-ml)with real-time inference, BYOC delivers enterprise-grade performance without operational overhead.Most data platforms make you choose between speed and manageability. VERA eliminates the question completely. This is what stream processing looks like when the people who invented it build it for production.
## Get Started
Ververica’s Unified Streaming Data Platform on Azure is available now.
## Existing Ververica Customers
Enable BYOC deployments from the Ververica Cloud console:
1. Deploy your cluster into your Azure environment
1. Subscribe to a BYOC Azure subscription, and link it to your Ververica Cloud account
1. Connect your cluster to your Ververica Cloud account
1. Start deploying your stream processing jobs!
## New to Ververica
Subscribe through [Azure Marketplace](https://marketplace.microsoft.com/en-us/product/saas/ververica.vvc_byoc) to start a trial deployment. You'll need an active Ververica Cloud account and an Azure subscription.
Follow the helpful [Getting Started](https://docs.ververica.com/byoc/getting-started/azure/prerequisites/) guide in Ververica’s documentation, or [talk](https://www.ververica.com/contact) to our solutions team.
- [View Azure Marketplace Listing](https://marketplace.microsoft.com/en-us/product/saas/ververica.vvc_byoc)
- Get Started: [BYOC Deployment Guide](https://docs.ververica.com/byoc/getting-started/)
- [Talk to Our Solutions Team](https://www.ververica.com/contact)
## More Resources
Learn more about Ververica’s Unified Streaming Data Platform Bring Your Own Cloud Deployment
[Data Sovereignty](https://www.ververica.com/sovereignty) - Your Real-Time Data Doesn't Belong in American Cloud Hands
Bring Your Own Cloud on [Ververica’s Blog](https://www.ververica.com/blog):
- [Introducing Ververica's Bring Your Own Cloud (BYOC) Deployment Offering](https://www.ververica.com/blog/introducing-byoc-deployment)
- [Your Cloud, Your Rules: Ververica's Bring Your Own Cloud Deployment](https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment)
- [Zero Trust Security with Ververica's Bring Your Own Cloud Deployment. Part One: The Road to Zero Trust](https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-part-one)
- [Zero Trust Security with Ververica's Bring Your Own Cloud Deployment. Part Two: Practical Security Improvements](https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-part-two)
- [Maximize Efficiency: How Ververica's BYOC Deployment Optimizes CAPEX and OPEX](https://www.ververica.com/blog/maximize-efficiency-how-ververicas-byoc-optimizes-capex-and-opex)
[Watch the Video](https://www.youtube.com/watch?v=2tdsGs6jXYM): Zero Trust or Bust Bring Your Own Cloud to Real Time Data
---
---
title: "Data Sovereignty Is Existential Most Platforms Treat It Like a Feature"
description: "DORA and NIS2 demand provable data sovereignty. Most streaming platforms fail this test. Learn why architecture and not contracts delivers real control."
lastUpdated: 2026-03-17T13:40:59.000Z
source_url:
html: "https://www.ververica.com/blog/data-sovereignty-is-existential-most-platforms-treat-it-like-a-feature"
md: "https://www.ververica.com/blog/data-sovereignty-is-existential-most-platforms-treat-it-like-a-feature.md"
---
European financial institutions spent two decades migrating to the cloud. In doing so, they traded something they didn’t realise was on the table: control. Not dashboard-level visibility. Not SLA-grade assurances. **Actual, provable, regulatory-grade control** over where data lives, who touches it, and what happens when things break.
That trade wasn’t deliberate. It was architectural. Most streaming platforms were designed when sovereignty was a geopolitical term, not a technical requirement. They optimised for throughput. Sovereignty was an afterthought. And your vendor knows it.
In 2026, [DORA is live](https://www.eiopa.europa.eu/digital-operational-resilience-act-dora_en). NIS2 is transposing across member states. National residency laws are multiplying. Every one of these regulations asks the same question: _**Can you prove you control your data?**_
Not “do you have a policy.” Not “does your vendor claim compliance.” Can you demonstrate under audit, in real time that your data never leaves your jurisdiction and your processing stays within your governance perimeter?
For most FSI organisations running on Confluent Cloud, Amazon MSK, or Azure Event Hubs, the honest answer is no. That’s not a feature gap. It’s a structural one.
## The Regulatory Reckoning
**DORA** (Regulation 2022/2554) mandates full visibility and control over ICT systems, including third-party providers. [Article 28 demands](https://www.digital-operational-resilience-act.com/Article_28.html) audit rights, data access guarantees, and exit strategies for every critical ICT provider. Technical standards require automated incident detection within four hours. If your streaming infrastructure runs in a hyperscaler’s managed service and an incident occurs, you must independently verify what happened, when, and to which data. DORA doesn’t care about your vendor’s compliance certifications. It cares about **your** ability to prove control.
**NIS2** makes the consuming organisation accountable for its entire supply chain’s sovereignty posture. Every managed service, every cross-border data flow is a node in your compliance perimeter. If your event broker routes data through a region where you have no legal standing, that’s your risk, not your vendor’s.
**National residency laws** fragment the picture further. France’s SecNumCloud, Germany’s BSI requirements, country-specific GDPR interpretations a pan-European institution doesn’t need “EU sovereignty.” It needs jurisdictional isolation at the processing level, provable at the record level, switchable without re-architecting.
## What Sovereignty Actually Requires
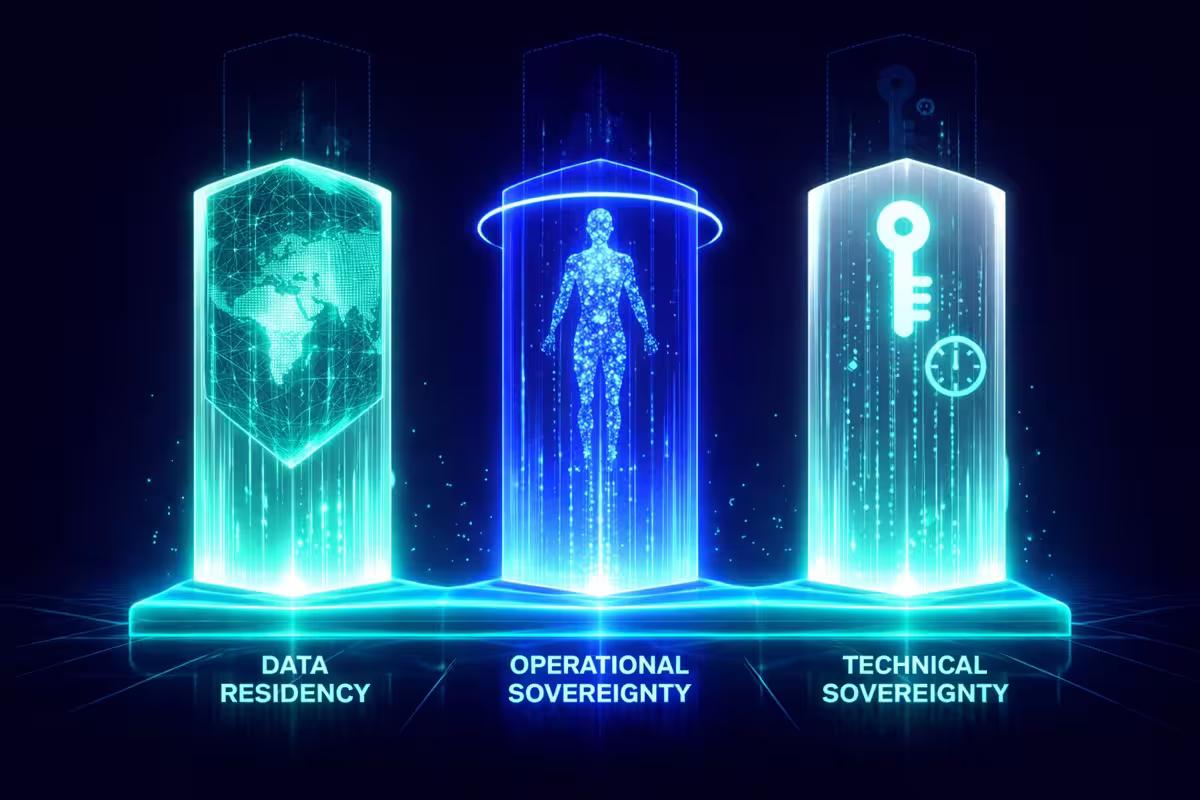
The industry has let “sovereignty” become marketing language. Vendors use it to mean “hosted in Frankfurt” or “encrypted at rest.” That’s compliance theatre. When regulators probe, they mean three things:
**Data residency** means _all_ data operational data, logs, configuration state, metadata stays in your governed jurisdiction. Hosting data in the EU while the control plane phones home to Virginia isn’t residency. It’s a marketing claim.
**Operational sovereignty** means the humans and systems operating your infrastructure are within your legal jurisdiction. If a US-headquartered provider holds admin access to your streaming cluster, you’re exposed to jurisdictional reach that regulators treat as a violation.
**Technical sovereignty** means producing auditable evidence of both in real time, under pressure, during an incident. Architectural guarantees, not contractual promises. Encryption keys you hold. Audit logs you generate independently.
If proving sovereignty requires a call to your vendor’s support team, you don’t have sovereignty. You have a dependency.
## Why Managed Platforms Fail This Test
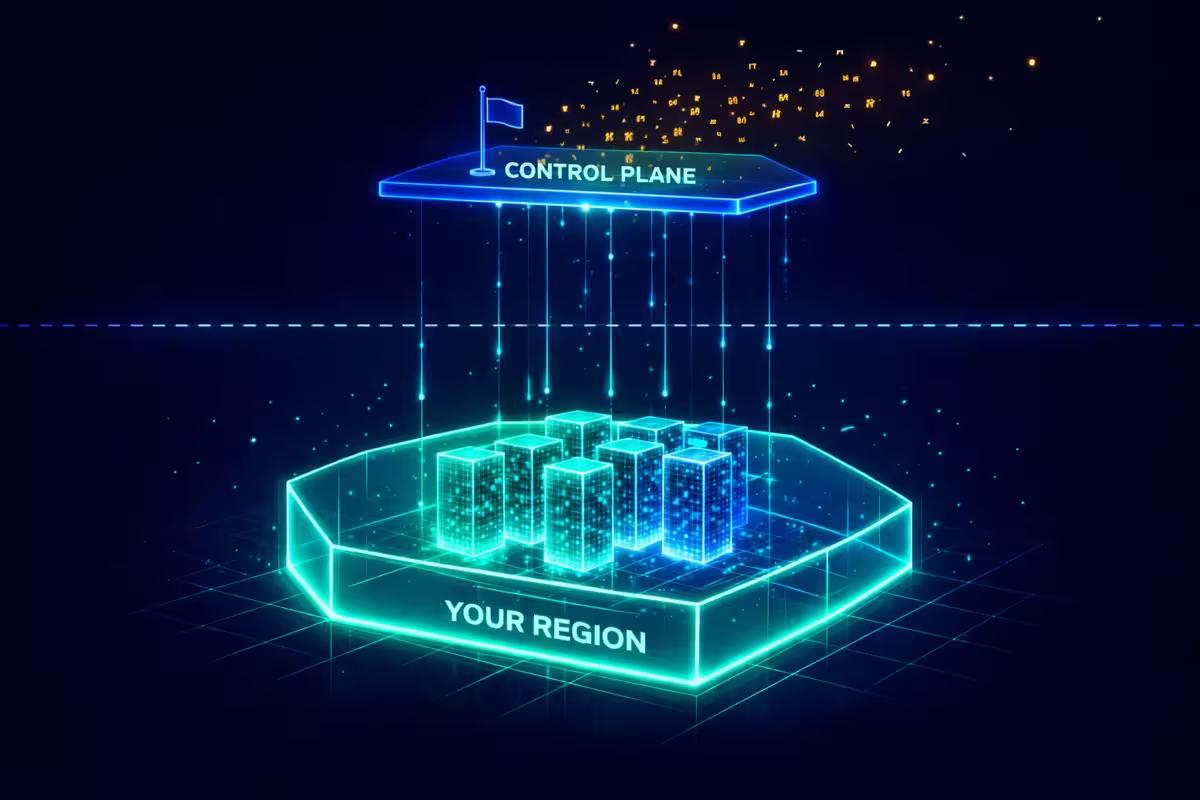
Confluent Cloud, AWS Managed Flink, Azure Event Hubs they all make the same sovereignty-breaking choice: **centralised control planes you can’t audit**. Provisioning, scaling, monitoring, access management all flow through infrastructure the customer doesn’t control. If the control plane sits outside your sovereignty boundary, your data’s sovereignty is a contractual fiction.
Even when data stays in-region, metadata often doesn’t. Topic names, schema registries, consumer group offsets, telemetry these artefacts routinely cross jurisdictional boundaries. Under GDPR and DORA, metadata leakage is a compliance exposure most vendors don’t even acknowledge.
And when DORA asks for your exit strategy? If your platform is coupled to proprietary APIs and tooling, your “exit” is a multi-year migration. That’s not a contingency plan. That’s lock-in with a compliance label.
## Sovereignty as Architecture: The Ververica Approach
Sovereignty isn’t solved by choosing the right cloud region. It’s solved by choosing an architecture where control is structural, not contractual. That’s what we built Ververica’s Unified Streaming Data Platform to deliver.
**Deploy where sovereignty demands.** [Ververica Platform runs self-managed on your infrastructure](https://www.ververica.com/deployment/self-managed), in your jurisdiction, under your operational control. [Our Bring Your Own Cloud (BYOC)](https://www.ververica.com/deployment/bring-your-own-cloud) deployment was engineered from the ground up around [Zero Trust principles](https://www.ververica.com/blog/introducing-byoc-deployment): your data stays in your cloud environment, governed by your policies, with no vendor-side data exfiltration.
For institutions that require air-gapped or on-premise deployment, the same [VERA engine runs identically](https://www.ververica.com/vera). No phone-home. No metadata leakage. No jurisdictional ambiguity. That’s the architectural guarantee DORA Article 28 demands not a contractual promise.
**Field-level lineage and governance built in.** Open-source Flink processes events. Ververica governs them. Our platform provides built-in data lineage not just table-level, but **field-level column lineage** that traces how individual data attributes flow through transformations, across pipelines, in real time. When a regulator asks “which fields of customer data were processed, by which pipeline, in which jurisdiction?” Ververica answers that from its own governance layer. Not from a vendor’s dashboard. Not from a reconstructed batch log. A Tier 1 European bank running Ververica processes over 5 billion events daily with full jurisdictional lineage and cut compliance audit preparation from six weeks to under five days.
**Enterprise-grade state management under your control.** VERA, our cloud-native engine, replaces open-source Flink’s RocksDB state backend with Gemini a purpose-built state engine that disaggregates compute and storage for faster checkpointing, faster recovery, and the ability to scale large stateful applications without the operational fragility that comes with vanilla Flink deployments. Crucially, Gemini’s state stays within your deployment boundary. Your application state the beating heart of any streaming pipeline never leaves your sovereignty perimeter.
**True portability. Real exit strategy.** VERA is 100% compatible with Apache Flink. Your applications run without modification across any infrastructure that supports the platform on-premise, private cloud, BYOC. That’s a DORA exit strategy you can execute in weeks, not one that exists only in a contract addendum.
We created Apache Flink. We’ve spent a decade operationalising it for institutions that cannot compromise on sovereignty, performance, or control. Ververica exists because we understood before the regulations forced the conversation that sovereignty is not a feature to bolt on. It’s the architectural foundation everything else depends on.
## The Path Forward
Sovereignty is binary. You either have architectural control over your data where it lives, who operates it, how you prove both or you don’t. Treating it as a roadmap item or a contractual assurance is strategic malpractice in 2026’s regulatory environment.
The institutions that act now build on foundations that support their regulatory obligations and their competitive position. The ones that don’t will discover, during their first serious audit, that “compliant on paper” and “sovereign in practice” aren’t the same and that regulators know the difference.
> **INFO:** Audit your sovereignty posture now. Download the FSI Data Sovereignty Readiness Checklist to evaluate your streaming platform against DORA, NIS2, and national residency requirements.
## Related Resources from Our FSI Streaming Sovereignty Campaign
This blog post is part of a comprehensive content series on streaming sovereignty for financial services. Explore the full campaign:
[The Control Illusion: What Vendor-Managed Platforms Hide](https://www.ververica.com/fsi-streaming-sovereignty-one-pager) A visual one-pager that makes the "managed means vendor-controlled" argument visual. See vendor promises vs. operational reality side by side.
[Zero Trust Theater: Why Most Streaming Platforms Are Pretenders](https://www.ververica.com/blog/zero-trust-theater-and-why-most-streaming-platforms-are-pretenders) The companion blog going deeper on why "Zero Trust" and "streaming platform" have been hollowed out by marketing. Examines Confluent Cloud, Databricks, and WarpStream against the three non-negotiable properties of a real platform.
[Streaming Sovereignty Checklist for Financial Services](https://www.ververica.com/streaming-sovereignty-checklist-for-financial-services-industry) A 27-requirement self-assessment to evaluate your platform's sovereignty posture against DORA, NIS2, GDPR, and EU AI Act requirements.
[How Ververica Delivers Sovereignty for Financial Services](https://www.ververica.com/how-ververica-delivers-sovereignty-for-financial-services-industry) The detailed product/solution page covering deployment models, native governance architecture, Zero Trust security implementation, and real-world FSI case studies including a global bank mainframe offloading and Humn.ai insurance risk assessment.
[FSI Streaming Sovereignty: The Complete Guide](https://www.ververica.com/fsi-sovereignty-playbook) The comprehensive pillar page tying everything together: what sovereignty means for FSI, Tier 1 vs Tier 2 requirements, the three pillars framework, sovereign AI, vendor evaluation criteria, and the Ververica solution.
---
---
title: "Dual Pipelines Are Done. Ververica Unifies Batch and Streaming."
description: "Ververica unifies batch and streaming data execution, eliminating pipeline duplication, reducing complexity, and rebuilding trust with Materialized Tables."
lastUpdated: 2026-03-17T13:41:09.000Z
source_url:
html: "https://www.ververica.com/blog/dual-pipelines-are-done-ververica-unifies-batch-and-streaming"
md: "https://www.ververica.com/blog/dual-pipelines-are-done-ververica-unifies-batch-and-streaming.md"
---
## Introducing Materialized Tables, Freshness-Driven Execution, and the End of Pipeline Duplication
Why are you running two completely separate data platforms when they're supposed to represent the same truth?
One pipeline runs continuously for real-time dashboards. Another runs on a schedule for historical analytics. They start with the same intent but drift apart in logic, semantics, and timing. Your real-time fraud detection shows different numbers than yesterday's compliance report. Your streaming customer 360 doesn't match your batch ML training data.
This isn't a "technology preference." **It's organizational cost, decision risk, and wasted engineering effort.**
Data teams spend more time reconciling pipelines than deriving insights. Analysts need to understand both streaming and batch semantics just to trust the numbers. Engineers maintain duplicate logic across Apache Spark™ and Apache Flink®. Business leaders stop trusting dashboards because the numbers keep changing.
**The root cause is simple**: your data architecture treats streaming and batch as separate problems when they should be unified expressions of the same intent.
Today, we're solving this.
## What We're Announcing
Ververica now delivers true unified streaming and batch execution with a new set of capabilities that eliminate pipeline duplication, reduce operational complexity, and rebuild trust in your data, including:
- **Materialized Tables:** Define tables once using SQL; the platform maintains them over time
- **Freshness-Driven Execution:** Declare how up-to-date data must be let the platform choose the execution strategy
- **Built-In Workflow Scheduling:** Bounded refreshes are planned and scheduled automatically
- **Resource Queue Management:** Always-on workloads are protected and batch work runs safely
- **Unified Streaming and Batch Semantics:** One platform, one set of rules
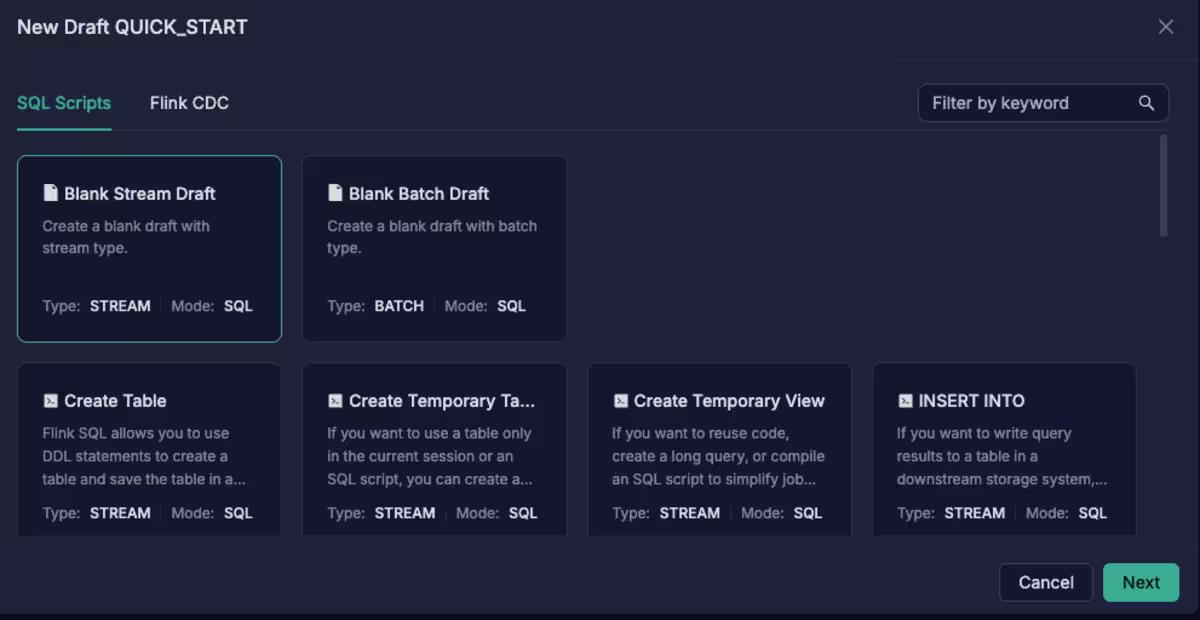
Also new in this release:
- Apache Iceberg Catalog support
- Delta Lake Connector
- Databricks Unity Catalog integration
This release fundamentally changes how you build, operate, and trust data pipelines. You no longer manage separate streaming and batch systems. You define what you want, and the platform handles the execution.
## The Problem: Two Systems for One Truth
Across every industry, data teams face the same challenge: two sets of pipelines that should represent one source of truth but don't.
Here's what that looks like in practice across industries:
**Financial Services**:
Your streaming fraud detection pipeline flags suspicious transactions in real-time. Your batch ML training pipeline recomputes fraud patterns nightly. The business logic should be identical, but they're implemented in different systems (Flink for streaming, Spark for batch). Over time, they drift. Your fraud model is trained on data that doesn't match production detection logic. **The result? False positives spike, compliance violations occur.**
**Retail & E-Commerce:**
Your real-time customer 360 dashboard updates continuously. Your batch analytics pipeline runs nightly for marketing campaigns. Same customer data, different numbers. Marketing sends campaigns based on yesterday's batch run while support sees today's real-time view. **Your teams are making decisions on inconsistent data.**
**Manufacturing & IoT**:
Streaming pipelines monitor machine sensor data for predictive maintenance. Batch pipelines analyze historical patterns for capacity planning. When the numbers don't match, you're either over-maintaining equipment (wasting money) or under-maintaining (risking downtime and safety).
The costs pile up fast:
- **Duplicate engineering effort:** Write the same business logic twice, maintain two codebases
- **Semantic drift:** Real-time and historical views diverge over time, eroding trust
- **Operational complexity:** Manage schedules, backfills, dependencies across two systems
- **Cognitive burden:** Analysts must understand both streaming and batch semantics
- **Hidden risk:** Inconsistent data leads to bad decisions, compliance failures
This isn't about having the wrong tools. **It's about having an architecture that treats streaming and batch as separate worlds when they should be unified.**
## The Solution: Table-Centric, Freshness-Driven Unification
Ververica solves this by collapsing the divide between streaming and batch entirely. One platform. One definition. One source of truth.
Here's how it works:
### Materialized Tables: Define Once, Trust Forever
Instead of building separate pipelines for streaming and batch, you define a Materialized Table once using SQL. That definition becomes a contract the platform maintains over time.
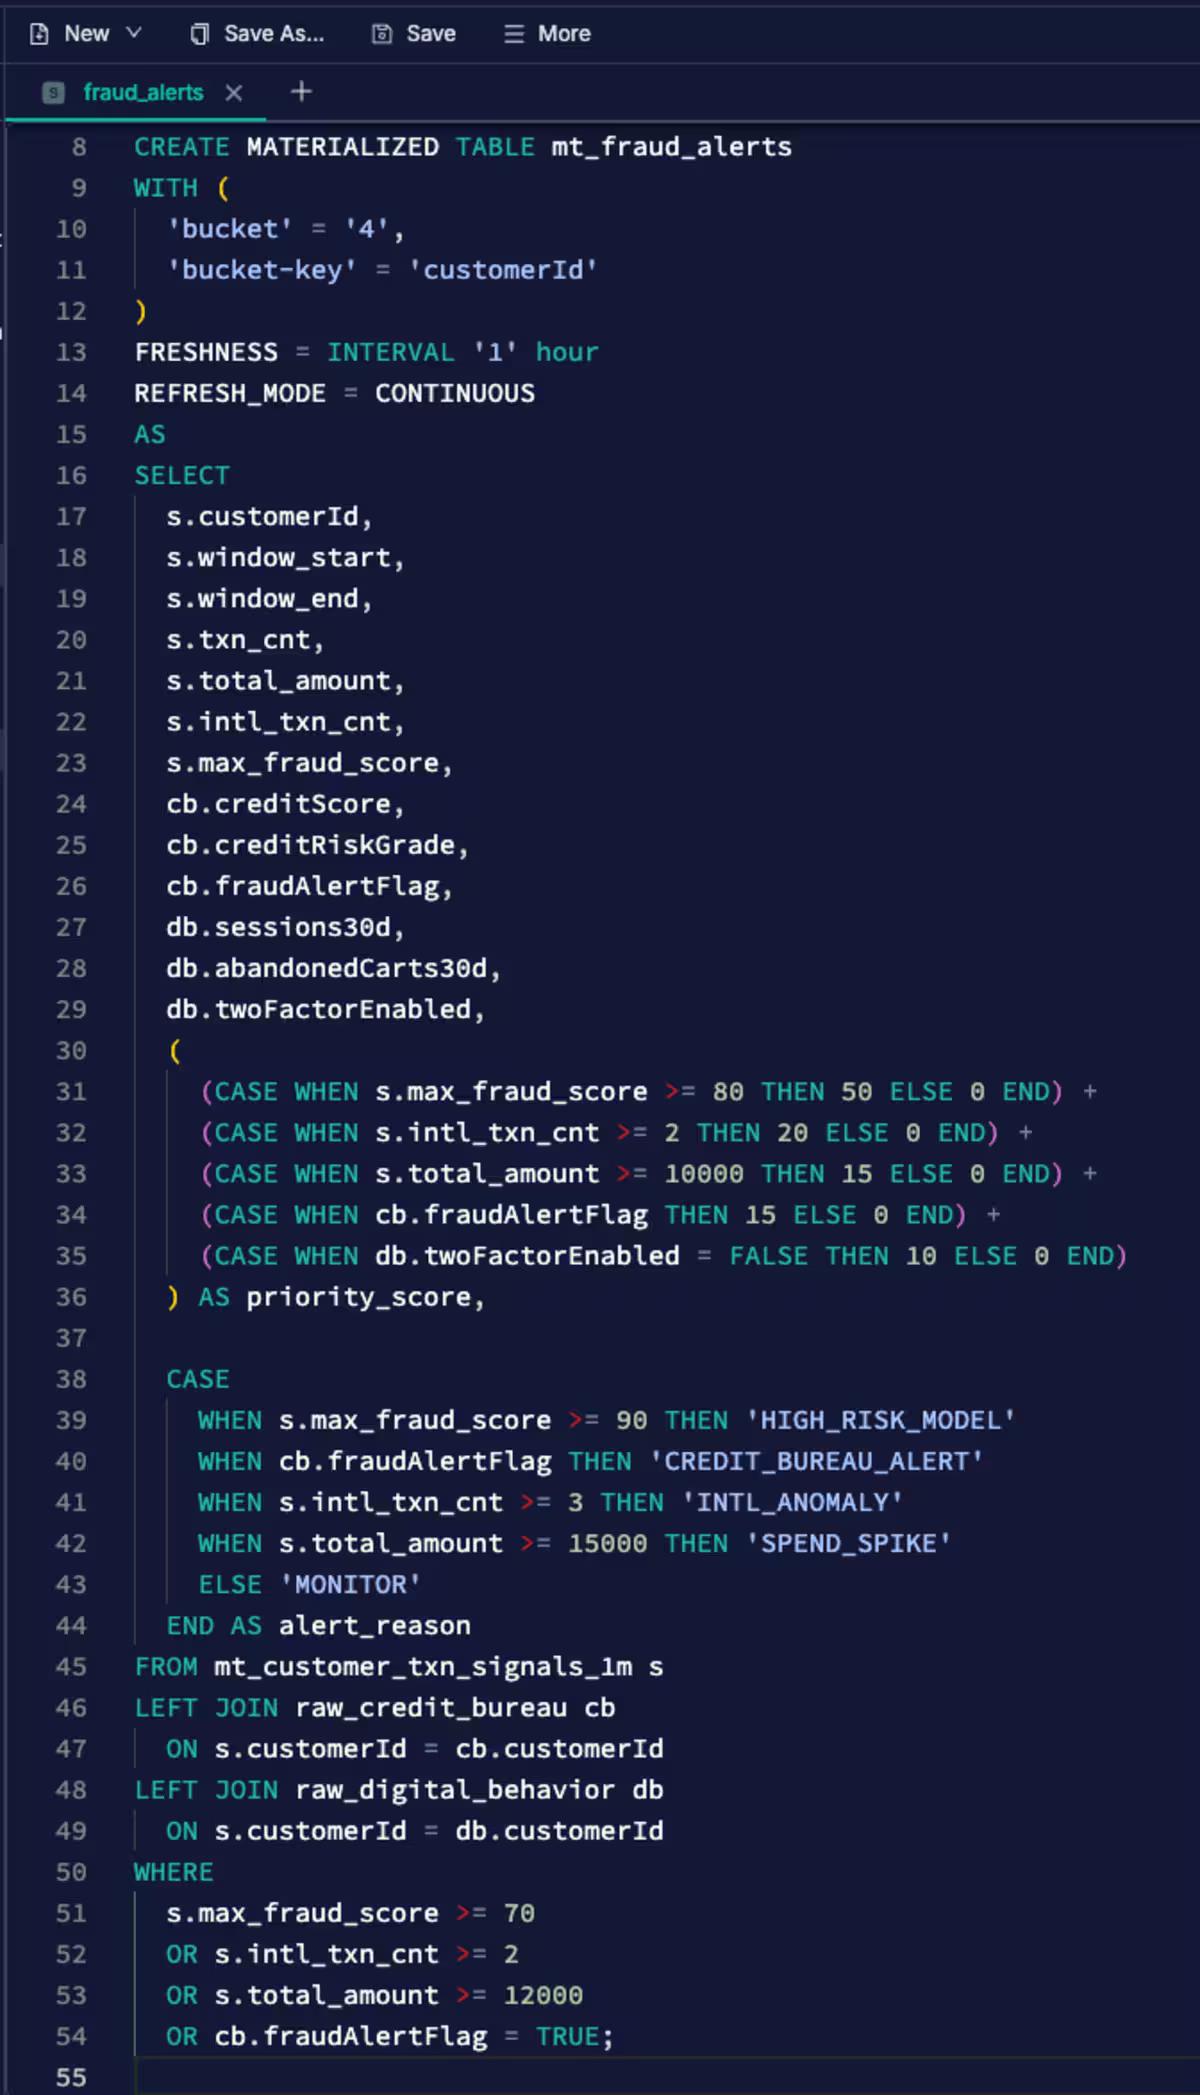
What happens next:
- The schema is derived automatically from your query
- The platform keeps the table up to date according to your freshness declaration
- The same table serves operational dashboards, historical reports, and exploratory analysis
- No separate pipelines. No duplicate logic. No semantic drift.
You don't manage execution modes. You declare intent. The platform handles the rest.
### Freshness-Driven Execution: Intent, Not Implementation
Freshness expresses how up-to-date your data needs to be, not how often something should run.
As business requirements evolve, you change freshness, not your SQL, not your pipeline architecture. The same table can move between "hot" (real-time) and "cold" (batch) usage patterns without rewriting anything.
This is critical for regulated industries where compliance reporting might need daily freshness, but fraud detection needs sub-second freshness.
**One table definition. Different execution strategies. No duplication.**
### Built-In Workflow Scheduling: No External Orchestrators
Not all data needs to be updated continuously. When bounded execution is required, Ververica generates and schedules refresh workflows automatically.
**No manually defined dependencies.**
The platform understands your table definitions, dependencies, and freshness requirements. It schedules refreshes, handles backfills, and coordinates execution, natively.
**This matters because:**
- Data engineers don't maintain orchestration code alongside business logic
- Changes to table definitions automatically propagate to scheduling
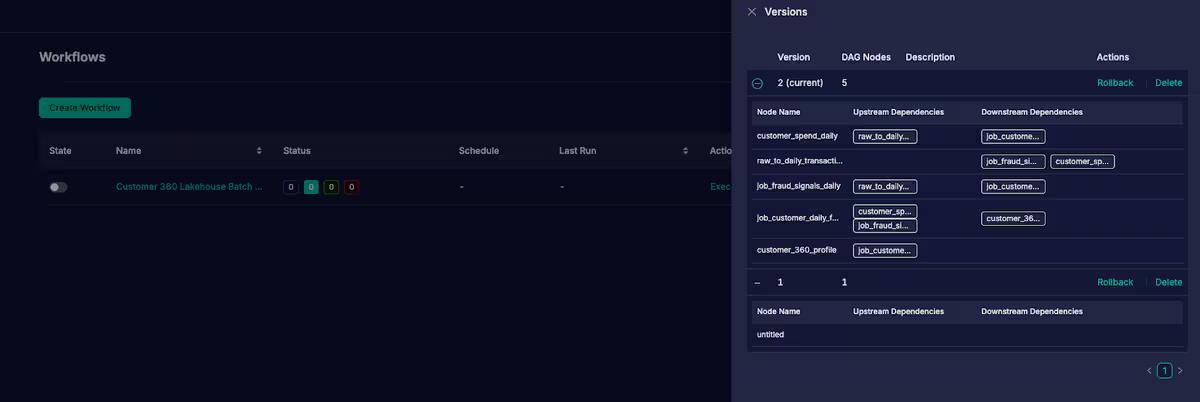
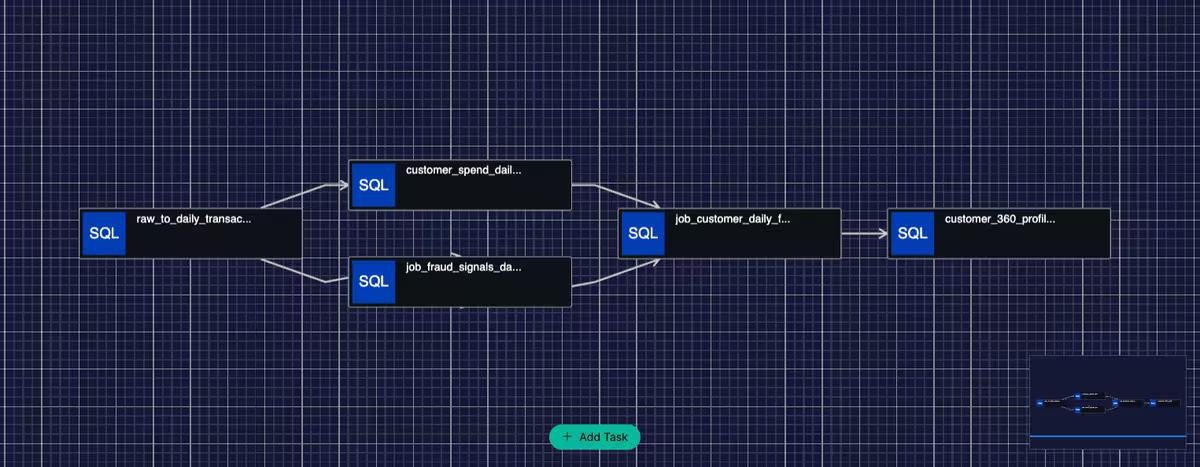
### Resource Queue Management: Safe Coexistence
In a unified platform, always-on streaming workloads and bounded batch jobs must coexist without conflict. This is where most "unified" platforms fail, because batch backfills starve streaming pipelines, or streaming workloads block batch execution.
Ververica solves this with resource queue management:
- **Always-on streaming workloads are protected with reserved capacity**
- **Batch and incremental work runs opportunistically when resources are available**
- **Historical recomputation never destabilizes production systems**
For highly-regulated industries including the financial services industry (FSI) this is non-negotiable. Real-time fraud detection can't be starved by a batch model training job. Payment processing can't be delayed because someone is running a historical compliance report.
**Ververica ensures workloads coexist safely—no resource starvation, no operational risk.**
## Why This Matters: Business Outcomes, Not Just Features
The primary value of Ververica's Unified Streaming Data Platform is simplicity that scales.
### Lower Operational Cost
When you stop maintaining duplicate pipelines for the same logic, your data platform costs drop. Fewer systems to manage. Fewer broken workflows to fix. Fewer engineers required just to keep things running.
### Reduced Risk
Many data problems don't show up as obvious failures. They show up as silent inconsistencies, like metrics that drift, reports that don't align, that result in decisions based on stale or incorrect data.
Ververica reduces this risk by maintaining data consistently over time. Changes are controlled. Backfills don't destabilize production. **Your data becomes reliable, not fragile.**
### Higher Trust in Data
When different dashboards show different numbers, confidence collapses. Teams stop acting on insights and start debating the data.
By defining data once and keeping it consistent everywhere, Ververica rebuilds trust. **Leaders can focus on decisions, not on whether the data is correct.**
### A Platform That Scales With Your Business
What works for a small team becomes unmanageable at scale—more pipelines, more schedules, more failures.
Ververica gets simpler as usage grows, not more complex. New use cases reuse the same definitions. Changes don't require rebuilding everything. **The platform absorbs complexity instead of pushing it onto your teams.**
## The Bottom Line
Data is continuous. Your data platform should treat it that way.
Ververica’s new release available in Ververica Cloud deployments eliminates the dual pipeline architecture that creates duplication, drift, and operational risk. With Materialized Tables, freshness-driven execution, and unified streaming and batch semantics, you define data once and trust the platform to maintain it over time.
**No more Spark for batch, Flink for streaming.**
**No more semantic drift between real-time and historical data.**
**No more orchestration complexity hiding business intent.**
One platform. One definition. One source of truth.
Please read the [**Release Notes**](https://docs.ververica.com/introduction/product-updates/#release-february-9-2026) for additional details.
## Vulnerability Fixes
Maintaining platform security is a top priority. In this release, several vulnerabilities were addressed to safeguard your deployments and ensure system integrity. For a complete list of the resolved vulnerabilities, check out the [**Release Notes**](https://docs.ververica.com/introduction/product-updates/#release-february-9-2026)
## Downloads
- If you are an existing customer, check out the [**Release Notes**](https://docs.ververica.com/introduction/product-updates/#release-february-9-2026) for all links and complete details of all changes in this release.
- If you are new to [Ververica's Unified Stream Data Platform](https://www.ververica.com/product#solutions), over [here you will find](https://www.ververica.com/product#solutions) everything you need to know to get started!
## More Resources
- Read more about [Ververica Cloud and BYOC](https://www.ververica.com/ververica-cloud)
- Learn more about [Ververica's Unified Streaming Data Platform](https://www.ververica.com/deployment/self-managed) flexible deployment options
- [Contact us to get started](https://www.ververica.com/contact)
---
---
title: "A World Without Kafka"
description: "Discover why Apache Kafka is becoming outdated for real-time analytics and how Apache Fluss offers a modern solution for evolving data needs."
lastUpdated: 2026-03-17T13:41:14.000Z
source_url:
html: "https://www.ververica.com/blog/a-world-without-kafka"
md: "https://www.ververica.com/blog/a-world-without-kafka.md"
---
## Why Kafka Falls Short for Real-Time Analytics (and What Comes Next)
Apache Kafka had a remarkable run, powering event-driven architectures for more than a decade. But the landscape has evolved, revealing clear **Kafka limitations for real-time analytics** as modern **streaming analytics** and decision-making use cases become more demanding. Kafka is increasingly being pushed to retrofit capabilities into a **real-time analytics architecture** it was never designed to support. To solve today’s streaming data pipeline challenges and analytics requirements, new capabilities are required. It’s time for a new kid on the block.
During the transition from batch processing to **real-time streaming data**, an open-source project developed inside LinkedIn gained significant attention and momentum: **Apache Kafka**. The goal was to simplify moving data from A to B in a scalable and resilient way using a publisher/subscriber model. Kafka enabled companies to build early **streaming data pipelines** and unlock a new class of event-driven use cases. An ever-growing ecosystem of connectors and integrations accelerated adoption and established Kafka as the preferred **streaming storage layer**. However, as **real-time analytics architectures** have evolved beyond simple ingestion, Kafka’s limitations for analytics workloads have become increasingly apparent.
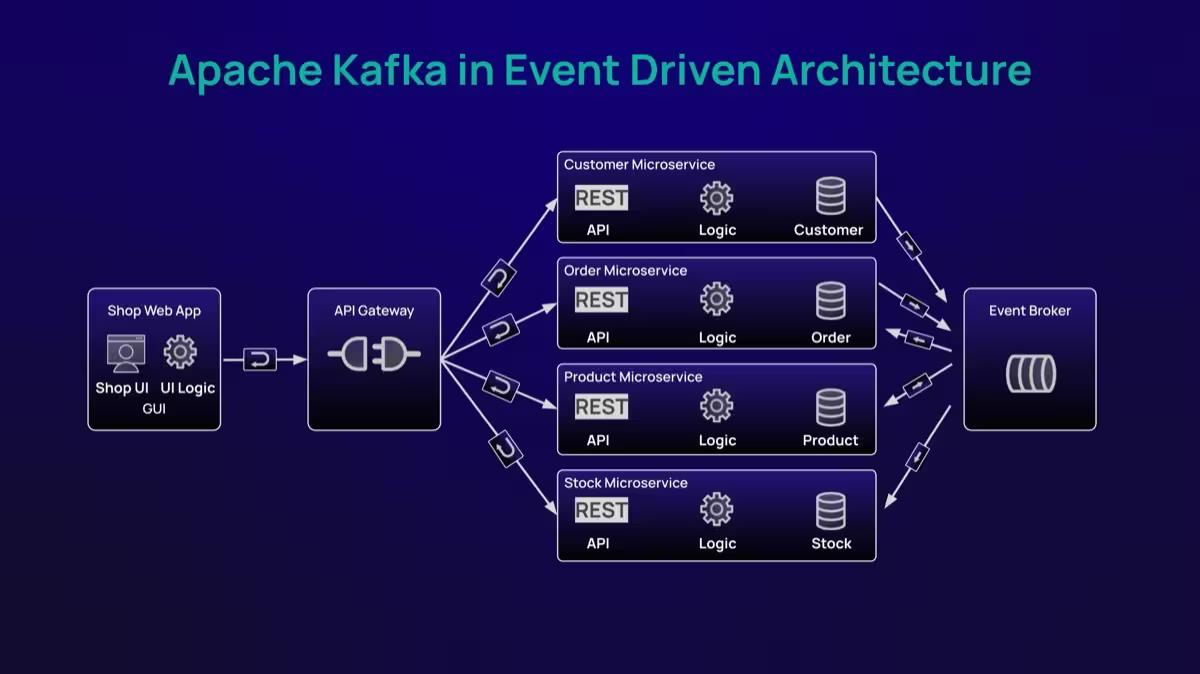
From an architectural standpoint, Kafka is not an analytics engine. It is a resilient and scalable **record-based storage system** for real-time, fresh data—often referred to as the hot layer. Analytics workloads therefore must be executed outside the Kafka cluster, continuously moving data between storage and processing engines, which increases network traffic and operational overhead. In addition, Kafka does not natively enforce schemas on data published to topics. While this flexibility was acceptable for early streaming use cases, modern **real-time analytics platforms** require schemas to ensure consistency, governance, and data quality. To compensate, Schema Registries emerged to enforce contracts between publishers and subscribers, adding complexity to Kafka-based analytics architectures.
Last but not least, and perhaps the most critical aspect, Kafka is a record-based storage system. That is well-suited for use cases requiring a message queue, such as real-time ingestion or event-driven architectures, but has considerable limitations in addressing the current and future needs for real-time projects. Processing engines such as Spark and Flink must consume the entire topic data, even though just a portion of the event data (columns) is required. The impact is unnecessary network traffic, degraded processing performance, and excessive storage requirements.
Record-based streaming storage components will still have their space in the data architecture. Solutions such as Kafka and Pulsar are well-suited to use cases requiring full record reads. Architectural patterns based on microservices can leverage the above solutions to interchange data, decoupling functions from message transportation to improve performance, reliability, and scalability. Full record reads are also beneficial for ingestion pipelines, in which data will be stored in long-term storage systems, such as Object Storage, for historical and archival purposes. Bottlenecks and limitations arise when they are used for analytics workloads that require capabilities beyond a simple data transport layer.
## Streaming Data Evolution
Today’s conversation is driven by a single aspect: Evolution. In other words, new needs require new approaches to data management. Kafka addressed the initial needs for streaming data. This first wave was mainly dominated by real-time ingestion pipelines and discrete (SEP, Simple Event Processing) analytics. Essentially, the ability to move data from point A to B, and in some cases, run simple data preparation and processing in between. Kafka, combined with Spark Streaming or ad-hoc connectors, was able to address those early use cases.
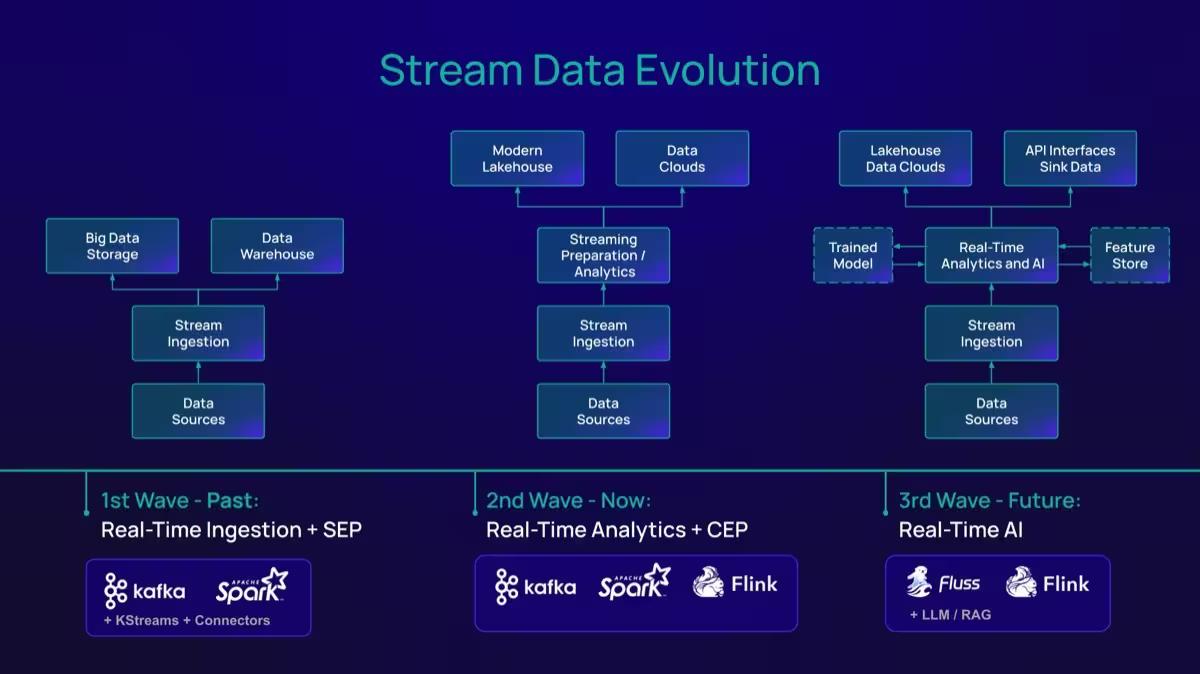
Fast-forward, and the second wave introduced complexity into the streaming pipeline. In addition to discrete data preparation, the use cases at this stage required advanced analytics functions, such as aggregation, enrichment, and complex event processing. Micro-batching fell short. A new architecture approach based on columnar storage with efficient projection pushdown and transparent data tiering, combined with sub-second processing engines, is needed. Apache Fluss and Apache Flink can deliver that promise and, together, constitute the future and the third wave in the maturity scale.
Every tech article nowadays mentions AI/ML. This third-wave evolution enables companies to build real-time AI pipelines that embed advanced analytics techniques (such as GenAI) into streaming data. This increases the need for modern real-time storage systems with enhanced features that tier data across both fast streaming and historical layers, providing integrated, unified access to business data.
## The New Kid On The Block
Apache Fluss is a modern, real-time data storage system for analytics. It consolidates years of experience and lessons learned from its predecessors while addressing the current and future needs of organizations. Fluss was born in an era in which more data is required to feed ML models, Lakehouses are part of the enterprise ecosystem, and cloud infrastructure is the preferred strategy for companies.
But data storage is just one piece of the architecture puzzle. Apache Flink provides the capabilities and resilience to process vast volumes of real-time data with sub-second latency, delivering the speed needed for future streaming applications. Not limited to Flink, additional processing engines and libraries are developing integrations with Fluss, thereby strengthening the ecosystem.
Here are the main features of modern real-time analytics.
### Stream as Table
Fluss stores data as schematized tables. This approach is suitable for most real-time use cases, including those that rely on both structured and semistructured data. By structuring streaming data, companies can enhance governance, improve data quality, and ensure that publishers and consumers share a common language. Fluss defines two types of tables:
- Log Tables are append-only, similar to Kafka topics. Use cases such as log monitoring, clickstreams, sensor readings, transaction logs, and others are good examples of append-only data. Events are immutable and should not be changed or updated.
- Primary Key (PK) Tables are mutable tables defined by a key. Records are initially inserted and subsequently updated or deleted over time according to the changelog they represent. A PK Table keeps the latest changes of the whole table, allowing a record “lookup” access pattern. Changelog use cases, such as account balances, shopping cart, and inventory management, can benefit from this approach. Kafka cannot perform this behavior, requiring external key-value or NoSQL databases to track the current record status, thereby resulting in complex, hard-to-maintain solutions.
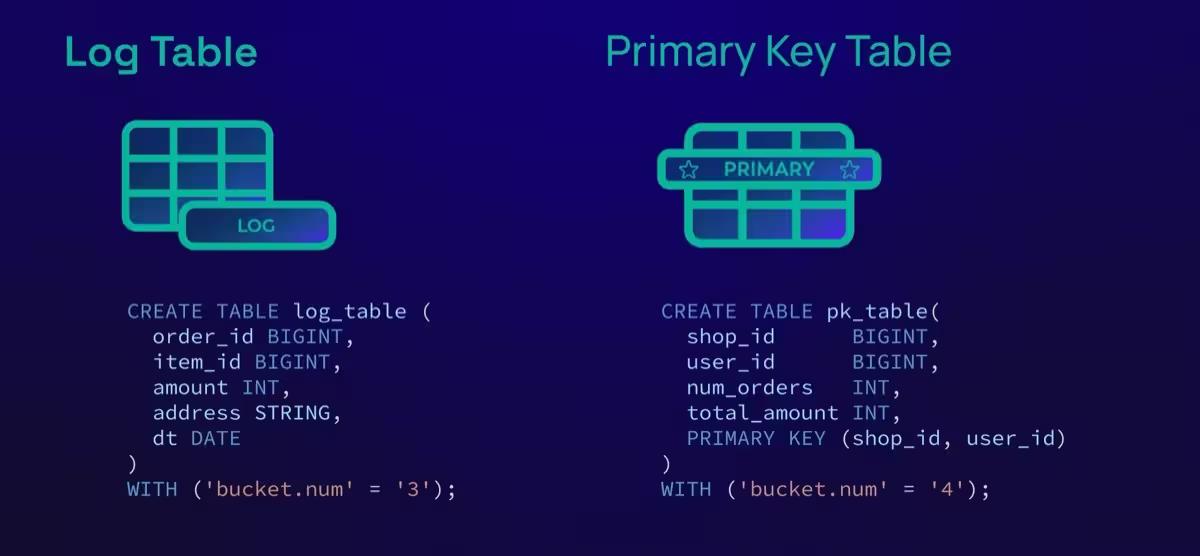
In brief, PK Tables ensure record uniqueness based on the primary key, INSERT, UPDATE, and DELETE operations, and provide comprehensive record mutation capabilities. On the other hand, Log Tables are append-only; record updates are not required.
### Columnar Storage
The way Fluss stores data on disk is arguably the most fundamental architectural shift relative to other solutions. Unlike Kafka, Fluss leverages Apache Arrow format to store data in columnar format, bringing the following benefits:
- Improved storage usage, as storing data in a columnar format requires less disk space. Compression rate depends on multiple data characteristics, but initial benchmarks indicate a promising 5x improvement when using Apache Arrow as the underlying storage format. Less storage = less cost. Kafka provides only a few data compression options, which are not comparable to those available in Apache Arrow out of the box.
- Efficient querying leveraging column pruning. In general, less than half of the attributes of a given business event are queried or accessed, ie, the column names you add to your SELECT FROM statement. Projection pushdown is a technique that removes unnecessary attributes (aka column pruning) when retrieving data from the storage system. Kafka is all-or-nothing due to its record-based storage format.
- Both columnar compression and projection pushdown will improve network traffic—less data to move around results in happier network administrators. With Kafka, companies are experiencing network congestion constantly and potential high egress costs.
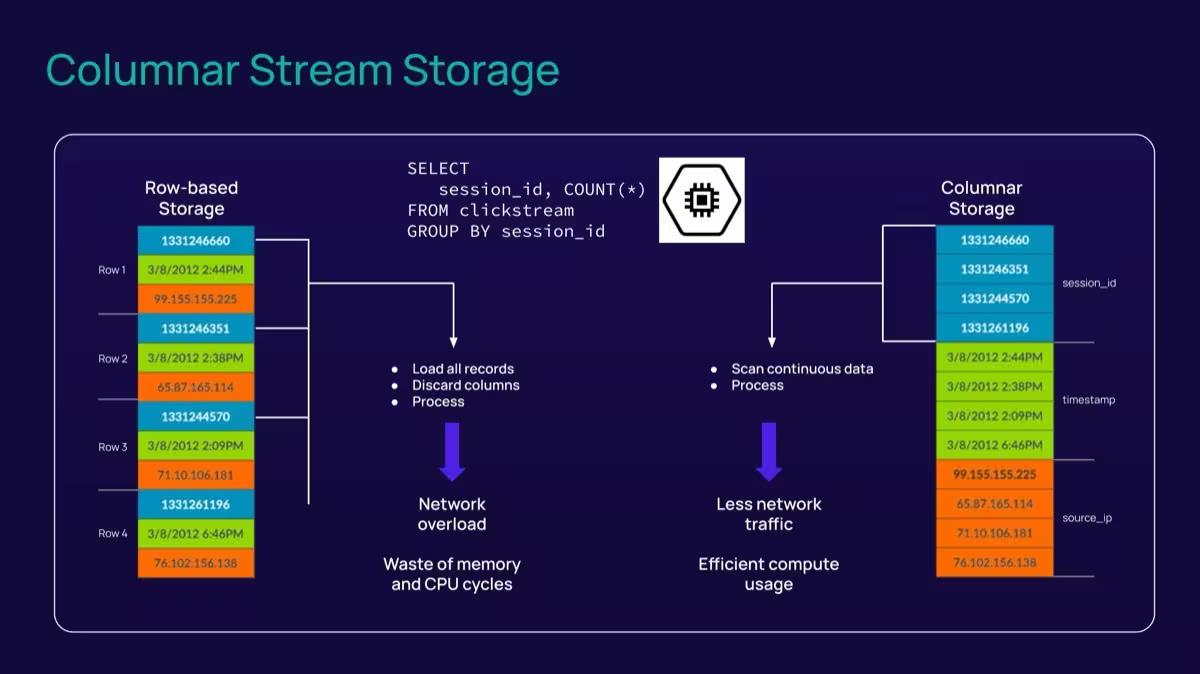
### Lakehouse Unification
Kafka was built in the Data Lake era. From the very start of design, Fluss was built for the Lakehouse. This makes a big difference. Companies realized that Data Lakes (or Data Swamps in many cases) are difficult to keep the lights on and pay back the investments in licenses, hardware, and personnel to build Big Data solutions. Fortunately, Lakehouses overcome those challenges. Lakehouses assert that data should be widely and easily accessible regardless of its age. Batch and real-time events overlap, and processing engines must be able to access both layers transparently.
These are the data tiering and unification view capabilities Fluss can provide, in addition to the hot/fresh data layer:
- Warm layer, for data aged from minutes to hours, primarily stored in Object Storage solutions.
- Cold layer, for data aged from days to years. Lakehouse solutions such as Apache Paimon and Iceberg are the preferred platforms for this historical data, feeding ML models, retrospective analytics, and compliance.
- Zero-copy data tiering, aging data from hot layer (Fluss tables) to warm/cold layers (Object Storage and Lakehouse). This means that a single copy of the data unit is available, either in the real-time or historical layer. Fluss manages the cutover between layers, facilitating querying and access. The Kafka approach relies on data duplication via a consumer/publisher job, resulting in increased storage costs and the need to convert Kafka topics to Lakehouse table format.
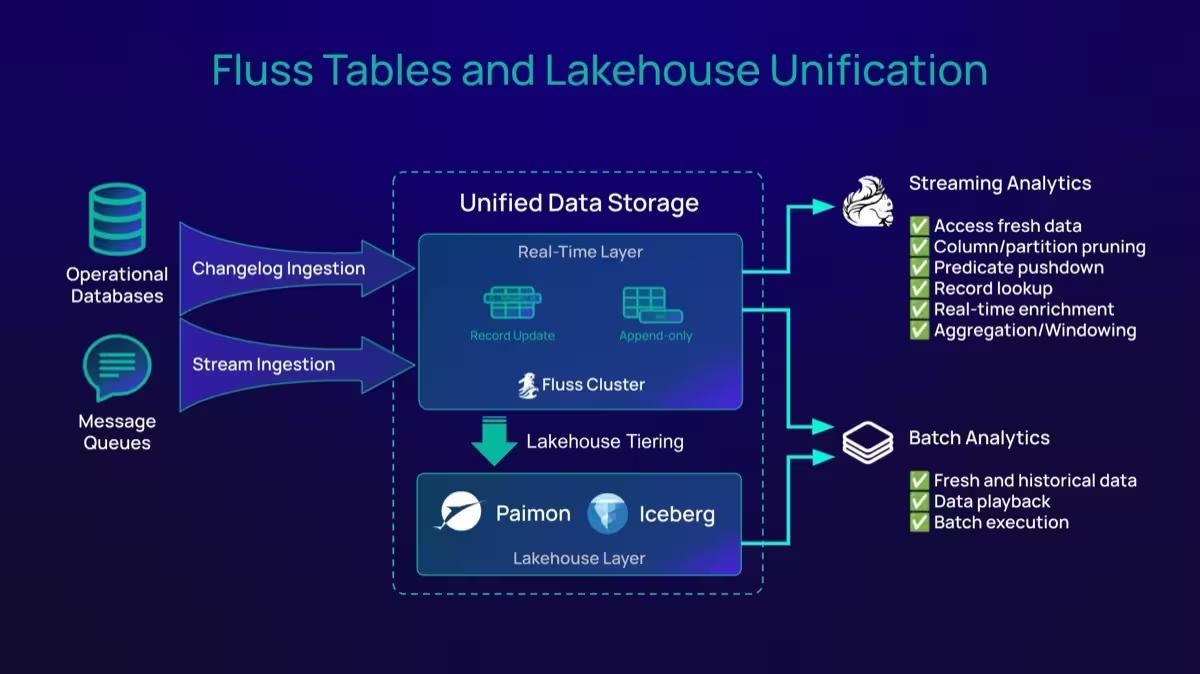
## A Bright Future Ahead
Real-time data analytics is becoming the cornerstone of modern companies. Digital business models must deliver a better user experience and timely responses to customer interactions, which forces companies to build systems to harness and manage data in real time to create engaging and “wow” experiences. Acting now is not merely a matter of technical feasibility; for most enterprises, it is becoming a unique advantage for survival in a highly competitive global market landscape.
Fluss helps companies bridge the gap between the real-time and analytics worlds, offering unified access to both fresh, real-time data and historical, cold data. In brief, Fluss enables seamless data access regardless of dataset age and simplifies complex data analytics architectures that were dragged along for years, primarily due to the lack of best-fit components and frameworks. With Fluss serving as the real-time storage layer for analytics, the Lakehouse is granted governance, simplicity, and scalability that future-proof modern architectures.
On the operational side, it offers significant advantages by reducing the complexity of managing, storing, and serving both real-time and batch data. These efficiencies translate into direct cost savings, primarily achieved through optimized Fluss table format, a two-tiered storage system based on data temperature, and finally, minimized overall pipeline CPU usage via predicate pushdown and column pruning. Collectively, these architectural elements alleviate the operational overhead associated with platform maintenance, accelerate the onboarding of new use cases, and facilitate seamless integration with the existing enterprise IT infrastructure.
## Additional Resources
[Fluss: Unified Streaming Storage For Next-Generation Data Analytics](https://www.ververica.com/blog/introducing-fluss)
[Fluss | Ververica documentation](https://docs.ververica.com/introduction/about-ecosystem/fluss/)
[Apache Fluss the Real-Time Streaming Lakehouse Storage](https://www.ververica.com/what-is-apache-fluss)
---
---
title: "Introducing The Era of \"Zero-State\" Streaming Joins"
description: ""
lastUpdated: 2026-03-17T10:52:08.000Z
source_url:
html: "https://www.ververica.com/blog/introducing-the-era-of-zero-state-streaming-joins"
md: "https://www.ververica.com/blog/introducing-the-era-of-zero-state-streaming-joins.md"
---
Large-scale streaming joins, real-time data enrichment, and continuous analytics have historically been limited by the complexity of managing state using solutions like [**Apache Flink®**](https://www.ververica.com/what-is-apache-flink). As streams grow in volume and velocity, operators face memory pressure, slow checkpoints, and long recovery times.
That complexity ends today with the **official launch of managed service for** [**Apache Fluss™**](https://www.ververica.com/what-is-apache-fluss) **(Incubating) on** [**Ververica’s Unified Streaming Data Platform**](https://www.ververica.com/product). Organizations can now take advantage of enterprise-grade streaming innovations that resolve long-standing challenges in modern streaming architectures and stateful stream processing.
## (Brief) History of Streaming Joins
Real-time streaming is revolutionizing how organizations make decisions. At its core, **streaming joins** combine multiple continuous streams of data as it arrives, producing **unified, real-time views of entities** such as customers, devices, or orders.
Streaming joins enable real-time **data enrichment**, where raw event streams are enhanced with dynamic contextual information, such as adding product or user profile data, to provide a complete view for analytics, AI models, or operational decision-making.
For instance, a [Customer 360 system](https://www.ververica.com/use-case/customer-360) merges streams from web and mobile apps, payment systems, Customer Resource Management (CRM) platforms, marketing tools, and product telemetry to build a complete, up-to-date view of each customer. Similarly, IoT platforms join device telemetry with user activity to [detect anomalies](https://www.ververica.com/use-case/fraud-detection), while e-commerce platforms join clickstreams with purchase events for [personalization](https://www.ververica.com/use-case/customer-360) and [fraud detection](https://www.ververica.com/use-case/fraud-detection).
By joining streams in motion, organizations can react instantly and maintain accurate, up-to-date insights. However, implementing streaming joins at scale has remained complex in practice.
## The Curse of Streaming Joins
Anyone operating large-scale stream processing systems is familiar with the operational challenges. As state grows with each additional stream and key, the system must maintain increasingly large volumes of data. Over time, resource demand increases, checkpointing slows to a crawl, and recovery becomes more time-consuming. Each new stream makes things worse. **The culprit? State.**
These issues are not unique to Apache Flink; they are **inherent to the nature of stateful stream processing**. Managing large and continuously evolving state while preserving low latency and high availability is **one of the most difficult problems in distributed computing**.
For years, both the **Apache Flink** community and **Ververica** have been addressing these challenges through continuous innovation. Ververica’s VERA engine has introduced several key advancements designed to make large-scale state management more efficient and resilient, including:
- **Tiered storage**: to offload cold state and reduce memory pressure while enabling larger state sizes.
- **Lazy state loading**: for faster startup and recovery by loading state as the job is running.
- **Key-value separation**, which improves scalability by storing large value data externally while keeping metadata local.
At the same time, **open-source Apache Flink** continues to evolve rapidly. The recent introduction of disaggregated state with **ForStDB** as a new state backend demonstrates the community’s ongoing commitment to improving performance, scalability, and reliability in state management.
This ongoing evolution, from Flink’s pioneering architecture to Ververica’s enterprise-grade enhancements, has kept shaping the way for the next step in simplifying and scaling stream processing.
## Zero-State Streaming Joins: The Next Step
While these reduce the pain of managing large state, **stream processing systems still fundamentally need to reason about state**. To address this challenge at its core, Apache Fluss introduces **Zero-State Streaming Joins**, a new approach where state is seamlessly moved from the compute layer into the streaming storage layer itself.
**“Zero-state” doesn’t mean stateless.** The state still exists, but it now resides in a more logical, scalable place. In traditional architectures, streaming joins can easily accumulate terabytes of state within Flink, leading to operational complexity and resource strain. Fluss changes this by offloading join state into a purpose-built, indexed storage layer that can efficiently manage, merge, and query data natively. This allows Apache Flink to focus purely on computation, without being burdened by heavy, persistent state.
Though conceptually simple, this represents a **fundamental shift in how we design and operate stateful workloads**. Fluss introduces key innovations such as **partial updates and Delta Joins**, which we’ll explore later in this post. Together, these transform streaming joins from a scalability bottleneck into a practical, efficient, and elastic foundation for real-time data architectures, making continuous data unification achievable at enterprise scale.
## The Problem: Why Streaming Joins Don’t Scale Easily
### The Multi-Stream Merge Scenario
Let’s look at an actual use case. An enterprise wants to see a real-time **Customer 360 view**. In order to accomplish this, they begin by merging data from:
- Web and mobile apps (behavior, sessions)
- Transactions (purchases, payments)
- CRM systems (support tickets, preferences)
- Marketing platforms (campaigns, engagement)
- Product telemetry (feature usage)
Each stream updates independently, but all must converge on the same **customer_id** to deliver the 360 view that supports personalization, fraud detection, and intelligent support.
### Traditional Architecture: Apache Kafka & Flink Joins
The common, standard implementation is relatively straightforward (below, Figure 1 shows an Apache Kafka-centric approach):
1. Each source writes its own Kafka topic.
1. Apache Flink consumes all topics.
1. Flink performs multi-way joins on **customer_id**.
However, in production, this design often becomes difficult to scale and maintain.
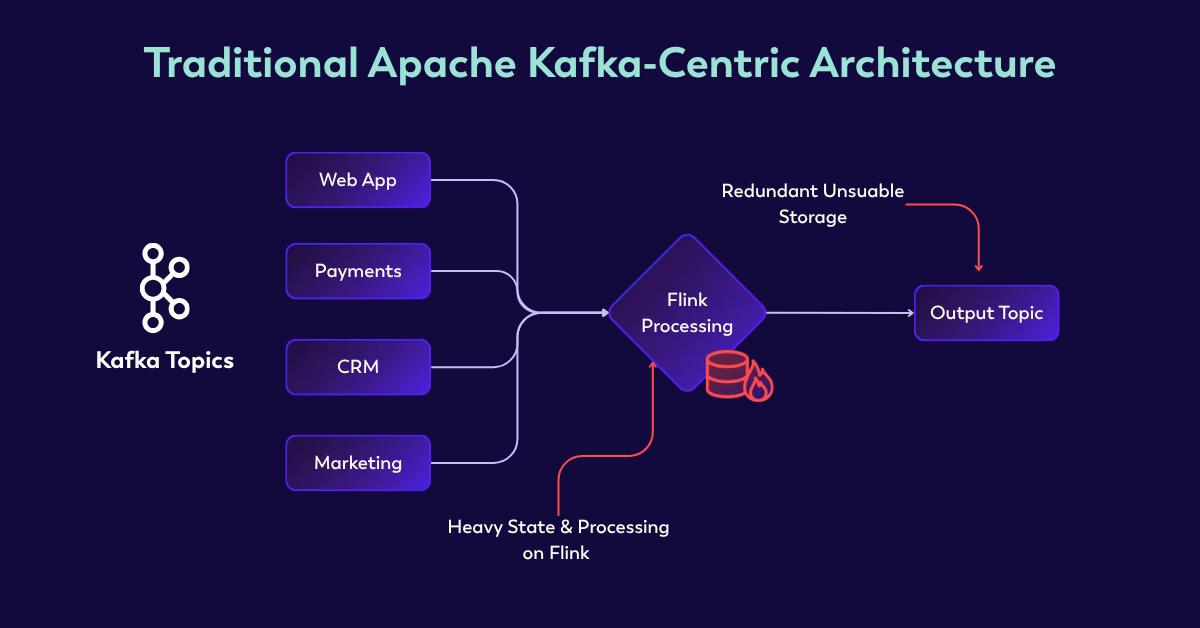
### Why Kafka + Flink Breaks at Scale
Streaming joins in Apache Flink are inherently **stateful operations**. To join multiple continuous streams, Flink must buffer incoming events until corresponding records with matching keys arrive from the other streams. This requires maintaining a **large keyed state**, where partial records and intermediate join results are stored in memory or on disk.
For every new event, Flink performs a lookup against this existing state to find matching entries and produce the joined output. To ensure **fault tolerance**, the entire state is periodically **checkpointed**, persisting potentially large volumes of data. As a result, streaming joins can become resource-intensive, consuming significant memory and storage while increasing checkpoint size and recovery times.
This creates several scaling issues, including:
- **High memory usage**: Even a moderate multi-stream join can consume tens of gigabytes just to store keys and intermediate results.
- **Increased CPU load**: Each incoming event triggers multiple lookups and join evaluations.
- **Slow checkpoints**: As the state grows, checkpoint operations take longer, reducing throughput.
- **Network overhead**: Large state transfers between TaskManagers increase shuffle load and recovery times.
### The Exponential Scaling Problem
As more streams are added, the operational cost of streaming joins in Flink increases **nonlinearly**. A simple **two-way join** is typically manageable, but as the number of input streams grows, complexity and resource consumption rise rapidly. A **four-way join** already becomes challenging to maintain, requiring substantial memory and state management, while an **eight-way join** can easily overwhelm the cluster.
At enterprise scale, where joining data from **ten or more sources** is common, streaming joins can consume **60–80% of available cluster resources**, with state sizes reaching **terabytes**. At that point, Flink spends most of its effort **managing and checkpointing state** rather than processing new events. The result is a cruel irony: as the system handles more valuable real-time data, the underlying infrastructure becomes significantly harder and more expensive to operate efficiently.
## The Solution: Apache Fluss and Zero-State Streaming Joins
**Apache Fluss** redefines how streaming architectures handle state. Instead of treating data as endless append-only logs (like Kafka), Fluss introduces **primary-key tables** as a first-class, mutable storage primitive.
The key difference is that state is no longer maintained within Flink operators. In conventional architectures:
- Each operator stores local state for joins, buffering, and lookups.
- This local state is the primary cause of high memory usage and slow checkpoints.
With Fluss, operator state is **offloaded to the streaming storage layer**, significantly reducing state requirements and improving overall system performance. Fluss handles merging, coordination, and versioning natively, so Flink becomes a **lightweight processing engine** reading already-merged, queryable data from Fluss. This is the essence of **zero-state streaming joins:** not stateless computing, but **moving the state** to a layer purpose-built for it. The result is a lean compute, durable state, and streaming joins that actually scale.
### Apache Fluss-Centric Approach
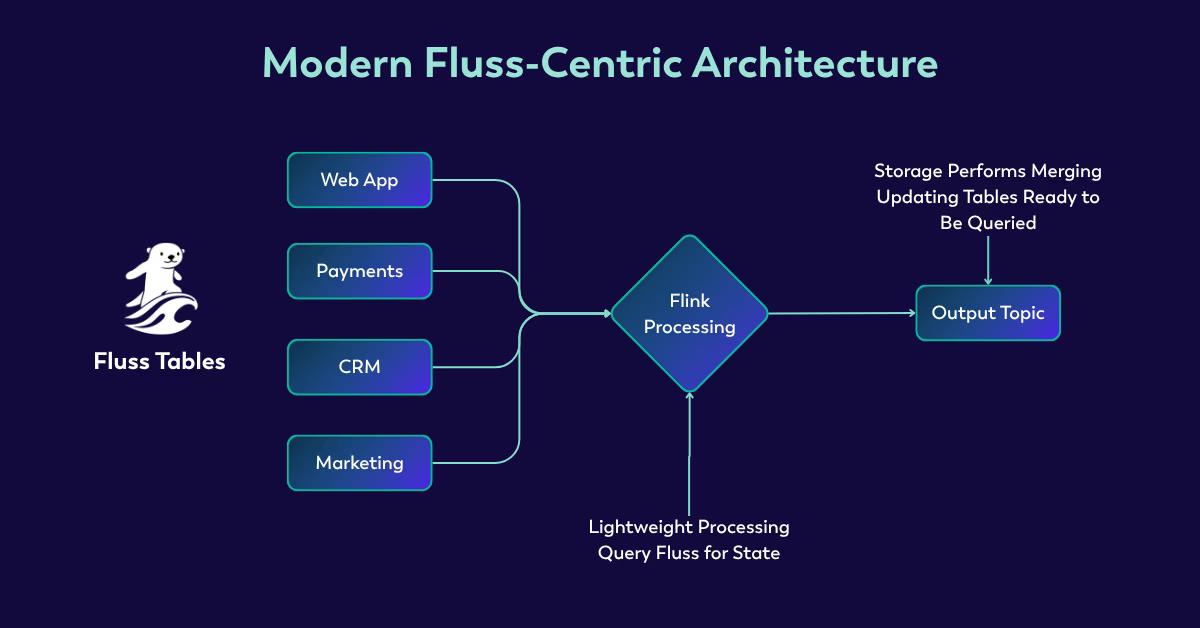
The table below summarizes the differences between the legacy Kafka and Flink and modern Fluss and Flink approaches:
Next, let’s jump into the specific features that Fluss has that allow it to work with Flink in a seamless, zero-state way, including partial updates, DeltaJoins, and Streaming Lookup Joins.
## Partial Updates: Eliminating Multi-Stream Merge State
### The Problem
You need to **merge multiple event streams that update the same entity** (like customers, orders, or devices). Each stream owns different attributes but shares a primary key.
Traditional Flink joins keep all streams in operator state and perform in-memory joins. This can be costly, slow, and mismatched with the goal to maintain only the latest version of each entity, instead of every draft.
### How Partial Updates Work
With **Fluss' primary key tables**, each source writes only the columns it owns, directly to a shared table keyed by the primary key. As a reference, think of Fluss as a Google Docs for streaming data, where everyone can edit, and the record stays consistent.
#### Example: Partial Updates for Real-Time Customer 360
Let’s look at an example using our Customer 360 use case. In the example below, each stream writes partial updates, while Fluss merges them into a single row per customer. As a result, the system always reflects the freshest data, with no coordination logic or “restart-the-job” mornings.
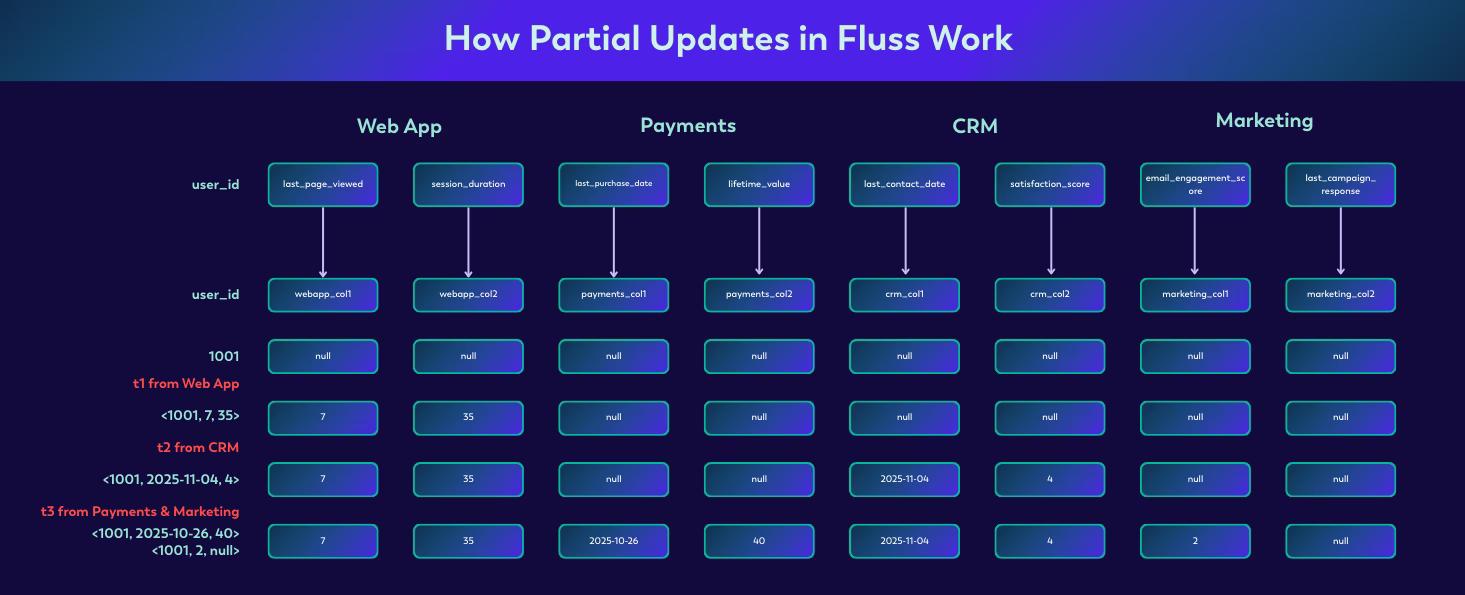
> **TIP:** Want to try this yourself? Find a hands-on example here.
## Delta Joins: The Bidirectional Lookup Join
### The Problem
When two high-volume streams need to be joined (for example, clicks with orders or profiles with events) traditional Flink joins maintain large buffers and join state for both sides. Each operator keeps keyed data until matching records arrive. Over time, this state grows unbounded, checkpointing slows, recovery takes longer, and jobs become fragile.
Most use cases don’t require re-joining the entire history every time a record changes. Instead, they only need **incremental updates** and small deltas that reflect changes on either side of the join. Conventional stream-stream joins, however, treat every incoming event as potentially requiring a full re-join, which leads to excessive memory and CPU consumption.
### How Delta Joins Work
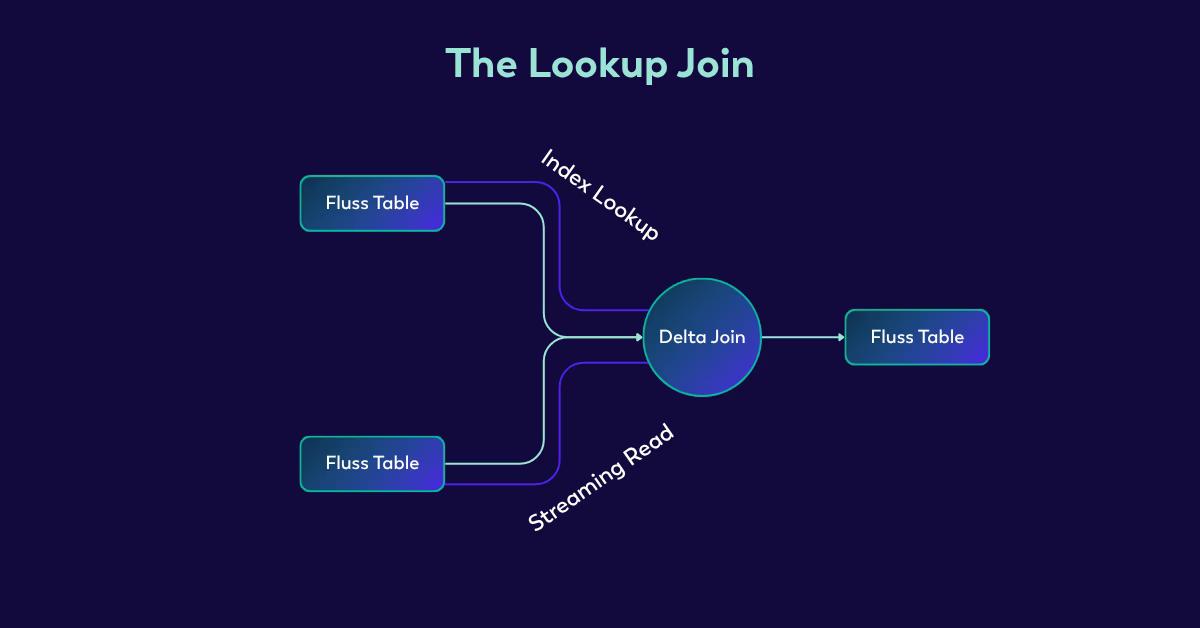
Delta Joins addresses this problem with a **bidirectional lookup join** approach, provided by **Apache Fluss**.
- Instead of buffering full streams on both sides, each incoming record probes the other stream’s table stored in Fluss by key.
- When a record arrives from stream A, it looks up the relevant key in stream B’s table, and when a record arrives from stream B, it does the reverse.
- Joined results are stored in Fluss tables rather than in operator buffers.
This preserves the full semantics of a stream-stream join. Both sides can trigger outputs, while **offloading state management to Fluss**. Operators remain lightweight, and all state is maintained efficiently in the Fluss KVStore. Because Fluss is integrated into the streaming layer, there’s **no need to manage or scale an external system**. In addition, all the above is achieved by maintaining both indexes and local caches for even **faster hot key access**.
### Results: Performance and Scalability Gains
Users typically run a stream-to-stream join using Apache Kafka & Flink. By externalizing state into Apache Fluss, Delta Joins allow Flink to perform incremental, delta-based joins without maintaining large in-memory operator states.
To see this in action, the benchmark results below come from online e-commerce platform Taobao and their Fluss production practice. [You can read more here.](https://fluss.apache.org/blog/taobao-practice/)
As depicted below, this architecture brings dramatic improvements:
- **Flink CPU and memory usage are reduced by up to 85%.**
- **Over 100 TB of operator state is eliminated** in production deployments.
- **Checkpoint durations cut from 90 seconds to just 1 second.**
- **Instant job startup** with no state bootstrapping required.
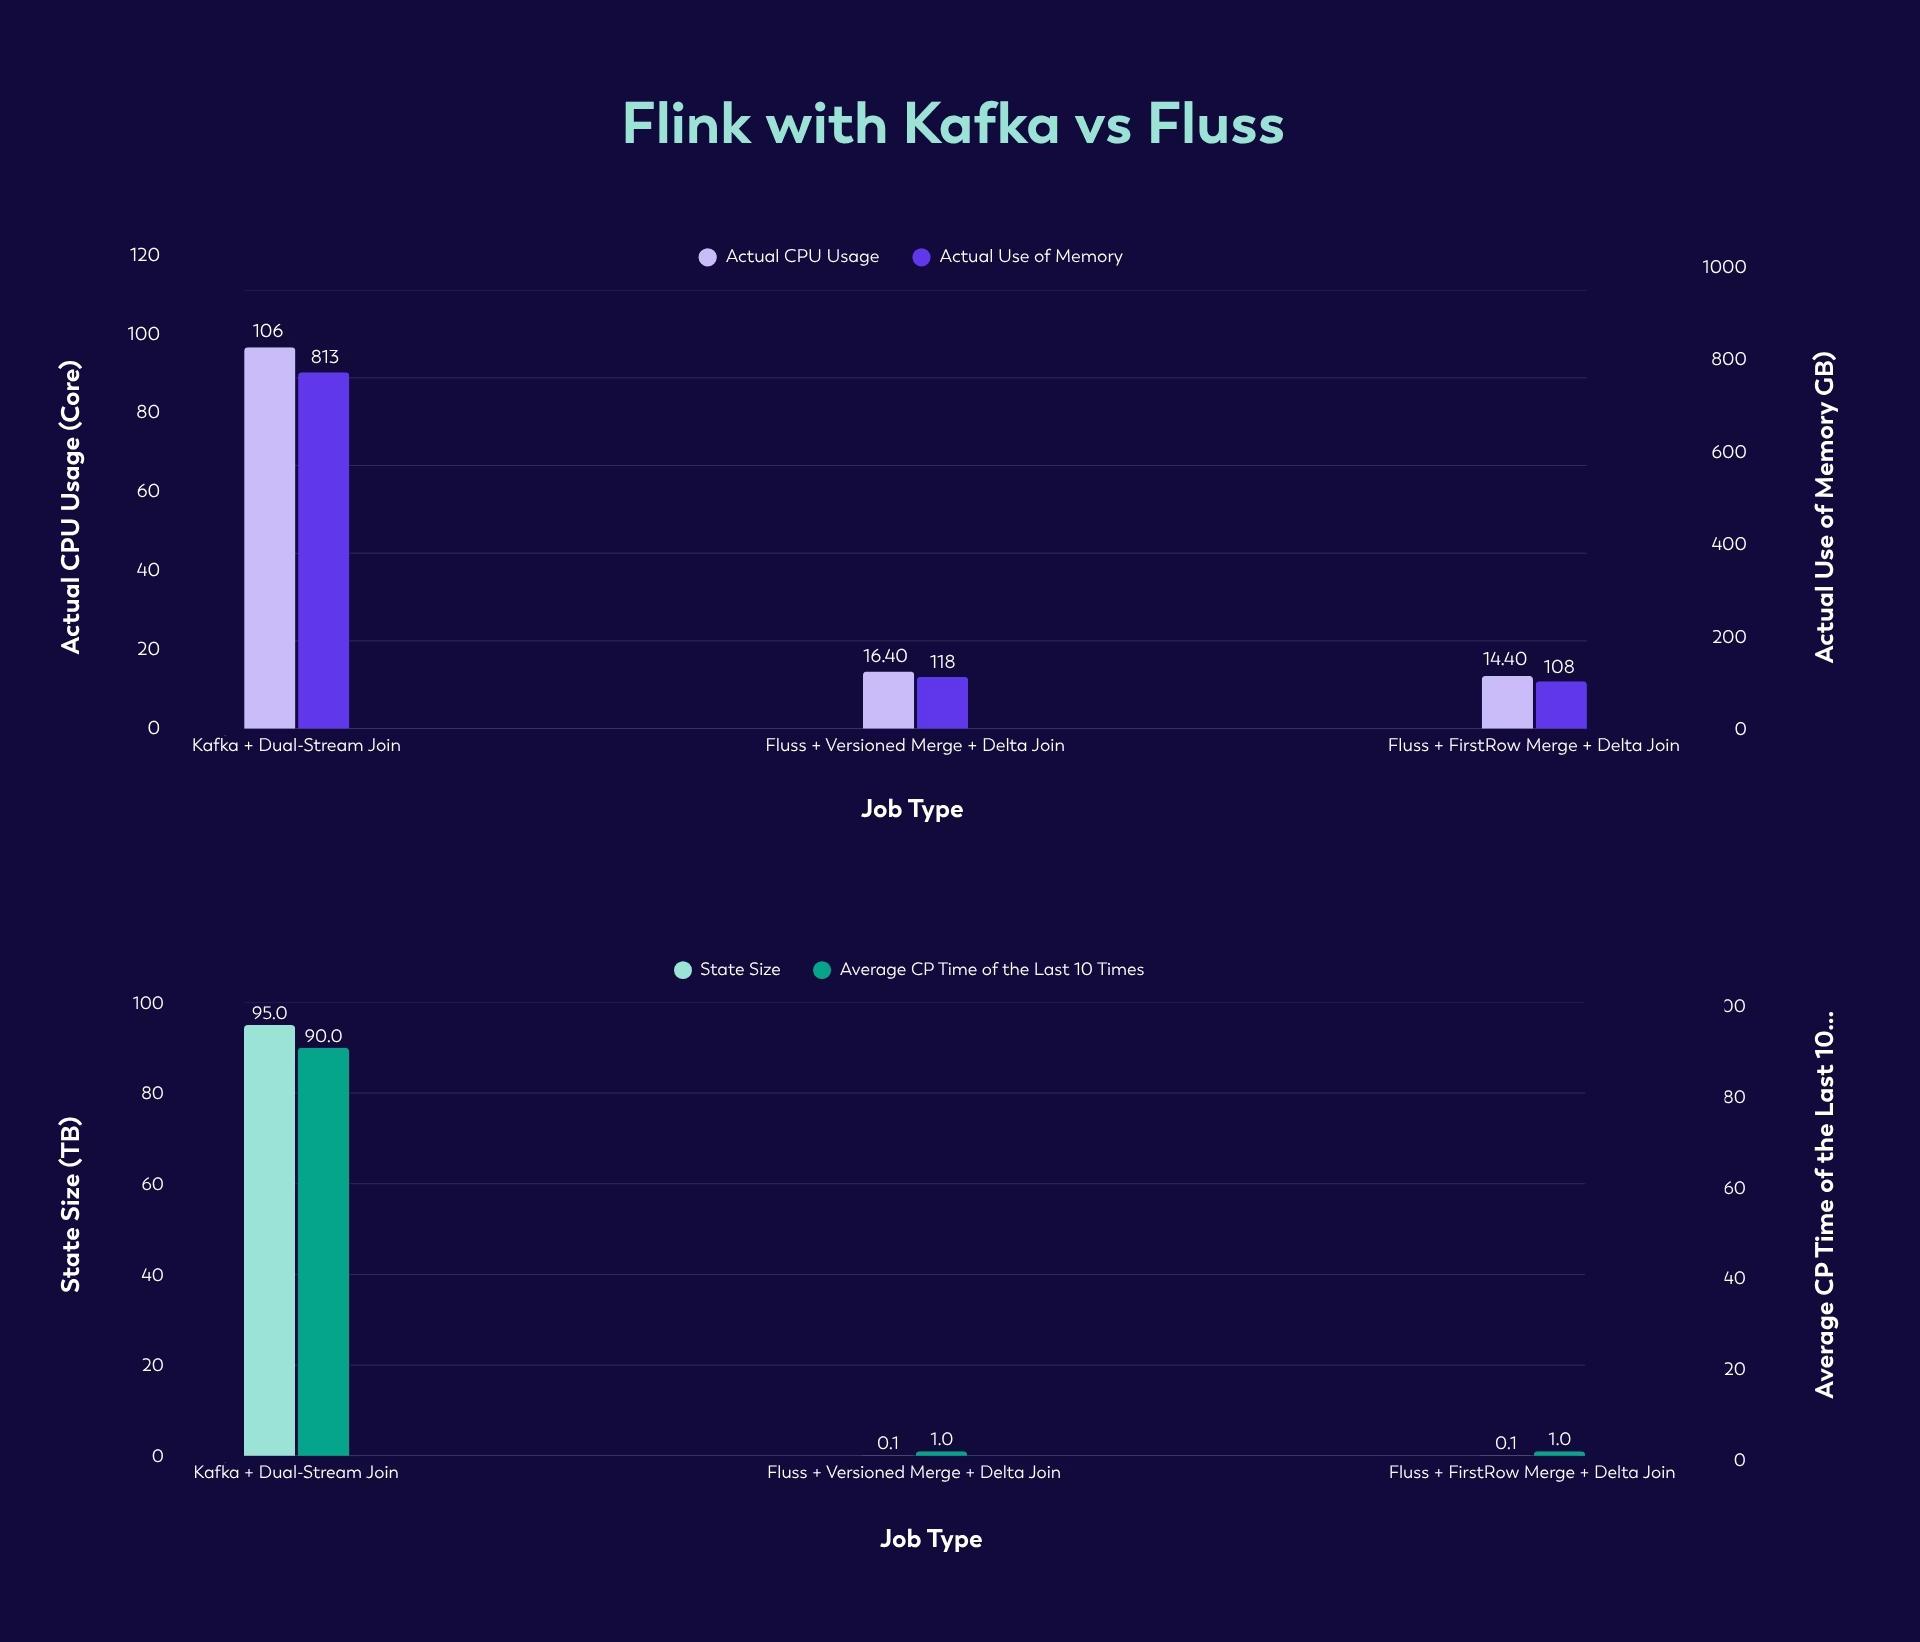
Because all state lives natively in Fluss, pipelines remain lightweight and fully fault-tolerant. Delta Joins transform what used to be a state-heavy, resource-intensive operation into a **scalable, zero-state streaming primitive**, enabling high-throughput real-time analytics without the traditional overhead.
**Note:** There is more work coming, like **multi-way streaming joins**, which are part of the project plan, along with improvements on the current **Delta join implementation**. [Visit the Fluss project future plan for details.](https://fluss.apache.org/docs/engine-flink/delta-joins/#future-plan)
## Streaming Lookup Joins: Updating Dimension Tables
Next, let’s take a moment to see what other features and benefits are available in Fluss. Although not directly related to zero-state streaming, there are scenarios where high-volume streams must be enriched by querying external systems, such as operational databases or key-value stores. In Kafka-centric architectures, users typically face two options: either **query an operational database**, which can introduce undesirable load and latency, or **deploy and maintain an external key-value store** to achieve fast access. Both approaches bring operational complexity, and in some cases, synchronization issues may arise. These considerations are beyond the scope of this blog, but you can [find more information here](https://fluss.apache.org/blog/pk-key-tables-log-cache-streaming).
With Apache Fluss, users can leverage **streaming lookup joins** on updating dimension tables using the system’s **primary key table**. In this setup, there is no need to deploy or scale an external database to handle lookups. This eliminates the operational overhead of managing caches, connectors, replication, or consistency guarantees across systems. The dimension table is **co-located with the stream**, maintained in Fluss’s primary key table, and backed by an **immutable changelog** that can be deterministically replayed.
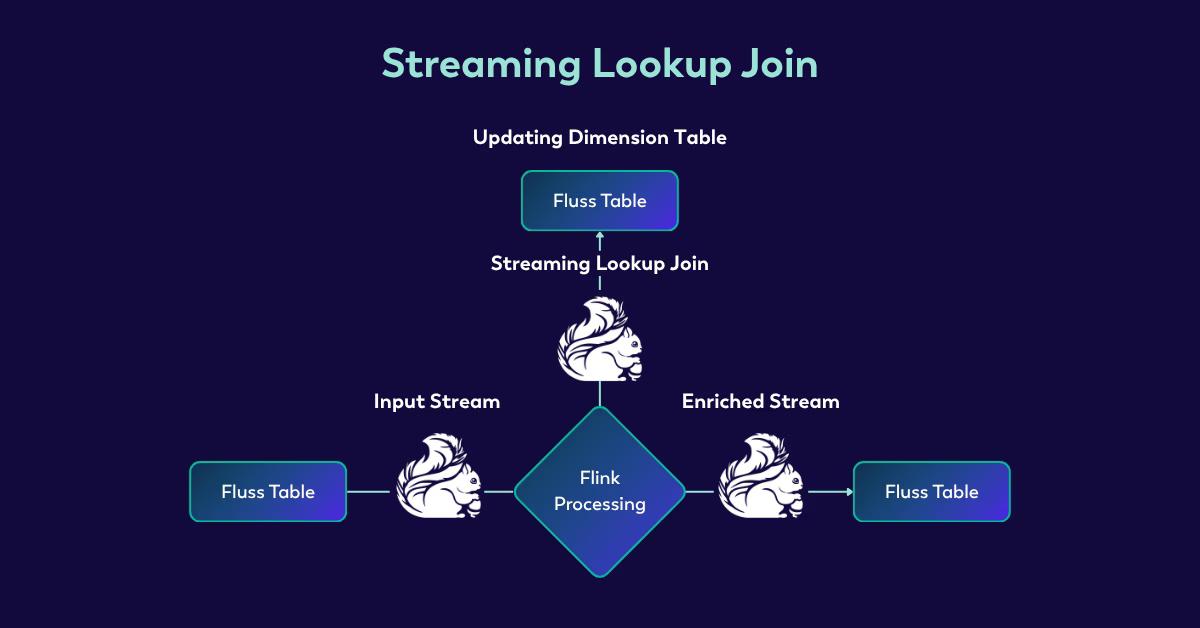
In traditional external KV-store setups, scaling enrichment performance typically requires provisioning r**ead replicas, sharding, or other database-level scaling strategies** to sustain high query throughput. Each additional replica or shard increases operational overhead and may introduce further latency due to network round-trip times and consistency requirements.
In contrast, Fluss scales enrichment **horizontally by adjusting the number of buckets in the primary key table**. While network I/O between Flink operators and the Fluss KVStore still exists, scaling is simplified: instead of managing an external database cluster, you scale the table buckets, and Fluss can match throughput requirements. This makes enrichment **linearly scalable with traffic**, constrained primarily by streaming throughput rather than the capacity of a backing database.
**A typical question** that is asked is: "How many queries per second Fluss can perform on an updatable dimension table?" Fluss is currently running in production at business-to-business giant [Alibaba](https://www.alibaba.com), and they have shared their latest known production numbers, which highlight **500k queries per second** on a single table.
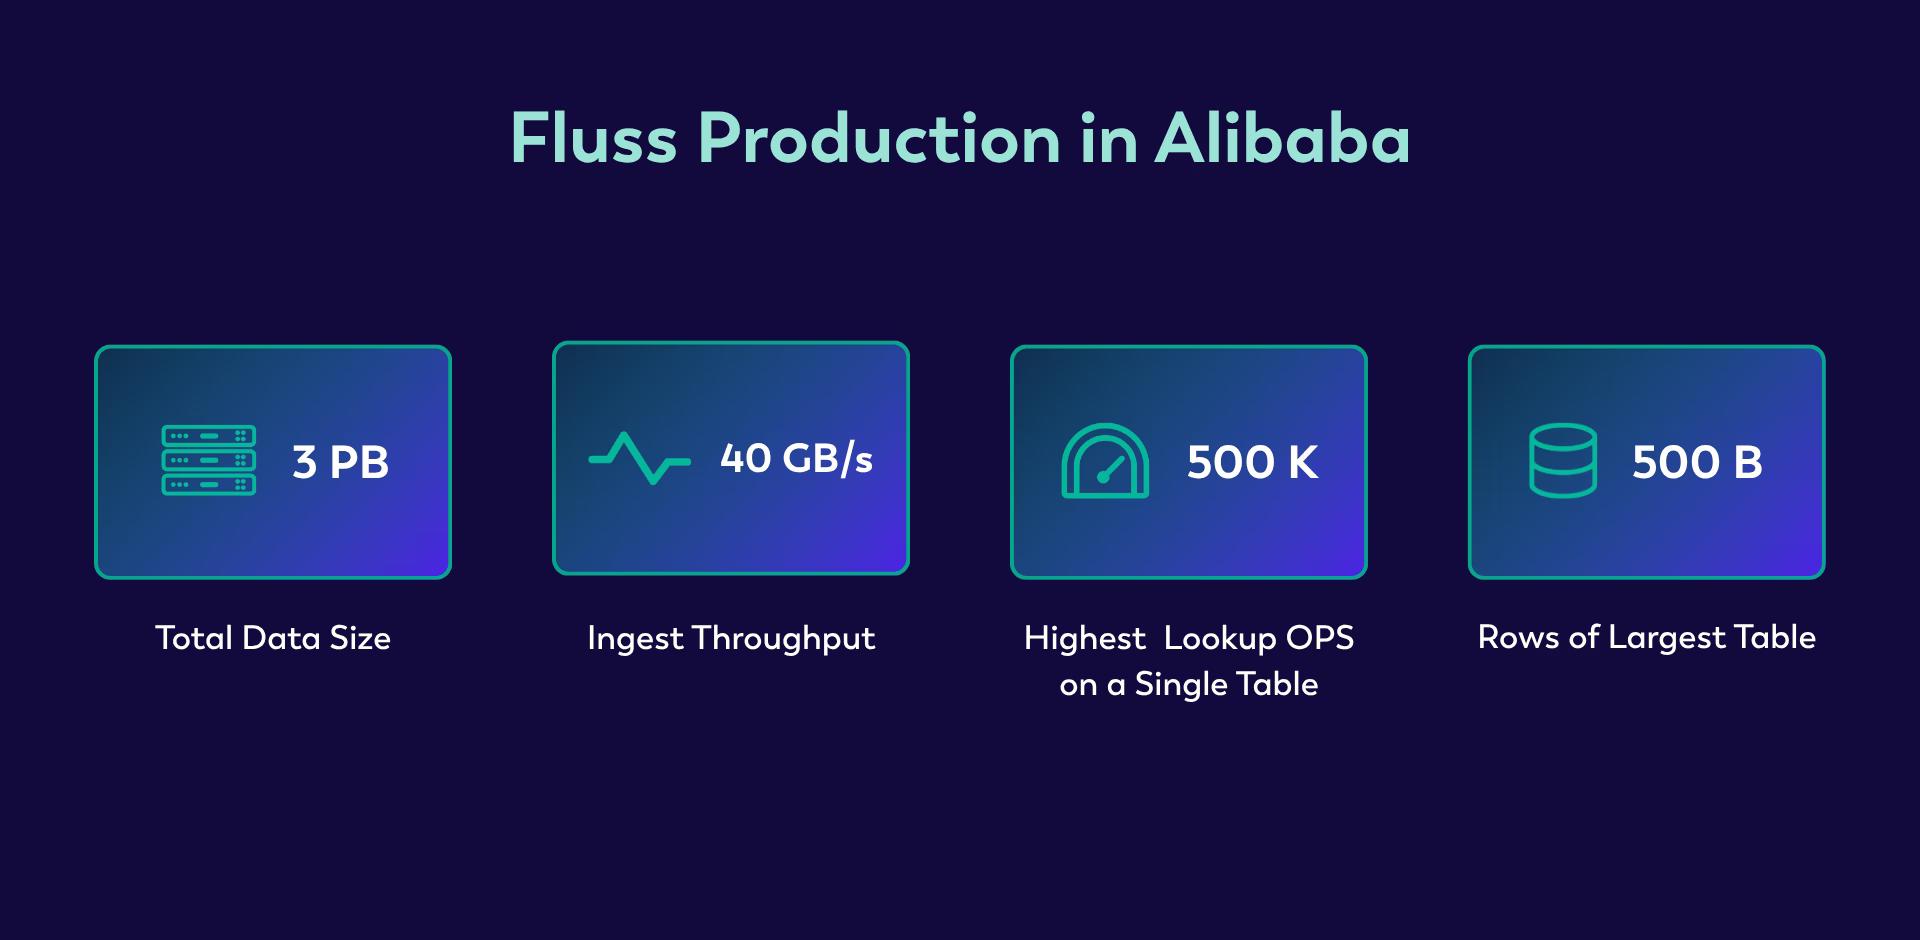
## Why Streaming Joins Are Critical for Agentic AI
Agentic AI systems that make decisions and take actions in real time depend on live, unified context. Whether it’s a customer service agent handling a refund, a fraud detection system flagging suspicious activity, or a personal assistant managing appointments, these agents need an up-to-the-second view of the world. Our original use case of a Customer 360 view also relies on instant real-time data in order to feed agents enough context and data to respond autonomously and appropriately.
The challenge is that relevant data comes from multiple continuous streams. This might include orders, support interactions, loyalty and preference updates, user behavior, and inventory changes. Without real-time merging, each stream remains isolated, and the AI agent might make decisions based on incomplete or outdated information.
Streaming joins solve this problem by combining these streams into unified, live views. For example, consider a fraud detection agent monitoring transactions. A new payment arrives, a recent support ticket opens, and the user’s loyalty tier changes, all in seconds. Streaming joins allow the agent to see all of this in context instantly, enabling accurate, autonomous decisions. Without them, the agent is processing streams separately, which introduces delays, inconsistencies, or errors.
The importance of streaming joins grows with complexity. Multi-step interactions, such as a conversation where the agent needs to reference prior actions, amplify the need for fresh, integrated context at each step. Each millisecond of delay compounds, impacting both accuracy and responsiveness.
In short, **streaming joins are the backbone of real-time context for agentic AI.** They enable agents to act with up-to-the-moment intelligence, turning disparate data streams into an actionable, coherent understanding.
**Note:** There is ongoing work on zero-state streaming joins, including **multi-stream delta joins**. [Keep an eye on the Fluss future project plan.](https://fluss.apache.org/docs/engine-flink/delta-joins/#future-plan)
## Next Step: Zero-State Streaming Aggregations
After tackling zero-state streaming joins, the next frontier is **streaming aggregations**. Just like joins, traditional Flink aggregations accumulate large amounts of keyed state inside operators. Examples of this include sums, counts, averages, or more complex column-wise merges.
The next step is to **move the aggregation state out of Flink operators and into the storage layer**, using an **aggregation merge engine**. This continues the zero-state philosophy: decoupling compute from state, letting Flink focus on transformations while Fluss manages aggregation deterministically and efficiently.
### How Fluss Handles Aggregations
Similar to [Apache Paimon](https://paimon.apache.org), Fluss also introduces the concept of the Aggregation Merge Engine. In simple terms, a **merge engine decides how multiple records should be merged** based on the same primary key. With the aggregation merge engine:
- Each stream writes **incremental updates** to a **primary-key table**.
- The storage layer applies **aggregation functions per column**, merging updates automatically.
- Flink operators remain **lightweight**, no longer buffering full state or performing heavy merges in memory.
**This is similar to how it offloads join state:** Flink emits updates, Fluss handles merging, and the system becomes both **scalable and queryable in real-time**.
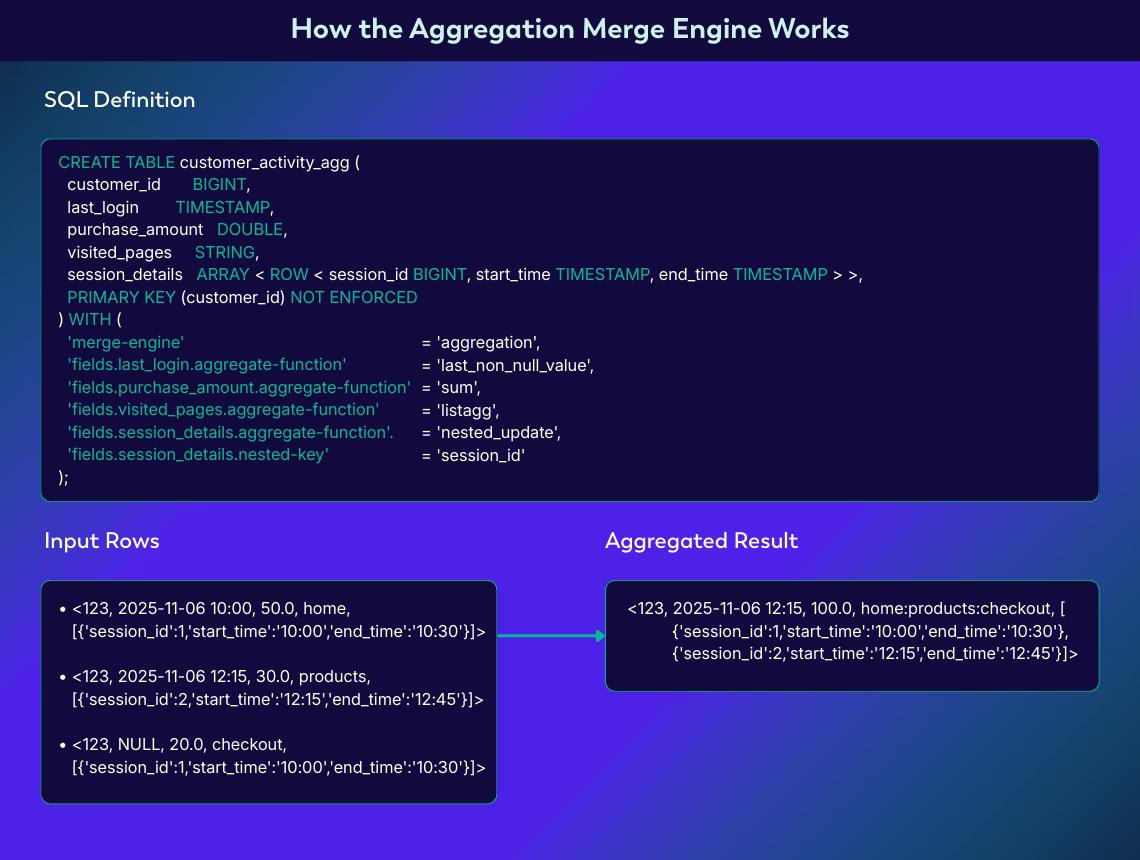
With zero-state aggregations, Flink operators become compute-light. No longer storing intermediate totals or stuck buffering large state, Flink can focus entirely on transformations. As a result, the architecture becomes highly scalable and predictable, as adding new keys or streams no longer risks memory blow-up. Recovery and checkpoints are faster since the aggregation state is already persisted and merged in the storage layer. Aggregated results are query-ready immediately, enabling downstream analytics or AI pipelines to consume fresh data without delay. In essence, this approach extends zero-state principles from joins to aggregations, decoupling computation from state and creating a streaming architecture that scales predictably.
## Fluss Combined Usage Best Practices
State management has long been the bottleneck in real-time stream processing. Traditional Flink streaming joins require operators to maintain large states, while connecting to external systems introduces latency, network overhead, and operational complexity. This combination often leads to high memory usage, slow checkpoints, long recovery times, and scaling challenges.
Apache Fluss addresses these issues by **externalizing all state into its integrated streaming key-value store (KVStore)**. Streaming joins no longer rely on massive local state, as lookup joins access the KVStore directly, eliminating the need for external databases while ensuring low-latency, transactional consistency. In addition, Delta Joins perform incremental, bidirectional updates efficiently without rebuilding the full join state.
The full potential of Fluss is realized when these patterns are used together. **Partial updates** consolidate entity state, **streaming lookup joins** enrich high-volume streams with real-time context, and **Delta Joins** apply incremental changes directly on the stored tables. By offloading all state management to Fluss, this combination delivers **low-latency, queryable views, minimal in-memory operator state**, and **scalable real-time pipelines** capable of supporting analytics and AI workloads at enterprise scale.
## Key Takeaways (Zero-State Benefits)
- **Lightweight operators and efficient resource use**: State is externalized to streaming storage, allowing operators to run with minimal local state and significantly reducing Flink’s memory and CPU footprint.
- **Fast checkpoints**: Minimal operator state means checkpoints complete quickly and consistently.
- **Instant restarts and rescaling**: Jobs recover immediately without rebuilding or reloading state.
- **Queryable state**: Live streaming state can be directly accessed for debugging, analytics, or AI model features without impacting running jobs.
---
---
title: "VERA-X: Introducing the First Native Vectorized Apache Flink® Engine"
description: ""
lastUpdated: 2026-03-17T10:53:59.000Z
source_url:
html: "https://www.ververica.com/blog/vera-x-introducing-the-first-native-vectorized-apache-flink-engine"
md: "https://www.ververica.com/blog/vera-x-introducing-the-first-native-vectorized-apache-flink-engine.md"
---
## Redefining Speed and Efficiency in Apache Flink with VERA-X
[Apache Flink](https://www.ververica.com/what-is-apache-flink)® is the standard for real-time stream processing, powering mission-critical applications worldwide. As the original creators of Apache Flink, Ververica pushes the boundaries of what stream processing can achieve. This includes the creation of [VERA](https://www.ververica.com/vera), the original enhanced engine that improves latency, stability, and efficiency for most streaming use cases.
Today, Ververica is proud to announce a new era of streaming technology: **VERA-X**. A native vectorized Apache Flink engine integrated into the [Ververica Platform](https://www.ververica.com/product) for selected prospects and customers. VERA-X delivers groundbreaking improvements in performance and efficiency, without requiring any changes to existing Flink applications. This marks a major step forward in our mission to empower our customers with the future of stream processing, accounting even for the most demanding [use cases](https://www.ververica.com/use-case) in the industry, where every millisecond matters.
## VERA-X: A New Era of Stream Processing Performance
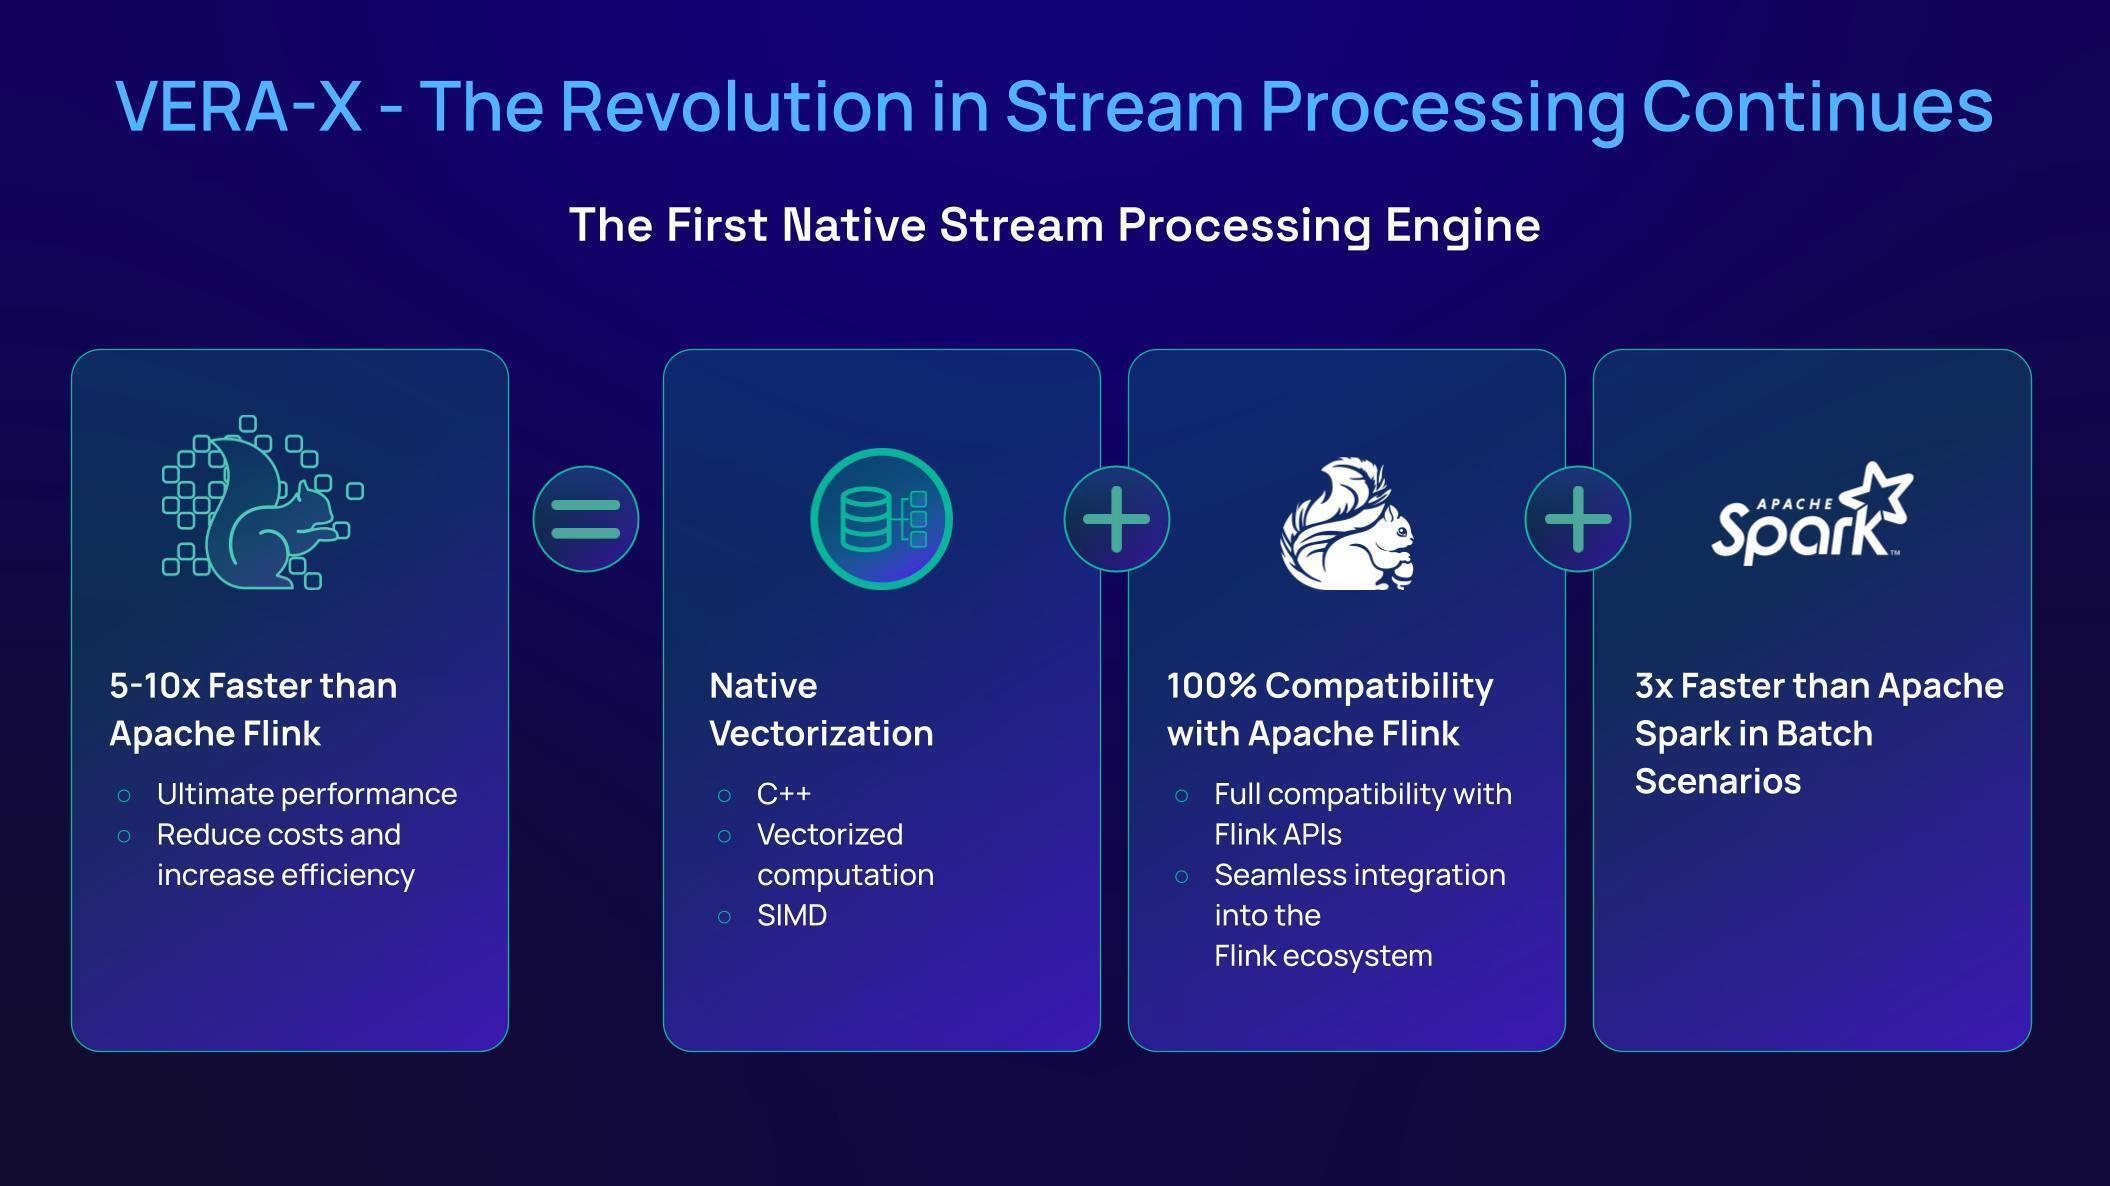
Modern enterprises demand ever higher throughput, lower latency, and greater cost-efficiency from their data streaming infrastructure. The biggest challenge is achieving order-of-magnitude performance gains while maintaining 100% compatibility with the Apache Flink APIs that users know and love. Incremental optimizations to Flink’s engine yield improvements, but these eventually hit a ceiling. Ververica recognizes the need for a new approach and delivers a solution that dramatically accelerates Flink workloads by fully leveraging today’s hardware, yet seamlessly integrates with the rich Flink ecosystem.
This results in VERA-X, the next-generation engine that combines Apache Flink’s proven framework with a powerful native execution core. Just as other data platforms have embraced native vectorized processing to boost performance, Flink now gains its own high-performance runtime for streaming.
This is particularly important for extremely latency-sensitive industries, where every millisecond matters. Many [use cases](https://www.ververica.com/use-case), including financial trading, [fraud detection](https://www.ververica.com/use-case/fraud-detection), ad-tech bidding systems, and IoT control loops all require sub-millisecond responsiveness. VERA-X is designed to deliver just that: ultra-low latency combined with an average of **52%** lower resource usage compared to the standard Flink runtime.
> **INFO:** This is only the beginning: VERA-X currently does not support disaggregated state storage. When introduced, users can expect costs to drop even further, making high-performance streaming more affordable than ever.
## VERA-X Architecture
VERA-X introduces a re-architected Flink runtime that is fully compatible with the standard Flink APIs, but internally adds several groundbreaking components to push the limits of speed and efficiency. The diagram below illustrates how VERA-X augments Flink’s architecture:
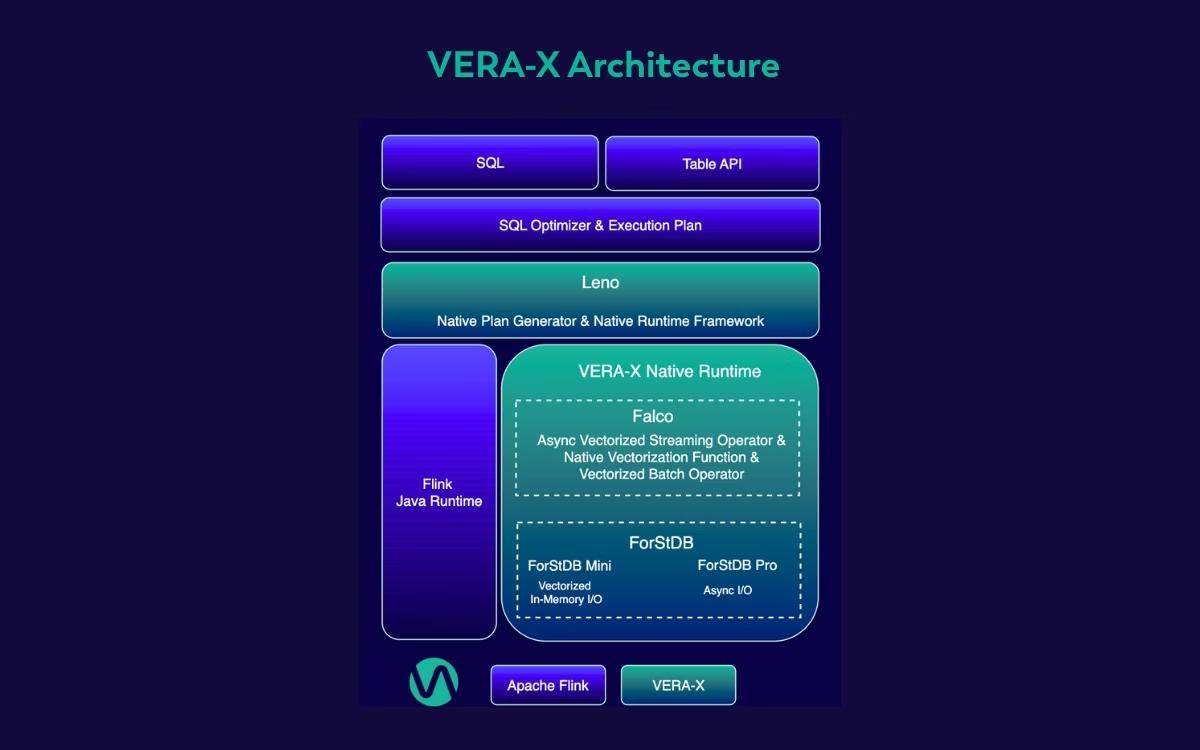
### Key Innovations of VERA-X Include:
- **Native Vectorized Execution:** The engine processes data in highly efficient batches, taking full advantage of modern hardware. This results in dramatically higher throughput and lower latency compared to Flink’s traditional runtime.
- **High-Performance State Management (ForStDB):** State-heavy streaming jobs run smoothly with a new state store that handles everything from in-memory operations to large-scale workloads. It keeps performance consistent even under heavy demand.
- **Seamless Flink Integration (Leno Layer):** VERA-X works transparently with all Flink APIs. Jobs migrate with **zero code changes**, maintaining full compatibility while unlocking the benefits of the new runtime.
- **Broad Operator & UDF Coverage:** From day one, most commonly used operators and functions are supported natively. User-defined functions (UDFs) also benefit, so custom business logic runs faster without modification.
## Performance Gains in Action
With VERA-X, we’re entering a new era of performance for Apache Flink. Whether running continuous streaming jobs or large-scale batch queries, the results are clear: higher throughput, lower latency, and significantly better resource efficiency. Benchmarks and production use cases alike show improvements of up to an order of magnitude compared to open-source Apache Flink.
### Streaming Workloads
Streaming jobs are the backbone of Flink, from continuous analytics to real-time recommendations. In this domain, VERA-X shines the brightest:
- **5–10× throughput improvement** compared to open-source Flink on SQL streaming benchmarks.
- Latency improvements measured in **single-digit milliseconds**, even under heavy stateful workloads.
- **50% lower infrastructure costs** due to better CPU utilization and vectorized state access.
#### How the benchmarks were conducted:
Streaming benchmarks are based on the Nexmark suite, an industry-standard benchmark for event stream processing. The tests compare open-source Apache Flink 1.19 against the new native engine under identical cluster configurations. Both engines execute the same SQL queries on workloads of 100 million and 200 million events, covering join-heavy, aggregation-heavy, and windowed queries. The hardware environment and cluster size are fixed to ensure a fair comparison, with results measured in execution time per query and throughput (events processed per second).
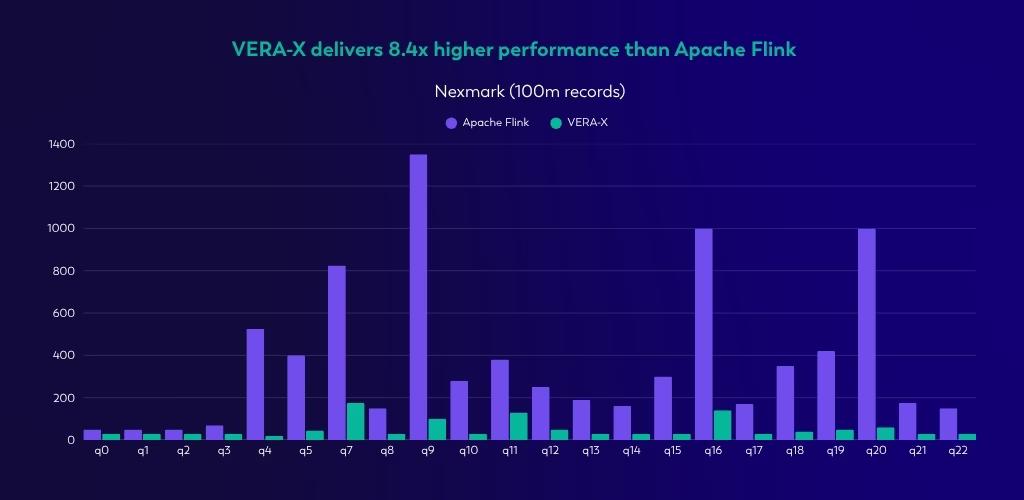
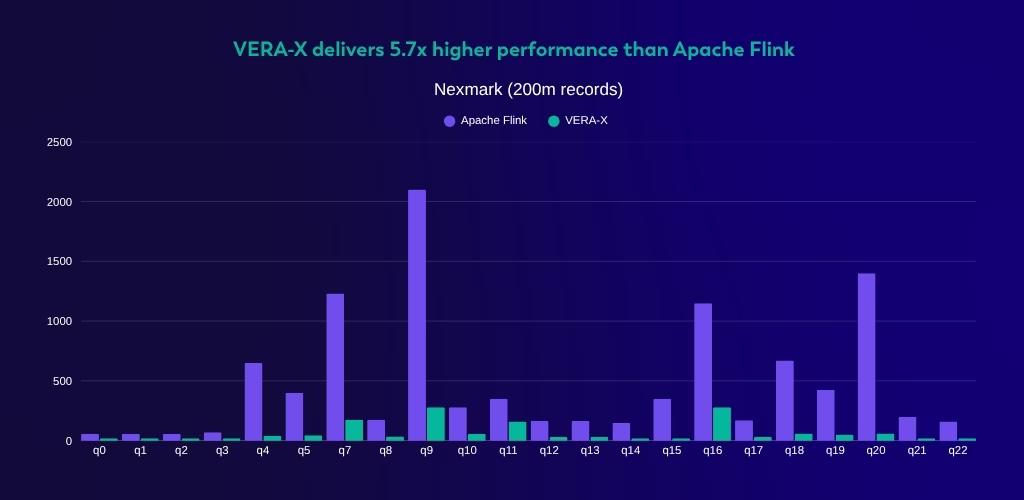
### Batch Workloads
Although VERA-X is built for streaming first, its architectural innovations also carry over to batch queries. Thanks to the same vectorized execution and optimized state access, batch analytics tasks benefit from:
- **2–3x faster execution times** compared to Flink’s Java runtime.
- **3.1x faster execution times** compared to Apache Spark 3.4.3.
- Lower CPU overhead translates into reduced cluster costs.
- The ability to **unify stream and batch pipelines** on a single platform simplifies architecture.
#### How the benchmarks were conducted:
Batch benchmarks use a collection of SQL analytical queries (including TPC-H–style queries) executed through Flink SQL. The focus is on evaluating scan, filter, aggregation, and join performance over large datasets. Tests are run with identical resource configurations across engines, comparing end-to-end query completion times and cluster utilization metrics. The improvements highlight how vectorized execution in VERA-X accelerates both streaming and batch jobs consistently.
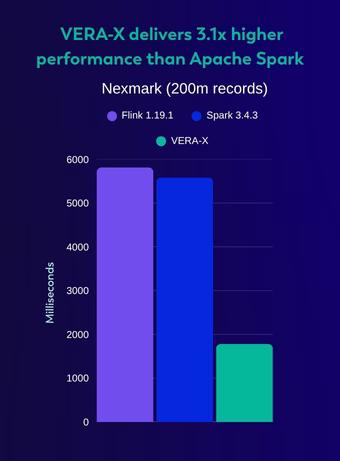
## Ververica: Unlocking What’s Next in Real-Time Data
In closing, **VERA-X** is about the future of Apache Flink and stream processing at large, even for the most demanding use cases. By combining Flink’s robust, battle-tested framework with a state-of-the-art execution engine, Ververica is delivering the best of both worlds: the familiarity and reliability of Apache Flink, and the blazing performance of a modern, vectorized runtime. This innovation empowers our users to tackle use cases that were previously impractical or costly, from **high-frequency analytics** to **real-time AI** and beyond, with greater ease and confidence.
Ververica remains committed to Apache Flink’s open standards and community. VERA-X is built in harmony with Flink, a continuation of our decade-long journey with stream processing technology, and we will continue to contribute back and collaborate on pushing Flink forward. We believe this next-gen engine represents a transformative step for the streaming ecosystem, and we’re incredibly excited to bring our customers along on this journey. Join us in embracing this future, and let’s unlock the full potential of real-time data together!
Ready to try VERA-X?
### More Resources
- [[Use Cases]](https://www.ververica.com/use-case) Learn how to detect and prevent fraud, and build AI systems that learn, adapt, and act in real-time, and more.
- [[Video]](https://www.ververica.com/vera) Learn more about the VERA engine.
---
---
title: "Introducing Apache Fluss™ on Ververica’s Unified Streaming Data Platform"
description: ""
lastUpdated: 2026-06-24T13:51:24.000Z
source_url:
html: "https://www.ververica.com/blog/introducing-apache-fluss-on-ververicas-unified-streaming-data-platform"
md: "https://www.ververica.com/blog/introducing-apache-fluss-on-ververicas-unified-streaming-data-platform.md"
---
The future of data lies in **breaking down the barriers between batch and streaming**. Ververica’s mission is to pioneer a new way of working with data by making insights available immediately, making architectures simpler, and giving organizations the ability to act on their data faster. Today, we are proud to announce the next major step toward that vision: [**Apache Fluss™**](https://www.ververica.com/what-is-apache-fluss) **(incubating) is now part of** [**Ververica’s Unified Streaming Data Platform**](https://www.ververica.com/product)**.**
This represents a turning point for how enterprises can think about real-time data, one beyond Kafka-centric architectures that were not designed and built for analytical use cases. With Apache Fluss, Ververica becomes a complete unified platform to seamlessly deliver ingestion, compute, and storage in one cohesive experience, without the fragmentation that comes with other solutions. No longer are data streams treated as raw event logs waiting to be transported, copied, and transformed across a patchwork of external systems. Instead, they are treated as living, queryable tables, continuously updated, instantly accessible, and ready to power the most demanding business applications, while reducing the need for stitching together multiple systems and products.
## Rethinking Streaming Architectures
For years, organizations have relied on messaging-centric architectures as the backbone of their real-time systems. These technologies excel at transporting large volumes of events, but they were never designed to serve as queryable stores, which is what data pipelines require. As a result, companies are forced to layer additional systems, caches, databases, and warehouses alongside their event log. Every new system results in additional pipelines to build and maintain, data duplication to manage, and latency gaps to tolerate.
This approach creates several challenges, including:
- **Complexity**: maintaining multiple layers for streaming, batching, caching, and analytics results in fragile pipelines with a high operational overhead.
- **Inefficiency**: storing the same data across systems drives up infrastructure costs while also creating inconsistencies between “hot” and “cold” views of the same dataset.
- **Latency**: separating real-time updates from historical storage inevitably means that decision-makers work with partial, fragmented, or outdated information.
- **Schema management:** most data streaming tools like Kafka operate as bytes, meaning that schemas have to be built and managed separately across multiple systems becomes an additional burden, making architectures fragile and costly to operate.
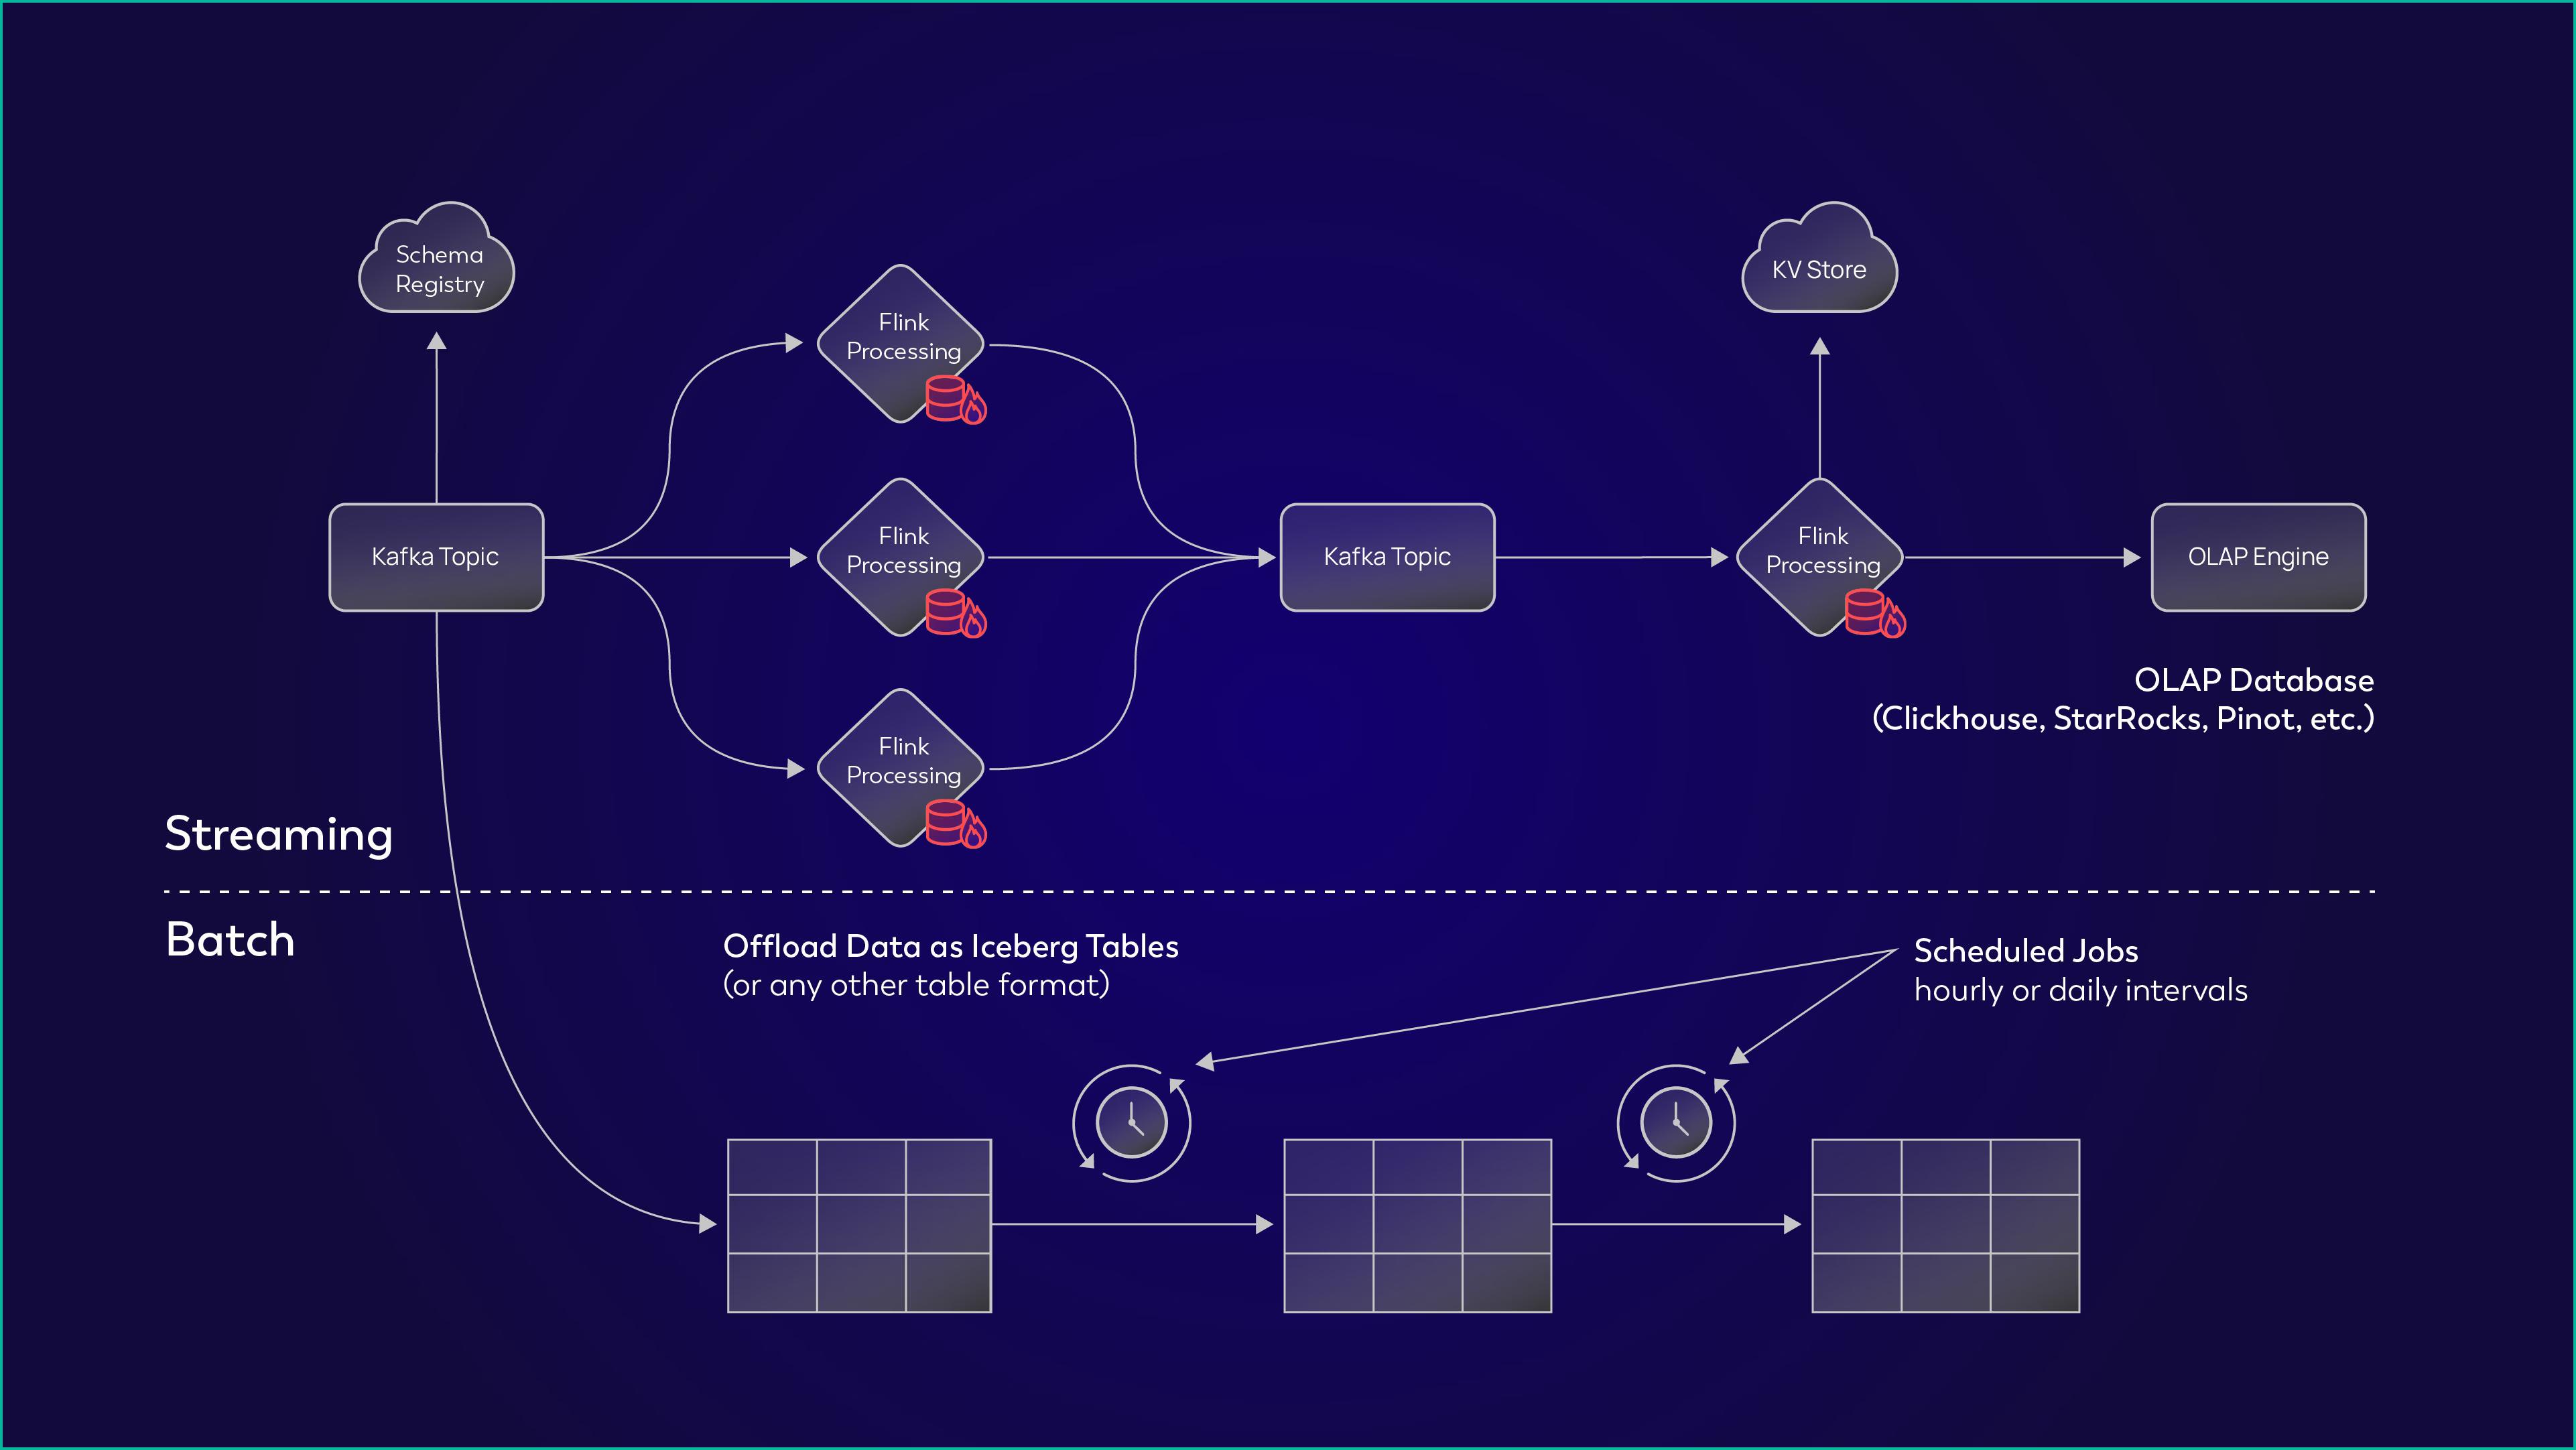
Apache Fluss reimagines this paradigm. Instead of treating a stream as an immutable sequence of events, it **treats streams as tables;** a columnar, queryable storage layer designed for streaming analytics. Every incoming change is immediately reflected in both the [log and an up-to-date table (cache) representation](https://fluss.apache.org/blog/pk-key-tables-log-cache-streaming/). Embracing this duality eliminates the artificial distinction between streams and tables. It enables enterprises to **query data in real time, join it efficiently with other flows, and persist it seamlessly into longer-term lakehouse storage**, all without shuffling data through external systems or writing complex glue code.
## Apache Fluss on Ververica’s Unified Streaming Data Platform
With Apache Fluss now integrated within Ververica, organizations can manage the full lifecycle of real-time data with a single unified solution. Data changes are captured in real time, processed and enriched in motion, and then persisted in Fluss, where they are immediately queryable. This creates a unified architecture that removes the boundaries between ingestion, computation, and storage.
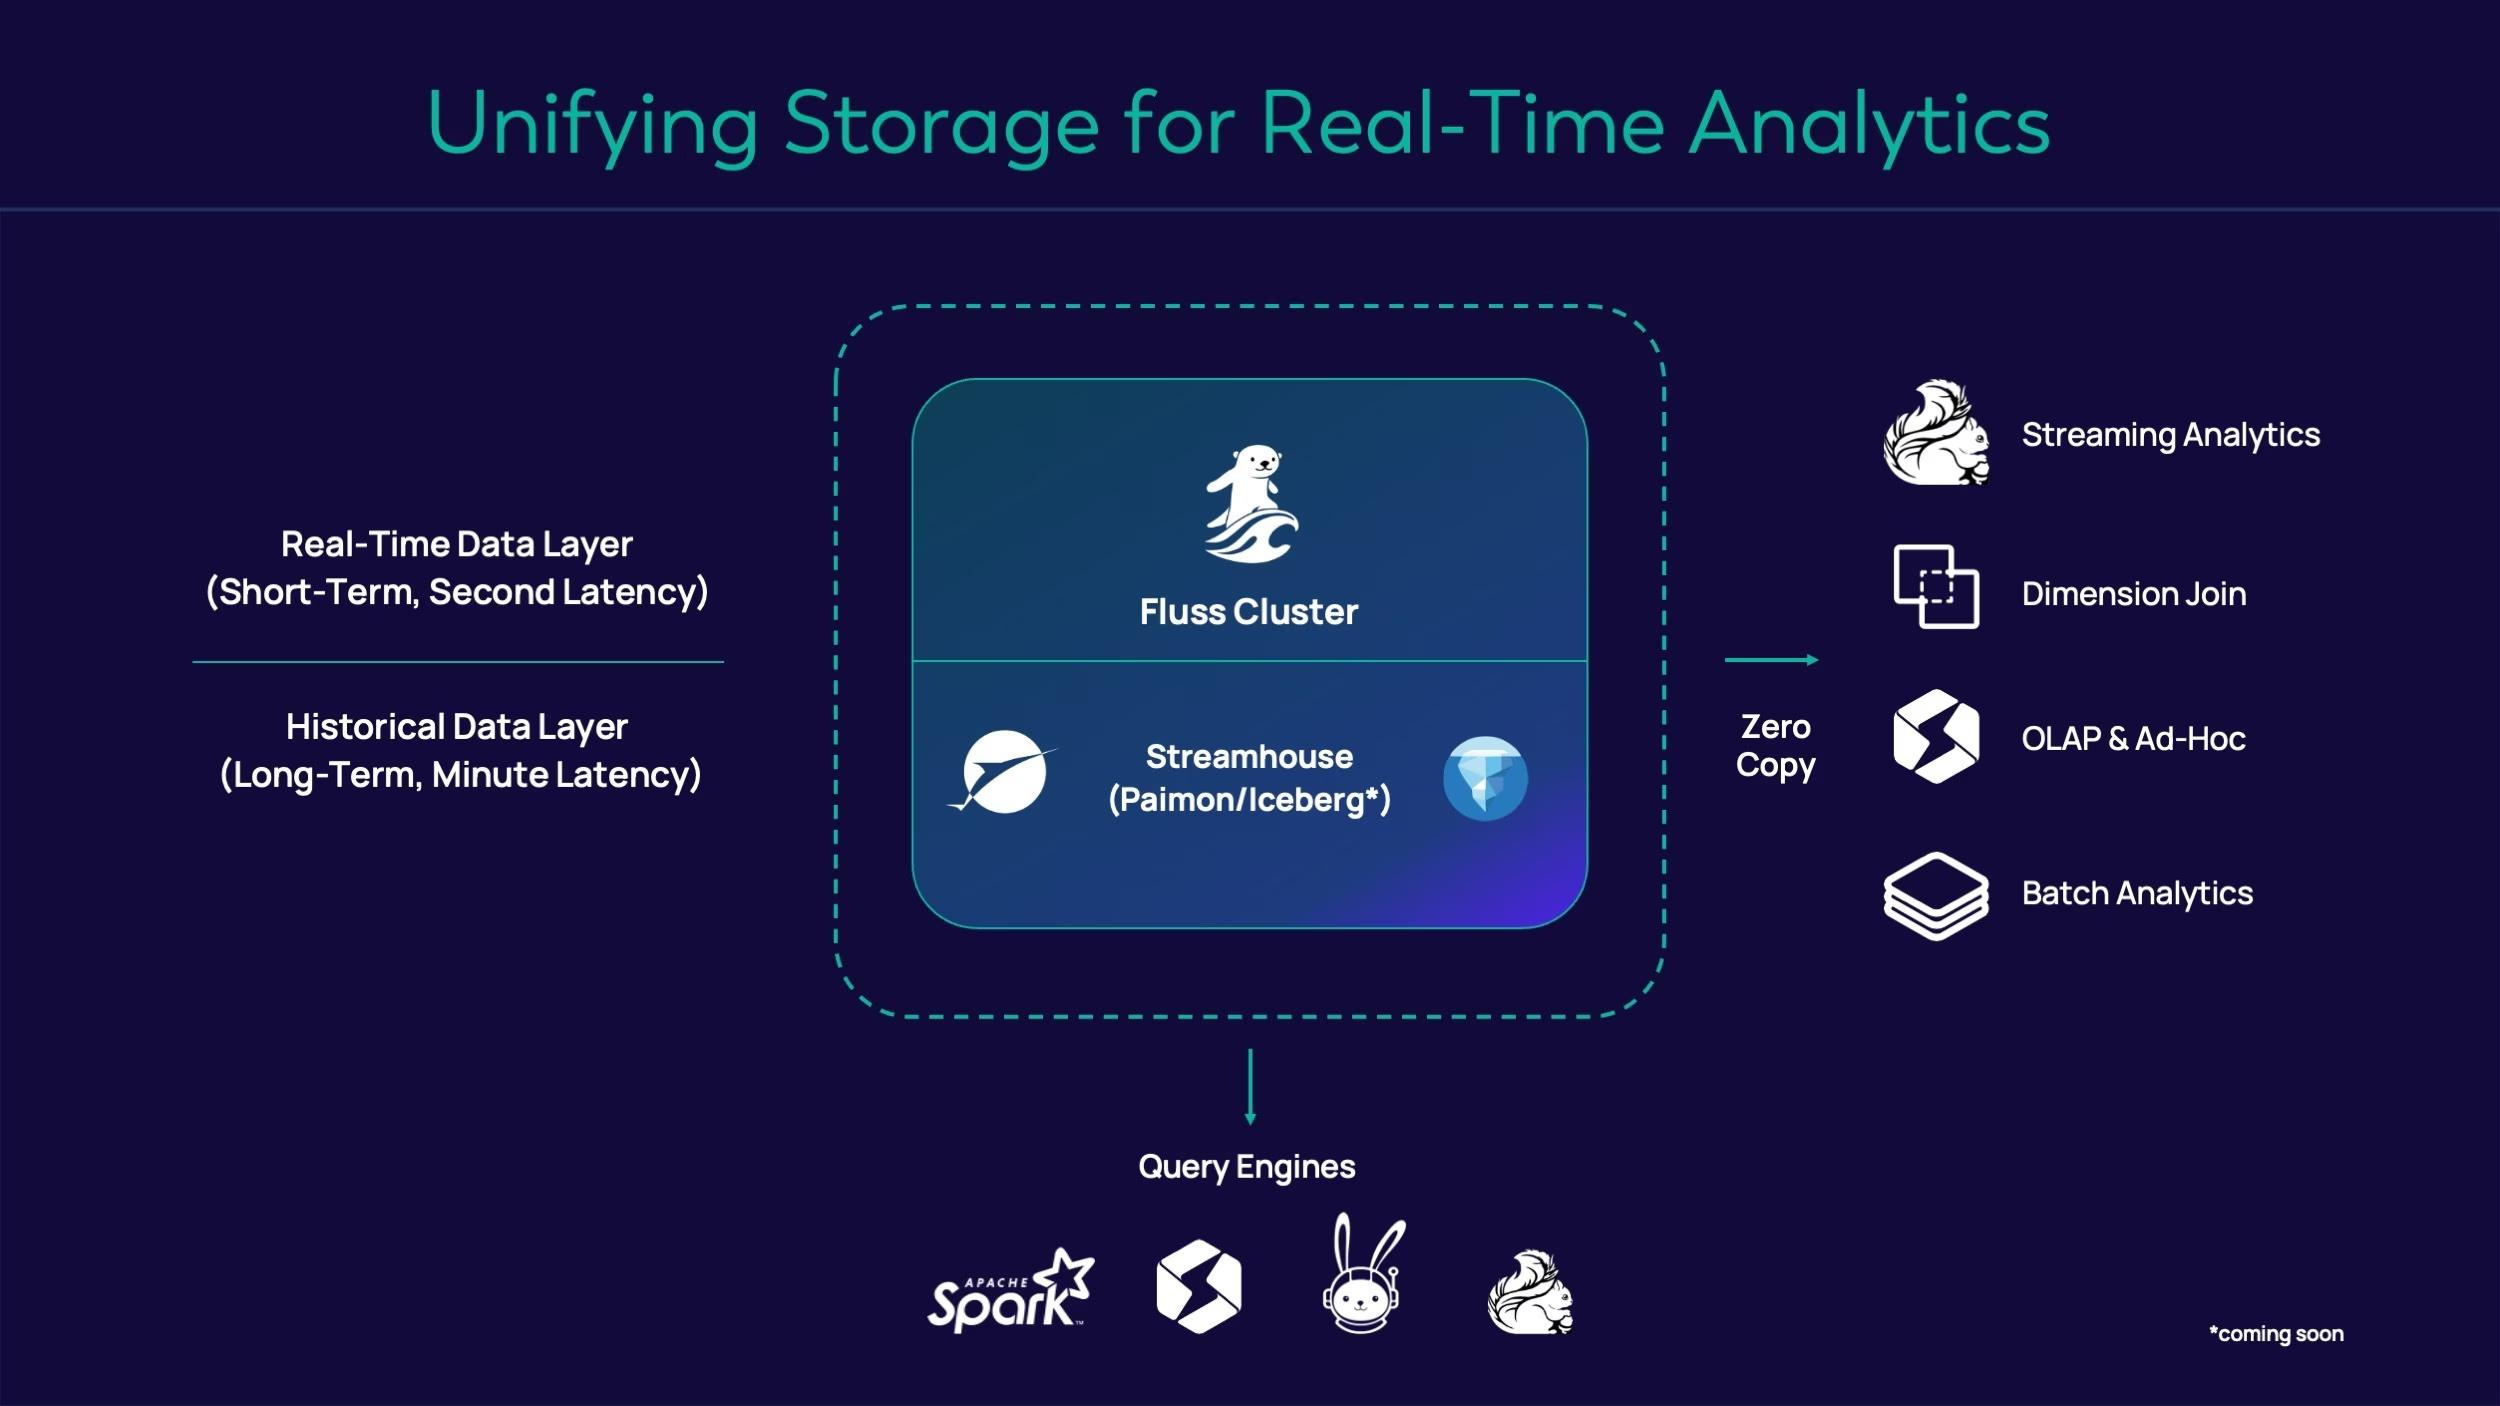
In this architecture, Apache Fluss is not a peripheral component but the **core storage engine** for streaming workloads. It makes it possible to:
- **Unify log and cache semantics in one system**, eliminating the complexity and overhead of managing them separately.
- **Enable “zero-state” streaming analytics**, reducing or even removing the need for massive, unstable stateful jobs by shifting heavy lifting into Apache Fluss.
- **Reduced network data transfer with efficient access patterns**, ensuring only the required columns, partitions, or records are transmitted, with no wasted network or storage costs.
- **Serve hot data and tier seamlessly into the lakehouse**, with shared metadata, consistent partitioning and bucketing, and the ability to combine real-time and historical queries in a single, unified view.
- **Power multi-modal and AI workloads**, with native support for modern formats such as Lance, making streaming pipelines ready for ML features, embeddings, and vector search.
This unified design allows enterprises to build applications where the freshest data is always available for queries, joins, and analytics, without detours through external databases or caches. It makes Ververica the **only truly unified platform** where organizations can connect, process, store, analyze, and govern data in real-time, all at sub-second latency.
## How Apache Fluss Completes Ververica’s Streamhouse Vision
As we’ve continued to develop Ververica’s Unified Streaming Data Platform and the [Streamhouse](https://www.ververica.com/streamhouse) concept, one area that’s posed challenges is the [real-time](https://www.ververica.com/vera#real_time) layer. While existing architectures can ingest and compute data with low latency, they often lack a storage layer that can simultaneously support analytics, queries, and statefulness without compromise.
Streamhouse is Ververica’s answer to bridging lakehouse and streaming, a concept meant to enable “real-time lakehouse” behavior. But until now, the real-time tier has gaps: it can’t fully deliver sub-second queryability, low-latency joins at scale, nor the seamless transition between streaming and historical workloads.
In other words, Fluss makes the Streamhouse vision complete, a single platform where ingestion, compute and storage converge, and where real-time and historical data are no longer separate worlds, but rather one unified solution.
**Learn more about bringing the Streamhouse to real-time in the 2024 blog:** [From the Kappa Architecture to Streamhouse: Making the Lakehouse Real-Time](https://www.ververica.com/blog/from-kappa-architecture-to-streamhouse-making-lakehouse-real-time)
## Ververica: An AI-Ready Solution
Apache Fluss also sets the foundation for AI-native data architectures. By treating streams as queryable tables and supporting modern formats like [Lance](https://lancedb.github.io/lancedb/) and [LanceDB](https://lancedb.com/), Fluss makes it possible to handle the ingestion of multimodal data, text, images, audio, video, and embeddings in real time. This enables use cases such as similarity search, retrieval-augmented generation (RAG), and multimodal analytics directly on live data, while seamlessly tiering older data into Lance-powered lakehouse storage for training and retraining.
Fluss can also serve as a real-time feature store, eliminating the need for separate online and offline layers. Features are always fresh, always queryable, and always consistent across inference and training. This unified approach simplifies ML pipelines, reduces duplication, and ensures models learn and adapt continuously from the latest data.
With Apache Fluss, Ververica customers get one unified solution where AI, multimodal workloads, and real-time analytics converge, all with sub-second latency.
## From Complex Pipelines To Real-Time Business Value
The impact of Apache Fluss within Ververica’s solution can be realized in every dimension of modern data architectures. For engineering teams, it means simpler systems that collapse what used to be a complex chain of tools into one cohesive platform. Pipelines that once required careful orchestration of multiple technologies can now be built and operated directly within Ververica, accelerating time-to-market and reducing risk.
For business leaders, it means faster and more reliable insights. Because data in Apache Fluss is both log and table, every change is queryable the moment it occurs. Real-time dashboards update continuously, and applications can respond to events with sub-second freshness. Decisions are no longer delayed by hours or days of batch processing, nor distorted by inconsistencies between systems.
For organizations at scale, Apache Fluss drives efficiency and cost savings. By reducing network transfer, offloading heavy state from compute jobs, and consolidating hot and cold data, workloads that once consumed thousands of cores can now run with a fraction of the resources. This translates into lower infrastructure costs and stronger ROI.
And for enterprises preparing for the AI-driven future, Apache Fluss provides an AI-ready foundation. With support for multi-modal data and AI, it erases the gap between operational and analytical data, enabling intelligent systems that learn, adapt, and act in real time.
## A New Day for Streaming In The Age Of AI
With Apache Fluss, Ververica is once again setting the standard for the industry. Just as we redefined stream processing with Flink, we are now redefining streaming storage. The combination of the two in one enterprise-ready platform creates an end-to-end real-time data platform that is unified, efficient, and ready for the age of AI.
This sets the blueprint for the next generation of real-time architectures. It is a way to finally collapse the silos between streams and the lakehouse, operational and analytical, and to replace them with a single, living, flowing system. This is different from other solutions, which stitch together disparate systems and solutions and are inherently fragmented and difficult to manage as a result.
Fluss was named for the German word for “river”. Ververica’s Unified Streaming Data Platform ensures your organization’s river of continuous data flows efficiently, smoothing out the path ahead for a new era of data-driven business and instant insights and results.
A Private Preview of Fluss on Ververica Platform will be available soon. Stay tuned.
[Contact us](https://www.ververica.com/contact)
## More Resources
Check out these helpful resources to learn more about Streamhouse, Fluss, and Flink:
- [Blog] [From Kappa Architecture to Streamhouse: Making the Lakehouse Real-Time](https://www.ververica.com/blog/from-kappa-architecture-to-streamhouse-making-lakehouse-real-time)
- [Blog] [Primary Key Tables: Unifying Log and Cache for 🚀 Streaming](https://fluss.apache.org/blog/pk-key-tables-log-cache-streaming/)
- [Video] [Fluss: Reinventing Kafka for the Real-Time Lakehouse](https://www.youtube.com/watch?v=OzE0mVD0GPs)
- [Video] [Optimizing Streaming Analytics with Apache Flink and Fluss](https://www.youtube.com/watch?v=GKsE_EUR9yU)
---
---
title: "Ververica Platform 3.0: The Turning Point for Unified Streaming Data"
description: "End the batch vs streaming divide. Flink-powered lakehouse with 5-10× faster processing, real-time AI, and unified data platform. Discover Platform 3.0."
lastUpdated: 2026-04-20T12:32:21.000Z
source_url:
html: "https://www.ververica.com/blog/ververica-platform-3-0-the-turning-point-for-unified-streaming-data"
md: "https://www.ververica.com/blog/ververica-platform-3-0-the-turning-point-for-unified-streaming-data.md"
---
The world of data has been changing rapidly. In 2025, businesses need to make decisions in real time, deliver [personalized customer experiences](https://www.ververica.com/use-case/customer-360) instantly, and enable applications that [learn and adapt](https://www.ververica.com/use-case/ai-ml) on the fly. Yet most data platforms remain fragmented, forcing teams to stitch together ingestion, processing, storage, and analytics across a patchwork of systems.
On top of that, companies are often forced to choose between [batch or streaming](https://www.ververica.com/stream-processing-with-apache-flink-beginners-guide) approaches. Batch systems provide reliability for historical analysis, while streaming delivers low-latency insights, but each lives in its own silo, with different tooling, infrastructure, and results. This fragmentation leads to complexity, higher costs, and slower innovation.
With the launch of Ververica Platform 3.0, we’re changing that. This release represents a turning point: Ververica has evolved into a complete [Unified Streaming Data Platform](https://www.ververica.com/). For the first time, you can connect, process, store, analyze, and govern your data end-to-end, all in a single platform designed for the speed and scale of modern data applications without compromise, and without choosing between batch and streaming.
## A Platform Built for the Future of Data in the Age of AI
From its origins as the commercial home of Apache Flink®, Ververica stands at the forefront of stream processing. With Ververica Platform 3.0, we are extending that heritage into something broader, a foundation that combines real-time stream processing, streaming storage, and advanced analytics with the governance and security enterprises demand.
This new release introduces three major innovations that bring the vision to life:
### VERA-X: Redefining Stream Processing
At the heart of the release is **VERA-X**, the new stream processing engine. VERA-X is the first **native vectorized execution engine for Apache Flink**, a leap forward in performance and efficiency. By optimizing how Flink executes queries at a low level, it delivers 5–10× higher throughput and single-digit millisecond latency on streaming benchmarks, while cutting infrastructure costs by up to 50%.
VERA-X is also not just for streaming. Batch queries run 2–3× faster than Flink’s Java runtime and up to 3.1× faster than [Apache Spark](https://spark.apache.org/)™ 3.4.3, all with zero changes to existing Flink applications.
For developers and operators, this means you can continue to use familiar Flink APIs and SQL while benefiting from a next-generation engine that’s built for the workloads of tomorrow.
**Learn more about VERA-X in the new blog:** [“VERA-X: Introducing the First Native Vectorized Apache Flink® Engine”](https://www.ververica.com/blog/vera-x-introducing-the-first-native-vectorized-apache-flink-engine)
### Apache Fluss: Completing the Streamhouse Vision
The [Streamhouse](https://www.ververica.com/blog/streamhouse-unveiled) unifies real-time streaming with the analytical power of the lakehouse. Flink provides best-in-class processing, but what is missing is a storage layer purpose-built for streaming. [Apache Fluss](https://www.ververica.com/blog/introducing-fluss) fills this gap.
Fluss treats streams as queryable tables, continuously updated and instantly accessible, so live data can be processed and analyzed the moment it arrives. This eliminates fragile pipelines and reduces the need for duplicate systems.
In Ververica Platform 3.0, Fluss works side by side with open table formats such as Apache [Paimon](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse)™ and Apache [Iceberg](https://iceberg.apache.org/)™. Fluss keeps the fresh, real-time data always available, while [Paimon](https://paimon.apache.org/) or Iceberg provide the historical persistence needed for large-scale analytics and governance. Together, they bridge the worlds of operational and analytical data.
This combination brings clear benefits:
- Unified view of live and historical data without stitching multiple systems together.
- Efficiency through less duplication and reduced infrastructure overhead.
- AI-readiness with vector search, real-time feature stores, and retrieval-augmented generation (RAG) directly on streaming data.
With VERA as the engine, Fluss as the live data store, and Paimon or Iceberg for historical data, Ververica Platform 3.0 delivers the complete Streamhouse vision — one cohesive platform for data in motion and at rest.
**Curious to learn more about Apache Fluss? Read the blog:** [“Introducing Apache Fluss™ on Ververica’s Unified Streaming Data Platform”](https://www.ververica.com/blog/introducing-apache-fluss-on-ververicas-unified-streaming-data-platform)
### Real-Time AI With Rag And LLM Support
Another exciting development in 3.0 is the arrival of real-time AI capabilities directly within the platform. With new [retrieval-augmented generation](https://en.wikipedia.org/wiki/Retrieval-augmented_generation) (RAG) and [large language model](https://en.wikipedia.org/wiki/Large_language_model) (LLM) support in Flink SQL, you can now bring the power of AI into your streaming pipelines.
This means enriching live data with context-aware insights, powering conversational interfaces that respond to the most recent events, or enabling AI-driven decision-making at the moment data arrives. Real-time AI is no longer a future vision, it’s something you can build today on Ververica Platform 3.0.
## No More Choosing Between Batch and Streaming
For years, organizations had to choose: build for batch or build for streaming. Batch systems offer reliability for historical data analysis, while streaming systems provide low-latency insights. But each lived in its own world, with different tooling, data models, and infrastructure. With Ververica, that complexity is removed, as both batch and streaming pipelines are unified into a singular solution.
At the heart of everything we do at Ververica is a streaming-first design philosophy. Whether your workload is continuous streaming or large-scale batch analytics, both are treated as first-class citizens to Apache Flink. This ensures consistency across workloads, eliminating the old divide between “real-time” and “historical” systems.
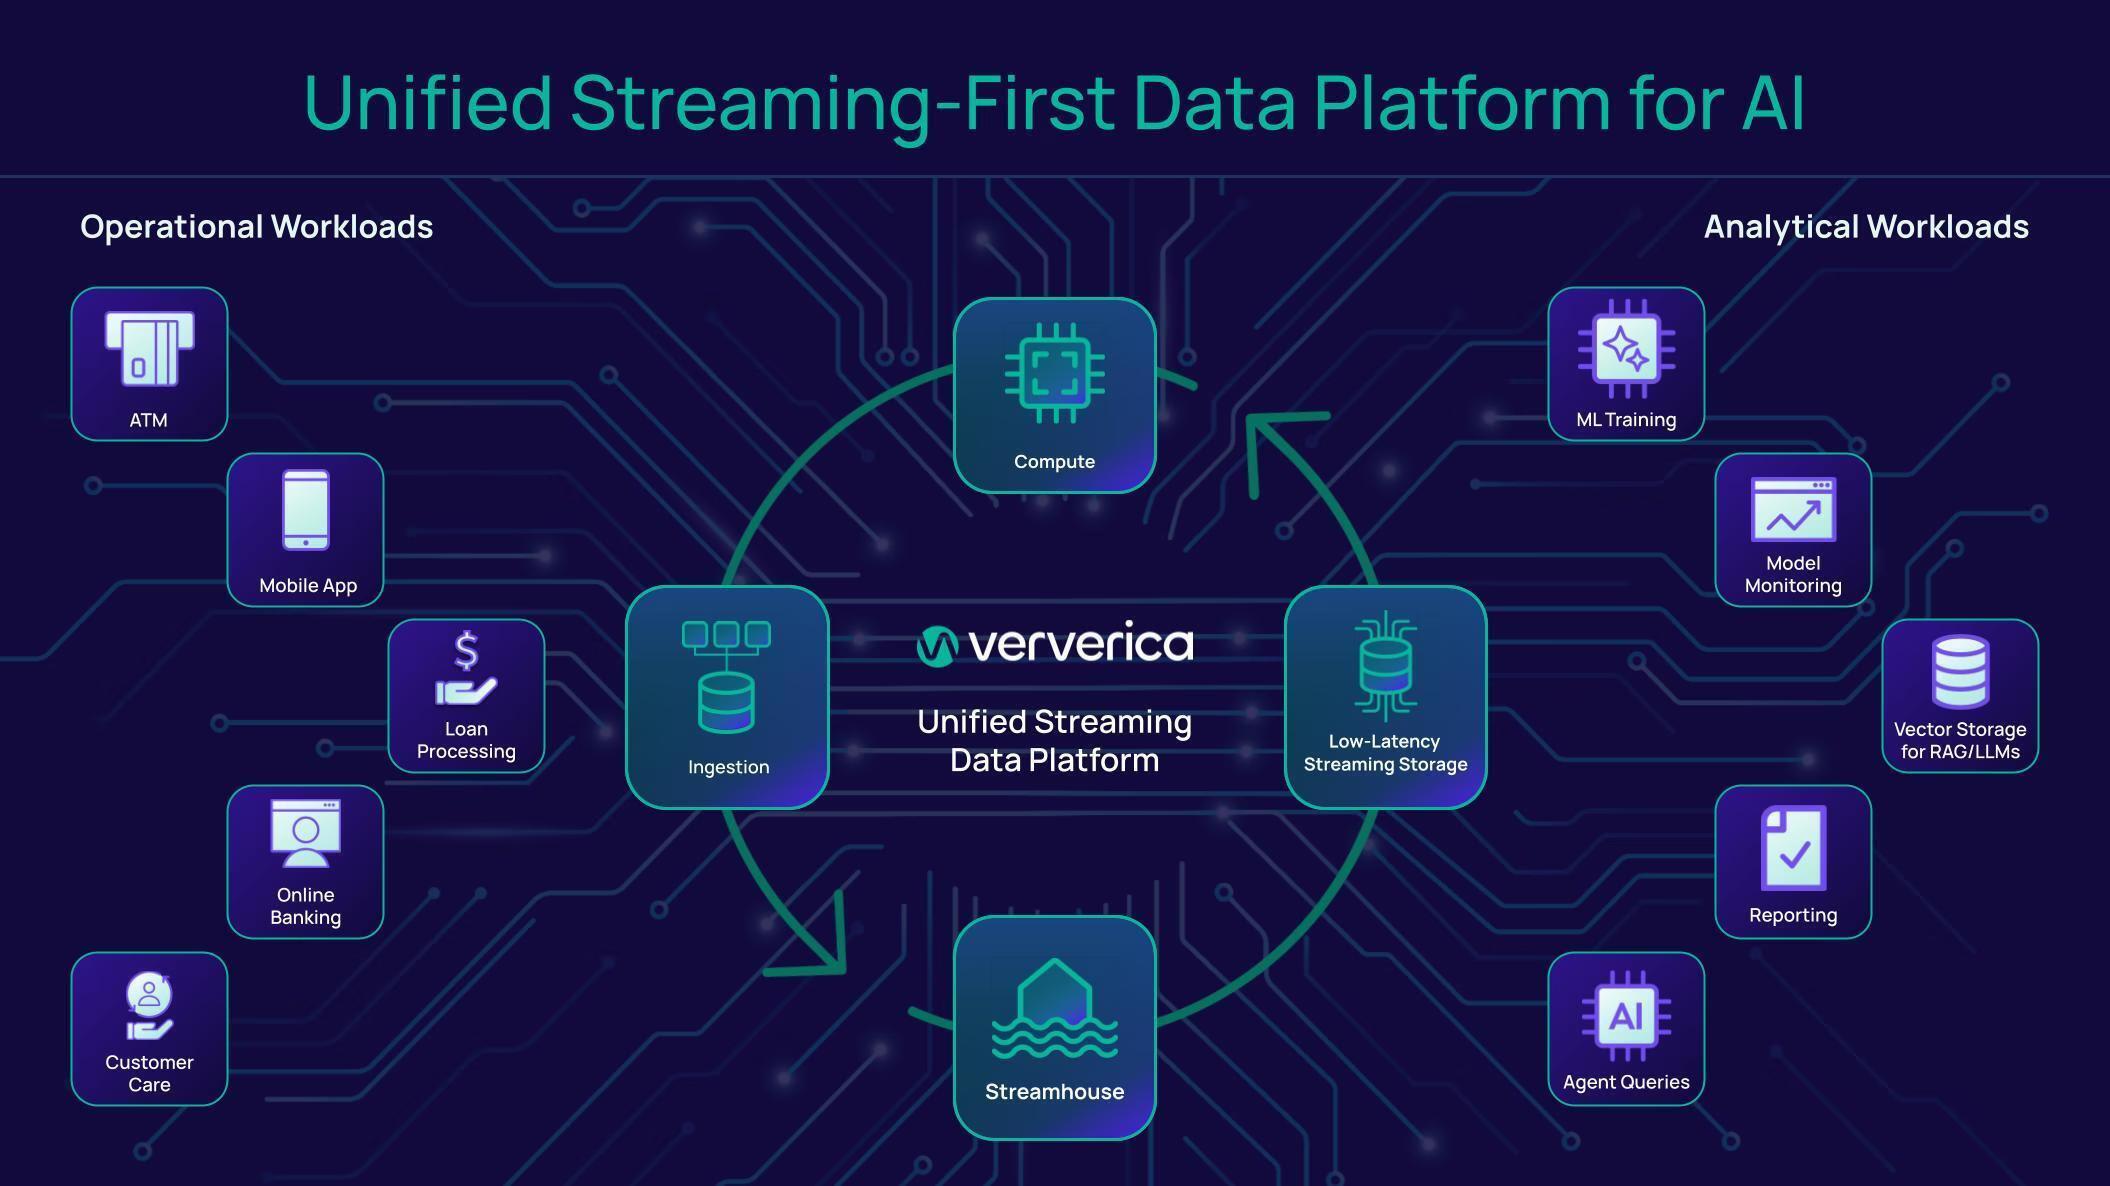
With Ververica Platform 3.0, any trade-offs disappear. By unifying batch and streaming, you gain:
- **One platform, one model**: Whether data is live, or historical, developers now work with a single API and SQL dialect.
- **Consistent results**: between batch-processed reports and real-time dashboards disappear, as both are powered by the same engine.
- **Simplified operations**: Reduce complexity and operational overhead with a single unified runtime and storage layer.
- **Faster innovation**: Teams can combine real-time and historical context seamlessly, powering richer analytics and more intelligent applications.
- **Cost efficiency**: Unified infrastructure means less duplication and fewer moving parts to manage.
This convergence of batch and streaming is what makes Ververica Platform 3.0 truly powerful - the best of both worlds, working together.
## The Value of a Unified Approach
Ververica Platform 3.0 is more than a product release. It represents a shift in how organizations can think about their data. Instead of managing separate systems for ingestion, processing, storage, analytics, and AI, you now have a single platform that does it all.
For enterprises, this means:
- **Simplicity**: Fewer moving parts and tighter integration across the data stack.
- **Performance**: A next-gen engine that scales with your needs.
- **Flexibility**: Support for both operational and analytical workloads in one place.
- **Innovation**: Built-in AI capabilities that allow you to experiment and deploy faster.
- **Governance and trust**: Enterprise-grade security and management, ensuring your data is protected.
- **Unified data experience**: No more silos between real-time and batch processing. Everything comes together in a single platform.
## A Turning Point for Ververica
Ververica Platform 3.0 represents a new era for both us and our users. From its roots in Apache Flink to the innovations of VERA-X and Fluss, we’ve always believed in the power of data in motion. Now, with the unification of batch and streaming, and the arrival of real-time AI, that belief becomes reality.
This is the most complete expression yet of our vision: a **streaming-first, unified data platform** that powers the applications of tomorrow.
And this is only the beginning. Ververica Platform 3.0 is not just a turning point for our product; it is the **foundation of real-time AI**. Because AI that truly matters is AI that acts on the freshest data, adapts instantly, and learns continuously. That requires more than static snapshots of the past; it requires a platform where streams and historical context come together seamlessly, where data is always alive, and where intelligence is built into the flow.
That is what Ververica Platform 3.0 delivers. The future of real-time AI starts here.
---
---
title: "Alibaba Cloud, Ververica, Confluent, and LinkedIn Join Forces on the Streaming AI Agents Innovation with Apache Flink®"
description: "Alibaba Cloud, Ververica, Confluent, and LinkedIn collaborate to launch Apache Flink Agents, enabling real-time, event-driven AI applications"
lastUpdated: 2026-03-17T12:47:43.000Z
source_url:
html: "https://www.ververica.com/blog/alibaba-cloud-ververica-confluent-and-linkedin-join-forces-on-the-streaming-ai-agents-innovation-with-apache-flink"
md: "https://www.ververica.com/blog/alibaba-cloud-ververica-confluent-and-linkedin-join-forces-on-the-streaming-ai-agents-innovation-with-apache-flink.md"
---
A landmark collaboration to build scalable, production-grade framework for event-driven streaming agents powered by Apache Flink.
Today at [Flink Forward Barcelona 2025](https://www.flink-forward.org/barcelona-2025), we announced the first release of Apache Flink Agents, a major collaboration between Alibaba Cloud, Ververica, Confluent, and LinkedIn—four influential companies in the Streaming Data area—to jointly develop and contribute a new open-source sub-project from the Apache Flink community designed to bring AI agents into the world of real-time, event-driven systems. This initiative marks a pivotal step toward industrial-scale AI applications that react instantly and autonomously to live data streams.
## Why Apache Flink Agents Matters
While AI agents have made rapid progress in interactive applications like chatbots, most still operate outside the high-throughput, low-latency world of real-time data processing. Yet in industrial settings, from e-commerce and finance to IoT and logistics, critical decisions must be made instantly in response to live events: a payment failure, a sensor anomaly, a user click.
These workloads demand more than just intelligence, they require massive scale, millisecond latency, fault tolerance, and stateful coordination, all of which are strengths of Apache Flink. But until now, there’s been no unified framework to bring agentic AI patterns into this proven streaming ecosystem. [Apache Flink Agents](https://github.com/apache/flink-agents) bridges this gap.
## Introducing Apache Flink Agents
Apache Flink Agents, a brand-new sub-project from the Apache Flink community, is an open-source framework for building event-driven streaming agents. Building on Flink's battle-tested streaming engine, Apache Flink Agents inherits **distributed, at-scale, fault-tolerant structured data processing and mature state management,** and adds first-class abstractions for Agentic AI building blocks and functionalities - large language models (LLMs), prompts, tools memory, dynamic orchestration, observability, and more.
This initiative is the result of a community-based joint effort by developers from [Alibaba Cloud](https://alibabacloud.com/), [Ververica](https://www.ververica.com/), [Confluent](https://confluent.io/), and [LinkedIn](https://www.linkedin.com/), a group of engineers with deep expertise in large-scale stream processing and real-time AI. By combining our experience in production-grade data infrastructure and intelligent systems, we are aligning on a shared vision: **bringing Agentic AI into the streaming data ecosystem, where it can operate with scalability, reliability, and real-time responsiveness.**
The key features of Apache Flink Agents include:
- **Massive Scale and Millisecond Latency:** Processes massive-scale event streams in real time, leveraging Flink's distributed processing engine.
- **Seamless Data and AI Integration:** Agents interact directly with Flink's DataStream and Table APIs for input and output, enabling a smooth integration of structured data processing and semantic AI capabilities within Flink.
- **Exactly-Once Action Consistency:** Ensures exactly-once consistency for agent actions and their side effects by integrating Flink's checkpointing with an external write-ahead log.
- **Familiar Agent Abstractions:** Leverages well-known AI agent concepts, making it easy for developers experienced with agent-based systems to quickly adopt and build on Apache Flink Agents without a steep learning curve.
- **Multi-Language Supports:** Provides native APIs in both Python and Java, enabling seamless integration into diverse development environments and allowing teams to use their preferred programming language.
- **Rich Ecosystem:** Natively integrates mainstream LLMs, vector stores from diverse providers, and tools or prompts hosted on MCP servers into your agents, while enabling customizable extensions.
- **Observability:** Adopts an event-centric orchestration approach, where all agent actions are connected and controlled by events, enabling observation and understanding of agent behavior through the event log.
### Looking ahead
This initial version provides core agent abstractions, integrates Flink's DataStream and Table APIs, supports Kafka-based action consistency, integrates with selected LLMs and vector stores, includes MCP support, and offers observability through event logs.
This milestone marks the beginning of a powerful new framework for building scalable, event-driven AI agents on top of Apache Flink. For more information, visit the [Apache Flink GitHub repository](https://github.com/apache/flink-agents).
Detailed timelines, design discussions, and community input can be found in the [GitHub Discussions section](https://github.com/apache/flink-agents/discussions) your go-to place to follow and contribute to the project’s evolution.
If you're passionate about building intelligent, autonomous systems that react in real time to streaming events, Flink Agents is a project worth watching and joining. We warmly invite developers, contributors, and AI enthusiasts to get involved and help shape the future of event-driven AI with Apache Flink.
### Learn more
- Read our in-depth blog: [Flink Agents: An Event-Driven AI Agent Framework Based on Apache Flink](https://www.alibabacloud.com/blog/flink-agents-an-event-driven-ai-agent-framework-based-on-apache-flink_602505)
- Watch the presentation from Flink Forward Asia Singapore 2025: Flink Agents – [The Agentic AI Framework based on Apache Flink](https://www.youtube.com/watch?v=9g7CC_MyFrw)
- Explore the original proposal: [FLIP-531: Initiate Flink Agents as a new Sub-Project](https://cwiki.apache.org/confluence/display/FLINK/FLIP-531%3A+Initiate+Flink+Agents+as+a+new+Sub-Project)
The future of AI isn’t just smarter models, it’s smarter systems that act continuously, reliably, and at scale.
With Apache Flink Agents, we’re building that future together.
---
---
title: "Ververica Announces Strategic Collaboration with AutoMQ"
description: "Ververica and AutoMQ partner to deliver cost-efficient, high-performance real-time data streaming solutions for enterprises."
lastUpdated: 2026-03-17T10:55:41.000Z
source_url:
html: "https://www.ververica.com/blog/ververica-automq-unlock-real-time-data-value-at-much-lower-cost"
md: "https://www.ververica.com/blog/ververica-automq-unlock-real-time-data-value-at-much-lower-cost.md"
---
We’re excited to announce a new partnership between [Ververica](https://www.ververica.com/vera) and [AutoMQ](https://www.automq.com/)! By combining our strengths in stream storage and processing, we deliver a more efficient, reliable, and cost-effective real-time data streaming solution, empowering enterprises to unlock the full potential of real-time data and build **next-generation real-time applications**
In today’s data-driven world, businesses demand unprecedented speed and efficiency in data processing. Batch processing can no longer meet the urgent needs of scenarios such as real-time risk control, recommendation, and monitoring. Stream processing has become the inevitable choice—but its implementation still faces challenges, including limited data throughput, low elasticity, complex operations, and high Total Cost of Ownership (TCO).
By joining forces, **AutoMQ and Ververica** are tackling the challenges of real-time data streaming, enabling enterprises to build end-to-end pipelines with higher efficiency and lower cost.
## About AutoMQ
[AutoMQ](https://www.automq.com/?utm_source=automq_ververica_partner) is a cloud-native streaming data platform. Its core product, **AutoMQ for Kafka,** is 100% compatible with the Apache Kafka® API. With architectural innovations such as storage-compute separation and automated elasticity, AutoMQ enables extreme scalability while reducing costs by up to **90%** . Positioned as the **"central nervous system"** for enterprise real-time data, AutoMQ delivers massive throughput and durable reliability to power mission-critical event streams.
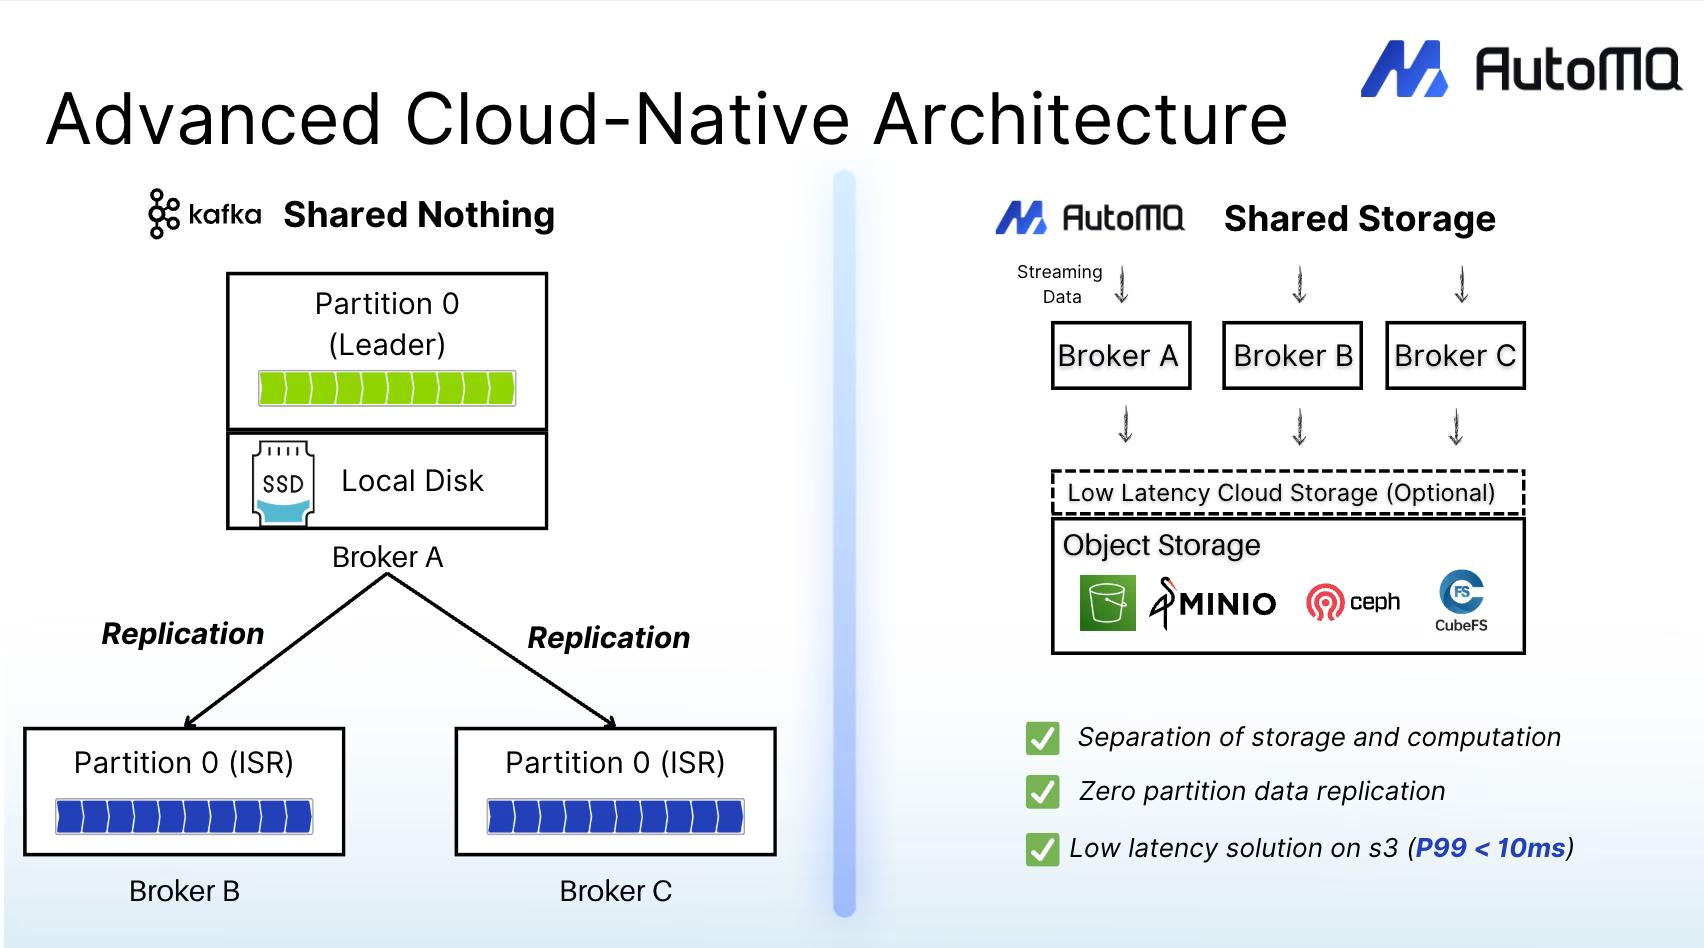
## How AutoMQ and Ververica Work Together
Enterprises building real-time streaming architectures often face high infrastructure costs from overprovisioning, operational complexity in scaling stream processing jobs, and the challenge of meeting the strict latency requirements of applications such as financial risk control and personalized recommendations.
To solve these challenges, **AutoMQ and Ververica have jointly launched an end-to-end cloud-native streaming solution:**
1. **Unified Architecture:** At the **storage layer**, AutoMQ replaces legacy components with a fully Kafka-compatible messaging interface, persisting data into cost-efficient object storage (e.g., AWS S3). Its storage-compute separation and automated elasticity eliminate cost and scalability barriers in messaging. At the **processing layer** , Ververica delivers the full power of Apache Flink with enterprise-grade management and operations, simplifying the development and management of complex streaming jobs.
1. **Seamless Integration:** AutoMQ’s storage-compute separation ensures data durability and elasticity, while Ververica enables workload-aware scaling of Flink clusters. Both layers communicate natively without manual configuration, allowing enterprises to quickly build high-performance streaming pipelines.
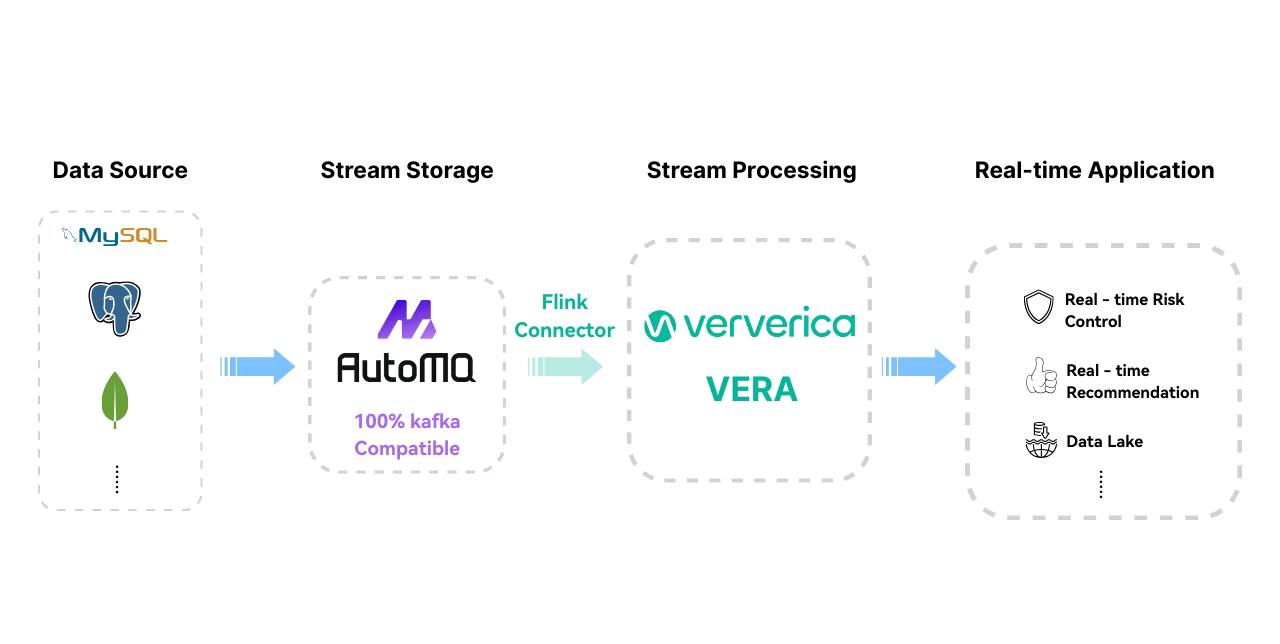
## What It Brings
This joint solution delivers not just technical synergy, but **tangible business value** across industries:
- **High Performance & Elasticity:** Millisecond-level latency with second-level scaling in both messaging and computation—enabling enterprises to handle traffic spikes effortlessly.
- **Cost Efficiency at Scale:** AutoMQ reduces messaging costs by up to 90% through object storage, while Ververica enhances developer and operator productivity, lowering overall TCO.
- **Operational Simplicity:** Unified monitoring, diagnostics, and automated recovery streamline daily operations and reduce management overhead.
- **Developer Productivity:** Developers can quickly build real-time applications using familiar Kafka APIs and Flink SQL, without rewriting existing code.
- **Reliability & Resilience:** Durable data persistence with AutoMQ and fault-tolerant processing with Ververica ensure consistent business continuity even under failure scenarios.
## Looking Ahead
The strategic partnership between AutoMQ and Ververica will continue driving enterprise digital transformation, delivering **high-performance, cost-efficient, and easy-to-operate real-time data pipelines** . These solutions empower mission-critical applications in domains such as financial risk control, real-time recommendations, and IoT.
This is just the beginning. Together, AutoMQ and Ververica will keep enhancing integration, optimization, and industry-focused solutions within a broader ecosystem.
**Ready to explore these solutions for yourself?**
Learn more about [AutoMQ](https://www.automq.com/?utm_source=automq_ververica_partner) – fully Kafka-compatible for seamless streaming integration.
---
---
title: "Modernizing Sports Betting with Real-Time Data Streaming"
description: "Discover how real-time data streaming is transforming sports betting with instant odds updates, fraud detection, and personalized experiences."
lastUpdated: 2026-03-17T10:56:31.000Z
source_url:
html: "https://www.ververica.com/blog/modernizing-sports-betting-technology-to-empower-live-odds"
md: "https://www.ververica.com/blog/modernizing-sports-betting-technology-to-empower-live-odds.md"
---
> **INFO:** What is real-time data streaming and how does it impact the live sports betting industry?
Real-time data streaming is the continuous flow of data that allows instant processing and analysis as events happen. In sports betting, it enables operators to offer live odds, detect risks instantly, and deliver dynamic in-play experiences that keep bettors engaged.
## The State of Data Streaming in Sports Betting
This blog explores the state of data streaming in the gaming industry in 2025. With the rapid evolution of casual online games, [Esports](https://en.wikipedia.org/wiki/Esports), social gaming platforms, gambling, and other emerging business models, the demand for reliable, scalable data infrastructure has never been greater.
To stay competitive, gaming companies that offer live sports betting need access to data at the moment that data is created. In addition, businesses need real-time observability across their systems, the ability to launch new features quickly, and seamless integrations with cutting-edge technologies like AI/ML, virtual reality, and cryptocurrency. In short, data streaming enables organizations to ingest, connect, process, analyze, and govern data instantly at any scale. This, in turn, transforms key business operations in the competitive sports betting industry.
## Sports Betting: From Batch Processing to Real-Time Data Streaming
The sports betting industry is undergoing a significant technological shift driven by the increasing need for low-latency data pipelines, real-time decision-making, and intelligent automation at scale. As regulatory environments evolve and user demand for in-play betting and instant responsiveness grows, operators are moving away from traditional batch-based architectures in favor of high-throughput, event-driven systems.
At the core of this transformation is [Apache Flink®](https://www.ververica.com/what-is-apache-flink) and [Ververica](https://www.ververica.com/product). Flink is a stateful stream processing open-source project built to handle unbounded data with sub-second latency and exactly-once semantics. Flink empowers sportsbooks to ingest and process live feeds in real time, enabling immediate odds recalculations, anomaly detection, and contextual personalization with high reliability and fault tolerance. In addition, Ververica, founded by the original creators of Apache Flink, offers a production-grade, enterprise solution that is 100% compatible with Flink and designed to meet the real-time demands of industries like sports betting.
Let’s examine how the integration of Flink and real-time data is redefining operational efficiency, user engagement, and risk management in modern sports betting platforms, and why embracing this architecture is essential for staying competitive in a data-intensive, high-frequency environment.
## The Sports Betting Digital Transformation
Technology is undeniably transforming the live sports betting industry, fueling its rapid growth and digital evolution. As of 2025, there are over [24,000 registered sports betting businesses](https://www.statista.com/topics/1740/sports-betting/#:~:text=Number%20of%20businesses%20in%20the,betting%20and%20lotteries%20industry%202025) globally, spanning both online and traditional platforms. However, a substantial and increasing portion of these businesses operate entirely online, reflecting a broader shift toward digital engagement.
Currently, [Statista.com](http://Statista.com) values the sports betting market at approximately **$53.78 billion**, with forecasts suggesting growth to **$93.31 billion** by 2030. Innovations such as advanced mobile applications, machine learning, and artificial intelligence have significantly contributed to this continued growth.
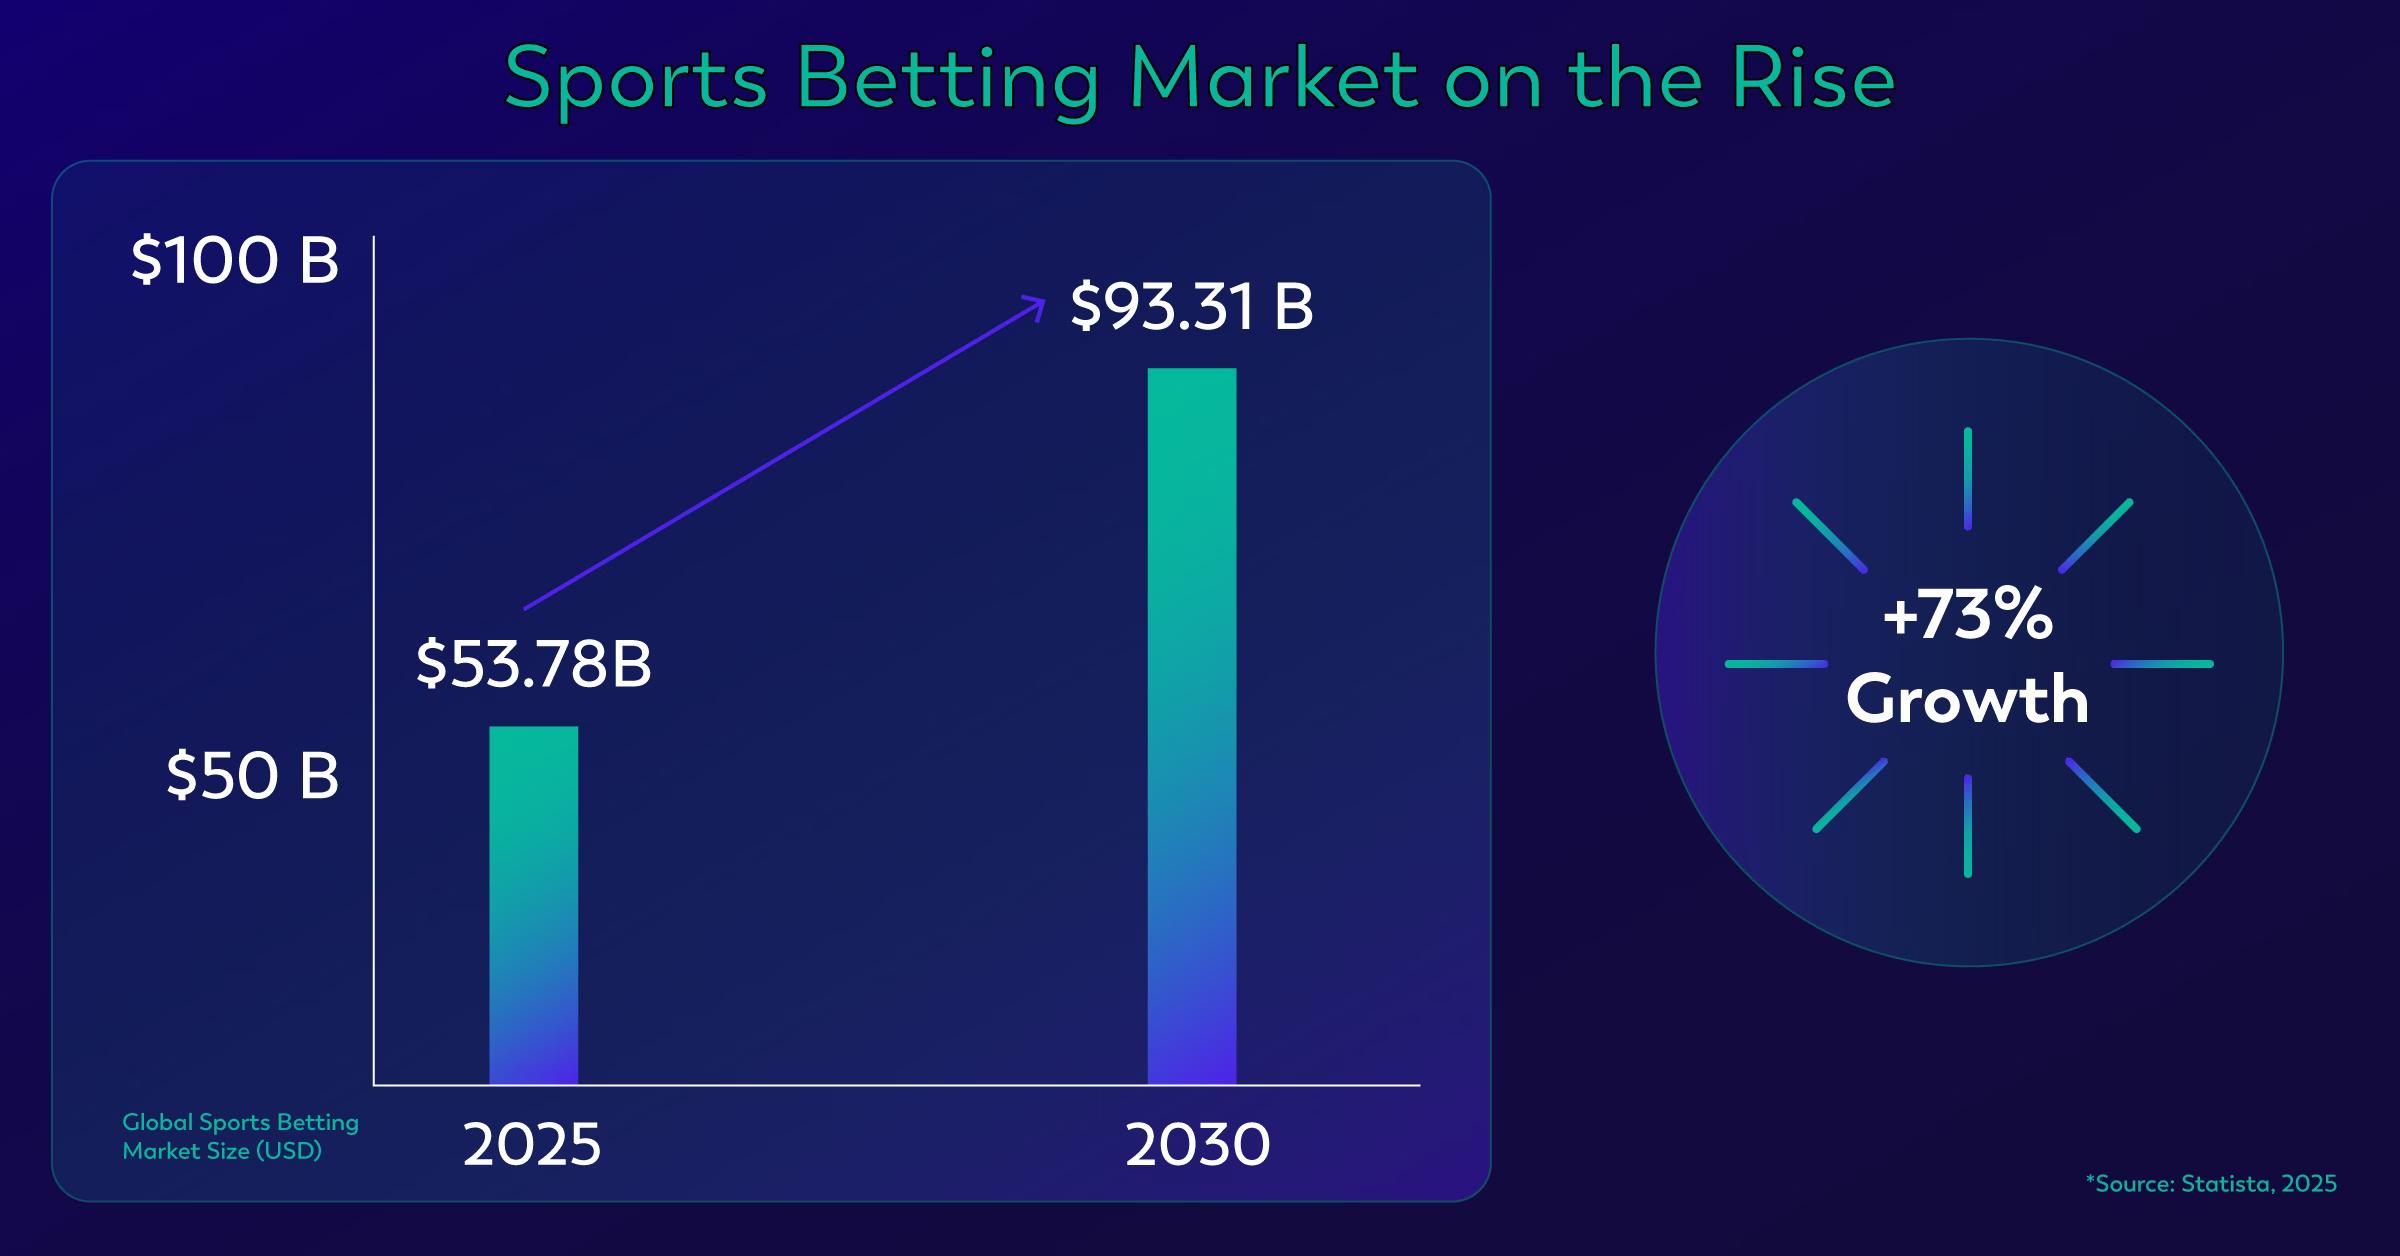
Additionally, cloud computing has provided the scalability necessary to sustain and further propel industry gains. Crucially, the migration from traditional RESTful APIs and batch processing to real-time streaming platforms has enabled the delivery of actionable insights in seconds or milliseconds rather than minutes or hours, unlocking substantial operational and competitive advantages for companies that offer live betting apps, websites, and the like.
## What Does Real-Time Data Streaming Have to Do With Live Betting?
So, what is real-time stream processing, and why does it matter? Real-time stream processing is a computing approach that continuously processes and analyzes data immediately as it arrives, rather than storing it for later analysis. Unlike traditional batch processing, which collects data into batches and processes them at scheduled intervals, often minutes or hours later, real-time streaming processes data instantly, enabling immediate insights and actions.
In the sports betting industry, where odds change by the second and bettors expect immediate responses, batch processing falls short. The delay inherent in batch methods leads to outdated odds, missed betting opportunities, and increased risk exposure. Real-time stream processing technologies, like Flink, ensure betting companies can dynamically adjust odds, detect suspicious patterns instantly, protect against fraud in the moment, and deliver a more engaging, responsive betting experience, which is essential for profitability and competitiveness.
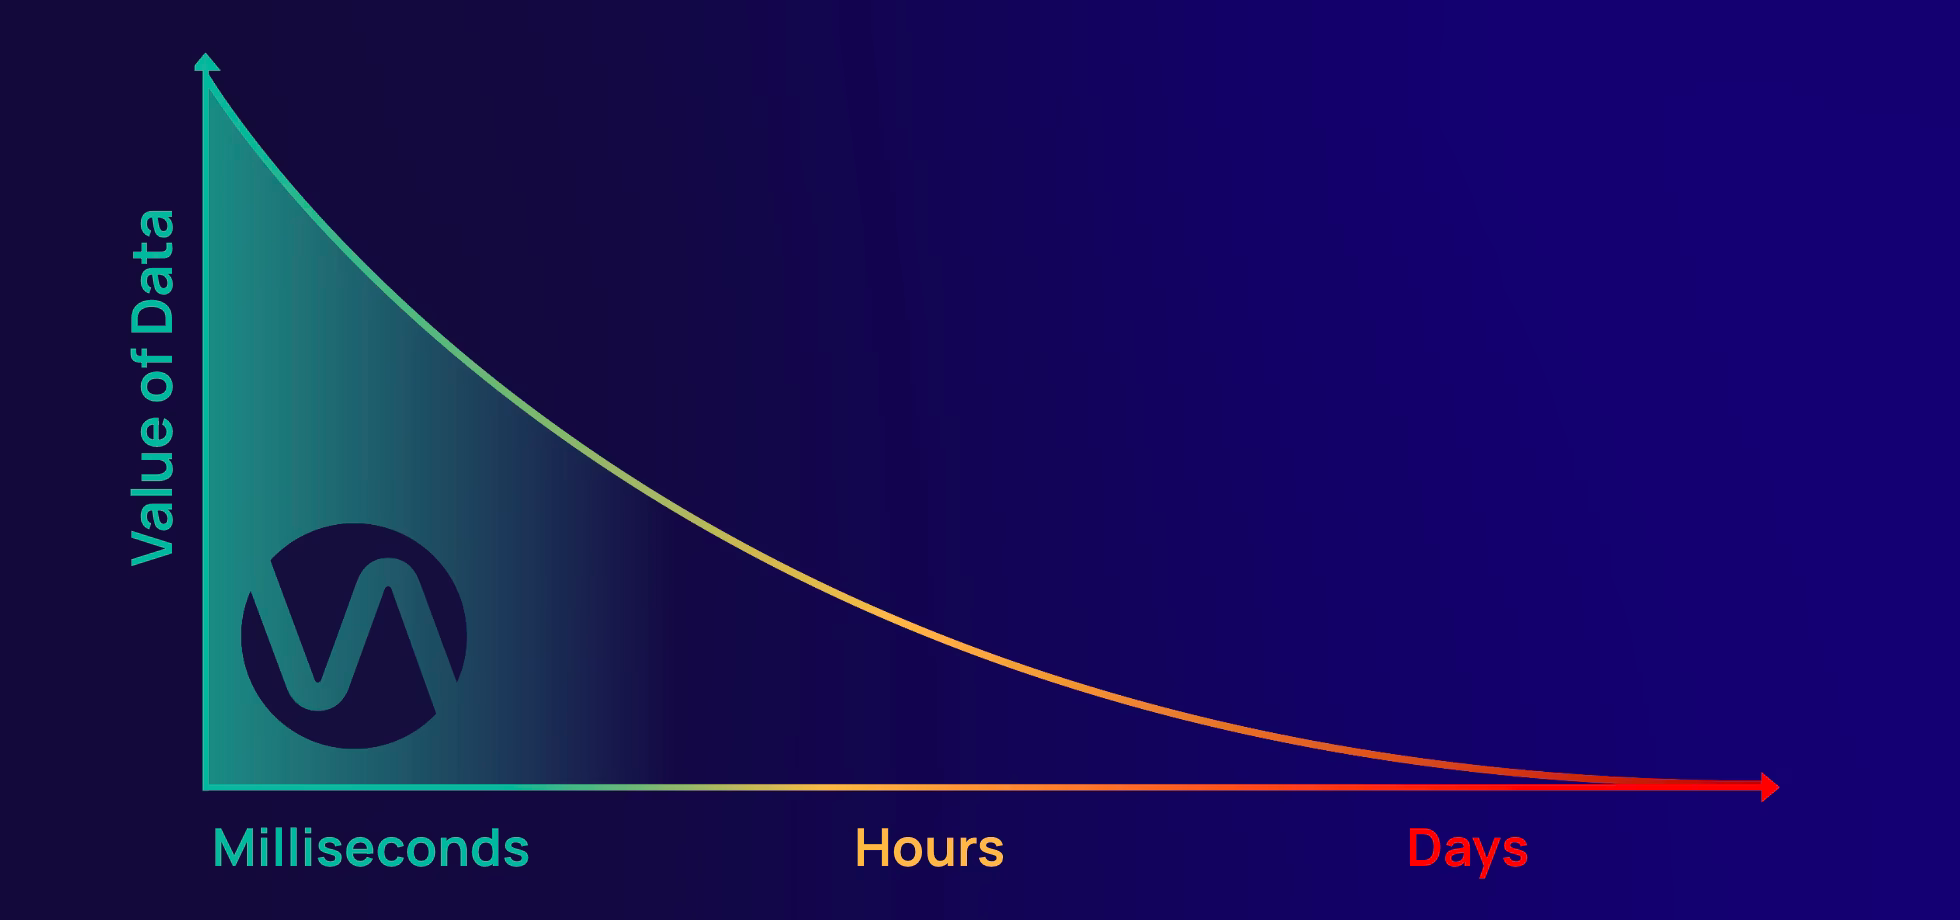
## Why Apache Flink and Real-Time Data are the Real MVPs of Betting Streams
Apache Flink behaves as an engine powering real-time data decisions. It’s an open-source project built to process endless streams of information the moment they happen. Designed to process data quickly, it is ideal for scenarios where milliseconds matter, like fraud detection, live recommendations, or adjusting sports betting odds on the fly.
When compared to other stream processing tools, Flink stands out in the crowd. For example, [Kafka Streams](https://kafka.apache.org/documentation/streams/) is great for lightweight use cases within the Kafka ecosystem, but Flink brings heavyweight power to the table, able to handle complex logic, massive scale, and stateful processing across any data source.
[Spark Structured Streaming](https://spark.apache.org/streaming/) is appropriate for batch-minded teams just dipping into streaming use cases, but its micro-batch architecture can introduce lag while Flink stays truly real-time throughout. Finally, while [Apache Storm](https://storm.apache.org/) helped pioneer the space, Flink is a modern upgrade, as it is fault-tolerant, expressive, and ready for production-grade workloads.
> **NOTE:** In short, if your business runs on live data and split-second decisions, Ververica isn’t just a tool; it’s your competitive edge.
## Odds That Keep Up With Bet Streaming Action
In the fast-paced world of online gambling, timing is everything. The ability to instantly update odds based on live events, like a sudden player injury, a red card, or a game-changing play, can make the difference between profit and loss. Using a real-time data solution like Flink and Ververica, sportsbooks can analyze incoming data streams and adjust odds within milliseconds, keeping them accurate and reflective of current game conditions. This speed not only improves the competitiveness of the business, allowing it to stay ahead of market shifts, but also builds trust with bettors who expect fair, up-to-date lines. The result is a smarter, faster betting experience that drives engagement, reduces risk, and gives operators a significant edge.
## Real-Time Fraud Detection and Risk Response
One of the most well-known and documented real-time data use cases is [fraud detection](https://www.ververica.com/use-case/fraud-detection), where the ability to correlate events, maintain per-user state, and react within milliseconds allows businesses to flag anomalies before they escalate.
Rapid detection of unusual patterns is critical to prevent fraud and minimize risk in the sports betting industry. Utilizing Flink, operators can monitor thousands of bets in real time, identifying suspicious activities like sudden spikes in bets on obscure matches or abnormal wagering behavior across accounts as it happens. This speedy responsiveness allows betting platforms to take immediate action, such as flagging accounts or suspending markets before damage occurs.
For betting operators, this translates into stronger security, smarter risk controls, and a competitive edge built on real-time insight. Figure Three below illustrates real-time fraud detection and response time via Ververica’s Unified Streaming Data Platform, built by the original creators of Apache Flink.
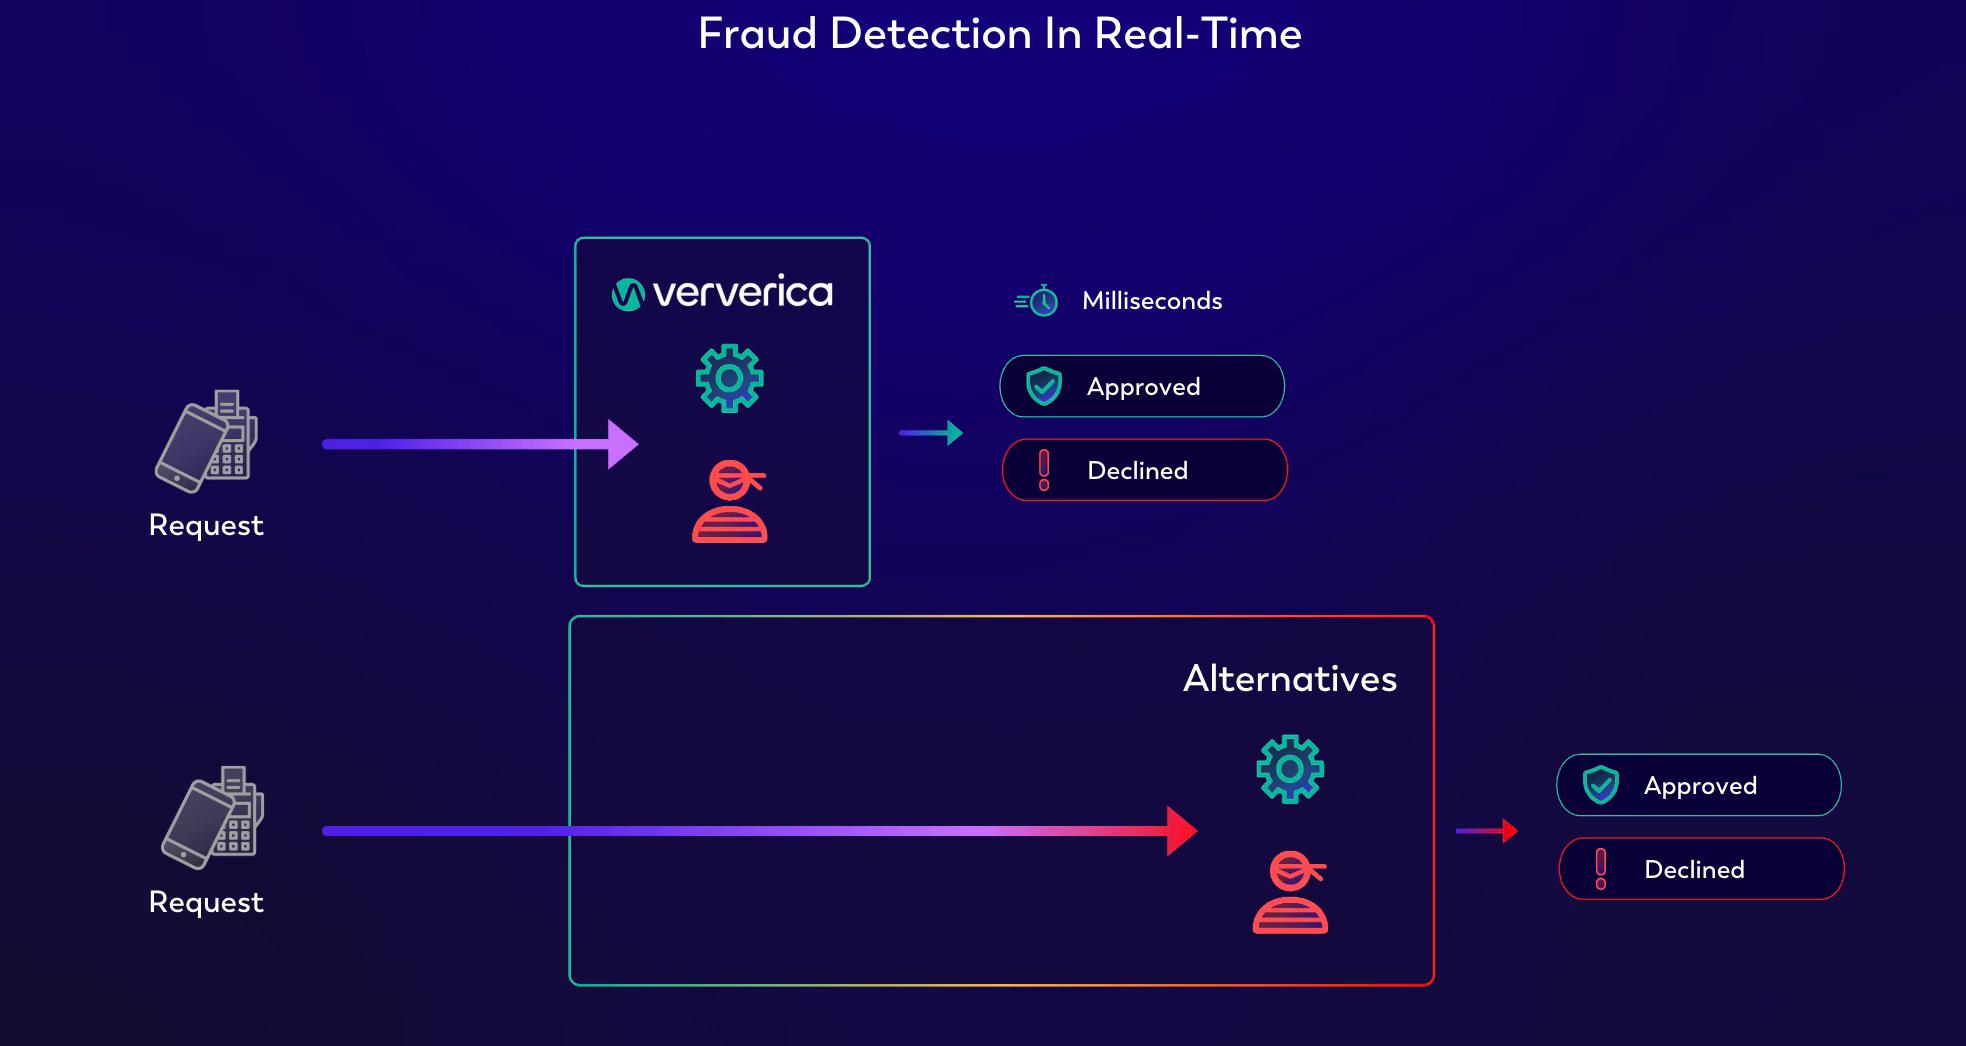
Related to fraud and anomaly detection, Flink also enables dynamic risk exposure management by continuously analyzing betting volumes and liabilities. Sportsbooks can then instantly adjust limits or odds to balance risk, ensuring they stay profitable and protected even in volatile, high-stakes betting environments.
## Personalized Dynamic Bets, Delivered Instantly
User engagement is heavily influenced by timing and [personalization](https://www.ververica.com/use-case/customer-360). Flink empowers operators to deliver real-time notifications, targeted offers (using live odds or live in-play betting), and personalized betting suggestions based on a user’s behavior, preferences, and live game data. Whether it's a push alert for a trending in-play bet or a custom promo triggered by a user's favorite team taking the lead, businesses can enable these dynamic betting interactions to happen within seconds.
This level of immediacy not only keeps bettors actively engaged but also creates a more dynamic and tailored experience. By responding to live events and user actions in real time, sportsbooks can boost conversion rates, increase session times, and foster stronger customer loyalty all through the power of streaming data.
## Predicting the Next Big Play Before It Happens
In-play live betting thrives on immediacy, where every second presents a new opportunity or risk. By harnessing data as it's generated, operators can offer [dynamic betting](https://www.ververica.com/use-case/dynamic-pricing) that evolves with the flow of the game. This can include adjusting lines, introducing new markets, or closing bets at just the right moment.
Real-time analytics and [customer 360](https://www.ververica.com/use-case/customer-360) views also open the door to smarter decision-making behind the scenes. By continuously monitoring how users interact with the betting platform, what markets they favor, how quickly they place bets after certain game events, or how they respond to odds changes, operators can uncover meaningful patterns in bettor behavior. These insights help anticipate shifts in demand, such as increased interest in a specific team, sport, or type of wager during certain scenarios.
Instead of relying on outdated, reactive insights, advanced real-time platforms (like Ververica’s Unified Streaming Data Platform) can leverage machine learning models to generate predictive insights. For example, based on historical data and current trends, systems can forecast which types of bets are likely to spike in popularity during key moments, or identify high-value users who may respond positively to a specific offer. This enables operators to act before trends fully materialize, proactively adjusting odds, launching timely promotions, or even limiting exposure on risky bets. By combining live data with predictive intelligence, operators can optimize engagement, reduce risk, and stay ahead of market shifts in a way that batch-based systems simply can’t match.
## Streamlining Your Stack (and Saving Cash)
Modern betting relies on fast, efficient data pipelines to stay competitive, especially when handling thousands of real-time events per second. With Flink, operators can drastically reduce latency by processing data at the moment it arrives, eliminating delays introduced by traditional batch systems. This real-time approach not only ensures that live odds, user actions, and market insights are handled instantly but also streamlines the flow of information across systems.
By consolidating multiple processing layers into a single, unified pipeline, businesses can:
- Reduce infrastructure complexity
- Minimize data duplication
- Avoid redundant computations
Flink’s ability to dynamically allocate resources and maintain performance under fluctuating loads means operators can deliver a high-speed experience without over-provisioning, making your tech stack leaner, faster, and more cost-effective. Proven at scale by global companies1 like [Alibaba](https://www.alibaba.com/), [Uber](https://www.uber.com/), [Netflix](https://www.netflix.com/), and [Booking.com,](https://www.booking.com/) Flink and Ververica already demonstrate the ability to handle billions of events per day with sub-second latency. For the sports betting industry, this means delivering a high-speed, cost-effective experience that adapts seamlessly to peak loads and real-time demands.
## Who's Already Winning at Live Sports Betting with Real-Time Streaming Data?
Several real-world implementations highlight how real-time data is driving innovation in the betting and real-time analytics industries1. Here are just a few:
- [Flutter Entertainment,](https://www.flutter.com/) the world's leading online sports betting and iGaming operator, currently relies on Ververica to power their real-time live odds calculations.
- In addition, a premier destination for online casino players leverages Flink to power parts of its real-time data infrastructure, enabling faster odds adjustments and more responsive betting experiences.
- Based in Canada, another popular online sports betting company that offers a mobile sportsbook uses Flink for ingesting and analyzing live sports data to support dynamic in-play betting markets.
- In Europe, another leading gaming and betting operator that reportedly supports 33 million users has also adopted Flink to build scalable, real-time pipelines for customer interaction and fraud detection.
Beyond betting, companies like [Booking.com](https://www.booking.com/) currently use Ververica to process billions of events per day, powering features like recommendations, alerts, and fraud monitoring, while also solving customer 360 and personalization use cases.
These implementations demonstrate the importance of combining low latency, scalability, and stateful processing to solve critical, high-volume challenges in sports betting. Next, let’s explore how Ververica’s solution specifically supports these use cases.
## Why Ververica Is the Smart Bet for Real-Time Sports Betting
Built to be 100% compatible with open source Flink, [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product) offers a production-grade, enterprise-grade solution designed for the real-time demands of industries like sports betting. In addition to the robust data streaming found in Flink, Ververica includes advanced features that are critical for powering live odds adjustments, including:
- Autoscaling
- Fine-grained observability
- State lifecycle management
In addition, Vererica’s Unified Streaming Data Platform is powered by [VERA](https://www.ververica.com/vera), a high-performance cloud-native engine that powers real-time data decisions. VERA is built to process endless streams of information the moment they happen, while incorporating historical data into the stream as well. While built using best-in-class open source Flink technologies, Ververica is also lightning-fast (up to 2x+ faster than OS Flink), and is designed to support real-time use cases like fraud detection, live recommendations, or adjusting sports betting odds instantly.
While sports betting use cases heavily rely on real-time data, Ververica offers both batch and real-time data speeds, in addition to being fault-tolerant, expressive, highly scalable, and ready for enterprise-grade workloads. And while Flink itself is already incredibly powerful, Ververica takes this further: providing operational support in addition to offering enterprise-grade security and expertise that is unavailable in any open-source community project.
Armed with commercial support and tools built by the minds behind Flink itself, Ververica enables sportsbooks to run low-latency, high-availability systems with ease and confidence, all at lightning speed. This powers use cases like instant odds recalculations, real-time fraud detection, and personalized user experiences, with enterprise-grade reliability and fault tolerance.
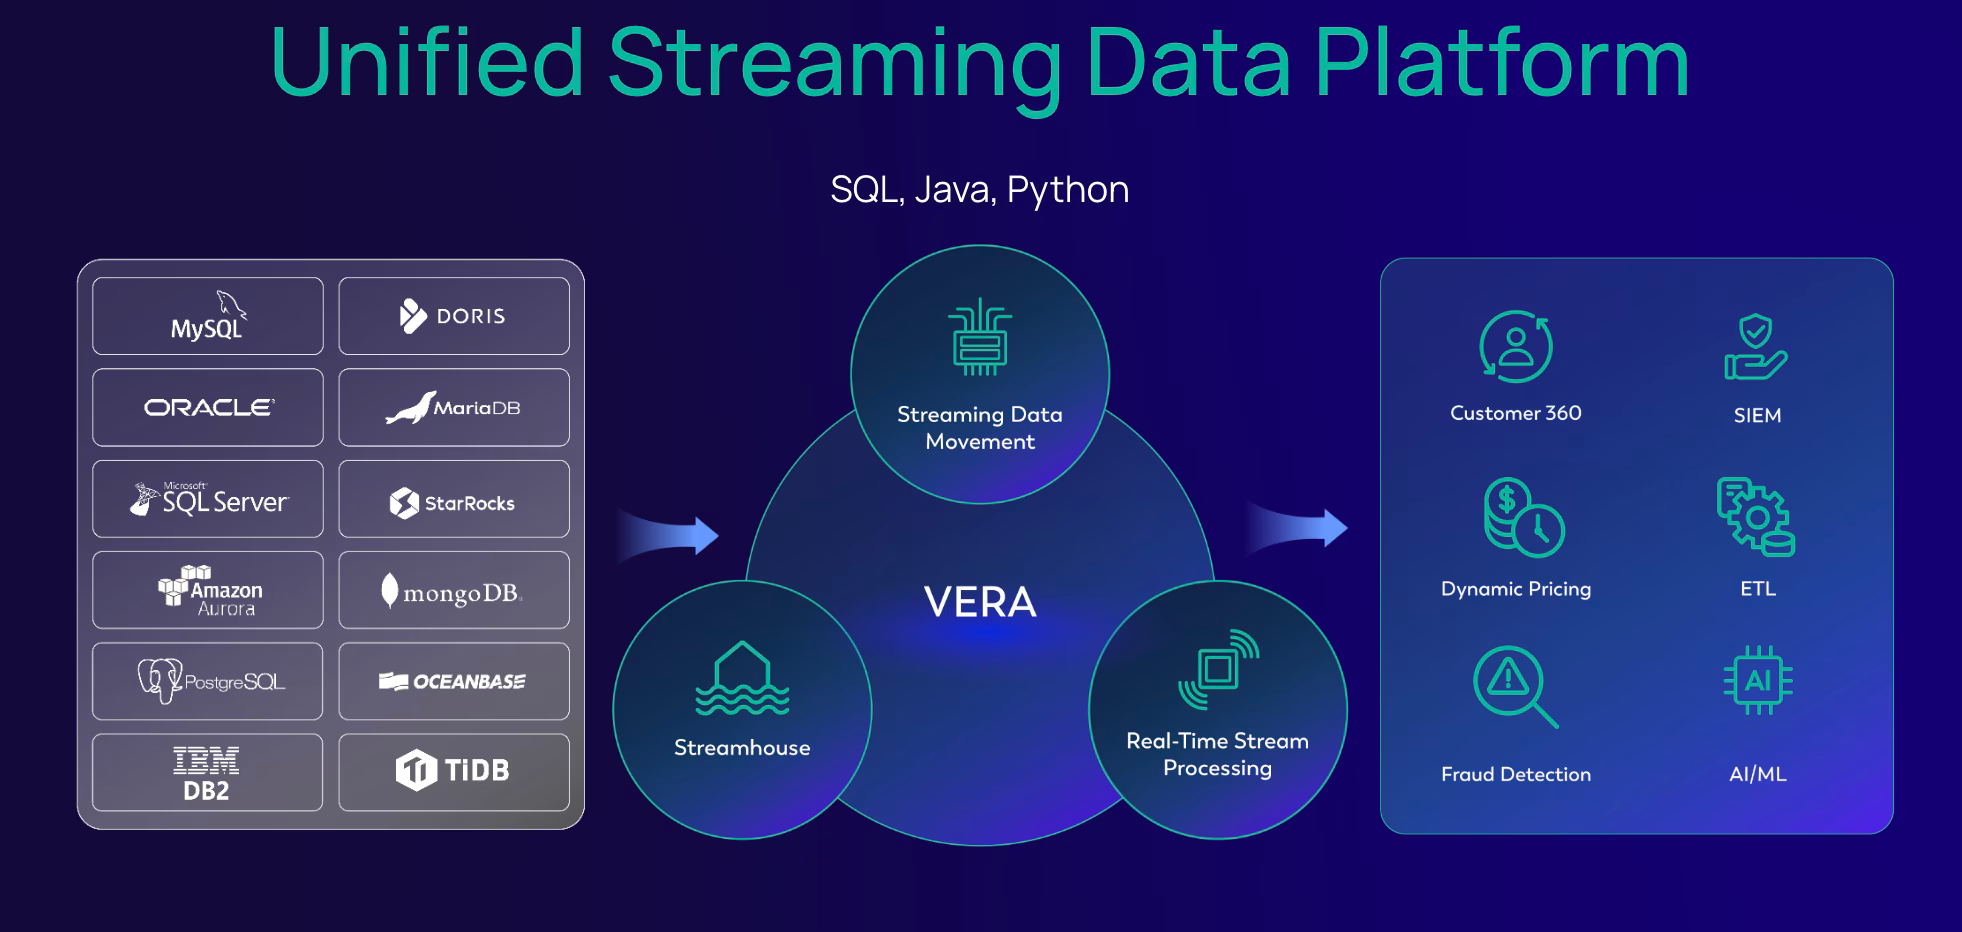
## Looking Ahead: The Future of Sports Betting Is Now
As the sports betting industry continues to evolve, the role of real-time data is becoming increasingly central to its success. Technologies like Flink and solutions like Ververica’s Unified Streaming Data Platform not only enable operators to process and react to live data with unprecedented speed but also lay the groundwork for smarter, more personalized, and more secure betting experiences.
From dynamic odds adjustments to predictive modeling and fraud prevention, Flink and Ververica help operators to make informed decisions in real time, turning data into a competitive advantage. Looking ahead, the integration of emerging technologies such as [real-time AI models](https://www.ververica.com/use-case/ai-ml), contextual personalization, and edge computing will further enhance the capabilities of streaming data systems. As these innovations mature, the future of sports betting will be defined by even faster insights, richer user engagement, and more adaptive, intelligent platforms, all built on the foundation of streaming data.
1 This blog post is based on publicly available information. It is not affiliated with, endorsed by, or sponsored by any of the companies mentioned. All company names and trademarks belong to their respective owners.
## More Resources
- Download the [Gaming Industry One-Pager](https://www.ververica.com/gaming-industry-powered-by-ververica)
- Learn more about [real-time streaming use cases](https://www.ververica.com/use-case)
- Explore how to prevent fraud and detect anomalies instantly in the blog: [Real-Time Fraud Detection using CEP](https://www.ververica.com/blog/real-time-fraud-detection-using-complex-event-processing)
- Do you operate a fast-paced, high-volume digital space? [Ververica can help.](https://www.ververica.com/contact)
---
---
title: "Ververica Expands Its Cloud Offering on Microsoft Azure"
description: "Ververica Cloud now offers a managed service on Microsoft Azure, providing enhanced flexibility, scalability, and seamless integration."
lastUpdated: 2026-03-17T11:04:52.000Z
source_url:
html: "https://www.ververica.com/blog/ververica-expands-its-cloud-offering-on-microsoft-azure"
md: "https://www.ververica.com/blog/ververica-expands-its-cloud-offering-on-microsoft-azure.md"
---
Ververica’s Unified Streaming Data Platform is now available as a managed service deployment on **Microsoft Azure**. This now offers more flexibility of choice between two cloud environments, adding to the established integration with **Amazon Web Services (AWS)**. For existing Azure users, this means they can now run Ververica Cloud: Managed Service with their existing **Azure infrastructure**. This strategic enhancement provides businesses with increased flexibility and scalability by leveraging Microsoft Azure’s infrastructure and services.
## Easier Deployment on Azure
Setting up streaming data applications should be simple. You can now launch and scale up your workloads on Ververica Cloud: Managed Service deployed on Azure without any extra infrastructure management needed.
## Seamless Integration With Azure Services
Ververica deployments integrate with your Azure environment through Azure **"Private Link"**.
This enables secure, private, and efficient **low-latency communication** between Azure services including **Blob Storage, Event Hubs, and PostgreSQL**, allowing you to meet your security compliance requirements and lower your network charges, without sacrificing on performance.
The intuitive UI allows you to develop, deploy, and manage your stream processing applications with ease. Whether you use SQL, Java, or Python, you can move fast and stay focused on building.
## Centralized Billing Through Azure Marketplace
Getting started is simple. Setup only requires a subscription through Azure Marketplace. With the flexibility to choose between plans to adapt to your enterprise needs, you can avoid long procurement cycles.
Centralized billing also helps teams manage budgets and simplify across departments.
## Built for Performance and Scale
**With Ververica Cloud: Managed Service on Azure**, you can harness the full power of VERA, with processing speeds up to **2x faster than open-source Apache Flink**. Expect scalability to support billions of events per second, with data processing latency reduced to milliseconds, ensuring higher throughput and better responsiveness for real-time applications.
## Security and Governance Built In
Ververica Cloud: Managed Service supports **role-based access control** and **workspace isolation** for secure, organized operations across dev, test, and production. You stay in control of access, data, and environments.
## Let’s Get Started
You can get started immediately by using your Ververica Cloud and Microsoft Azure accounts, with billing and subscriptions handled directly through the [Azure Marketplace](https://azuremarketplace.microsoft.com/en-us/marketplace/apps/ververica.vvc_managed). Alternatively, explore more about how Ververica’s Unified Streaming Data Platform can [support you](https://www.ververica.com/deployment/managed-service).
---
---
title: "Global Bank Achieves 90% Cost Savings with Mainframe Offloading!"
description: "Discover how a leading global bank achieved 90% cost savings with Ververica's solution by offloading mainframe workloads to a modern, scalable platform."
lastUpdated: 2026-03-17T11:05:34.000Z
source_url:
html: "https://www.ververica.com/blog/global-bank-achieves-90-cost-savings-with-mainframe-offloading"
md: "https://www.ververica.com/blog/global-bank-achieves-90-cost-savings-with-mainframe-offloading.md"
---
> **INFO:** What is Mainframe offloading?
Mainframe offloading is the process of reducing the workload on traditional mainframe systems by moving specific data processing tasks, applications, or analytics to more modern, scalable, and cost-effective platforms, including cloud-based systems, distributed computing environments, or streaming data platforms.
## Real-World Results: Mainframe Offloading in Leading Banks
In 2025, the ability for businesses to act quickly, adapt seamlessly, and make decisions based on real-time data is no longer just a competitive edge; it's a fundamental requirement for survival. Yet despite the rapid pace of technological innovation, many global financial enterprises feel shackled to legacy mainframe systems.
This is problematic because mainframe architectures were originally designed in the era of batch processing, long before the advent of AI, instant insights, or cloud-native agility were even conceivable. And while these traditional mainframe systems are proven to be reliable and robust, they fundamentally cannot keep up with modern business needs. In this blog, we’ll explore why and how one major financial institution updated their mainframe systems into the modern era.
Innovation is constant for financial industry leaders, including a top-tier global bank that, without sacrificing the reliability of their legacy mainframe systems, recently successfully modernized its decades-old data infrastructure. By reimagining how to use their existing systems (rather than replacing them entirely) **in just three weeks,** the bank achieved transformative results, including:
- **90%** reduction in mainframe processing costs
- **60%** acceleration in job runtime
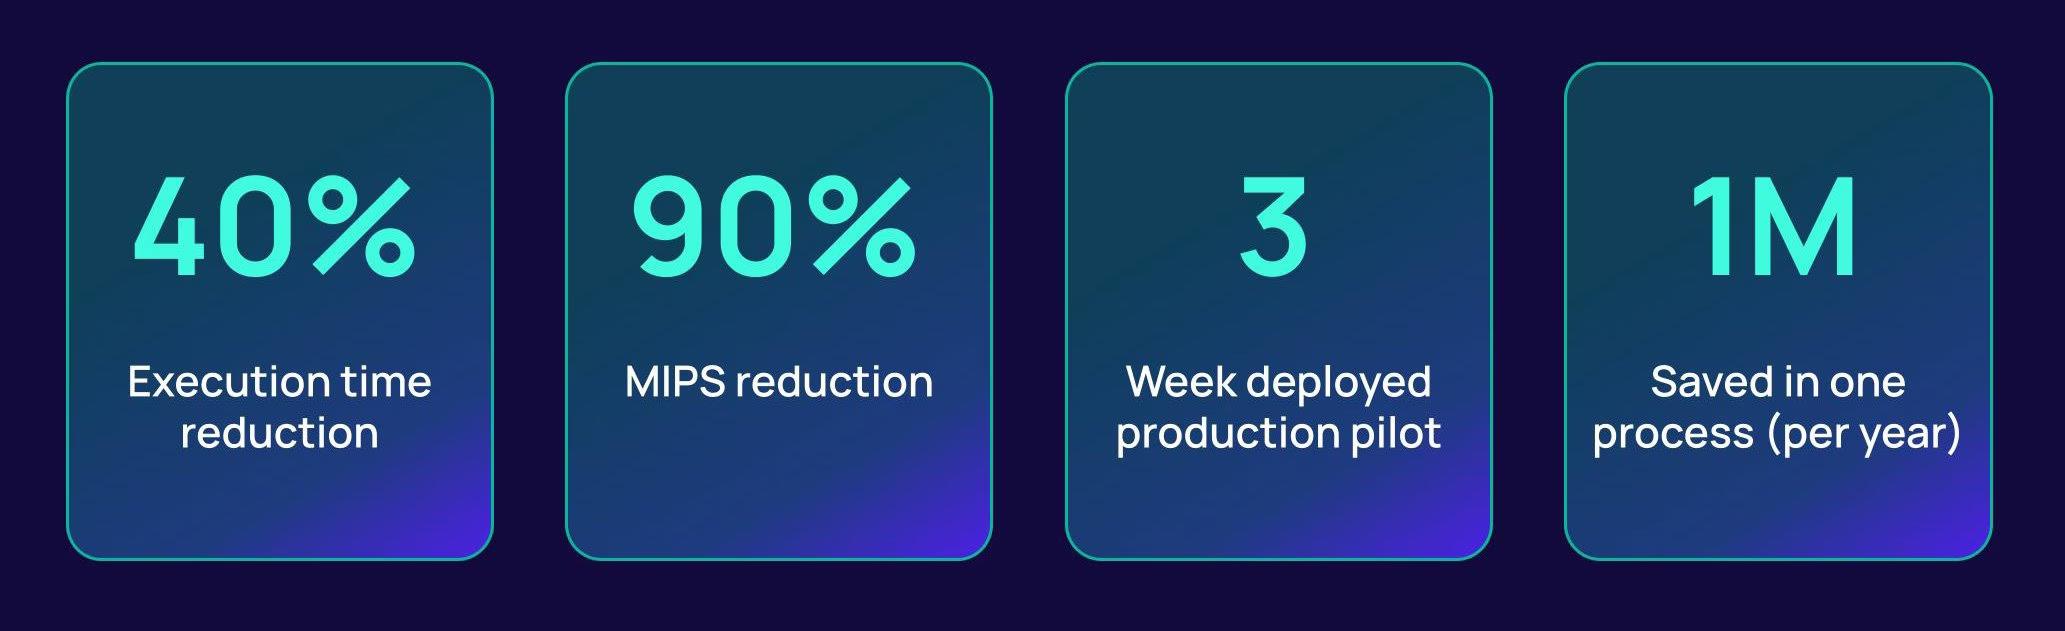
Even though this bank is keeping its identity private (for now), the story of how it achieved these results is worth sharing. Let’s dive into how they are able to accomplish these remarkable results and outcomes.
## The Hidden Burdens of Legacy Mainframe Infrastructure
At the heart of this bank’s operations is a core [IBM mainframe system](https://www.ibm.com/think/topics/mainframe) that runs [COBOL](https://en.wikipedia.org/wiki/COBOL) (Common Business-Oriented Language)-based batch jobs. Those jobs are responsible for processing several essential financial functions, including interest calculations, fraud detection, account status updates, and regulatory reporting. For years, this system has served reliably under moderate loads. But as customer volumes grow and digital expectations intensify, cracks are appearing in the foundation.
- **Poor performance and stability:** The nightly batch cycle, which once completed in a manageable window, now stretches to eight hours, composed of 30 tightly coupled steps. Typically, if any single step fails, the entire process has to be restarted from the beginning, leading to frequent delays, operational bottlenecks, and mounting pressure on IT teams. System instability is common, latency increases unpredictably, and recovery times are longer, all of which threaten service level agreements and business continuity.
- **Delayed reporting and compliance:** Beyond performance issues, these limitations also create serious strategic risks. [Fraud detection](https://www.ververica.com/use-case/fraud-detection), for example, can occur after transactions are finalized, leaving the bank exposed to losses during the gap between activity and analysis. Regulatory compliance also suffers, as delayed liquidity reporting makes it hard to meet tightening deadlines imposed by financial authorities.
- **Rising MIPS costs:** the reliance on [MIPS](https://en.wikipedia.org/wiki/MIPS_architecture) (Millions of Instructions Per Second) drives up licensing fees and compute expenses exponentially. Meanwhile, maintaining and enhancing the system requires specialized skills in legacy technologies like COBOL, [VSAM](https://en.wikipedia.org/wiki/Virtual_Storage_Access_Method) (Virtual Storage Access Method), and IMS (Information Management System). Finding talent that can support these technologies is hard among professionals (most opting for more modern technologies as a course of study), and as a result, talent is increasingly expensive to source and retain. Compounding these operational concerns is that in the past, modernization efforts were often avoided due to fears of disruption, complexity, or failure.
> **TIP:** “Mainframe offloading isn’t about tearing down the past. It’s about building a bridge to the future, incrementally, one stream at a time.”
## Customers Demand Real-Time, Always-on Banking
At the same time that this bank navigates its specific challenges, the [entire financial sector](https://www.internationaljournalssrg.org/IJCSE/2025/Volume12-Issue1/IJCSE-V12I1P103.pdf) is experiencing major disruptions. For example, several major banks, including [Bank of America,](https://www.bankofamerica.com/) [Commonwealth Bank of Australia](https://www.commbank.com.au/), [ANZ](https://www.anz.com.au/personal/), [Royal Bank of Scotland](https://www.rbs.co.uk/), and [NatWest,](https://www.natwest.com/) recently suffered repeated tech outages, locking customers out of online banking and disrupting critical services. These aren’t just glitches; they signal a deepening crisis of confidence in traditional banking infrastructure, fueling the rise of agile fintechs rapidly gaining market share. The fallout is severe, including:
- Eroding customer trust and deposit losses
- Business-critical payment delays
- Systemic risks across interconnected financial networks
- Growing pressure for government intervention
The bank knows taking action is critical. To future-proof its operations, it needs resilient, high-performance systems that ensure uninterrupted uptime, real-time responsiveness, and consistent performance, all at speed. A new mainframe is not an option, as they are too expensive, inflexible, and reliant on a shrinking talent pool. The team realizes that cloud-native technologies offer the scalability, cost-efficiency, and platform modernization that are needed in the current landscape.
But staying competitive means more than simple modernization. It requires always-on availability, customer-centric services, and real-time processing that is seamlessly integrated with existing legacy systems. Ultimately, they need a smarter solution that consists of enterprise-grade stream processing to deliver the speed, consistency, fault tolerance, security, and high availability required, all preferably in one unified solution.
## The Smarter Path Forward: Strategic Mainframe Offloading
Rather than implement a risky "rip-and-replace" strategy (which is known to incur high costs, long timelines, and operational upheaval), the bank chooses a more elegant solution: strategic data offloading. Leveraging the mainframe as a secure, reliable source of truth, they begin to shift computationally intensive workloads to a modern, cloud-native streaming platform.
This is where Ververica steps in. In partnership, the bank deploys [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product), powered by [Apache Flink](https://www.ververica.com/what-is-apache-flink)®. With this, they extract high-value data from the mainframe in real time and process it on the new, modern, scalable solution. This hybrid model allows the organization to preserve the integrity and resilience of its legacy infrastructure while unlocking new capabilities through real-time data processing. See Figure 2 for architecture details of the descriptions below.
This transformation centers around several key technical and architectural advancements:
- Efficient Data Export: Using [JDBC](https://www.marcobehler.com/guides/jdbc) connectors, the team extracts transactional data stored in VSAM files directly from the IBM mainframe. These exports are carefully orchestrated to minimize the impact on production workloads while ensuring completeness and consistency.
- Modern Codebase Migration: Critical business logic embedded in aging COBOL programs, such as rules for interest accrual or eligibility checks, is systematically refactored into Java, preserving functionality while making the codebase maintainable, testable, and extensible in a modern development environment.
- Seamless Cloud Integration: Processed streams are routed into [Azure Blob Storage](https://azure.microsoft.com/en-us/products/storage/blobs) for durable storage and further downstream use. The architecture is built to integrate smoothly with [Apache Kafka®](https://kafka.apache.org/) for event-driven workflows, and the team has future plans to adopt [Apache Paimon™](https://paimon.apache.org/) for efficient lakehouse-style analytics.
- Real-Time Stream Processing at Scale: Apache Flink, managed via Ververica’s enterprise-grade solution, enables the processing of millions of events per second with sub-second latency. This allows the bank to analyze transactions in real-time, enabling immediate responses to anomalies and opportunities alike.
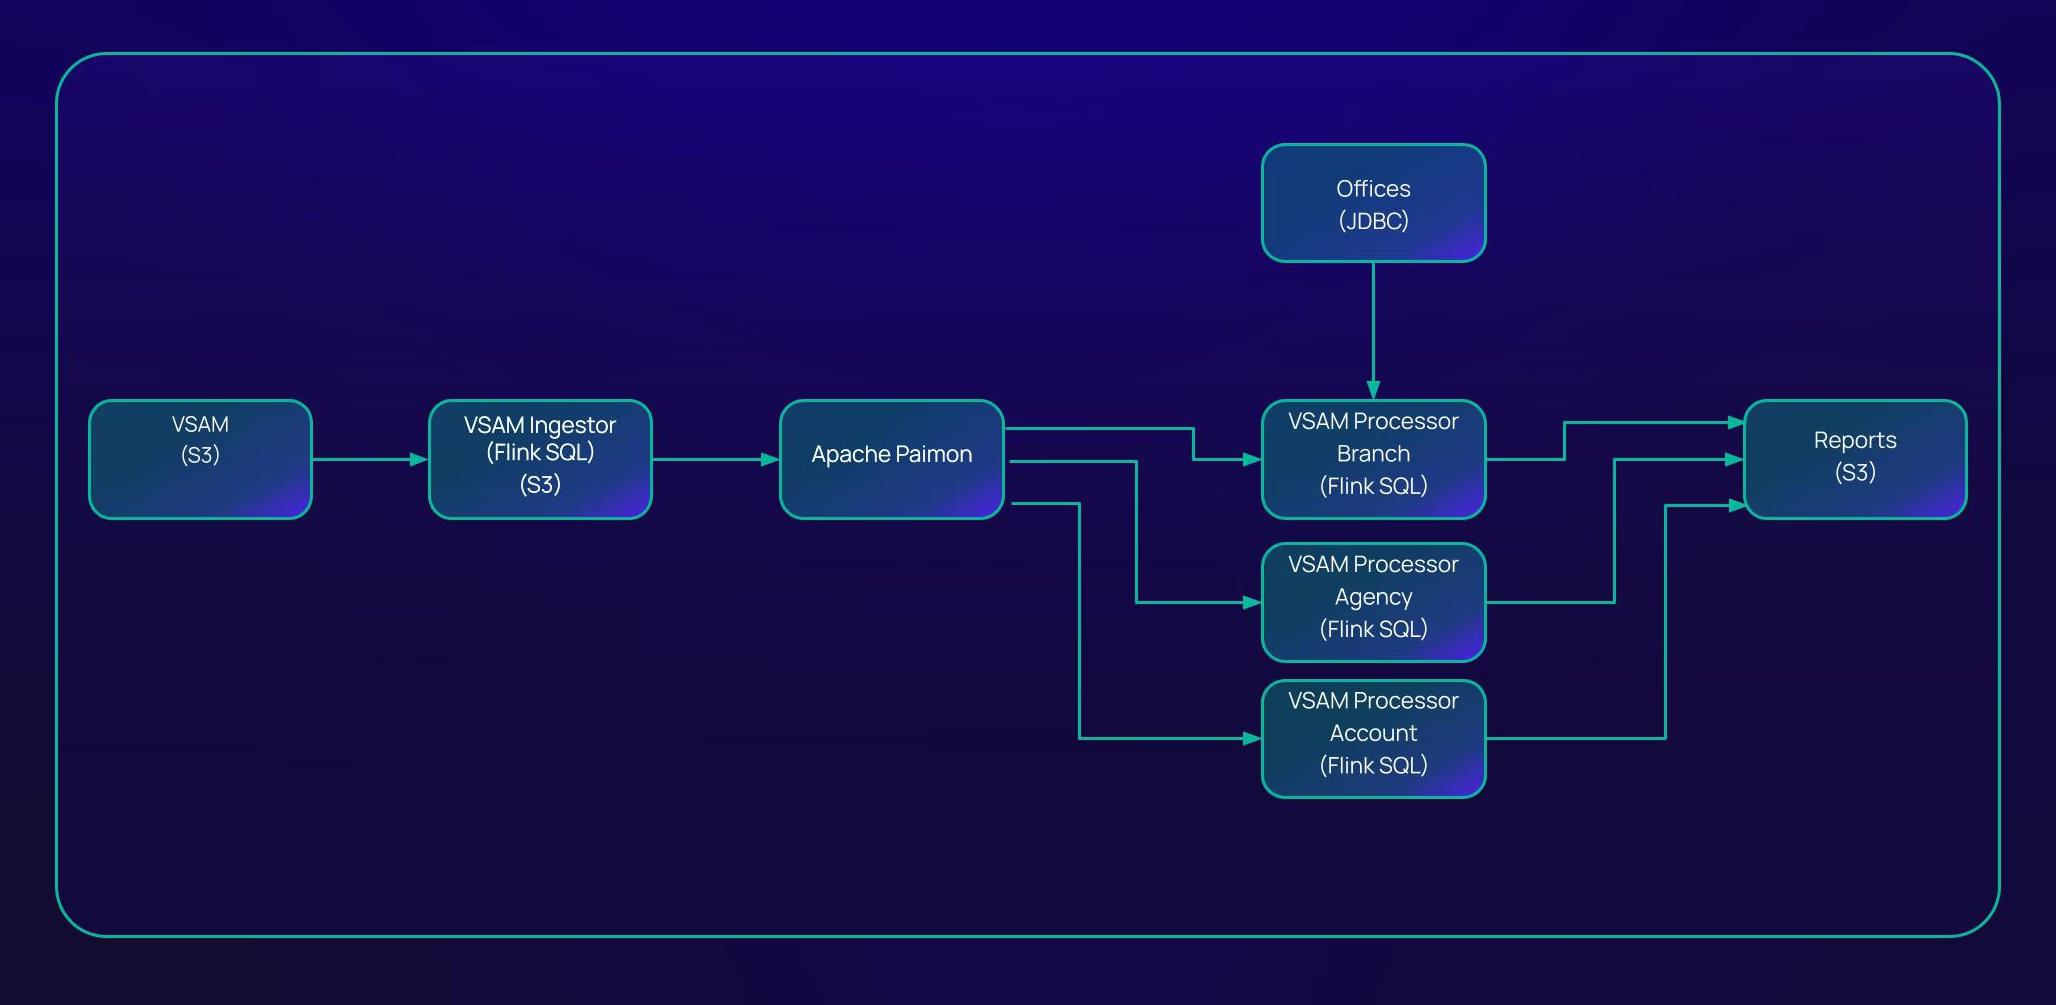
This phased, non-disruptive approach also ensures zero downtime during migration. Crucially, it allows the bank to leverage existing cloud investments and avoid vendor lock-in, all while accelerating time-to-value. The entire deployment from design to full operation takes under three weeks, demonstrating that with Ververica’s Unified Streaming Data Platform, large-scale modernization doesn’t mean months of planning and execution.
## Tangible Results from Mainframe Offloading: Speed, Savings, and Strategic Advantage
The impact of the transformation is both immediate and measurable:
By offloading resource-intensive computations to Ververica, the bank drastically reduces its dependence on costly mainframe cycles. Every percentage point reduction in MIPS usage translates directly into lower software licensing fees and hardware costs, delivering more than a million in cumulative savings annually. But the benefits extend far beyond the balance sheet. With access to real-time data streams, the bank fundamentally improves its operations:
- [Fraud detection](https://www.ververica.com/blog/real-time-fraud-detection-using-complex-event-processing) is now proactive instead of reactive. Suspicious patterns are recognized during transactions rather than after the fact, which significantly reduces exposure and improves customer protection and satisfaction.
- Interest calculations and balance updates are instantaneous, enhancing customer experience and trust.
- Regulatory reporting is now proactive instead of delayed. This results in greater transparency with oversight bodies, and better insight into potential problems before they happen.
These capabilities fix broken processes and open doors to new possibilities. Armed with real-time data pipelines, the bank is currently exploring advanced applications powered by artificial intelligence, including agentic [AI models](https://www.ververica.com/use-case/ai-ml) for [adaptive fraud prevention](https://www.ververica.com/blog/outrun-fraudsters-with-agentic-ai-and-ververica) and [personalized](https://www.ververica.com/use-case/customer-360), context-aware customer interactions.
## Ververica: The Strategic Enabler for Mainframe Offloading
Selecting the right solution for mainframe system updates is critical. The bank recognizes the need for a solution that combines raw performance with enterprise-grade reliability, security, and ease of integration. Ververica stands out among other established alternatives for several reasons:
- Ververica’s Unified Streaming Data Platform is powered by [VERA](https://www.ververica.com/vera), the high-throughput stream processing engine that can handle massive data volumes with predictable low latency.
- Exactly-once semantics: in the event of failures, each event in the stream is processed exactly once, ensuring data consistency and accurate results, with no exception.
- The elastic, cloud-native architecture scales automatically with demand, reducing both cost and manual oversight.
- Built-in enterprise scheduling, monitoring, and observability tools provide operations teams with comprehensive visibility and control.
- Native support for integrating with legacy environments makes bridging old and new systems seamless.
- Available as a managed service, Ververica reduces operational overhead, allowing internal teams to focus on innovation instead of infrastructure maintenance.
Most importantly, Ververica has a proven track record, including a highly credible customer base in mission-critical finance environments, where accuracy, consistency, and uptime are non-negotiable.
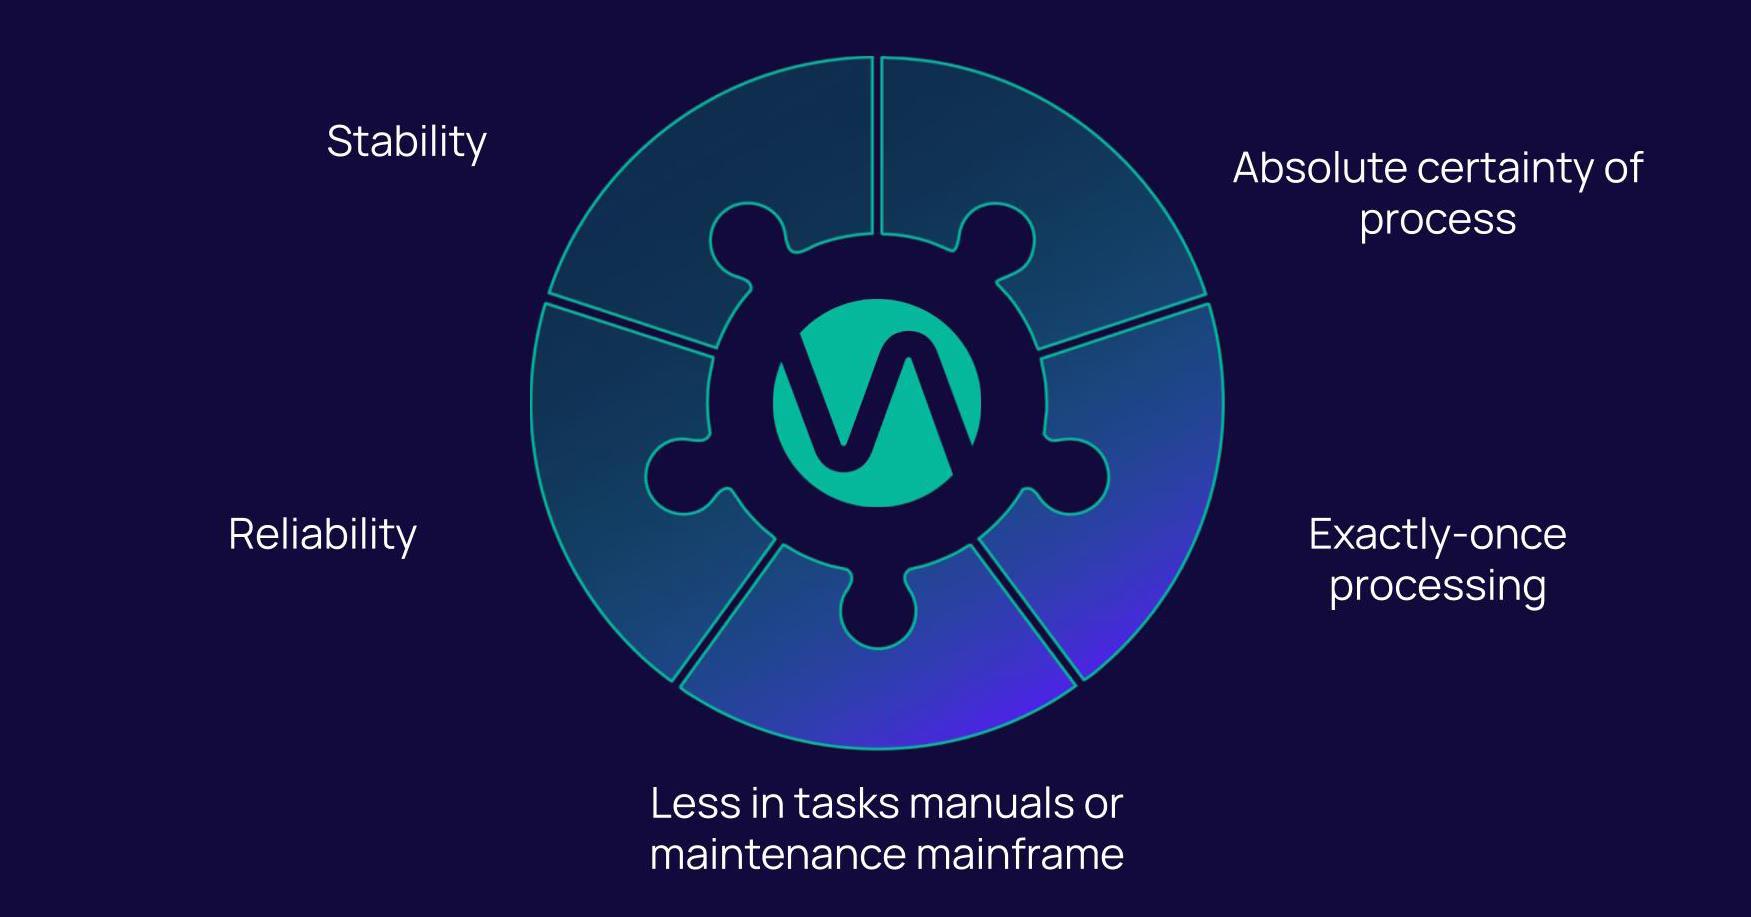
## The Road Ahead: Evolving into a Real-Time Financial Enterprise
The success of this initiative has sparked a broader cultural and technological shift across the organization. What started as a targeted optimization project is now evolving into a company-wide movement towards real-time operations.
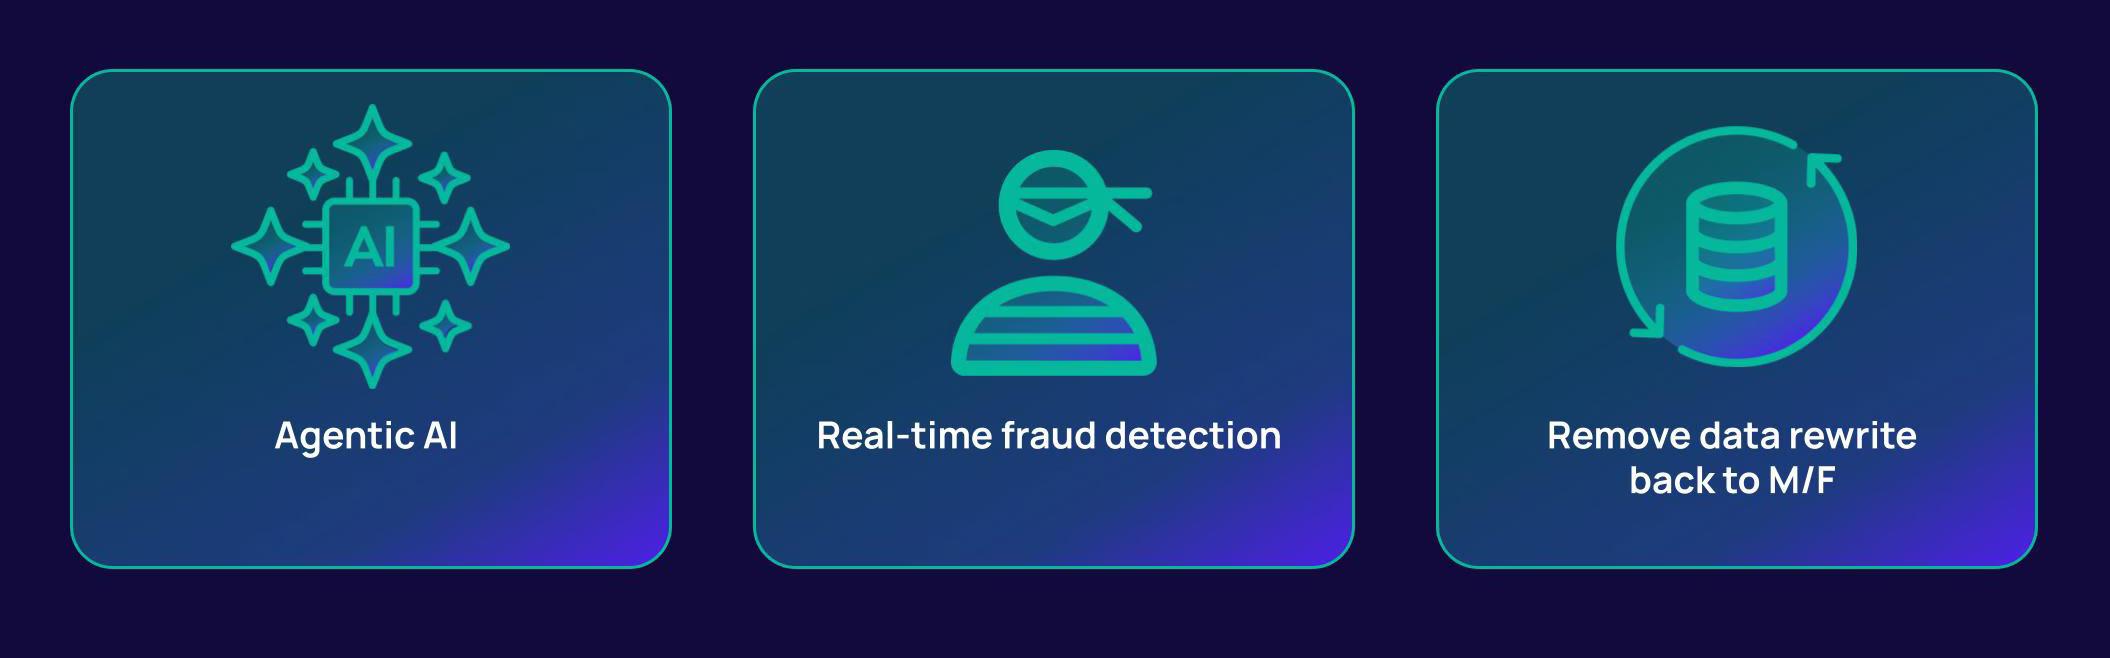
Future plans involve migrating the remaining batch processes to continuous, unbounded streaming architectures, which build on already demonstrated cost savings and operational benefits. By leveraging [Change Data Capture (CDC)](https://www.ververica.com/blog/a-deep-dive-on-change-data-capture-with-flink-sql-during-flink-forward), the bank can achieve real-time synchronization between the mainframe and external systems, similar to implementations seen with several of Ververica’s other existing customers. This enables instant updates to accounts, balances, and customer profiles across dashboards, risk engines, and compliance tools, eliminating data latency and empowering real-time decision-making.
Additionally, the foundation is now in place within the company to develop AI-driven decision engines capable of automating complex risk assessments and personalized customer recommendations. As these capabilities mature and the need to write processed data back to the mainframe diminishes, the mainframe’s workload will further reduce, accelerating the path toward a more agile, scalable, and future-ready architecture.
As one of the region’s most forward-thinking banks, this institution is now setting the standard for what modern banking can look like: responsive, intelligent, and driven by data flowing freely across all types of systems, regardless of source.
## Conclusion: Legacy Modernization is Imperative for Success
Mainframes aren’t becoming extinct, nor should they. Their reliability, security, and transactional integrity remain unmatched for many core banking functions. But when used as the sole engine for analytics, reporting, and real-time decision-making, they become bottlenecks in a world that demands speed and agility.
This bank’s journey proves there’s a smarter way, one which preserves the strengths of legacy systems while augmenting them with modern, real-time platforms. By strategically offloading data and computation, organizations can achieve dramatic cost reductions, accelerate processing, and unlock innovation, all without compromising stability.
For any enterprise weighed down by aging infrastructure, the message is clear: transformation isn’t about tearing down the past. It’s about building a bridge to the future, incrementally, one stream at a time.
## Related Resources:
- Learn more about the many data [use cases Ververica helps solve](https://www.ververica.com/use-case).
---
---
title: "Ververica’s Foolproof Path to AI: Why Streaming ETL Fuels Next-Gen Machine Learning"
description: "Ververica’s Unified Streaming Data Platform enables real-time machine learning and predictive analytics with streaming ETL for next-gen AI innovation"
lastUpdated: 2026-03-17T12:32:35.000Z
source_url:
html: "https://www.ververica.com/blog/why-streaming-etl-fuels-next-gen-machine-learning"
md: "https://www.ververica.com/blog/why-streaming-etl-fuels-next-gen-machine-learning.md"
---
> **INFO:** What is Streaming ETL?
ETL (Extract, Transform, Load) is the process of continuously moving and transforming data in real time from source systems into a destination system like a data lake, data warehouse, or database.
Discover how Ververica’s [Unified Streaming Data Platform](https://www.ververica.com/product) empowers your company to build a foolproof path to AI success. By using real-time data and streaming [ETL](https://www.ververica.com/use-case/extract-transform-load), you can transform machine learning from reactive to truly predictive, accelerate decision making and drive measurable business impact. Learn how to move from experimentation to production-grade AI applications quickly, stay ahead of competitors, and access next-generation capabilities with scalable, reliable streaming infrastructure.
## Ververica’s Path to AI Infrastructure Success
> **TIP:** The competitive advantage of tomorrow belongs to companies that can act on data while it's still warm.
In financial services, the difference between catching fraud in milliseconds versus minutes can mean millions in prevented losses. In retail, dynamic pricing that responds to demand spikes like [Black Friday](https://en.wikipedia.org/wiki/Black_Friday_(shopping)) or [Double 11](https://www.alibabacloud.com/en/customers/double-11?_p_lc=1) events can drive 300% increases in conversion. In telecommunications, identifying churn‑risk signals as they emerge (rather than after customers have already decided to leave) enables prevention strategies that would otherwise cost 5‑10× more in win‑back campaigns.
The common thread? **Algorithms are only as powerful as the data feeding them.** Even the most sophisticated machine‑learning models become reactive rather than predictive when forced to analyze yesterday’s patterns to solve today’s problems.
## The Cost Of Delayed Decisions
Traditional batch ETL creates an invisible tax on machine learning (ML) performance. While these systems diligently collect data throughout the day and process it overnight, competitive threats now move and evolve in seconds. This slower approach worked when business decisions were made on a weekly or monthly cycle, but in today’s always‑on economy, even minutes of delay can compound into significant risk.
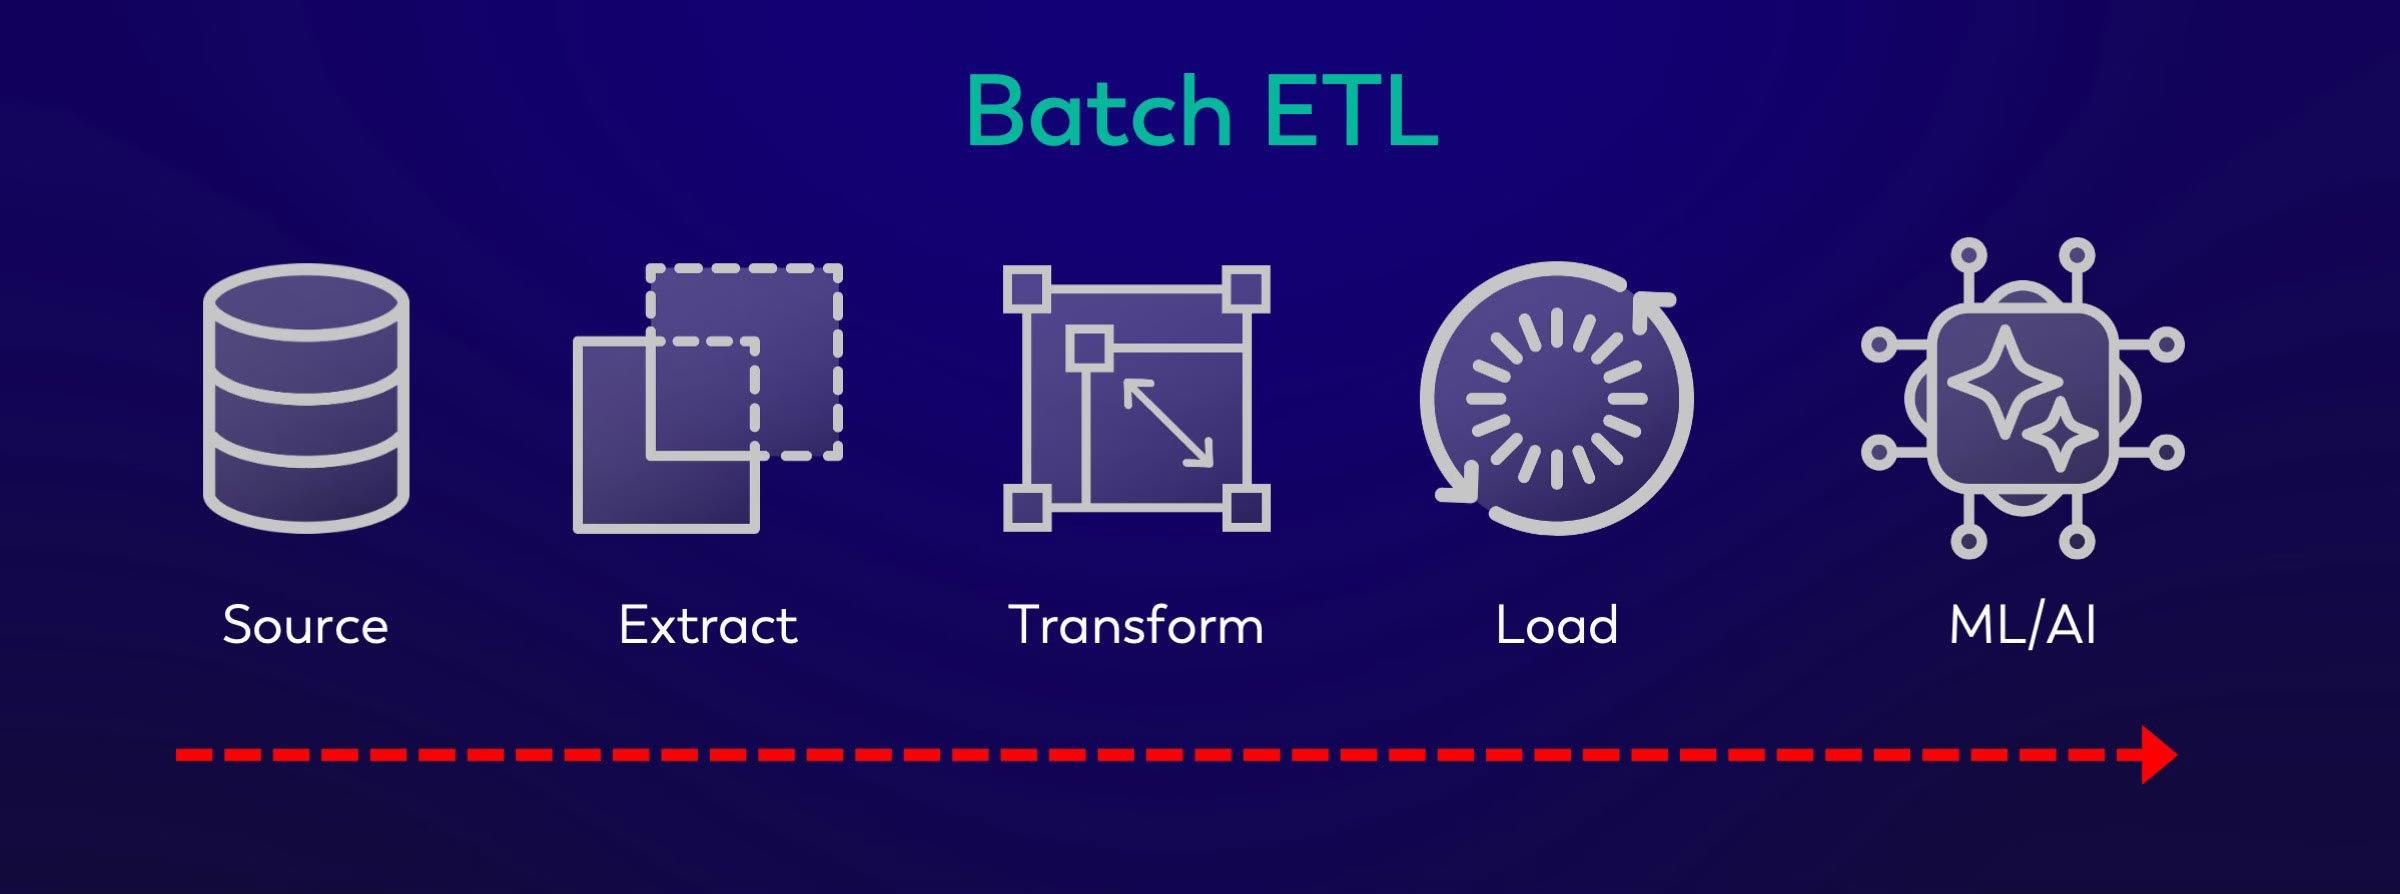
Consider the real‑world impact across critical business functions:
- **Security teams fight yesterday’s attacks.** Multi‑vector cyber‑attacks evolve within minutes, but batch‑processed security data creates detection gaps that allow sophisticated threats to establish persistence before defensive systems even recognize the initial breach indicators. [Modern SIEM architectures](https://www.ververica.com/use-case/security-information-and-event-management) require real‑time event correlation to identify new attack patterns as they unfold.
- **Financial institutions react to fraud patterns after losses accumulate.** By the time batch systems identify coordinated account take‑overs or synthetic‑identity schemes, criminal networks have already extracted maximum value and moved to new targets. [Real‑time fraud detection](https://www.ververica.com/use-case/fraud-detection) enables millisecond response to suspicious patterns before losses occur.
- **Customer‑experience teams optimize for behaviors that have already shifted.** When personalization engines work from hours‑old interaction data, recommendation algorithms essentially make educated guesses based on outdated preferences, missing the real‑time signals that indicate immediate purchase intent or emerging dissatisfaction. [Unified customer‑360 platforms](https://www.ververica.com/use-case/customer-360) require real‑time data integration to deliver truly interactive and engaging personalized experiences.
> **TIP:** This data latency creates an artificial ceiling on machine learning capabilities. No matter how advanced the algorithms are, they cannot predict or prevent what they cannot see in real time.
## The Breakthrough: Streaming ETL As Competitive Infrastructure
The shift from batch to streaming ETL represents more than a technical upgrade — it's the foundation for machine‑learning systems that operate at the speed of business opportunity. Rather than collecting data for later analysis, streaming ETL enables continuous ingestion, transformation, and delivery of fresh data to downstream models as events occur. This means operational models can update both their context and their memory in real time.
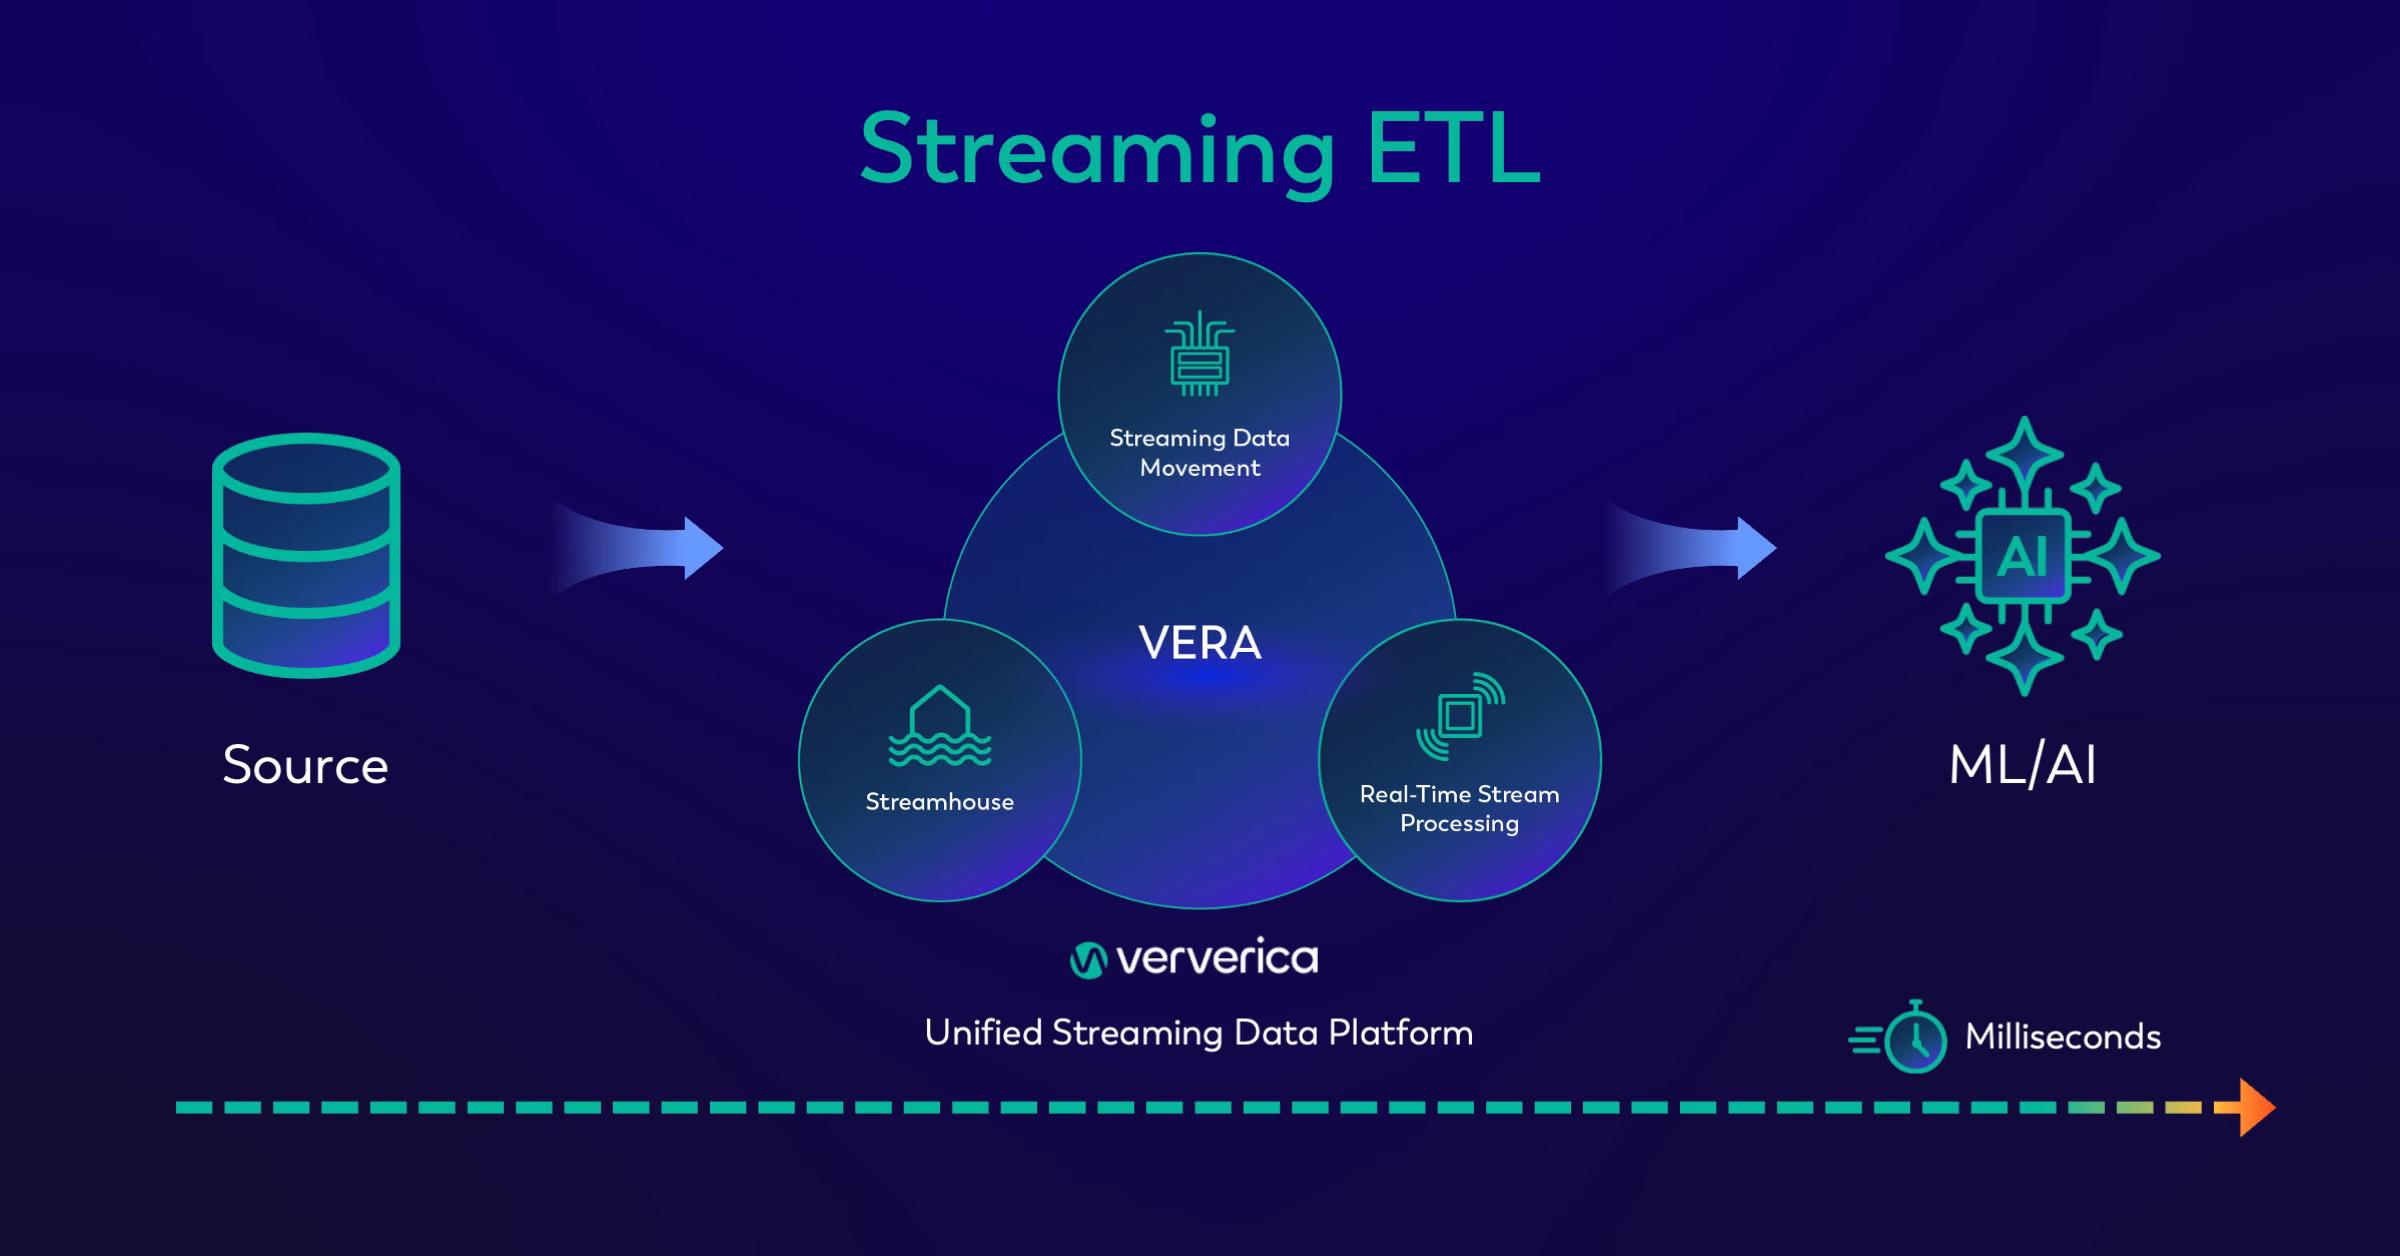
This architectural change unlocks several breakthrough capabilities:
- **Truly predictive models add value in real time.** Machine learning systems analyze emerging patterns rather than historical snapshots, identifying trends and anomalies while there’s still time to respond effectively.
- **Feedback loops accelerate learning.** Instead of waiting for batch cycles, machine learning models can receive immediate outcomes from their predictions, enabling continuous refinement that improves accuracy with each interaction. Even vector stores can be updated in near real time, allowing models to retain those learnings across future iterative inferences or deployments.
- **Faster insight means faster actions.** The gap between detecting a problem and resolving it shrinks from hours to milliseconds. That’s often the difference between preventing an issue and reacting after the damage is done.
[Apache Flink®](https://www.ververica.com/what-is-apache-flink), the gold standard stream processing project that Ververica’s Unified Streaming Data Platform is built on, processes millions of events per second while maintaining the reliability and consistency that enterprise machine‑learning applications demand. This technical foundation enables organizations to evolve from reactive analytics to proactive, prevention‑oriented intelligence.
## Prevention Economics: Real‑Time Machine Learning In Action
The business case for streaming ETL is compelling when you examine the prevention economics across high‑impact use cases:
- **Fraud Detection:** Real‑time transaction analysis prevents losses before they occur. For example, [One Mount Group](https://www.ververica.com/case-study/one-mount-group) processes millions of financial transactions daily with millisecond‑level anomaly detection, stopping sophisticated fraud schemes that would slip through batch analysis.
- **Customer Retention:** Early‑warning systems flag churn risk early enough for retention strategies to stay cost‑effective. Streaming analytics detect shifts in engagement patterns that signal emerging dissatisfaction, making it possible to intervene proactively right when it matters most.
- **Dynamic Pricing:** Revenue optimization responds to demand fluctuations in real time, not after opportunities are missed. During major shopping events, companies like AliExpress have realized up to 300% increases in conversion efficiency by using [real‑time price optimization](https://www.ververica.com/use-case/dynamic-pricing) to stay ahead of demand spikes.
- **Predictive Maintenance:** Equipment failures are detectable and preventable events rather than costly surprises. [Sensor‑driven models](https://www.ververica.com/blog/preventing-blackouts-real-time-data-processing-for-millisecond-level-fault-handling) spot early signs of degradation before they escalate into catastrophic failures, enabling proactive targeted interventions that reduce downtime and extend asset lifecycles.
These applications share a common characteristic: the value of real‑time insights compounds exponentially when action is taken immediately.
## Infrastructure For Intelligence: Building Streaming‑First Machine Learning
Organizations ready to unlock next‑generation capabilities should approach the transition strategically:
- **Start with high‑impact prevention** [**use cases**](https://www.ververica.com/use-case)**.** Identify where real‑time decision making directly prevents losses or captures time‑sensitive opportunities. Focus on applications where preventing problems before they occur, acting proactively rather than reacting afterwards, reduces costs and delivers clear, measurable ROI for streaming infrastructure.
- **Architect for both real‑time and historical context.** Effective models require immediate data to act quickly and historical data to spot patterns. Ververica’s Unified Streaming Data Platform removes the gap between real‑time and batch processing, letting models benefit from both speed and depth.
- **Design for continuous operation.** Unlike batch systems that can recover from downtime during off‑hours, streaming ETL has to run reliably 24/7. Invest in monitoring, fault tolerance, and performance visibility as core requirements, not afterthoughts.
- **Plan for elastic scaling.** Real‑time workloads can spike without warning during crises or big market events. Your infrastructure must scale automatically to handle sudden increases in data volume without compromising latency, resilience or accuracy.
## Enabling AI Evolution: Get Ready with Ververica
Machine learning is the workhorse that delivers today’s predictive insights, but its constant exposure to real‑time data is what sets the stage for true AI evolution. Streaming ETL is the mechanism that keeps models, and the AI systems they power, forever learning. Here’s how Ververica makes that evolution practical:
- **Continuous context refresh:** Ververica feeds fresh, contextual information into feature stores and vector databases, ensuring foundation models stay aligned with the latest reality.
- **Online model management:** Native support for stateful application upgrades means you can deploy improved models without downtime, so learning flows without interruption.
- **Adaptive pipelines:** Declarative configuration makes it easy to incorporate new data sources or features as your AI maturity grows, shortening the path from idea to production.
- **Built‑in observability:** Fine‑grained metrics and state snapshots let teams trace decisions back to the exact data that informed them, forming the feedback loop required for safe, explainable AI.
- **Scalable semantics:** Ververica utilizes Flink SQL, allowing data and ML engineers to use the same language and infrastructure from prototype to petabyte scale, reducing the friction that slows organizational learning.
> **TIP:** Streaming ETL does more than simply keep machine‑learning models accurate; it provides the living bloodstream that lets AI itself evolve responsibly, iteratively, and transparently.
## The Strategic Imperative
The convergence of machine‑learning adoption and real‑time data processing isn’t just changing how businesses operate - it’s redefining what competitive advantage looks like. Organizations that continue operating on batch‑processed insights will find themselves consistently reacting to market conditions that streaming‑enabled competitors are already shaping.
This shift marks a fundamental change in business velocity. Companies using streaming ETL don’t just respond faster; they operate on a completely different time horizon. While competitors rely on historical approximations, they make decisions based on live, real-world conditions.
Ververica’s Unified Streaming Data Platform enables this transformation by providing enterprise‑grade streaming infrastructure that feeds machine‑learning systems the fresh, contextual data they need to deliver preventive intelligence and support ongoing AI evolution. The question isn’t whether your organization will adopt streaming ETL, it’s whether you’ll lead the transition or follow competitors who already have.
## Move your AI Strategy into Real-Time.
Ververica eases operational complexity and, depending on the deployment option, is ready within minutes, so you can make faster, smarter decisions quickly.
## More Resources
- Explore additional [ETL Use Cases.](https://www.ververica.com/use-case/extract-transform-load)
- Learn more about [AI and ML Use Cases.](https://www.ververica.com/use-case/ai-ml)
---
---
title: "Ververica Announces Partnership with Aiven: Empowering Leading Enterprises to Create Value from Data in Real-Time"
description: "Ververica and Aiven partner to unlock real-time streaming data together."
lastUpdated: 2026-03-17T12:33:23.000Z
source_url:
html: "https://www.ververica.com/blog/ververica-announces-partnership-with-aiven-empowering-leading-enterprises-to-create-value-from-data-in-real-time"
md: "https://www.ververica.com/blog/ververica-announces-partnership-with-aiven-empowering-leading-enterprises-to-create-value-from-data-in-real-time.md"
---
We’re excited to announce a new partnership between [Ververica](https://www.ververica.com/vera) and [Aiven](https://aiven.io/)! This collaboration brings Ververica’s enterprise-grade [Unified Streaming Data Platform](https://www.ververica.com/) directly to Aiven customers, making it easier than ever to unlock the full potential of real-time data processing from the original creators of Apache Flink®.
## Turning Streaming Potential Into Real Business Value
Stream processing solutions should be swift, scalable, and secure. By partnering with Aiven, Ververica is helping businesses harness the speed and intelligence of real-time data, regardless of the source, volume, or velocity.
Aiven users can now more easily solve real-time, AI-ready use cases with Ververica’s Unified Streaming Data Platform, backed by expert support that makes building a streaming data pipeline more efficient and developer-friendly. Whether you’re already using another stream processing solution or just starting your streaming journey, this partnership removes complexity and accelerates your ability to build resilient, scalable, and robust real-time applications.
> "This partnership is about removing friction and delivering real business value. Aiven users running Kafka can now seamlessly step into real-time stream processing with Apache Flink through our enterprise-grade platform. And for Ververica users, Aiven simplifies operations with a proven managed service. Together, we’re lowering the barrier to scalable, high-performance streaming." - Vladimir Jandreski, Ververica Chief Product Officer
## Building for Real-Time, Together
Aiven customers benefit not only from simplified access to powerful stream processing but also from the deep expertise behind Ververica’s technology. Together, businesses can act on data instantly for countless use cases, including [customer 360](https://www.ververica.com/use-case/customer-360?hsLang=en), [fraud and anomaly detection](https://www.ververica.com/use-case/fraud-detection?hsLang=en), [dynamic pricing](https://www.ververica.com/use-case/dynamic-pricing?hsLang=en), mainframe offloading, and [many more](https://www.ververica.com/use-case?hsLang=en).
> "Partnering with Ververica gives our customers direct access to enterprise-grade stream processing, powered by the creators of Apache Flink. Together, we’re making it easier to build scalable, real-time applications with expert support and unlock more value from streaming data, faster." - Conor Forde, SVP Go To Market at Aiven.
## Why Ververica + Aiven = Value
- **End-to-End Streaming Simplicity**Seamlessly connect Aiven’s managed Kafka and other data services with Ververica’s enterprise-ready platform, no glue code or heavy lifting required.
- **Faster Time to Value**Process, analyze, and act on data in real time. Turn raw data into meaningful business outcomes within milliseconds.
- **Enterprise-Grade Reliability**Leverage the only solution built and supported by the original creators of Flink, with enterprise SLAs, governance, and 24/7 observability built in.
- **Built-In Observability & Governance**Monitor and manage your data pipelines with confidence. Versioning, data lineage, and optional governance tools give teams full visibility and control.
- **Developer Velocity**Empower developers to build real-time applications faster using SQL or APIs, with zero infrastructure friction and full support from both Ververica and Aiven.
- **Cloud-Native and Open Source Aligned**This partnership supports multi-cloud, hybrid, and open-source-first strategies to future-proof your architecture while ensuring no vendor lock-in.
- **Future-Ready Data Infrastructure**Whether you’re moving from batch to real-time, modernizing your architecture, or scaling globally, this partnership gives you the tools and expertise to succeed.
This is just the beginning of Ververica’s collaboration with Aiven. We’re jointly committed to empowering data teams to innovate faster, operate smarter, and deliver new value from their data in motion.
## More Resources
- Learn more about the countless [use cases](https://www.ververica.com/use-case) solved by Ververica.
- Learn how [Aiven for Apache Kafka](https://aiven.io/kafka) helps you build your event-driven architecture and streaming data pipelines.
- [Read the official press release](https://www.businesswire.com/news/home/20250617806011/en/Ververica-Announces-Partnership-with-Aiven---Empowering-Leading-Enterprises-to-Create-Value-from-their-Data-in-Real-Time) announcing the Aiven and Ververica partnership.
- Ready to explore real-time data streaming projects? [Contact us.](https://ververica.com/contact)
---
---
title: "Preventing Blackouts: Real-Time Data Processing for Millisecond-Level Fault Handling"
description: "Leverage real-time data processing for instant power outage detection. Improve grid reliability and enable predictive maintenance."
lastUpdated: 2026-03-17T12:34:03.000Z
source_url:
html: "https://www.ververica.com/blog/preventing-blackouts-real-time-data-processing-for-mission-critical-infrastructure"
md: "https://www.ververica.com/blog/preventing-blackouts-real-time-data-processing-for-mission-critical-infrastructure.md"
---
> **INFO:** What is real-time data processing, and why is it important for energy grid blackout prevention?
Real-time data processing enables instant fault analysis and response to grid conditions, helping prevent blackouts with predictive maintenance and smart grid monitoring that instantly detects and remediates faults before they escalate.
At Ververica, we specialize in helping companies ingest, transform, analyze, and act on large volumes of data in real time. Customers like ING, Microsoft, Booking.com, and Alibaba rely on our [Unified Streaming Data Platform](https://www.ververica.com) to power critical applications, including [fraud detection](https://www.ververica.com/use-case/fraud-detection) and [cybersecurity](https://www.ververica.com/use-case/security-information-and-event-management).
Reflecting on Ververica’s experience helping companies understand threats, act quickly and prevent losses combined with my personal experience in energy engineering, this blog explores how millisecond-level fault detection and real-time data processing can help build a more resilient grid that integrates even higher levels of zero-carbon renewable energy while, quite literally, keeping the lights on.
## Power Grid Monitoring: Black Magic Or Delicate Balance?
The power systems we use today were mostly designed in an era where almost all energy was produced from thermal sources, which can generally be throttled at will. If the grid needs more power, you can increase the output of a gas turbine or a coal boiler by simply increasing the amount of fuel that flows into the system. In principle, it’s similar to stepping on the gas pedal of a gas-powered car that is run by an internal combustion engine.
Electric grids are inherently delicate: at every moment, the total energy produced and input into the grid must precisely match the energy that is consumed by all the users drawing power from it. One additional person turning on a kettle means that somewhere, somehow, the production of one of the power plants connected to the grid at that point must also increase by approximately 1 kilowatt.
One can’t help but wonder:
- How can my grid operator know that I really need some tea now?
- How can they notice and respond to my personal choices?
The answer is by carefully monitoring grid frequency: when more power is drawn from the grid than fed into it, the grid frequency dips - and this is a clear-cut signal to increase power generation. A delicate balance between power supply and demand maintains the grid frequency at (or very close to) its design frequency: 50Hz in most countries (mainly Europe, Africa, Asia) and 60Hz in others (mostly in the Americas). This is absolutely crucial because electrical and electronic equipment will malfunction if it is fed electric power at a different frequency than what it is designed to handle.
For example, in 2018, a frequency slip in the Central European grid [made all grid-connected clocks lag](https://www.theguardian.com/world/2018/mar/08/european-clocks-lose-six-minutes-dispute-power-electricity-grid) in some parts of Europe, since they rely on the grid frequency to count the passing of time. This meant that for the duration of the event, critical systems like trains, radars, and others were unreliable or rendered completely unusable. Because the power electronics that control large electric motors and actuators can be damaged by higher or lower frequencies than what they are designed for, they will shut down preventively in those conditions to avoid further damage. Electronics like computers and microcontrollers are also very sensitive to frequency deviations, and the impact of these types of protective measures means loss of service and interruptions.
## Renewables Enter The Game
The scientific consensus is firm about climate change and how human actions, in particular greenhouse gas emissions, are accelerating it. **Simply put, it is humanity’s duty to stop and reverse this, if we are to survive as a species.** Renewable energy is probably the brightest development in this area, allowing us to [grow our energy usage by over 400% since the 1950s](https://ourworldindata.org/grapher/primary-energy-cons), while at the same time halving the average emissions from [900 gCO2e/kWh to below 450 gCO2e/kWh](https://ember-energy.org/latest-insights/global-electricity-review-2023/). However, renewable energy introduces a whole new set of challenges to the energy grid. By its very nature, renewable energy is not ‘dispatchable’, i.e., it cannot be turned on and off at will (with the notable exception of hydropower). This means that the rest of the grid must constantly adjust to its availability, one second at a time.
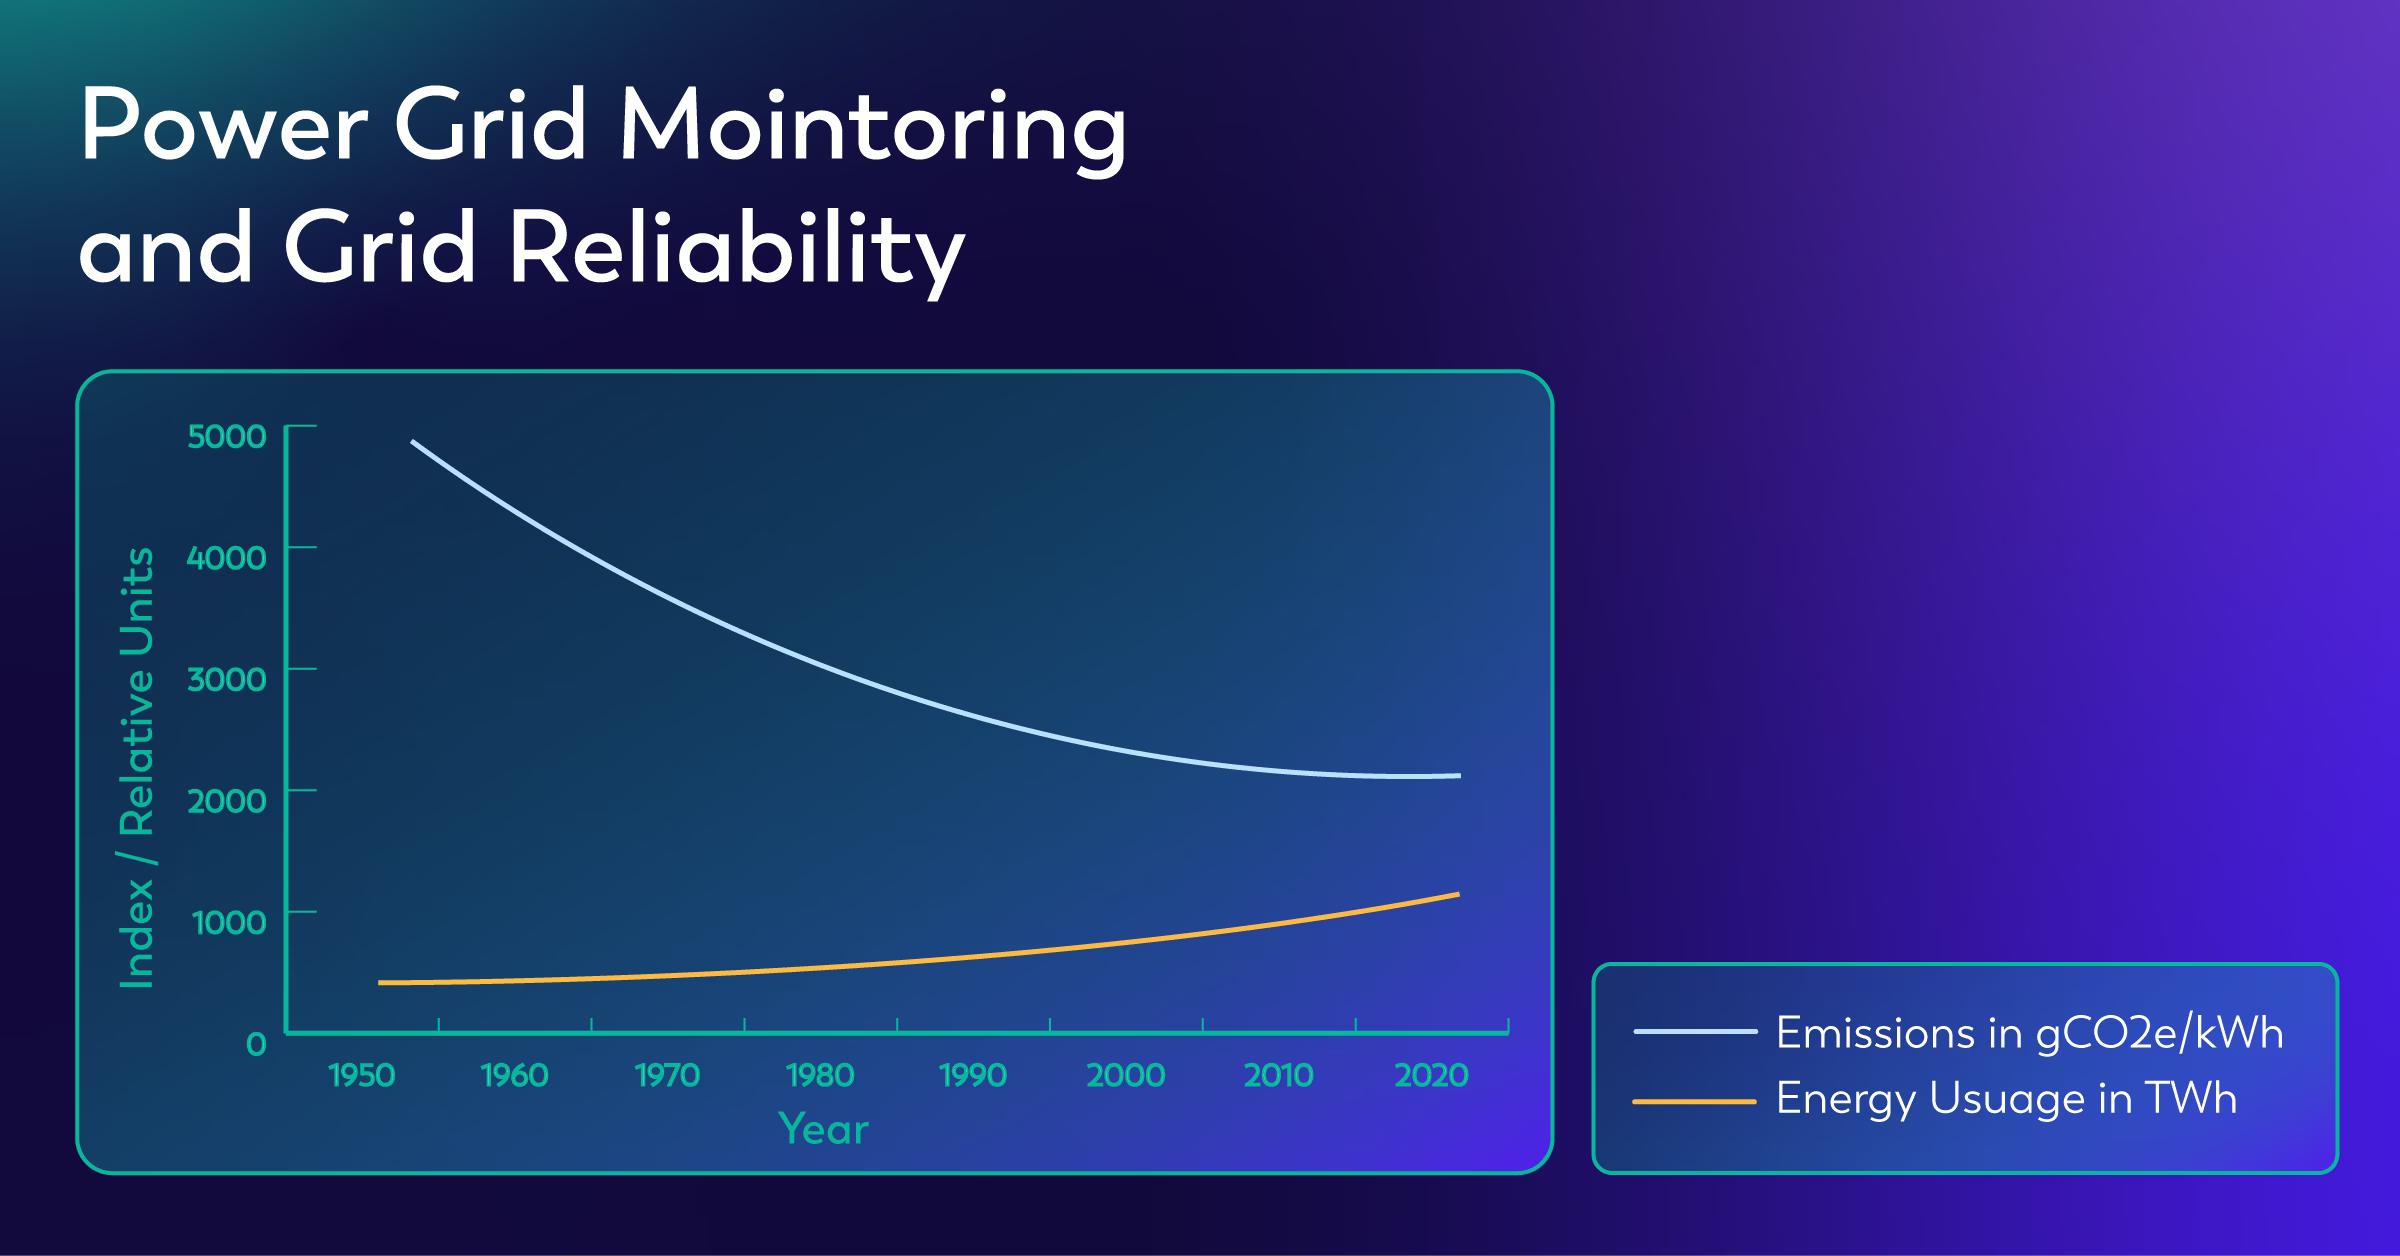
Forecast models have gotten very good at predicting the long-term output of a renewable resource (for example, public models exist that forecast how much solar energy your roof will produce if fitted with PV panels, month by month), but it is notoriously difficult to forecast output in the very short term. In addition, any weather variation can have an immediate impact; cloud cover, for example, can reduce the output of a solar plant [from 100% to 37% in 1 minute](https://ember-energy.org/latest-insights/global-electricity-review-2023/).
To make up for this unpredictability, power grids have multiple reserve mechanisms that step in and fill in the gaps left by renewable power sources like solar and wind that decrease output momentarily, like a solitary cloud passing overhead, or more permanently at sunset, or if a power line fails. Many thermal plants do not run at full throttle - or in some cases, don’t run at all - just to be ready to ramp up and pick up the load in case that is needed. These supply the reserve margin of the power system, and most countries generally provide sufficient incentives for firms to profitably build and operate the plants that provide this reserve capacity. However, when either primary production or reserves are insufficient, the end result is a blackout.
## The Iberian Peninsula Blackout Of April 2025
On Monday, April 28, 2025, at 12:33 CEST, the Iberian grid, which covers Spain and Portugal, experienced a sudden fifteen gigawatt drop—about 60% of Spain’s load—in just five seconds, triggering a peninsula-wide blackout lasting ten hours. This is nothing short of catastrophic: European nations are accustomed to continuous, on-demand electricity access, and it is a foundational commodity the community relies on. From traffic lights to data centers, [electric vehicles](https://www.ververica.com/blog/driving-efficiency-using-real-time-data-to-optimize-the-ev-industry) to televisions, everything that is considered a part of basic existence stopped working suddenly with no explanation or indication of when it would be available again.
Currently, the proximate cause of the blackout is still being investigated, and a report will be published by the authorities in due time. Thus far, the [Spanish Transmission System Operator](https://www.ree.es/en) (REE) has acknowledged the following: the sudden drop of fifteen gigawatts of generation capacity in the southeast of Spain caused the frequency to drop below acceptable limits ([press release, in Spanish](https://www.ree.es/es/sala-de-prensa/actualidad/nota-de-prensa/2025/04/proceso-de-recuperacion-de-la-tension-en-el-sistema-electrico-peninsular)). This, in turn, forced other generating units connected to the grid via inverters to also disconnect from the grid to protect themselves, starting an adverse domino effect that made Spain and Portugal go dark within a few seconds.
## Why Millisecond Detection Matters for Power Grid Monitoring
The protective relays and circuit breakers that are fitted to European grids operate in the 10–100 millisecond (ms) range. This is _**mind-blowingly fast**_: as my friend and Ververica’s Field CTO [Ben Gamble](https://www.linkedin.com/in/bengamble7/) likes to point out, a human blink lasts about 250 milliseconds.
To put this speed in perspective, Figure four demonstrates another common [use case](https://www.ververica.com/use-case) of real-time data processing: a financial transaction with a payment card. In the time it takes to blink an eye, to keep business and customer satisfaction high, an entire process quickly occurs:
- The initial request is received and processed.
- [Fraud detection](https://www.ververica.com/use-case/fraud-detection) ensures the legitimacy of the transaction,
- And the appropriate response is received back at the request source.
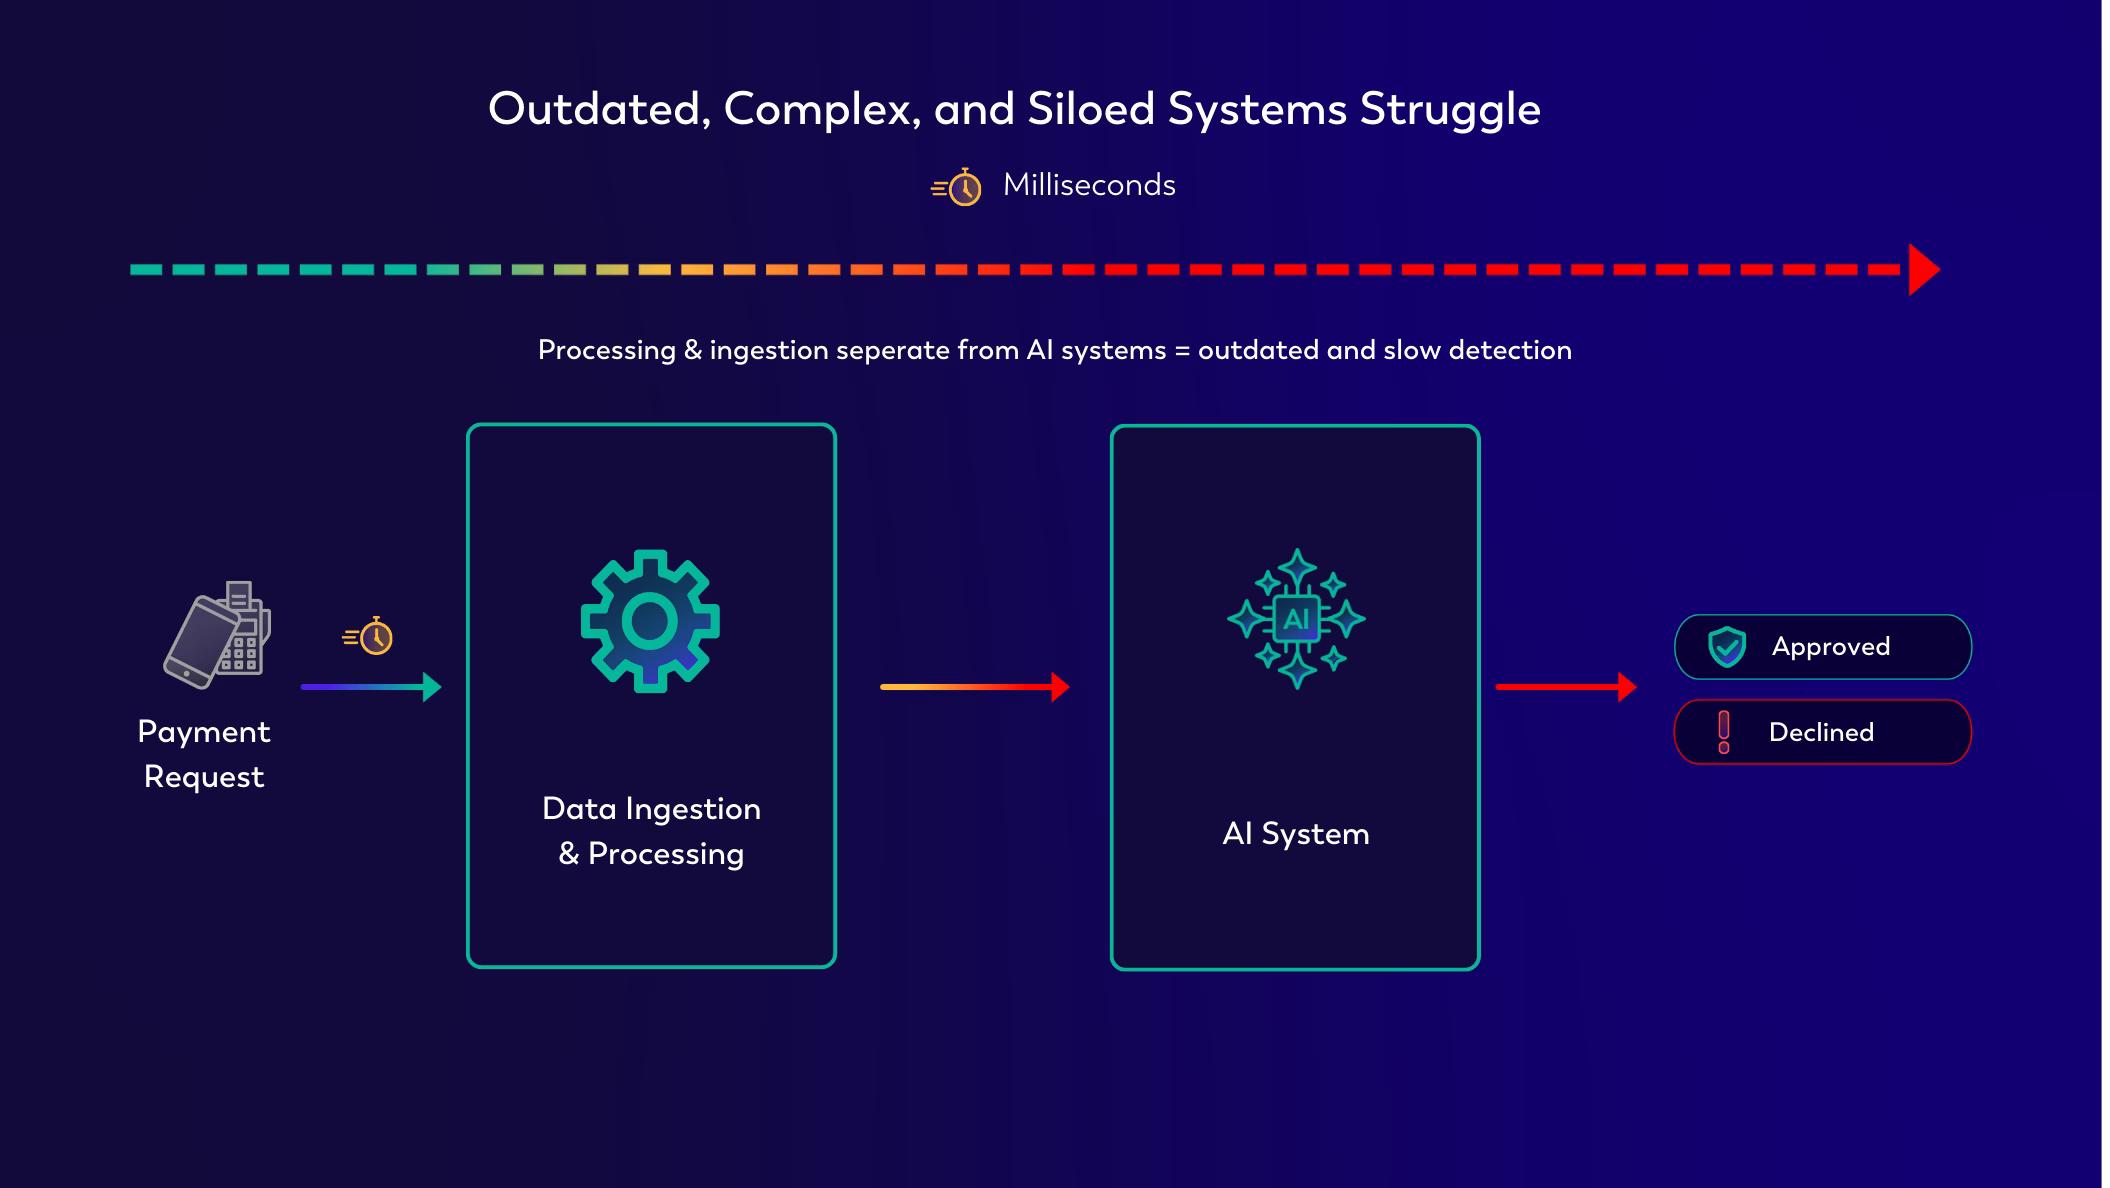
Likewise, in _**less than half a blink**_, a well-designed electrical protection and smart grid monitoring system can detect a fault and trigger the appropriate response. This instant fault detection is possible because the protective relays and circuit breaker devices work on the principle of fault isolation. When something is “off” in a node, like the current, voltage, or frequency registers, dangerously high or low, the node disconnects and is sacrificed to preserve the integrity of the entire system and to prevent the fault from cascading through adjacent nodes.
However, the Supervisory Control and Data Acquisition (SCADA) systems that govern generators and some other electrical equipment have polling cycles of 1–2 seconds, which makes them comparatively incredibly slow to detect and register a fault. Additionally, once a fault is registered, delays continue to add up. A trained operator must be alerted, assess the situation, and issue a response. From the moment the fault occurs to the point where a command is executed by the controller, this round-trip process can take over 5 seconds, which is far too slow to prevent cascading blackouts.
And the threat to energy grids is constant, with a myriad of factors that can trigger a fault. From the mundane, like a software glitch, to the catastrophic, like a tree falling on top of a transmission line, or the truly bizarre, like [a bullet striking a power line.](https://choptankelectric.coop/DSTL) What is common to all faults is that they must be detected, understood, and mitigated very quickly to prevent further damage.
## Streaming Fundamentals for Smart Grid Monitoring and Data-Driven Fault Handling
Real-time grid monitoring hinges on **streaming** (processing data as it arrives) versus **batch** (processing large, scheduled chunks). Streaming pipelines target **sub-100 millisecond latencies**, while batch jobs typically operate on seconds or minutes of delay (though they can run much longer).
With Ververica’s Unified Streaming Data Platform (powered by the [VERA engine](https://www.ververica.com/vera), and built by the original creators of [Apache Flink®](https://flink.apache.org/)), you can build a responsive, real-time streaming architecture that supports modern smart grid monitoring and prevents grid instability, ingesting **Phasor Measurement Units (PMUs)** as a foundational data source.
> **INFO:** What are PMUs, and why are they ideal for real-time power grid monitoring?
Phasor Measurement Units are specialized devices that provide high-precision, time-synchronized measurements of electrical waves on a power grid, which make them indispensable for real-time monitoring, control, and protection of modern grids.
Phasor Measurement Units (commonly referred to as PMUs) are specialized devices that provide high-precision, time-synchronized measurements of electrical waves on a power grid. Unlike traditional measurements that sample steady-state values every second or more, PMUs capture the instantaneous magnitude and phase angle of voltage and current waveforms at rates of 30–60 samples per second. This granularity and synchronicity make them indispensable for real-time monitoring, control, and protection of modern grids. They are orders of magnitude faster than SCADA systems, which typically poll every 1–2 seconds.
Acting as the foundational data source in a real-time streaming architecture, PMUs offer:
- **High-resolution time series data:** PMU phasors can flow into Kafka topics at sub-100 ms intervals.
- **Event timestamps:** Ververica’s Unified Streaming Data Platform aligns events by their timestamps, which ensures out-of-order packets still fit correctly into temporal analyses.
- **Data richness:** The amount and resolution of magnitude and phase data provided by PMUs can be very useful to detect voltage sags, angle jumps, or frequency dips in under 50 ms, triggering alerts or automated isolation commands before cascading failures can propagate.
By providing high-fidelity, time-synchronized measurements, PMUs are the linchpin for any system aiming to detect, alert, and handle grid faults in real time, and protect against rapid cascades like those resulting in the April 28, 2025, Iberian Peninsula blackout. Ververica’s stateful architecture retains context (e.g., last N snapshots), and its exactly-once guarantee ensures consistency even under failures, making it well-suited for sub-50 ms decision loops at grid scale.
## Fault Detection in Milliseconds
To catch grid anomalies in under 50 ms, and prevent cascading faults and blackouts, streaming pipelines must ingest, correlate, and act on phasor data faster than a human blink. A performant and reliable streaming data pipeline that achieves this might look like the following:
- **High-Velocity Ingestion**
- **PMUs → Kafka** via Kafka Connect: sub-millisecond writes into partitioned topics keyed by substation.
- **Exactly-once semantics:** Kafka’s acknowledgments paired with Ververica’s checkpoint guarantee no data loss or duplication, even under flash crowds (e.g., during a widespread fault).
- **Pattern Detection with** [**Complex Event Processing (CEP)**](https://www.ververica.com/blog/real-time-insights-for-airlines-with-complex-event-processing)
- **Define temporal patterns** (e.g., voltage sag + angle jump) with CEP rules.
- **Windowing & Event-Time Semantics:** Watermarks align out-of-order PMU streams so that late data can still trigger alarms within a bounded lateness (e.g., 20 ms).
- **Adaptive ML Models**
- **Online anomaly detectors** (e.g., streaming K-means) can run alongside CEP, spotting novel fault signatures that rules might miss.
- **Model updates in-flight:** We can use Ververica’s dynamic CEP to define new patterns and update thresholds and rulesets on the fly with no downtime required. For example, immediate adaptation to daily forecasted production and consumption, seasonal variations, or renewable intermittency.
## Instant Fault Detection and Automated Handling
Detecting a fault is only half the battle, as automated systems must then isolate the affected nodes, reconfigure the network, and restore power in a tightly controlled sequence to prevent a small disturbance from cascading into a regional blackout like the one that affected Spain and Portugal.
In an environment like the one we have described in this blog, where incident detection and alerts can happen in milliseconds by detecting fault patterns in the PMU readings, the process for fault handling could resemble the following:
1. **Fault isolation**When a high-severity fault is detected, the first automated response is to **isolate** the affected segment by tripping the nearest circuit breaker. Modern substations use the IEC 61850 GOOSE (Generic Object Oriented Substation Events) protocol for peer-to-peer protection messaging, and relays publish a “trip” command over Ethernet so that subscribing breakers act within a few milliseconds. Because GOOSE messages are multicast and pre-configured in the substation network, there’s no need for centralized polling, and as a result, latencies as low as 5-10 ms are routinely achieved ([source](https://library.e.abb.com/public/dc853877595c4086ae649ca29924c0ec/Paper_GOOSE%20Utilisation%20in%20Protection.pdf)).
1. **Grid topology reconfiguration**After isolation, the next step involves **reconfiguring the topology** of the grid to route power away from the affected node to maintain service continuity. Typically, an Advanced Distribution Management System (ADMS) holds the real-time network topology and load forecasts. Upon receiving a breaker-open event, the ADMS computes alternate feeder paths within 100–200 ms and pushes new switch-closing commands back through the same control network. This achieves the goal of maintaining power flow from producers to consumers while the faulted node remains de-energized, minimizing possible damages to equipment and disruptions to grid users.
1. **Black start** (if necessary)If the outage is severe enough to trigger a blackout, a planned and coordinated **black-start sequence** must be carried out when grid integrity has been verified. This involves remotely activating specific power plants that are capable of starting with no external power, and providing the power needed for larger grid-forming units to start up themselves. Automated restoration plans, stored in the Energy Management System (EMS), list these black-start units (including hydro plants, diesel gensets, or battery banks). These units are critical to the disaster recovery capacity of a power system and constitute the last line of defense. The EMS issues start commands to black-start sources in a pre-defined order, and as each generator comes online, its voltage and frequency are stabilized to match the grid design conditions. Progressively, new transmission lines are energized, paving the way for more generation units and consumers to come back online.
## Building a Power Grid Monitoring Architecture
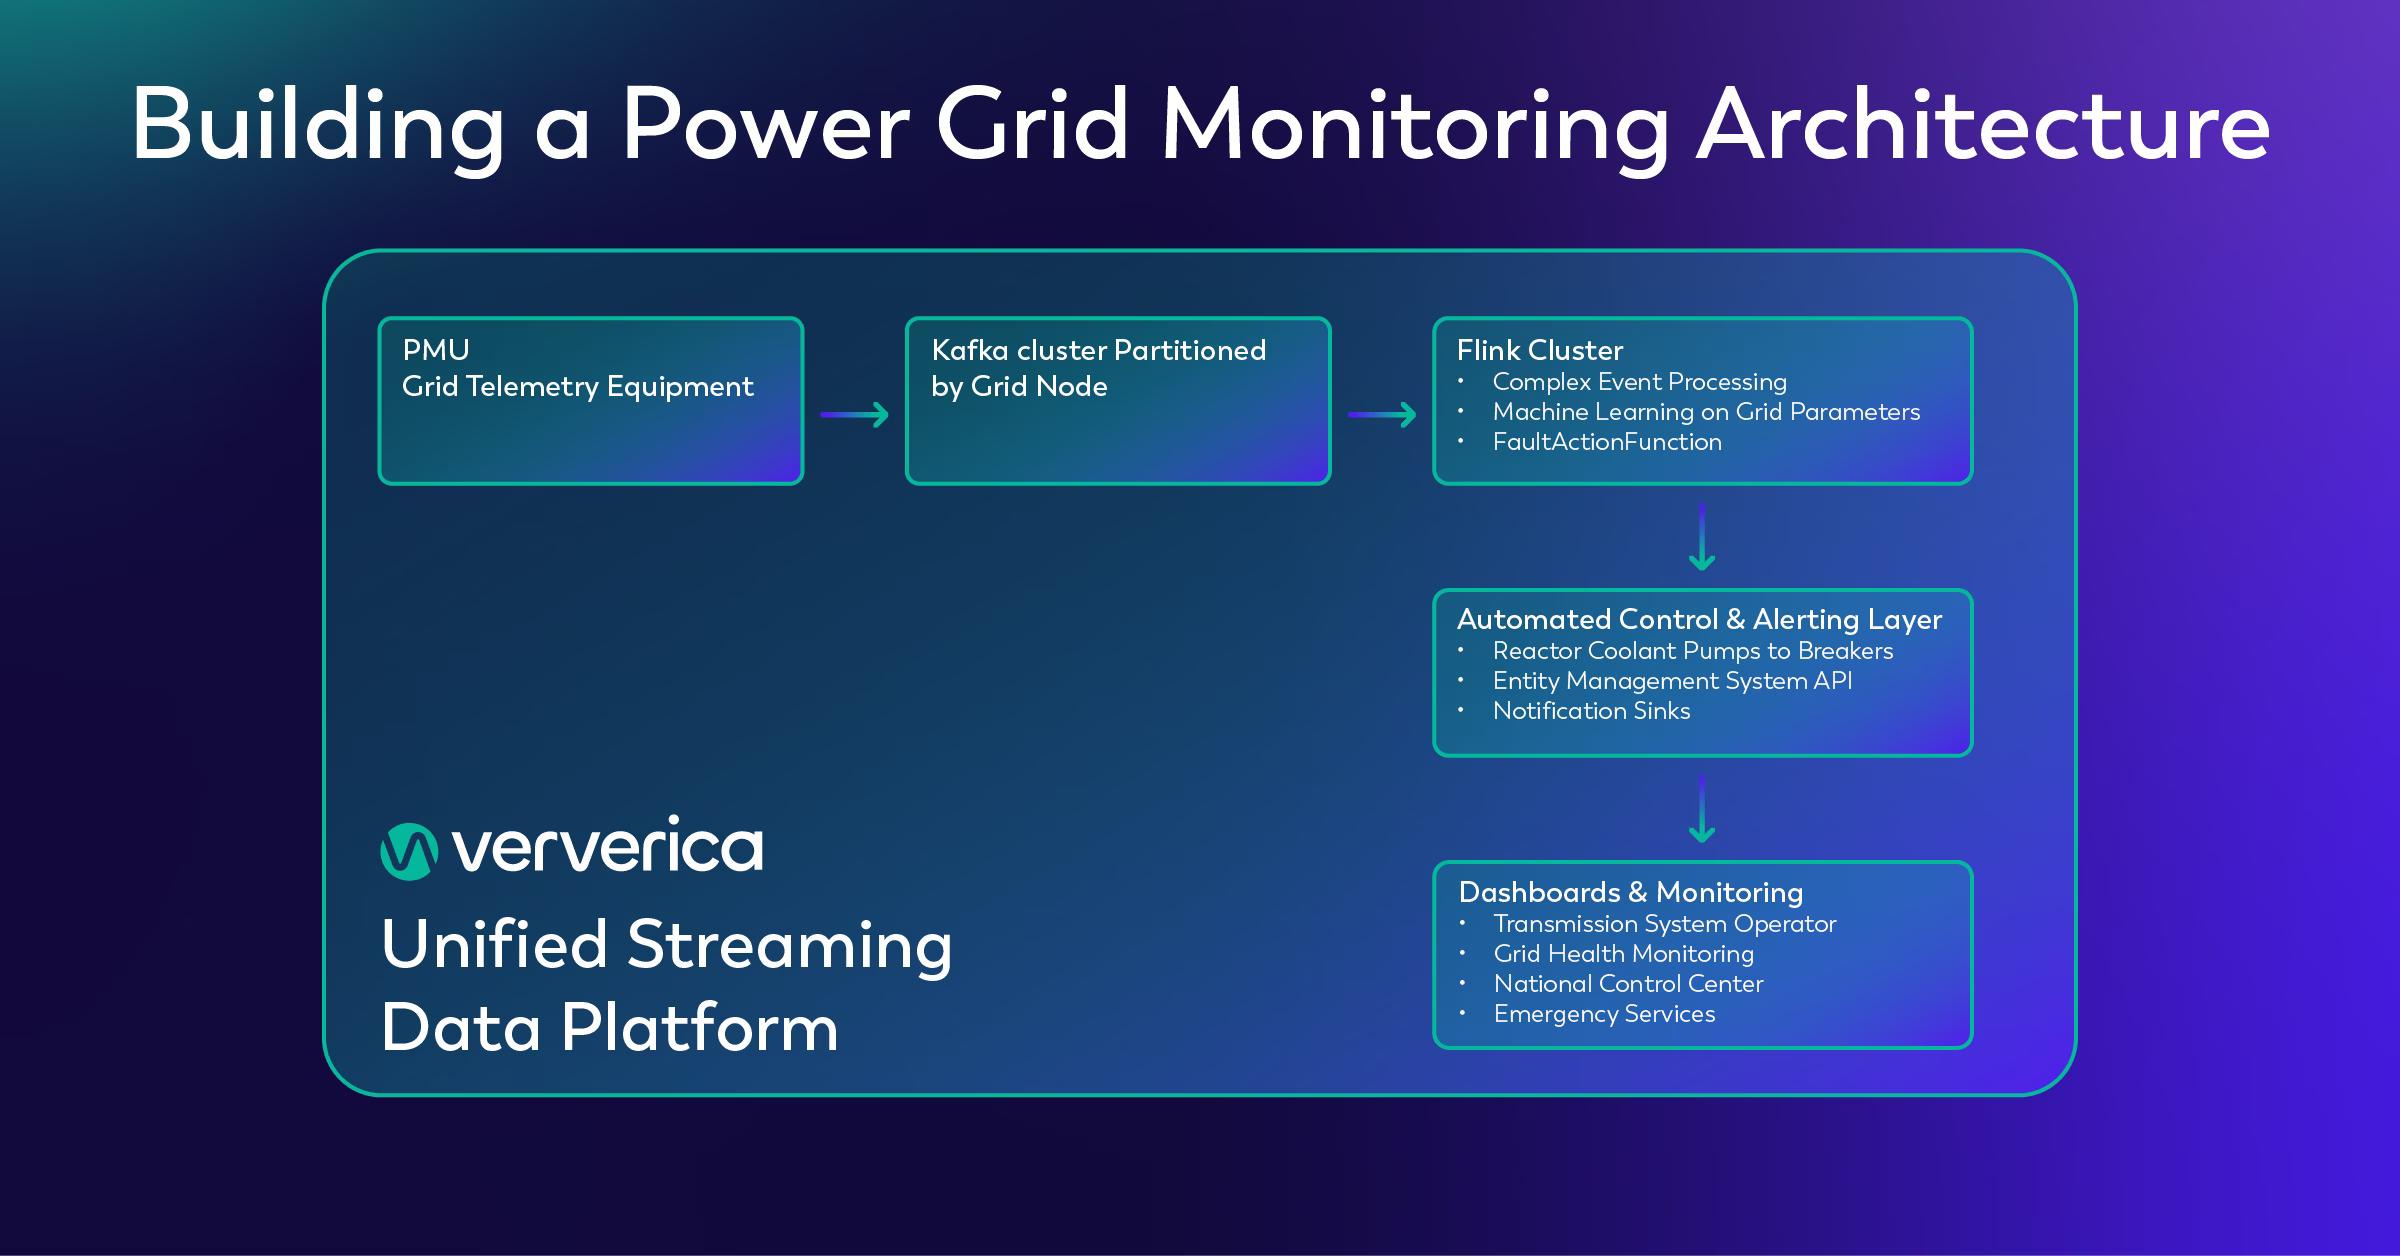
## Summary
As the [Iberian Peninsula Blackout](https://www.powermag.com/understanding-the-april-2025-iberian-peninsula-blackout-early-analysis-and-lessons-learned/) of April 28, 2025, demonstrates, split-second faults can cascade across thousands of kilometers of grid if they aren’t caught and contained in real time. Power grids with high penetration of renewables are more unpredictable and require faster actions and responses than legacy systems are designed to handle. For that reason, adopting streaming-first architectures and a wide range of actions to stabilize and secure the grid in real time is a critical step to guaranteeing energy supply in decarbonizing energy systems.
In this blog, we propose a solution that joins high-fidelity PMU telemetry with Ververica’s Unified Streaming Data Platform, giving grid operators the millisecond-level visibility and control they need to detect anomalies, isolate faults, and restore services automatically before a local disturbance becomes a regional crisis. Whether you’re piloting edge-deployed Flink clusters in remote substations or fine-tuning CEP patterns and online ML models for adaptive protection, the path to blackout-proof power systems runs through real-time data pipelines.
## More Resources
- Learn more about [Complex Event Processing](https://www.ververica.com/blog/real-time-insights-for-airlines-with-complex-event-processing)
- Explore more real-time [use cases](https://www.ververica.com/use-case)
- Learn more about the [Iberian Peninsula Blackout of 2025](https://www.powermag.com/understanding-the-april-2025-iberian-peninsula-blackout-early-analysis-and-lessons-learned/), including lessons learned and early analysis.
- Ready to build a resilient energy grid? [Contact Ververica.](https://www.ververica.com/contact)
---
---
title: "Real-Time Fraud Detection Using Complex Event Processing"
description: "Real-time fraud detection with Complex Event Processing helps identify suspicious transactions instantly. Try 3 real-world exercises for 2025 trends."
lastUpdated: 2026-03-17T12:34:38.000Z
source_url:
html: "https://www.ververica.com/blog/real-time-fraud-detection-using-complex-event-processing"
md: "https://www.ververica.com/blog/real-time-fraud-detection-using-complex-event-processing.md"
---
> **INFO:** What is real-time fraud detection, and how does it benefit the financial industry?
Real-time fraud detection is the immediate identification and prevention of suspicious or unauthorized activity as it happens. With real-time transaction monitoring, businesses and their customers are better protected from financial crime, payment fraud, account takeover, e-commerce fraud, and other suspicious transactions.
## Real-Time Fraud Detection and Pattern Recognition
To enable faster and more informed decision-making and handle their ever-increasing data volume, businesses are embracing real-time data processing. **Complex Event Processing (CEP)** and **Dynamic CEP** are powerful tools that allow you to detect event patterns in endless streams of events, helping you pinpoint critical insights and focus on the data that truly matters, including [real-time fraud detection.](https://www.ververica.com/use-case/fraud-detection)
In this blog post, we’ll explore how CEP is reshaping fraud prevention and anomaly detection strategies, including moving beyond batch-based systems to spot and correlate anomalies as they happen, trigger immediate interventions, and ultimately safeguard the business bottom line and brand while maintaining customers' trust. In addition, learn how [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product) enables continuous, stateful event processing to power fraud detection at scale. Finally, try it for yourself with several exercises available in our [GitHub playground](https://github.com/ververica/ververica-cep-fraud-detection), including:
- Identifying high-value consecutive transactions (back-to-back big spends)
- Responding to multiple rapid-fire transactions
- Building location-based suspicious activity solutions
## Detecting Fraud: Mission-Critical for Financial Institutions
Today, financial fraud is sophisticated, frequent, and extremely damaging. With cybercriminals constantly evolving their tactics, traditional fraud detection methods are no longer enough. The financial industry needs smarter, faster tools to keep pace, and that starts with real-time data and detection.
Are you ready to explore how real-time stream processing connects the dots before fraudsters do significant damage?
## Real-Time Detection
The ever-increasing speed and volume of digital transactions demand an equally agile response to fraud. Real-time detection enables financial institutions to continuously monitor and assess transactions as they happen, drastically reducing the window of opportunity for criminals to exploit stolen accounts or cards. In contrast, traditional batch-based systems are slow. Analyzing transactional data happens hours or even days after the original event, by which time substantial damage has already been done.
> **TIP:** Real-time data streaming enables continuous monitoring and fast assessment of financial transactions.
## Traditional vs. Real-Time Approaches
Historically, many banks rely on **batch jobs** that run on a set timeline to detect anomalies in transaction patterns. This delayed detection means that fraudulent transactions can slip through unchecked for a considerable period of time, and by the time a suspicious pattern is finally flagged, financial losses and damages have multiplied, as criminals have ample time to make additional unauthorized purchases or transfers.
A real-time system, on the other hand, evaluates transaction data as it flows in. Instead of waiting for large data sets to accumulate, each event is processed almost instantly. This approach offers two key benefits:
1. **Immediate Alerts:** Suspicious transactions trigger immediate notifications, allowing fraud teams to investigate and respond right away, reducing the risk of further fraudulent activities.
1. **Automated Intervention:** With real-time visibility, financial institutions can block cards or freeze accounts the moment they detect irregularities, containing losses before criminals exploit the window of delay inherent to batch processing.
## Continuous Data Streams: Enabling Continuous Monitoring
The shift from batch-based processing to real-time analytics requires a continuous data streaming infrastructure capable of handling high-volume, high-velocity transaction data. Furthermore, the system must be able to ingest data from multiple channels, seamlessly combining data from various sources that each have the potential to generate thousands of events per second, including:
- ATMs
- Mobile banking apps
- Online payment platforms
- Point-of-sale devices
- ...and more
Complex detection logic (like identifying repeated high-value transactions or suspicious location patterns) must also be executed in-flight, with low latency, as any significant processing delay provides criminals with the time needed to complete fraudulent transactions. Also, because transaction volumes can spike unpredictably (like during holiday seasons or during major shopping events), the system must be able to scale horizontally, adding more nodes or processing resources on demand to ensure that detection capabilities keep pace.
By adopting real-time detection methodologies, financial institutions not only protect themselves and their customers more effectively but also gain critical intelligence into emerging fraud tactics. This proactive stance helps preserve trust, minimizes financial damage, and helps to meet ever-evolving regulatory and compliance expectations.
## Centralizing Streams & State with Ververica’s Unified Streaming Data Platform
A core challenge in real-time processing is consolidating data from numerous disparate sources (including message queues, transactional databases, and third-party event buses) and then maintaining stateful logic on unbounded data flows. Ververica delivers this functionality by providing seamless, unified data ingestion, including integrated custom connectors and operators that funnel events from multiple channels into one pipeline.
Ververica offers real-time stream processing that enables transformations, filtering, and anomaly detection as each event arrives. Ververica also offers dynamic state management, providing tools to store and update session or user-specific information over time. As a result, Ververica can manage the complexities of continuous data ingestion, real-time analytics, and stateful computations in a single, enterprise-ready solution.
Below, Figure 2 visualizes Ververica’s real-time fraud detection pipeline, including ingestion from various financial events, consolidation of these individual transactions with the Unified Streaming Data Platform, and representation of rulesets that lead to a final response of either an alert or allow for the original transaction.
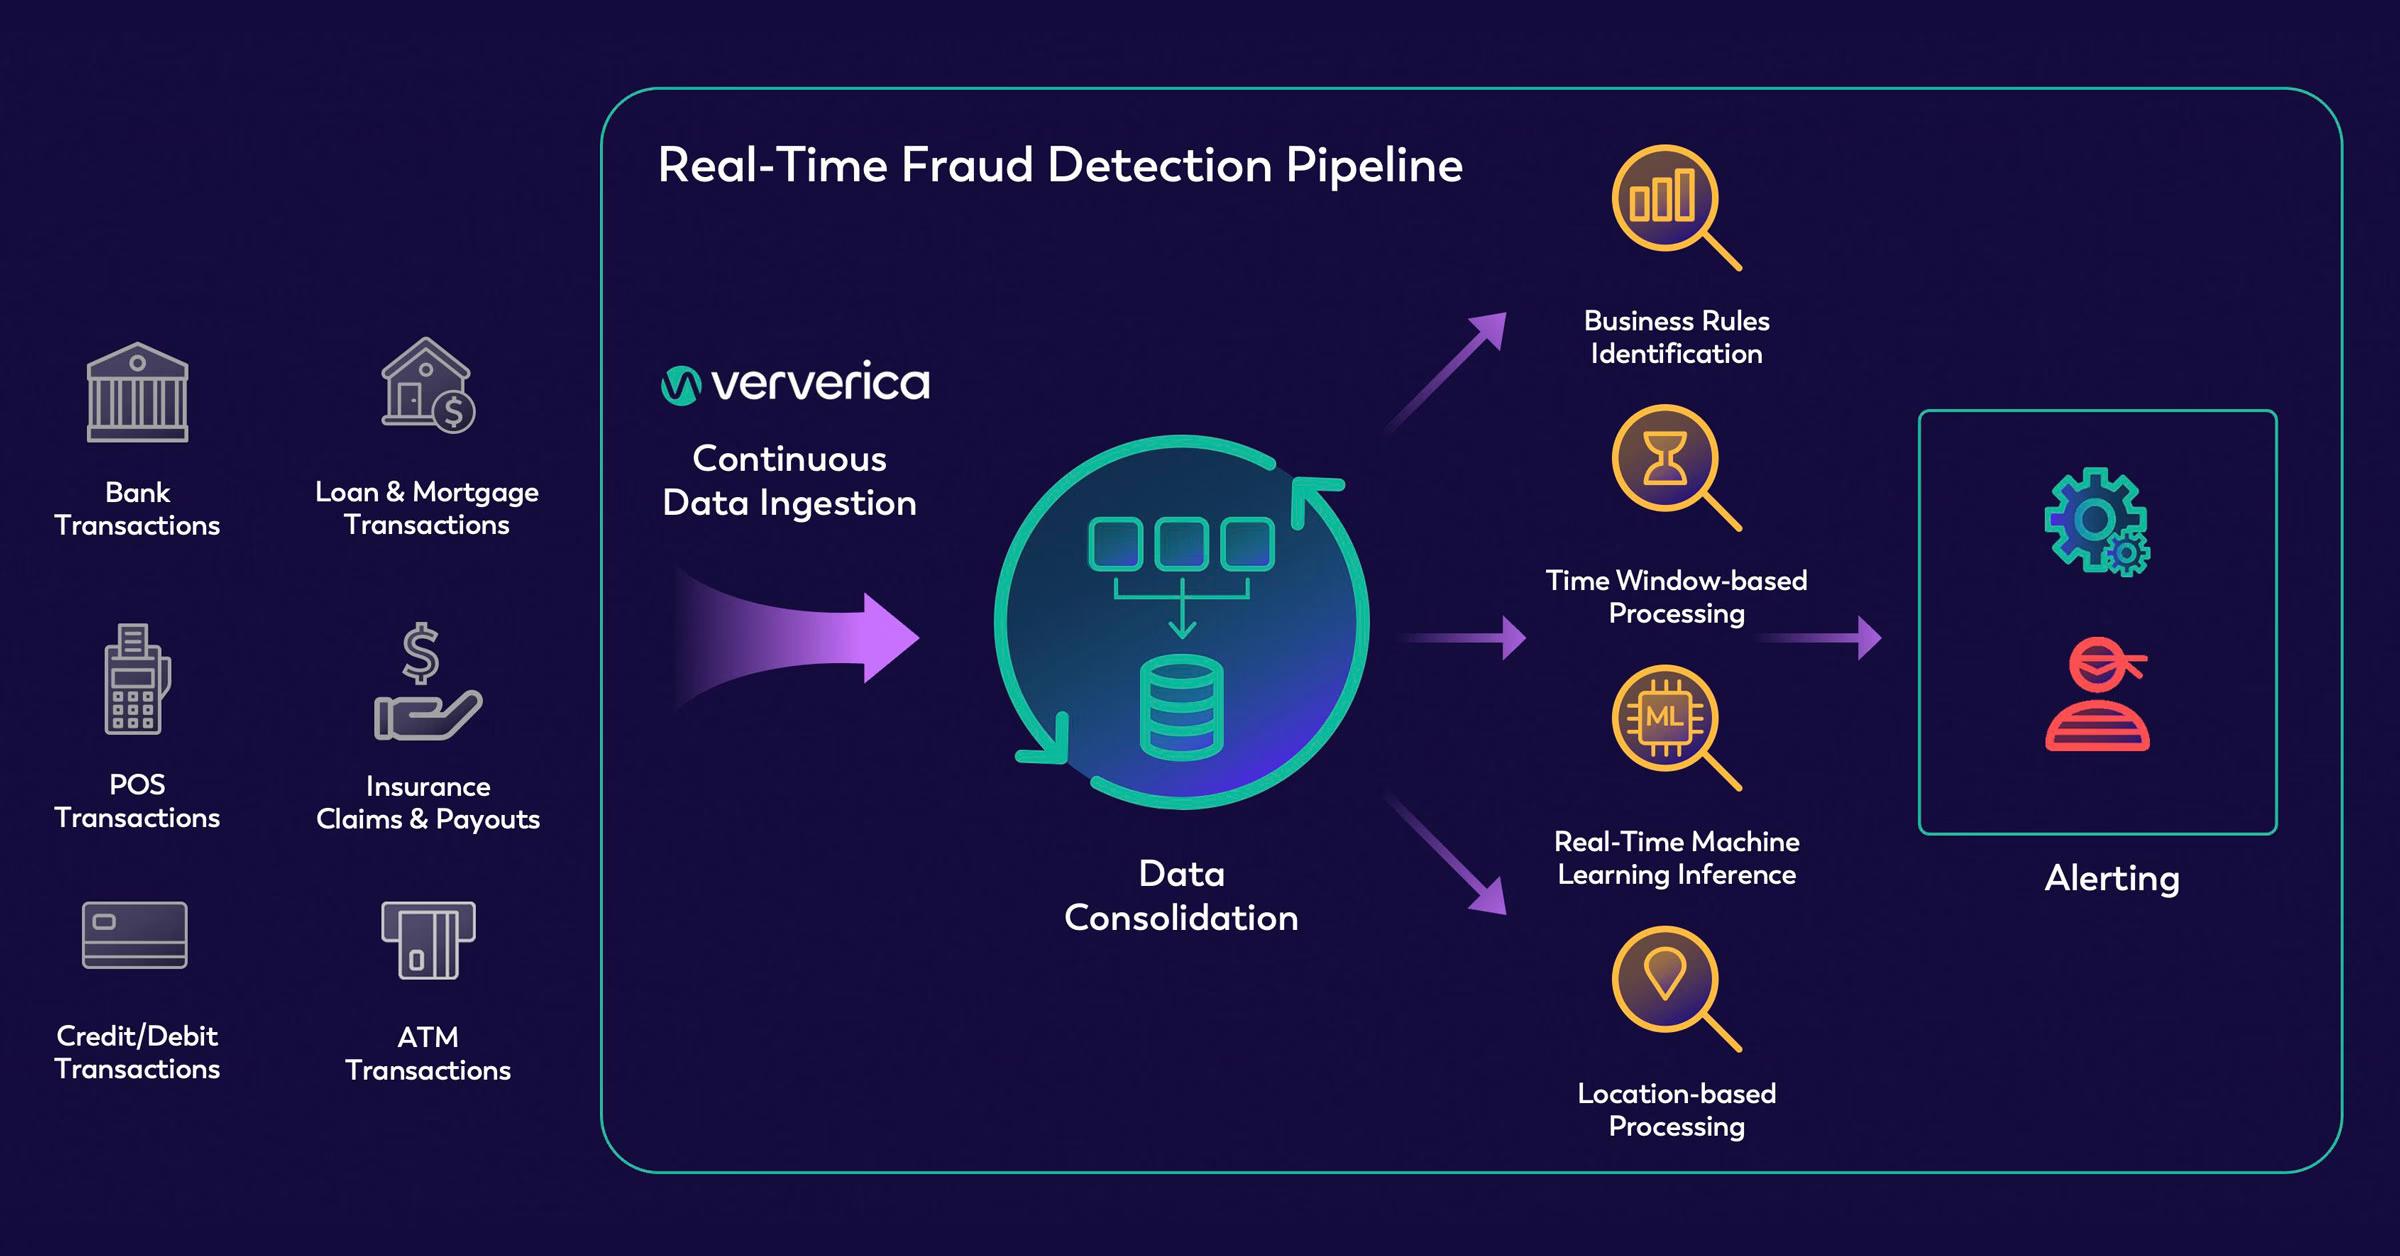
Both Ververica and [Apache Flink®](https://www.ververica.com/what-is-apache-flink) offer Complex Event Processing (CEP), a powerful tool that correlates events in real-time. The built-in CEP library makes it easy to apply CEP to streaming data, allowing businesses to define and track patterns across event streams, including detecting specific sequences and conditions that are important to their operations. As a result, teams can set up alerts, make adjustments, and trigger automated responses based on current events. As a differentiator from open-source Flink, Ververica also offers Dynamic CEP, which allows in-flight rule changes with no need to restart or experience any downtime, ideal for use cases like fraud detection, where any lag or delay in the continuous stream can have disastrous outcomes.
> **INFO:** What is Complex Event Processing?
CEP is the real-time analysis of multiple data events to identify meaningful patterns, trends, or anomalies and trigger immediate actions.
> **INFO:** What is Dynamic CEP?
The ability to adapt and modify event pattern rules based on changing data streams or conditions without pausing or restarting your data pipeline.
## How Does Complex Event Processing Work?
CEP is a methodology for analyzing and matching sequences of events against predefined patterns under certain time and logical constraints. Rather than treating each event (like credit card transactions) in isolation, CEP systems observe the flow of events to detect meaningful combinations.
Figure 3 demonstrates how CEP works. Data enters via the input event streams and moves through the CEP engine, where the patterns and rules that require identification have been defined. The engine continuously monitors the input data streams, applying the defined rules. When a match is identified, CEP outputs that matching event, allowing the business to take action directly.
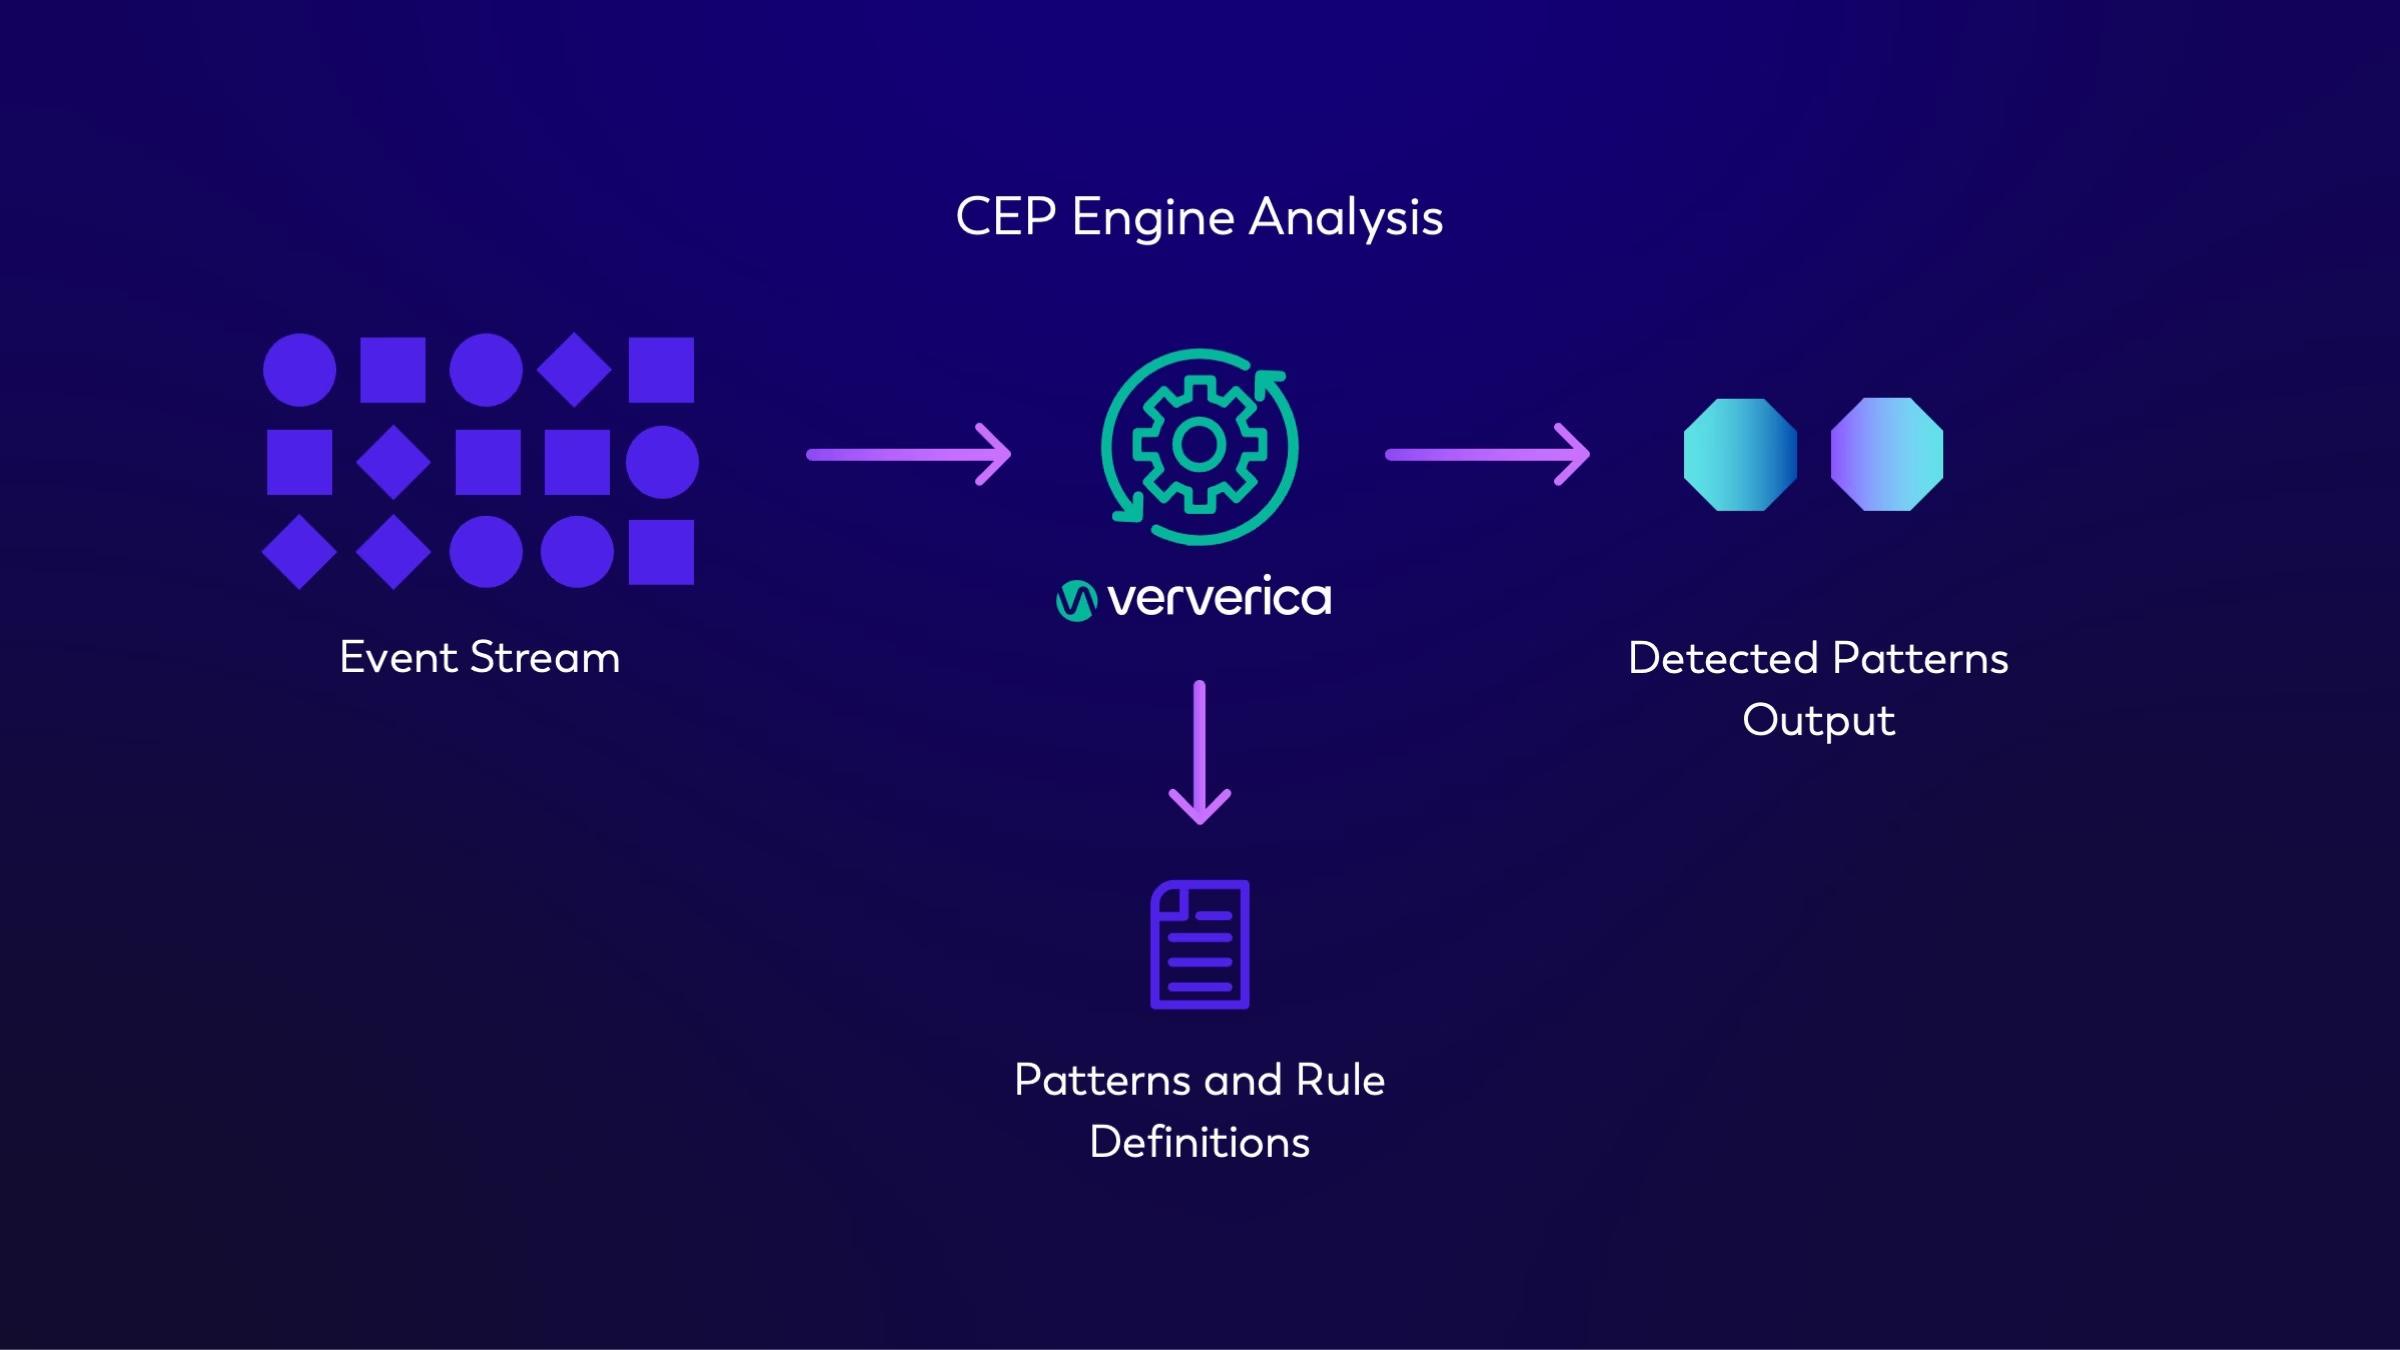
By continuously monitoring data streams, CEP can:
- **Specify Time Windows:** Identify patterns that happen within seconds or minutes (e.g., 3 transactions in 10 seconds).
- **Apply Flexible Conditions:** Factor in transaction amounts, locations, user history, or merchant categories.
- **Automate Response:** Trigger real-time alerts, freeze accounts, or escalate to risk teams whenever a defined pattern is matched.
This approach provides a more holistic view of user activity, enabling proactive and immediate action when potential fraud is detected. CEP enables businesses to track critical interactions, detect risks, and initiate automated responses in real-time. The result is an environment where critical insights are identified and reported as they happen, enabling more efficient and effective operations.
## Spotting Fraud in Real-Time: How Complex Event Processing (CEP) Connects the Dots
Modern financial fraud is rarely a one-off event involving only a single, isolated transaction. Instead, fraudsters create patterns of exploitation via a series of actions that are fast, subtle, seemingly unrelated, and cleverly disguised.
**This is where CEP shines.**
Instead of looking at transactions in isolation, CEP stitches events together in real-time, revealing suspicious behavior that single checks might miss. As a result, CEP empowers financial institutions to correlate multiple events in real-time, helping to catch suspicious activity that could otherwise go unnoticed when transactions are analyzed individually.
## Complex Event Processing Applications for Fraud Detection
Now, let’s create and test a few real-world fraud scenarios. Below are three common challenges that financial institutions face that illustrate how CEP correlates events together and can raise the alarm more effectively than single-event checks. Find sample implementations of the fraud patterns below in this [GitHub repo](https://github.com/ververica/ververica-cep-fraud-detection). And, it includes a data generator to test it out!
Find sample implementations of the fraud patterns below [in this GitHub repo](https://github.com/ververica/ververica-cep-fraud-detection), including a data generator to test them out.
### Exercise One: High-Value Consecutive Transactions (Back-to-Back Big Spends)
- **Scenario:** A stolen credit card gets swiped for two big purchases, each over $900, within just 30 seconds.
- **Why it’s suspicious:** While a legitimate user might splurge on pricey back-to-back purchases, multiple expensive purchases in quick succession are also a classic move for fraudsters trying to max out a stolen card before it’s shut down.
- **How CEP helps:** CEP connects the dots quickly, with continuous monitoring and pattern recognition that helps identify a possible account takeover, instantly flagging these events as suspicious. That alert prompts extra bank security checks or automatically freezes the card, stopping the financial crime before it spirals out of control.
### Exercise Two: Multiple Rapid-Fire Transactions
- **Scenario:** Within a very short timeline, multiple small transactions from different online stores occur from a single account.
- **Real-Life Context:** While a person might have a good reason to make several small purchases from different online stores within a very short time period, the rapid frequency of the purchases is unusual and points to another classic tactic used by fraudsters. Testing out stolen cards by exploiting smaller transaction thresholds allows potential account takeover to go unnoticed, as no individual event is an obvious suspicious transaction when inspected independently from one another.
- **How CEP Helps:** CEP continuously monitors for bursts of activity in short time windows (for example, three or more transactions in 10 seconds). By defining a specific time window and looking for multiple consecutive events, CEP alerts the bank anytime it detects these bursts of activity that might be an anomaly. As soon as this pattern appears, the system flags it, and the bank can then temporarily block the card and ask the real account owner whether the recent transactions are real or a financial crime.
### Exercise Three: Location-Based Suspicious Activity (The “Impossible Travel” Trick)
- **Scenario:** A credit card is used in Berlin, and then again in London less than 20 minutes later.
- **Real-Life Context:** Even with modern travel, covering that geographical distance in mere minutes is completely impossible. This type of activity indicates card cloning, account takeover, or account compromise, including possible card theft or illicit account sharing.
- **How CEP Helps:** CEP calculates both the distance and elapsed time between transactions to catch these “impossible travel” events. If the travel time doesn’t add up, it immediately flags the activity. Using real-time alerts that prompt the bank to initiate step-up authentication or block the account until the user verifies their location, the bank can engage in better fraud prevention and reduce financial crimes.
## Conclusion: Correlating Multiple Events
Fraud detection systems are a must-have for financial institutions ([fraud trend predictions for 2025](https://www.acfe.com/acfe-insights-blog/blog-detail?s=top-fraud-trends-2025) show an increase in both fraud activity and pressure regarding how a company should respond to protect customers), and real-time capabilities are the difference in limiting losses and protecting customers. Modern fraud is rarely the result of a single suspicious event, instead, it’s a sequence of subtle, fast-moving actions that only make sense when viewed in context. CEP excels at identifying these patterns, helping to expose risks that would otherwise remain hidden. Rather than reacting to individual anomalies, CEP enables financial institutions to act on meaningful correlations in real time, whether that’s detecting a rapid burst of high-value purchases or spotting location shifts that don’t align with usual user behavior.
Acting like a smart security camera for your data, CEP is always on, always learning, and always ready to act, helping to connect the dots across time, geography, and transaction types, and empowering financial institutions to detect and stop fraudulent behavior in real time.
Ultimately, financial institutions gain a future-proof fraud detection solution that is scalable, adaptive, and resilient. With Ververica’s Unified Streaming Data Platform, data teams can centralize data ingestion, stateful processing, and pattern detection in a singular, robust solution. With the ability to correlate complex behavior patterns and trigger instant responses, Ververica helps organizations stay one step ahead of evolving threats, safeguard customer trust, and meet the growing demands of a real-time digital economy.
## More Resources
Learn more about the importance of real-time fraud detection in: “[Outrun Fraudsters with Agentic AI,](https://www.ververica.com/blog/outrun-fraudsters-with-agentic-ai-and-ververica)” where we discuss two transformative technologies, [Agentic AI](https://www.ververica.com/use-case/ai-ml) and [stream processing](https://www.iotinsider.com/industries/industrial/real-time-data-has-become-the-norm-said-ben-gamble-from-ververica/), and how, when combined, they form a powerful solution for combating fraud effectively.
Read more about real-world CEP use cases in “[Real-Time Insights for Airlines with Complex Event Processing”](https://www.ververica.com/blog/real-time-insights-for-airlines-with-complex-event-processing). (Also includes GitHub exercises to try for yourself!)
Watch the video: “[Understanding Complex Event Processing with Applications in E-Commerce Platforms](https://www.youtube.com/watch?v=xugLuycUyKM)” for more examples of how CEP correlates data into actionable insight, including:
- Cross-sell and upsell opportunities
- High-value card abandonment detection
- Purchase intent scoring
- Price sensitivity detection
- Churn prediction
[Try out CEP for yourself!](https://github.com/ververica/ververica-cep-fraud-detection) Create a real-time streaming application.
---
---
title: "Outrun Fraudsters with Agentic AI and Ververica"
description: "Enhance fraud detection with agentic AI and Ververica's real-time stream processing for robust, scalable, and adaptive solutions."
lastUpdated: 2026-03-17T12:35:30.000Z
source_url:
html: "https://www.ververica.com/blog/outrun-fraudsters-with-agentic-ai-and-ververica"
md: "https://www.ververica.com/blog/outrun-fraudsters-with-agentic-ai-and-ververica.md"
---
> **INFO:** What is Agentic AI and How Does Fraud Detection Benefit From It?
Agentic AI systems connect to enterprise data and act autonomously, making independent decisions, and adapting new information to solve complex, multi-step challenges with minimal human intervention. Because AI agents can make context-aware decisions and execute tasks dynamically, they are beneficial for any use case that requires real-time anomaly detection, data analysis, and preventative action or response.
## Fraud Detection
Fraud detection stands as a pivotal challenge for businesses across all industries, from financial services to e-commerce and beyond. The consequences of inadequate [fraud detection](https://www.ververica.com/use-case/fraud-detection) systems can be devastating for companies; as unauthorized credit card transactions, digital wallet hacks, AML (Anti-Money Laundering) and KYC (Know-Your- Customer/Client) fraud, and other malicious activities exploit vulnerabilities in applications. This leads to significant negative outcomes like lost revenue, regulatory fines, customer churn, and damage to brand integrity. Let’s explore modern tools that help businesses outrun fraud.
## Outdated Infrastructure Stifles Innovation
A leading cause of inadequate fraud detection is outdated and complex solutions that struggle to process perpetually increasing transactions. Another is incompatibility with modern technologies like AI-driven fraud detection systems. Many businesses already grapple with time-sensitive SLAs (Service Level Agreements) mandated by regulatory bodies around the world, including the FCA, SEC, SBS, and NFRA.1

Thankfully, modern architectures and infrastructures provide [real-time processing](https://www.ververica.com/vera#movement) and dynamic scalability to accommodate increasing data volumes and the computational intensity of advanced algorithms. This shift not only enhances fraud detection outcomes but also ensures compliance with industry standards. As fraudsters grow increasingly sophisticated, businesses must continue to adopt advanced technologies capable of outmaneuvering emerging threats.
Next, let’s dive into how agentic AI and stream processing help to accomplish this goal.
## Necessity is the Mother of Invention
[Agentic AI](https://www.ververica.com/use-case/ai-ml) and stream processing are two transformative technologies that, when used together, form a powerful solution for combating fraud effectively. Agentic AI introduces autonomous decision-making and continuous learning, enabling systems to adapt dynamically to new patterns of fraudulent behavior. Stream processing ensures the real-time ingestion and analysis of data, providing the real-time insights necessary for timely intervention. Together, these innovations offer a robust framework for addressing the complexities of modern fraud detection.
Agentic AI is a paradigm shift in how typical AI systems operate. Whereas traditional AI models rely on static training data and struggle to adapt to new or unforeseen anomalies, agentic AI introduces autonomy, adaptability, and contextual awareness. These systems operate independently, analyzing streams of data, identifying patterns, and taking actions without human (or manual) intervention. They continuously learn from new data in real-time, updating their knowledge base to improve accuracy over time. Moreover, agentic AI understands the broader context of transactions, user behavior, and environmental factors, enabling more nuanced fraud detection. The benefits of this approach are profound: proactive fraud prevention, adaptability to new threats, and reduced false positives.
Online banking is a good example where agentic AI can flag unusual login attempts, large transfers to unfamiliar accounts, or atypical spending patterns—all while adapting to legitimate changes in customer behavior.
## Instant Action from the Freshest Data
A critical component of effective fraud detection is ensuring that AI models have access to the freshest data. Fraudulent activities often unfold rapidly, leaving little room for delayed responses based on stale data. The leading stream processing solutions play a vital role in ingesting, analyzing, and acting on event-driven data in sub-200 milliseconds, rather than accessing it in a database at a later time. By analyzing data as soon as it’s generated, stream processing enables real-time insights and actions. Fresh data is essential for fraud detection because it provides immediate visibility into emerging threats, allows AI models to stay ahead of dynamic fraud patterns, and incorporates contextual information such as geolocation, device type, and session duration. Stream processing pipelines ensure that agentic AI systems receive a constant flow of relevant data, empowering them to make timely and accurate decisions.
To further enhance the speed and accuracy of AI model output, [Model Context Protocol (MCP)](https://github.com/modelcontextprotocol) is an emerging standard that enables AI models to connect to external data sources in real-time, without the need for customized integrations. This provides much greater accuracy for real-time queries, reduces hallucinations, and provides a standardized approach for models to access the freshest data without developers having to spend time building and maintaining data integrations.
## Ververica’s Relentless Pursuit: Agentic AI Workloads
When implementing agentic AI for fraud detection, choosing the right stream processing solution is crucial. [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product) is the premier choice, boasting robust capabilities and dynamic scalability. Ververica supports high-throughput, low-latency stream processing, making it perfect for applications that require instant responses. It seamlessly scales to handle several billions of transactions per second, ensuring the highest performance under any load. The platform integrates effortlessly with existing data sources, analytics tools, and machine learning frameworks, simplifying the deployment of agentic AI workflows. Built by the original creators of [Apache Flink®](https://www.ververica.com/what-is-apache-flink), and 100% compatible with open-source Flink, Ververica provides enterprise-grade, mission-critical capabilities that guarantee the highest performance, consistency, availability, and security, to ensure zero downtime and zero data loss. Its unified architecture combines batch and stream processing in a single platform, reducing infrastructure complexity and stream processing development.
For fraud detection, Ververica provides end-to-end pipeline support, customizable workflows, and an AI-friendly environment that makes deploying and managing agentic AI models straightforward.
## Autonomous, Context-Aware Decision-Making
Let’s consider a real-world example. Imagine an [e-commerce company](https://www.ververica.com/blog/kartshoppe-real-time-feature-engineering-with-ververica) facing rising cases of chargeback fraud. Using Ververica’s Unified Streaming Data Platform, the company sets up a real-time fraud detection system powered by agentic AI. Transaction data flows into the platform from multiple sources, including payment gateways, user profiles, and third-party APIs. Ververica processes this incoming data in real-time, enriching it record-by-record with contextual information such as shipping addresses, purchase history, and behavioral analytics. An agentic AI model evaluates each transaction against known fraud patterns and dynamically adjusts its criteria based on new data. Suspicious transactions are flagged immediately, triggering automated actions such as sending verification codes or blocking payments. Over time, the AI model continues to learn from every interaction, further refining its ability to distinguish between legitimate and fraudulent activity. Utilizing this modern fraud detection system, the e-commerce company lowers the cases of chargeback fraud dramatically, reducing cost and payouts for fraudulent activity, and ends up with a better overall customer experience as well.
By leveraging agentic AI and Ververica’s capabilities, businesses reduce fraud and enhance customer trust and satisfaction. In addition, they benefit from seamlessly integrating modern application architectures into their existing infrastructures at a fraction of the time and cost due to the multi-faceted capabilities of Ververica’s Unified Streaming Data Platform.
## Curtailing the Barrier to Entry
There is a perception that agentic AI capabilities are overly complex and difficult to integrate within current architectures. Ververica streamlines the unification of agentic AI with legacy systems. With a flexible architecture and extensive compatibility, it is remarkably easy to adopt, even within entrenched legacy environments. Designed to work seamlessly with a wide range of data sources, sinks, and third-party tools, Ververica ensures zero disruption during migration, empowering organizations to modernize their systems and unlock the full potential of agentic AI, while preserving existing investments. In addition, Ververica offers expert knowledge from subject matter experts.
## Staying Ahead of Potential Risks
The demand for cutting-edge technologies that match the speed and sophistication of modern cybercriminals continues. Agentic AI brings unparalleled intelligence and adaptability to fraud detection, while Ververica’s Unified Streaming Data Platform ensures that AI-driven applications have access to the freshest possible data, delivering the performance, scalability, and flexibility required for real-time fraud detection. Ververica’s seamless integration with agentic AI workflows makes it an indispensable solution for businesses looking to stay ahead of fraudsters. Outrun fraudsters with agentic AI powered by real-time stream processing to build robust, future-proofed systems that protect business assets and customers.
## More Resources
[Use Cases] [Learn](https://www.ververica.com/use-case) how to detect and prevent fraud, and build AI systems that learn, adapt, and act in real-time, and more.
[Case Study] Read how KartShoppe leverages [Ververica for real-time feature engineering.](https://www.ververica.com/blog/kartshoppe-real-time-feature-engineering-with-ververica)
1[FCA-Financial Conduct Authority](https://www.fca.org.uk/) (UK), [SEC-Securities & Exchange Commission](https://www.sec.gov/) (USA), [SBS-Superintendencia de Banca, Seguros y AFP](https://www.gob.pe/sbs) (PERU), [NFRA-National Financial Reporting Authority](https://www.nfra.gov.cn/en/view/pages/index/jiansuo.html)(China), [BaFin-Federal Financial Supervisory Authority](https://www.bafin.de/EN/Homepage/homepage_node.html) (Germany).
---
---
title: "KartShoppe: Real-Time Feature Engineering With Ververica"
description: "Discover how KartShoppe leverages Ververica’s real-time feature engineering to enhance their AI and ML models for immediate, data-driven decision-making."
lastUpdated: 2026-03-17T12:36:05.000Z
source_url:
html: "https://www.ververica.com/blog/kartshoppe-real-time-feature-engineering-with-ververica"
md: "https://www.ververica.com/blog/kartshoppe-real-time-feature-engineering-with-ververica.md"
---
This is a story based on a real business use case, featuring an e-commerce company (“KartShoppe”) that is just beginning to explore and implement real-time feature engineering.
## Introduction
KartShoppe has a significant challenge: their data teams are struggling to keep up with the growing demands of the business. KartShoppe operates a popular online marketplace with millions of users, and every click, view, and purchase generates data that is crucial for understanding user behavior, providing recommendations, and identifying possible fraudulent activities. However, no matter how much the team tries, they can’t shake the feeling that their data pipelines and models are lagging behind the actual user experience. The explanation? By the time their models receive the latest user data, that data is already out-of-date, making it incredibly hard for their recommendation and fraud detection engines to provide helpful decisions that further engage their customers, provide a better customer experience, and ultimately increase business profits.
**KartShoppe is ready to make real-time decisions based on real-time data.**
The next step? Implementing feature engineering that allows the team to select, transform, and create relevant input variables from their raw data that improves the performance of their machine learning models. Feature engineering is a crucial step in the AI/ML pipeline to ensure models receive high-quality, meaningful data at low latency and at highly scalable, variable volumes.
If KartShoppe’s challenge sounds familiar, you’re not alone. Real-time data engineering, especially for [machine learning and AI](https://www.ververica.com/use-case/ai-ml), allows companies to deliver quick insights and timely predictions, and traditional batch processing isn’t fast enough when the goal is to create real-time experiences. With the recent explosion of AI, real-time stream processing solutions like [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product) have become even more essential across industries that rely on instant data for immediate decision-making. In this blog post, we’ll explore how real-time data pipelines that support feature engineering strategies are implemented. Let’s begin with a look at the big picture of real-time AI pipelines and workflows, and then dig into the technical components that KartShoppe adopts to solve their use cases.
> **NOTE:** Throughout this blog the term “AI” is used interchangeably when describing both machine learning and AI models. AI refers specifically to externally owned models (including Qwen, Gpt4o, and DeekseekR1) vs ML where the model is trained in-house (with tools like TensorFlow or PyTorch).
## Real-Time Data Pipelines For AI: The Big Picture
Building effective real-time AI pipelines involves more than simply feeding data into a model. It requires an end-to-end data pipeline that continually ingests, processes, and refines incoming data, while at the same time being able to adapt and incorporate new information. Figure Two below outlines the major components of a complete real-time AI data pipeline. Let’s break down each of these steps:
### 1. Data Ingestion
Real-time data pipelines begin with the ingestion layer that captures event streams from various sources, including operational databases, message queues, and third-party APIs. Ingesting raw data from nearly any source is incredibly powerful, but techniques like Change Data Capture (CDC) also come into play, turning databases into continuously updated streams of inserts, updates, and deletes. CDC tracks and identifies every modification made to data in real-time, ensuring that the data and pipeline remain consistent and in sync with the latest changes, enabling models and other downstream applications to have access to the freshest possible inputs near-instantaneously.
### 2. Data Preprocessing
Before any model can extract value, incoming data needs to be cleaned, standardized, and validated. During this stage, the pipeline removes duplicates, normalizes values into a consistent format, and flags outliers or anomalies that could skew predictions. Completing these steps early sets a strong foundation for reliable feature engineering and accurate model outputs, mitigating issues that could compound downstream.
### 3. Feature Extraction and Engineering
Once data is cleaned, the pipeline transitions to transforming raw observations into relevant features, including the metrics or attributes that capture the essence of what the model needs to learn. For example, an e-commerce business like KartShoppe might track **"number of items viewed in the last 10 minutes"** or **"time since the user’s last login** as features to support real-time recommendations. High-quality features enhance a model’s view of user behavior or system states, thereby boosting accuracy and resilience. This step is often considered the “creative core” of AI, as well-crafted features can dramatically improve predictive performance.
### 4. Model Serving and Inference
With features generated and readily available, the pipeline must serve these features to deployed models at scale and on time, including demands that must take place within milliseconds. A well-designed serving infrastructure handles high volumes of requests (e.g., personalized recommendations or fraud checks,) while maintaining low latency. In practice, this might involve specialized microservices or inference frameworks optimized for concurrency, load balancing, and failover. By seamlessly feeding up-to-date data into model inference, real-time pipelines can support prompt decisions that directly impact user experience or security.
### 5. Adaptive Learning
Over time, the environment in which these models operate can shift significantly. Adaptive or online learning allows models to update their parameters continuously based on new data as it arrives, without requiring a full offline retraining process. This capability is important for situations like evolving fraud tactics or rapidly changing consumer preferences. By assimilating the latest data, models retain their relevance and effectiveness, reducing the time lag between shifts in real-world behavior and the pipeline’s response.
### 6. Feedback Loops
While adaptive learning focuses on real-time changes in the data itself, feedback loops emphasize the ongoing evaluation of model performance. Each prediction generates an outcome, for example, whether a recommended item was clicked or if a flagged transaction was indeed fraudulent. The pipeline records these outcomes to assess predictive accuracy and to further refine the model in subsequent iterations. This continuous feedback mechanism underpins true machine learning maturity: the system not only adapts to new data patterns, but also learns from its own successes and missteps to improve decision-making over time.
It’s important to note that adaptive learning and feedback loops might seem similar, but they are not the same. Both concepts involve improving the model over time, but adaptive learning focuses on learning from new data, while feedback loops provide improvements based on the accuracy of previous decisions.
### The Complete Real-Time AI & ML Pipeline
When put together, this complete pipeline creates the backbone of real-time AI, where data is ingested, processed, and used for real-time actions while simultaneously adapting and improving based on feedback and new data.
Now that we have an understanding of the overall pipeline, let’s focus on feature engineering specifically.
## The Journey from Batch to Real-Time Feature Engineering
Feature engineering is the process of transforming raw data into meaningful inputs (ie: features) that improve the performance of models. At its core, AI and ML models rely on features to represent the problem domain in a way that the model can understand and process. High-quality features allow:
- **Actionable signals:** Features do not merely replicate raw data; instead, they highlight the elements most relevant to the predictive task. By capturing crucial patterns (like recent clicks, transactions, or anomalous activities) into a more informative representation, they allow the model to focus on what truly matters. This accelerates learning and avoids overwhelming the model with “noise” (ie: irrelevant content).
- **Improve model accuracy:** When features capture the most pertinent aspects of user behavior or system states, the model’s predictive power increases significantly. Robust features help the model generalize effectively, meaning it can produce reliable predictions even when presented with new, unseen data. Better generalization translates into fewer mistakes and more consistent performance.
- **Reduce complexity:** Properly engineered features simplify how the model “views” the problem space. Rather than forcing a model to infer critical relationships from unprocessed data, high-quality features organize and refine the input, making patterns more apparent. This streamlined input representation reduces the risk of overfitting, (where a model memorizes details specific to the training data,) and also makes it easier to tune and maintain models over time.
- **Domain relevance and interpretability:** Effective feature engineering often integrates domain expertise, ensuring that each feature reflects a real-world concept or behavior. Domain alignment not only improves the model’s accuracy but also makes the results more interpretable. When decision-makers can connect model outputs back to meaningful features, (like **"average purchase frequency"** or **"time since last login"**) they gain greater trust and insight into why the model behaves the way it does.
### Taking Batch to Real-Time
In a batch processing setup, engineers usually create features by aggregating data over long time windows, such as weeks or months. While plenty of use cases still benefit from batch processing, many modern business use cases demand real-time requirements, and batch processing simply isn’t fast enough to keep up. For example, in the case of KartShoppe building their recommendation engine, knowing what a user did a month ago is valuable, but understanding what they did a few seconds ago is much more powerful, actionable data.
Features are also not static. In dynamic environments and industries like e-commerce, finance, or IoT, (to name a few,) the data landscape evolves rapidly. Static, pre-computed features quickly become stale, leading to degraded model performance. This is particularly detrimental in applications where decisions need to be made in real-time, like recommending products during an active user session, or for fraud detection.
So how do we turn raw, real-time data into high-quality features for ML models? For companies like KartShoppe, this is where streaming data platforms shine, making the process seamless for engineers.
Built to be 100% compatible with Apache Flink, the de facto standard for stream processing, Ververica’s Unified Streaming Data Platform is ideal for real-time feature engineering. Powered by the [VERA engine](https://www.ververica.com/vera), the solution provides [Streaming Data Movement](https://www.ververica.com/vera#movement), [Streamhouse](https://www.ververica.com/streamhouse), and [Real-Time Stream Processing](https://www.ververica.com/vera#real_time) into a single platform. (See Figure 3.)
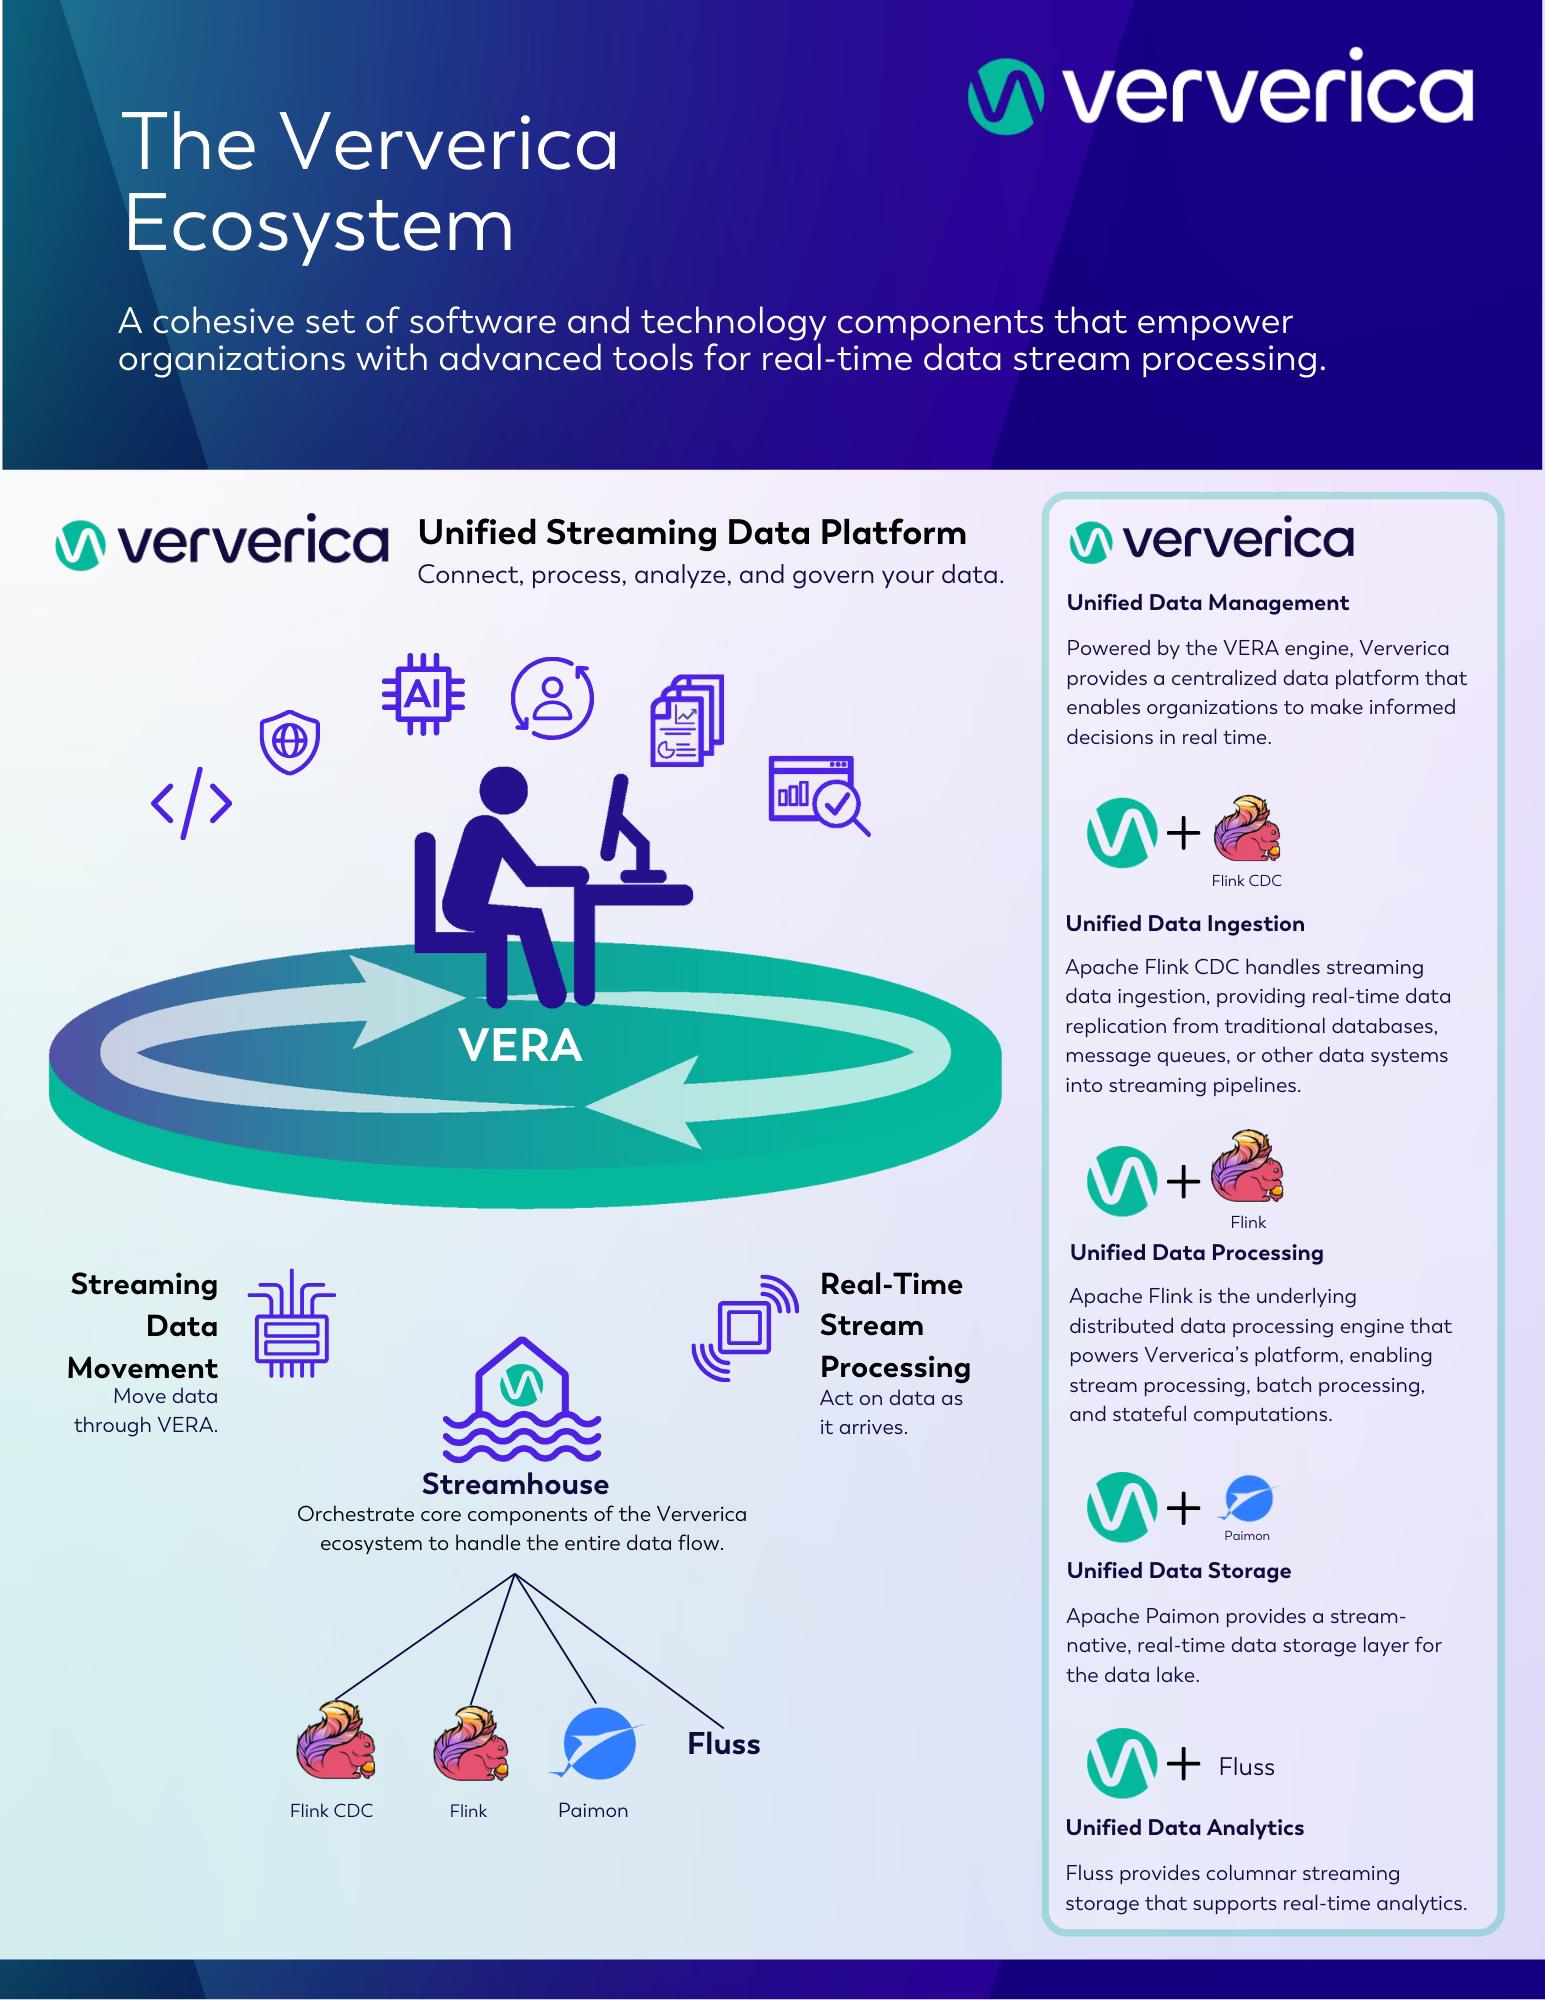
While the solution can handle data at any speed, it is exceptional at real-time data streaming. Instead of waiting for batches of data, the platform processes events as they happen, with minimal latency. It then allows you to apply transformations, aggregates, and other complex logic directly on data streams, effectively creating features in real-time, allowing businesses (like KartShoppe) to make decisions on fresh data and respond to user behavior in milliseconds.
## KartShoppe: Using Ververica for Real-Time Feature Engineering
With powerful stream processing capabilities, Ververica’s Unified Streaming Data Platform empowers KartShoppe’s data team to convert a once-lagging batch process into a dynamic, real-time engine for machine learning. This shift is more than just a technological upgrade, it fundamentally changes how KartShoppe approaches data, enabling immediate event-driven transformations and dramatically reducing the latency between raw input and actionable insights.
### Continuous Transformations
Before adopting Ververica, KartShoppe relied on scheduled batch jobs to generate and refresh features. These jobs often run hourly or even daily, resulting in stale features whenever user behavior changes rapidly. With Ververica, data ingestion becomes a continuous flow. The team no longer waits to accumulate large batches of events, instead, each click, purchase, or page view is processed and actionable the moment it arrives.
In addition, they use Datastream API to allow the engineering team to create streaming applications that perform filtering, mapping, and aggregation on the fly. They also handle out-of-order events, a common scenario in distributed systems where network delays or asynchronous processing cause events to arrive late. By deploying watermarking strategies, the team preserves correct ordering at the logical level, ensuring no data is lost or doubly processed. As soon as a user makes a purchase, metrics such as **"time since last purchase"** and **"number of items viewed in the current session"** update, making KartShoppes models far more adaptive than before.
### Accurate, Time-Based Aggregations
KartShoppe needs to incorporate time-sensitive behavior into both its recommendation and fraud detection features. For instance, a feature like "**"total amount spent by a user in the last hour"** is only useful if it is calculated precisely according to event times. Ververica's event-time processing model, combined with sliding or tumbling windows, offers a way to compute these aggregates with a high degree of accuracy.
In practice, this means the system handles small delays or inconsistencies in how events arrive, as watermarks ensure that windowed computations trigger only when a certain level of timestamp certainty is met. If a user’s payment event trails behind by a few seconds or arrives out of sequence, the platform still updates the feature correctly once the correct watermarks are reached. These consistently accurate time-based features become invaluable for predicting immediate user actions and identifying anomalies that might only appear when examined within specific time intervals.
### Time-Based Joins for Event Correlations
To build richer features, the KartShoppe team needs to correlate events occurring within specific time intervals. For example:
"Time gap between a product view and a purchase": This required joining product view events with subsequent purchase events within a defined window.
Support for **interval joins** makes this straightforward. By defining a time-based join between two streams (e.g., views and purchases), the team can compute features like:
```sql
SELECT
v.userId,
v.productId,
TIMESTAMPDIFF(SECOND, v.eventTime, p.eventTime) AS timeToPurchase
FROM
productViews v
JOIN purchases p ON v.userId = p.userId
AND v.productId = p.productId
AND p.eventTime BETWEEN v.eventTime
AND v.eventTime + INTERVAL '30' MINUTE
```
With interval joins, correlating events from two different streams, like **productViews** and **purchases** also becomes easier. By specifying a time-based condition, the system automatically pairs view events with corresponding purchase events that happen within a fixed interval (30 minutes for example). This allows the calculation of features that capture user intent, urgency, and overall responsiveness to marketing or search placements. In turn, these features drive more nuanced recommendations and higher confidence in identifying future fraudulent or abnormal purchasing behavior.
### Stateful Processing for Complex Features
Not all real-time features can be derived from a single pass aggregation. Some require the system to remember and update data over extended periods. For example, KartShoppe needs rolling averages of purchase amounts and session-level details like total session duration or the number of distinct items viewed in one session.
Using managed state, developers build sophisticated event handlers that retain context between streams of data. The rolling average of purchase amounts (for example) is maintained in a keyed state that keeps track of how many purchases a given user has made and at what amount. Whenever a new purchase event arrives, the solution updates the state and recalculates the average. Because Ververica’s Unified Streaming Data Platform offers built-in fault tolerance and checkpointing via Flink, these stateful computations handle machine restarts or occasional outages without losing critical information. This resilience gives KartShoppe confidence that even under high-traffic scenarios, every feature calculation remains consistent and correct.
### SQL for Simplicity
While DataStream transformations provide flexibility, many real-time features are simpler to express using declarative SQL. Flink SQL, within Ververica, offers a concise way to define windowed aggregations, joins, and filter conditions. By leveraging SQL, data engineers can rapidly prototype new features, freeing them from writing extensive Java or Scala code.
For instance, computing “average session duration” can be solved as a SQL query that joins session-start events with session-end events, and then calculates the time differences before aggregating them. Similarly, “conversion rate per campaign” is just another straightforward SQL grouping scenario. This ease of expression allows the team to accelerate feature development and respond more quickly to changing business needs or new ideas coming from the data science group.
### How This Transformation Changes the AI Pipeline
Bringing all these capabilities together produces a robust, real-time feature engineering pipeline that fundamentally changes KartShoppe’s approach to machine learning:
- **Immediate Adaptation:** With minimal lag between data arrival and feature computation, models instantly reflect changes in user behavior, which results in more timely and relevant recommendations.
- **Higher Model Accuracy:** Features like real-time session metrics and event correlations provides the models with richer, context-aware information, improving the overall predictive performance.
- **Reduced Operational Complexity:** Declarative SQL, paired with built-in fault tolerance, simplifies operational tasks. The team no longer has to orchestrate multiple batch jobs or worry about data being out-of-sync across different systems.
Ultimately, by implementing Ververica’s solution, KartShoppe turns raw events into actionable signals for their ML models at near-instant speeds. The shift to real-time feature engineering lays the groundwork for an agile, data-driven environment, in which new ideas can be tested quickly, and user interactions are captured so rapidly that every click, view, and purchase drives more accurate predictions, with the additional benefits of uptime guarantees, expert help and support, and SLAs.
### The Need For Feature Stores
As KartShoppe’s e-commerce data team continue building real-time feature pipelines, they quickly recognize another challenge: producing up-to-date features alone does not guarantee their models can reliably access those features at both training and serving time. Particularly in environments that include online recommendations and fraud detection, a predictive model is only as good as the data fed into it, and if the model is supplied with outdated or inconsistent feature values, the performance and reliability of predictions suffer.
To solve this, KartShoppe adds a feature store into their architecture. The feature store serves as a centralized system for maintaining, versioning, and distributing features across the organization. By integrating this tool with their Ververica-powered streaming jobs, the team establishes an end-to-end pipeline that ensures features are always fresh, consistent, and readily available for real-time inference.
In this case, Ververica ingests the raw event streams, (including clicks, views, and purchases) directly from databases and message queues. During ingestion, the team applies transformations such as time-based joins, windowed aggregations, and stateful queries to convert raw events into relevant features (for example: **"average purchase amount over the last ten minutes"**). Once calculated, these features are immediately pushed to the feature store, making them accessible to any model that requires real-time data for inference.
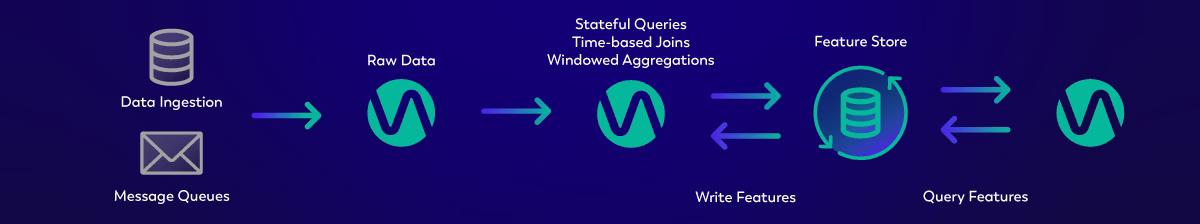
This approach solves multiple challenges at once. First, it eliminates discrepancies between how features are generated for training and how they are served for inference, as both processes pull their data from exactly the same definitions. Second, it removes much of the costly overhead associated with repeatedly re-computing or copying features across different models and environments. And finally, it affords the data team a transparent way to track version histories of each feature, so that experimental changes or schema updates can be carefully managed without disrupting production pipelines.
The outcome is a real-time engine that reacts as user behaviors change. KartShoppe’s recommendation system no longer serves stale suggestions, and their fraud detection engine has immediate visibility into suspicious patterns, while new business initiatives can rapidly incorporate features from the store without duplicating any upstream engineering work. In essence, the feature store becomes the backbone of KartShoppe’s evolving AI ecosystem, delivering reliable, up-to-date feature data wherever it is needed.
### Lessons Learned: Best Practices for Real-Time Feature Engineering
By moving to real-time feature engineering, KartShoppe continues to learn how to keep their systems both efficient and accurate. The first lesson they discover is that data quality can make or break the entire pipeline. Because everything operates in continuous mode, any anomalies or duplicated data can cause immediate downstream issues. As a result, the team adopts thorough validation at ingestion to safeguard data integrity and prevent sudden surges of flawed information.
Another key insight is the necessity of planning for schema evolution. As new product lines or user events emerge, the structure of incoming data changes, which can easily destabilize a streaming pipeline. By implementing a versioning strategy and building resilience into the pipeline, KartShoppe ensures each new data variation integrates without breaking existing feature engineering jobs.
Resource management also is a top priority. Handling large volumes of data in near real-time requires meticulous tuning of parallelism and memory allocation. Thoughtful partitioning strategies prevent data skew, a common issue when certain keys receive disproportionate amounts of traffic. To solve this, KartShoppe monitors workloads continuously and adjusts partitions to spread the load more evenly, using the elasticity and built-in scalability found in Ververica’s Unified Streaming Data Platform.
Finally, reliability proves paramount. Without robust fault-tolerance mechanisms, any unexpected disruption can interrupt data flows and degrade model performance. By using checkpointing and restart strategies, the team avoids lengthy outages and preserves stateful information across transient failures, ensuring that feature computations continue smoothly even in adverse conditions.
## Conclusion: KartShoppe’s Journey
By embracing real-time feature engineering with Ververica, KartShoppe is able to successfully solve two major use cases, with plans to expand: first, their recommendation system is revitalized, and now provides customers with relevant suggestions at the exact moment that need and interest are highest. In addition, their fraud detection engine is able to catch potentially costly anomalies while simultaneously protecting the customer experience. Batch pipelines that once lagged now update features in real-time, ensuring that KartShoppe’s ML models always operate on the freshest, most recent user behavior data.
Behind this transformation, Ververica’s Streaming Data Platform provides robust real-time capabilities, alongside a feature store that safeguards consistency between training and inference models.
To summarize: KartShoppe’s post-transformation workflows demonstrate the potential of real-time AI pipelines to help businesses, including:
- **Boosting engagement** – A constant supply of accurate, context-aware recommendations increases click-through and conversion rates.
- **Enhancing operational efficiency** – Real-time analytics and automated feature engineering reduces manual intervention and data bottlenecks.
- **Providing future-proof scalability** – Adaptive, feedback-driven pipelines ensure the platform evolves in sync with changing user behaviors and market trends.
Real-time decision-making is an increasingly competitive edge in modern environments where milliseconds can help create a positive user experience or result in a lost sale. By combining modern architectural strategies with powerful solutions, organizations of all sizes can accelerate their journey from batch processing to real-time streaming and in doing so, position themselves as leaders in the era of AI-driven innovation.
For KartShoppe, the upgrade to real-time data processing and feature engineering marks a pivotal milestone. This not only improves their internal data efficiency, but also elevates their customers' experiences, ensuring that every recommendation, alert, or offer is relevant and timely and that the business and customers are protected from potentially fraudulent behavior. KartShoppe is a great example of how in the e-commerce industry, few advantages are as powerful as real-time intelligence.
## Learn More
Curious to learn more about how Ververica’s Unified Streaming Data Platform solves other [real-time use cases](https://www.ververica.com/use-case)?
Check out the pages below:
- [Protect from fraud and other anomalies](https://www.ververica.com/use-case/fraud-detection)
- [Build a strong Customer 360 view](https://www.ververica.com/use-case/customer-360)
- [Optimize your pricing with Dynamic Pricing](https://www.ververica.com/use-case/dynamic-pricing)
---
---
title: "Maximize Efficiency: How Ververica's BYOC Deployment Optimizes CAPEX and OPEX"
description: "Learn how Ververica's BYOC deployment leverages CAPEX and OPEX to optimize efficiency while integrating seamlessly with your cloud-native infrastructure."
lastUpdated: 2026-03-17T13:39:30.000Z
source_url:
html: "https://www.ververica.com/blog/maximize-efficiency-how-ververicas-byoc-optimizes-capex-and-opex"
md: "https://www.ververica.com/blog/maximize-efficiency-how-ververicas-byoc-optimizes-capex-and-opex.md"
---
Welcome to the next installment of the Bring Your Own Cloud blog series!
## BYOC Blog Series
The [first blog](https://www.ververica.com/blog/introducing-byoc-deployment) of this series introduced Ververica’s Bring Your Own Cloud Deployment option, offering a high-level overview of why BYOC was created and the benefits users can expect when utilizing this deployment option. The [second blog](https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment) explored “The Dilemma” businesses encounter when trying to find an ideal balance to ensure that a chosen deployment provides the appropriate level of **flexibility**, **efficiency** and **security** required. The third blog (split into [Part One](https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-1) and [Part Two](https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-2)) focused on **security**, dissecting the Zero Trust design choices Ververica made that future proof [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product) BYOC deployment.
This fourth piece tackles **efficiency**, another component of “The Dilemma,” by exploring how Ververica’s BYOC offering helps businesses to optimize Operational Expenditure (OPEX) and reuse Capital Expenditure (CAPEX) when building data streaming and processing projects.
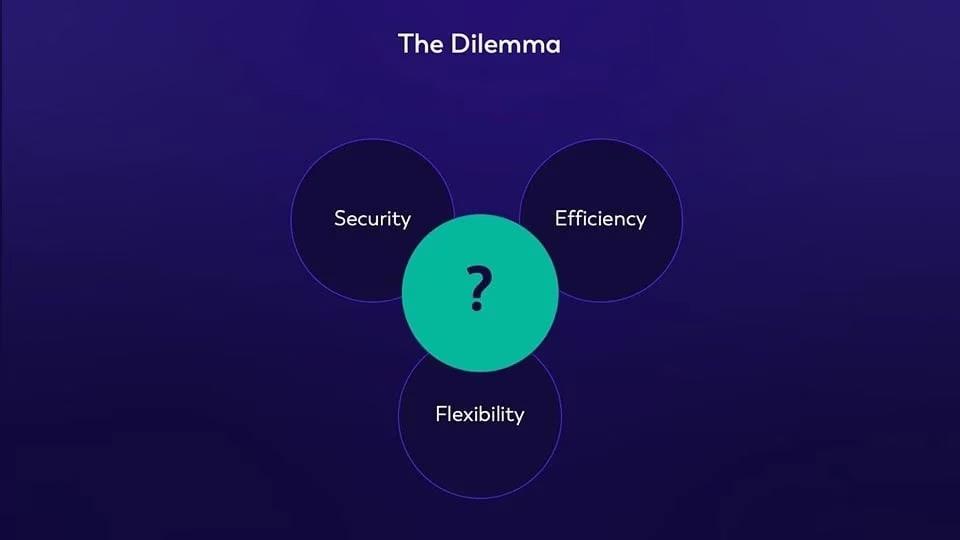
## The Vendor Control Plane and User Data Plane: More Flexibility = Better Efficiency
BYOC operates by clearly separating the vendor-managed control plane from the distributed data plane that resides in the customer’s cloud or region of choice. In this model, Ververica manages only the metadata, while your business retains complete control over your data (see Figure 2).
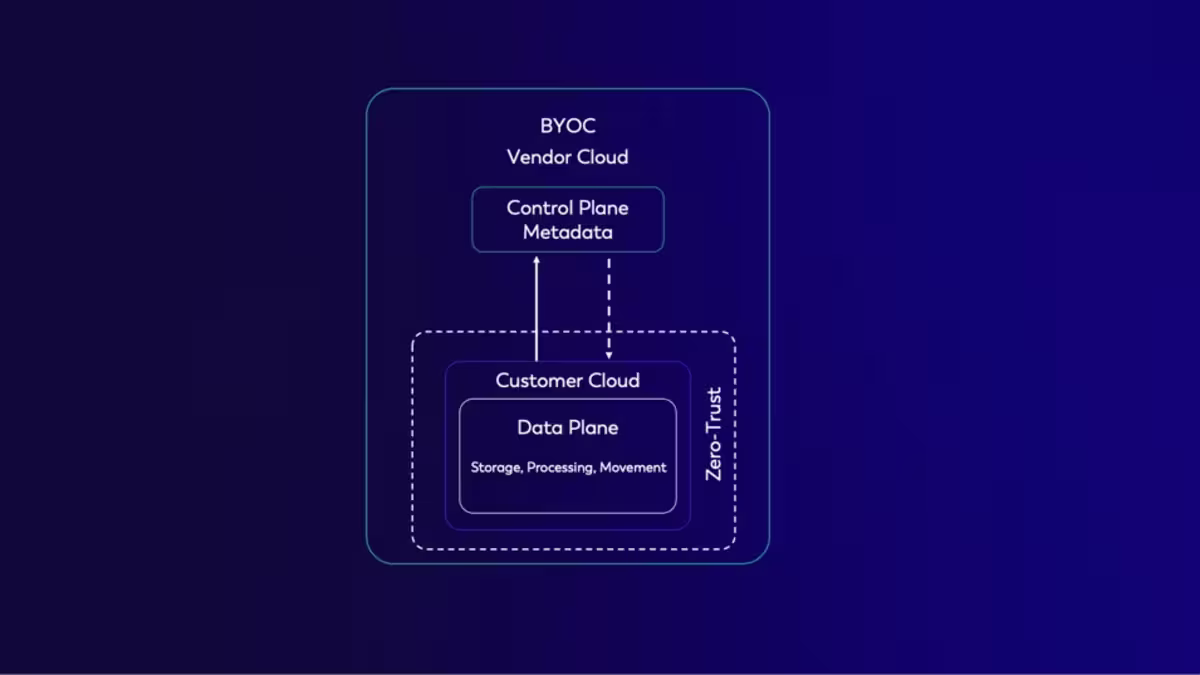
### Leverage Existing CAPEX and OPEX
The beauty of a BYOC deployment lies in its cloud-native design, allowing it to work seamlessly with your existing infrastructure. This means that if you are already using cloud-native tools or resources, BYOC integrates smoothly, preserving prior investments and infrastructure.
In reality, businesses often have existing strategic partnerships with cloud providers (see Figure 3) including annual pricing plans and service commitments. They have likely already built a cloud-native infrastructure to run containerized applications orchestrated by Kubernetes, the de facto portability standard for running cloud-native apps. It’s also probable that specific compute instances, storage types, databases, and other resources are already in place and being utilized.
In many cases, these decisions are shaped by architectural constraints, especially during the lift-and-shift phase of a cloud-native journey, and based on required storage characteristics or the need for larger virtual machines to handle bigger workloads. For fully cloud-native architectures, the focus is often how to optimize OPEX, minimize footprint, increase density, and manage networking costs efficiently.
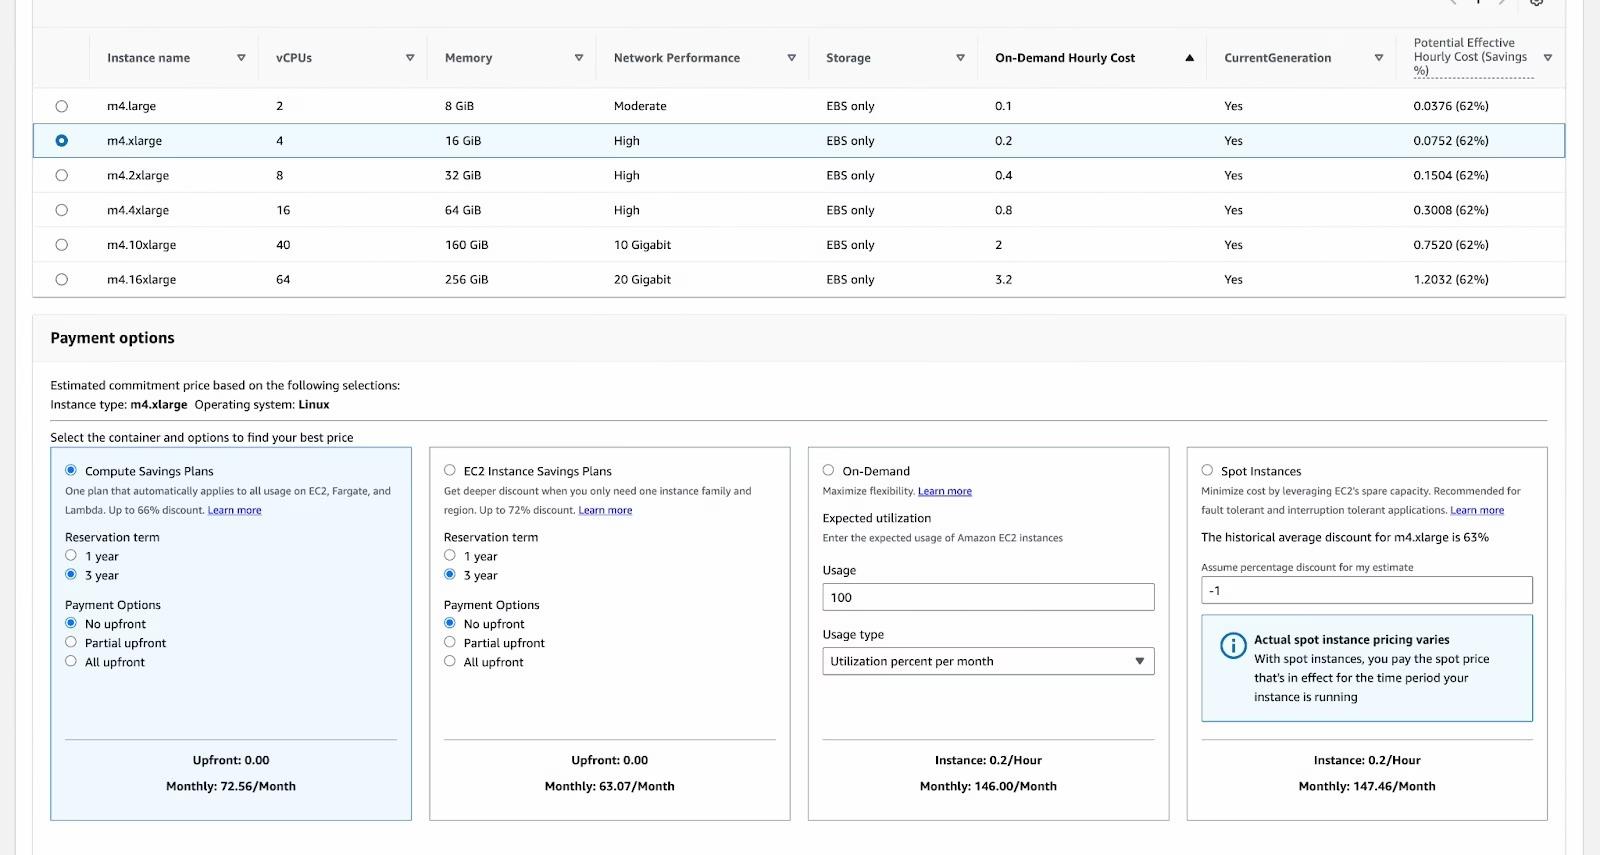
To allow for this flexibility, Ververica’s BYOC data plane software seamlessly integrates and runs in any type of compute, storage, and networking infrastructure underneath a Kubernetes and container runtime cluster.
In addition, you can create or decommission development and testing environments on-demand per team or per task, or share and continuously run them across teams. For on-demand environments, organizations can choose to decommission them during off-peak hours, and in the case of shared environments, workloads can be shut down when not in use to optimize costs. Ververica’s BYOC deployment supports both use cases, where rapid provisioning and de-provisioning of streaming workspaces is common for efficient development and testing.
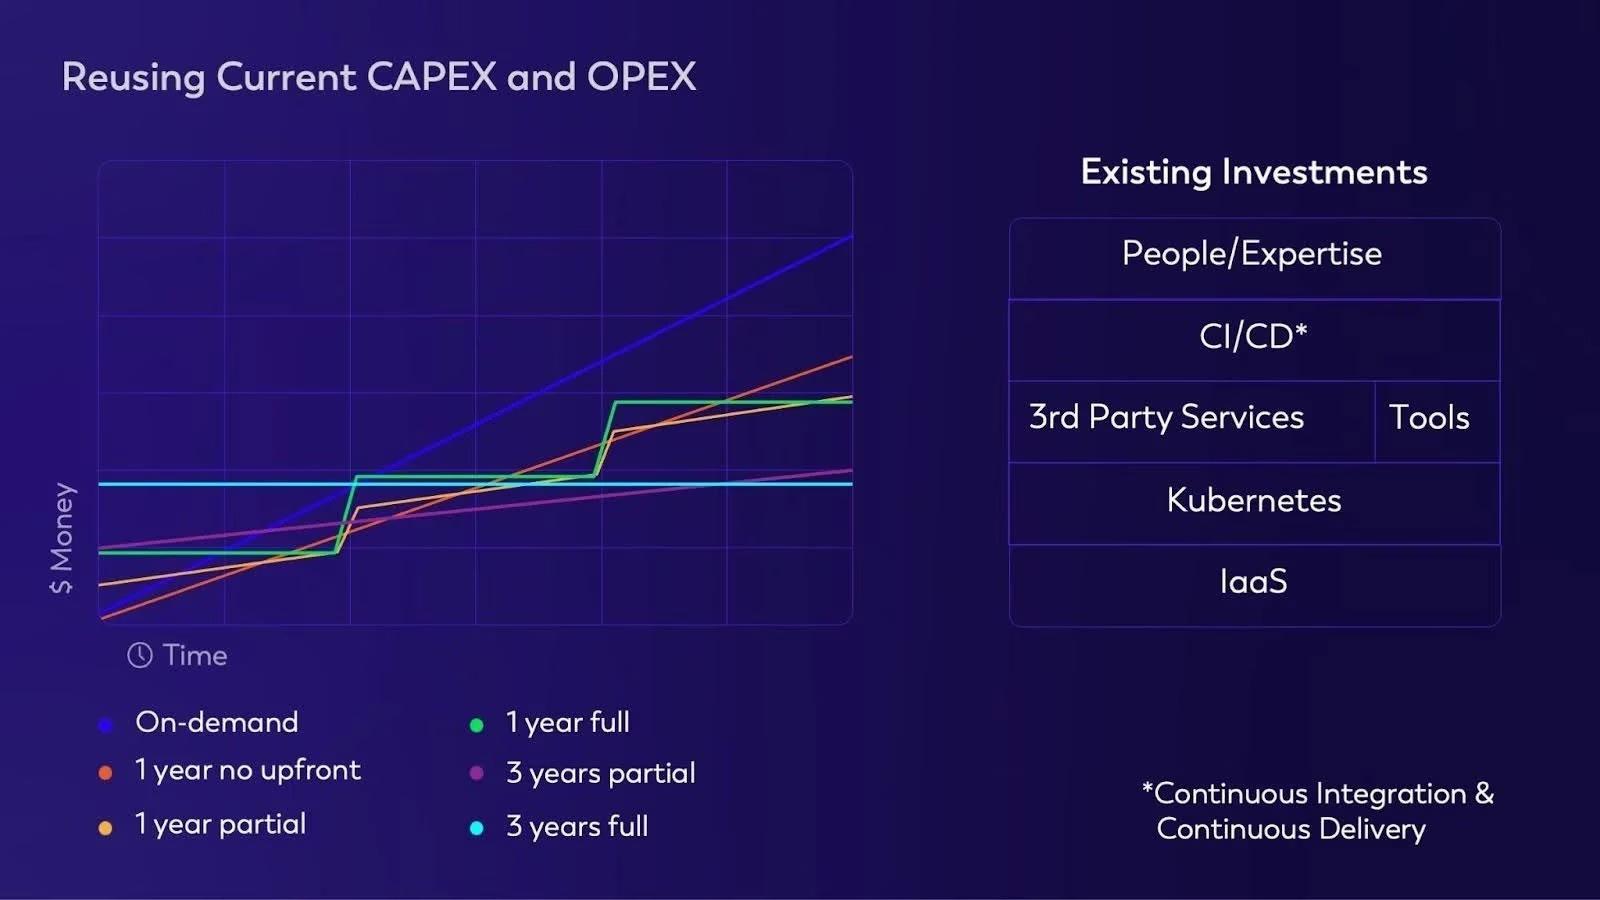
With Ververica’s Unified Streaming Data Platform BYOC deployment option, you can use:
- **Existing Discounts**: Keep any pricing agreements with your current cloud providers, applying them to Ververica’s Managed Service while maintaining in-house data control.
- **Existing Investments**: Reuse existing infrastructure, Kubernetes clusters, third-party services, and other ecosystem tools, avoiding costly new setups or integrations.
### Pay-As-You-Go and Network Bandwidth Costs
You are probably familiar with Pay-as-you-go usage models that provide flexibility and cost efficiency for cloud offerings.
A key advantage of Ververica’s BYOC is its hourly prorated billing and unified payment system, which allows centralized cost tracking and real-time OPEX optimization across all BYOC workspaces. Businesses often overlook the significance of this level of cost control.
One of the biggest OPEX challenges in stream processing is the cost of both public and private cross-account network bandwidth. Ververica eliminates these costs by keeping stream processing and data movement within the customer’s own cloud and network domain, avoiding any cross-cloud account public or private link costs. This not only avoids expensive cross-account traffic fees, but also reduces operational complexity and maintenance costs associated with cross-account network peering and routing.
By running stream processing inside your network, Ververica ensures cost efficiency, performance optimization, and simplified operations. In short with Ververica, you can:
- **Pay-As-You-Go (PAYG)**: BYOC offers a flexible, usage-based model, so you pay only for the resources and services you actually use.
- **Eliminate Network Bandwidth and Operational Costs**: By bringing stream processing close to where the data resides, BYOC minimizes or removes inter-cloud connectivity charges.
### BYOC: Cloud-Native and Lightweight
Kubernetes orchestration with container runtime has become the standard for cloud-native workload portability. Co-locating workloads within existing infrastructure enhances efficiency by reducing overhead and optimizing resource utilization. Ververica’s BYOC deployment follows this principle by ensuring its data plane microservices are lightweight, independent, and resilient. Additionally, you can co-locate multiple BYOC workspaces within the same compute and network infrastructure, enabling multi-tenant efficiency across different business units or teams within an organization. This approach allows Ververica to seamlessly integrate with existing workloads, maximizing Kubernetes cluster investments, and leveraging Kubernetes’ scheduling to achieve high compute density by running multiple workspaces (tenants) within the same compute capacity domain.
As shown in Figure 5, Ververica’s cloud-native data plane microservices can integrate with your existing compute, network, and storage infrastructures, as well as Kubernetes clusters to seamlessly co-locate with other workloads.
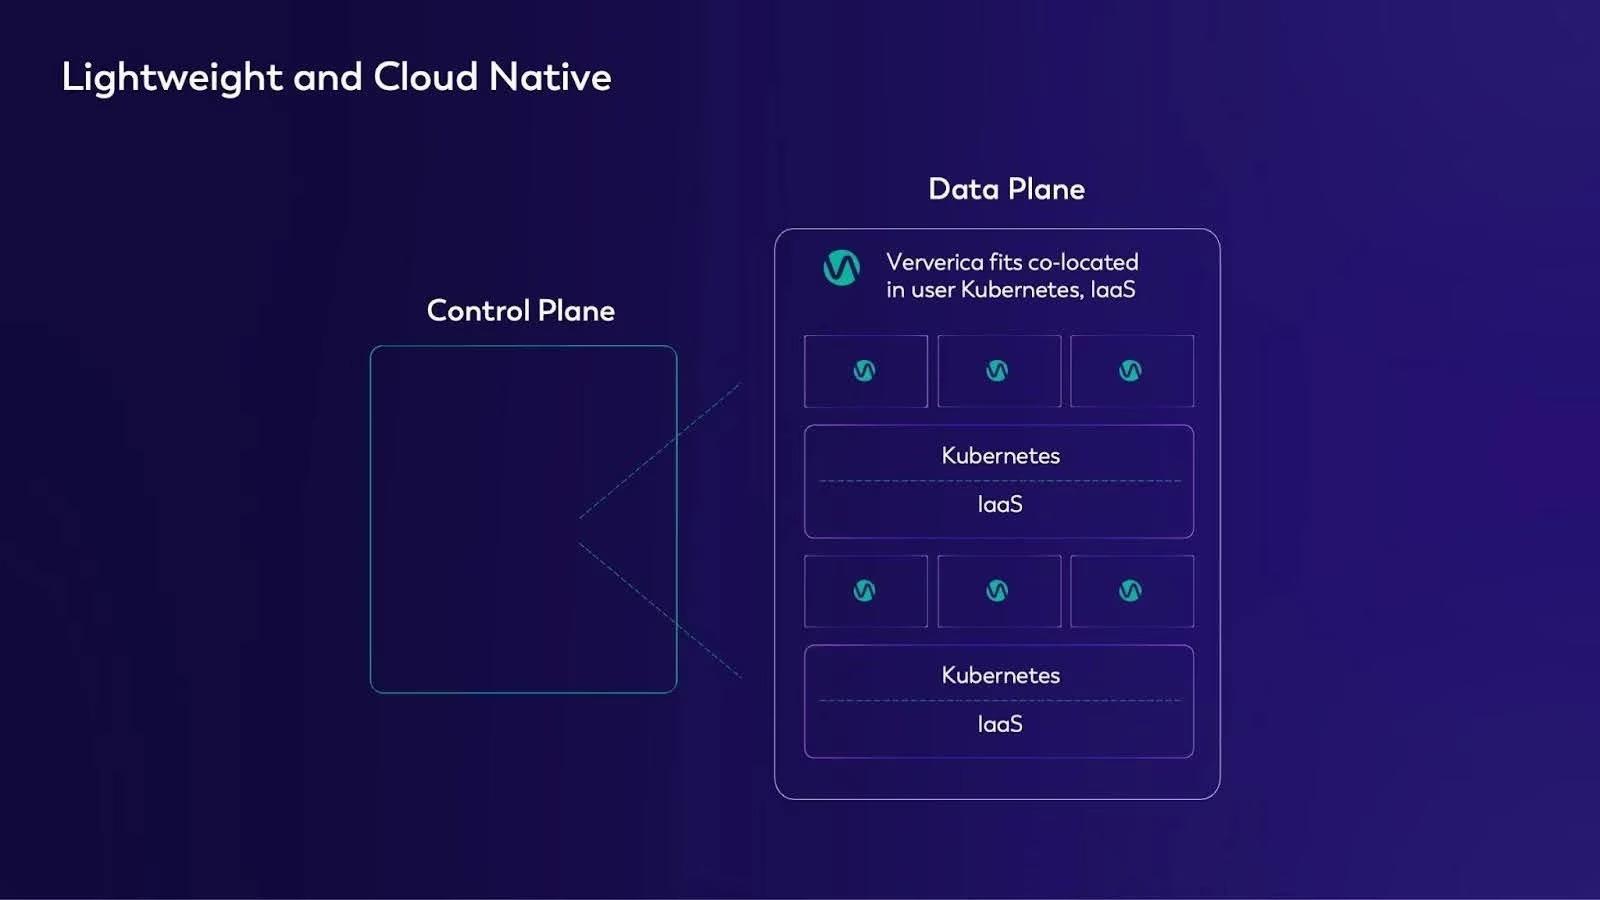
In summary, Ververica’s BYOC offers:
- **Seamless Co-location with Existing Workloads**: BYOC integrates smoothly with current Kubernetes clusters, maximizing existing infrastructure utilizations and investments.
- **Kubernetes-Native Portability**: BYOC works out of the box for organizations managing containers with Kubernetes, ensuring easy deployment and flexibility.
- **Intra-Organizational Multi-Tenancy for Streaming Data:** BYOC Enables co-location of multiple Ververica workspaces within your data plane, allowing different business units to run completely separate streaming environments and data pipelines efficiently.
### Maximizing Efficiency with Ververica's BYOC Deployment
In conclusion, Ververica’s BYOC deployment helps businesses to optimize OPEX and CAPEX when building data streaming and processing projects, providing a more efficient data streaming and processing deployment. This deployment optimizes efficiency at every level, offering advantages including:
- Freedom from Vendor Lock-In: Deploy in any region or cloud provider of your choice.
- Cost Optimization: Reuse existing cloud discounts across any compute instance types.
- Cloud-Native Alignment: Seamlessly integrate with containerized, Kubernetes-based infrastructures.
- Reduced Data Movement Costs: Minimize expensive cross-account and cross-region network traffic.
- High-Density Scheduling: Optimize resource utilization with efficient BYOC data plane microservices.
- Multi-Tenancy for Efficiency: Co-locate pipelines from different business units to maximize compute productivity.
Organizations know their cloud environments and infrastructure best, and Ververica’s Unified Streaming Data Platform BYOC deployment provides a highly flexible solution that allows businesses to pull the most appropriate cost-saving levers based on their unique operational needs.
## Additional Resources
Catch up on the entire BYOC Blog Series:
- [Read Blog One:](https://www.ververica.com/blog/introducing-byoc-deployment) Introducing Ververica's Bring Your Own Cloud (BYOC) Deployment Offering" Blog
- [Read Blog Two](https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment): "Your Cloud: Your Rules Ververica’s Bring Your Own Cloud Deployment: Introducing “The Dilemma"
- [Read Blog Three, Part One:](https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-1) "Zero Trust Strategy with Ververica's Bring Your Own Cloud Deployment, Part One"
- [Read Blog Three, Part Two:](https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-2) "Zero Trust Strategy with Ververica's Bring Your Own Cloud Deployment, Part Two"
- Unlock Ververica's Unified Streaming Data Platform, powered by the VERA engine. Ready to get started? [Contact us.](https://www.ververica.com/contact)
- Want to learn more about Ververica’s Bring Your Own Cloud deployment? [Log into Ververica Academy](https://www.ververica.academy/courses/3d163483-5040-4d60-b5b3-755c3277edf7/activities/75f48f8e-5972-44d6-ba1c-a61a8e9f22c8) to watch Ben Gamble and Igor Kersic onstage at Flink Forward Berlin 2024.
---
---
title: "Zero Trust Security with Ververica's Bring Your Own Cloud Deployment. Part Two: Practical Security Improvements"
description: "Explore Ververica's new BYOC deployment option that ensures a Zero Trust security strategy."
lastUpdated: 2026-03-17T12:44:25.000Z
source_url:
html: "https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-part-two"
md: "https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-part-two.md"
---
Simply put: Ververica’s new Bring Your Own Cloud architecture follows Zero Trust design principles, providing a deployment method that blends security and accessibility for businesses.
## BYOC Blog Series
This blog is the next installment of the BYOC series. The [first blog](https://www.ververica.com/blog/introducing-byoc-deployment) introduced Ververica’s Bring Your Own Cloud Deployment option, offering a high-level overview of why BYOC was created and the benefits users can expect when utilizing this deployment option. The [second blog](https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment), digs more deeply into “The Dilemma” businesses encounter when trying to find an ideal balance to ensure that a chosen deployment provides the appropriate level of flexibility, efficiency and security required.
The third blog focuses on security, and is divided into two parts. [Part One](https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-1) shares the evolution of the connectivity landscape, and the pressures businesses face in a world that is interconnected via the internet with no clear physical boundaries. It also introduces the variations of BYOC in the market and how well they support security measures, including Zero Trust strategies.
Part Two explores exactly how Ververica’s BYOC deployment option helps businesses to address ever-growing issues of connectivity, solution complexity, and the capability to adhere to strict security measures when utilizing [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/blog/ververicas-unified-streaming-data-platform-now-available-on-aws). In addition, Part Two dives into how Ververica ultimately allows data streaming and processing projects as a cloud deployment that aligns and supports Zero Trust strategies. Let’s get started!
## Bring Your Own Cloud, Zero Trust At Core
Simply put: Ververica’s new BYOC architecture follows Zero Trust design principles, providing a deployment method that blends security and accessibility for businesses.
When beginning to build a Zero Trust architecture, there are several essential questions that help guide how to best comply with Zero Trust design, including:
- How do we provide self-service across globally distributed planes?
- Who owns the metadata and where does it live?
- Who owns the data, and where does it live?
- Where does data processing and data movement take place?
In Ververica’s BYOC option, the control plane is centralized and fully managed by the vendor, while the distributed data plane resides within the customer cloud.
The next two questions are related to data governance. With Ververica, vendors in the control plane store and control only metadata, so data never leaves the data plane and is 100% owned by the customer, ensuring security.
All data processing and data movement also happens within the customer cloud, inside the customer cloud account, thus keeping processing and data movement local and entirely under customer control. (As depicted in Figure 8.)

With Ververica’s BYOC, this same pattern repeats: the user has all control and the vendor has no implicit trust. Let's dive a bit deeper.
### Policy Control, Observability, and Sovereignty Principles
The next set of questions to ask when creating a BYOC offering includes:
- Who controls the vendor-customer connectivity policies?
- Who owns and controls data access policies?
- How can all parties gain full observability at all levels?
With Ververica, in order to maintain Zero Trust, policy administration, observability, and all security policies remain under full control of the business. The vendor is then treated as a 3rd party, maintaining compliance with [NIST 800-207](https://csrc.nist.gov/pubs/sp/800/207/final). Figure 9 illustrates the implementation approach for managing policy control, observability, and sovereignty.
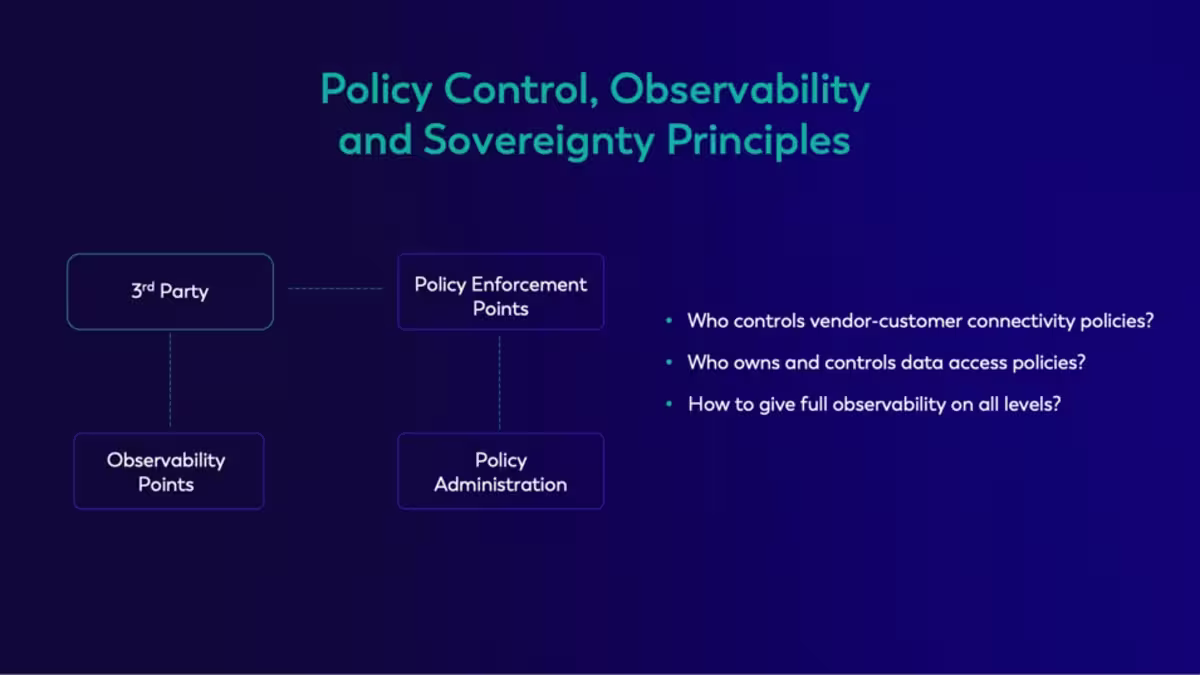
To achieve this, it starts with interface decoupling. In Ververica’s BYOC model, we provide an agent that operates within the customer's cloud. This agent functions as a client, establishing a one-way connection from the customer's cloud to the control plane (server-side). This ensures that customers retain full control over connectivity with the vendor's (Vererica’s) control plane. (Figure 10.)
The agent is designed and packaged to allow seamless integration with the customer’s existing security and observability policies and tools, such as AWS VPC Flow Logs. Additionally, all data processing and movement occurs locally within the customer’s cloud, fully decoupled from third-party control planes. As a result, customers maintain complete control over data storage and access policies, ensuring sovereignty over their data at all times.
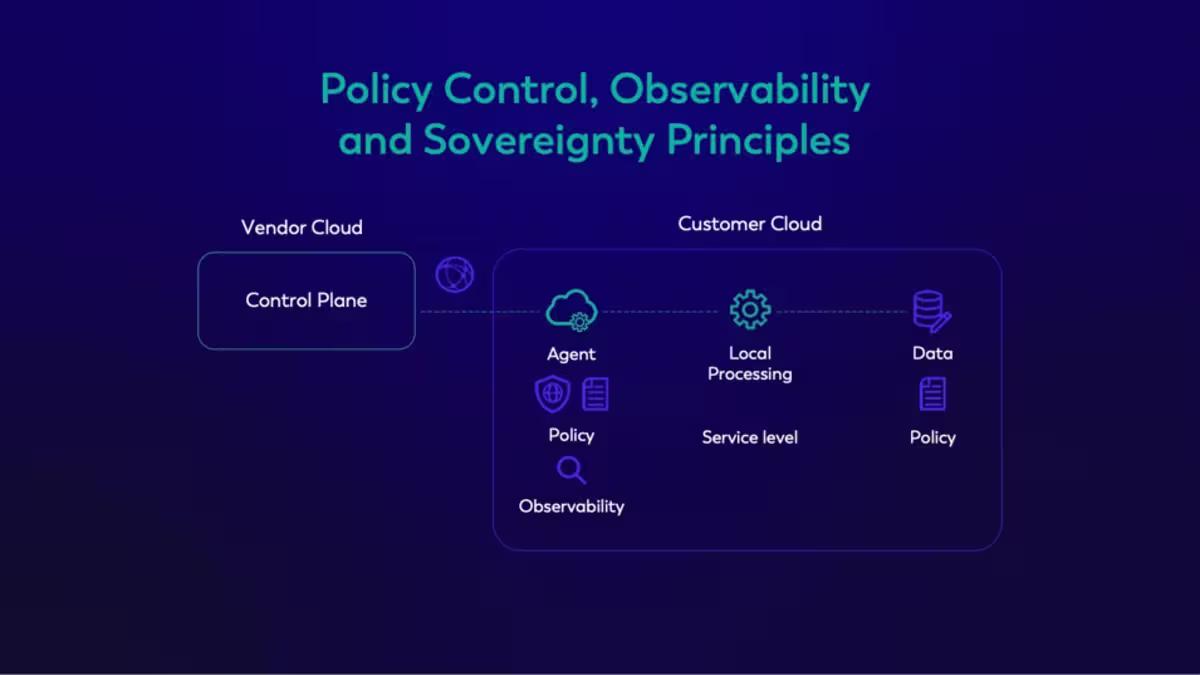
Next, let’s drill down even further in the implementation of the tenant local processing following Zero Trust strategy.
### Least Privileges Principle
One of the most important Zero Trust principles is the principle of least privilege (PoLP), a security concept that dictates that users, applications, systems, or processes should have the minimum access permissions necessary to perform their specific tasks or functions. This minimizes the potential damage that can occur from accidental errors, security breaches, or malicious activities due to restrictive access rights.
Questions to consider here include:
- How much control should vendors control in the customer stack?
- How do you insure least privilege design?
- Who owns observability and other auxiliary systems?
Getting the implementation right at this stage introduces significant design trade-offs. Figure 11 highlights the seriousness of these challenges. Access privileges often start with broad permissions over infrastructure services, resulting in a larger trust surface. For example, if a vendor has control over your networking, compute, or storage services, the attack surface expands substantially. On shared IaaS (Infrastructure-as-a-Service) networking or storage resources, achieving granular service access, such as microsegmented access, is typically not feasible.
Similarly, in CaaS (Container-as-a-Service) environments, granting elevated privileges across entire clusters inherently requires a trust surface encompassing the full scope of those clusters. Since the cloud emphasizes co-location and density optimization, implementing a true Zero Trust model in scenarios requiring elevated IaaS or CaaS privileges is challenging.
Even if access is limited to the service level, a critical question arises: Which services should vendors have access to? The answer should always be the bare minimum required for the vendor’s services to function. Vendor designs must be closely scrutinized by repeatedly asking: _"Does the vendor truly need this access to deliver its core business function?"_
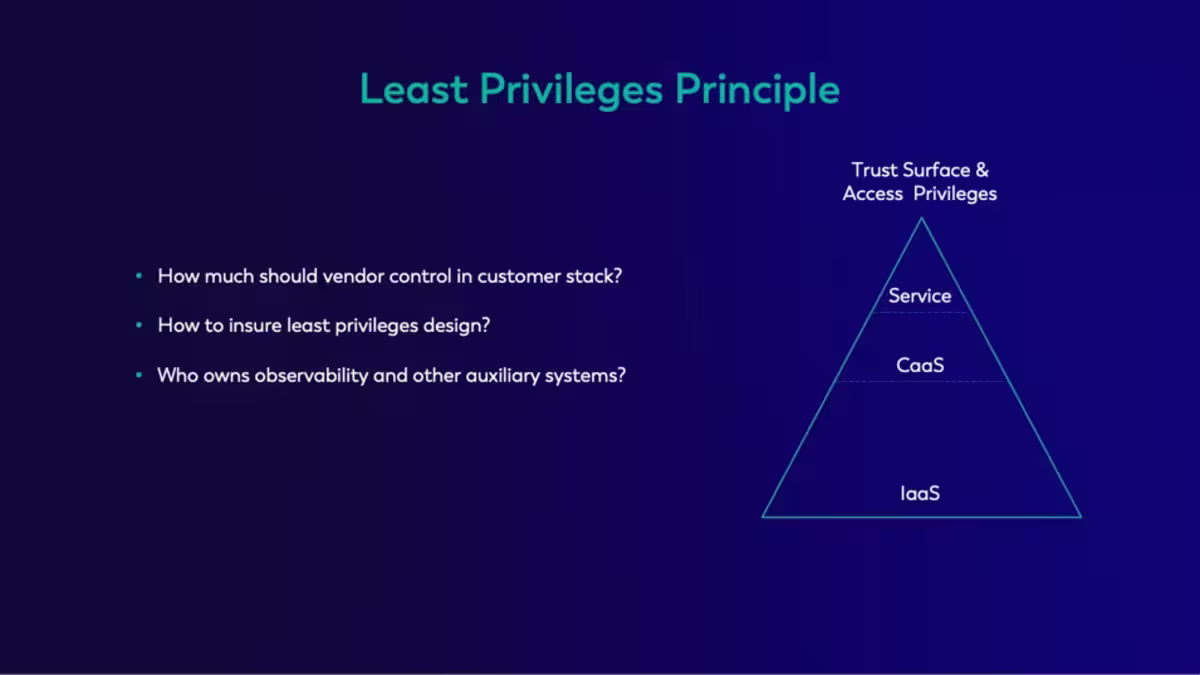
### Implementation of Kubernetes Workloads
With Kubernetes now the de facto industry standard for orchestrating containerized workloads and enabling cloud portability, businesses must make several key implementation decisions early in the implementation process. Here are recommendations:
- **Containerized Microservices**: Package data plane software as microservice containers orchestrated by certified Kubernetes distributions. These containers should adhere to OCI (Open Container Initiative) standards and be compatible with any CNI (Container Network Interface), CSI (Container Storage Interface), or storage class to maximize portability.
- **Integration Flexibility**: Design services to seamlessly integrate with existing policies, observability tools, and monitoring solutions. This approach mirrors the flexibility and freedom of self-managed software while maintaining compatibility within the data plane.
- **Security by Design**: Ensure data plane software operates without elevated privileges, including access to the host operating system or Kubernetes control plan in order to maintain a secure and isolated environment.
By adhering to these principles, businesses can build highly portable, secure, and customer-friendly solutions that align with modern cloud-native practices. Figure 12 shows how Ververica’s data plane software is made of containerized cloud native services that fit existing K8S/IaaS infrastructure, requiring no elevated privileges.
Ververica creates non-privileged Kubernetes namespaces dedicated to each tenant (workspace). Integration to existing customer monitoring solutions is portable and easily achievable, using collecting or scraping of containers standard output (for logs) and prometheus metrics within the Kubernetes cluster. The control plane then communicates only over agents for each tenant.
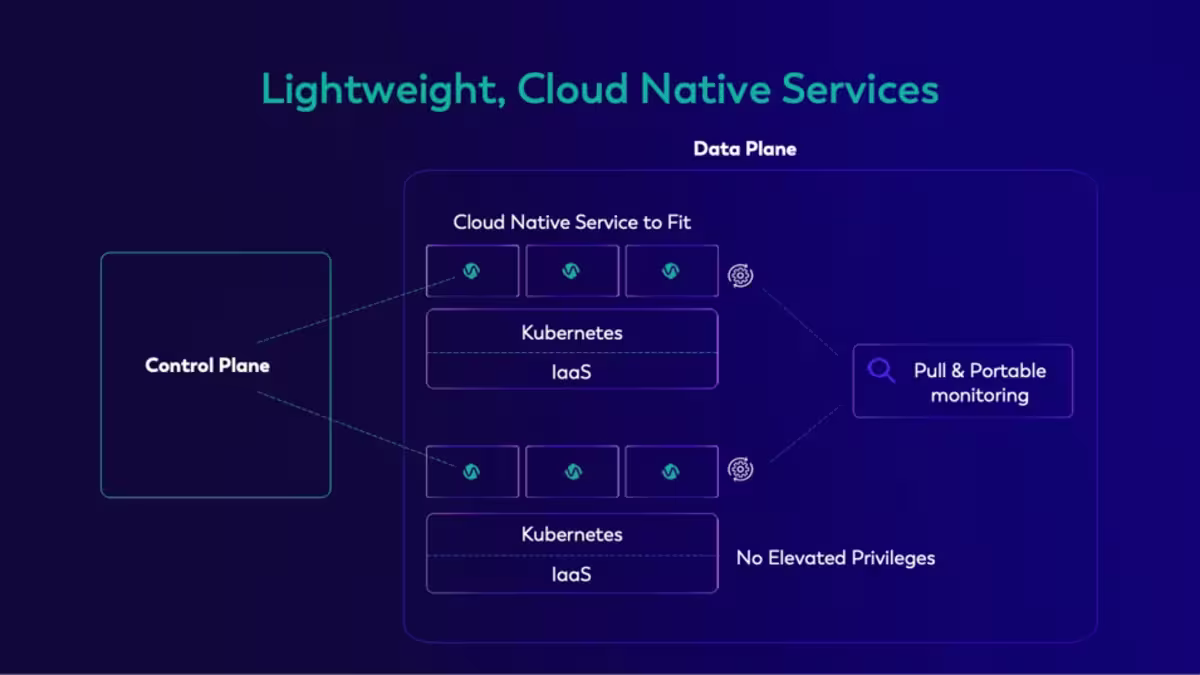
### Isolated, Dynamic, and Granular
Things get more sophisticated as we look at the next series of Zero Trust design questions (Figure 13). This part is critical, because it brings in the toughest choices and it really shows the difference between before and after zero trust architecture.
The last set of questions to consider when building a Zero Trust BYOC offering are :
- How do you ensure security breach isolation?
- Who owns authentication and authorization services?
- How can companies ensure identity security based authentication?
- How to ensure dynamic authorization?
- How to ensure granular access control?
Ververica ensures breach isolation by maintaining complete separation of service chains between tenants. This design guarantees that a breach in one tenant does not impact others. Authentication and authorization services are fully owned and managed by the business or customer, not the vendor, ensuring greater control and security.
Dynamic authorization further enhances security by using ephemeral or rotating access tokens for critical tenant data. This approach significantly mitigates risks, even in the event of a credentials breach.
Granular access control empowers customers with explicit policies, defining precise third-party access URLs and listing allowable API calls for tenant storage. Importantly, these access policies remain under the customer's full control.
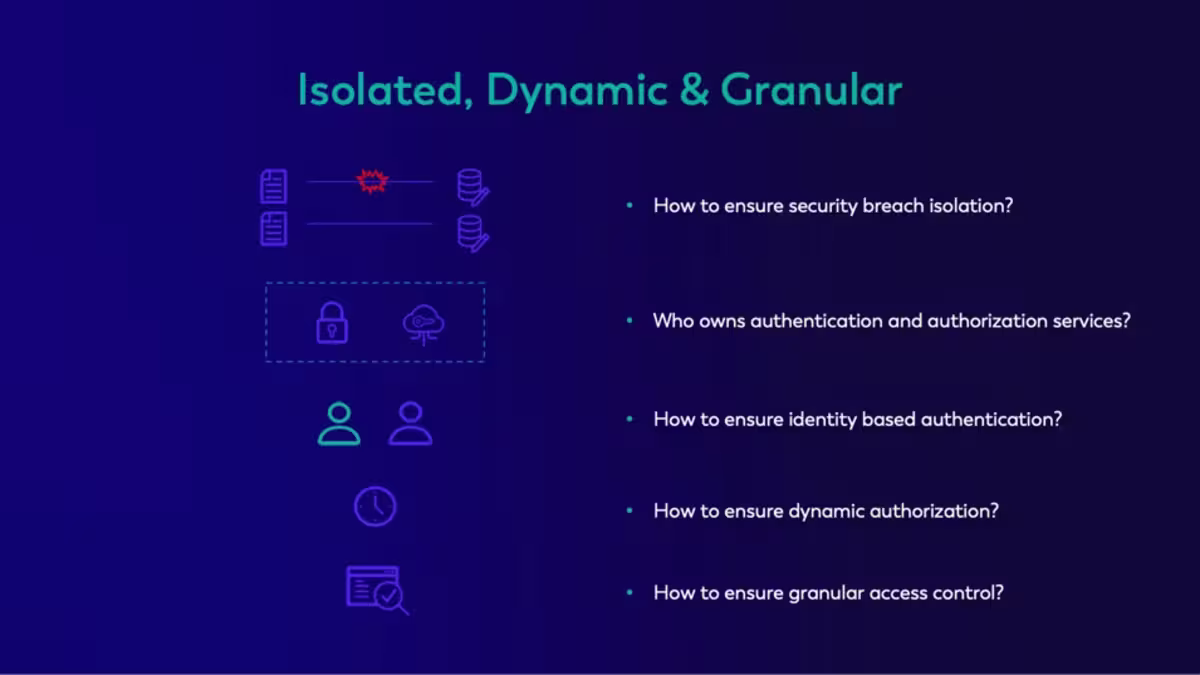
### Secure Implementation with Isolated Service Chains
Implementation begins with isolating service chains to ensure breach isolation (Figure 14). Each Ververica tenant (workspace) is assigned its own dedicated access, managed through Role-Based Access Control (RBAC). This includes a dedicated agent, a specific set of services, and exclusive data storage. A single service chain is designed to serve only one tenant, ensuring complete isolation.
A critical aspect of this implementation is leveraging existing cloud-native customer services for authentication and authorization when accessing customer data. While portability is often prioritized, as discussed in previous chapters, it is not always the best choice for Zero Trust implementations. In this case, data plane software must follow best practices by integrating with specific cloud-native solutions, such as OpenID Connect (OIDC) providers and security token services. This approach allows Ververica’s BYOC deployment to avoid managing these services, their artifacts, or service policies, leaving full control to the customer.
Finally, accessing customer data storage is equally critical. Storage remains entirely under the customer's control and is isolated for each tenant. Customers should define and manage access policies, specifying exactly which resources (e.g., a specific S3 bucket) and which actions (e.g., `GetObject, PutObject`) are permitted. This approach enforces granular access control and upholds the principle of least privilege.
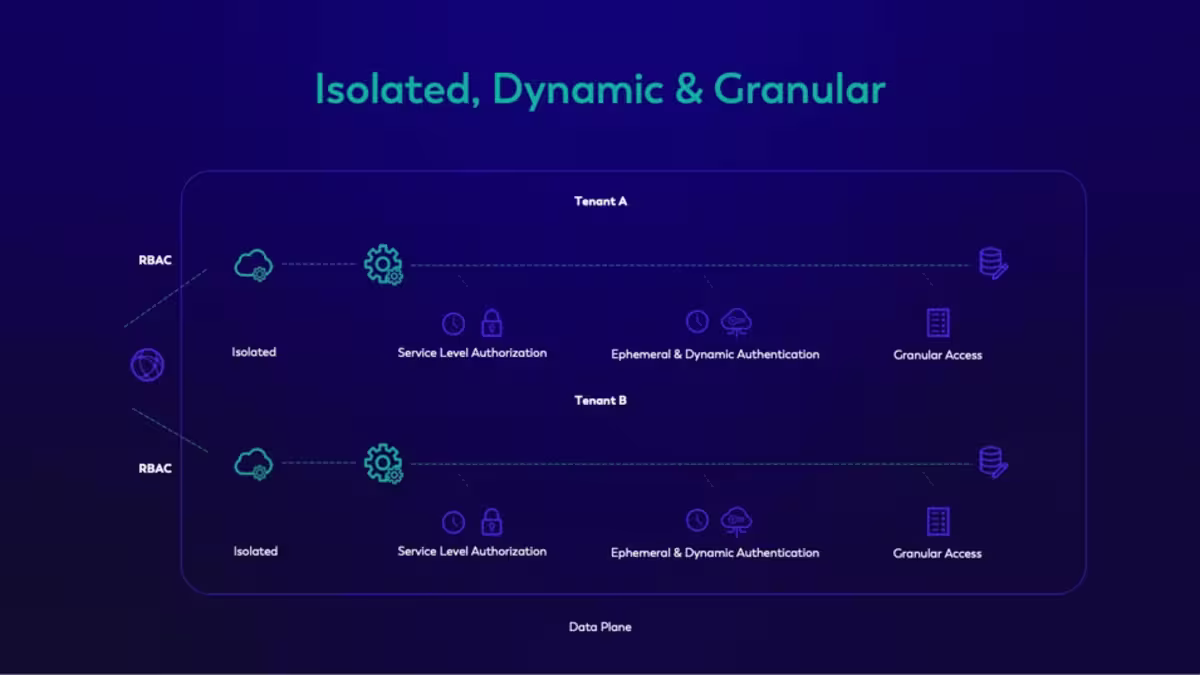
## Conclusion
The Zero Trust paradigm is changing how organizations are building and thinking about security. The importance of assuming a breach has already happened, never providing implicit trust and always requiring verification are key steps to meeting Zero Trust strategies. [Gartner](https://www.gartner.com/en/newsroom/press-releases/2024-04-22-gartner-survey-reveals-63-percent-of-organizations-worldwide-have-implemented-a-zero-trust-strategy) revealed that Zero Trust architecture and solution trends are on the rise, with 63% of organizations already implementing Zero Trust strategies. Ververica takes security seriously and acknowledges this trend, which is why our BYOC deployment option is built specifically to meet Zero Trust specifications.
In conclusion, let’s summarize how the BYOC deployment of Ververica’s Unified Streaming Data Platform meets Zero Trust principles (Figure 15):
1. **Globally Distributed, Centrally Managed** - Ververica’s Unified Streaming Data Platform offers self-service real-time stream processing and Streamhouse capabilities. This supports multi-cloud and hybrid-cloud distributed Flink job pipelines while maintaining strict Zero Trust policies.
1. **Proximity to Customer Data** - By enabling Ververica’s solution to operate near customer data sources and sinks, lateral data movement is reduced. This proximity ensures adherence to low-latency data motion service-level objectives.
1. **Localized Real-Time Processing** - Ververica’s Unified Streaming Data Platform performs Apache Flink® processing within the customer’s cloud ecosystem. This localized approach maintains low-latency data processing goals and avoids unnecessary data transfer.
1. **Integrating VERA into Customer Clouds** - The VERA engine is deployed within the customer’s cloud-native ecosystem, aligning with their existing security and compliance policies. This provides enterprise-grade, cloud-native Flink processing while adhering to the customer’s governance standards.
By following these principles, Ververica is able to provide a secure, high-performance streaming data platform solution that aligns with Zero Trust architecture in a flexible BYOC deployment method, meeting and exceeding the security requirements of a deployment option.
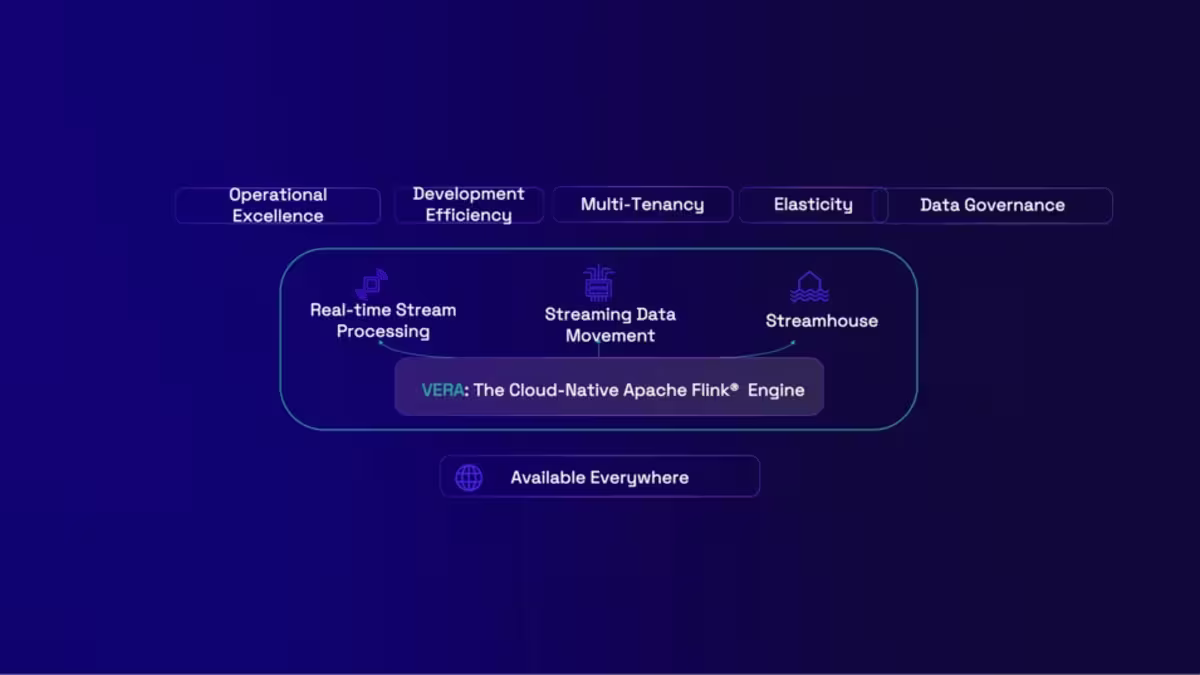
Stay tuned! In the next blog of this series, dive into how Ververica’s BYOC offering increases efficiency, another part of “The Dilemma” business face when choosing a solution and implementation.
## Additional Resources
Catch up on the entire BYOC Blog Series:
- [Read Blog One:](https://www.ververica.com/blog/introducing-byoc-deployment) Introducing Ververica's Bring Your Own Cloud (BYOC) Deployment Offering" Blog
- [Read Blog Two](https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment): "Your Cloud: Your Rules Ververica’s Bring Your Own Cloud Deployment: Introducing “The Dilemma"
- [Read Blog Three, Part One:](https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-1) "Zero Trust Strategy with Ververica's Bring Your Own Cloud Deployment, Part One"
- Ready to get started? [Explore](https://www.ververica.com/deployment/bring-your-own-cloud) the deployment options.
- Not sure which deployment method is best for you? [Contact us.](https://www.ververica.com/contact)
- Want to learn more about Ververica’s Bring Your Own Cloud deployment offering of Ververica’s Unified Streaming Data Platform? [Log into Ververica Academy](https://www.ververica.academy/courses/3d163483-5040-4d60-b5b3-755c3277edf7/activities/75f48f8e-5972-44d6-ba1c-a61a8e9f22c8) to watch Ben Gamble and Igor Kersic onstage at Flink Forward Berlin 2024.
---
---
title: "Zero Trust Security with Ververica's Bring Your Own Cloud Deployment"
description: "Explore Ververica's new BYOC deployment and learn if variations of BYOC in the market support Zero Trust security measures."
lastUpdated: 2026-04-30T11:35:06.000Z
source_url:
html: "https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-part-one"
md: "https://www.ververica.com/blog/zero-trust-security-with-ververicas-bring-your-own-cloud-deployment-part-one.md"
---
In the [first blog](https://www.ververica.com//blog/introducing-byoc-deployment) of this series, we introduced Ververica’s Bring Your Own Cloud Deployment option, offering a high-level overview of why BYOC was created and the benefits users can expect when utilizing this deployment option. The [second blog](https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment) explored “The Dilemma” businesses encounter when trying to find an ideal balance to ensure that a chosen deployment provides the appropriate level of flexibility, efficiency, and security required.
In this third blog, the focus is entirely on security, and is divided into two parts. Part One covers the evolution of the connectivity landscape and the pressures businesses face in a world that is interconnected via the internet with no clear physical boundaries. It also introduces the variations of BYOC in the market and how well they support security measures, including Zero Trust strategies.
Part Two explains exactly how Ververica’s BYOC deployment option helps businesses to address ever-growing issues of connectivity, solution complexity, and the capability to adhere to strict security measures when utilizing [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/blog/ververicas-unified-streaming-data-platform-now-available-on-aws). It also explores how Ververica ultimately allows data streaming and processing projects as a cloud deployment that aligns and supports Zero Trust strategies.

## Change Is On The Horizon...
As cloud adoption accelerates, businesses today are continuously faced with the challenge of balancing flexibility, scalability, and security in their solution deployments. In particular, the cloud deployment landscape is becoming more complex as multi-cloud and hybrid cloud environments continue to evolve, with remote connectivity and interconnectivity over the internet becoming the preferred standard.
### Evolution of the Connectivity Landscape
Until recently, connecting businesses and people was done by simply extending corporate and private network infrastructures. This was an effective solution as network perimeters are relatively easy to guard and defend. As shown in Figure 2, the business network domain, (pictured on the right side) is connected with outside 3rd party IaaS/PaaS/SaaS service providers, (shown on the left) via a corporate firewall. The firewall acts as a security boundary, allowing only those who are authorized to access inside the business network. While this is an effective solution that provides a good balance of accessibility and security, the cloud and business landscape requires greater connectivity, and modern businesses have duties, work, and data that exist outside of clear walls and boundaries, and still needs to be protected.
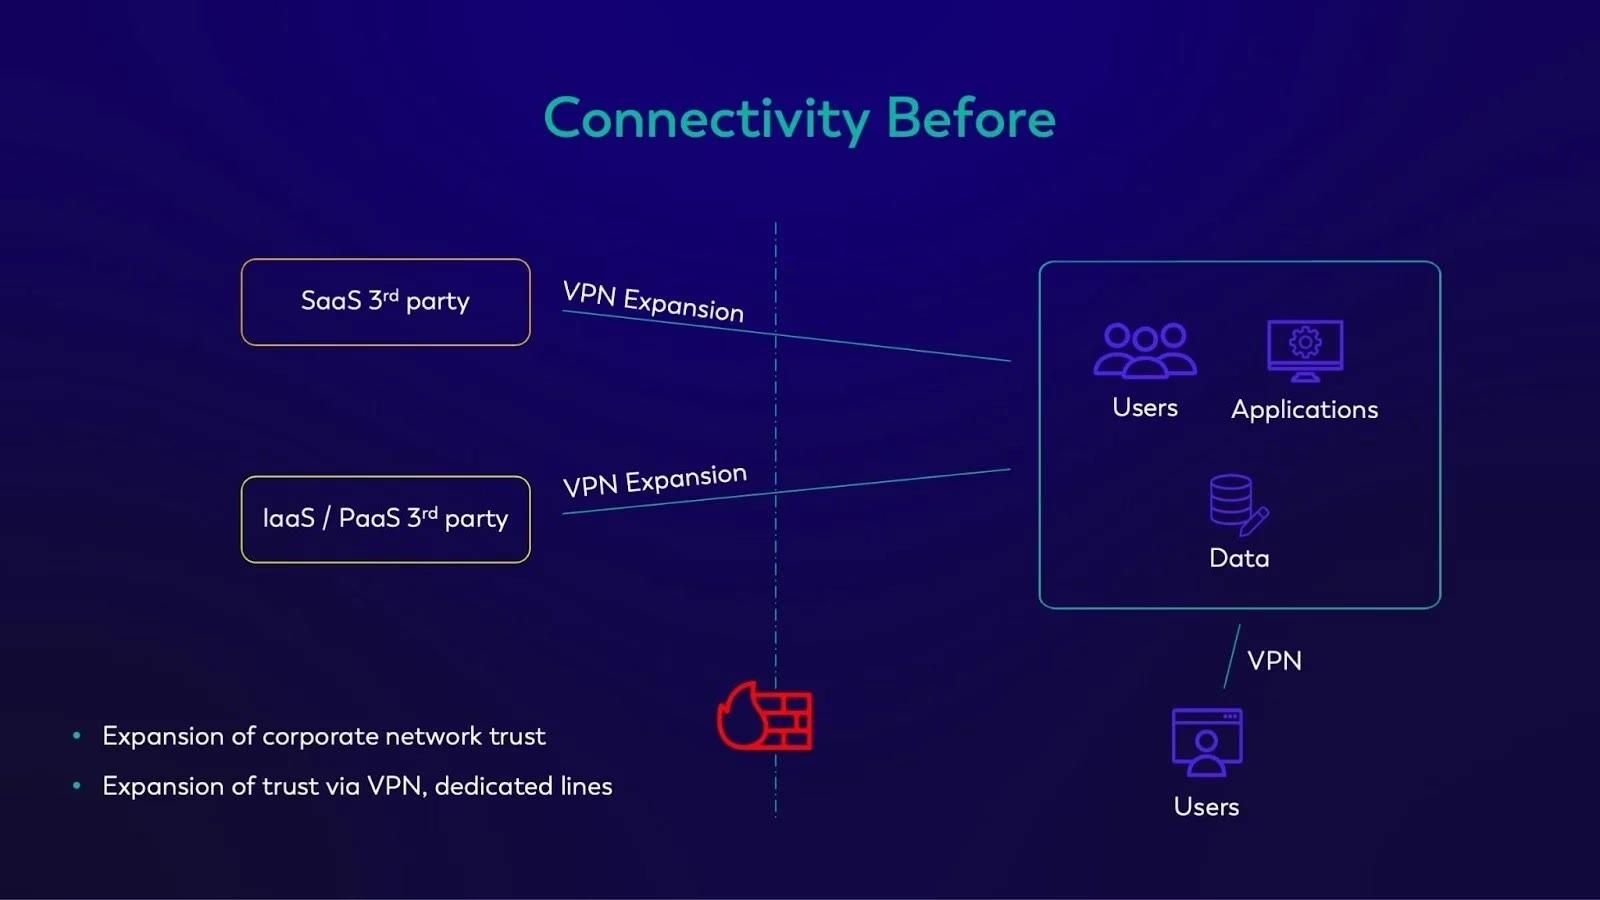
### Global Connectivity Via the Internet Rises
Businesses today require global connectivity that morphs easily, in an ever-growing environment where there are no distinct networks or physical boundaries, and the connection requests may change often. Currently, the world is interconnected via the internet, not extensions of sprawling corporate networks. In this model, businesses (including their users, applications and data) are connected with 3rd party vendors, business critical infrastructure, and corporate users/partners from anywhere. (See Figure 3.)
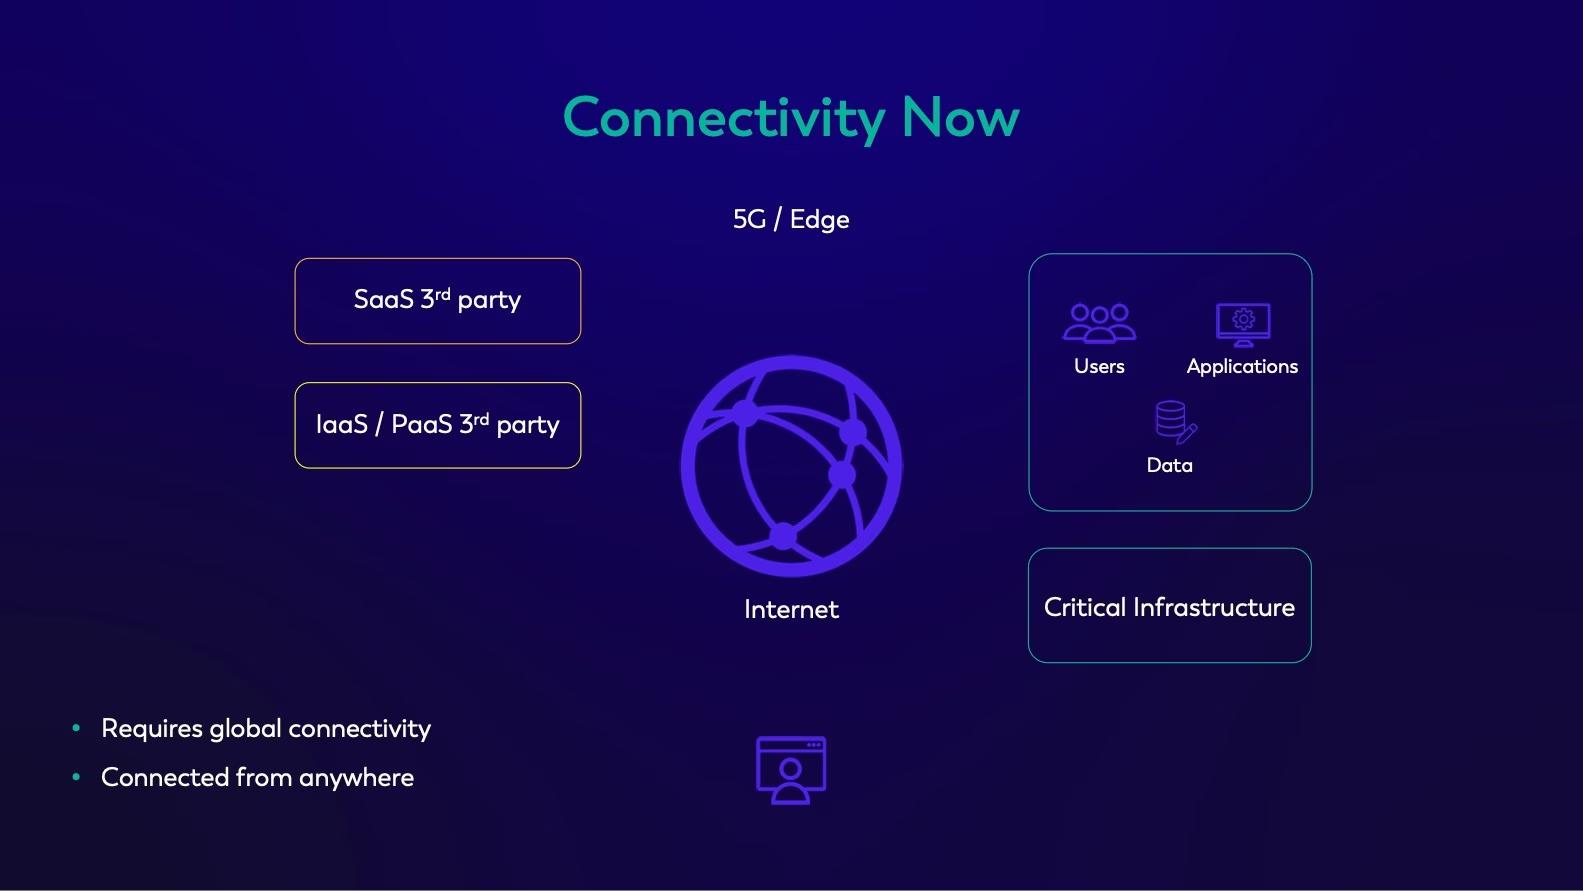
### Driving Changes in Connectivity
There are multiple factors and use cases that drive the connectivity change, including varied cloud adoption rates, remote or hybrid workforces, enhancement in connectivity (5G) technology, and complicated business use cases that demand access and security from anywhere at any time. In addition, different departments of the same business may have different security requirements and different cloud adoption speeds. Also, migration from legacy application architectures toward cloud native architectures is an incremental evolution with long transition periods.
Additional complexities include:
- As the business landscape expands over multiple hyperscale cloud providers, organizations seek more efficiency and escape from vendor lock-in.
- Cloud native transformation rates and adoption are often different across separate business units.
- Work is often spread across different public/private or hybrid clouds within the same organization.
- Application architectures within the same organization often vary from legacy to fully cloud native.
- “Lift and shift” is often the first step, which causes a non-ideal blend of partial cloud and partial on-premise infrastructures that are hard to protect.
As a result, there is no fixed network perimeter for business users, applications, or data. This is incredibly hard to defend, and means that security strategies are complex and difficult to achieve. (See Figure 4.)
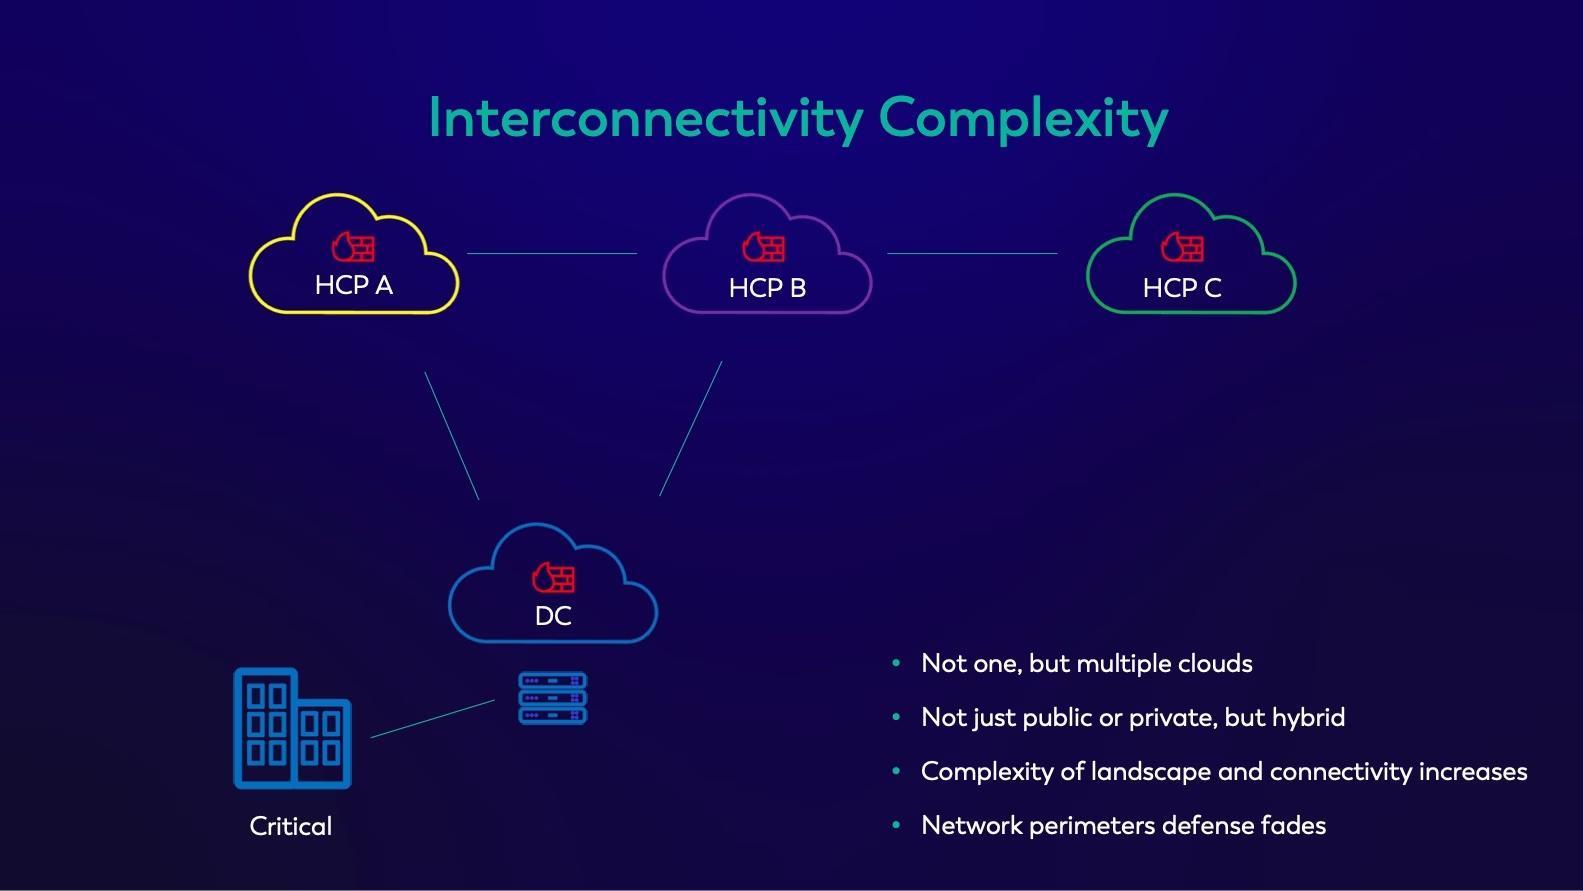
## Shifts in Security
Simultaneously, security breaches are increasing in frequency and sophistication, compelling organizations to prioritize the protection of their most sensitive data and workloads. As connectivity demands and complexity grows, traditional security measures become inadequate. Now, businesses must operate under the assumption that intruders and threats may already be inside, and trust can no longer be implicit.
Figure 5 depicts a security landscape in which multiple credentials and users are breached.
Business domains, (shown on the right side of external access network defense perimeter) are being guarded with network defense best practices. This includes a no-trust zone, often called a “demilitarized zone” (DMZ) which exists between the external network and private network domain. Businesses must assume and be ready to deal with intruders that break trust and breach the private / trusted zone. If not properly handled, such threats can cause wide damage, endangering multiple business tenants.
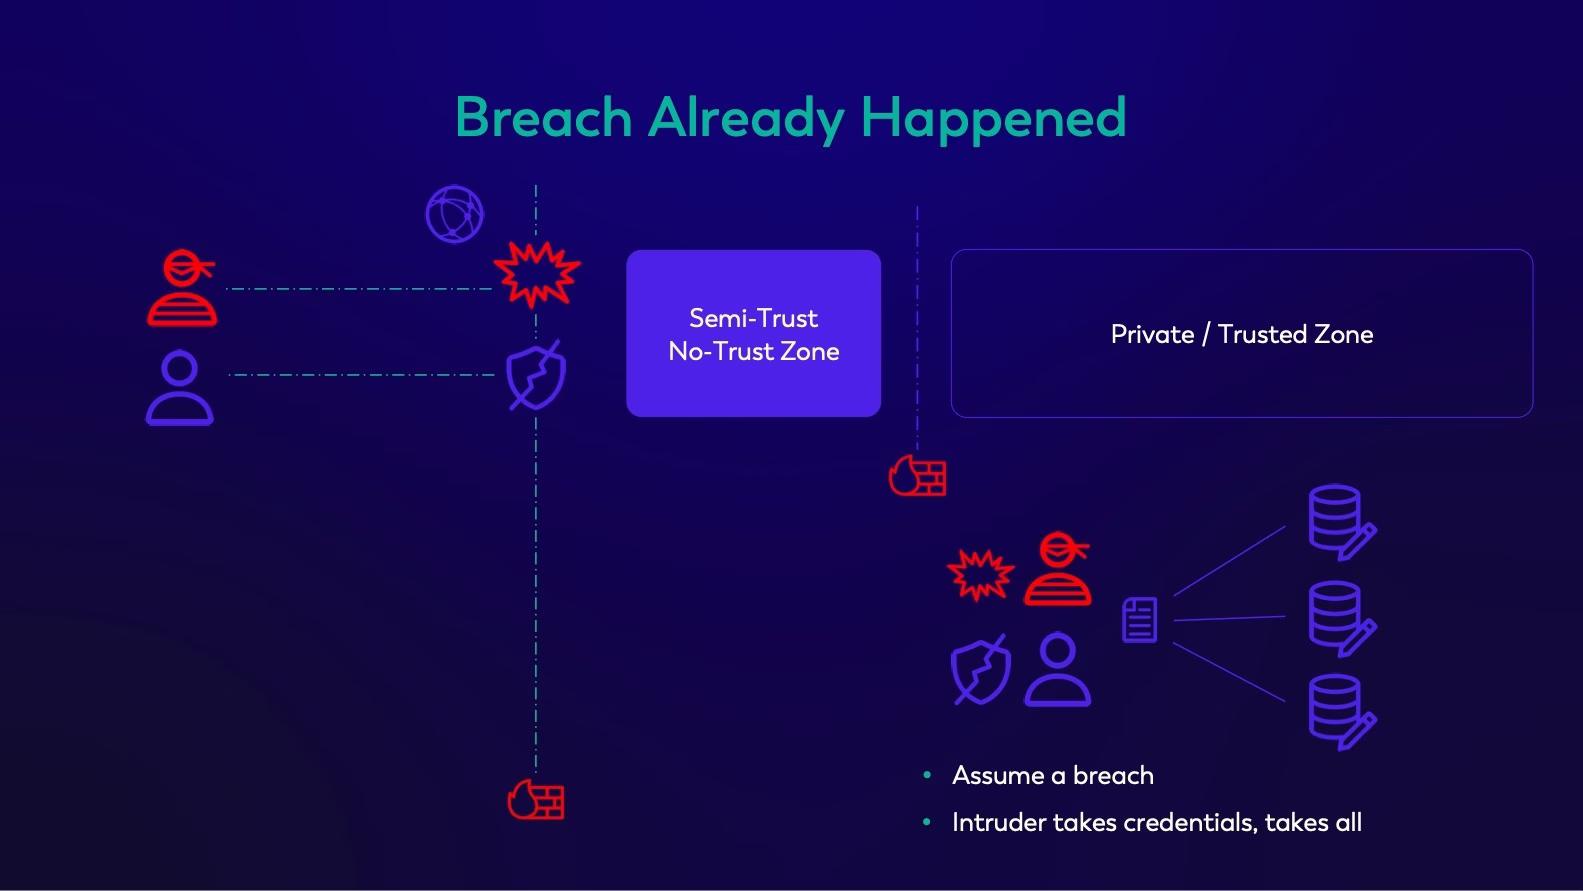
The cybersecurity community acknowledges that traditional network perimeter defenses are no longer effective, prompting the emergence of new strategies and architectures like Zero Trust Architecture ([NIST 800-207](https://csrc.nist.gov/pubs/sp/800/207/final)).
## It's a Road, Not a Destination
Aligning additional cybersecurity and Zero Trust initiatives with existing business technology and transition stages can be complicated. Organizations have often already made substantial investments in their current end-to-end security frameworks, (whether cloud-based or on-premise,) along with various organizational and operational policies. These investments include existing infrastructure, dedicated security and operational teams, and accumulated expertise and team knowledge that would be detrimental to change significantly or too quickly.
One thing is certain: it is essential to build upon these existing assets and evolve strategies that maximize the value of these prior investments, as demonstrated in Figure 6. In most cases, rip and replace is not a viable or cost effective solution, and instead it's important to carefully thread new strategies into existing workflows. Past decisions, tools and investments must be considered when introducing Zero Trust implementation roadmap.
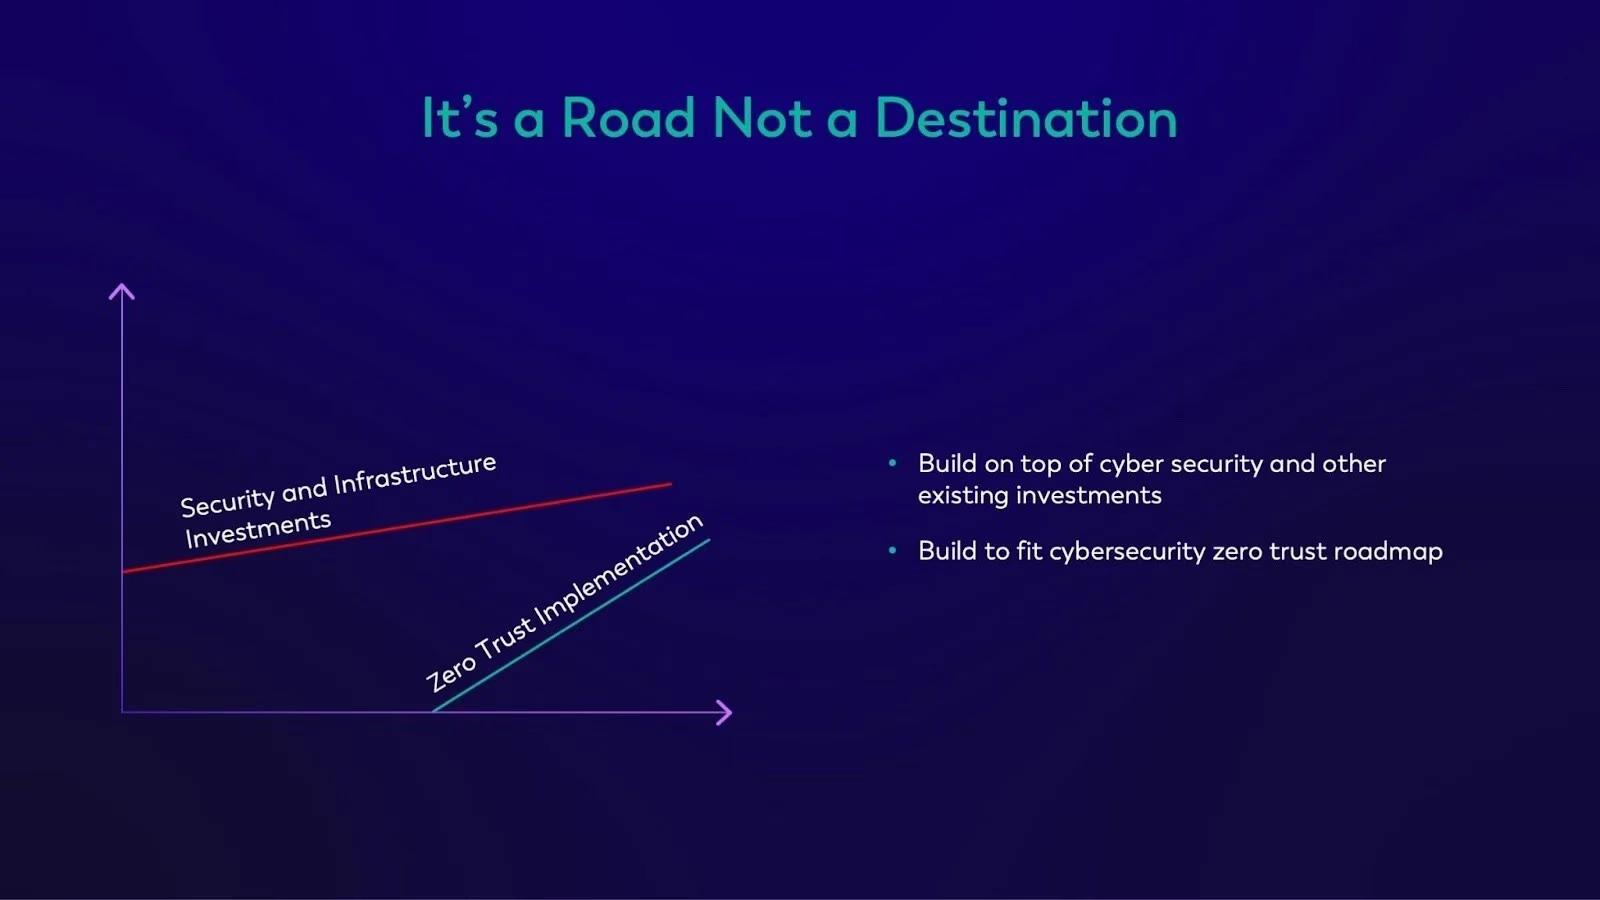
## The Problem with Current Deployment Models
The traditional fully managed cloud service model offers undeniable value, but maintaining control over security policies enforcement, observability, and having operational and data governance has become a significant concern. On the other hand, the traditional self-managed software model is not flexible enough to sustain business needs for leveraging usage based consumption model (PAYG), self-service approach, streamlined delivery and centralized management. In order to stay competitive, businesses must seek the best of different cloud options, including Bring Your Own Cloud deployment models that marry the benefits of fully managed service and self-managed software models.
### Variations of BYOC
Bring Your Own Cloud (BYOC) deployment models have gained traction across many industries, promising to combine the advantages of existing deployment approaches. Typically, these models feature a control plane managed by the vendor in their cloud, while the data plane resides within the customer's cloud.
However, with no established design best practices, different vendors' BYOC solutions vary in terms of design, architecture, and shared responsibility models. In addition, they vary in how effectively they embrace Zero Trust strategies.
Some vendors build BYOC using the traditional network perimeter trust approach, which is reminiscent of traditional managed environments. This model of BYOC suffers from the same risks introduced by network perimeter based defense, as trust is implicit, and therefore exposure to risk is higher.
Other vendors' BYOC variations use a cloud provider cross-accounts approach to manage user services in user trusted zones. This approach introduces several security concerns when viewed through Zero Trust architecture guidelines, including:
- Cloud cross-accounts and policies are usually permanent, thus more prone to breach.
- Vendor management is done by issuing commands from the vendor cloud account toward the user cloud account (sometimes called the ‘push’ model). This strips users of operational and connectivity governance.
- Vendors manage a set of IaaS services (Compute, Network, Storage) in the user cloud, which requires elevated and wide privileges. In this model, trust is implicit and shared responsibilities are very entangled.
Newer BYOC designs try to increase operational governance by using an agent that pulls commands from the vendor cloud account to execute in the user cloud account. However, this may involve the management of substantial parts of the customer’s infrastructure on top of primary vendor services, which requires elevated privileges and roles and exposes large parts of the business to potential breach.
Each of these variations of BYOC try to blend accessibility with security, and demonstrate how difficult finding this appropriate balance can be. The variations of BYOC designs are further illustrated on Figure 7.
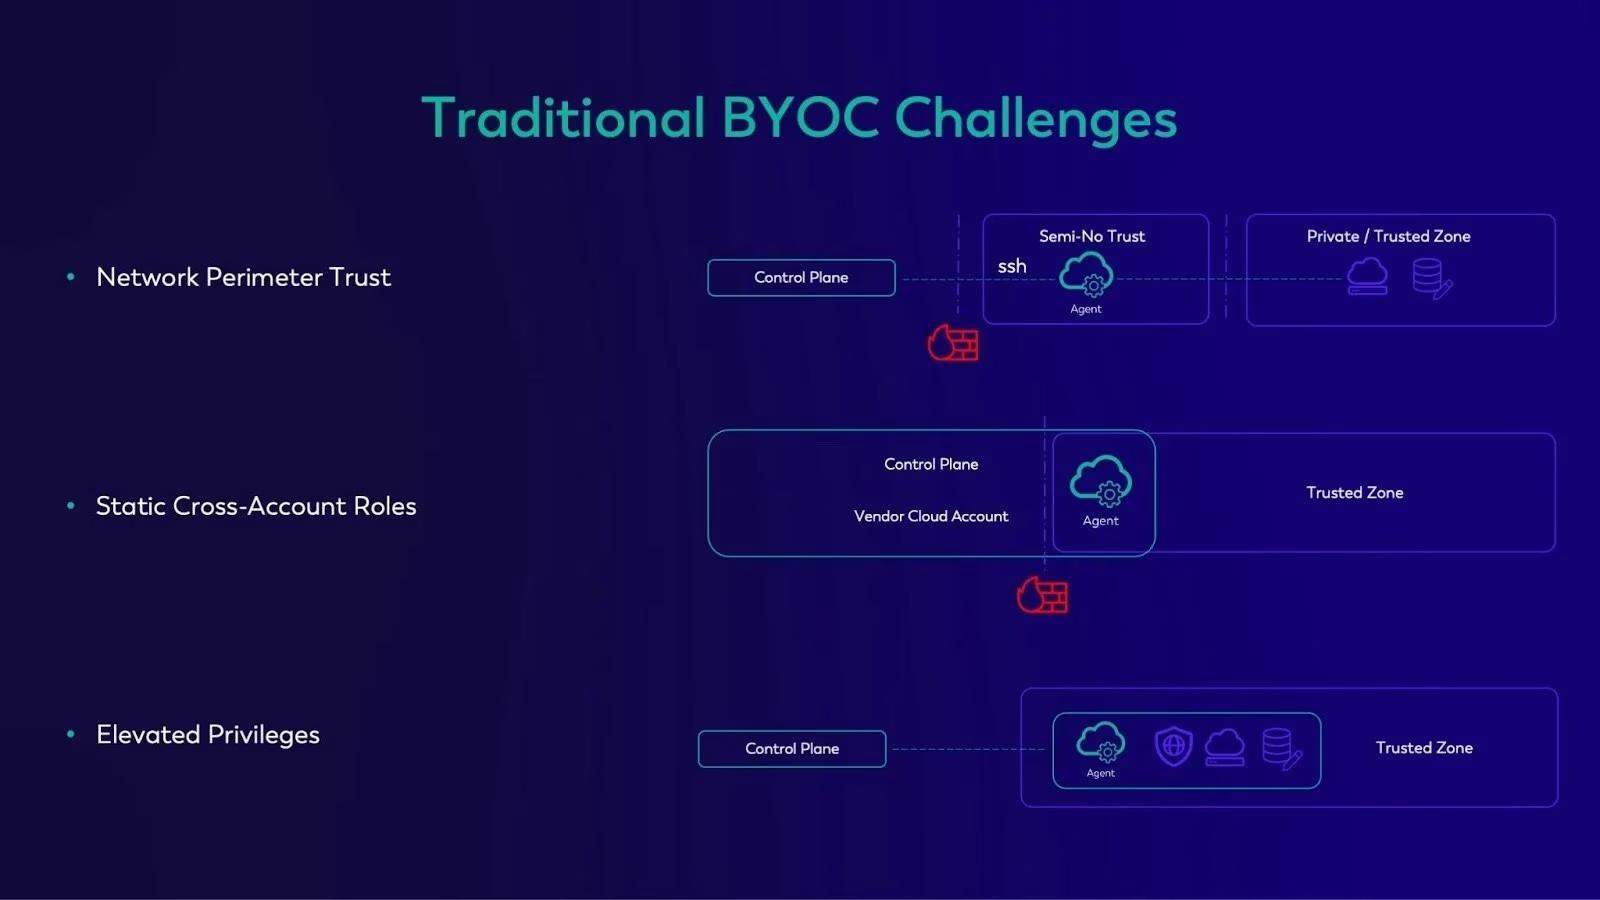
When building Ververica’s BYOC deployment option, we were very mindful of the variations of BYOC available in the market, and purposefully built our option from the ground up to best combine connectivity and security needs. Stay tuned for Part Two, where we explore Ververica's BYOC offering and dive into exactly how Ververica's architecture follows Zero Trust design principles.
## Additional Resources
Catch up on the entire BYOC Blog Series:
- [Read Blog One:](https://www.ververica.com/blog/introducing-byoc-deployment) "Introducing Ververica's Bring Your Own Cloud (BYOC) Deployment Offering" Blog
- [Read Blog Two:](https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment) "Your Cloud: Your Rules Ververica’s Bring Your Own Cloud Deployment: Introducing “The Dilemma"
- Ready to get started? [Explore](https://www.ververica.com/product/deployment/byoc) the deployment options.
- Not sure which deployment method is best for you? [Contact us.](https://www.ververica.com/contact)
- Want to learn more about Ververica’s Bring Your Own Cloud deployment offering of Ververica’s Unified Streaming Data Platform? [Log into Ververica Academy](https://www.ververica.academy/courses/3d163483-5040-4d60-b5b3-755c3277edf7/activities/75f48f8e-5972-44d6-ba1c-a61a8e9f22c8) to watch Ben Gamble and Igor Kersic onstage at Flink Forward Berlin 2024.
---
---
title: "Driving Efficiency: Using Real-Time Data to Optimize the Electric Vehicle Industry"
description: "Optimize EV industry efficiency using real-time data with Ververica's Unified Streaming Data Platform. Enhance charging station operations"
lastUpdated: 2026-03-17T12:37:50.000Z
source_url:
html: "https://www.ververica.com/blog/driving-efficiency-using-real-time-data-to-optimize-the-ev-industry"
md: "https://www.ververica.com/blog/driving-efficiency-using-real-time-data-to-optimize-the-ev-industry.md"
---
As electric vehicles (EVs) grow in popularity, the demand for reliable and efficient charging infrastructure and services also increases. Currently, EV users frequently face issues including long wait times, unavailable charging stations, limited charging options, and other inefficiencies with station operations, all of which impact the adoption and user satisfaction of EVs. In addition, station operators must balance station utilization with real-time vehicle health monitoring to ensure seamless service while maintaining and growing their business.
In this blog, we’ll dive into how leveraging modern data processing technologies like [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product) helps to solve these challenges, optimizing real-time charging station operations, monitoring EV telemetry effectively, and helping to provide a reliable, efficient user experience for EV drivers and station operators alike.
[Video](https://cdn.sanity.io/files/6b38iw1w/production/888e8ff3630ea3def894296a8aa0d8fe3c91f0ea.mp4)
## EV User and Station Operator Challenges
Harvard Business School recently published an [article about the infrastructure state of charging stations](https://www.hbs.edu/bigs/the-state-of-ev-charging-in-america), calling them: “... unreliable and not as easy as topping off a tank of gas.” The research further demonstrates that chargers are, on average, only 78% functional and have “pricing like the ‘Wild West.’” Additional issues they discovered include concerns with:
- Charging cable management
- Charging station compatibility issues
- Slow charging speeds
- Unreliable charging infrastructure
- Safety of charging stations (particularly when charging speeds are slow)
- Connector compatibility problems
- EV charging apps are glitchy or unavailable
- Faulty charging
- Loose connectivity
- Software glitches
- Unpredictable pricing models
- Charging "deserts"
In addition to these findings, EV drivers and station owner/operations experience other common key challenges and pain points, including:
- **Station Availability:** High EV adoption and a lack of available charging facilities leads to station congestion and delays.
- **Operational Inefficiencies:** Simply building charging stations is not enough. They must be staffed, maintained, and run efficiently. Stations may exist but remain unavailable to EV users due to issues like delays or operational downtime. These inefficiencies lead to lost revenue for station operators and frustration among EV users.
- **Supply/Demand Mismatch:** When there are more EV users than stations available to support drivers within a region, it results in congestion at the stations that are available. This imbalance creates delays and inconveniences for drivers, further undermining the user experience.
- **Extended Wait Times:** Unpredictable wait times and delays frustrate users and further impede adoption of electric vehicles.
- **Vehicle Health Monitoring:** EVs have specific, potentially expensive maintenance needs, making real-time data essential for operators to provide timely and safe maintenance.
## Dynamic Solutions For Complicated Problems
Ververica’s Unified Streaming Data Platform is uniquely positioned to help solve each of these challenges [Powered by VERA](https://www.ververica.com/vera), the cloud-native engine that is revolutionizing Apache Flink®, Ververica is 100% compatible with open source Flink, the stream processing framework that excels at processing large columns of real-time data with low latency. In addition, Ververica leverages [Fluss, the streaming storage system](https://www.ververica.com/blog/introducing-fluss) designed for real-time analytics, to deliver incredibly efficient data storage and retrieval capabilities. This combination enables Ververica to offer seamless data ingestion, analysis, and updates that can solve problems like those listed above. In the next section, let’s dive more deeply into the technology that tackles these specific challenges.
### Real-Time Data Ingestion
Ingesting data in real-time allows for continuous collection of telemetry data and empowers instant decision-making and actionable insights. For example, EV metrics like battery level, charging needs, and vehicle location can be matched to station metrics including station availability, operational status, current wait time and load. The driver can decide, based on this data, where and when to stop and charge. The ability to pull data from multiple sources and then process that in real-time provides a better user experience, matching needs with available resources immediately.
Ververica provides the ability to process data dynamically, matching EVs with the most suitable charging stations. With intelligent data analysis, drivers can expect information like proximity of the nearest available stations, the availability and confirmation of open charging points, and load balancing which ensures that vehicles are distributed in order to avoid station overcrowding and long wait times. Matching in real-time both minimizes user wait time and optimizes the resources available in a given region.
### Efficient Storage and Updates with Fluss
[Fluss](https://www.ververica.com/blog/introducing-fluss) is open source software that is incorporated into Ververica’s solution and ensures low-latency updates and smooth integration with data Lakehouse architectures. This powerful technology allows for real-time updates, providing immediate visibility into changes that happen with station availability and wait queues. By simplifying streaming workloads with efficient updates via changelogs, Fluss directly consumes these updates by stream processing in real time. Its seamless Lakehouse integration, combined with real-time analytics and historical data insights to equip station operators with an up-to-date view of the changing network at all times, empowering prompt decisions and efficient and effective infrastructure management. In turn, drivers have a better experience and EV adoption continues to grow.
## Outcomes That Transform Experiences
When users and businesses are armed with a solution that provides insight into the entire charging network, facilitating real-time, data-driven decision-making, numerous positive outcomes emerge. These include:
- Efficient resource allocation based on the number of users accessing available stations.
- Reduced wait times and faster charging assignments.
- Improved station utilization that optimizes the use of charging stations across the network by recommending stations based on balanced load and workflows.
- Enhanced user experience and proactive planning, with real-time notifications and charging options that allow users to know what to expect before arriving at a station.
- Predictable maintenance needs through telemetry trends that anticipate and address issues before they become emergencies.
## What Other Challenges Can We Solve?
This integrated real-time data solution opens the door to a wide range of potential benefits. Combining data from a nearly infinite number of sources allows for some really interesting questions to be addressed. For example, analyzing historical maintenance reports for individual EVs or car models can help identify issues before they break down or cause downtime.
Aligning charging operations with data on renewable energy source availability not only supports sustainability strategies, but also maximizes the cost efficiency of owning an EV. Operators could also engage in dynamic pricing, incentivizing off-peak usage to improve grid stability. It could be helpful for both users and beneficial for business to allow users to schedule charging, providing them a guaranteed available slot, and allow trip planning that eliminates range anxiety all together. Or, station operators offer additional loyalty or membership programs along with text notifications as users drive close to their location.
The possibilities of using real-time data for vehicles extends far beyond EVs also. Imagine using real-time data to find the cheapest gas reliably, or the highest-rated, fastest service provider in a region. Ultimately, the power of real-time data at scale has profound implications that transform everyday life and businesses in ways we are just beginning to explore.
## Conclusion: Building a Smart and Sustainable EV Ecosystem
In conclusion, leveraging Ververica’s Unified Streaming Data Platform provides a robust framework to solve known challenges with EV charging stations and operations, unlocking data-driven optimizations in real time. This solution in turn provides a reliable, efficient user experience, paving the way for a more efficient and user-friendly ecosystem. As a result, users and station operators alike can build and benefit from a highly scalable, sustainable, and user-centric EV ecosystem and stronger infrastructure.
### Get Started
- Learn more about how Ververica solves other [real-time use cases](https://www.ververica.com/use-case)
- [Watch](https://youtu.be/RTi2jsen8Wo) the 10-minute video "Driving Efficiency: Using Real-Time Data to Optimize The Electric Vehicle Industry"
- Learn more about [Fluss](https://www.ververica.com/blog/introducing-fluss)
---
---
title: "Your Cloud, Your Rules: Ververica's Bring Your Own Cloud Deployment"
description: "Explore Ververica's new BYOC deployment option that balances flexibility, efficiency, and security for optimal cloud management and data control."
lastUpdated: 2026-03-17T12:42:54.000Z
source_url:
html: "https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment"
md: "https://www.ververica.com/blog/your-cloud-your-rules-ververicas-bring-your-own-cloud-deployment.md"
---
As the cloud and business landscape grows more complex and interconnected, businesses are continuously searching for solutions that offer the right mix of flexibility, efficiency, and security. Today, however, companies often face a limited choice between either self-managed software or fully-managed service, and each option poses their own specific security and management challenges.
Over time, the list of business and deployment pressures have only increased, as illustrated in Figure 1:
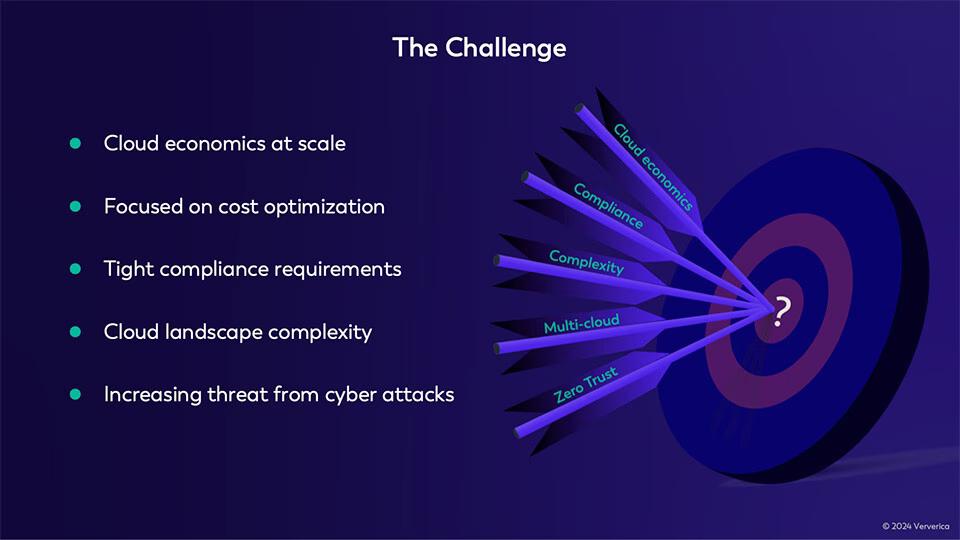
Initially, organizations adopted cloud deployments to benefit from their elasticity, ease of self-service, and cost-effective scalability, in addition to reducing their CAPEX (capital expenditures). However, as cloud adoption grew, OPEX (operational expenditures) became a concern, leading to cost-optimization strategies like annual commitments or selecting lower-cost regions.
The ever-changing landscape of compliance and regulatory requirements adds further complexity to cloud deployments, requiring companies to ensure data locality in addition to considering other governance measures. Cloud offerings and architectures are becoming increasingly more diverse, with organizations adopting multi-cloud and hybrid-cloud models. However, the rate of adoption differs across departments within the same organization, with each business unit moving at its own pace based on specific needs and resources. Finally, the rise of sophisticated cyber threats in recent years heightens the need for enhanced security measures within the cloud ecosystem.
Finding the ideal balance can be challenging with any deployment option, as it must deliver the right level of flexibility, efficiency, and security to address the specific needs of the business solution. We’ll refer to finding the balance of these three elements as “The Dilemma”.
## The Dilemma
When choosing to implement a solution, businesses are met with the dilemma of how to choose a deployment that best balances the needs of:
- **Flexibility**: Including self-service options and portability.
- **Efficiency**: Maximizing investment value and optimizing costs.
- **Security**: Addressing the limitations of traditional security defenses in an evolving threat landscape.

Today, there are two widely accepted and popular deployment models:
1. **Fully Managed Cloud Service**: In this model, the vendor manages the entire infrastructure stack within their own environment, delivering the product as a complete service. This approach aligns with the traditional "Software as a Service" (SaaS) model.
1. **Self-Managed Software**: In this model, the vendor ships the product as a set of deployable software artifacts, which the customer is responsible for managing entirely within their own infrastructure.
Both of these common deployment methods have their own strengths and weaknesses:
The **Fully Managed Cloud Service** model offers advantages such as economies of scale, on-demand elasticity, reduced CAPEX, complete infrastructure management, seamless self-service updates, operational support, and a pay-as-you-go pricing model. This heavily balances the flexibility and efficiency of the deployment method, but it offers less security.
In contrast, the **Self-Managed Software** model enables alignment with customer-specific security policies, customization, proximity to existing and legacy services, comprehensive observability, and reuse of existing infrastructure investments. This deployment model prioritizes security and offers some flexibility, though it generally lacks the efficiency of a cloud-based deployment.
Recognizing the strengths and potential benefits of each, Ververica has consistently offered both of these deployment options for our Unified Streaming Data Platform. While these options each meet a wide range of business needs, we identified an opportunity to create a new deployment model that bridges the gaps left between the two existing ones.
Ververica now offers the [Bring Your Own Cloud](https://www.ververica.com/blog/introducing-byoc-deployment) deployment option, enabling customers to leverage existing cloud resources while retaining full control over their cloud infrastructure. This deployment offers the full flexibility and scalability of [Ververica’s Unified Streaming Data Platform](https://www.ververica.com), while addressing the three key elements of the dilemma with a more balanced approach, ensuring an equitable distribution of flexibility, efficiency, and security.
## Combining Strengths
Bring Your Own Cloud (BYOC), is a fresh approach that enables customers to store their data in their own cloud while the vendor manages the metadata. BYOC frees companies from vendor lock-in and aligns seamlessly with strict cybersecurity strategies by leveraging cloud-native technologies and Zero Trust principles.
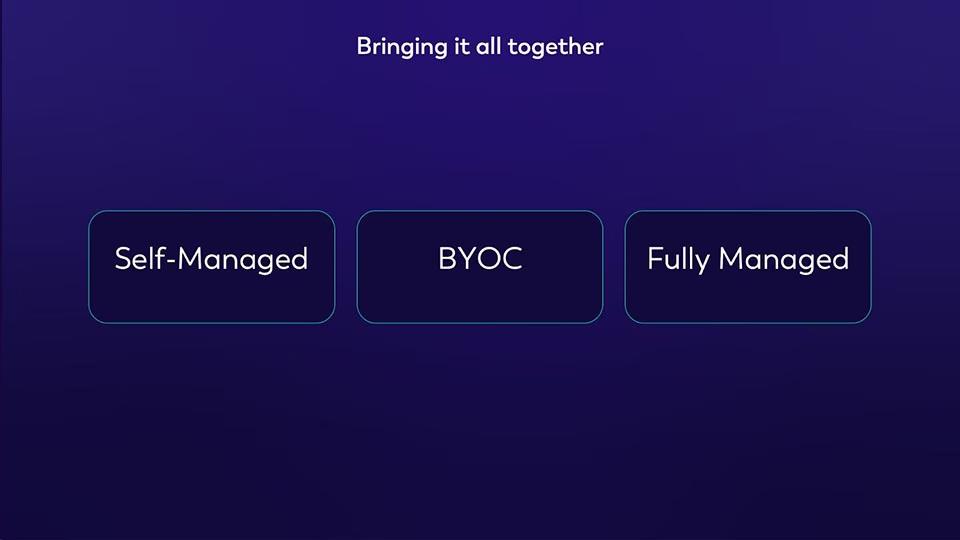
Next, we’ll briefly discuss how the Bring Your Own Cloud (BYOC) approach addresses the challenges of balancing flexibility, efficiency, and security, and solves the dilemma. We’ll also cover the fundamental architecture of this deployment model.
## The Vendor Control Plane and User Data Plane: More Flexibility, More Security
BYOC operates by clearly separating the control plane (managed by the vendor, in this case, Ververica) from the distributed data plane (residing in the customer’s cloud or region of choice). In this model, Ververica manages only metadata, while customers retain complete control over their data (see Figure 4).
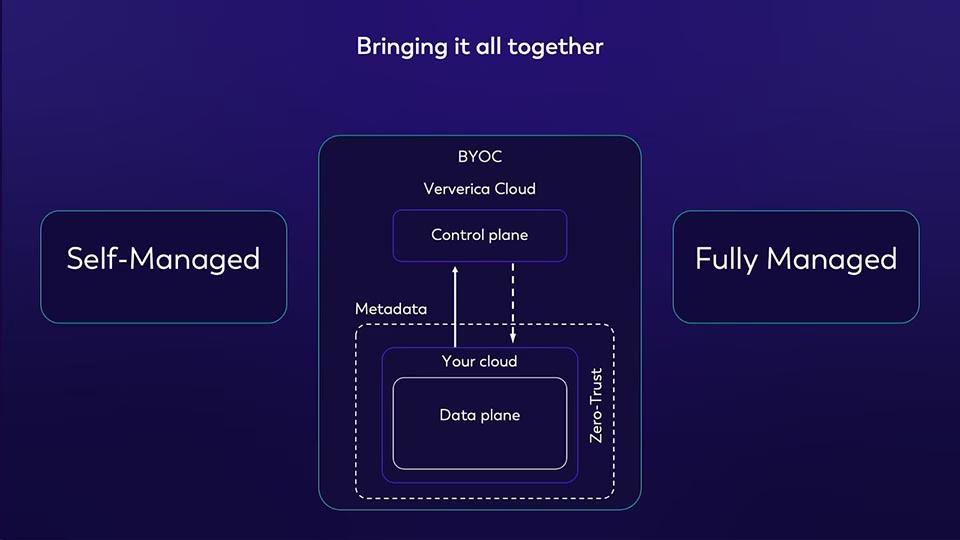
This setup provides flexibility by allowing Ververica to handle management tasks, while customers maintain full control over their data ensuring compliance and privacy.
## BYOC, Cloud-Native and Lightweight: More Efficiency, More Security
The beauty of a BYOC deployment lies in its cloud-native design, allowing it to work seamlessly with your existing infrastructure. This means that if you are already using cloud-native tools or resources, BYOC integrates smoothly, preserving your prior investments.
BYOC offers:
- **Seamless Integration with Existing Infrastructure**: BYOC fits naturally into your current setup, maximizing the use of existing infrastructure and investments.
- **Kubernetes Compatibility for Portability**: For customers using Kubernetes to manage containers, BYOC can easily integrate and co-locate alongside other workloads.
This approach enhances your data governance and control, extending your capability without disrupting your existing cloud environment.
As shown in Figure 5, Ververica’s cloud-native data plane microservices are designed to integrate with any existing compute, network, and storage infrastructure. In addition, it integrates with Kubernetes clusters, seamlessly co-locating with other workloads.

## Leverage Existing CAPEX and OPEX: More Efficiency, More Flexibility
Another key benefit of BYOC is the ability to leverage existing cost-saving agreements with existing cloud providers, including any prepaid or discounted services.
With BYOC, you can:
- **Use Existing Discounts**: Keep any pricing agreements with current cloud providers, applying them to Ververica’s Managed Service while maintaining in-house data control.
- **Utilize Existing Investments**: Reuse existing infrastructure, Kubernetes clusters, third-party services, and other ecosystem tools without needing new setups.
- **Pay-As-You-Go (PAYG)**: BYOC offers a flexible, usage-based model, so you pay only for the resources and services you actually use.
- **Eliminate Network Bandwidth Costs**: By bringing stream processing close to where the data resides, BYOC minimizes or removes inter-cloud connectivity charges.

## BYOC + Zero Trust: Strengthening Security
Ververica designed BYOC from the ground up with [Zero Trust](https://www.cisa.gov/zero-trust-maturity-model) principles, allowing customers to maintain full control over their cloud while future-proofing their security strategy. Zero Trust is a security model based on the principle of never trusting anyone or anything by default (whether inside or outside the network) and requiring verification for every user and system.
With Zero Trust principles intentionally built into the BYOC deployment option, you gain:
- **Future-Ready Security**: Aligning with a Zero Trust framework ensures that organizations are well-positioned for future security upgrades and standards.
- **Reduced Security Risks**: By adhering to Zero Trust principles, organizations lower the risk of unauthorized access. If a breach occurs, Zero Trust helps contain it, limiting potential damage.
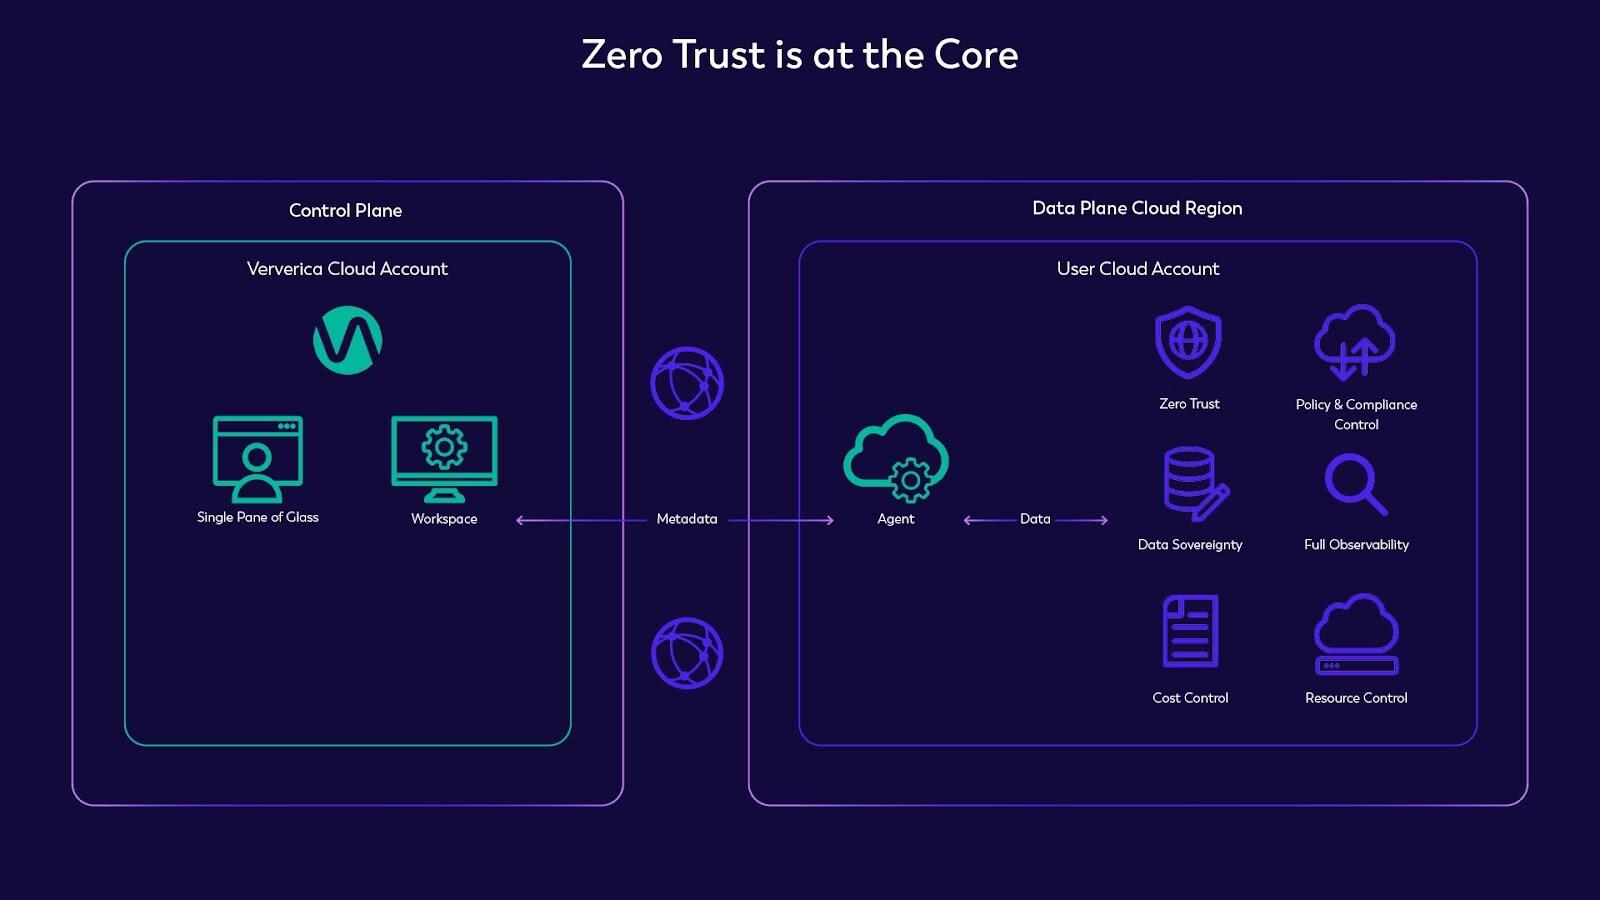
## Take Control with Balanced Security, Flexibility, and Efficiency
[Ververica’s Unified Streaming Data Platform](https://www.ververica.com) Bring Your Own Cloud deployment option provides organizations with a data streaming solution that offers an ideal mix of flexibility, efficiency, and security.
BYOC bridges the gaps between fully-managed and self-managed solutions, giving you full control of your environment. Designed for seamless integration with your existing cloud infrastructure, it eliminates vendor lock-in and incorporates Zero Trust principles to support long-term cybersecurity objectives.
Stay tuned! In the upcoming posts of this blog series, we’ll explore each of these three challenges in greater detail.
## Additional Resources
Read ["Introducing Ververica's Bring Your Own Cloud (BYOC) Deployment Offering" Blog](https://www.ververica.com/blog/introducing-byoc-deployment)
Ready to get started? Explore the [deployment options.](https://www.ververica.com/deployment/bring-your-own-cloud)
Not sure which deployment method is best for you? [Contact us.](https://www.ververica.com/contact)
Want to learn more about Ververica’s Bring Your Own Cloud deployment offering of Ververica’s Unified Streaming Data Platform? [Log into Ververica Academy](https://www.ververica.academy/courses/3d163483-5040-4d60-b5b3-755c3277edf7/activities/75f48f8e-5972-44d6-ba1c-a61a8e9f22c8) to watch Ben Gamble and Igor Kersic onstage at Flink Forward Berlin 2024.
---
---
title: "From Kappa Architecture to Streamhouse: Making the Lakehouse Real-Time"
description: ""
lastUpdated: 2026-03-24T05:41:45.000Z
source_url:
html: "https://www.ververica.com/blog/from-kappa-architecture-to-streamhouse-making-lakehouses-real-time"
md: "https://www.ververica.com/blog/from-kappa-architecture-to-streamhouse-making-lakehouses-real-time.md"
---
The demand for real-time insights has transformed how businesses approach data architectures. Over the last decade, the Kappa Architecture has evolved significantly to address modern scalability, efficiency, and real-time analytics requirements. However, while Kappa may be able to streamline handling event-driven applications and continuous data streams, it also has inherent limitations, including the inability to integrate historical data processing.
The next evolution to emerge is the data Lakehouse, which offers structured and transactional data processing in addition to the flexibility of traditional Data Lakes. However, as real-time data demands continue to grow, efforts to extend Lakehouse capabilities into streaming-first scenarios raise additional concerns, including gaps in latency, efficiency, and the seamless integration of both.
[Ververica’s Streamhouse](https://www.ververica.com/blog/streamhouse-evolution) is the newest concept that combines the real-time, low-latency capabilities of streaming systems with Lakehouse's robust analytics and flexibility. Helping to drive this shift are technologies like [Apache Paimon](https://paimon.apache.org/) and [Fluss](https://www.ververica.com/blog/fluss-is-now-open-source), which integrate perfectly with Apache Flink® and Flink CDC, enabling businesses to unify real-time and historical data processing in a single, efficient solution.
In this post, we’ll discuss the evolution from Kappa to Lakehouse and the emergence of Streamhouse, exploring how they help address modern data challenges and how Streamhouse unlocks the potential of unified batch and stream processing systems.
## The Starting Point
Several innovative data architectures have been introduced over time. In this section, we’ll focus on Lambda and Kappa.
### Lambda Architecture
Emerging in the early 2010s, the Lambda architecture addresses several big data processing challenges. Lambda features a dual-layer design:
- **Batch Layer**: Processes large historical datasets accurately using tools like Apache Hadoop®.
- **Speed Layer**: Focuses on low-latency, real-time data processing with systems like Apache Flink or Spark Structured Streaming.
While Lambda was an effective solution at the time of its invention, this approach has significant drawbacks, including:
- **Complexity**: Maintaining separate codebases for batch and streaming layers increases development and operational overhead.
- **High Latency**: The reliance on the batch layer for completeness delays the integration of historical data with real-time results.
- **Resource Intensive**: Operational inefficiencies make scaling difficult.
### Kappa Architecture
In response to these drawbacks, the Kappa Architecture appeared in 2014 as an alternative that emphasizes real-time streaming over batch processing (ie: it adopts a streaming-first strategy). Kappa simplifies data architectures by eliminating the batch layer, using a single immutable log as the source of truth, and is often implemented with Apache Kafka® for storage and Apache Flink for real-time processing. This design offers several advantages:
- **Simplicity**: No duplicate codebases are needed for batch and streaming processing.
- **Low Latency**: Optimizes real-time stream processing, and is ideal for event-driven applications.
- **Scalability**: Enables replaying streams for debugging and reprocessing.
Despite these benefits, Kappa also faces limitations as data processing demands continue to grow, including:
- **Limited Batch Integration**: Kappa struggles to handle hybrid use cases that require batch processing.
- **Costly Reprocessing**: Replaying entire streams to manage historical data is very resource-intensive.
- **Challenging Analytics**: Log-based streaming systems lack support and optimization for ad hoc queries and complex analytical workloads. This requires integrating external systems to offload and inspect real-time data, which are often more batch-oriented and can’t cope with the demand of real-time data analysis.
Figure 1 depicts a streaming-first Kappa Architecture. Note that intermediate results are written into Kafka topics, but those results can’t be reused or queried, only consumed.
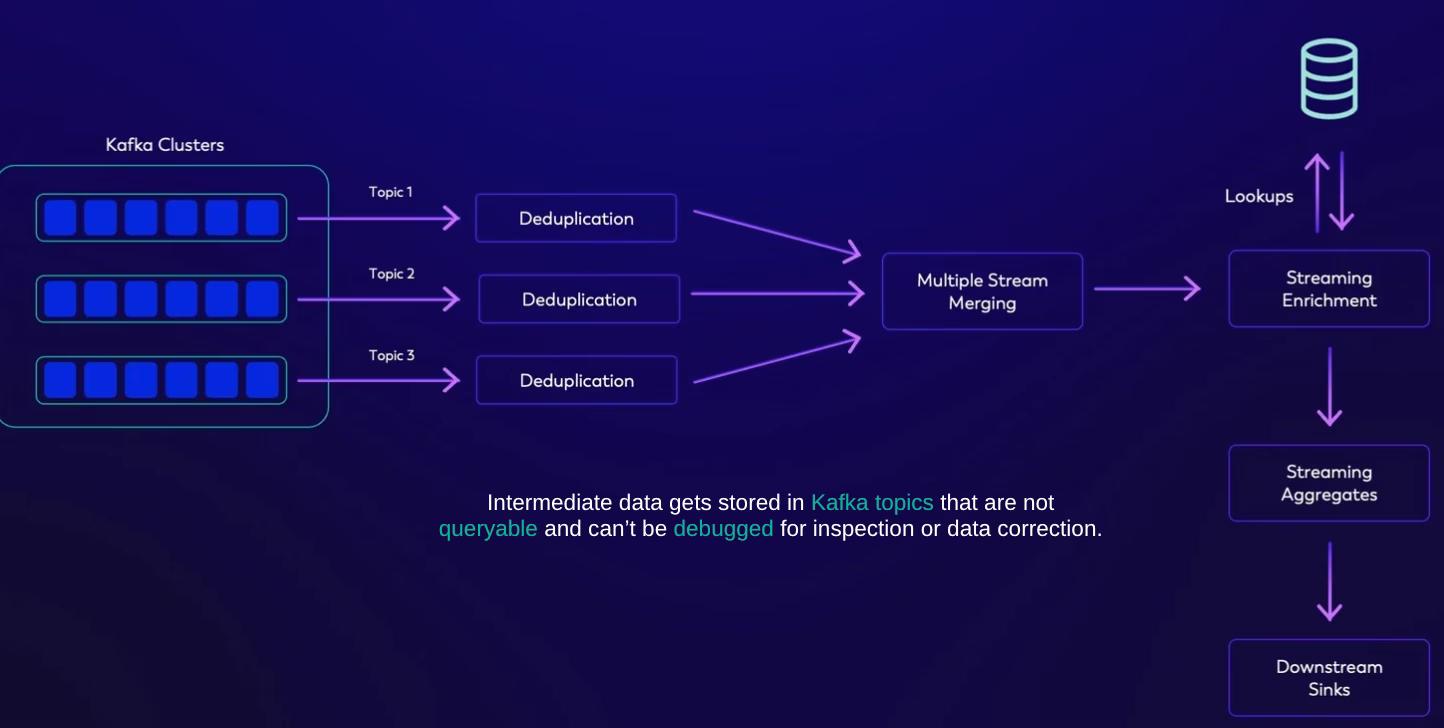
## The Rise of the Lakehouse
The Lakehouse concept, introduced circa 2017, combines the scalability of Data Lakes with the transactional guarantees of data warehouses. Technologies like Apache Iceberg™, Delta Lake, and Apache Hudi™ help to bring order and structure to Data Lakes, making it easier to organize, manage, and query data. These table formats address long-standing challenges such as consistency, transactional integrity, and query performance.
While these technologies introduce significant innovations, they are fundamentally designed with predominantly batch processing workflows in mind:
- **Designed for Batch Processing**: These formats excel at batch processing by optimizing queries over large, static datasets.
- **Streaming Capabilities**: Although some of these table formats incorporate streaming features, (Hudi, for example, can support some streaming use cases and CDC data) they often fall short of the high-performance demands of streaming-first architectures.
- **Latency Challenges**: Achieving real-time updates and second-level query freshness is challenging, especially when working with large streaming datasets.
These table formats display several shortcomings when integrated with streaming engines like Apache Flink. As a whole, the Flink connectors for Apache Iceberg, Delta Lake, and Apache Hudi struggle to meet the stringent requirements of streaming-first engines and fail to address many of the use cases that Flink aims to support. This limits the ability for businesses to achieve the low-latency, high-throughput, unified batch and stream processing capabilities they increasingly demand.
One architecture that is commonly used today involves streaming data into Apache Iceberg tables to enable analytical systems to query these tables efficiently. While effective for certain scenarios, this approach still presents several limitations:
- **Limited Streaming Use Cases**: Current implementations focus on streaming ingestion only, leaving significant gaps in achieving end-to-end streaming pipelines. As a result, expanding the scope of use cases remains challenging.
- **High Resource Demand:** The absence of streaming materialized views within the Lakehouse architecture leads to frequent recomputation of queries, which is computationally intensive and resource-heavy.
- **Pipeline Fragmentation**: Integrating streams and tables often necessitates using disparate systems, resulting in complex and fragmented pipelines that increase operational complexity and reduce overall efficiency.
These challenges highlight the need for more integrated solutions that seamlessly support advanced streaming use cases while maintaining the flexibility and performance expected in modern Lakehouse environments.
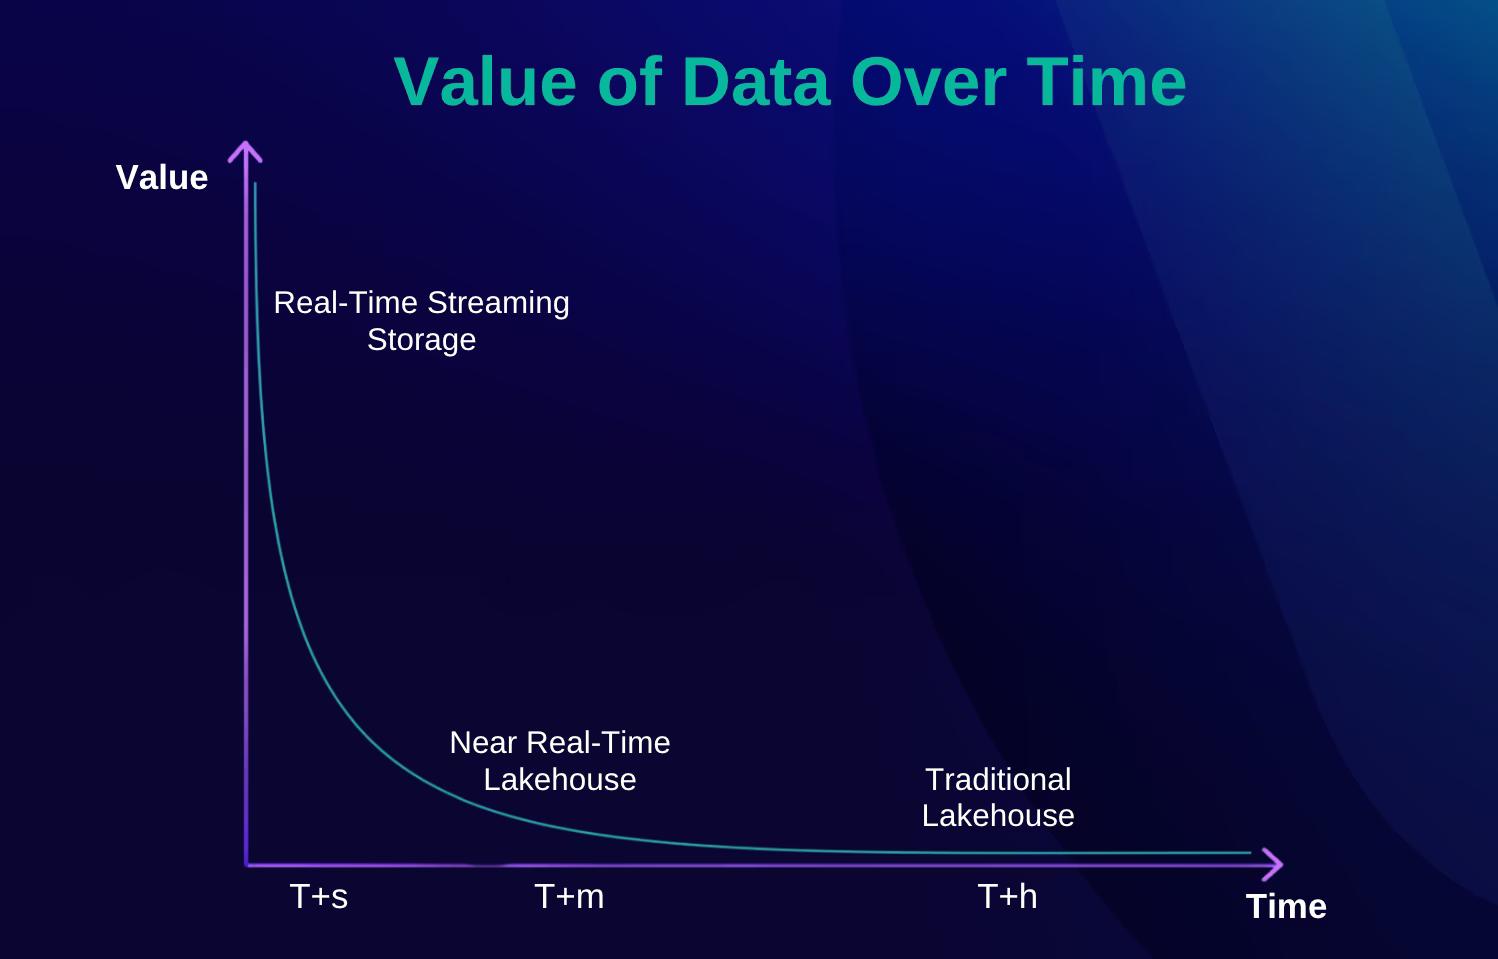
As organizations increasingly demand real-time insights and the seamless integration of batch and streaming workloads, the limitations of these predominantly batch-oriented approaches become more apparent. To bridge these gaps, Streamhouse is designed explicitly to prioritize streaming-first use cases, while preserving the flexibility and structural advantages of the Lakehouse.
## Streamhouse and Real-Time Streaming Storage for Data Analytics
[Streamhouse](https://www.ververica.com/streamhouse) unifies streaming and the Lakehouse, (much like the Lakehouse unifies Data Lakes and data warehouses). As the next evolution, Streamhouse combines the real-time capabilities of data streaming with the flexibility and structure of the Lakehouse, offering a single solution that seamlessly integrates both real-time and batch workloads.
Streamhouse not only enables organizations to achieve streaming-first architectures without compromising on batch efficiency and scalability, but it also enables **stream/table duality** within the same system. Technologies like [Apache Paimon](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse) and [Fluss](https://www.ververica.com/blog/introducing-fluss) support both streams (append-only data) and tables (updates), offering different table types that meet diverse user needs and use cases. This convergence delivers an integrated, efficient, and flexible solution that exceeds modern data processing demands.
In the next two sections, we’ll explore how these adjacent technologies support Streamhouse, and provide a cost-effective solution that prioritizes stream processing, while continuing to support batch use cases.
## Apache Paimon: Near Real-Time Lakehouse Storage
[Apache Paimon](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse) is an evolution of traditional Lakehouses, designed specifically to address the needs of real-time, streaming-first workloads. While there are attempts to introduce more support for streaming use cases in Lakehouses like Apache Iceberg, Lakehouses are still fundamentally built to address batch processing. Alternatively, Paimon enables an architecture that is optimized for streaming and excels in low-latency, high-throughput scenarios.
### Key Advantages of Apache Paimon
- **Optimized for Streaming**: Paimon is built to handle high-frequency data updates and real-time queries efficiently, making it ideal for modern applications with lower latency requirements.
- **Native CDC Support**: Paimon natively ingests Change Data Capture (CDC) streams, ensuring real-time updates for dynamic and evolving datasets.
- **Cost-Effective Alternative to Message Queues**: With built-in support for strong ordering guarantees and integration with tools like Flink CDC, Paimon serves as a cost-effective alternative to projects like Kafka for certain workloads, trading minimal latency increases for significant cost savings.
- **Iceberg Interoperability**: Paimon supports Iceberg snapshots, enabling seamless integration with existing Lakehouse ecosystems, while concurrently offering unique benefits for streaming workloads.
Apache Paimon addresses many of the challenges associated with traditional batch-first Lakehouses, (including Lakehouse’s higher latencies and inefficiencies in solving real-time scenarios) by focusing on streaming-first use cases. Paimon is particularly well-suited for businesses seeking a unified platform to handle both real-time and historical data processing.
Paimon’s origination and design began with the desire to bring streaming and stream processing with Apache Flink to the Lakehouse, essentially unlocking the ability to implement the Kappa Architecture directly on the Lakehouse.
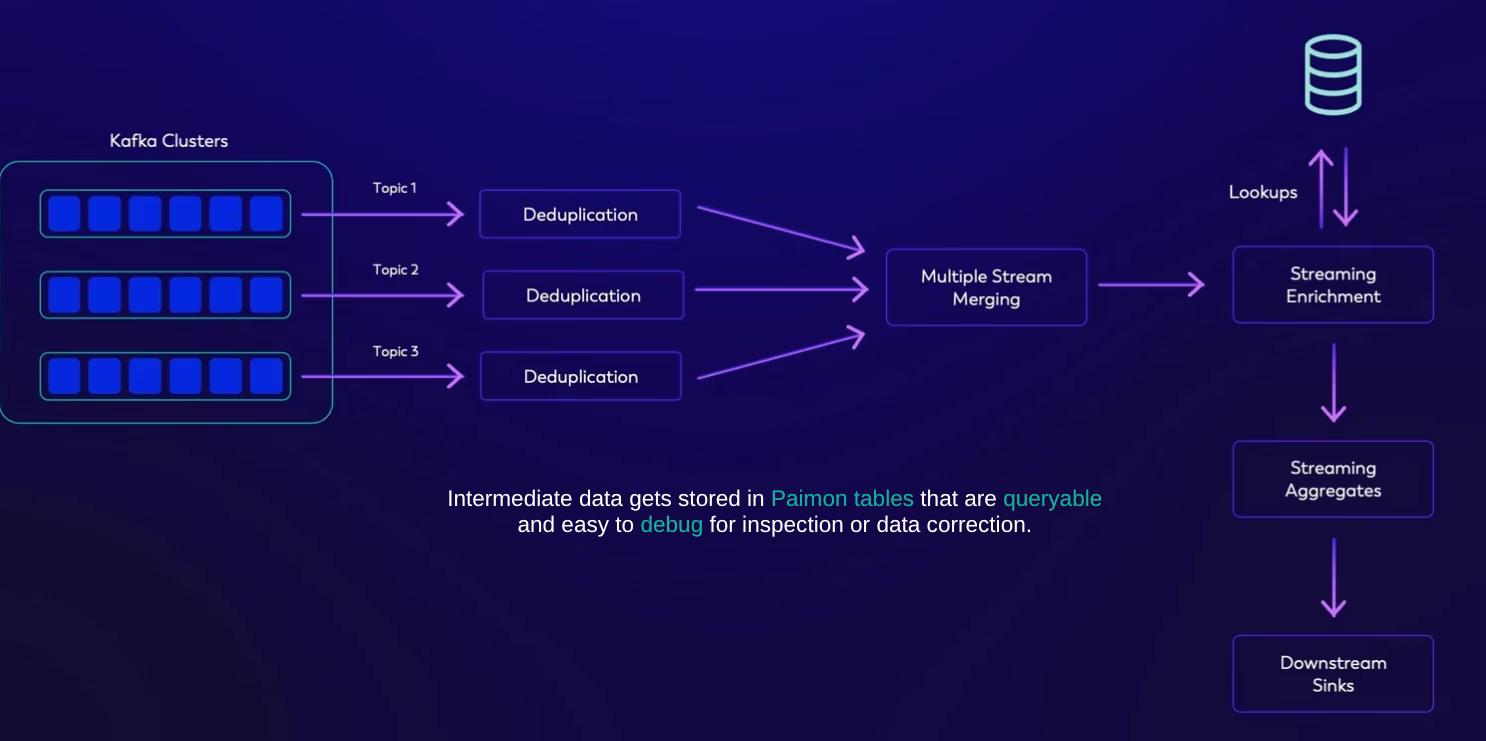
Revisiting Figure 1, this architecture can be implemented with an alternative approach that replaces Kafka entirely with Paimon (provided minor additional latency is acceptable for the required use case). Paimon inherently offers all the necessary properties required for this architecture, and this substitution results in a significantly more cost-effective solution. Furthermore, this architecture enhances transparency and flexibility by utilizing intermediate tables instead of topics. These tables are also directly queryable, which simplifies inspection and debugging processes and enables seamless integration with analytical engines for direct queries.
Paimon is a great fit for creating streaming-first architectures directly on the Lakehouse. However, as it interacts directly with files on object storage, the latency is near-time (typically to ~1minute) for large scale updates that can handle TBs of real-time data.
Next, let’s dive into [Fluss](https://www.ververica.com/blog/introducing-fluss), which is a real-time streaming storage for sub-second-level latencies.
## Fluss: Real-Time Streaming Storage
Fluss is a streaming storage built for real-time analytics which can serve as the real-time data layer for Lakehouse architectures. Fluss solves the limitations that log-based streaming storage solutions like Kafka have regarding data analytics, and helps users refine the implementation of the Kappa Architecture. With its columnar stream and real-time update capabilities, Fluss integrates seamlessly with Apache Flink and enables high-throughput, low-latency, cost-effective streaming data warehouses tailored for real-time applications.
### Key Features and Benefits of Fluss
The key features and benefits of Fluss for streaming data analytics include:
- **Sub-Second Latency:** Fluss ensures sub-second latency streaming reads and writes, enabling immediate read and write operations for fast, actionable insights. Ideal for time-sensitive applications like monitoring and financial platforms, Fluss delivers data as soon as it's ingested.
- **Updates and Changelogs - Stream/Table Duality:** Fluss supports stream-table duality, allowing efficient updates with comprehensive changelogs. This ensures consistent data flow, providing full visibility into stream changes for accurate real-time and historical insights within the same system.
- **Ad-Hoc, Interactive Queries:** Fluss is fully queryable, enabling direct data inspection without extra processing layers. This reduces development complexity, simplifies debugging, and allows immediate access to live data insights.
- **Unified Batch and Streaming:** Fluss offers a unified batch and streaming data system, enabling efficient historical processing alongside live streams. This seamless integration optimizes infrastructure for AI, ML, and analytics workloads.
- **Column Pruning:** Fluss uses column pruning to optimize streaming reads, fetching only the necessary fields for queries. This reduces data transfer, improving performance up to 10x and lowering network costs.
- **Columnar Streaming Reads:** With columnar streaming reads, Fluss enhances performance by storing data in a columnar format. This improves compression and speeds up analytics, making it perfect for data-heavy, real-time applications.
Named after the German word for “river,” Fluss symbolizes the continuous flow of data into unified storage and redefines real-time analytics with exceptional performance, scalability, and flexibility, making it an important enablement piece for the next generation of streaming storage solutions.
## Fluss and Paimon: Complementary Pillars of Streamhouse
While both Fluss and Paimon are Streamhouse technologies, they serve complementary roles:
- **Fluss** is a **real-time** streaming storage layer, optimized for data analytics and sub-second query freshness.
- **Paimon** is a **near real-time** Lakehouse format with native support for large-scale updates and CDC ingestion, while also offering Iceberg compatibility to ensure harmony with the current Lakehouse ecosystem.
They enable businesses to build robust, scalable, and cost-efficient data platforms that unify batch and streaming workloads. The future is **streaming-first, but not at the expense of batch processing**. Instead, the focus is on unifying the two paradigms to support diverse workloads with a single architecture. As the ecosystem matures, businesses can benefit from adopting Streamhouse.
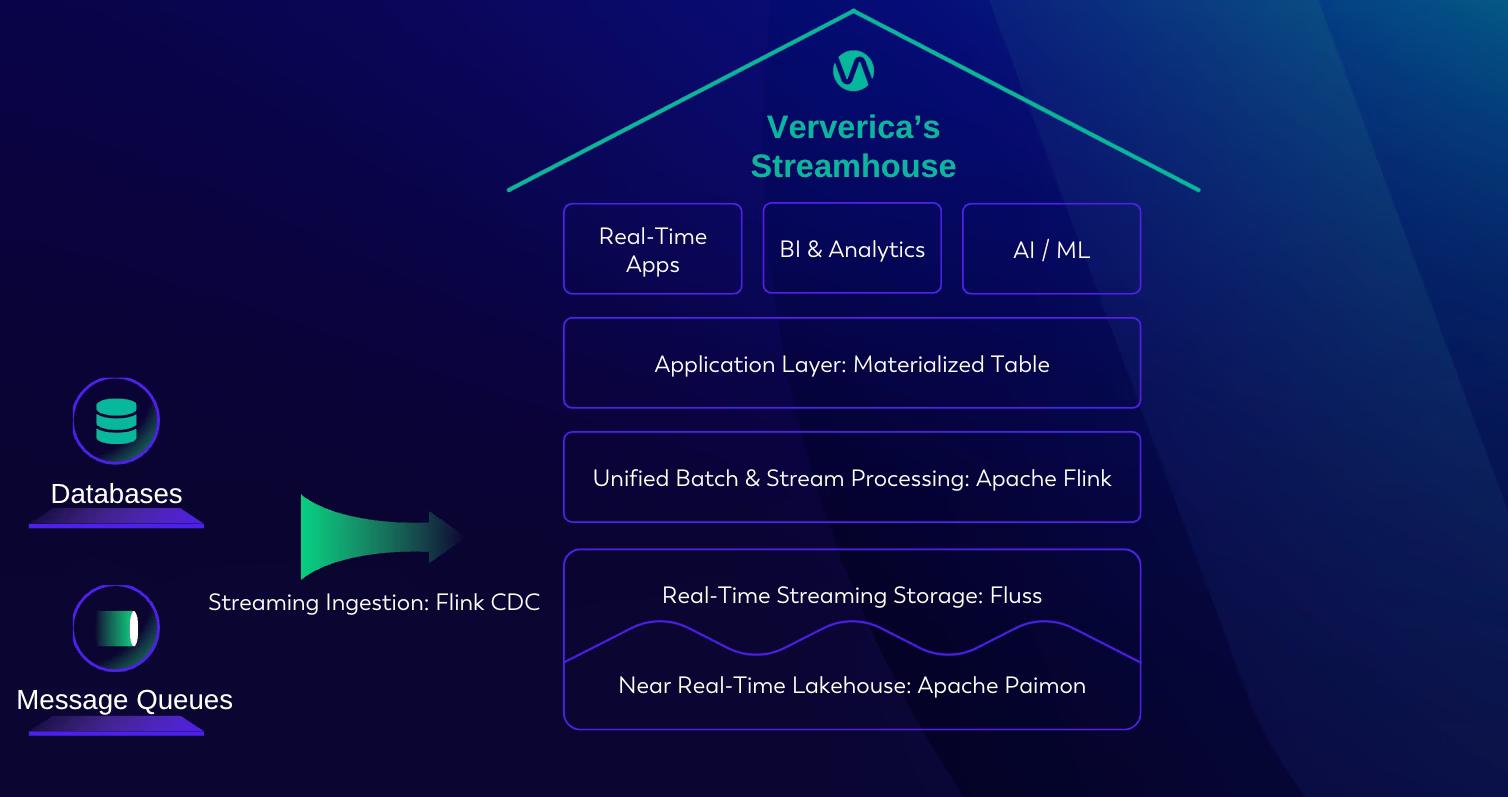
## Benefits of Ververica's Streamhouse
- **Real-Time Decision Making:** With real-time analytics, businesses can respond quickly to market changes, customer needs, and operational challenges, driving competitive advantage in industries like e-commerce, finance, and logistics.
- **Unification of Batch and Streaming Workloads:** By integrating batch and streaming capabilities, Streamhouse eliminates silos between the two, enabling seamless data processing within a single architecture. This reduces operational complexity and enhances flexibility.
- **Simplified Data Systems:** Streamhouse replaces fragmented pipelines with a cohesive framework, lowering infrastructure costs and simplifying data operations while reducing the total cost of ownership.
- **Scalability and Performance:** Technologies like Fluss and Apache Paimon empower businesses to handle high-throughput workloads with low latency, ensuring seamless scalability as data volumes grow.
- **Future Proof Infrastructure:** Designed to support both real-time and historical processing, Streamhouse offers the flexibility to adapt to evolving data requirements without rearchitecting pipelines.
For modern enterprises, Ververica’s Streamhouse provides the tools to unlock real-time insights, streamline operations, and build a scalable, cost-efficient data platform.
## Conclusion
Streaming data architectures have evolved significantly over time in the relentless pursuit of simplicity, flexibility, and real-time insights in modern data systems. Each new architecture has addressed the challenges of their time, and Streamhouse offers a transformative next step as a unified solution that bridges the gap between real-time and batch workloads.
With supporting technologies like Fluss and Apache Paimon, Streamhouse is much more than an incremental improvement, instead, it represents a paradigm shift in how to think about real-time data processing. By combining low-latency streaming capabilities with the analytical power of the Lakehouse, this new solution enables businesses to extract meaningful insights from their data faster, more efficiently, and at scale.
Looking ahead, Streamhouse offers a robust foundation for businesses to thrive in a real-time, data-driven world. Organizations that adopt strategies that unify streaming and batch processing are better equipped to stay ahead of the curve and can unlock new business opportunities empowered with the data required to make smarter data-driven decisions.
With Streamhouse, the limitations of the Kappa and Lakehouse architectures disappear, allowing businesses to address modern data challenges and unlock the potential of truly unified stream and batch processing systems.
### Additional Resources
**Learn more about Streamhouse:**
- Blog: [Streamhouse Unveiled](https://www.ververica.com/blog/streamhouse-unveiled)
- Blog: [Streamhouse: Data Processing Patterns](https://www.ververica.com/blog/streamhouse-data-processing-patterns)
**Explore Apache Paimon:**
- Blog: [Apache Paimon: The Streaming Lakehouse](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse)
**Get to Know Fluss:**
- Announcement Blog: [Introducing Fluss: Unified Streaming Storage For Next-Generation Data Analytics](https://www.ververica.com/blog/introducing-fluss)
- Blog: [Fluss Goes Open Source](https://www.ververica.com/blog/fluss-is-now-open-source)
- Flink Forward Berlin 2024 Opening Session Keynote Announcement:[The Future - Introducing Fluss](https://www.ververica.academy/courses/3d163483-5040-4d60-b5b3-755c3277edf7/activities/1af290fd-05bc-4fab-90be-6ed4628399be)
- Flink Forward Berlin 2024 Fluss Breakout Presentation: [Is Kafka the Best Storage for Streaming Analytics?](https://www.ververica.academy/courses/3d163483-5040-4d60-b5b3-755c3277edf7/activities/a366d118-6c53-47ef-91bb-289fc2462b07)
**Ready to get started with the** [**power of Streamhouse**](https://www.ververica.com/streamhouse)**?**
Learn more about [Ververica’s Unified Streaming Data Platform](https://www.ververica.com/product), powered by the VERA engine.
---
---
title: "Fluss Is Now Open Source"
description: ""
lastUpdated: 2026-03-23T18:25:30.000Z
source_url:
html: "https://www.ververica.com/blog/fluss-is-now-open-source"
md: "https://www.ververica.com/blog/fluss-is-now-open-source.md"
---
Earlier this year at Flink Forward 2024 Berlin we [announced Fluss](https://www.ververica.com/blog/introducing-fluss) and today we are thrilled to announce open-sourcing the project. Fluss is a **streaming storage system** designed to power real-time analytics. Fluss changes how organizations approach real-time data by acting as the **real-time data layer** for the Lakehouse. Its cutting-edge design enables businesses to achieve **sub-second latency**, **high throughput**, and **cost efficiency** for data analytics, making it the ideal solution for modern data-driven applications.
Historically, we have invested significant effort into advancing the data streaming ecosystem, including major contributions to [Apache Flink](https://flink.apache.org/), [Apache Flink CDC](https://www.ververica.com/blog/ververica-donates-flink-cdc-empowering-real-time-data-integration-for-the-community), and [Apache Paimon](https://paimon.apache.org/). As part of our commitment, Fluss is now open source under the Apache 2.0 license and is available on [GitHub](https://github.com/alibaba/fluss), inviting users to create the next generation of real-time architectures.
## Real-Time Streaming Storage for the Lakehouse Era
The need for real-time insights has grown exponentially, especially with the recent explosion of Artificial Intelligence (AI). However, the tools and architectures we’ve relied on for years weren’t designed with streaming-first analytical workflows in mind. Traditional architectures often involve complex integrations between message queues like Kafka, processing engines like Flink, and storage systems that are more batch than real-time oriented. This approach not only increases latency but also adds operational overhead and cost. Fluss offers a **unified streaming storage layer** purpose-built for **real-time analytics**.
At its core, Fluss combines the best of **streaming** and **analytical storage**. Its **columnar stream** design is optimized for real-time analytical queries, enabling lightning-fast data access and updates. With support for **real-time data ingestion** and integrations with **real-time lakehouse solutions** such as Paimon, Fluss ensures that data is always fresh and ready for analysis. This makes it ideal for applications where low latency is critical.
Fluss extensively integrates with Apache Flink, the de facto gold standard for stream processing. This integration combines a **stream processor** and a **real-time storage layer**, eliminating the need for separate message queues like Kafka in analytics-focused architectures. Fluss simplifies pipelines, reduces costs, and improves performance for **high-throughput, low-latency analytics**.
## Building the Future of Analytics with Fluss
Fluss supports a wide range of use cases, from powering dashboards and monitoring systems to enabling **streaming ETL** and **real-time intelligence pipelines** for the modern AI era. Its ability to provide real-time updates makes it a natural fit for **streaming data warehouses**, where fresh data is essential for decision-making.
By serving as the real-time data layer on the Lakehouse, Fluss supports both **streaming-first architectures** and **unified batch and stream processing**. This flexibility is appealing for organizations looking to modernize their analytics stack while keeping costs low and performance high.
## What’s Next for Fluss?
Open-sourcing Fluss is just the beginning and soon it will be donated to the [Apache Software Foundation](https://www.apache.org/) (ASF). We’re committed to working closely with the community to expand its capabilities and adoption. You can learn more about the [project’s roadmap here](https://fluss.apache.org/roadmap/).
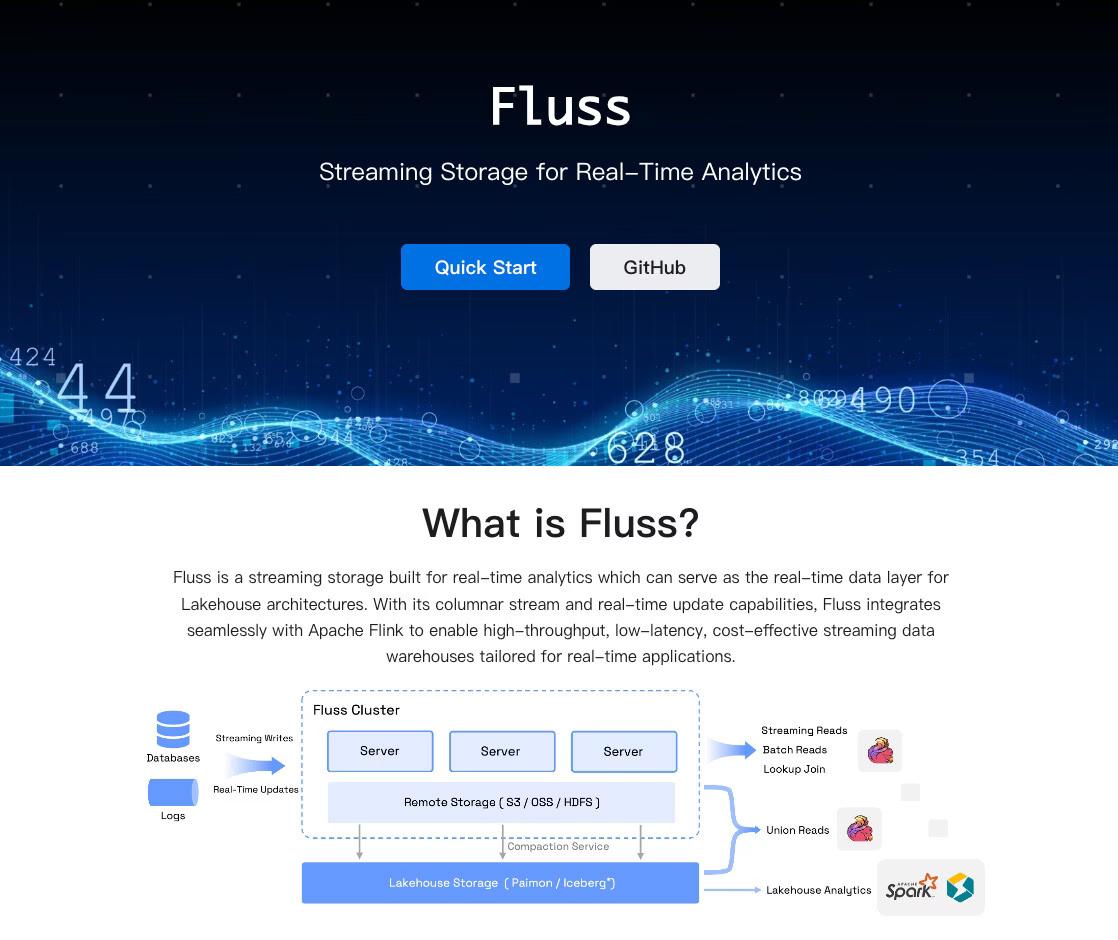
## Join the Journey
We invite you to join us and help grow our community around the project. Explore Fluss, contribute to its development, and build the next generation of data pipelines!
Keep an eye on the project, give it a try, and if you like it, don’t forget to give it some ❤️ via ⭐ on GitHub.
### Get Started
1. Visit the [GitHub repository](https://github.com/alibaba/fluss)
1. Check out the [Quickstart Guide](https://fluss.apache.org/docs/quickstart/flink/)
### Additional Resources
Ready to learn more? [Watch "Optimizing Streaming Analytics with Apache Flink and Fluss](https://www.youtube.com/watch?v=GKsE_EUR9yU)" for an introduction to Fluss, the next evolution of streaming storage built for real-time analytics.
- **Announcement Blog:** [Introducing Fluss: Unified Streaming Storage For Next-Generation Data Analytics](https://www.ververica.com/blog/introducing-fluss)
- **Flink Forward Berlin 2024 Opening Session Keynote Announcement:** [The Future - Introducing Fluss](https://www.ververica.academy/courses/3d163483-5040-4d60-b5b3-755c3277edf7/activities/1af290fd-05bc-4fab-90be-6ed4628399be)
- **Flink Forward Berlin 2024 Fluss Breakout Presentation:** [Is Kafka the Best Storage for Streaming Analytics?](https://www.ververica.academy/courses/3d163483-5040-4d60-b5b3-755c3277edf7/activities/a366d118-6c53-47ef-91bb-289fc2462b07)
---
---
title: "Real-Time Insights for Airlines with Complex Event Processing"
description: "Discover how Complex Event Processing (CEP) and Dynamic CEP help optimize airline operations through real-time data insights and dynamic rule updates."
lastUpdated: 2026-04-30T11:27:21.000Z
source_url:
html: "https://www.ververica.com/blog/real-time-insights-for-airlines-with-complex-event-processing"
md: "https://www.ververica.com/blog/real-time-insights-for-airlines-with-complex-event-processing.md"
---
## Introduction
Businesses are embracing real-time data processing to better handle their ever-increasing data volumes, and to enable faster, more informed decision-making. Complex Event Processing (CEP) and Dynamic CEP are powerful tools that allow you to detect event patterns in endless streams of events, helping you pinpoint critical insights and focus on the data that truly matters.
Apache Flink® is the de-facto gold standard for real-time data processing, and its built-in CEP library makes it easy to apply Complex Event Processing to streaming data, allowing businesses to define and track patterns across event streams, including detecting specific sequences and conditions that are important to their operations. As a result, teams can set up alerts, make adjustments, and trigger automated responses based on real-time, current events.
In this blog post, we’ll explore how CEP delivers practical benefits specifically to the airline industry, where real-time detection, monitoring, and event optimization are crucial. We’ll also introduce Dynamic CEP, a unique capability found only in [Ververica's Unified Streaming Data Platform](https://www.ververica.com/product) that provides the ability to adjust patterns and rules as conditions evolve.
We’ll walk through examples including:
- Monitoring flight delays,
- Managing security alerts, and
- Improving turnaround times for aircraft.
Lastly, we’ll discuss the importance of Dynamic Complex Event Processing, and the ability to adjust rules as conditions evolve, so businesses can stay responsive without downtime.
## What is Complex Event Processing?
CEP is a tool that identifies patterns, trends, and sequences within real-time data streams. Rather than analyzing events in isolation, CEP connects multiple events to provide a holistic view of the current state, helping organizations to see and understand a complete picture of their operations.
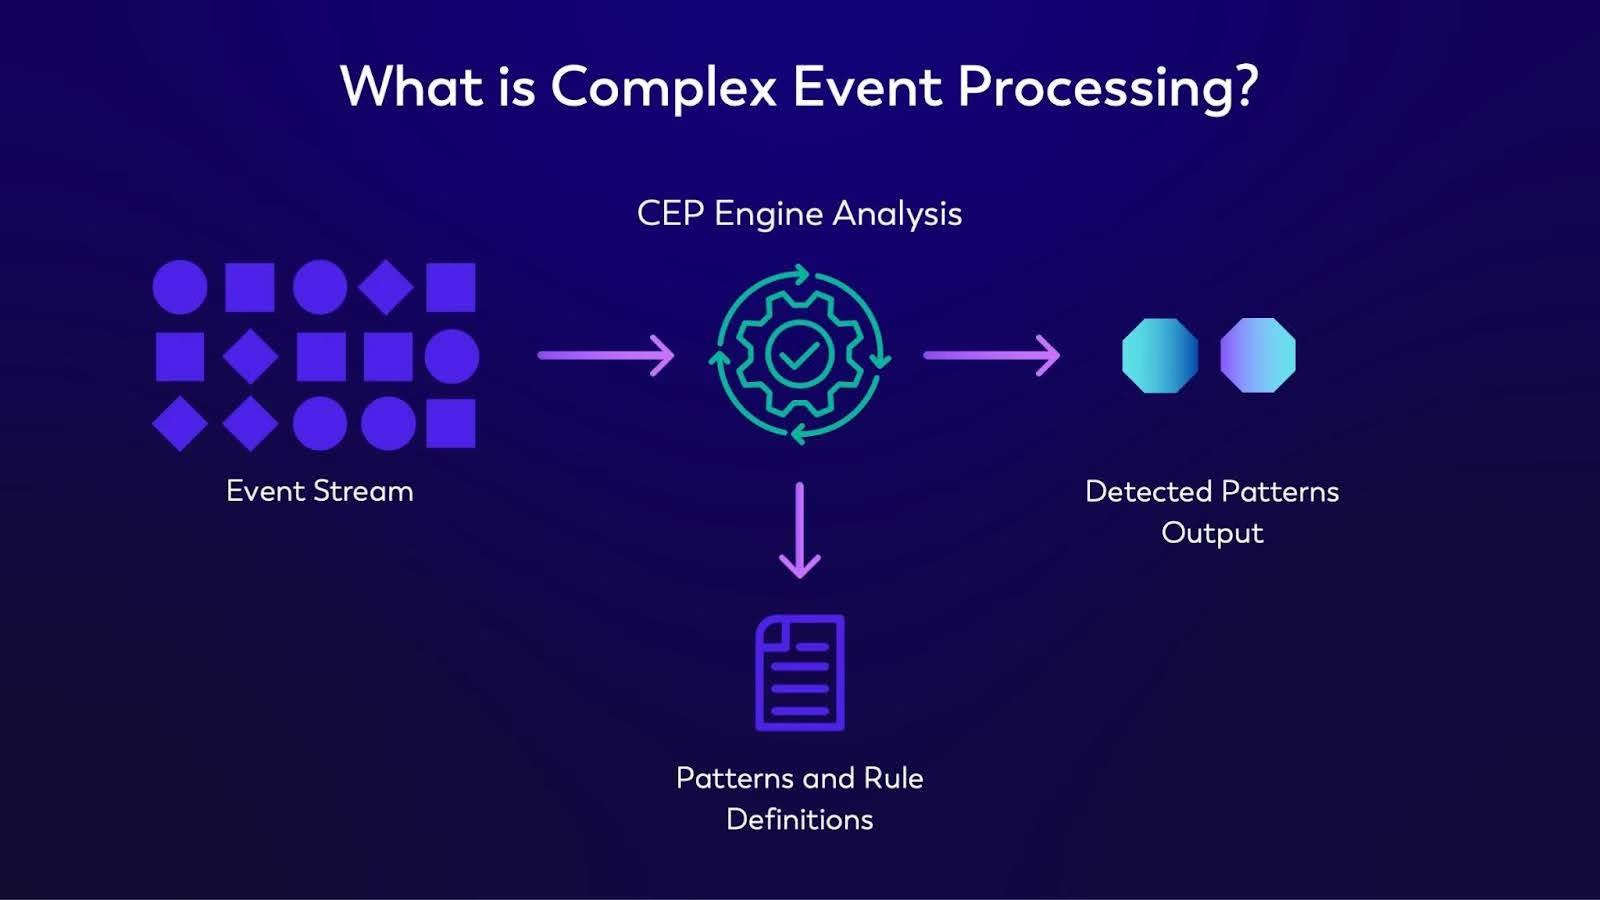
The visual above (Figure 1) demonstrates how CEP works. Data enters via the input event streams, and moves through the CEP engine, where the patterns and rules that require identification have been defined. The engine continuously monitors the input data streams, applying the defined rules. When a match is identified, CEP outputs that matching event, allowing the business to take action directly.
Complex Event Processing enables businesses to track critical interactions, detect risks, and initiate automated responses in real-time. The result is an environment where critical insights are identified and reported as they happen, enabling more efficient and effective operations.
Imagine a system monitoring thousands of real-time data streams simultaneously, such as aircraft movements, weather updates, and passenger information. While individual data points may seem insignificant on their own, analyzing them as part of a larger sequence can reveal critical insights. CEP empowers organizations to define specific patterns and rules that in turn trigger automated actions or alerts the moment those predefined conditions are met, unlocking value which is often otherwise hidden (or very hard to correlate) in event streams.
## Why is Complex Event Processing Important?
While CEP is a powerful feature that many industries utilize to solve various use cases, some benefits that CEP provides specifically for the airline industry include:
- **Cost and Resource Optimization**: By catching potential disruptions early, airlines can avoid costly delays, improve resource allocation, and optimize schedules.
- **Proactive Operations**: Identifying patterns in real-time allows teams to be notified and to act on potential disruptions before they escalate to business critical downtime. This allows teams to be proactive and help avoid costly delays while optimizing workflows.
- **Passenger Experience Enhancement**: Flight schedules, security, and ground operations can be proactively managed, helping deliver a smoother, more predictable experience to passengers (i.e. a better customer experience in an industry with slim margins and heavy competition).
- **Support for Operational Agility**: Airlines can adapt swiftly and respond dynamically to evolving industry demands and conditions, including adjusting schedules based on weather changes, quickly implementing new security protocols, or meeting new regulatory requirements.
Fundamentally, CEP makes it possible to define, monitor, and act upon complex patterns across data streams.
## Complex Event Processing Applications in the Airline Industry
Next, let’s explore three specific common use cases for CEP for the airline industry, including examples of how Apache Flink’s CEP library supports these applications.
> **TIP:** TRY IT!
Sample implementations of the patterns discussed below can be found in this GitHub repo, including a data generator to test it out!
### 1. Flight Delay Detection Due to Weather Conditions
Flight delays are one of the most common and costly disruptions to the airline industry, and are typically caused by and related to adverse weather conditions. Because weather conditions can significantly impact flight schedules, quick decision-making to manage resources, notify passengers, and adjust downstream flight is required.
With CEP, you can monitor both flight schedules and weather data streams together and detect potential delays in real time. To accomplish this, a team can define a rule that monitors sequences where adverse weather events coincide with scheduled departure or arrival times, and be able to take action before the delay escalates.
### 2. Monitoring and Escalating Security Incidents
Security is a top priority and identifying potential risks, (like unattended luggage or other suspicious activities) is essential for passenger safety. However, monitoring security issues in real-time across a busy terminal is challenging and can strain resources when attempted without utilizing automated support.
With CEP enabled, you can detect unattended luggage or other suspicious activities. By simultaneously monitoring data from security cameras, passenger movement, and IoT-enabled luggage tags, CEP can identify when a bag is left stationary in a public area without a nearby passenger. If the luggage remains unattended for a specific amount of time, a security alert can be set to automatically trigger.
Real-time monitoring of security risks helps improve airport safety and allows airlines to respond to potential threats faster, reducing operational disruptions and enhancing passenger and customer confidence. By automating detection, security teams can focus on handling incidents rather than manually scanning for them.
### 3. Analyzing Aircraft Turnaround Times to Optimize Ground Operations
Aircraft turnaround time is critical for operational efficiency. Delays in unloading, refueling, cleaning, and boarding can quickly escalate, causing cascading delays for other flights and disrupting airport schedules, potentially resulting in monetary penalties and customer dissatisfaction.
With CEP, you can monitor the series of events involved in aircraft turnaround and detect any delays in real-time. From gate arrival to boarding, by tracking each step in the turnaround process, you can quickly highlight bottlenecks or delays that need intervention.
For instance, if you detect that disembarkation is taking longer than expected, ground operations can be alerted to prioritize other steps, reducing the overall delay. With this level of granular insight, every stage of the turnaround process can be optimized, resulting in a more predictable service and improved experience for passengers.
## Dynamic Complex Event Processing
Now, here’s where things get _really_ interesting.
Businesses and their data needs are constantly evolving, requiring data monitoring rules to change and update also. But what happens when you need to change a pattern or add a new rule? Traditional systems required downtime to update, which is a major issue for industries (like airlines) that operate 24/7.
Ververica’s [Unified Streaming Data Platform](https://www.ververica.com/product), powered by the [VERA engine](https://www.ververica.com/vera), solves this by offering Dynamic CEP, which allows instant updates to processing rules without interrupting operations. Quite literally, Dynamic CEP provides the capability for you to update and modify your event processing rules in-flight. For example, if you need to re-define the average time window for an aircraft turnaround, or update a security risk, you can update these patterns instantly, without disrupting your data stream or causing downtime. With Dynamic CEP, you can modify patterns and rules on the fly, while your system keeps running, as shown in Figure 2:
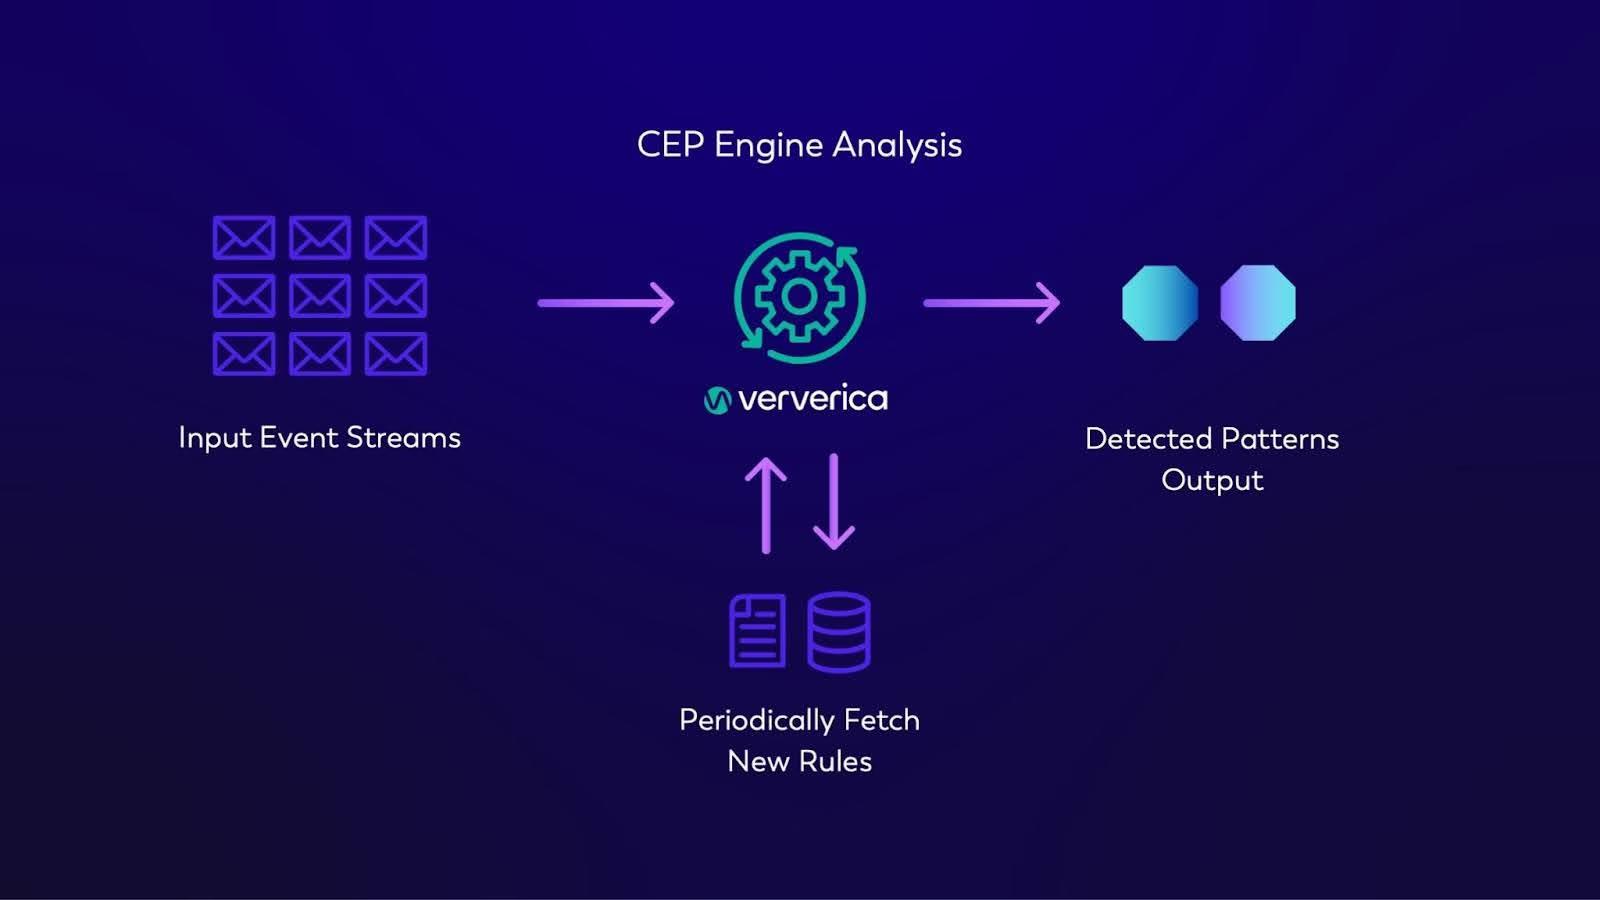
Dynamic Complex Event Processing is important because it allows:
- **Continuous Operations**: Dynamic CEP eliminates the need for restating applications or downtime when updating rules, ensuring that real-time insights are uninterrupted.
- **Instant Adaptability**: Business rules can be adjusted as conditions change, allowing teams to respond to events like weather disruptions or heightened security needs faster and without disrupting current workflows.
- **Scalable Efficiency**: Dynamic rule updates support long-term scalability, allowing airlines to fine-tune operations without the need to overhaul existing systems or workflows.
For example, if a new security policy reduces the unattended luggage threshold from 10 minutes to 5 minutes, Dynamic CEP makes it possible to implement this change immediately. In a traditional setup, such changes might require downtime and testing, but with Dynamic CEP, updates happen in real-time, keeping operations seamless and efficient.
## Conclusion
Complex Event Processing offers a scalable, real-time solution to many of the challenges facing the airline industry. By enabling immediate insights into flight delays, security incidents, and ground operations, (in addition to various other use cases) CEP empowers airlines to optimize performance, drive cost savings, reduce risks, and deliver a better user experience for all passengers.
CEP provides a turnkey library that transforms operations by providing the tools needed to detect, analyze, and act on real-time insights. Dynamic CEP, available exclusively in Ververica’s [Unified Streaming Data Platform](https://www.ververica.com/product), powered by the [VERA engine](https://www.ververica.com/vera), takes this one step further by allowing rules to be updated on the fly, ensuring applications remain responsive to changing conditions without downtime.
## Learn More about CEP
[[Video]](https://www.youtube.com/watch?v=xugLuycUyKM) Watch the video: Understanding Complex Event Processing with Applications in E-Commerce Platforms for examples of how CEP correlates data into actionable insight, including:
- Cross-sell and upsell opportunities
- High value card abandonment detection
- Purchase intent scoring
- Price sensitivity detection
- Churn prediction
## Related Resources
[[Case Study]](https://www.ververica.com/case-study/airbus) Download: How Ververica Transformed Real-Time Intelligence at Airbus to learn how Ververica helps Airbus to deploy Apache Flink at scale.
[[Demo]](https://github.com/ververica/airlines-cep-demo) Try out CEP for yourself! Create a real-time streaming application using CEP and Apache Flink that:
- Detects flight delays correlated with adverse weather conditions.
- Monitors and escalates security incidents (e.g., unattended luggage).
- Analyzes aircraft turnaround times to optimize ground operations.
Ready to utilize Dynamic CEP to make updates to your rule set without downtime? [Contact](https://www.ververica.com/contact) Ververica to get started.
---
---
title: "Ververica’s Unified Streaming Data Platform Now Available on AWS Marketplace"
description: "Ververica's Unified Streaming Data Platform is now on AWS Marketplace, simplifying deployment and enhancing real-time data processing with powerful integration and scalability."
lastUpdated: 2026-04-30T13:13:45.000Z
source_url:
html: "https://www.ververica.com/blog/ververicas-unified-streaming-data-platform-now-available-on-aws"
md: "https://www.ververica.com/blog/ververicas-unified-streaming-data-platform-now-available-on-aws.md"
---
We’re thrilled to announce that Ververica’s Unified Streaming Data Platform is now available on the AWS Marketplace. This means you can now effortlessly take into use our fully managed, cloud-native service right within your existing AWS account, and enjoy the advantages of centralized billing by leveraging your existing AWS payment and billing mechanisms. With this new self-service option, you’ll be up and running, processing streaming data at lightning speeds in just a few clicks.
## Deployment made simple
Let's be real: setting up streaming applications can be complex. We have heard your pain, and we've worked on making our platform available through the AWS Marketplace. No more time wasted wrestling with complex infrastructure, setup or complex billing.
Ververica’s Unified Streaming Data Platform offers a single-pane-of-glass UI that simplifies the development, deployment and operations of streaming and Flink ML applications. Whether you're using SQL, Java, or Python, our solution lets you deploy applications quickly without getting bogged down by infrastructure complexities. It’s seamless, efficient, and designed with you in mind.
## All the power of VERA, seamlessly integrated with your existing AWS footprint
In the world of real-time data, every millisecond counts: high-performance applications mean the difference between catching a fraudulent transaction before it goes through, detecting a critical system anomaly before it causes downtime, or making a split-second business decision that could save or earn millions. With our Ververica Runtime Assembly (VERA), you can achieve performance that’s up to 2x faster than open-source Apache Flink®. Imagine processing hundreds of millions—or even billions—of transactions per second, with data processing delays reduced to mere milliseconds. And the best part? You can seamlessly integrate this power with your existing AWS services. Connectors for popular services like Amazon Kinesis, MySQL, PostgreSQL and Apache Kafka; as well as catalog creation for Apache Kafka, MySQL and Apache Paimon are available out of the box. It’s like giving your streaming applications a supercharged engine within the AWS ecosystem you already know and love.
## Enhanced scalability and cost-efficiency
Scaling your applications shouldn’t break the bank or give you a headache. By leveraging AWS’s infrastructure alongside Ververica’s powerful solution, you can handle large volumes of streaming data in real-time without hefty upfront costs. Our solution offers enterprise-level performance that grows with your business needs, giving you the flexibility to adjust resources on the fly. Plus, with features like automatic fault recovery, you can keep your applications running smoothly without constantly worrying about uptime.
Accessing our platform through the AWS Marketplace doesn’t just make deployment easier—it also brings significant cost and speed benefits. You can leverage your existing AWS credits and discounts, simplifying your budget management. There’s no need to navigate lengthy procurement cycles or deal with separate contracts and renewals; everything is seamlessly integrated within your AWS account. This means you can self-service your needs and get started faster without administrative hurdles, allowing you to focus on building and scaling your streaming applications while keeping costs in check.
## Data governance & security
We understand that security and data governance are paramount for our customers. That’s why Ververica’s Unified Streaming Data Platform offers robust features like private connections to the cloud services of your choice and role-based access control for granular control of your resources and your data. You can also benefit from isolated workspaces to separate your production and testing environments, ensuring your data remains secure and well-organized. It’s all about giving you peace of mind while you innovate.
## Get started today
We couldn’t be more excited to bring you this powerful combination of Ververica’s Unified Streaming Data Platform and AWS’s robust service offering. So why wait? Head over to the AWS Marketplace today to take our platform into use and take your real-time data processing to the next level. We can’t wait to see what you’ll build!
---
---
title: "Introducing Fluss: Unified Streaming Storage For Next-Generation Data Analytics"
description: "Discover Fluss, a revolutionary unified streaming storage solution designed for real-time data analytics with Apache Flink, enhancing performance and simplifying processes."
lastUpdated: 2026-04-30T13:39:24.000Z
source_url:
html: "https://www.ververica.com/blog/introducing-fluss"
md: "https://www.ververica.com/blog/introducing-fluss.md"
---
We are excited to introduce Fluss, a groundbreaking project designed to tackle longstanding challenges in streaming data storage and analytics. Named after the German word for 'river,' Fluss is engineered to offer a high-performance, scalable, and fully integrated solution for real-time data processing with Apache Flink®, driving our vision towards a complete unified batch and streaming data platform.
## Streaming Storage for Next-Generation Data Analytics
Apache Flink has become the de facto standard for stream processing and Flink SQL has become an indispensable tool for users to build real-time applications. Typical application scenarios include data cleaning, feature engineering and extraction, transformations, multi-stream merging and joins, aggregations, and more. Flink is often deployed along with a streaming storage layer like Apache Kafka and combined with real-time OLAP systems, such as Clickhouse and StarRocks. This enables the creation of streaming-first architectures that treat all incoming data as unbounded streams, with the ability to process and analyze data as it arrives.
The following figure depicts a streaming-first architecture:
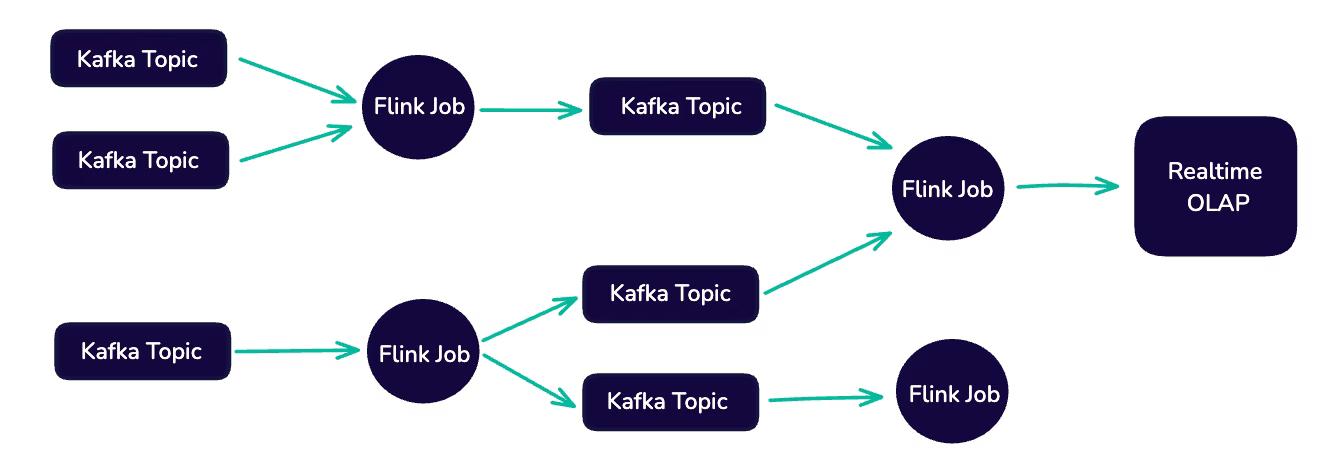
Apache Kafka plays a central role in such architectures by acting as the backbone for storing and transporting real-time data. It can capture events from multiple sources—applications, sensors, and databases—and stream them in real time to consumers, like analytics platforms, microservices, or machine learning models. Kafka's high throughput, fault tolerance, and scalability make it a popular choice for building large-scale, real-time data pipelines.
On top of Kafka, Apache Flink provides a powerful framework for real-time data processing. Flink’s stream-first architecture allows it to handle continuous data flows, making it an excellent choice for event-driven applications that require sub-second latency. Flink’s support for stateful computations, windowing, and exactly-once processing semantics allows for complex operations such as event-time processing and real-time aggregations.
These capabilities have fueled the adoption of streaming-first architectures, allowing companies to develop solutions for real-time fraud detection, personalized recommendations, monitoring systems, and more.
## The Need for Unified Streaming Storage
Although Apache Kafka has excelled as a row-oriented, log-based storage layer, it falls short in certain key areas, especially regarding real-time data analytics. Log-based storage falls short in the following areas:
- **Handling Upserts Efficiently:** Upserts (Updates and Inserts) are common when working with streaming systems. Kafka doesn’t natively support upserts in the way that stream processors like Flink require. Apache Flink needs to generate changelogs to track updates, which can introduce latency and complexity to ensure state consistency. This results in issues with result correctness, incomplete semantics (PK semantics can not be completely aligned), and slower processing times, particularly for large-scale or high-throughput systems.
- **No Direct Query Capabilities**: Kafka lacks direct query support, meaning users can’t easily access or extract insights from streaming data without building additional infrastructure layers like stream processors or data stores. This adds complexity and delays in accessing real-time insights as it requires moving the data to an external system, such as a data warehouse or a data lake, to perform complex queries and analytics. Revisiting Image 1, notice that the main reason for the intermediate Kafka topics is to store intermediate results without actual business value, resulting in unnecessary storage amplifications as they can’t be reused.
- **Historical Data Processing**: To perform historical analysis, Kafka users must replay entire logs, which is not only time-consuming but also computationally expensive. This approach creates a bottleneck for companies that need to analyze large volumes of past data quickly and efficiently.
- **Debugging Challenges**: Debugging issues within Kafka is cumbersome due to its log-based architecture. Users often have to sift through large logs without the ability to directly query and inspect the data, making troubleshooting inefficient and costly.
- **High Network Costs and Bottlenecks**: Kafka’s architecture often requires heavy data movement across networks, leading to significant infrastructure costs and performance bottlenecks, especially when scaling for real-time analytics.
Apache Flink’s strength lies in real-time data processing, and it's often paired with Online Analytical Processing (OLAP) systems for deep-dive analysis of aggregated data. However, OLAP introduces its challenges in the architecture, particularly when considering storage costs. OLAP systems are designed to enable fast, multidimensional queries over large datasets, which are particularly useful for reporting, dashboards, and business intelligence use cases. However, this capability comes at a cost—literally.
Apache Flink uses RocksDB to store state, but it lacks a streaming storage layer to provide a database-level experience. Flink needs to stitch multiple upstream and downstream storage components, which increases the complexity of the system and affects the experience (some systems support upserts and some don’t, and primary key constraints are easily broken). There are a lot of variations between different storage layers, and behaviors vary greatly, leading to problems of not knowing what to choose. What is missing is a streaming storage layer that resembles a data warehouse while being native to Flink.
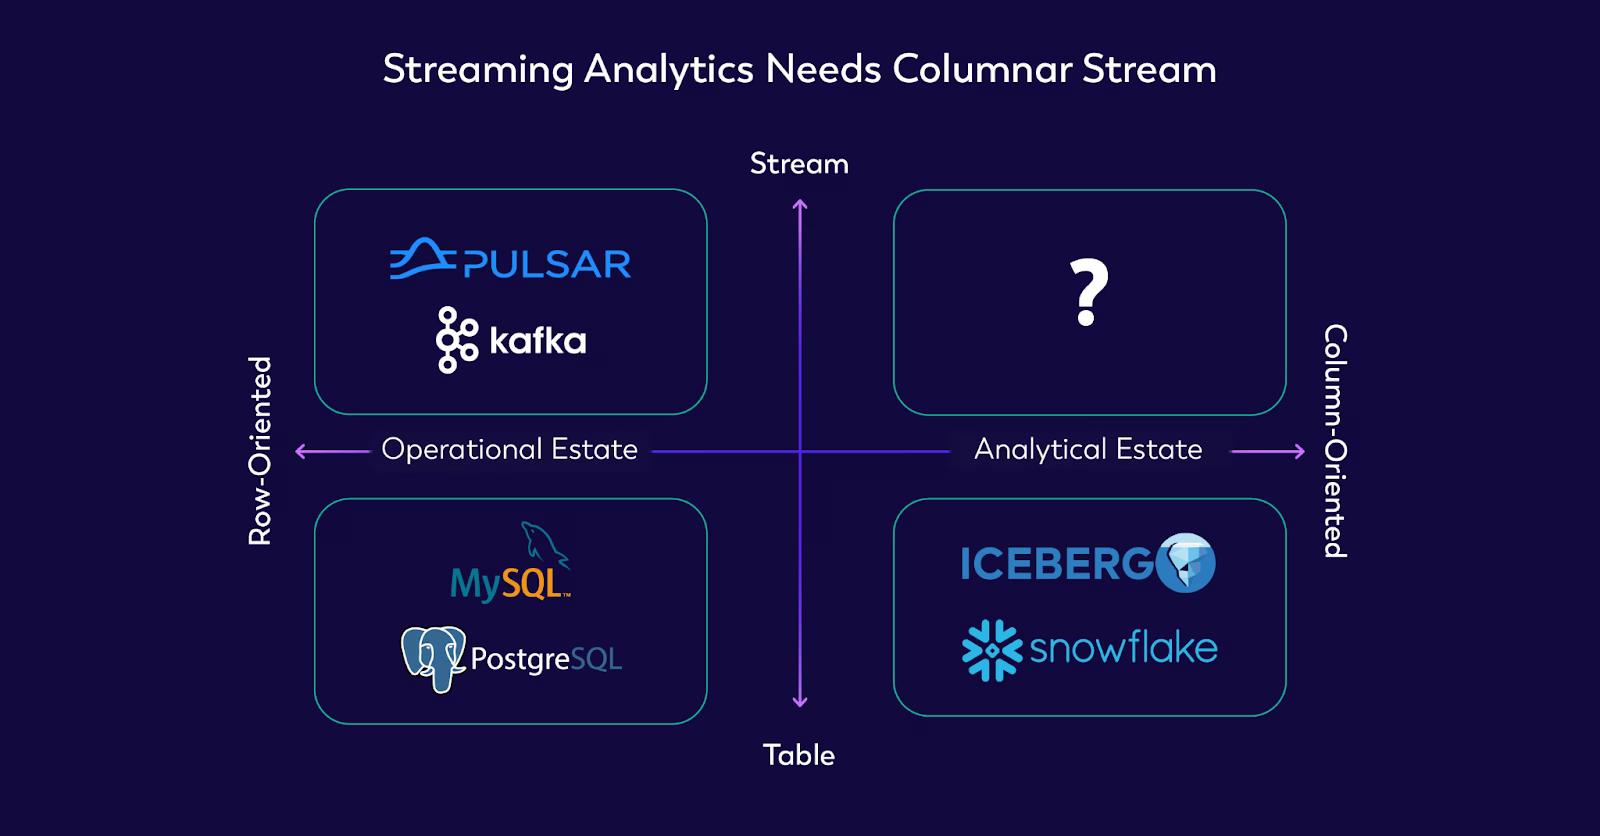
It is difficult to transform existing streaming solutions to fit these needs, so we developed a streaming storage designed for real-time analytics. This started the development of Fluss, a purpose-built storage layer optimized for modern stream processing needs.
## Introducing Fluss
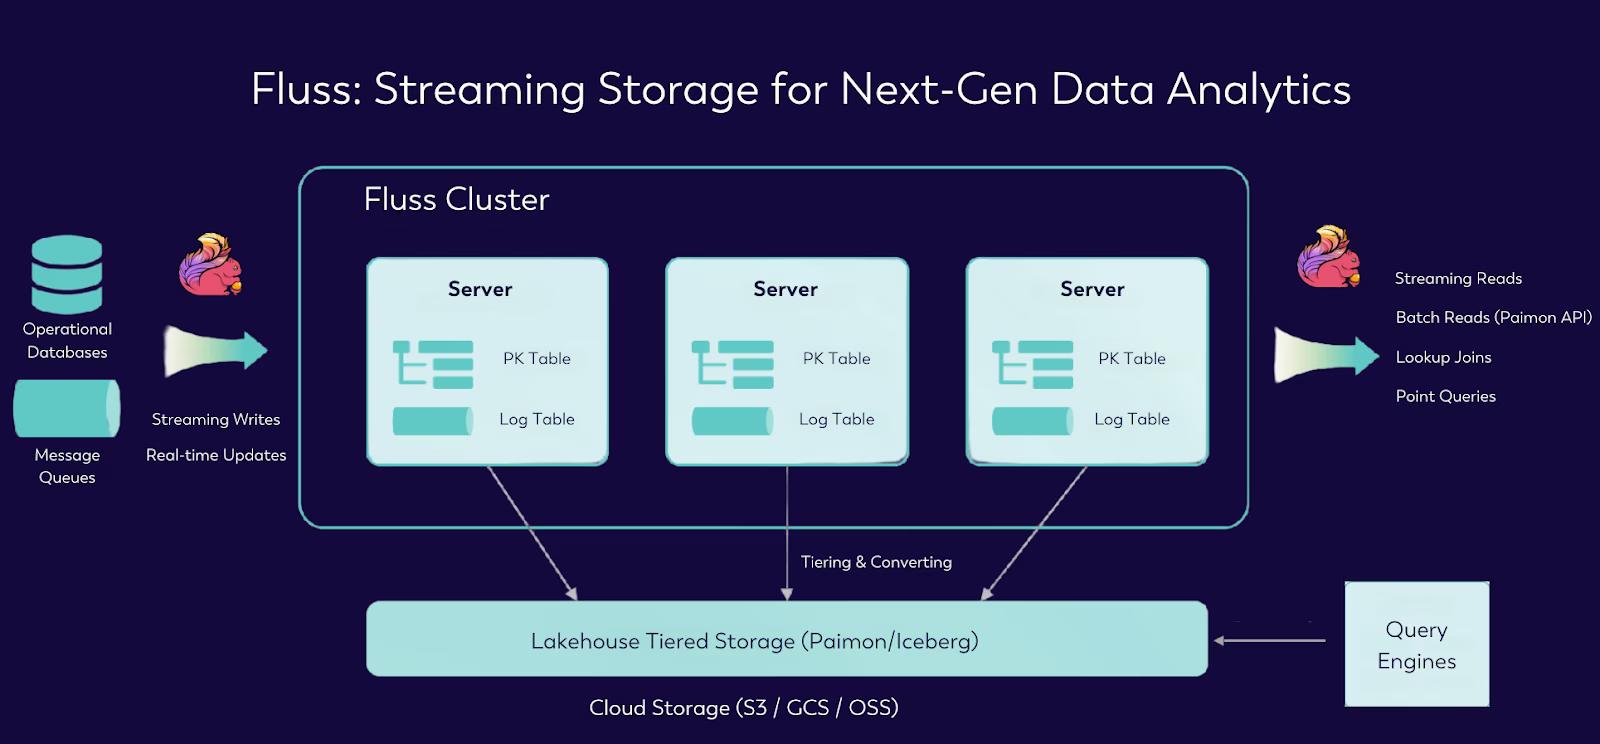
Fluss is designed to provide a unified streaming storage layer that addresses these specific limitations head-on. The key features and benefits of Fluss in the world of streaming data analytics include:
- **Sub-Second Latency:** Fluss ensures sub-second latency streaming reads and writes, enabling immediate read and write operations for fast, actionable insights. Ideal for time-sensitive applications like monitoring and financial platforms, it delivers data as soon as it's ingested.
- **Updates and Changelogs - Stream-Table Duality:** Fluss supports **stream-table duality**, allowing efficient updates with comprehensive changelogs. This ensures consistent data flow, providing full visibility into stream changes for accurate real-time and historical insights within the same system.
- **Ad-hoc, Interactive Queries:** Fluss is fully queryable, enabling direct data inspection without extra processing layers. This reduces development complexity, simplifies debugging, and allows for immediate access to live data insights.
- **Unified Batch and Stream:** Fluss offers a **unified platform** for batch and streaming data, enabling efficient historical processing alongside live streams. This seamless integration optimizes infrastructure for AI, ML, and analytics workloads.
- **Projection Pushdown:** Fluss uses **projection pushdown** to optimize streaming reads, fetching only the necessary fields for queries. This reduces data transfer, improving performance up to 10x and lowering network costs.
- **Columnar Streaming Reads:** With **columnar streaming reads**, Fluss enhances performance by storing data in a columnar format. This improves compression and speeds up analytics, making it perfect for data-heavy, real-time applications.
It also provides lakehouse tiered storage such as [Apache Paimon](https://paimon.apache.org/) and [Apache Iceberg](https://iceberg.apache.org/), allowing bi-directional communication with lakehouses. This allows a streaming job to load state from batch sources, enabling seamless state initialization and synchronization between batch and streaming data.
Fluss has been running in production for the last few months. It will be open-sourced and donated to the [Apache Software Foundation](https://www.apache.org/) (ASF) at the end of the year.
## The Future of Real-Time Data Analytics
In the age of AI and machine learning, where data must be both accessible and immediately actionable, Ververica provides a solution for businesses looking to harness real-time and historical data together. Whether you're building advanced analytics pipelines, monitoring real-time events, or implementing AI-driven insights, Ververica’s Streaming Data Platform provides the flexibility, speed, and efficiency you need to succeed.
We hope that the idea of streaming storage for Apache Flink that can be shared across multiple systems holds the potential to significantly reshape the landscape of real-time data processing and analytics. By integrating a native, purpose-built storage system within Flink, organizations can achieve a unified architecture that seamlessly supports both real-time and long-term data processing. This would eliminate the current need for intermediate Kafka topics or separate stream processing tools, simplifying data pipelines and reducing operational complexity.
## More Resources
Ready to learn more? [Watch "Optimizing Streaming Analytics with Apache Flink and Fluss](https://www.youtube.com/watch?v=GKsE_EUR9yU)" for an introduction to Fluss, the next evolution of streaming storage built for real-time analytics.
- Get started unlocking the full power of Apache Flink with Veverica’s Streaming Data Platform by [contacting us](https://www.ververica.com/contact).
- Learn more about [VERA,](https://www.ververica.com/blog/vera-from-steam-to-stream) the engine powering Ververica's Streaming Data Platform, in a 3-part blog series.
- [Explore](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse) Apache Paimon: The Streaming Lakehouse
---
---
title: "Embracing the Future with Apache Flink® 2.0"
description: "Ververica celebrates the transformative Apache Flink 2.0 features which unifies batch & stream processing and sets new standards in realtime data analytics"
lastUpdated: 2026-05-01T07:03:26.000Z
source_url:
html: "https://www.ververica.com/blog/embracing-the-future-apache-flink-2-0"
md: "https://www.ververica.com/blog/embracing-the-future-apache-flink-2-0.md"
---
The [Apache Flink](https://www.ververica.com/ecosystem-introduction/what-is-apache-flink)® community has just unveiled the preview release of Apache Flink 2.0, marking a pivotal moment in the evolution of data processing. This isn't just another update; it's a bold leap toward fulfilling the true promise of a unified batch and stream processing engine. At Ververica, we're thrilled about this release, as it aligns with our vision and the work we've been doing to push the boundaries of real-time data processing.
## Modernizing Legacy to Meet Today's Demands
Over the years, Apache Flink has been a powerhouse in stream processing. But let's face it—the data landscape has changed dramatically. **The lines between batch and stream processing have blurred, and the need for a seamless, unified engine is more critical than ever.** Flink 2.0 addresses this head-on by modernizing legacy components and introducing features that combine batch and stream processing together like never before.
One significant change is the removal of outdated APIs, such as the DataSet API and the Scala versions of the DataStream and DataSet APIs. While some may see this as a hurdle, it's a stride towards simplifying development and maintenance. By encouraging users to adopt the more versatile DataStream API and Table API/SQL, Flink is streamlining the development experience and paving the way for future innovations.
In addition, many users are migrating their code from Scala to Java or SQL. This trend isn't just in Flink; other open-source projects like Apache Kafka are also moving towards Java. Whether this is a welcome change could be debated, but one thing is clear: it allows for a larger community of contributors and makes the technology more accessible.
## Apache Paimon Nears Version 1.0: Building the Streaming Lakehouse
Alongside Flink's evolution, [Apache Paimon](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse) is gearing up for its 1.0 release. Paimon plays a pivotal role in realizing the streaming lakehouse concept which is a modern, unified architecture that combines the best of data lakes and data warehouses for real-time analytics.
The integration of Flink and Paimon brings significant SQL optimizations, making it easier to build and manage streaming lakehouses. This is a huge milestone. It means we can handle dynamic data updates and queries with varying levels of freshness, catering to a wide range of analytical needs. **Whether you need data refreshed to the day or the second, this integration has you covered.**
Table formats like Paimon have distinct advantages over alternatives like Iceberg and Hudi, especially regarding real-time data. The enhanced integration in Flink 2.0 means better performance, more efficient resource usage, and the ability to handle larger datasets with ease.
## Disaggregated State Storage: Bigger, Faster, More Flexible
One of the most exciting features in Flink 2.0 is the introduction of disaggregated state storage and management. This is a game-changer. **Flink decouples compute and storage resources by using Distributed File Systems (DFS) as the primary storage.** Here's what that means:
- **Scalability**: You can now handle massive datasets—including those with hundreds of terabytes—without worrying about local disk constraints.
- **Flexibility**: Jobs can be rescaled faster and more efficiently, adapting to changing workloads without a hitch.
- **Performance**: By utilizing asynchronous execution models, resource spikes are reduced, and checkpoint optimization ensures a smoother experience.
At Ververica, we've been championing disaggregated state storage in our engine for some time. Seeing these concepts being adopted in Flink 2.0 is not just validating, it's exhilarating. It means we're all moving in the right direction together, and the future of data processing is looking brighter than ever.
## Trends from Flink 1.20 to 2.0: A Rapid Evolution
If we look back at Flink's 1.20 release, it's clear that the groundwork was being laid for these significant changes. Materialized Tables were introduced as an MVP feature, and now in 2.0, they're getting the enhancements needed for production-ready use.
Adaptive Batch Execution is another feature in 1.20 that's advanced in 2.0. By dynamically optimizing logical and physical plans based on execution insights, Flink is unlocking its full potential in batch processing and OLAP workloads.
What's remarkable is how quickly these advancements are happening. **The time between the 1.20 and 2.0 releases is shrinking, reflecting the growing momentum and interest in Flink.** It's a testament to the community's dedication and the increasing demand for powerful, efficient data processing tools.
## The Data Processing Boom: OLAP and Beyond
We're in the midst of an explosion of data processing tools, especially with Online Analytical Processing (OLAP). **Businesses are hungry for faster insights from ever-growing datasets, and tools that can handle both real-time and historical data efficiently are in high demand.**
Flink's enhancements in OLAP capabilities position it as a leader in this space. The need for data is skyrocketing, but so is the need for efficiency. Modern use cases demand more data and faster processing, without breaking the bank on resources.
## The Impact of Large Language Models: More Data, More Demands
Let's talk about the elephant in the room: Large Language Models (LLMs) and other data-hungry applications. These tools are incredible, but they require vast amounts of data to train and operate effectively. **In turn, this mandates the need to support hybrid workloads that can handle both batch and streaming data seamlessly.**
Flink 2.0 rises to this challenge. Its unified approach and support for hybrid workloads make it an invaluable tool in an era where new applications demand more data and more sophisticated processing capabilities.
If there's one thing we've learned, it's that new tools merely require more data—nothing else.
## Conclusion: Embracing the Future with Flink 2.0
Apache Flink 2.0 isn't just a step forward; it's a leap into the future of data processing. **By modernizing its legacy components, embracing disaggregated state storage, and enhancing integrations with projects like Apache Paimon, Flink is setting new standards for what's possible.**
At Ververica, we see Flink 2.0 as a crystallization of much of the work we've been doing. It's a realization of our efforts to simplify data engineering workflows, enhance scalability, and meet the evolving needs of data-driven applications. We're excited to support Flink 2.0 for our customers and to integrate its powerful features into our offerings.
As the demand for data continues to grow, (and let's be honest, it's certainly not slowing down) the importance of efficient, scalable, and unified data processing can't be overstated. Flink 2.0 is a significant step towards meeting these challenges head-on.
The future is here, and it's streaming in real-time. Let's embrace it together!
> **NOTE:** This blog post is inspired by the Apache Flink 2.0 preview release notes and reflects the perspectives of Ververica, the original creators of Flink, who continue to contribute to Flinks development.
## More Resources
### Upgrade Notes
The Flink community tries to ensure that upgrades are as seamless as possible. However, certain changes may require users to make adjustments to certain parts of the program when upgrading to version 2.0. Please refer to the release notes for a comprehensive list of adjustments to make and issues to check during the upgrading process.
### Getting Started with Flink
- Get started with [Veverica's Unified Streaming Data Platform](https://www.ververica.com/product/deployment/cloud) and unlock the full power of Apache Flink as a managed service.
- Apache Flink is available for [download](https://nightlies.apache.org/flink/flink-docs-stable/docs/try-flink/local_installation/).
- For additional information on the release of 2.0, check out [The Apache Flink Site.](https://flink.apache.org/posts/)
### Get Involved
The vitality of Flink relies on continued community growth, which would not be possible without each and every contributor to the project. The Flink community welcomes contributions from anyone with a passion for open source, messaging and streaming! Looking for more ways to stay connected with the Flink community? Check out the following resources:
- Ready to start contributing to the project? Start with the [Apache Flink Contributors guide](https://flink.apache.org/how-to-contribute/overview/).
- Follow [@ApacheFlink](https://x.com/ApacheFlink) on Twitter/X , and join the Flink community on [Slack](http://apache-flink.slack.com/).
### Thank You!
It would be remiss not to thank the many contributors to the project and development of Apache Flink 2.0, in particular:
- Disaggregated State: Dr. Yuan Mei
- MT: Lincoln Li and Xintong Song
- Apache Paimon: Jingsong Li
- New APIs and async state APIs: Jark Wu and Team
Ververica offers our congratulations and thanks to all Apache Flink contributors!
---
---
title: "Introducing Ververica's Bring Your Own Cloud Deployment Offering"
description: "Introducing Ververica's new Bring Your Own Cloud (BYOC) deployment, which allows full control over your infrastructure and seamless integration with AWS."
lastUpdated: 2026-05-01T07:15:52.000Z
source_url:
html: "https://www.ververica.com/blog/introducing-byoc-deployment"
md: "https://www.ververica.com/blog/introducing-byoc-deployment.md"
---
We are excited to introduce a powerful new deployment option for Ververica's Streaming Data Platform: **Bring Your Own Cloud (BYOC)**. This deployment provides a managed experience that uses your existing cloud resources to leverage the flexibility and scalability of Ververica’s Streaming Data Platform while maintaining full control over your cloud infrastructure.
At launch, our BYOC deployment will offer a seamless integration with [AWS infrastructure](https://aws.amazon.com/marketplace/pp/prodview-luvmqd6leha4i), and will later expand to include other major cloud providers like Google Cloud and Microsoft Azure.
## Why Bring Your Own Cloud?
As the demand for scalable, real-time data streaming grows, companies increasingly need solutions that are not only highly performant, but that also integrate with their existing infrastructure. Ververica’s BYOC deployment harnesses the full capabilities of our Streaming Data Platform that is powered by the [VERA engine](https://www.ververica.com/product/vera). Built on and 100% compatible with Apache Flink®, Ververica allows you to solve both batch and real-time streaming use cases, while leveraging the security of your existing cloud environment. While some vendors have built cloud functionalities through acquisitions and mergers, Ververica’s BYOC deployment option was engineered and developed entirely in-house, by the original creators of Apache Flink.
## Zero-Trust at the Core: Bring Your Own Cloud with Ververica
As security threats continue to evolve, adopting a zero trust security¹ strategy has become essential for organizations aiming to protect their data and infrastructure. [Gartner reports](https://www.gartner.com/en/cybersecurity/topics/zero-trust-architecture) that more than 50% of organizations are moving toward a zero trust model. Ververica’s Bring Your Own Cloud deployment provides an effective solution that aligns with zero trust principles. With BYOC, you retain absolute data sovereignty, as your data is stored in object storage and hosted on a cloud environment fully controlled by your organization, ensuring full oversight and security.
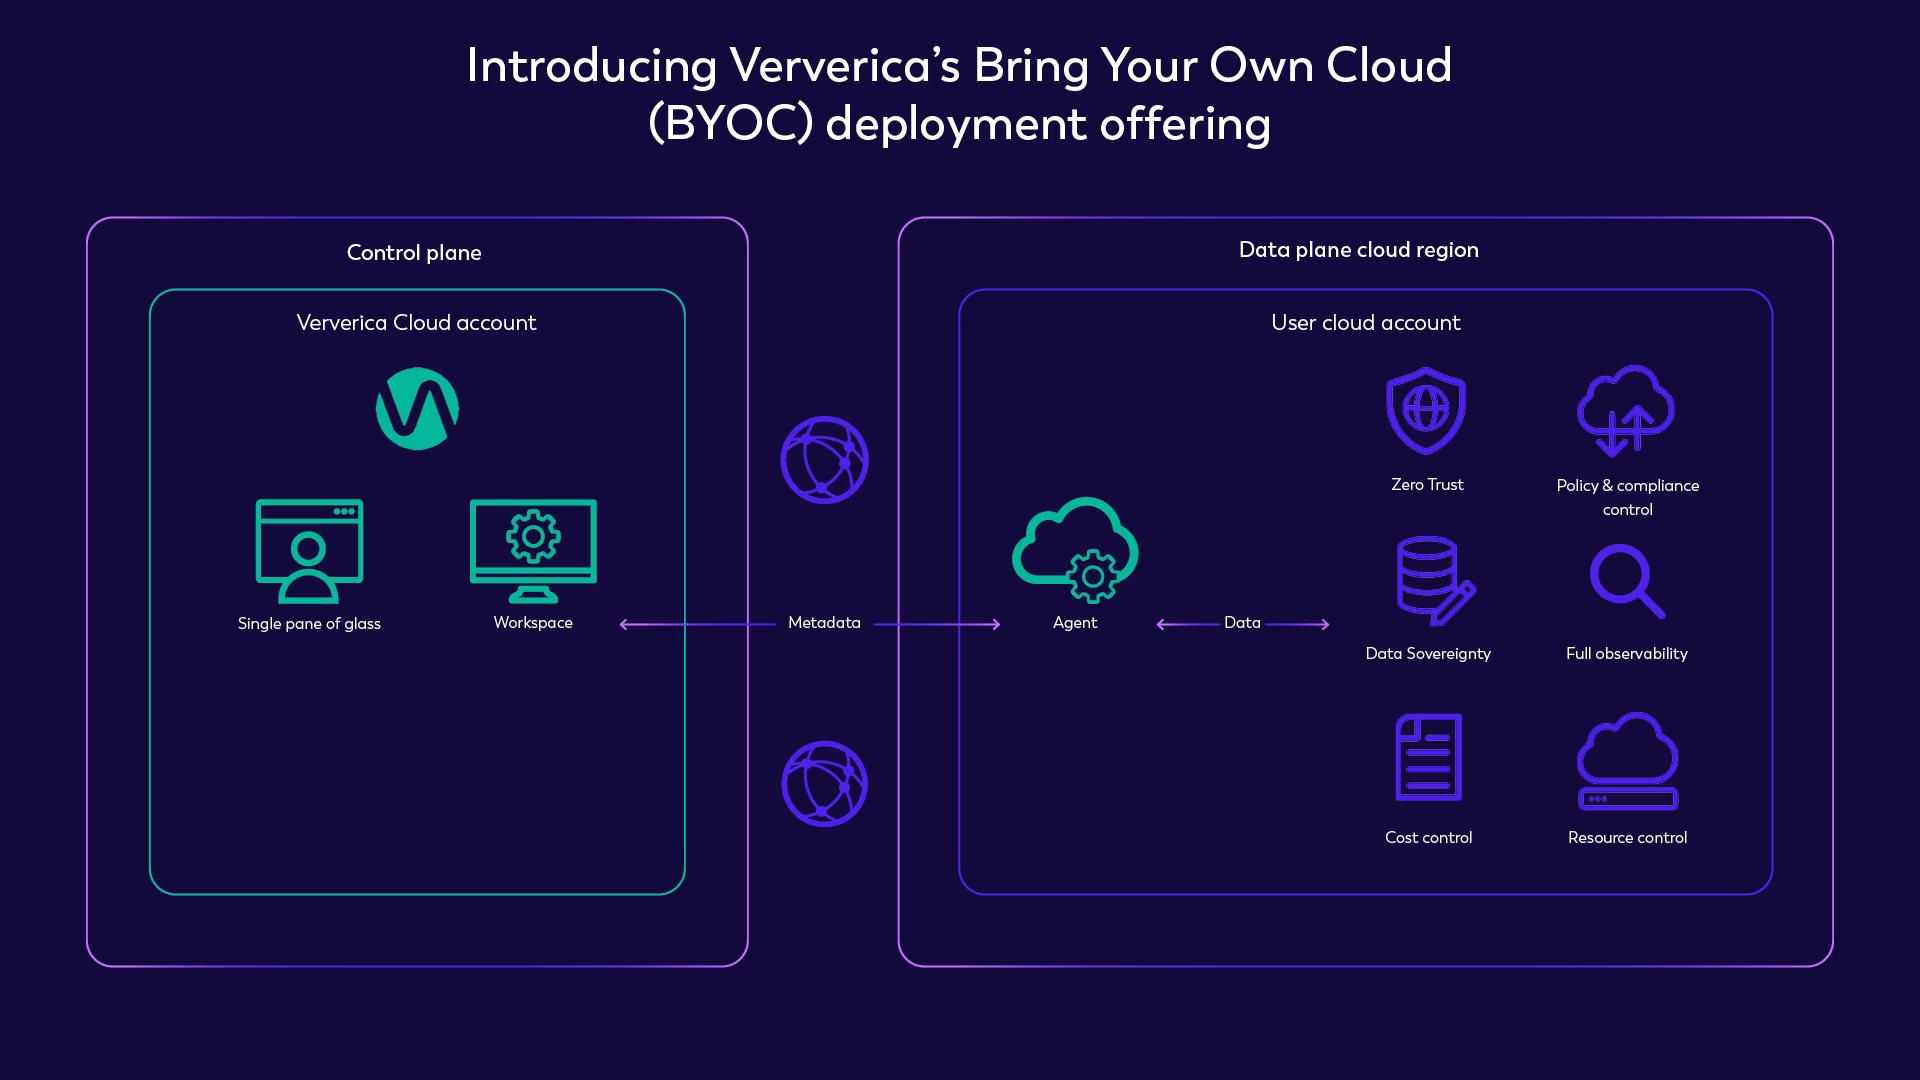
## Benefits of BYOC
- **Maintain Full Control Over Your Cloud Infrastructure**BYOC gives you the power to configure, monitor, and scale your infrastructure exactly how you need it, ensuring your specific security and compliance requirements are met. You choose the cloud provider (AWS at launch, GCP and Azure added soon), the regions, and the resources that fit your business.
- **Seamless Integration with Your Existing Tech Stack** When launched, you can deploy Ververica’s Streaming Data Platform on AWS, (shortly to include GCP and Azure,) and integrate with your existing DevOps, CI/CD pipelines, and other critical tools. This means less downtime, faster implementations, and more efficient operations.
- **Optimized for Real-Time and Batch Processing**Whether you're handling real-time data streams or batch workloads, Ververica’s BYOC deployment provides the flexibility to seamlessly scale up or down based on your operational needs. This allows you to access an ultra-high performance streaming data solution while maintaining cost-efficiency, and without compromising on your cloud strategy.
- **Security and Governance**With BYOC, your data remains in your cloud, giving you complete control over security, data governance, and compliance. For industries like healthcare, finance, or any other highly regulated or sensitive business, you can rest assured that your data is handled with complete compliance to your internal policies.
- **Cost Optimization**
Customers can leverage their preferential pricing and existing spend commitments with cloud providers by buying the Ververica Streaming Data Platform through cloud marketplaces like the [AWS marketplace](https://aws.amazon.com/marketplace/pp/prodview-luvmqd6leha4i). Ververica’s usage-based pricing ensures that you only pay for what you use, and that your streaming infrastructure adapts elastically to what your business needs.
## Who Should Consider BYOC?
Ververica’s BYOC deployment is ideal for enterprises that:
- Want to retain full control over their cloud infrastructure.
- Prefer or require full observability of their data.
- Have specific security, governance, or compliance needs.
- Use multi-cloud or hybrid cloud architectures.
- Have preferential pricing or spend commitments with cloud providers.
- Need a flexible, scalable solution for real-time stream processing.
- Want to utilize VERA, the engine revolutionizing Apache Flink for their streaming and batch processing projects, and will benefit from a managed Flink offering within their own cloud environment.
## How BYOC Works
Ververica’s BYOC offering is simple to set up and manage. After selecting your preferred cloud provider, you can deploy Ververica’s Streaming Data Platform with just a few clicks. Our dedicated customer support will guide you through the process, ensuring that your deployment is up and running smoothly.
From there, you can start leveraging Ververica’s Streaming Data Platform’s unparalleled streaming capabilities, allowing your teams to build, deploy, and manage stream processing applications with ease at any scale, all within your own cloud environment.
## What's Next?
At Ververica, we’re committed to empowering your streaming data projects with our Streaming Data Platform that provides a better-than Open Source Apache Flink experience, with speeds up to 2x faster than OS Flink. Our soon-to-be available BYOC deployment offering is just one of many steps we're taking to ensure that your stream processing solutions are as flexible, powerful, and secure as possible.
For more information on how you can get started with Ververica’s Streaming Data Platform, please [contact us](https://www.ververica.com/contact). Unsure of which deployment is right for you? [We can help.](https://www.ververica.com/contact)
## More Resources
- Learn more about the different deployment options available for Veverica’s Streaming Data Platform, and get started with [Veverica](https://www.ververica.com/product/deployment/self-managed) to unlock the full power of Apache Flink as a managed service.
- Learn more about [VERA,](https://www.ververica.com/blog/vera-from-steam-to-stream) the engine powering Ververica's Streaming Data Platform, in a 3-part blog series.
---
---
title: "The Streamhouse Evolution"
description: ""
lastUpdated: 2026-05-01T07:26:44.000Z
source_url:
html: "https://www.ververica.com/blog/streamhouse-evolution"
md: "https://www.ververica.com/blog/streamhouse-evolution.md"
---
## A Glimpse Into the House of Streams
In addition to being the heart of Ververica’s Streaming Data Platform, Apache Flink® has been the de facto gold standard for stream processing. Throughout the years, Ververica’s Streaming Data Platform has been deployed in production workloads with impressive scalability, including sustaining processing peaks of up to 7 billion events per second. The need to provide this kind of scalability means we continuously push to make our solutions more performant and cost-efficient.
In the evolving landscape of data infrastructure, businesses are continuously striving to process and analyze vast amounts of data in real time while also retaining the ability to perform deep analytical queries on historical data. Traditionally, organizations have relied on separate architectures for batch and stream processing—batch systems to handle large-scale, offline data analysis, and streaming systems to process real-time data as it flows in. This separation often leads to complex, siloed architectures that are expensive to maintain and difficult to scale.
In this article, we will explore the need for a unified solution that not only delivers the flexibility of stream processing but also brings the robustness of batch analytics into one framework and how Ververica provides such a solution, which is ideal for organizations looking to build a modern, real-time analytical infrastructure.
## Current Status Quo of the Data Landscape
In today's rapidly evolving data landscape, two dominant paradigms shape the way organizations process and analyze data: **real-time streaming** architectures and **data lakehouses**. Both of these models offer unique advantages, but they also come with inherent trade-offs, leaving many organizations searching for an ideal middle ground.
### Real-Time Streaming
Real-time streaming architectures have transformed how businesses handle data by enabling the processing of events as they happen. This real-time approach is crucial for use cases such as fraud detection, pairing an AI chatbot, recommendation engines, online gaming, financial market updates, IoT devices, and monitoring, where low-latency insights are essential. However, the infrastructure required to support real-time systems can be expensive to maintain. The cost of ensuring fault tolerance, processing speed, and data consistency in high-throughput environments is significant, particularly when scaling to accommodate growing data volumes.
Such architectures are often built with Apache Flink and streaming storage layers like Apache Kafka. Streaming storage layers write, read, and store data at high speeds, making them an ideal combo for moving data in real-time (within seconds). However, despite their strength with low-latency streaming, this approach comes with a few drawbacks, including:
- Data is not directly queryable on these streaming storage layers and data reprocessing needs to replay a lot of data.
- These solutions require significant engineering knowledge, and are harder to learn and use for data professionals who might not be familiar with these systems.
- It’s difficult to find data errors and apply corrections.
- Real-time streaming solutions often come with high operational costs, as they require keeping data for longer durations, which can yield unnecessary networking and storage costs.
### The Data Lakehouse
On the other hand, the data lakehouse has emerged as a popular solution for handling batch processing and long-term data storage. Compared to the early data warehouses (like Hive), Lakehouse architecture is more than a simple batch solution that requires hour-to-day data delays. Instead, by combining the flexibility of data lakes with the reliability and performance of traditional data warehouses, lakehouses provide a cost-effective solution for managing and analyzing historical data. Their architecture is optimized for large-scale batch processing, which allows for efficient querying of historical data, but they fall short when it comes to delivering real-time insights. As a result, they are often not suited for applications requiring immediate decision-making based on live data streams.
Many users try to leverage Apache Flink in conjunction with a table format. At first, commodity storage was the solution of choice, but has been quickly supplanted by much cheaper cloud alternatives that offer high performance resilient data stores in order to offload data and create a Lakehouse. Compared with a real-time streaming solution, accessing cheap object storage when using a Lakehouse makes that data easily accessible for data professionals via various query engines. This approach also allows for better data transparency, creating a single “source of truth” for your data on the lake and allowing for integration with any query engine.
This creates a gap between the two paradigms. Real-time streaming offers immediate insights but is expensive and resource-intensive to maintain at scale. Data lakehouses provide a more economical approach but are focused on batch processing, limiting their ability to offer up-to-the-minute insights. For many organizations, this trade-off between cost and real-time capabilities presents a significant challenge, as neither solution fully addresses the need for both real-time and historical analysis in an integrated, efficient manner.
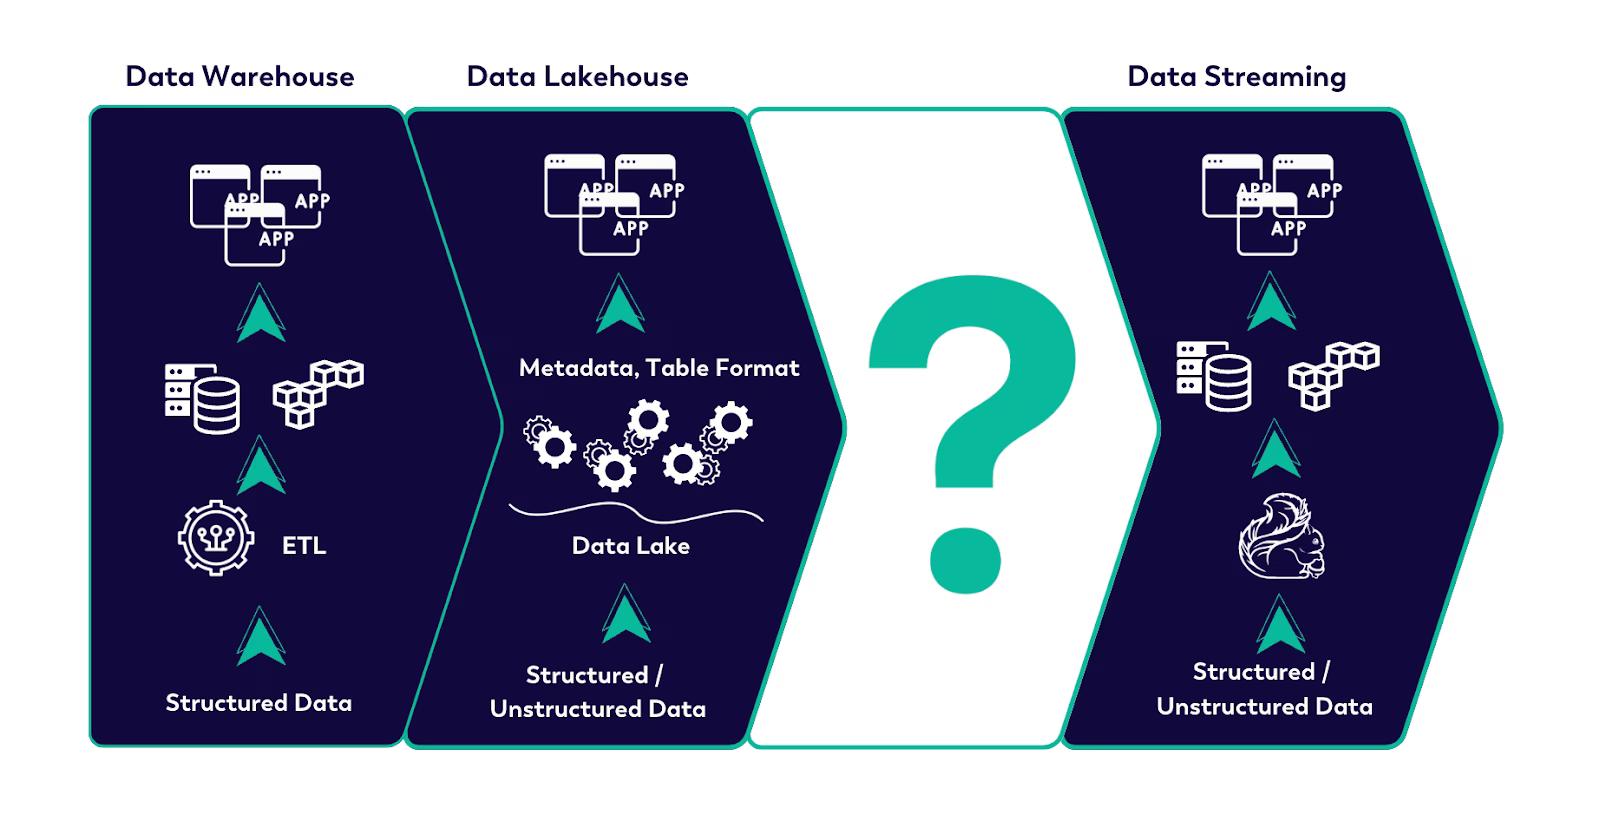
The lack of an intermediate solution has left businesses juggling complex, siloed systems to balance these needs. What is required is a solution that seamlessly unifies real-time and batch processing without compromising on performance or cost—allowing organizations to achieve real-time insights while also benefiting from cost-effective storage and long-term data analysis.
## Enter Ververica's Streamhouse
While enterprises today widely adopt Lakehouse capabilities, the increasing demand for real-time data processing and up-to-date data (data freshness) conflicts with the limitations of traditional Lakehouses. This increasing need for a solution that provides fast, fresh data, while remaining cost-effective and easy for engineers to implement, is likely driven by several factors, including:
- The recent explosion of machine learning (ML) and artificial intelligence (AI) workloads
- Increasingly strict requirements that demand high-throughput data ingestion
- Use cases that depend on low-latency data processing
- The need for high-performance, real-time queries
- The requirement for mutable data processing
Such requirements can be classified as a [Streaming Lakehouse](https://www.ververica.com/blog/building-real-time-data-views-with-streamhouse), which is more than just streaming ingestion.
Enter Ververica’s [Streamhouse](https://www.ververica.com/blog/streamhouse-unveiled), a groundbreaking approach that unifies batch and stream processing into a single, cohesive solution. Built on the powerful Apache Flink engine, Streamhouse bridges the gap between real-time data processing and historical batch analytics. It offers a seamless way to ingest, process, and analyze both streams of real-time data and large datasets with low latency, providing businesses with a holistic, unified analytical platform. By simplifying the architecture and eliminating the need for separate systems, Streamhouse enables organizations to derive insights faster and more cost-effectively, paving the way for a more integrated, scalable, and efficient data-driven future.
With Streamhouse, organizations can now achieve real-time insights and long-term analytical capabilities in one cohesive platform, powered by Apache Flink’s robust, scalable engine. This convergence reduces operational complexity, cuts down infrastructure costs, and empowers businesses to harness the full potential of their data—whether it’s streaming in real time or being queried from a vast historical dataset. As data continues to play an increasingly critical role in decision-making, Ververica’s Streamhouse represents a critical step forward in modern data architecture, offering a flexible, scalable, and integrated approach for organizations seeking to remain competitive in a data-driven world.
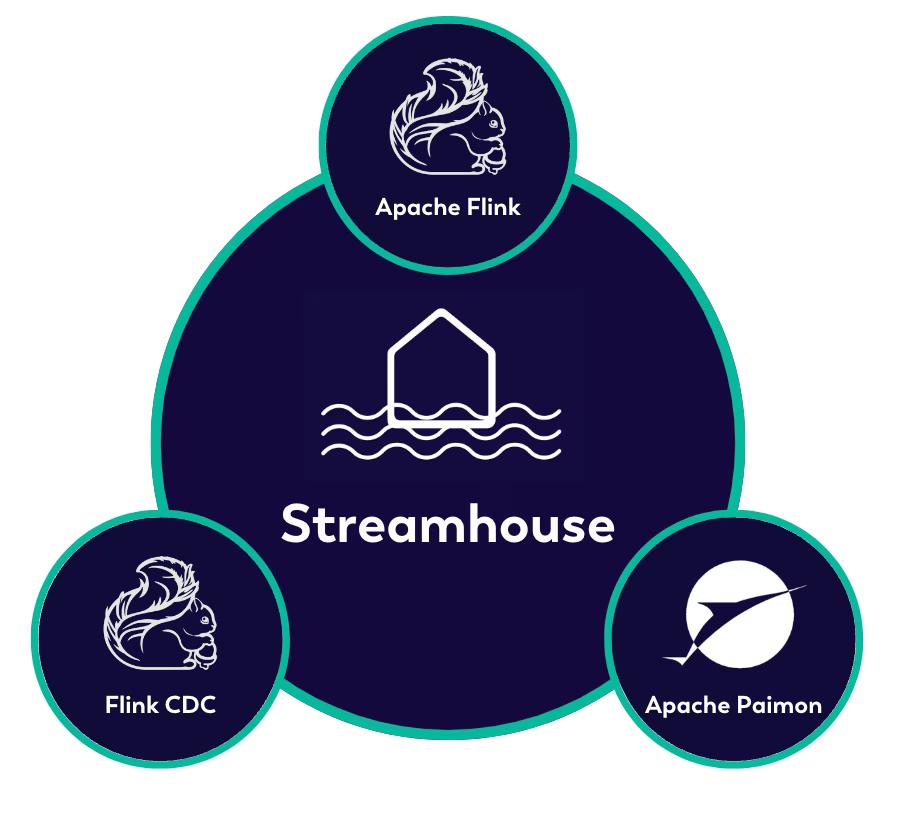
Streamhouse is powered by three open-source projects:
- **Apache Flink CDC** handles Change Data Capture streaming data ingestion.
- **Apache Flink** offers unified batch and stream processing.
- **Apache Paimon** provides unified Lakehouse storage for batch, OLAP, and streaming queries.
There are plenty of resources and blogs available for you to explore the capabilities of [Apache Flink](https://flink.apache.org/) and [Flink CDC](https://www.ververica.com/blog/ververica-donates-flink-cdc-empowering-real-time-data-integration-for-the-community), as they are quite popular in modern large-scale production environments. [Apache Paimon](https://paimon.apache.org/), however, is a newer addition to the tech stack, functioning as a table format that brings real-time streaming capabilities to the Lakehouse.
While a data Lakehouse is a combination of the best a data lake and a data warehouse have to offer, the Streamhouse is a continued evolution of the Lakehouse, with well-established Apache Flink sitting at its core.
## Streamhouse = Streaming + Lakehouse
Essentially, Streamhouse = Streaming + Lakehouse and as discussed it combines the ease and cost of the Lakehouse with the power of real-time streaming to merge the best of both, allowing you to leverage the benefits of the Lakehouse and real-time streaming in one solution.
## Unified Batch and Streaming
You may have noticed the term 'unified' used for the trio of projects (Apache Flink, Apache Paimon, and Flink CDC) that work together. While Apache Flink is known for its streaming and batch processing capabilities, in the Streamhouse context, "unified" means that the underlying engine has all the technology required to support both batch and streaming workloads.
As depicted in the illustration below, we can think of batch as a specialized type of stream.
> **NOTE:** Note: OLAP is also a specialized type of Batch.
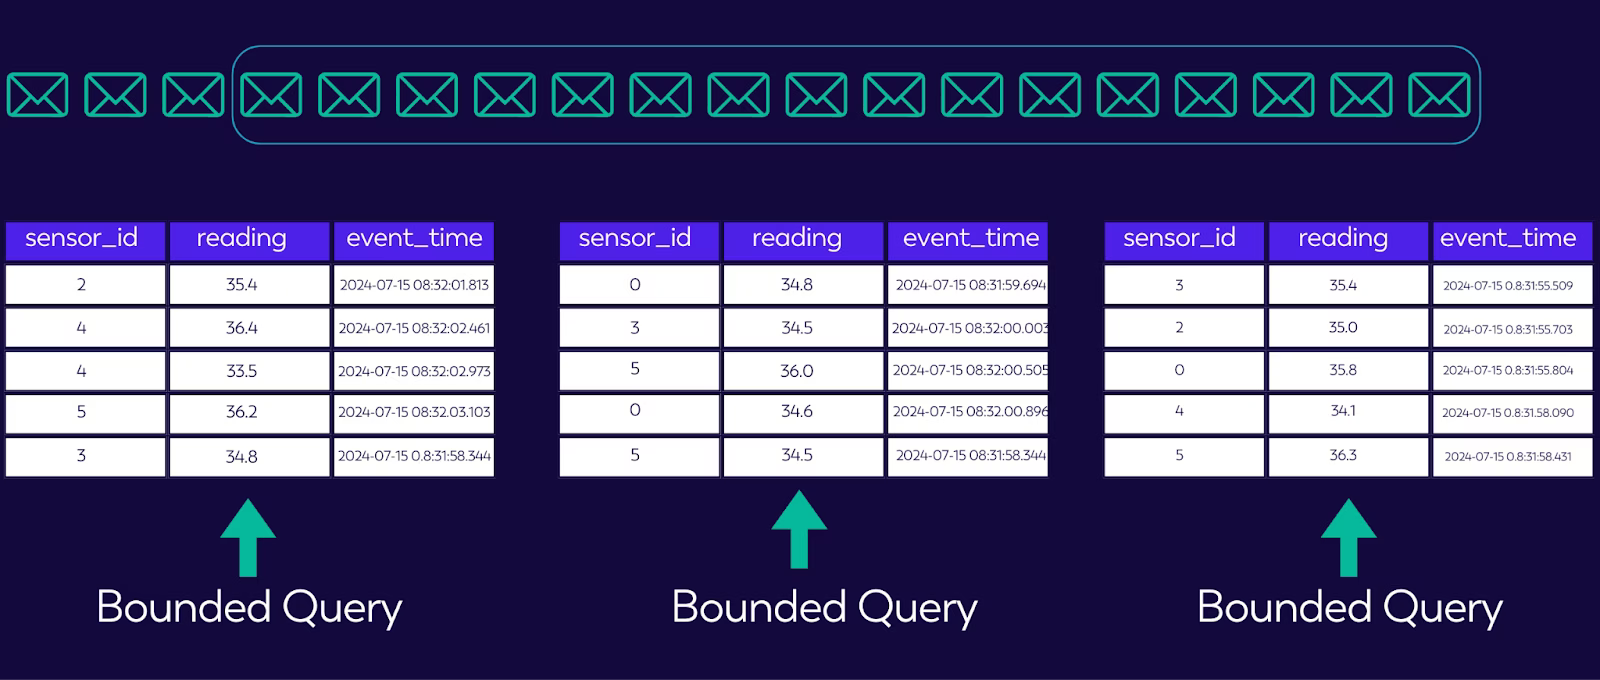
A stream is an unbounded collection of events, but at any point in time that stream can be broken down into discrete views and then queried, yielding results up to that precise point in time. This highlights that Streamhouse is a one-stop solution that can handle batch and streaming workloads. Overall, the Streamhouse provides a solution boasting three lows (3Ls): low latency, low complexity, and low cost.
Next, let’s explore the three musketeers of the Streamhouse (Apache Flink, Flink CDC, and Paimon).
## Apache Flink: Unified Compute
Apache Flink provides capabilities that solve both batch and stream processing use cases. Since its original inception, Flink has evolved significantly and one of its core distinguishing features is a unified batch and streaming API. This API allows users to connect a streaming storage layer and perform queries on both batch and streaming data, as Flink itself does not include a storage layer.
As mentioned, the unified batch and streaming API is a conceptual advantage. Although batch and stream share similarities, they have distinct needs and requirements. An effective engine must support both, and seamlessly switch between the two.
Figure 4 depicts some of the different properties of streaming and batch processing.
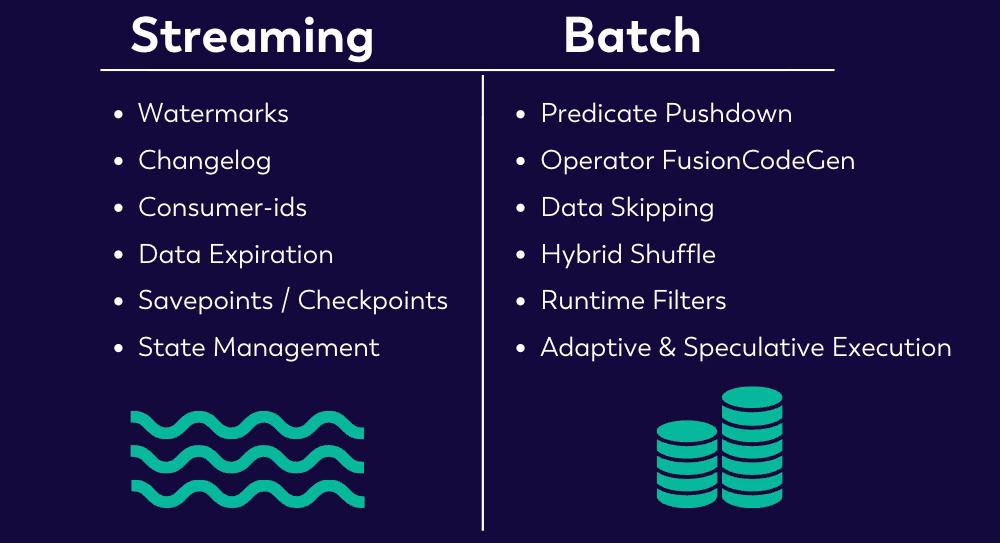
Additionally, to move the Apache Flink project towards a Streaming Lakehouse, is the result of significant effort. It introduces and supports more [Lakehouse APIs](https://flink.apache.org/2023/10/24/announcing-the-release-of-apache-flink-1.18/#extended-ddl-support), including extended DDL (Data Definition Language) support and time travel features.
## Apache Flink CDC: Unified Ingestion
With Apache Flink as the engine, the first step is getting data into the lake. Naturally, the next question is, why would you ingest operational data in a data lake in the first place? Business application data is typically stored in operational databases like MySQL or Postgres. Generally speaking, when there is a need to perform data analysis you typically want to avoid querying the database directly. There are two primary reasons for this:
- Querying large tables may cause excessive database load, which can affect business operational workloads negatively. As a result, data scientists and analysts need to have a good understanding of the anticipated data volumes and how their queries will affect the underlying system.
- The query performance might need improvements, as data is not stored in columns.
As discussed above, streaming and real-time data can be moved into a streaming storage layer like Apache Kafka or Apache Pulsar, although each of these solutions may, in turn, have their own limitations based on the scenario.
The above examples help to better understand why it is necessary to synchronize the data on a data lake or data lakehouse for analytical use cases, and a crucial aspect of that is Change Data Capture (CDC) ingestion.
### Important Considerations for CDC Ingestion
The Streamhouse aims to provide a seamless CDC ingestion experience. If you are working in large-scale production environments there is a good chance that you have a considerable number of tables within a database, and those tables can undergo numerous schema changes as the business evolves. In addition, new tables might be added to the database as the business grows. Typical user challenges include:
- How to map all of the tables' DDL (Data Definition Language) to Flink DDL?
- How to easily synchronize the full database with all the tables?
- How to make sure all the schema changes are reflected downstream?
- How to deal with scenarios where new tables are added to the database over time?
- How to read all the historical data and then know how to start reading the new changes from the database?
At the same time, the underlying framework should not put too much pressure on the database when doing large-scale CDC ingestion to keep DBAs (Database Administrators) satisfied.
### Streamhouse Ingestion for CDC Data
To eliminate the above concerns and allow users to focus on creating data products, Ververica’s Streamhouse provides convenient syntactic sugar via SQL.
More specifically, there are: **CREATE TABLE AS (CTAS)** and **CREATE DATABASE AS (CDAS)** statements.
**CTAS** allows users to move data in real time between upstream and downstream systems, while also handling and synchronizing all the schema changes.
**CDAS** is a syntax sugar for CTAS that provides access to all the database metadata, allowing multi-table or even full database synchronization.
In addition, source merge optimization is supported. This is particularly applicable to MySQL CDC because it not only reduces the number of database connections, but also avoids repeated pulling of Binlog data to reduce the database reading pressure.
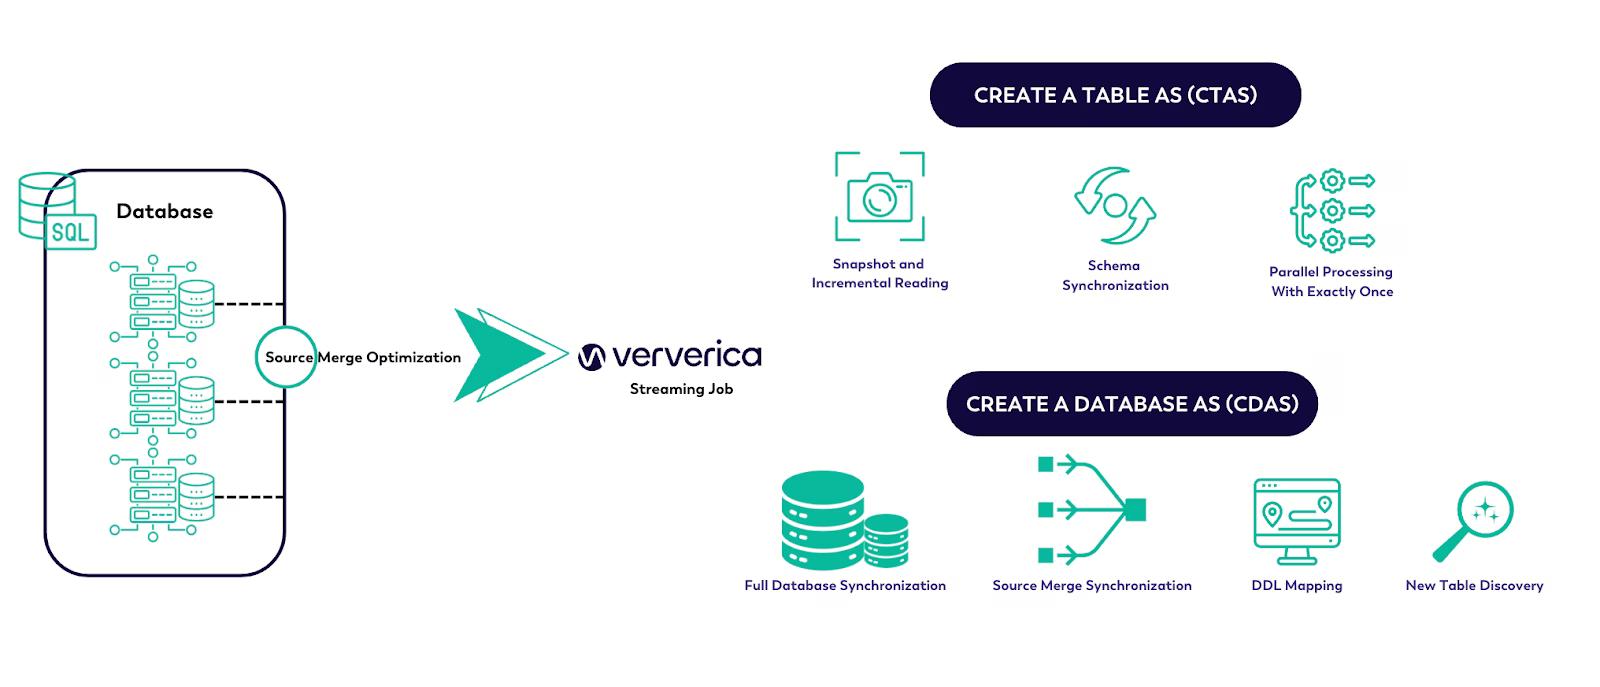
Now, let’s use an example to demonstrate the simplicity of this process. Imagine there is a large database with multiple tables of sales data that need to be synchronized. In addition, you are required to sync all the schema changes that take place within the database, along with any new tables that are added. Since this impacts CDC (mutable/updates) data, these changes need to be reflected in the ingestion layer tables.
This can all be achieved by leveraging the built-in catalogs and the CDAS SQL abstraction. The following code snippet demonstrates how you can achieve all the requirements listed in the example above with a singular SQL statement.
```sql
SET 'table.exec.sink.upsert-materialize' = 'NONE';
SET 'table.cdas.scan.newly-added-table.enabled' = 'true';
CREATE DATABASE IF NOT EXISTS `paimon-catalog`.rds_dw
WITH (
'changelog-producer' = 'input'
) AS DATABASE rdsdb.sales_db INCLUDING ALL tables;
```
## Apache Paimon: Unified Lakehouse Storage
As mentioned previously, Apache Paimon is a fairly new addition to the ecosystem. Paimon is a unified lakehouse storage that relies on a single table abstraction that can handle different use cases, including message queue functionality, range scan queries, and key/value lookups. On the API, a single interface needs to be provided. With Paimon, a single SQL query can operate on batch, OLAP, and streaming data, without any code changes.
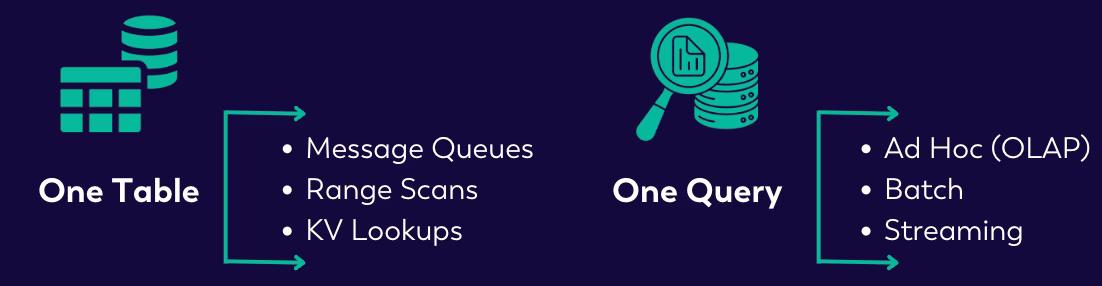
Apache Paimon builds on Lakehouse primitives and provides all the required properties, including ACID guarantees, efficient querying, time travel, schema evolution and more. Paimon also takes it one step further, with the ability to bring all the required streaming capabilities onto the lake.
### Unified Lakehouse Storage: Features of Apache Paimon
Apache Paimon is built to work seamlessly with Apache Flink, and helps to unlock the full potential of Flink on the Lakehouse.
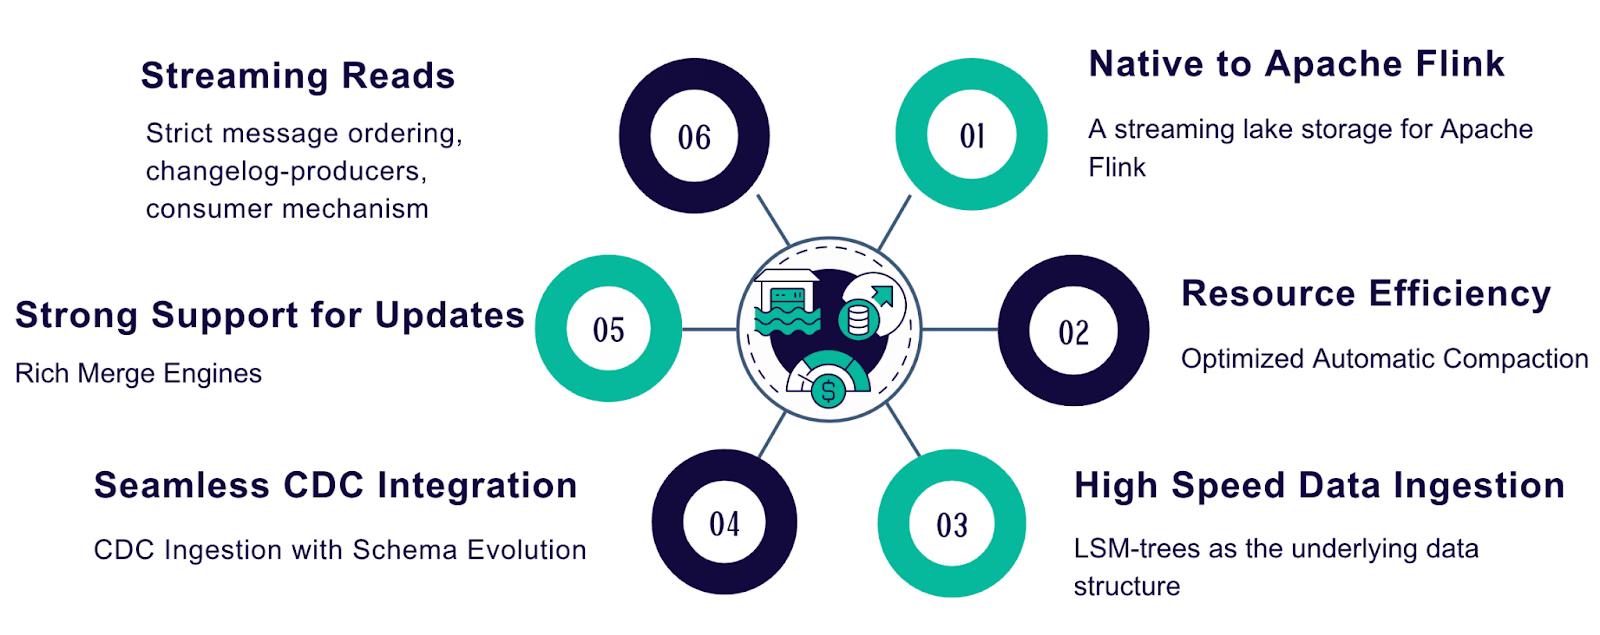
Let's take a closer look at six key areas that make this possible:
**1. Strong Native Flink Integration**: Paimon works well with Apache Flink, supporting all the latest versions and features.
**2. Resource Efficient Automatic Data Compaction**: To best balance read and write speeds, Paimon automatically combines smaller files into larger ones, making data queries faster. It does this via an internal process called compaction. Compaction handles small files by merging them automatically and asynchronously into larger files, resulting in faster querying and performance optimizations.
**3. High-Speed Data Ingestion**: Paimon uses Log-Structured Merge (LSM) trees, a popular data structure for fast data writing, used by systems like RocksDB, ScyllaDB, Clickhouse, and Cassandra to name a few. Paimon does this efficiently by utilizing low-cost object storage.
**4. Seamless CDC Ingestion**: Paimon integrates seamlessly with Flink CDC, leveraging the sophisticated features of the framework to handle data changes smoothly and updates effectively, which is crucial for Change Data Capture.
**5. Robust Upsert Support**: Paimon leverages merge engines to handle updates on the Lakehouse, supporting various methods like deduplication, first-row, aggregation, and partial updates. One of its key strengths is the partial update merge engine, which allows merging multiple streams together, eliminating the need for costly streaming joins on the primary keys. The partial-update can also be combined with the aggregation engine. All merge engines store the state directly on object storage, making streaming ETL more cost-effective.
**6. True Streaming Reads**: Streaming writers can generate a changelog, similar to a database binlog, which keeps track of all the changes that occur on a table. This is important for the downstream consumers to be able to always see correct results. At the same time table formats have a snapshot management mechanism, which means at any point in time, various data files can expire and be deleted, resulting in FileNotFoundExceptions for consumers. Apache Paimon provides different safeguard mechanisms, along with a consumer-id mechanism, allowing for true streaming reads.
## When Should You Consider Adopting Streamhouse?
Vererica’s Streamhouse helps fill the gap between traditional streaming and batch architectures. If you are already invested in or considering Apache Flink and its ecosystem and you want to fully leverage a lakehouse, then adopting this unified solution yields several business benefits. Below, we’ve listed a few use cases highlighting when Streamhouse is worth exploring:
- **Data lake entry:** If the business has strong requirements for CDC data ingestion.
- **Near-real-time:** If your real-time SLAs can afford 1-minute latencies, Streamhouse can provide lower operational costs than traditional stream processing.
- **Data freshness:** When there is a requirement to provide fresh data on your Lakehouse (1-minute interval) Streamhouse can help provide up-to-date data seamlessly.
- **Fast writes and Blazing fast OLAP:** When there is a requirement for fast writes and blazing fast OLAP queries.
- **Streaming Materialized Views:** When there is a requirement for streaming materialized views and incremental updates, to avoid recalculating predefined queries.
- **Connecting upstream and downstream tables:** Anytime there is a need to connect upstream and downstream tables via streaming, you can utilize the Streamhouse. This singular solution includes using an ingestion layer as the source of truth, a processing layer that contains tables for streaming deduplication, multi-stream merging, lookup joins, and aggregations with business aggregates and KPIs, all ready to be served.
- **Testing:** If your existing data infrastructure is oriented towards batch, and there is a need to introduce streaming, Streamhouse allows you to easily experiment with streaming use cases before making permanent, significant investments.
All the above are a small sampling of business scenarios that can leverage Ververica’s Streamhouse. In addition, Streamhouse makes streaming data accessible to more data professionals, allowing them to leverage and experiment with fresh data for ML and AI applications. The image below represents the single-solution offered by Streamhouse, including ease of use for professionals and a sampling of the many use cases it helps to solve.
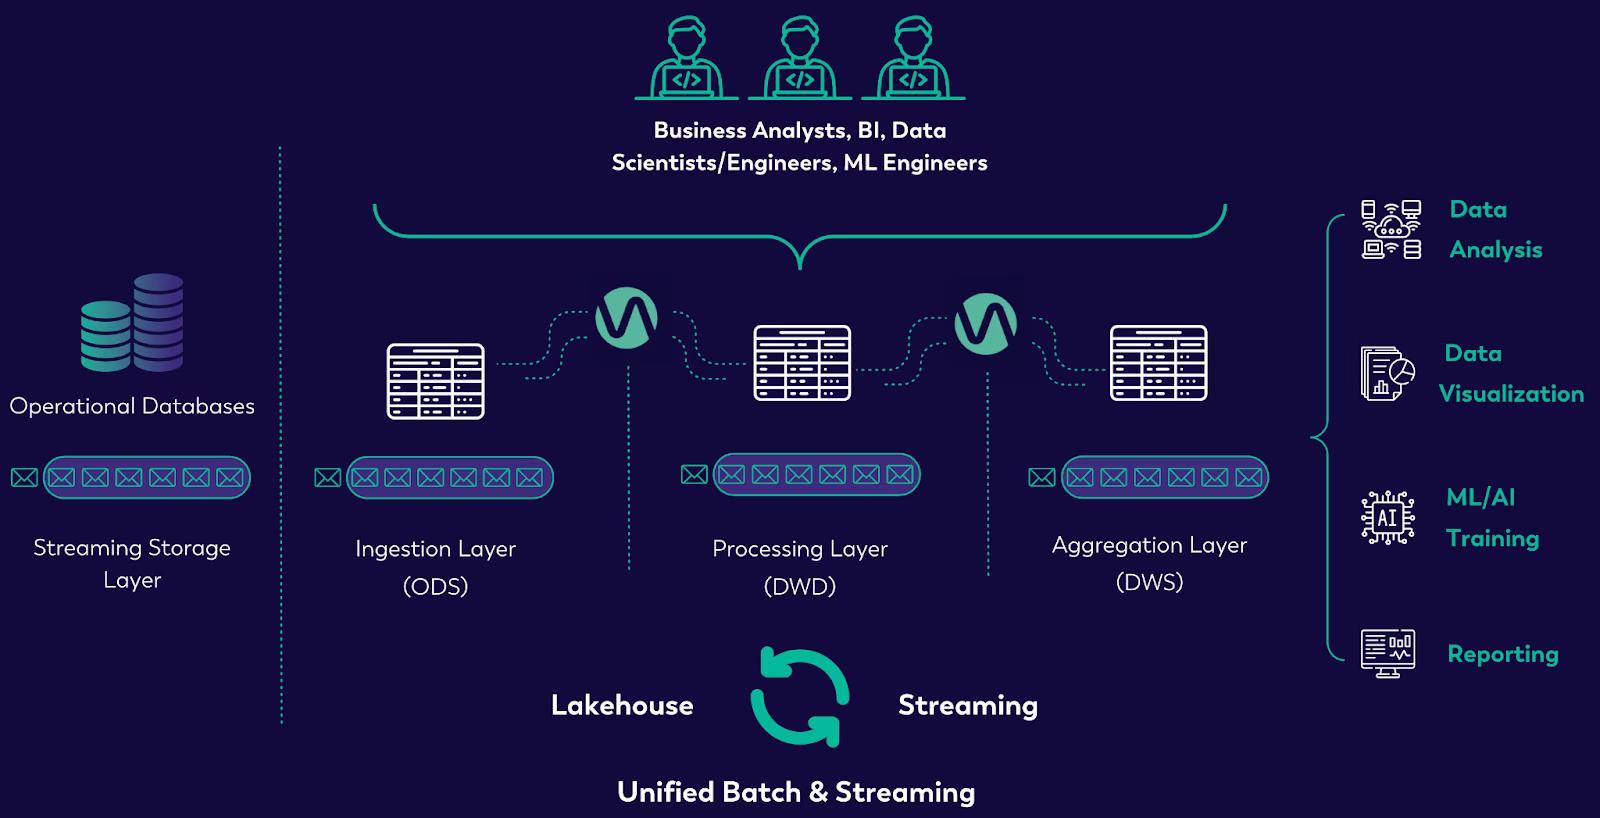
## Conclusion
Ververica’s Streamhouse offers a transformative solution in today’s data-driven landscape, addressing the critical need for a unified batch and streaming architecture. By seamlessly converging real-time streaming with data lakehouse capabilities, Streamhouse offers businesses the flexibility to process data in real time while also benefiting from the cost-effectiveness and scalability of batch processing. This powerful combination eliminates the need for maintaining complex, separate systems, reducing both operational costs and inefficiencies.
With Streamhouse, organizations can harness the full spectrum of their data—whether streaming for faster insights or leveraging historical datasets for deep analytical purposes—all within a cohesive platform. This approach redefines what’s possible with modern data architectures, enabling businesses to stay agile, scale effortlessly, and derive value from their data faster and more efficiently than ever before. As the demand for real-time insights continues to grow, solutions like Streamhouse are paving the way for a more unified, efficient, and intelligent approach to data processing.
## More Resources
> **NOTE:** Note: In data architectures, there is no one-size-fits-all solution, which is why the community requires transparency, and why integrations are often an important part of any solution.
- Read more about Streamhouse:
- [Apache Paimon: The Streaming Lakehouse](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse)
- [Streamhouse Unveiled](https://www.ververica.com/blog/streamhouse-unveiled)
- [Streamhouse: Data Processing Patterns](https://www.ververica.com/blog/streamhouse-data-processing-patterns)
- [Building Real-Time Data Views with Streamhouse](https://www.ververica.com/blog/building-real-time-data-views-with-streamhouse)
- [VERA Blog Series Part 2: Under the Hood: VERA's 3 Core Pillars](https://www.ververica.com/blog/vera-under-the-hood)
- [Watch more of the interview with Ben Gamble](https://www.youtube.com/playlist?list=PLaDktj9CFcS8rF8IENlEcPNJMqX3TPfAZ) discussing VERA and Streamhouse on YouTube.
- Access the [VERA docs.](https://docs.ververica.com/introduction/about-vera)
- Ready to get started? Take VERA (with Streamhouse) for a test run by spinning up your own [Ververica Cloud deployment.](https://www.ververica.com/product/deployment/cloud)
- Have questions? Our team can help! [Contact us.](https://www.ververica.com/contact)
- [Join the Apache Flink Community](https://www.flink-forward.org/) at Flink Forward, filled with Flink training courses, expert speakers, networking, an entire track dedicated to Flink use cases, and much more.
> **INFO:** Thanks!
This blog wouldn't be possible without the contributions of the many PMC Members, engineers, Ververicans and community members who contribute to the Apache Flink project and repo, and those who support the Apache Paimon and Flink CDC projects.
---
---
title: "VERA Blog Series Part 3: Full Stream Ahead!"
description: "Explore the key features, benefits, and impressive performance metrics that VERA, the cloud native engine revolutionizing Apache Flink contains."
lastUpdated: 2026-05-01T08:46:43.000Z
source_url:
html: "https://www.ververica.com/blog/vera-full-stream-ahead"
md: "https://www.ververica.com/blog/vera-full-stream-ahead.md"
---
## VERA: The Cloud Native Engine Revolutionizing Apache Flink® Blog Series
Welcome to the final installment of the three-part blog series that introduces [Ververica Runtime Assembly (VERA)](https://www.ververica.com/product/vera), the cloud-native, ultra-high-performance engine that powers Ververica’s Streaming Data Platform. In this final blog, let's dive into the features, capabilities and benefits of VERA.
## VERA's Capabilities
To recap quickly, in the [first blog](https://www.ververica.com/blog/vera-from-steam-to-stream) of our series introducing the VERA engine, we discussed the evolution of VERA and the pressures and limitations of other streaming data solutions (including OS Apache Flink,) that helped to drive the creation of this powerful streaming data engine. In the [second blog](https://www.ververica.com/blog/vera-under-the-hood), we dove into the technical capabilities of the Three Core Pillars that form the VERA engine, and what that means for the user.
In this final piece, let's take a look at VERA’s capabilities, features and benefits, as well as share some of the performance metrics real users are experiencing using VERA today.
### Key Features and Benefits
VERA offers a range of key features and benefits. While its capabilities are extensive, here are a few unique aspects that set VERA apart:
- **Open Core**
VERA is Open Core, designed with additional features that are built in alignment with existing Open Source Apache Flink functionalities. As a result, VERA is 100% compatible with Flink, ensuring there is never vendor lock-in. It is engineered to keep all the advantages of OS Flink, including low latency processing, high throughput, stateful stream processing, and the unified programming model, allowing VERA to seamlessly run Flink applications without any modifications or compatibility issues. In addition, VERA offers multiple deployment options, including both on-prem and cloud options.
- **Ultra-high Performance**
VERA is able to process billions of events per second with sub-second latency that is up to 2X faster than self-managed open-source Flink on similar hardware, reducing data processing delays to the millisecond level. VERA’s performance allows quick deployment of streaming apps in a scalable and cost-effective way.
VERA also disaggregates individual components within the network, compute, metadata, and storage layers to further increase performance, including optimization on the SQL engine and state access.
- **Infinitely Scalable and Elastic**
VERA reduces costs and enhances performance by separating the compute and storage layers. This architecture eliminates concerns about disk capacity planning and job rescaling due to storage limitations. It also resolves latency issues and accommodates large stateful applications, while lowering both storage and operational expenses.
- **Always Available**
Because VERA is cloud native, your data streaming apps can run in a cloud environment, which lowers your state storage and operational costs, while also allowing for fast rescaling and the ability to hyperscale.
VERA also offers uptime/runtime redundancies that won’t fail, and it is highly reliable, with a 99.99% uptime Service Level Agreement (SLA) using Ververica Cloud deployment. Finally, VERA provides highly-available functionalities like hot updates to rescale your jobs, and dynamic complex event processing (CEP) to change rules mid-flight without restarting jobs. This allows VERA to perform job updates with minimal to zero downtime.
- **Fault tolerant**
VERA has no single point of failure, with built-in easy rollover and recovery. VERA’s fault tolerance features ensure reliable, uninterrupted operation, even when faced with the inevitable failures that occur from time to time.
VERA achieves this tolerance and ensures your deployment is functional, robust, and resilient as a result of the following features:
- Tiered state
- Lazy state loading
- Delayed state pruning
- Faster and more stable checkpoints
- Failure detection with task-local recovery
- Operator isolation
- Dynamic re-scaling
- Efficient recovery mechanisms
- Faster state rebuilding and job startup process
- **Secure**
VERA prioritizes security, streamlining data access management and reducing maintenance overhead. Leveraging Ververica's security certifications, it ensures appropriate data access while minimizing time spent on updates and patches. This allows teams to focus on building applications and solving use cases rather than constant manual maintenance.
- **Multi-tenancy**
VERA allows many independent applications to run in a shared environment, with the ability to isolate data at both the namespace and tenant level, utilizing configurable access management and role-based access control. This allows workspaces to be quickly provisioned and released on demand, reducing cost by meeting operational demands, even as they change over time and circumstances.
- **Data Governance**
VERA is designed to keep data organized, secure, and consistent. Users can move, process, use, and store data while continuously tracking data origin and utilization. This allows for quick discovery and resolution, and ensures data credibility and accuracy.
### Democratizing Stream Processing
This is just a sampling of the capabilities and features that VERA offers in the pursuit of how Ververica is democratizing stream processing. This democratization allows users to access both fresh, current data and historical data to make informed business decisions at the right time, in the right place, with VERA handling both batch and real-time streaming data use cases.
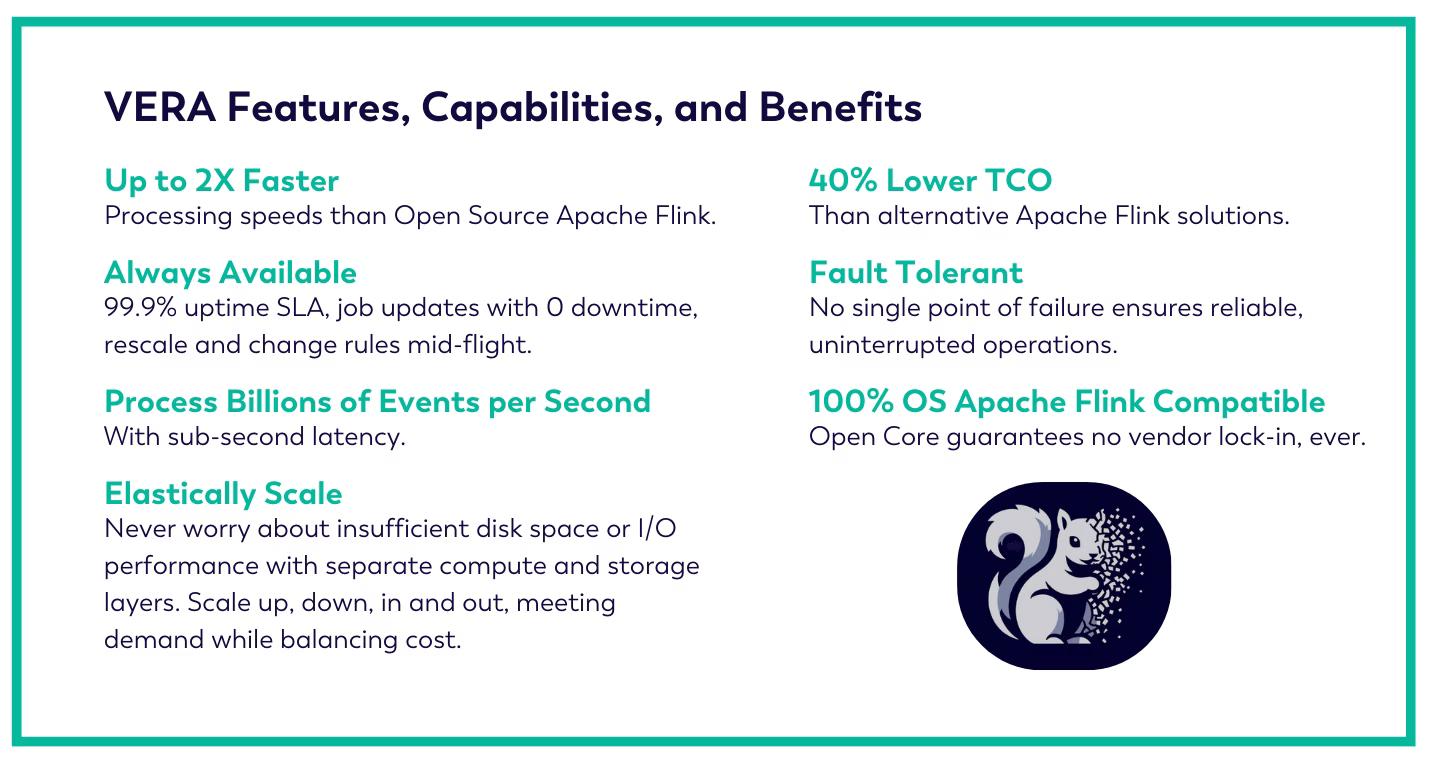
> "VERA makes it easier, faster, and more cost effective for businesses to build their streaming apps and get meaningful insights from their data." Alex Walden, Ververica CEO
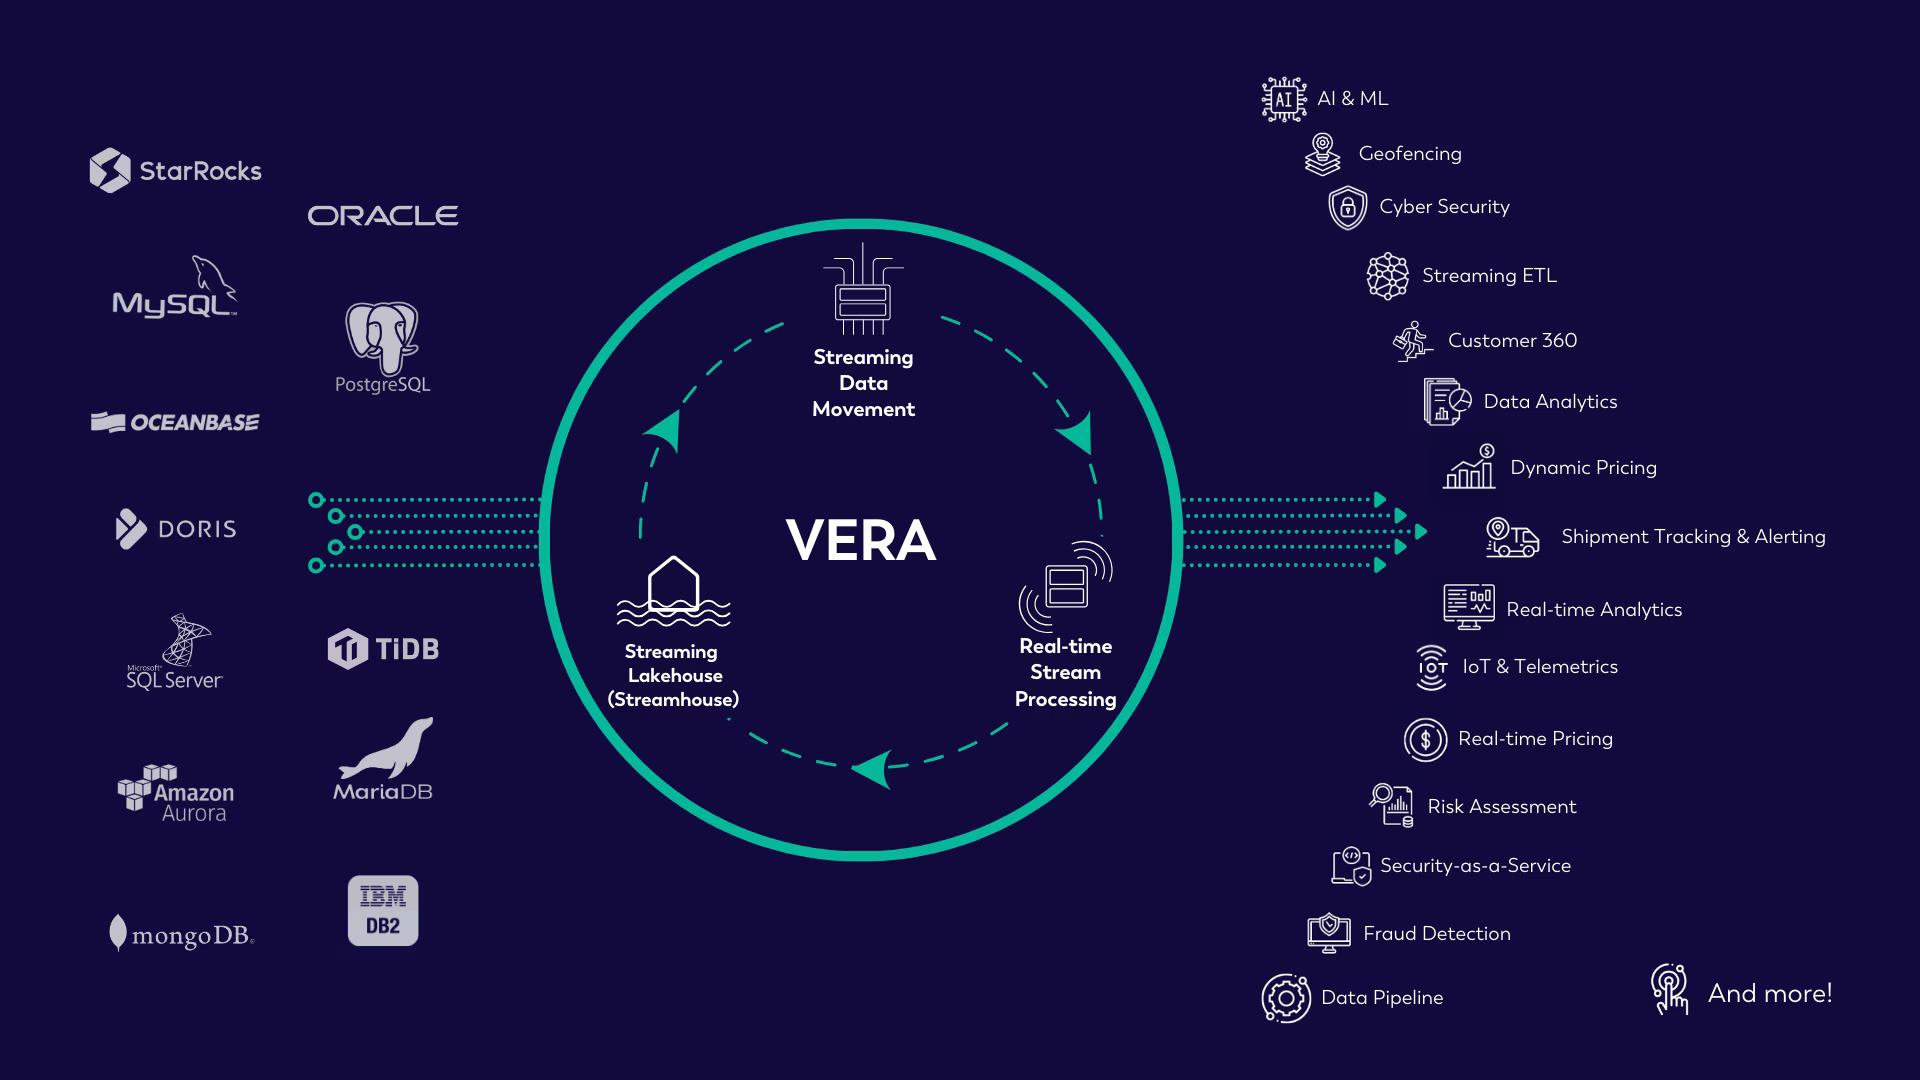
VERA was built with users in mind, allowing them to maximize performance and productivity, while minimizing resource use with enterprise-grade flexible tools. By removing the complexities of OS Flink, developers can focus on delivering business outcomes, and in turn, businesses are empowered with tools that make managing, monitoring and maintaining their data streaming solution faster, easier, and cheaper.
The goal of Ververica’s Streaming Data Platform is to remove the complexity of Flink entirely, while still benefiting from all the advantages and power of the Flink solution. In the future, you will simply choose your deployment method from both on-premise and cloud offerings, then choose your sources, tune the solution, and get results, regardless of your use case.
Next, let’s explore the impact VERA has on cost effectiveness and Return on Investment (ROI) when deployed.
## ROI and Cost Effectiveness
Thanks to the benefits and features listed above, VERA also reduces operational costs and increases ROI. As we know, open source software itself is free. However, the overhead required to successfully run open source software increases costs exponentially. The people, operations, and infrastructure, (including servers, observability, governance, security, storage, and networking) required to run OS software is expensive when compared to investing in a managed product. This is particularly true when that managed solution is also faster, higher performing, and more secure.
Ververica’s solution handles continuous updates, feature innovations, and constant monitoring for you, eliminating the need for self-management of your data system. Ververica also ensures rapid rollout of updates with minimal interruptions, providing a more stable Flink experience and continuously improving service without manual effort. This approach significantly reduces operational overhead for your team.
### Performance Results
It’s one thing to say what a technology is designed to be doing, but another to see actual results. The VERA engine has been tested at scale, and current deployments report truly impressive numbers, including:
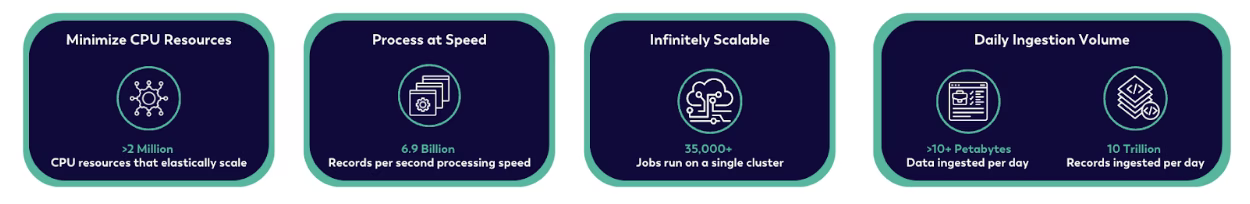
- Highly scalable compute resource allocation, 2 million+ cores
- Processing ability up to 6.9 billion records per second
- Task size flexibility, one install reports 35,000+ jobs running on a single cluster
- 10+ petabytes per day ingestion speed
- 10 trillion records ingested per day
### Nexmark Benchmark
In addition to exploring current [Use Cases](https://www.ververica.com/use-cases), We’d also recommend checking out the [Nexmark Benchmark](https://docs.ververica.com/managed-service/reference/vera-benchmark) results comparative analysis of query execution times.
The most recent evaluation of VERA highlights the impact of VERA’s optimizations and demonstrates the impressive processing speed VERA reaches when compared to OS Flink. From the test results below, you can see that VERA has a significant effect on improving job performance (single-core throughput), with an average of 50% improvement (with some stateful workloads improving even more significantly).
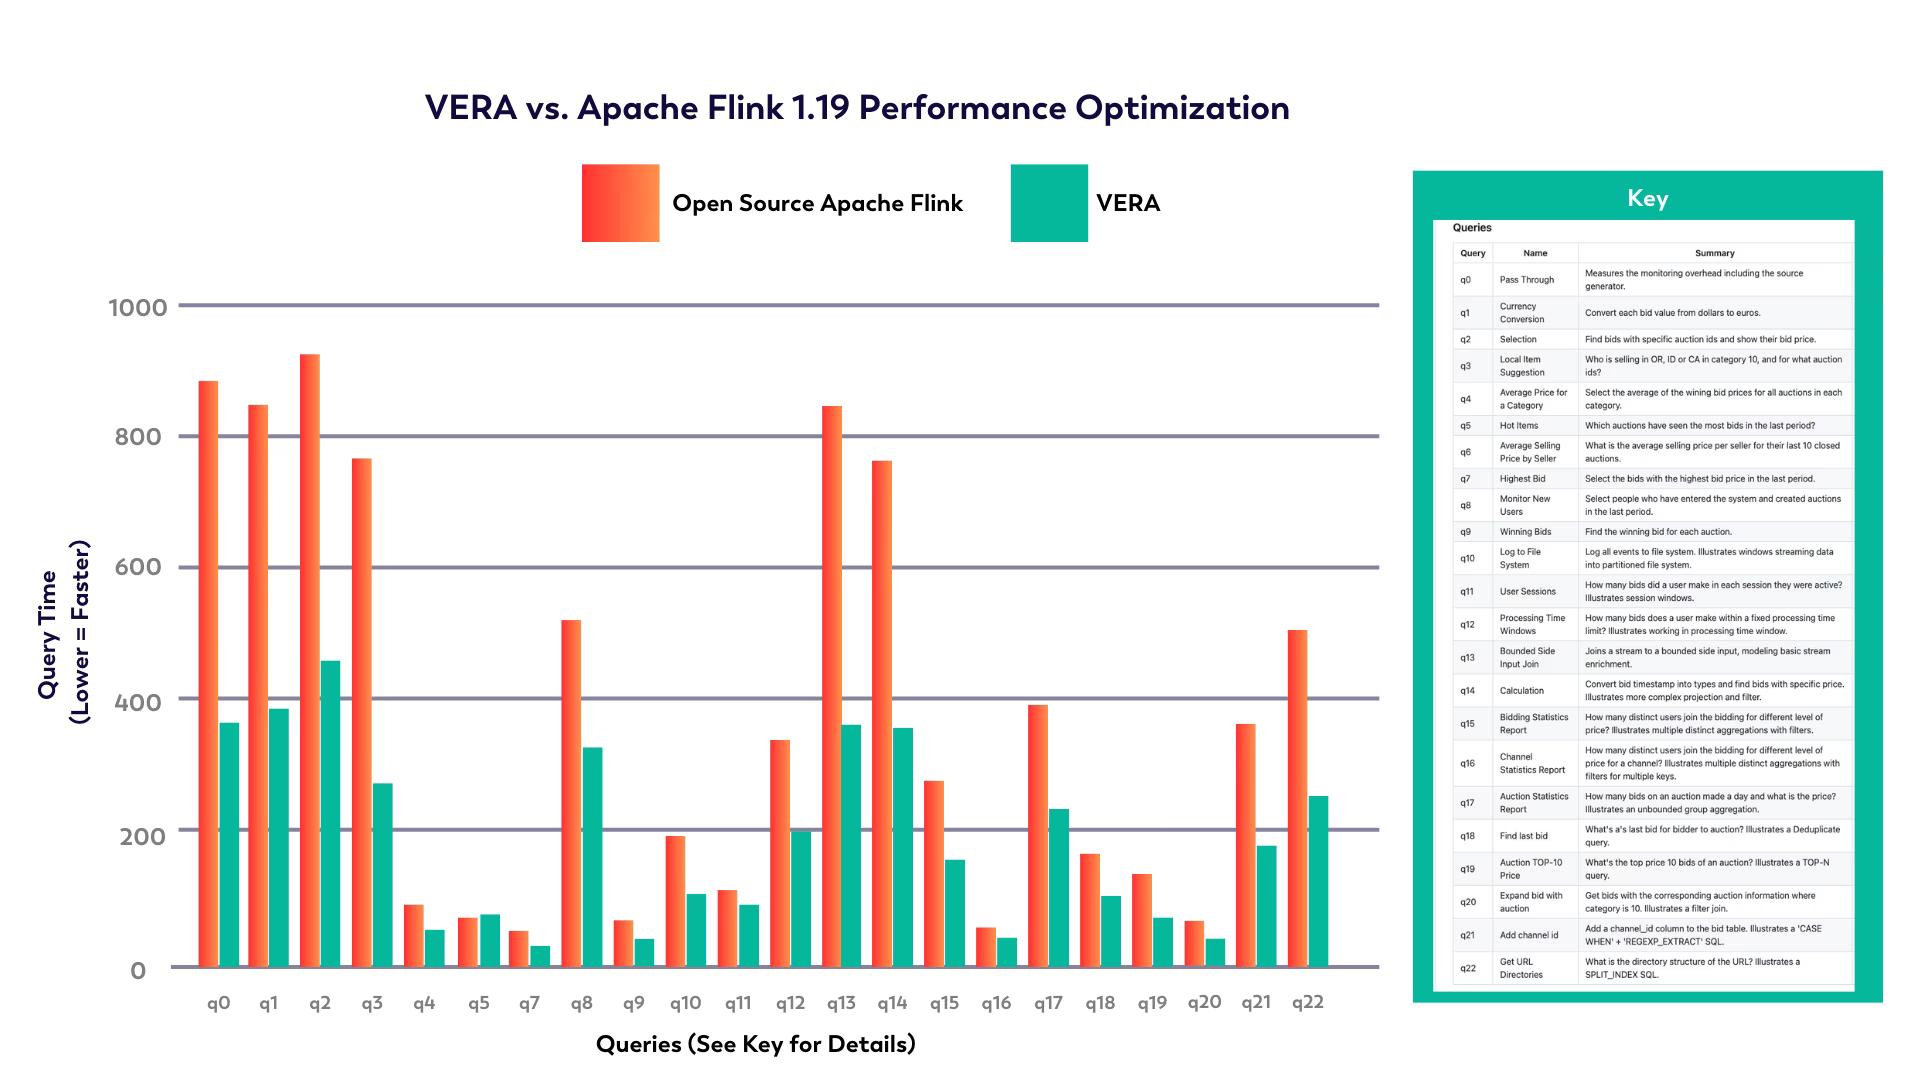
You can also access the updated Nexmark Benchmark to run your own testing:
- [https://github.com/nexmark/nexmark](https://github.com/nexmark/nexmark)
- [flink-benchmarks](https://github.com/apache/flink-benchmarks/tree/master/src/main/java/org/apache/flink/state/benchmark)
## VERA: Full Stream Ahead!
Throughout this blog, we’ve shared many of the capabilities, key features and benefits of VERA, the engine powering Ververica’s Streaming Data Platform. To conclude, VERA is built to be fast, easy to use and cost effective, and designed to democratize stream processing and, as a result, revolutionize Open Source Apache Flink and the future of stream processing.
In addition, throughout this three-part blog series, we’ve explored why VERA was created, taken a look at the three Core Pillars that power the engine, and discussed the features and benefits that VERA offers users. Stay tuned for more content, including deep technical dives into the Core Pillars, and further explorations and examples of the myriad of interesting streaming data [use cases](https://www.ververica.com/use-cases) that the VERA engine helps solve.
Finally, it would be poor form not to provide a shout-out to the many PMC Members, engineers, Ververicans, developers, and other community members who’ve spent long days creating VERA, contributing to the Apache Flink project and repo, and supporting projects including Apache Paimon, and Flink CDC. Thank you!
## More Resources
- Learn more [about VERA](https://www.ververica.com/product/vera).
- [Watch Ververica Field CTO Ben Gamble](https://www.youtube.com/playlist?list=PLaDktj9CFcS8rF8IENlEcPNJMqX3TPfAZ) discuss VERA on YouTube.
- Access the [VERA docs](https://docs.ververica.com/introduction/about-vera).
- Ready to get started? Take VERA for a test run by spinning up a [Ververica Cloud deployment.](https://www.ververica.com/product/deployment/cloud)
- Have questions? Our team can help! [Contact us.](https://www.ververica.com/contact)
- [Join the Apache Flink Community](https://www.flink-forward.org/) at Flink Forward Berlin 2024, filled with Flink training courses, expert speakers, networking, an entire track dedicated to Flink use cases, and much more.
- Review the [Nexmark Benchmark Report.](https://docs.ververica.com/managed-service/reference/vera-benchmark)
Did you enjoy this blog series? Consider sharing the links below and visit the [VERA page](https://www.ververica.com/product/vera).
VERA: The Cloud Native Engine Revolutionizing Apache Flink® Blog 3-Part Blog Series:
- [Part One: From Steam to Stream](https://www.ververica.com/blog/vera-from-steam-to-stream)
- [Part Two: Under the Hood: VERA’s Three Core Pillars](https://www.ververica.com/blog/vera-under-the-hood)
- [Part Three: Full Stream Ahead: The Capabilities and Benefits of VERA](https://www.ververica.com/blog/vera-full-stream-ahead)
---
---
title: "VERA Blog Series Part 2: Under the Hood: VERA's 3 Core Pillars"
description: ""
lastUpdated: 2026-05-01T09:27:40.000Z
source_url:
html: "https://www.ververica.com/blog/vera-under-the-hood"
md: "https://www.ververica.com/blog/vera-under-the-hood.md"
---
## VERA: The Cloud Native Engine Revolutionizing Apache Flink® Blog Series
Welcome to part two of our three-part blog and video series that introduces [Ververica Runtime Assembly (VERA)](https://www.ververica.com/vera), the cloud-native, ultra-high performance engine that powers Ververica’s Streaming Data Platform.
## Under the Hood: VERA's Three Core Pillars
In the [first blog](https://www.ververica.com/blog/vera-from-steam-to-stream) of this series we discussed the creation of VERA, including the challenges that helped to drive the development of this powerful streaming data engine that powers Ververica’s Streaming Data Platform. In this blog, we’ll dive into the technical capabilities of the Three Core Pillars that comprise the VERA engine.
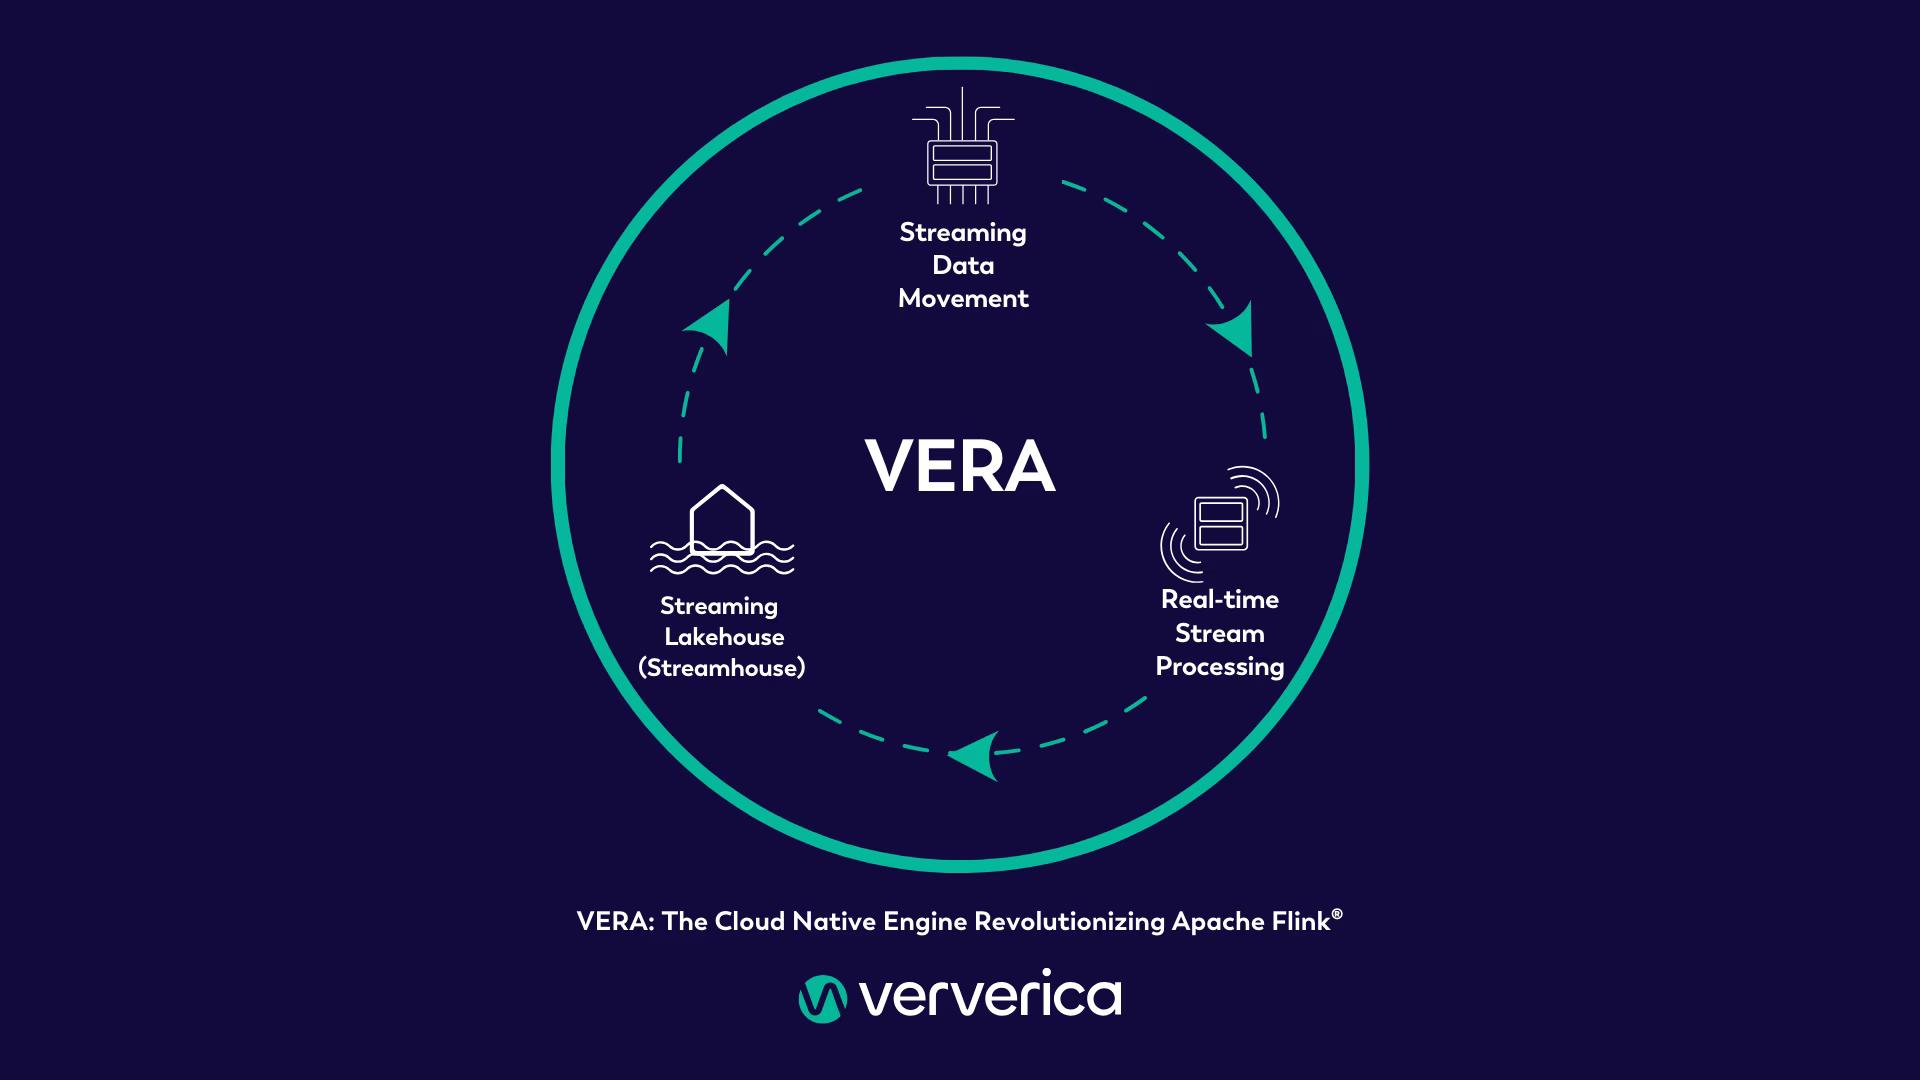
VERA’s power comes from the Three Core Pillars:
- Streaming Data Movement
- Real-time Stream Processing
- Streaming Lakehouse (Streamhouse).
When combined, VERA and the Three Pillars provide a one-stop shop for all your data streaming needs, whether you are processing, storing, or moving data. Let’s take a closer look at each of these pillars and the benefits they offer.
## Core Pillar #1: Streaming Data Movement
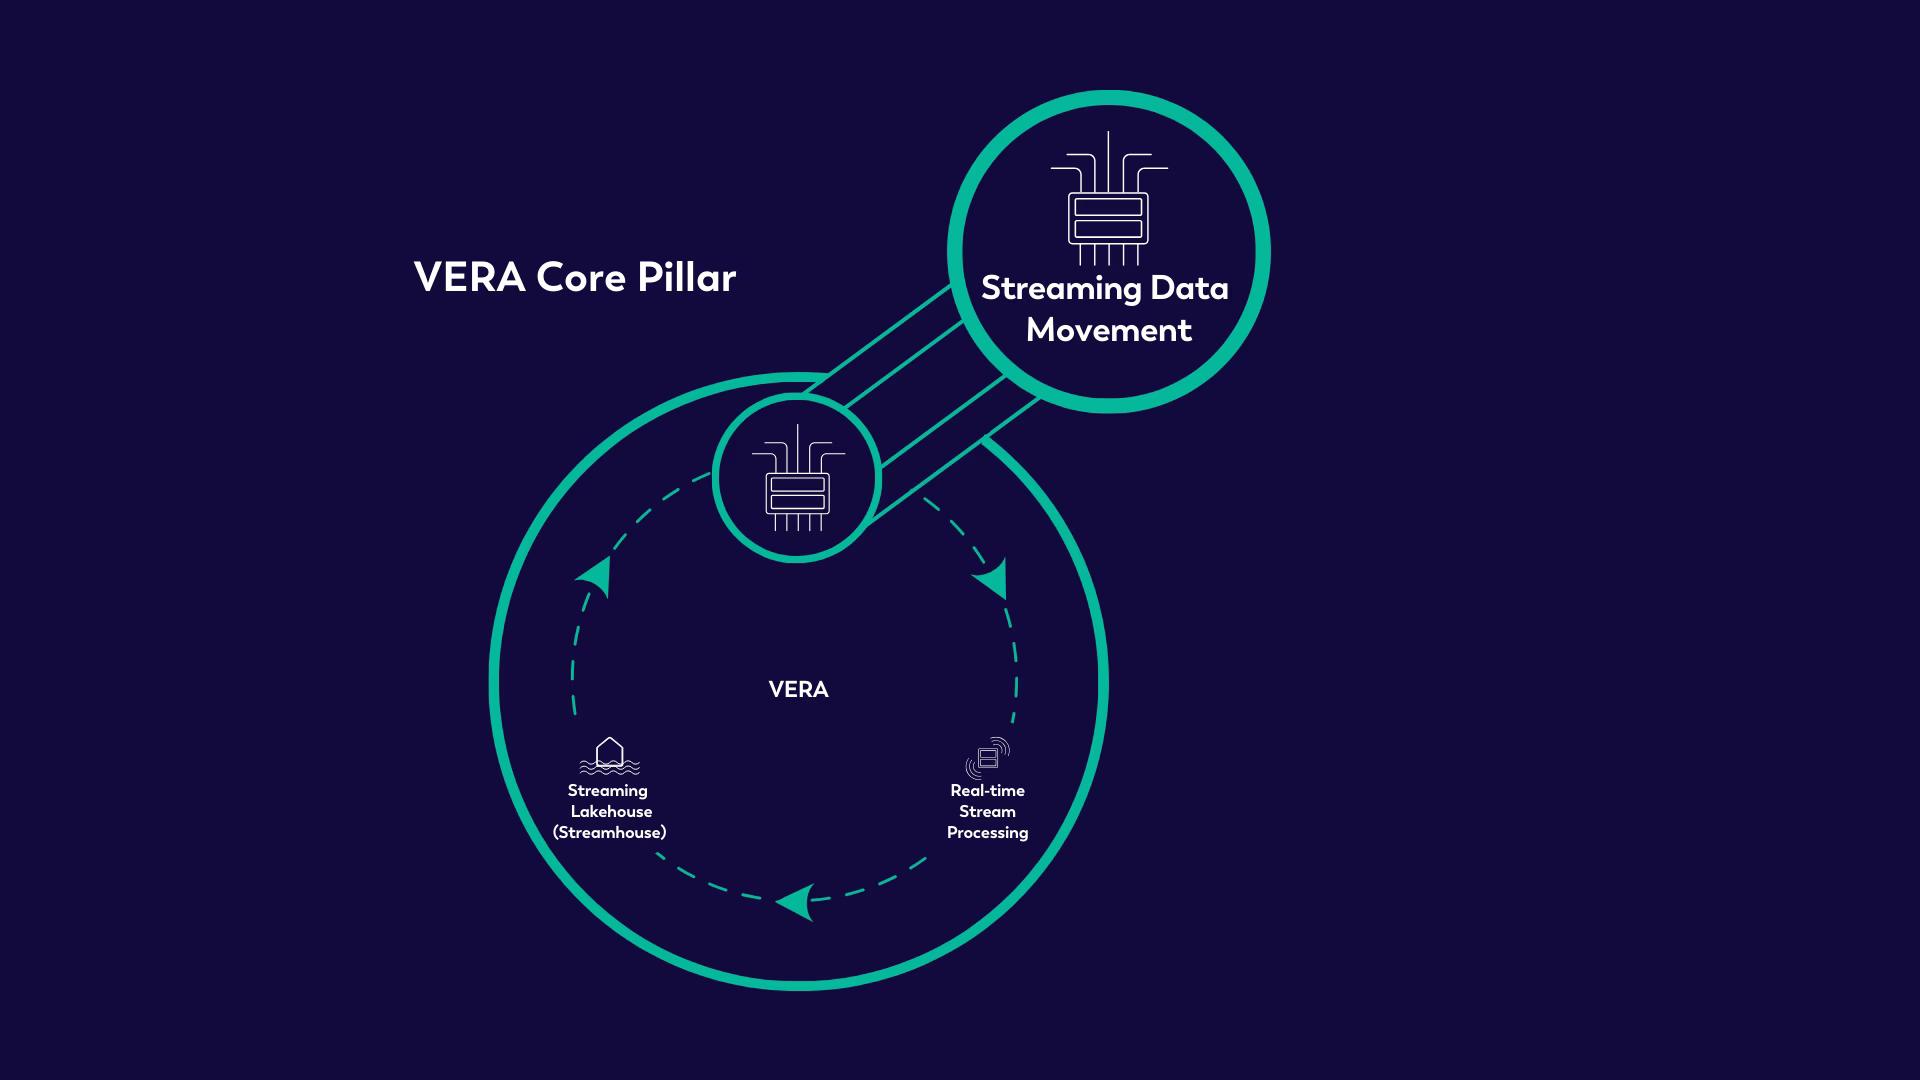
### From Source to Sink
The first Core Pillar of VERA is Streaming Data Movement.
All data lives in different places, meaning your business decisions are also spread out over your architecture. Data lives in postgres. It lives in a MYSQL. It lives in _any_ number of other operational data sources, and this has a huge effect on your tactical decisions.
Streaming Data Movement is the end-to-end process of utilizing Flink Change Data Capture (Flink CDC) to move data and events through VERA. This is accomplished by loading data generated from various applications and systems (often in different formats and volumes) and transforming it into a uniform type, then continuously processing that data in real time. This is followed by consuming the processed data and finally putting it into destination systems for potential later use, all while maintaining data lineage and security.
In essence, VERA absorbs data into a unified format, regardless of where it originated, and makes the data easily accessible and actionable. By seamlessly connecting, processing, and analyzing data throughout the data lifecycle, events are transformed into a uniform data set that you can then use to make data-driven decisions.
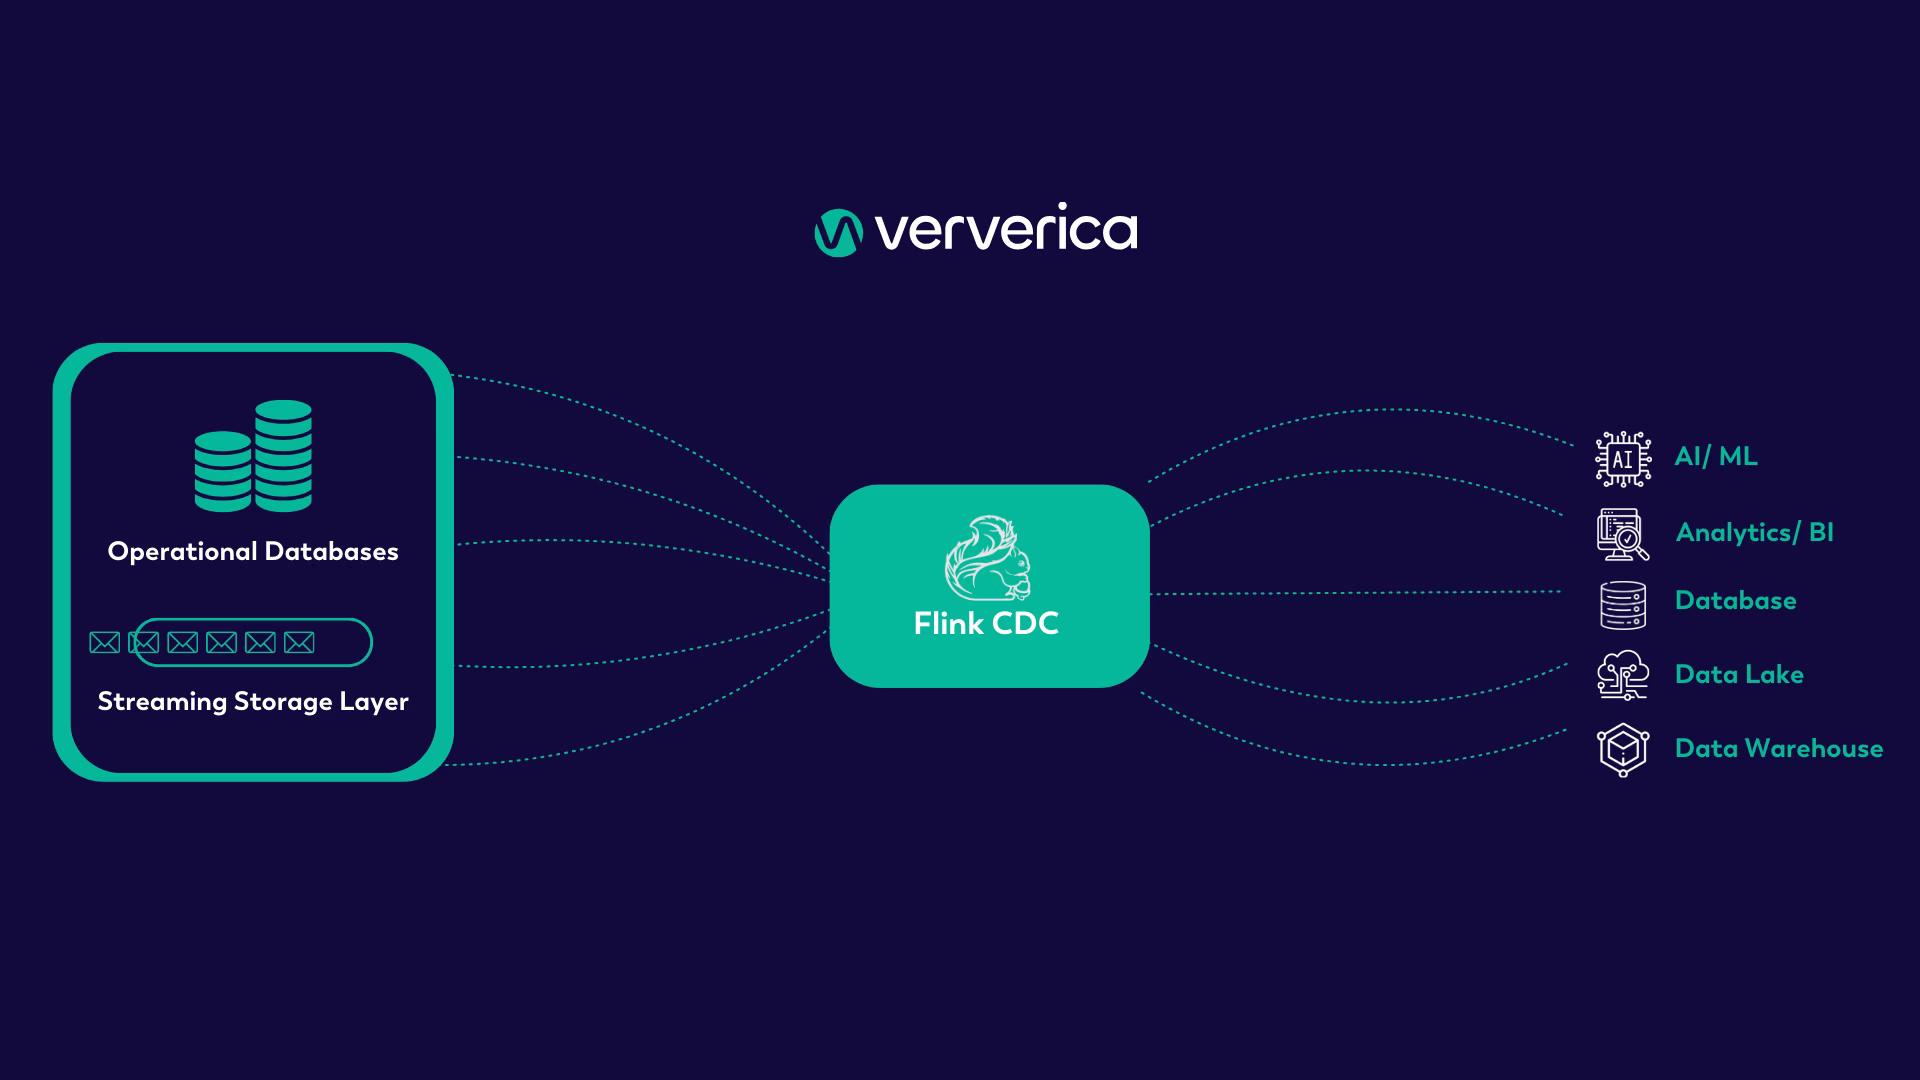
### Benefits For Users
Regardless of where your data originates, and no matter how much it grows over time, with VERA, you can easily access and format that data, run it through time-based processing, and then store it for later use and safekeeping. In addition, you can potentially use that data for future decisions that are on a slower timeline, or for use cases that require historical context.
VERA allows you to move all of your data and events into a common stateful processing layer, and provides you with a unified, 365-degree, real-time view and processing window into that data. In addition, VERA doesn’t care if you prefer developing apps with Java, Python, or SQL, as it offers all three options out-of-the-box. All of this functionality is available without compromising the performance, security, or reliability of your underlying systems.
In short: Streaming Data Movement makes all of your data easily available, so you can take action faster and make better-informed business decisions using that data.
#### Learn More About Flink CDC
Ververica is proud to have contributed Flink CDC to the Apache Software Foundation in early 2024. To learn more about Flink CDC, check out [this blog post](https://www.ververica.com/blog/ververica-donates-flink-cdc-empowering-real-time-data-integration-for-the-community).
## Core Pillar #2: Real-time Stream Processing
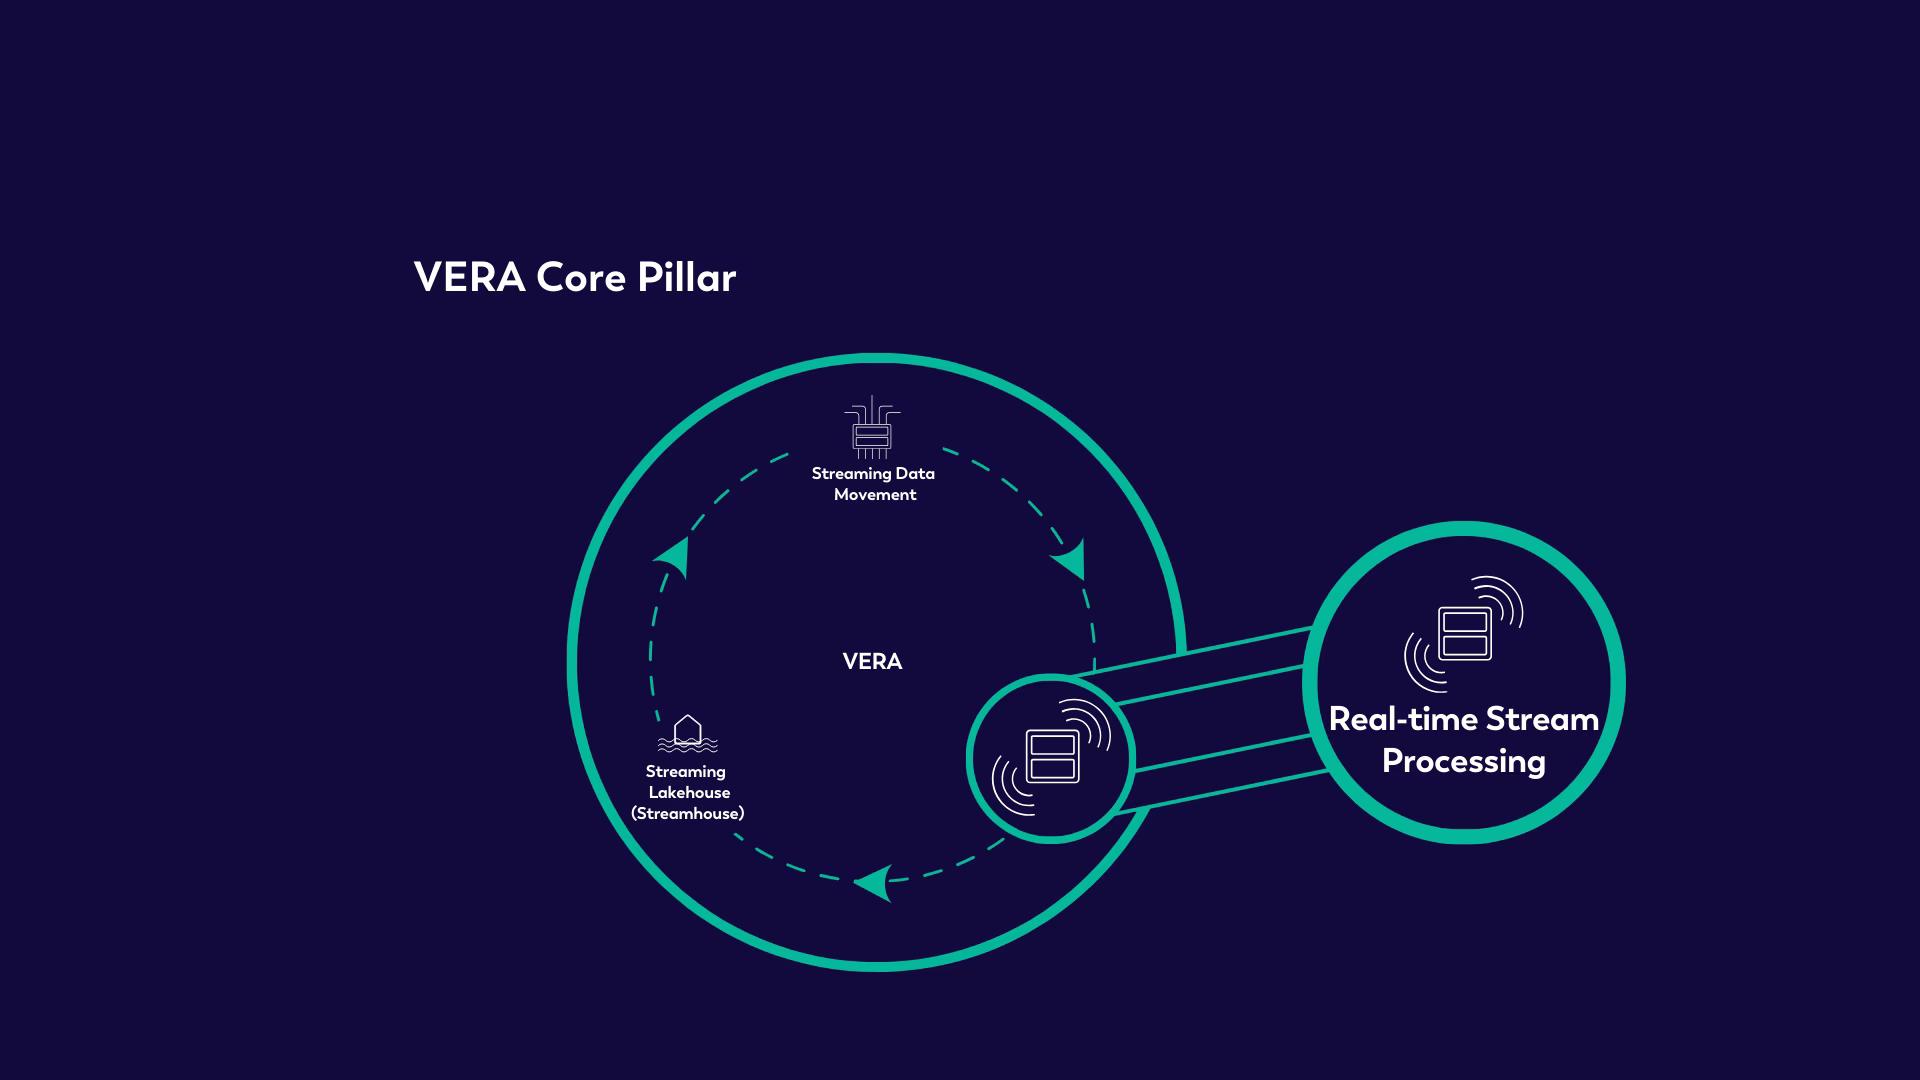
### Get the Power of Now
The second Core Pillar of the VERA engine is Real-time Stream Processing.
Processing and acting on your data in real time allows you to extract immediate meaning and insight from data, and removes the historical lag and wait time of batch processing. In fact, the vast majority of today’s successful online real-time experiences are powered by Apache Flink.
Consumers may not realize what is happening under the hood, but Flink underpins nearly every real-time transaction, be that an instant review, travel booking, an online purchase, a delivery or transportation service, an instant insurance claim, or notifications of identity fraud or credit card protection alerts. In addition, countless financial and banking interactions happen thanks to Flink, along with massive online multiplayer gameplay, social media applications, and any services that use the conventional concept of “streaming”. Of course, this only scrapes the surface of the use cases that Flink helps to solve.
Simply put: our lives without Flink would be _very_ different.
Listen as Ben Gamble, Ververica Field CTO briefly explains the Power of Now in the 40-second video:
[Video](https://cdn.sanity.io/files/6b38iw1w/production/522a755d8760b20db51af4b9df6799613f12cff9.mp4)
You can also watch the entire short video playlist: ["Introducing VERA The Engine Revolutionizing Apache Flink"](https://www.youtube.com/watch?v=SE8eRBwVuo4&list=PLaDktj9CFcS8rF8IENlEcPNJMqX3TPfAZ&pp=gAQBiAQB) available now on YouTube, during which Ben shares his thoughts on the creation of VERA and digs further into each of the core pillars.
### Enter Scalable, Flexible VERA
While OS Flink can solve an abundance of use cases, it is not without some challenges. VERA solves Flink’s limitations, (as discussed in the [first blog](https://www.ververica.com/blog/vera-from-steam-to-stream) in this series,) including the costs incurred when trying to dramatically scale Flink applications.
VERA is _highly_ scalable and stable, thanks to the decoupling of the storage and compute layers, and is optimized to deliver both stream processing and batch processing capabilities that allow for stateful computations over data streams. VERA manages the execution of Flink applications and seamlessly integrates with Flink and Flink APIs, which in turn allows developers to process and analyze large amounts of data to extract insights in real time.
Since data and traffic demands can fluctuate wildly, having the ability to easily and elastically scale capacity to any size; whether up or down, side to side, and back again, is paramount. For example, if one of your posts goes viral, or a huge number of consumers suddenly flock to your ticketing website, you don’t want that system to suddenly go down because of your sudden popularity and success. Utilizing open core VERA, built with Flink, gives you a safety net complete with built-in scalability, that also provides more flexibility, better performance, and lower overhead than traditional deployments.
Because VERA is designed for stateful stream processing and streaming analytics, in addition to processing data in real time, it inherently supports both data at rest (batch data pipelines and data stored in object stores), and data-in-motion (streaming pipelines and real-time use cases). Simply put, whether you need real time streaming or batch processing to solve a business need, VERA supports both.
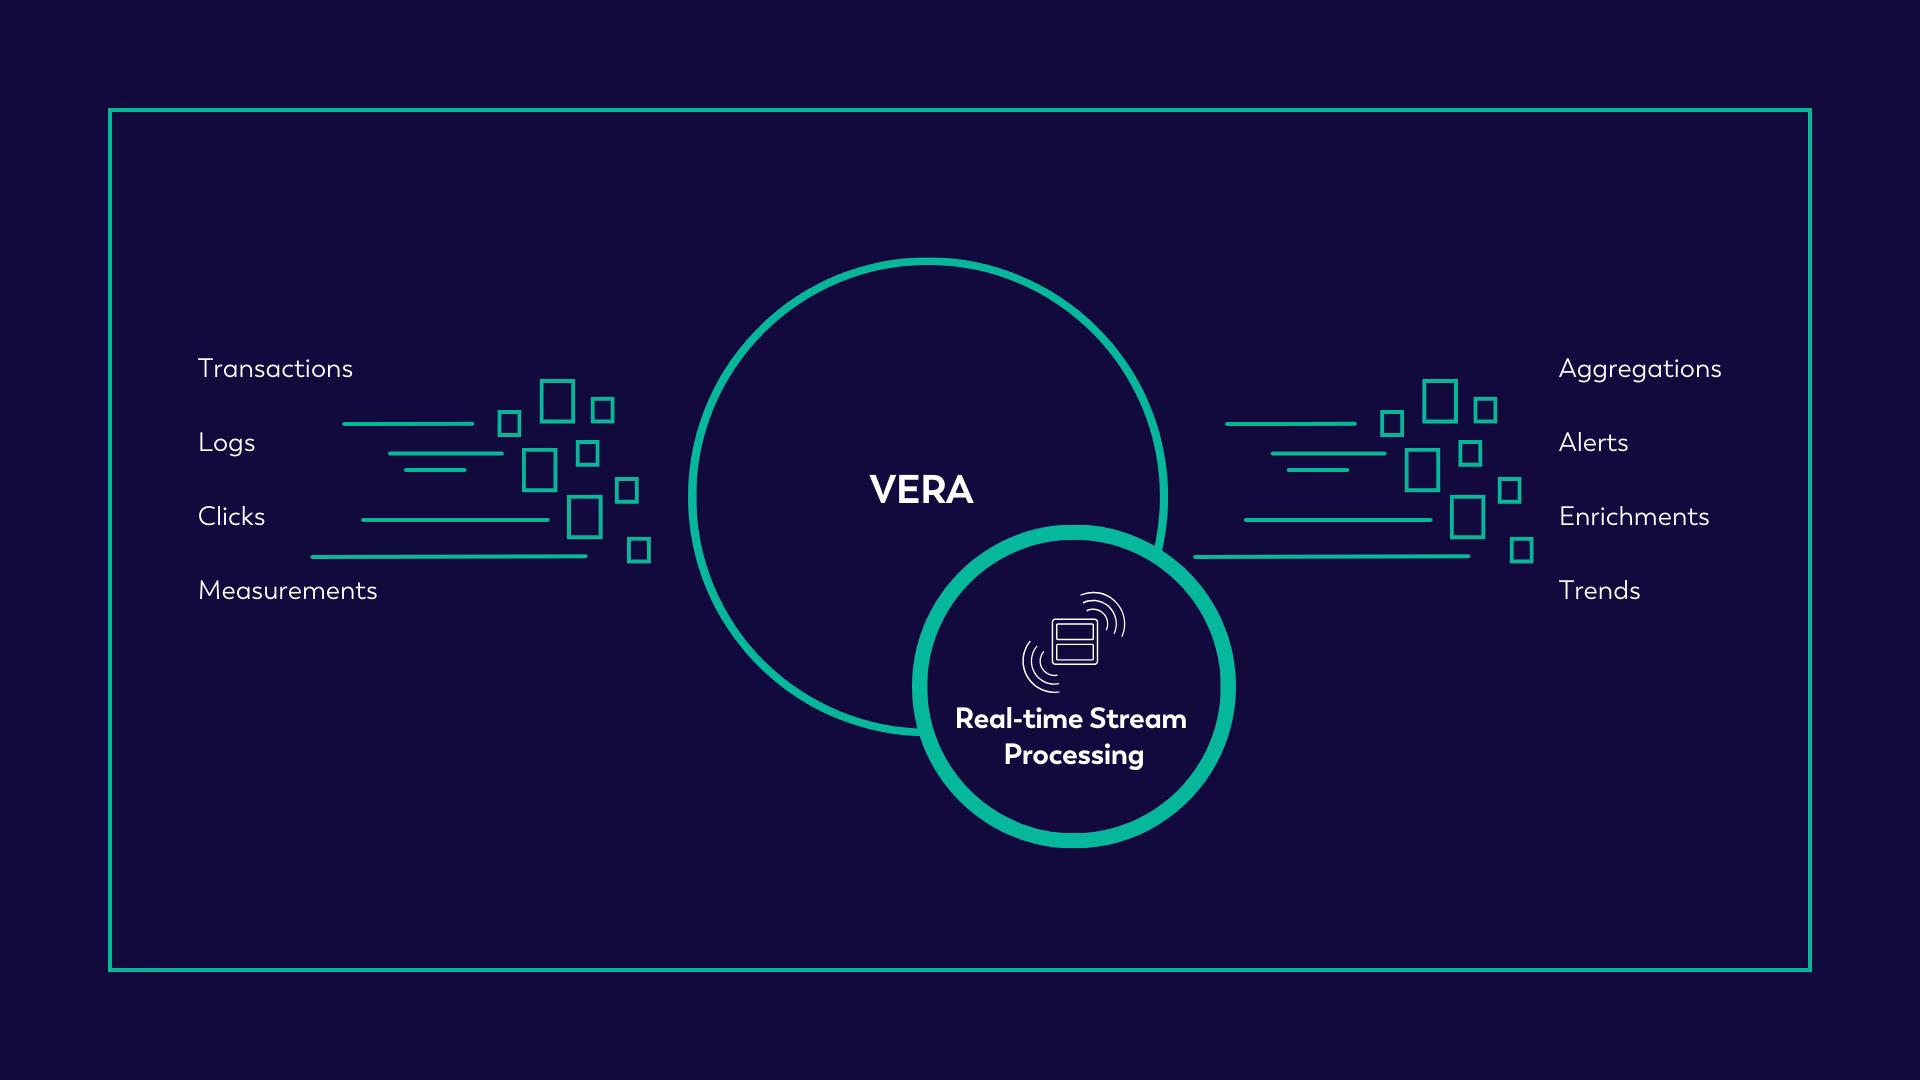
### Benefits For Users
For many modern use cases, failing to provide immediate transactions that execute flawlessly can result in unhappy customer experiences, reduced security, and any number of other negative business outcomes. Because VERA allows users to act on data as it arrives, and is continuously processing that data, you can stop waiting for data to catch up, and instead make fast, reliable decisions using the freshest information available.
In short, any piece of data that is inherently time-bound, whether happening asynchronously, or subject to an absolute time window guarantee, requires the highly scalable, elastic, and more stable real-time processing that VERA offers.
Here are a few more examples of the infinite use cases that can benefit from VERA’s real-time stream processing abilities:
- Providing up-to-date travel, weather, or fire warnings – because map updates using data from a quiet afternoon drive while you’re in the middle of a morning rush hour aren't relevant or helpful.
- Making a trade on a Stock Exchange – time is most definitely of the essence for any use case in which time=money.
- Scanning tickets for concert entry – nobody wants to be denied access to an event for which they have a ticket.
- Giving movie recommendations – late recommendations for a movie on a streaming app several weeks after your last venture into that specific genre aren’t necessarily high-risk, but they also aren't as meaningful as immediate suggestions that keep a consumer engaged and watching.
The VERA engine handles these situations with ease, boosting your business relevance by giving you the ability to make instantaneous decisions, with highly relevant and current data, and allowing you to act with Power of Now. The Power of Now means that you can take action on your data as it arrives, in whatever format it arrives, and use it to make immediate decisions.
## Core Pillar #3: Streaming Lakehouse (Streamhouse)
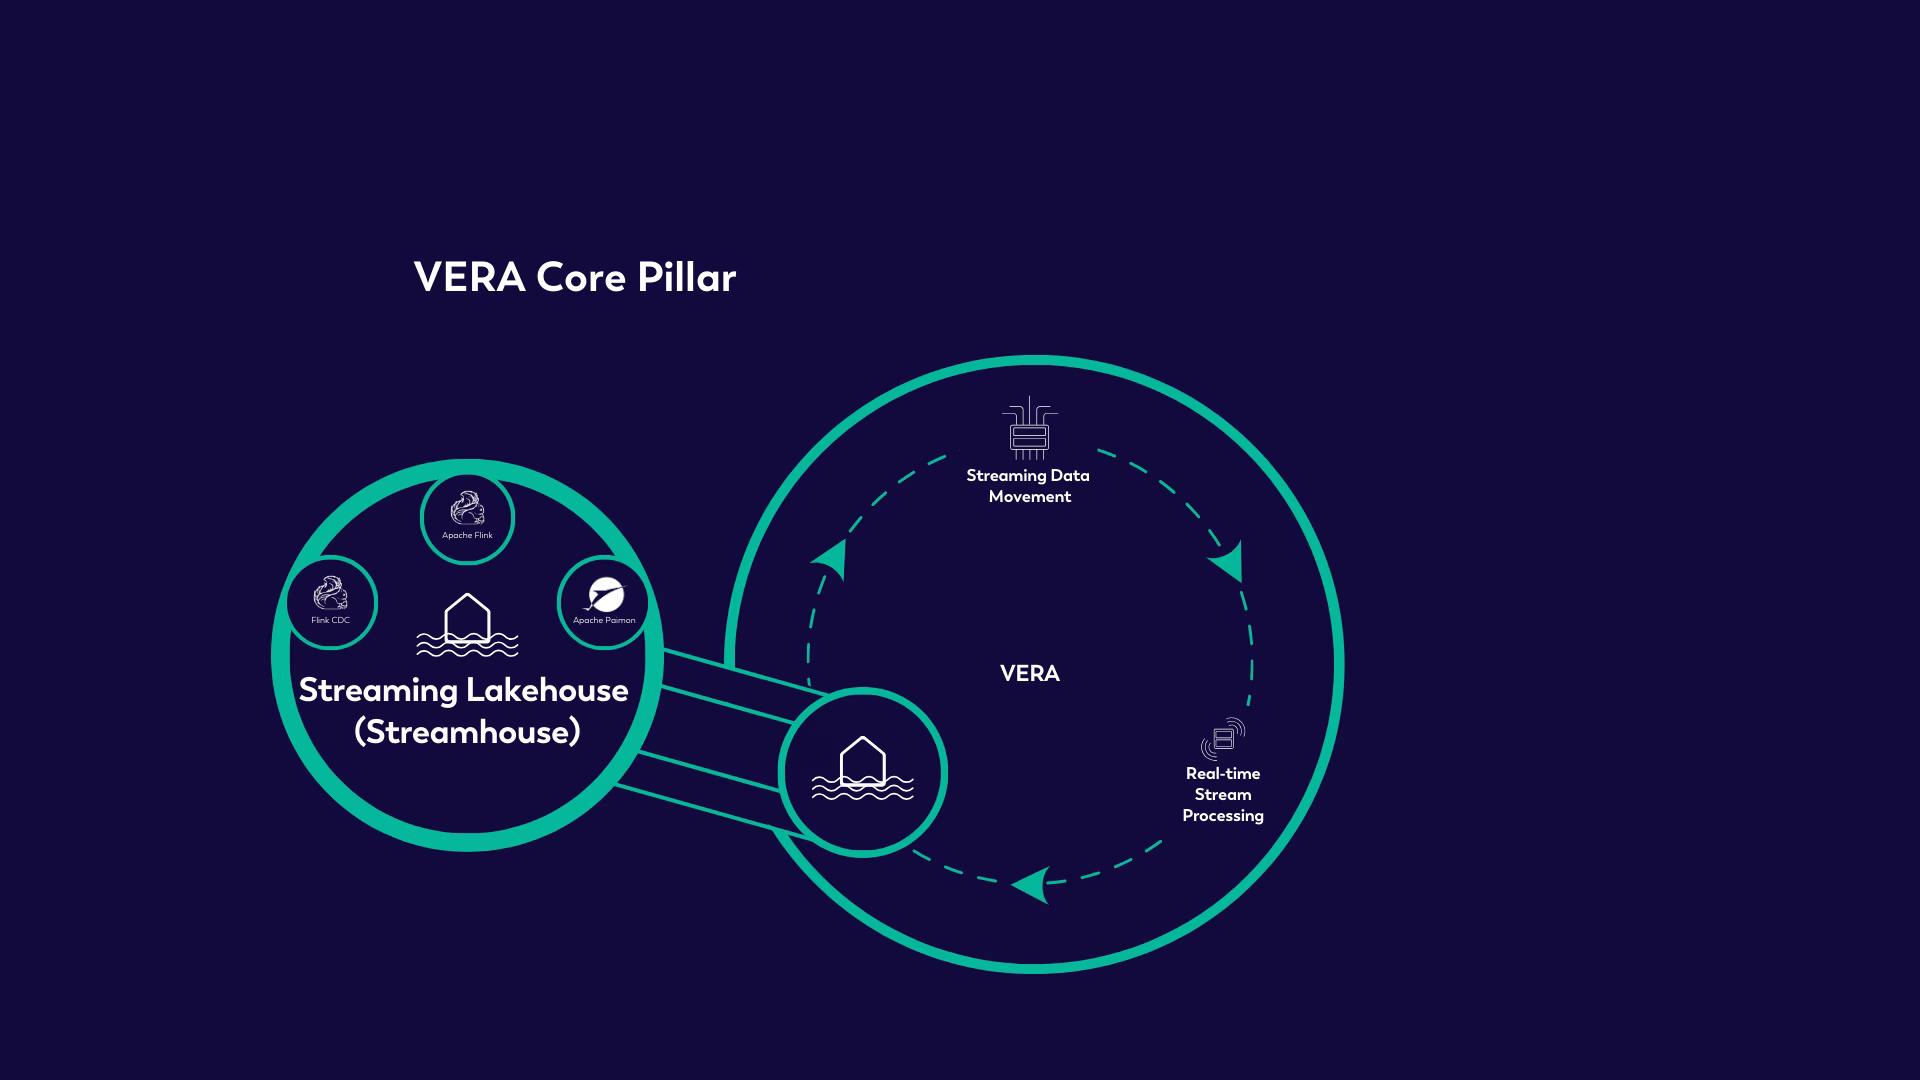
### Who Said Data Lakes Have to be Slow?
The third Core Pillar of the VERA engine is Streaming Lakehouse.
VERA combines Apache Flink for stream processing with Apache Paimon on the streaming storage layer. At Ververica, we call this _Streamhouse_, and it delivers stream processing capabilities while maintaining near-real-time results on the Data Lake.
### The Alternatives
In order to understand why Streaming Lakehouse architecture was created, and why it’s so powerful, let’s take a quick look at the alternatives.
In the past, when mainframes were predominant, storage was incredibly expensive and, as a result, Data Warehouses were created. Data Warehouses are great for storing and managing large volumes of structured data using predefined, fixed schema, but you already need to know ahead of time what outcomes you might want from any data you keep _before_ you place it in a Data Warehouse. In addition, Data Warehouses are also still quite expensive, particularly once you begin to scale your data volume, and you run the potential risks of storing expensive data you’ll never use, or missing important data entirely due to budget constraints.
It didn’t take long for storage and bandwidth to begin to drop in cost, and at that point it became more cost effective to keep every last piece of data, transferring and placing it all into the next evolution: the Data Lake. Data Lakes are huge libraries (akin to our kitchen junk drawers) of both structured and unstructured data, which allow a business to store all of their data in raw, original formats. Data Lakes make it easier to store large amounts of data without having to maintain structure, and allow access to that data to make future decisions.
With Data Lakes, it became possible to keep every piece of data, whether or not it would prove to be useful or usable in the future, and then put it through a query engine to pull relevant decisions at a later time.
What became very clear, very quickly, is that data is extremely valuable, and the value of data (often) depreciates over time. Relying on predefined outcomes or bulk data collection with exact-transform-load (ETL) solutions fails to address the speed and accuracy requirements of modern decision-making processes. While both Data Warehouses and Data Lakes each solve part of a larger challenge, neither solution gives us a truly fast, accurate, and cost-effective way to _act_ on our data.
### Balancing Act
Data Warehouses are expensive, because you pay for the index, you pay for a query engine that you may or may not be using, and you pay for reformatting.
Meanwhile, Data Lakes are a much less expensive place to store immense amounts of data, but their accuracy is measured in hours, not seconds, making them far from real-time. This is great if you have a use case that can wait, but not good when you’re faced with a tight timeline and the need for immediate analytics.
What if you could get the best of both worlds? Imagine a Data Lake that is accurate in seconds, **and** the richness of queries from your Data Warehouse, all at the cost of your Data Lake?
This is where Streaming Lakehouse (Streamhouse) was born.
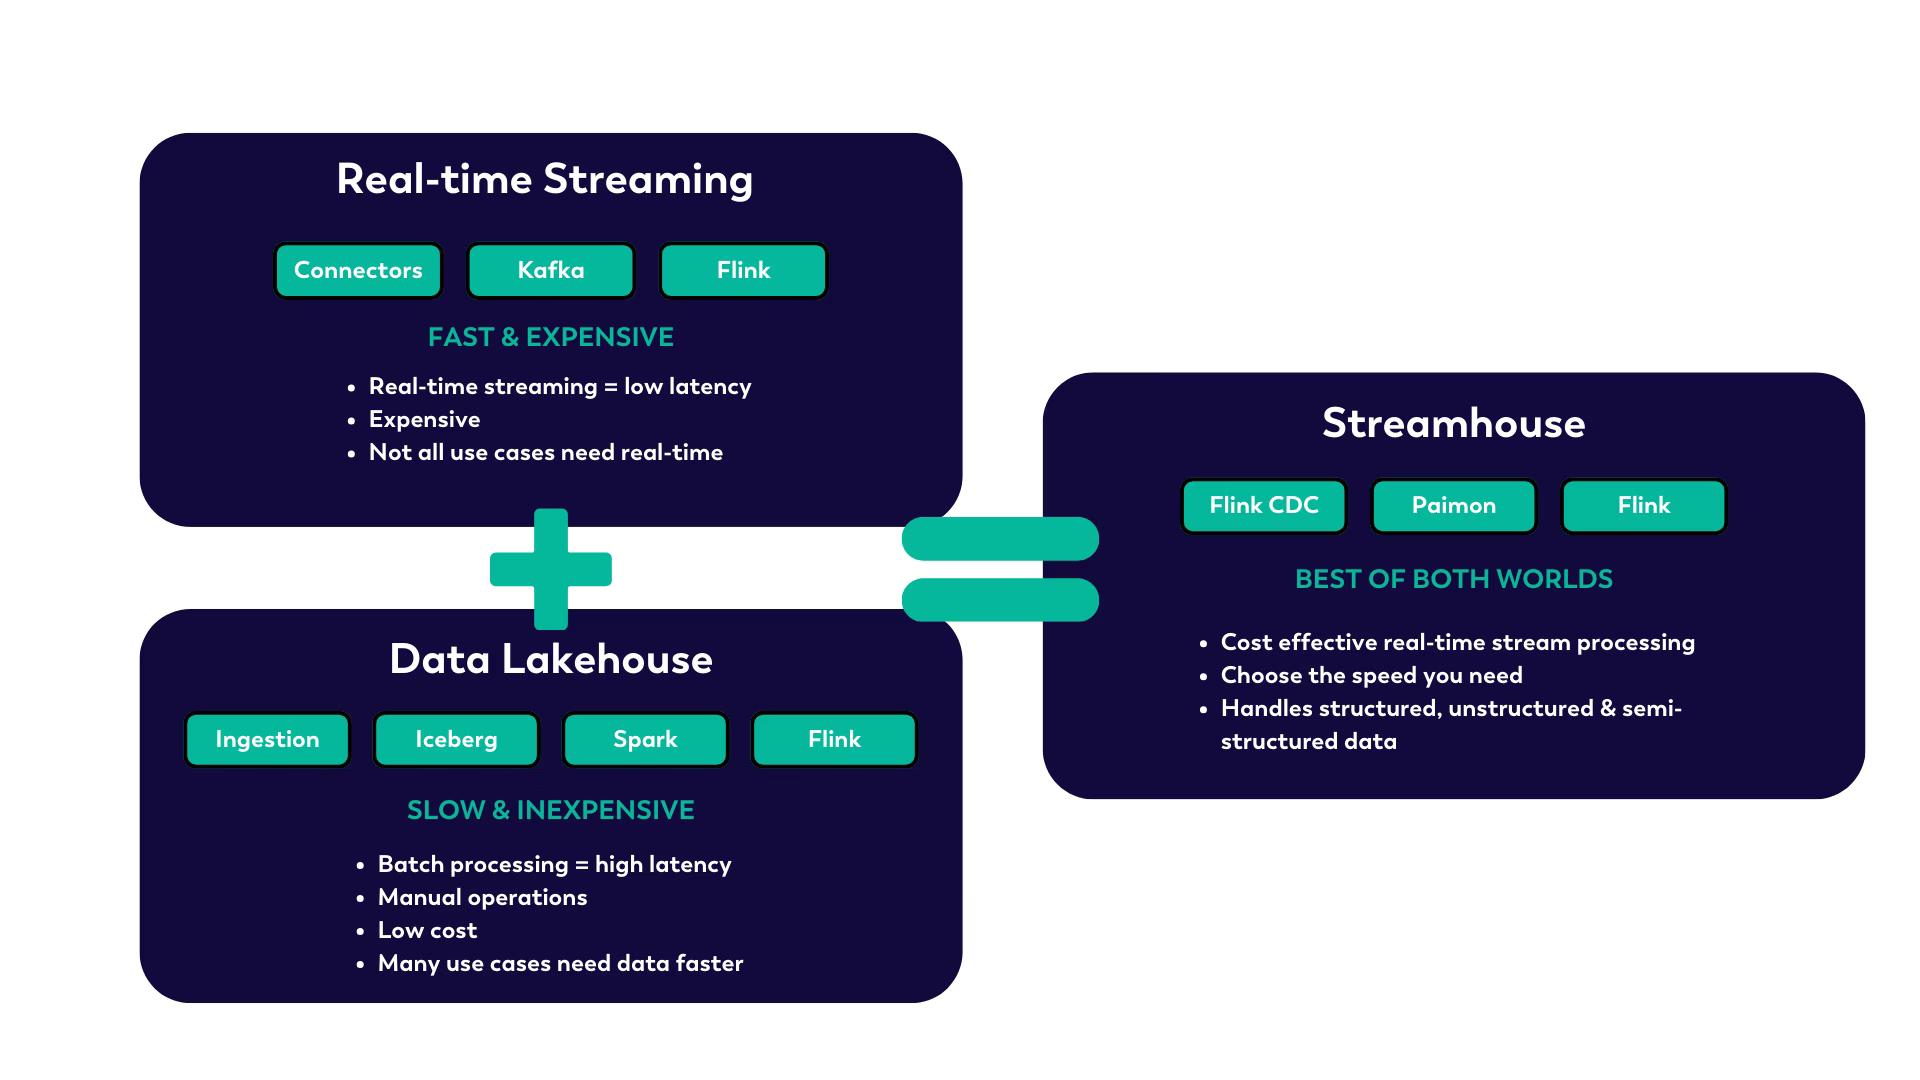
### The Streaming Lakehouse (Streamhouse)
Streamhouse is stream processing on the Lakehouse. It’s the next big thing in streaming analytics that combines streaming with the Lakehouse, making stream processing cost efficient and easily accessible to everyone.
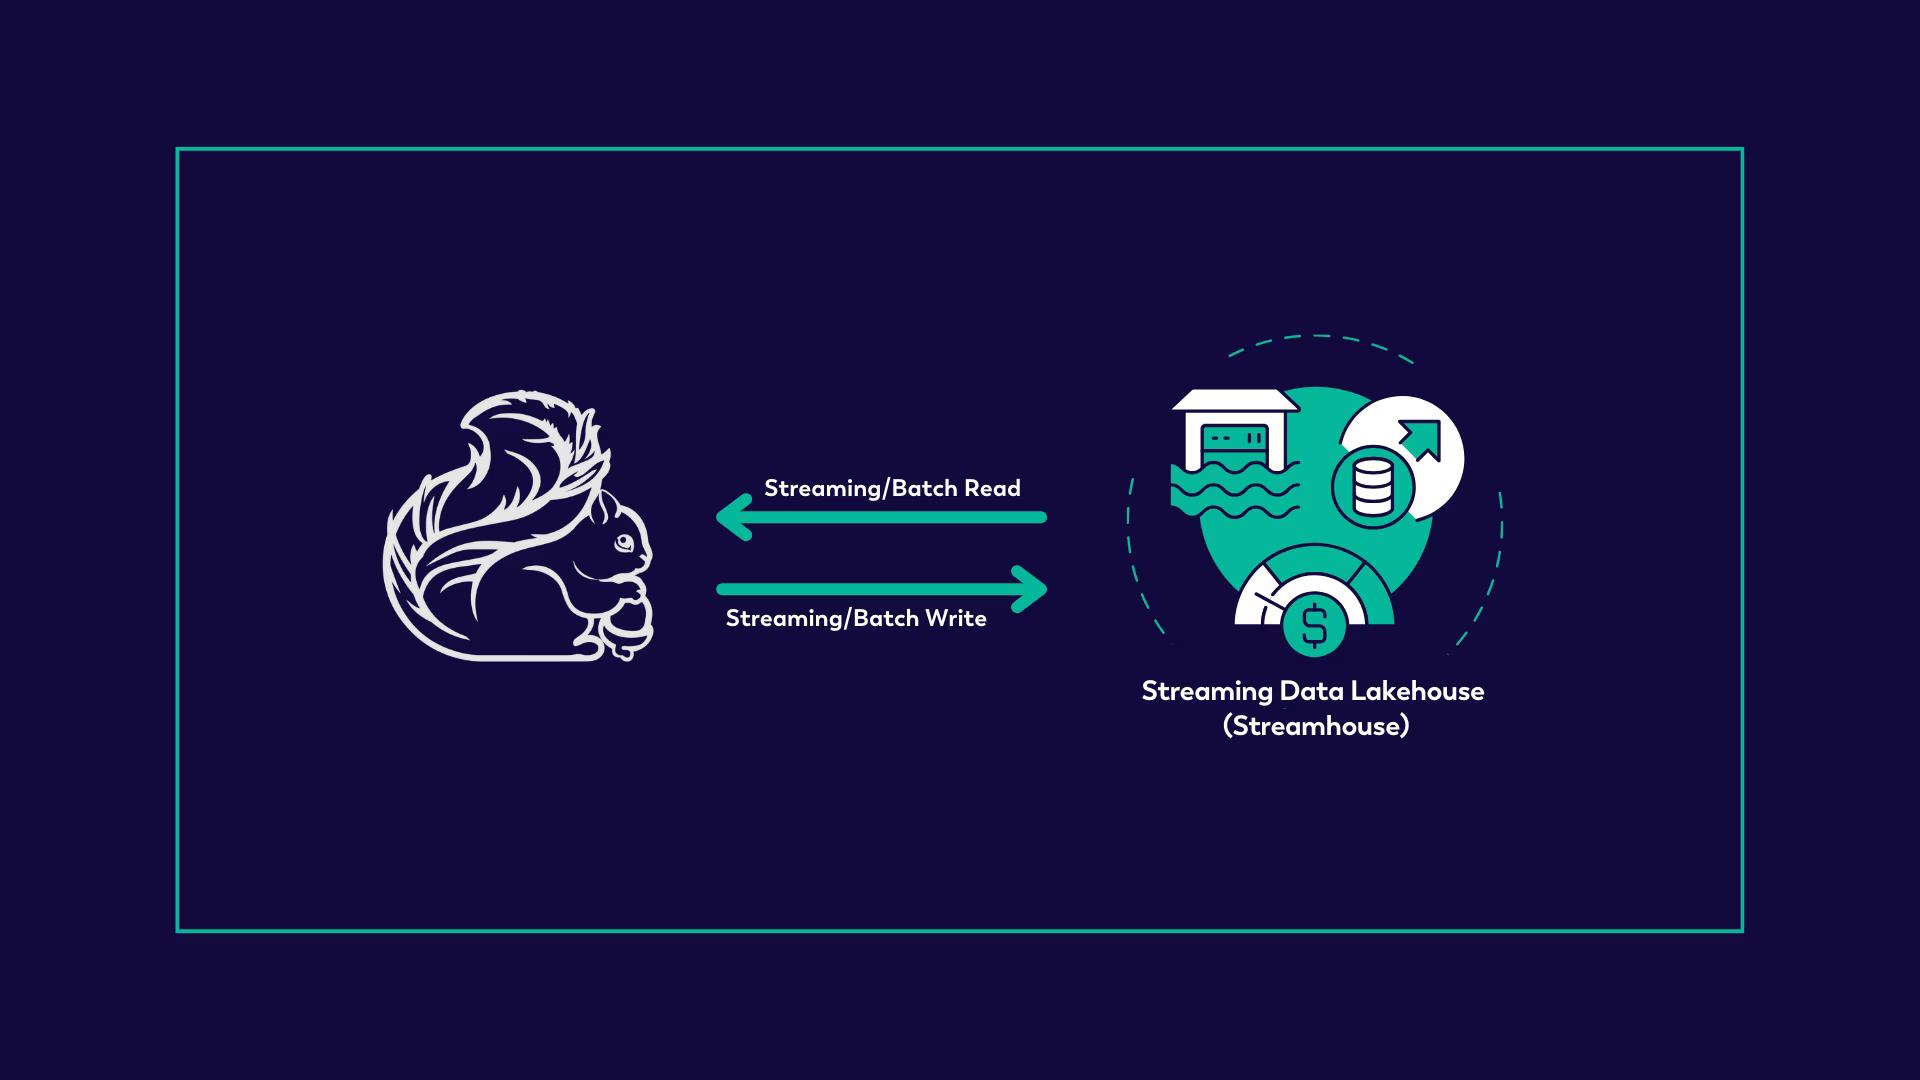
[Jing Ge](https://www.linkedin.com/in/gejing/), Ververica CTO and Apache Flink Committer and PMC Member, first introduced the concept and coined the name "Streamhouse" at Flink Forward Seattle in 2023, which you can read more about in his blog: [Streamhouse Unveiled](https://www.ververica.com/blog/streamhouse-unveiled).
At its essence, Streamhouse provides Flink with a storage layer that leverages a table format to make data in dynamic tables directly accessible. Let’s take a quick look at how Streamhouse achieves this:
1. Flink CDC handles data ingestion and adds the lake entries.
1. Flink SQL performs streaming and batch ETL, and ad-hoc analysis.
1. A set of engines completes data entry, analysis, and queries.
### Benefits For Users
We, (both humans and now AI,) generate A LOT of data, much of which we’ve placed in relatively cheap storage options, without necessarily giving much thought to how and why we might want to access and use that data in the future. Streamhouse navigates the fine line between two existing worlds: historically, real-time streaming is super low latency but very costly, while traditional Lakehouse batch processing may be inexpensive, but is also very slow.
VERA provides the best of both worlds: nearly unlimited storage inside your streaming compute engine means you can run queries across petabytes (or exabytes!) of data without having to compromise your ability to store it in a cost-effective manner.
In addition, with Streamhouse, you can run real-time and near real-time stream processing from one powerful engine, giving you the ability to make informed decisions leveraging both current and historical data.
### Learn More About Streamhouse
Curious to learn more about Streamhouse? In addition to Jing's [blog,](https://www.ververica.com/blog/streamhouse-unveiled) here are a few recommended resources:
- [Streamhouse: Data Processing Patterns](https://www.ververica.com/blog/streamhouse-data-processing-patterns)
- [Stream Processing & Apache Flink - News and Best Practices](https://www.ververica.com/blog)
- [Apache Paimon: The Streaming Lakehouse](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse)
- [Building Real-time Data Views with Streamhouse](https://www.ververica.com/blog/building-real-time-data-views-with-streamhouse)
## Start Your Engine: What Do You Want From Your Data?
In this blog, we’ve introduced the Three Core Pillars of VERA, the engine that powers Ververica’s Streaming Data Platform, which allows you to connect, process, analyze, and govern your data in one streaming data solution.
When combined, VERA's Streaming Data Movement, Real-Time Stream Processing, and Streamhouse provide powerful technical capabilities and allow you to further explore what you require from your data.
### Quick Exercise & Conclusion
Ask yourself:
**What do you want from your data?**
_I want data that…_
- Moves beyond analysis into action.
- Allows me to make informed decisions using both current and historical events.
- Answers complicated questions and use cases, even those with multiple components.
- Can scale from zero to infinity, and back again.
- Runs in real-time and supports batch.
- Processes data while streaming, without being cost-prohibitive.
- Is available in an easy-to-use, consistent, and unified format.
- Resolves conflicts and allows roll-backs in time.
- Provides the best of Flink and data streaming, without having to run and build the solution, architecture or infrastructure myself.
If your answers align with the above, and you are ready to talk about what you want from your data, Ververica can help. [Contact us](https://www.ververica.com/contact) to see a demo, or spin up a deployment of [Ververica Cloud](https://www.ververica.com/cloud) and get started using VERA with $400 free credits.
Up next, in part three of this blog series, we’ll take an even deeper look at VERA’s features and benefits, as well as share some of the performance metrics real users are experiencing using VERA today. We’ll also peek into the future of Ververica’s Streaming Data Platform.
Available now! VERA: The Cloud Native Engine Revolutionizing Apache Flink® Blog Series:
- [Part One: From Stream to Stream](https://www.ververica.com/blog/vera-from-steam-to-stream)
- [Part Three: Full Stream Ahead: The Capabilities and Benefits of VERA](https://www.ververica.com/blog/vera-full-stream-ahead)
## More Resources
- Learn more about [VERA](https://www.ververica.com/vera).
- [Watch more of the interview with Ben Gamble](https://www.youtube.com/playlist?list=PLaDktj9CFcS8rF8IENlEcPNJMqX3TPfAZ) discussing VERA on YouTube.
- Access the [VERA docs](https://docs.ververica.com/introduction/about-vera).
- Ready to get started? Take VERA for a test run by spinning up your own [Ververica Cloud](https://www.ververica.com/cloud) deployment.
- Have questions? Our team can help! [Contact us.](https://www.ververica.com/contact)
- [Join the Apache Flink Community](https://www.flink-forward.org/) at Flink Forward Berlin 2024, filled with Flink training courses, expert speakers, networking, an entire track dedicated to Flink use cases, and much more.
> **INFO:** Thanks!
This blog series wouldn't be possible without the contributions of the many PMC Members, engineers, Ververicans and community members who’ve spent long days creating VERA, in addition to contributing to the Apache Flink project and repo, and supporting additional projects including Apache Paimon and Flink CDC.
In addition, special thanks to Dawn Leamon for her editing expertise and the video content (in addition to her many other talents).
---
---
title: "VERA Blog Series Part 1: From Steam to Stream"
description: "VERA: The Cloud Native Engine Revolutionizing Apache Flink®. Discover how VERA optimizes and modernizes Flink for high-performance stream processing. "
lastUpdated: 2026-05-01T09:48:18.000Z
source_url:
html: "https://www.ververica.com/blog/vera-from-steam-to-stream"
md: "https://www.ververica.com/blog/vera-from-steam-to-stream.md"
---
## VERA: The Cloud Native Engine Revolutionizing Apache Flink® Blog Series
Welcome to part one of a three-part blog series that introduces [Ververica Runtime Assembly (VERA)](https://www.ververica.com/vera), the cloud-native, ultra-high-performance engine that powers Ververica’s Streaming Data Platform. In this first piece, we'll discuss the drivers behind the evolution and creation of the VERA engine.
## From Steam to Stream: Introduction to VERA
Stream processing enables the handling of continuous data streams from an array of sources, including, (but in no way limited to) financial transactions, website analytics, and data from IoT devices. While this technology is not new – the ability to send data over the wire and act on it has been available for a long time now – the ever-increasing number of sources and the sheer scale of data being created makes for an extremely complicated and resource-hungry task. As a result, stream processing on a single machine is usually no longer feasible for businesses and organizations that now process massive data sets across distributed systems consisting of thousands of distributed machines.
While an open-source solution might seem like an attractive proposition, most companies lack the internal resources or expertise required to build the supporting architecture and infrastructure necessary to run complicated solutions using purely open source technologies. That’s precisely why Ververica, (the original creators of Apache Flink®, the open source toolkit that can harness data and analyze it in real time) offers our Streaming Data Platform. Ververica’s Streaming Data Platform handles the complexity of streaming data solutions for businesses looking to quickly and easily harness the power of their data. We do this by unifying the operational, tactical, and strategic decisions required to process distributed data streams in the modern world.
## Meet VERA
[Ververica Runtime Assembly (VERA)](https://www.ververica.com/vera) is the ultra-high performance, cloud-native engine that optimizes Apache Flink and powers Ververica’s Streaming Data Platform. VERA solves the challenges that come with managing large volumes of distributed data, by allowing you to quickly make mission-critical, data-driven decisions. Rather than having to wait for data to be collected and processed before you can act on it, you can analyze and use data in real time. This means you have an immediate realization of value, making your decisions with the most up-to-date information possible. Built to revolutionize Apache Flink, VERA is the stream data processing engine of the future, designed to unify both batch processing and real-time stream processing use cases within one powerful solution.
But what does it mean to say that VERA is revolutionizing Flink? Simply put, VERA is a combination of breakthrough technologies that supply dramatic improvements in efficiency, speed, and scalability when compared to other streaming solutions, including Open Source Apache Flink.
VERA functions as the heart of Ververica’s Streaming Data Platform, and combines the power of three technologies into a singular engine that allows you to connect, process, analyze, and govern your data in one unified streaming data solution. We call these technologies the Three Core Pillars of VERA, and they are:
- Streaming Data Movement
- Real-time Stream Processing
- Streaming Lakehouse (Ververica’s Streamhouse).
Working together, these pillars provide seamless support for data ingestion, stream processing in real time, and streaming Lakehouse architectures. As a result, VERA democratizes stream processing and allows you to choose the functionalities you need to solve an infinite number of streaming data use cases.
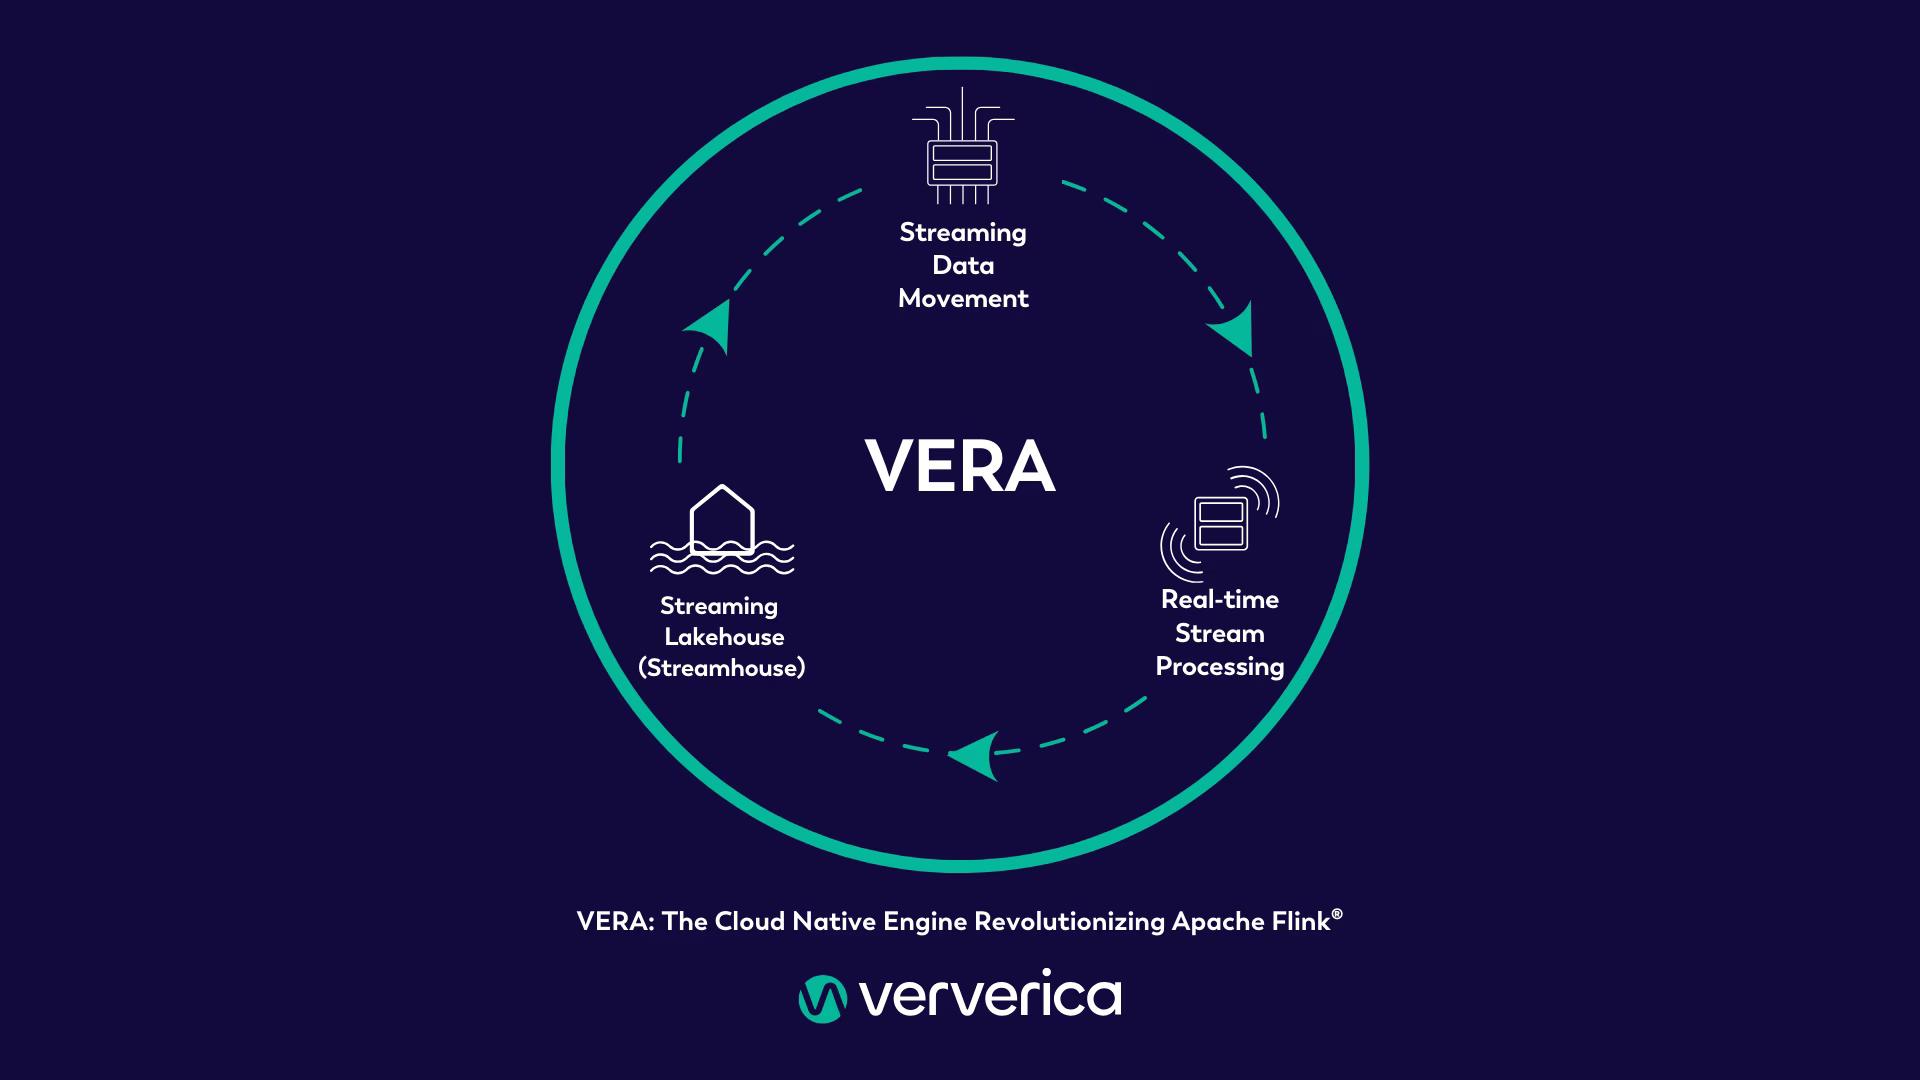
In the second blog in this series, we deep dive into the technology behind each of the three core pillars that comprise the VERA engine. For now, let’s explore why VERA was created in the first place.
## The Evolution of VERA: Why Do You Need VERA?
While VERA is an integral part of Ververica’s Streaming Data Platform, it is the engine that powers the Streaming Data Platform, rather than a stand-alone product. Understanding why VERA was built, and the challenges it helps to solve provides clarity into the business advantages it offers and the astonishing number of streaming data use cases it can solve.
For those who want to self-manage their data stream processing systems, VERA doesn’t displace open-source Apache Flink. In fact, Ververica continues to contribute heavily to the Apache Flink community and OS project. Intentionally, VERA, and Ververica’s Streaming Data Platform, are open-core technologies, built to be 100% compatible with OS Flink, so there is never a worry of vendor lock-in.
> "If it says Flink on the outside, it's Flink on the inside."
-Alex Walden, Ververica CEO
The combination of using established Flink technology with the robust additional capabilities available in VERA is what allows Ververica to offer a superior service, boasting phenomenal speed and scalability. Better yet, this service is available in the deployment method of your choice, so whether you want Ververica clusters hosted on Ververica’s public cloud, or clusters deployed and managed on-premise, VERA is full stream ahead.
Hear more about VERA and the 3 Core Pillars in this 1.5 minute video from Ben Gamble, Ververica Field CTO:
[Video](https://cdn.sanity.io/files/6b38iw1w/production/3ab7be5a6668fb06828cabd5587abbecf655d53b.mp4)
You can also watch the entire short video playlist: ["Introducing VERA The Engine Revolutionizing Apache Flink"](https://www.youtube.com/watch?v=SE8eRBwVuo4&list=PLaDktj9CFcS8rF8IENlEcPNJMqX3TPfAZ&pp=gAQBiAQB) available now on YouTube.
## Modernizing Open Source Flink
Let’s take a step back to discuss the circumstances that inspired the development and creation of VERA in the first place. VERA was born out of the necessity to address existing key challenges in stream data processing, including challenges found in OS Apache Flink.
While Flink is considered the de facto gold standard streaming solution for _good_ reason, it’s also had more than ten years of continuous development. The [rise](https://git-contributor.com/?chart=contributorOverTime&repo=apache/flink,apache/incubator-paimon,ververica/flink-cdc-connectors) in Flink’s popularity and growth over time proves how beneficial and advantageous the technology is, but, like all software, it must continue to adapt to new pressures that evolve naturally over time.
Below are some of the challenges that VERA aims to address in OS Flink today, including:
- Historical single-tenant design and fragmented direction.
- High operational complexity and costs associated with building, running, and managing a deeply technical OS solution.
- Unfriendly “black box” behavior for developers, who would rather spend their time building applications that solve specific use cases.
- Architecture that has not changed or evolved to support today’s workloads, deployment methods, and storage models.
- Operational overhead and additional tech stack requirements to make OS Flink work in modern streaming data use cases, many of which demand both batch and real-time streaming capabilities.
- Inability to run natively in modern cloud environments.
## Ververica's Solution
The VERA engine solves all of these key challenges, simultaneously modernizing and merging tried-and-true technologies, including:
- Keeping the best-in-class functionality of OS Flink, while also solving the expected limitations of a 10-year old technology.
- Creating a more developer-friendly experience.
- Reducing operational complexity and cost for users.
- Allowing Flink to run natively in modern cloud environments.
- Handling both batch and streaming use cases, including offering support for high-throughput, low-latency workloads, all without incurring additional significant cost.
VERA's innovative architecture and intelligent resource management provide a robust and scalable platform capable of handling high-throughput, low-latency workloads. Its adaptive capabilities ensure optimal performance under varying conditions, and its ease of use empowers developers to focus on building applications and solving complex streaming data use cases, rather than managing complicated infrastructure.
VERA redefines the possibilities for real-time stream processing by providing a modern cloud-native engine that is both powerful and user friendly. In addition, VERA ultimately democratizes stream processing and revolutionizes Apache Flink.
Check out Ben quickly explaining how VERA is revolutionizing Apache Flink in this 1 minute video:
[Video](https://cdn.sanity.io/files/6b38iw1w/production/6fde6194bed143798cc8204c54529c9796e8c860.mp4)
Stay tuned for part two of this blog series introducing VERA, where we’ll dive into the technical components of the Three Core Pillars of VERA, and discover how VERA provides a one-stop shop for all your data streaming needs, whether you are processing, storing, moving, or using data.
Read the rest of the VERA: The Cloud Native Engine Revolutionizing Apache Flink® Blog Series:
- [Part Two: Under the Hood: VERA’s Three Core Pillars](https://www.ververica.com/blog/vera-under-the-hood)
- [Part Three: Full Stream Ahead: The Capabilities and Benefits of VERA](https://www.ververica.com/blog/vera-full-stream-ahead)
## More Resources
- [Learn](https://www.ververica.com/vera) about VERA.
- [Watch](https://www.youtube.com/playlist?list=PLaDktj9CFcS8rF8IENlEcPNJMqX3TPfAZ) more of the interview with Ben Gamble discussing VERA on YouTube.
- Access the VERA [docs.](https://docs.ververica.com/introduction/about-vera)
- Ready to get started? Take VERA for a test run by spinning up your own [Ververica Cloud deployment.](https://www.ververica.com/cloud)
- Have questions? Our team can help! [Contact us.](https://www.ververica.com/contact)
- [Join](https://www.flink-forward.org/) the Apache Flink Community at Flink Forward Berlin 2024, filled with Flink training courses, expert speakers, networking, an entire track dedicated to Flink use cases, and much more.
---
---
title: "(Re)Introducing Ververica"
description: "Learn about Ververica's journey to revolutionize stream processing. Explore VERA, the engine powering our advanced Unified Streaming Data Platform."
lastUpdated: 2026-05-05T05:22:51.000Z
source_url:
html: "https://www.ververica.com/blog/reintroducing-ververica"
md: "https://www.ververica.com/blog/reintroducing-ververica.md"
---
This blog provides a brief history of Ververica, our vision, and why you should choose Ververica for your streaming data needs.
## From Concept to Code
You may already be familiar with Ververica as the original creators of Apache Flink®, but if not, let’s start at the beginning…
Similar to Apache Spark™, Flink originated from an academic project. In 2009, the “Stratosphere” student research project at the Technical University of Berlin set out to develop the next generation Big Data Analytics platform. While Flink has since evolved far beyond its initial scope, its roots lie in academia with the mission to: “Write like a programming language, execute like a database.”

Starting in 2009, our founders were hard at work developing a prototype and, in 2014, [Apache Flink](https://flink.apache.org/) was born; their journey culminated in the donation of Flink to the Apache Software Foundation.
At the same time, Ververica (formerly known as Data Artisans) was formed to support the Flink project and make it successful both in the open-source community and commercially. We continued to develop Apache Flink, extending its feature set, improving its usability and, of course, fixing bugs.
In 2015, we made the pivot to focus on stream processing and real-time data - and never looked back! By 2016, more and more companies began relying on Apache Flink for business critical tasks creating a tipping point for Apache Flink adoption.
Ververica announced our first proprietary product in 2017, called [Veverica Platform,](https://www.ververica.com/product) which provided tooling and expert help with Apache Flink, making deployment and management easier.
Flash forward to 2024 and the upcoming 10-year Apache Flink celebration at [Flink Forward Berlin](https://www.flink-forward.org/berlin-2024) and launch of our new Unified Streaming Data Platform deployments.
## Stream Processing for Everyone
Flink today is considered the de facto gold standard streaming solution and it has more than ten years of continuous development from community members. The rise in Flink’s popularity and growth over time proves just how critical the technology is. But like all software, it too must continue to adapt to new pressures that arise over time.
In the span of ten years, the world of data streaming has naturally progressed and looks very different today than it did in the past. These advancements in stream processing led us to think about how we could evolve and adapt Apache Flink to meet the requirements of the modern era. So, we intentionally set out to democratize stream processing and make it easily accessible for everyone, not just those with expertise and unlimited budgets or resources.
**The result: We built VERA.**
Ververica Runtime Assembly (VERA) is our engine that operationalizes streaming data – moving it, processing it, and storing it – to provide a one-stop shop for all your organization’s data streaming needs. VERA lies at the heart of our Unified Streaming Data Platform, which makes it easy for you to harness insights from your data, at any scale.
## You're in Good Hands with Ververica
At Ververica, our vision is to empower organizations to fully realize the value of their data through stream processing technologies.
We are continuously innovating and pushing the boundaries of data streaming and processing solutions, which allows us to provide unparalleled customer service and foster a vibrant ecosystem of partners and developers. By consistently open-sourcing our innovations and giving them back to the community, we enable businesses to speed up application development, streamline operations, and boost agility to better drive innovation and meet evolving customer needs.
With our advanced Unified Streaming Data Platform powered by VERA (the engine that revolutionizes Apache Flink), customers can harness data to solve any business problem at scale while maintaining SLAs. This platform leverages advanced data streaming capabilities in real-time or on the Lakehouse, making it possible to connect, process, govern and analyze data across infinite use cases.
If you’re interested in learning more about Ververica or trying out our Unified Streaming Data Platform, please [contact us](https://www.ververica.com/contact).
## More Resources
- Curious to learn more about Ververica's Unified Streaming Data Platform powered by the VERA engine? [Check out](https://docs.ververica.com/introduction/about-vera) the docs.
- Ververica is proud to organize Flink Forward, the conference dedicated to all things Apache Flink and Streaming Data. Join the Flink community at Flink Forward Berlin 2024 in October. [Learn more and register.](https://www.flink-forward.org/)
---
---
title: "Performing API Calls Via a Custom HTTP Connector Using Flink SQL"
description: "Learn how ING Bank leveraged FlinkSQL to build a novel HTTP connector for data enrichment, connecting to API endpoints for stream processing."
lastUpdated: 2026-05-05T05:22:08.000Z
source_url:
html: "https://www.ververica.com/blog/performing-api-calls-via-a-custom-http-connector-using-flink-sql"
md: "https://www.ververica.com/blog/performing-api-calls-via-a-custom-http-connector-using-flink-sql.md"
---
With [Flink Forward Berlin 2024](https://www.flink-forward.org/) coming up fast, Ververica is spotlighting some of the interesting learnings from prior years and the engineering techniques behind them. This guest blog from [Erik de Nooij](https://www.linkedin.com/in/erik-de-nooij-93ab1a/), current Program Committee Member and Flink Forward Speaker, focuses specifically on data enrichment by connecting to an API endpoint using FlinkSQL, by building a novel HTTP connector for FlinkSQL at ING bank.
This blog provides additional information to what ING shared during [this presentation](https://www.flink-forward.org/seattle-2023/agenda#model-inference-in-flink-sql-using-a-custom-http-connector) last year at Flink Forward Seattle 2023. You can watch the [recording](https://www.ververica.academy/courses/f352775b-6c43-475b-84e0-d6070c57b1a7/activities/8ef06409-d384-45bf-9f18-9f9112931970) of that session by signing into [Ververica Academy](https://www.ververica.academy/app). ING are long time users of Apache Flink and Ververica, and in this piece Erik shows how ING enables its business users to do API calls, including model inferencing using Flink SQL.
## Introduction
Data enrichment is a common task in stream processing, and Flink offers various capabilities to connect to external sources like lookup tables, databases, or web services that can be used to fetch the required data during the processing of events in a stream.
Although calling an API from Flink SQL for data enrichment purposes was our first and main objective, without changing any code it can also be used for model inferencing in case an ML model has been wrapped in an API which may be the case if you use e.g. MLflow for model inferencing.
## Background
ING Bank has been an early adopter of Apache Flink since 2016. Our first implementation was a custom Scala implementation in which we implemented a DSL (Domain Specific Language) enabling business users to configure their use cases. Note that back then Flink SQL did not exist yet, but we already adopted the same philosophy that use cases could be described in a declarative way.
For this initial custom implementation, custom code was written to be able to call APIs. However, when ING adopted Flink SQL and moved to a SQL-first approach it revealed a gap in the out of box capabilities of Flink SQL, necessitating the development of an alternative solution to do data enrichments: the HTTP connector.
## Requirements for the HTTP connector
The following section lists the requirements followed by a paragraph per requirement providing additional details.
1. Data enrichment must be performed asynchronously via API calls using plain SQL.
1. The specifications of the API as defined in the Open-API definition must be adhered to.
1. The runtime characteristics of the API endpoint should be considered.
1. Life cycle management of libraries that implement an HTTP client.
### Ad 1: Data enrichment must be performed asynchronously via API calls using plain SQL.
In Flink SQL, data sources and sinks are abstracted as tables. This allows you to use standard SQL to declaratively define the transformations you want to perform on the data. The logical consequence is that to support data enrichment via API calls as part of these transformations, also API endpoints need to be abstracted as tables.
By abstracting an API endpoint as a reference table, a [lookup join](https://nightlies.apache.org/flink/flink-table-store-docs-master/docs/development/lookup-join/) can be used to enrich data when processing events.
A lookup join in Flink SQL is implemented using the processing Time Temporal Join syntax which is characterised by having a common key (like any other join) but also by time attributes of the participating events. Asynchronicity is achieved by inheriting from the AsyncLookupFunction class.
### Ad 2: The specifications of the API as defined in the Open-API definition must be adhered to
An API endpoint that is called is often developed and operated by another team, or even another organisation than the team using the HTTP Connector to call the API, so the specification of the endpoint is a given.
This specification of an API is typically described via a Swagger file or Open API document which describes the following items:
1. API Information: General information about the API, including title, version, description, and contact details.
1. API Endpoints: Available endpoints of the API, including their paths, HTTP methods (GET, POST, PUT, DELETE, etc.), and parameters.
1. Request and Response Formats: Data formats and models used for request payloads (inputs) and response payloads (outputs) of the API, including data types, validation rules, and example data.
1. Authentication and Authorization: Description of the authentication mechanisms used by the API, such as API keys, OAuth, or JWT tokens.
1. Error Handling: Documentation of the possible error responses that the API can return, including the HTTP status codes, error messages, and error code conventions.
1. API Documentation: Additional descriptive information about the API, such as usage guidelines, examples, and explanations for each endpoint.
1. API Schema: Definition of a schema or data model for the API, describing the structure and properties of the data objects used in the API.
### Ad 3: The runtime characteristics of the API endpoint should be considered
The HTTP connector should be able to deal with the characteristics of a specific API being:
1. Scalability
- Although APIs are typically designed to scale there is a limit to the amount of TPS they can handle. To avoid flooding APIs with requests, caching has been implemented on the following two levels.
- Result caching. If the result of the API call has been cached it is returned immediately
- Request caching. if the same request (same "key") is pending, the request is coupled with the previous request instead of calling the API again.
1. Security
- APIs typically require authentication, often implemented interpreting a credential passed on via the HTTP header. The table definition has columns that can be populated for the HTTP connector to set the HTTP headers
1. Versioning
- APIs often undergo updates and changes over time. When the definition of the API changes this will be handled by generating a new table definition and give it a new unique table name.
1. Data format
- APIs can support various data formats, such as JSON, XML, or custom formats
1. Response Handling
- A well-designed API provides specific HTTP codes with corresponding specific response messages. This includes the error codes. Each HTTP code results in a specific column in the table definition containing the field(s) to store those response (error messages.
### Ad 4: Life cycle management of libraries that implement an HTTP client
To have the HTTP connector perform an API call an HTTP client is required. There are many libraries available that implement an HTTP client, some of them are compatible with the libraries used by Flink but some are not. To avoid dependencies issues, an HTTP client of our choosing has been used that has been deployed exclusively in a side car container that co-exists in the pod of the Flink taskmanager. From the Flink taskmanager the sidecar is called using an HTTP client that is implemented in a library already available as part of the Flink libraries.
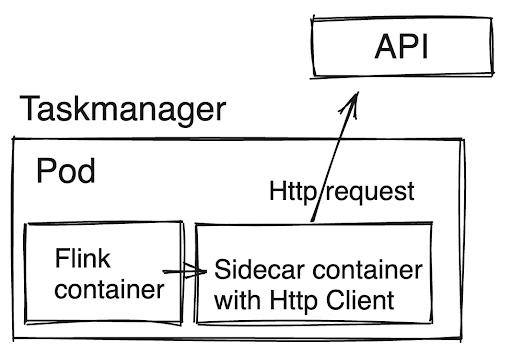
## Using the HTTP connector from a user perspective
Now that the requirements are clear, let’s look at using the HTTP connector from the perspective of a user that wants to do an API call in a use case built using Flink SQL.
### Step 1: Convert the open-api file to a Flink SQL table definition
To convert an open-api file to a Flink SQL table definition the following configuration is needed by the conversion script:
- The path to the open-api-file.
- Which endpoint to use from the open-api-file, since typically an open-api file defines multiple endpoints
- Which _method_ to use, this can be _get_ or _post._ Note that the _post_ method is not used to do an update but to do a functional _get_ by passing on the required parameters via the request payload and not via the query parameters to the url.
- The _path_ that is to be used by the http client to construct the url
- The primary key column(s) which are one or more fields used in the lookup join
- Etc, the full list is in the paragraph on implementation details
Based on the configuration the following is generated:
- The Flink SQL table definition: especially for large open-api definition files _generating_ the Flink SQL table definition instead of _manually creating_ it, is the only way to make this an effortless and errorfree exercise.
- Technical information needed to execute the API call stored as table options: From the open-api file several parameters are retrieved that are needed by the HTTP connector to do the API call, these parameters are added to the table definition as table options, e.g.
The table definition that is generated contains both the key-fields that are used in the _request_ as well as the fields that are used in the _response._ In other words, the table is being used as an abstraction to pass information back and forth between the Flink job and the API. In the appendix there is a sample open-api file and the corresponding generated Flink SQL table definition.
### Step 2: Create the table definition for the input table and output table
A lookup join enriches information based on a (compound) key field from an input table and uses the enriched information to populate the fields of an output table.
In the example that we will be using below the input table only contains a customer identifier which is used to do the API call. For the given customer identifier, the API will return firstName, lastName and date_of_birth.
Note: The table definitions of the input and output table can be found in the appendix
### Step 3: Creating the lookup join
Now that we have the definitions of all tables, we can write our query. The query is a standard lookup join shielding all the technical details of the API call that are being made under the hood. This enables every end user with standard SQL knowledge to do data enrichments without the need to have technical knowledge of the API. In other words, something inherently complex has been made very easy to use.
```sql
INSERT INTO `outputTable` (
`id`,
`firstName`,
`lastName`,
`date_of_birth`
)
SELECT
inputTable.`id`,
apiTable.`firstName`,
apiTable.`lastName`,
apiTable.`date_of_birth`
FROM inputTable
INNER JOIN apiTable FOR SYSTEM_TIME AS OF inputTable.procTime
ON inputTable.id = apiTable.id
WHERE apiTable.httpStatusCode = 200
```
### Step 4: Deploy the Flink job and test it
Once the Flink job has been deployed, an event on the input topic triggers the API call and in this example the customer ID is found, and the fields returned by the API are written to the output topic.

> **NOTE:** The screenshot above has been taken from the outputTable in the Flink SQL editor. The field values shown are those returned by the API.
## Error handling
Proper error handling is important for any IT system but maybe even more so when doing an a-synchronous API call from a stream to an API that you do not have any control over.
When calling an API, errors can be divided into two categories: The “known” documented errors that are described in the open-api file for the various http return codes errors and the ones that you don’t have any control over like network errors.
### The known documented errors
If the API returns a http code code other than 200 then the specific field for that code is being populated. E.g. calling the API with a non-existing key will populate the httpcode404 field and leave the other fields empty. The same mechanism is in place for all http codes defined in the swagger file. Additionally, there is a fall back implemented in case an HTTP code is returned that has not been defined in the open-api file since documentation tends not to be flawless.
### The unknown errors
Errors in this category are timeouts, network issues and similar issues that prevent the request to either reach the API or that prevent the API to return a response. The timeouts can be detected by the Http Client in the sidecar which will then return a HTTP 408 return code.
## Model inferencing and updating and deleting data via API calls
The original purpose behind the HTTP connector was to be able to do data enrichments using plain SQL. Technically this can be done by a _get_ in case the parameters are passed on via the url or a _post_ in case the parameters are passed on via the request body.
Over time additional requirements were met with only slight additions to the HTTP connector.
- Model inferencing: Model inferencing did not require a change in the HTTP connector, it was implemented by wrapping the model in an API and describing the API using an open-api file.
- Updating, creating and deleting information via an API call. Since the _post_ method was already implemented it only required a small change to use it to call an API to update or create information. The only change required was to disable the caching which was in place in case the _post_ method was used to perform a functional _get_. An argument could be made that changing information should be done via a sink at the end of the execution plan. Reason that this was not implemented that way, was because the lookup join had additional advantages in error handling. In other words, depending on the http code being returned one could handle the event differently. In the case of a sink this would be a _send and pray_ scenario.
## Implementation details
This section peeks under the hood and explains several implementation details.
The behaviour of an API table is configured via table options which are part of the table definition and are generated by converting an open-api file. Below is an example of a table where the various options are detailed further down.
```sql
CREATE TABLE apiTable (
-- See Appendix for an example of the fields that are generated for a given open--- api file
) WITH (
-- connector options
'connector' = 'api-endpoint-ing', -- Mandatory table options
'host' = 'api.mycompany.com',
'method' = 'post',
'path-template' = '/lookup',
'status-code-column' = 'httpStatusCode',
'response-column-prefix' = 'httpcode',
'format' = 'json', -- Optional table options
'base-uri' = '${api_base_uri}',
'http-connect-timeout' = '5 seconds',
'http-socket-timeout' = '10 seconds',
Etc, see further down
)
```
## The connector _'api-endpoint-ing'_
The API table is a Dynamic table meaning Flink does not own the data itself. The content of a Dynamic table comes from an external system, in this case it comes from an API response. Implementing the connector can be done by hooking into the existing stack. To make it a bit more specific, the custom _'api-endpoint-ing'_ connector has been implemented by creating a class _'ApiDynamicTableFactory'_ which implements the Java interface DynamicTableSourceFactory which has several methods that need to be implemented as document below.
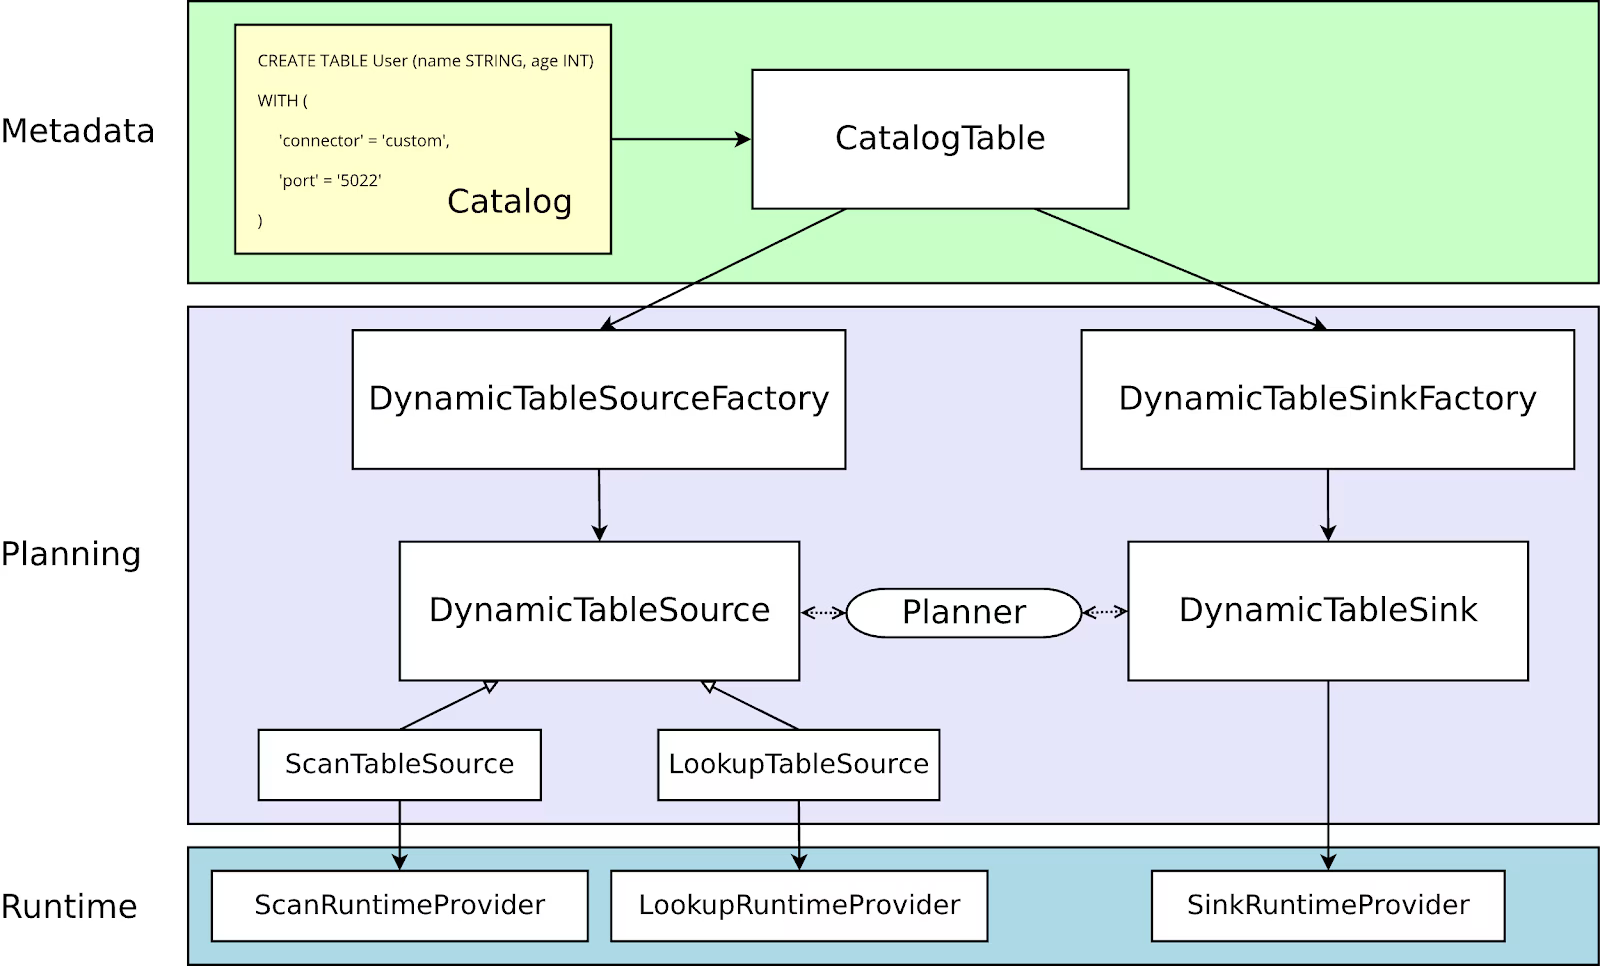
The function _`factoryIdentifier`_ registers the connector _`api-endpoint-ing`_ to Flink
```java
@Override
public String factoryIdentifier() {
return "api-endpoint-ing";
}
```
The function _`requiredOptions`_ makes the mandatory table options known to the connector so that the connector can construct the request and knows in which columns to store the result. The actual values come from the mandatory table options
```java
@Override
public Set> requiredOptions() {
final Set> options = new HashSet<>();
options.add(HOST); // FQDN of the host that serves the API
options.add(METHOD); // post or get
options.add(PATH_TEMPLATE); // Query URL parameter, e.g. /lookup
options.add(STATUS_CODE_COLUMN); // Field used to store the httpcode
options.add(RESPONSE_COLUMN_PREFIX); // Prefix applied to all column names
return options;
}
```
The function `_optionalOptions_ ` is similar to the function `_requiredOptions_` with the difference that these options are optional and are used for more specific APIs and to optimize the runtime behavior of the connector to fit the runtime characteristics of the API.
```java
@Override
public Set> optionalOptions() {
final Set> options = new HashSet<>();
options.add(BASE_URI); // base-uri used to call the api
options.add(REQUEST_BODY_COLUMN); // Column name for for the request-body
options.add(QUERY_COLUMNS); // Columns names mapped to query-arguments
options.add(HEADER_COLUMNS); // Columns names mapped to header values
options.add(HTTP_CONNECT_TIMEOUT); // Timeout setting for the HTTP connection
options.add(HTTP_SOCKET_TIMEOUT); // Timeout setting for the SOCKET connection
options.add(HTTP_VALIDATE_AFTER_INACTIVITY); //Re-validate connections setting
options.add(HTTP_TIME_TO_LIVE); // Total span of time connections
return options;
}
@Override
public DynamicTableSource createDynamicTableSource(Context context)
…
// Helper functions implementing the functionality of the DynamicTableSource
…
return new ApiDynamicTableSource(
apiEndpointDefinition,
decodingFormat,
encodingFormat,
producedDataType,
cache);
}
```
Finally, the core of the runtime behavior is in the `_ApiRowDataAsyncLookupFunction_` class which has all parameters to its proposal and implements the construction of the HTTP request and handles the response.
## Discussions & open questions
### Is the HTTP Connector open source?
No, it has not been open sourced at this moment. Reason being is that there are several implementation details that are ING specific. Then again, certain parts can be beneficial to other users of Flink SQL and can be open-sourced. E.g. the tool to generate a table definition based on an open-api file which is very similar to the tool we have built to convert an. avro schema to a Flink SQL table definition.
Both the HTTP connector and the ING specific Kafka connector are based on standard connectors with additional ING specific security functionality which is the reason why the source code of these connectors cannot be open sourced in its entirety.
### How does the HTTP connector relate to FLIP_437 number?
The HTTP connector can also be used for model inferencing based on the condition that the ML model is wrapped in an API. If that condition is met, then an end-user can do model inferencing using plain SQL. The approach that is outlined in [FLIP 437](https://cwiki.apache.org/confluence/display/FLINK/FLIP-437%3A+Support+ML+Models+in+Flink+SQL) is a programmatically approach that requires implementing a Java interface.
## Future outlook
ING has adopted a SQL first approach for its Streaming Data Analytics (SDA) platform and where possible a SQL only approach. Paramount to its success is being able to abstract all sources and sinks using tables and where needed develop the relevant connectors.
Moving forward, SDA is expected to play a bigger role in the orchestration of model inferencing via integration with a feature store. Last but not least, we are investigating if and how SDA can play a role in the RAG architecture of Generative AI and LLM’s. Developments in these areas will be shared via additional future blogs and possible on Flink Forward (subject to abstract approval).
## Resources
If you'd like to learn more about Apache Flink and network with the Flink Community, including Erik, tickets for Flink Forward 2024 in Berlin are available [here](https://www.flink-forward.org/).
---
---
title: "Ververica donates Flink CDC - Empowering Real-Time Data Integration"
description: "Discover how Ververica donated Flink CDC to Apache Software Foundation, empowering real-time data integration."
lastUpdated: 2026-05-05T05:32:32.000Z
source_url:
html: "https://www.ververica.com/blog/ververica-donates-flink-cdc-empowering-real-time-data-integration-for-the-community"
md: "https://www.ververica.com/blog/ververica-donates-flink-cdc-empowering-real-time-data-integration-for-the-community.md"
---
Ververica has officially donated Flink Change Data Capture (CDC) to the Apache Software Foundation. In this blog, we’ll explore the significance of this milestone, and how it positions Flink CDC as a one-stop, real-time data integration solution based on Apache Flink.
## Overview
CDC Connectors for Apache Flink® (also known as Flink CDC) is an open-source project on Github, developed by Veverica.
Flink CDC was initially launched in July 2020 by [Jark Wu](https://www.linkedin.com/in/jarkwu/), Head of Flink SQL. Since then, the community has witnessed remarkable growth and innovation under the stewardship of [Leonard Xu](https://www.linkedin.com/in/leonard-xu-409382225/). The project introduced cutting-edge features that simplified the user’s CDC data processing links and provided an elegant data integration solution.
These advancements propelled the rapid growth of the project with:
- Over 100 source code contributors
- More than 5,000 GitHub stars
- A vibrant community of over 10,000 members
## What is Flink CDC?
[Flink CDC](https://nightlies.apache.org/flink/flink-cdc-docs-stable/) is a streaming data integration tool. It works well with most mainstream databases to enable real-time integration of Change Data Capture (CDC) data technology based on database changelogs.
Flink CDC captures database changes (inserts, updates, deletes) as events and streams them to downstream systems for processing. It offers efficient real-time data handling, cost-effective scalability, adaptability to dynamic data environments, and streamlined integration using features like schema evolution and full database synchronization.
Today, Flink CDC is deployed in production environments by companies around the globe.
## How Apache Flink and Flink CDC work together
Apache Flink is well known for its powerful pipelines and its extensive support for connecting to other systems. This ability to handle continuous streams of data makes it well-suited for CDC tasks where changes in the source database need to be processed in real-time.
**Here's how it works:** Flink CDC interprets and parses the user's YAML file, defining data source, sink, and transforms between them, then builds and submits a Flink job to start the pipeline of synchronization. As changes occur, they are read by Apache Flink, optionally transformed and routed by operators, and then streamed to downstream processing pipelines or systems for further analysis, reporting, or other purposes.
By using Apache Flink, Flink CDC can efficiently integrate large amounts of data in real-time. This capability is particularly useful in scenarios such as real-time analytics, data synchronization between different systems, maintaining replica databases, or triggering real-time actions based on database changes.
## Ververica donates Flink CDC
In our role as a maintenance member of the open-source community, Ververica strives to broaden the impact of Flink CDC within the field of data integration. We collaborate with users and developers to build and strengthen the community.
As the Flink CDC project evolved over recent years, two copyright concerns surfaced that required attention.
- Although Flink CDC source code was open under [Apache License, Version 2.0](https://www.apache.org/licenses/LICENSE-2.0), the copyright of the project belonged to Ververica, not to a neutral foundation.
- The project name, **CDC Connectors for Apache Flink**strong>, was abbreviated to “Flink CDC;” however, the project was not directly affiliated with Apache Flink, leading to potential copyright concerns.
To address these concerns and remove any hesitation to participate in the Flink CDC open source community, we opted to donate the project. During Flink Forward Asia in December 2023, Jark Wu (the visionary behind Flink CDC) announced Ververica's intent to donate Flink CDC to the Apache Foundation as a sub-project of Apache Flink.
Thanks to the collaborative endeavors of the Flink CDC community developers, particularly community maintainers, the donation process has officially concluded.
## Changes to access and process
Now that the donation process is complete, the original code repository and documentation website will no longer be used. The project now resides in a new GitHub repository and documentation site, aligning with Apache Flink's community standards and development practices.
- **Github repository**: [https://github.com/apache/flink-cdc](https://github.com/apache/flink-cdc)
- **Documentation**: [https://nightlies.apache.org/flink/flink-cdc-docs-stable/](https://nightlies.apache.org/flink/flink-cdc-docs-stable/)
As a sub-project of Flink, the subsequent development of Flink CDC will strictly follow the Apache Flink community processes, including:
- The management of work items and defects through Github issues will be migrated to Flink Jira.
- Community development discussions and exchanges will transfer gradually to the Flink community mailing list.
- [Flink JIRA](https://issues.apache.org/jira/projects/FLINK/issues) for issue management. (When opening an issue, please select “Flink CDC” as the module name.)
- Flink dev mailing list ([dev@flink.apache.org](mailto:dev@flink.apache.org)) for development-related discussions.
- Flink user ([user@flink.apache.org](mailto:user@flink.apache.org) for English users) and Flink user-zh ([user-zh@flink.apache.org](mailto:user-zh@flink.apache.org) for Chinese users) mailing lists for user Q&A and communication.
See the [Apache Flink Community page](https://flink.apache.org/what-is-flink/community/#mailing-lists) and [Developer Guide](https://nightlies.apache.org/flink/flink-cdc-docs-release-3.0/docs/developer-guide/contribute-to-flink-cdc/) for more information and to join discussions in the Flink mailing list.
## Repositioning Flink CDC within the data integration framework<
As an independent sub-project of Apache Flink, **Flink CDC is no longer limited to providing Flink source connectors.** Instead, it can deliver complete end-to-end integration capabilities.
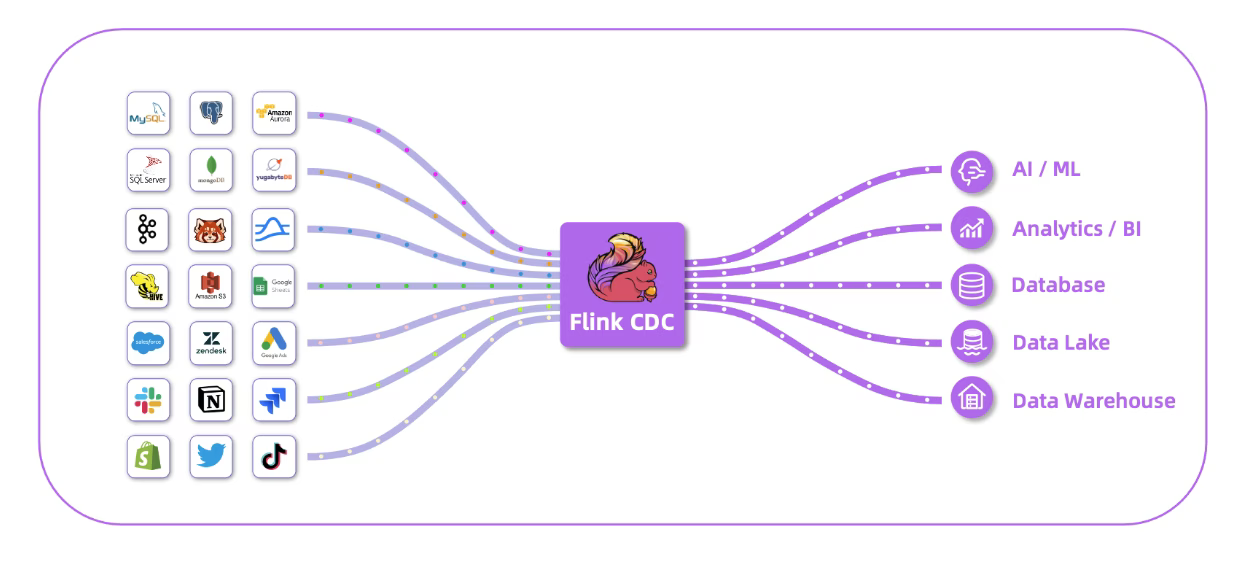
The new framework provides a brand-new API, designed specifically for data integration scenarios. **Users can launch a synchronization pipeline by specifying information from external systems on the source and sink side, without understanding the internals of Apache Flink.**
As a sub-project of Apache Flink, Flink CDC can cooperate and integrate more deeply with the Flink runtime, and leverage the dominant position of Apache Flink in the stream processing area to provide a high-performance and real-time data integration experience.
Looking forward, the Flink CDC community will continue to improve on the ecosystem by:
- Supporting transform operations
- Expanding the connector ecosystem to support more systems like Apache Kafka, Apache Pulsar, and Apache Paimon
## Advanced CDC with Ververica Cloud
As the leader in streaming data technologies, founded by the original creators of open-source Apache Flink®, Ververica has developed advanced CDC capabilities with its flagship product, [Ververica Cloud](https://www.ververica.com/product/deployment/cloud).
The Ververica Runtime Assembly ([VERA](https://docs.ververica.com/introduction/about-vera)) is an optimized Flink stream processing engine that seamlessly integrates with Flink CDC, and is an integral part of Ververica Cloud.
**VERA supports** **advanced CDC capabilities** such as:
- **data and table merging**
- **schema evolution**
- **full database synchronization**
- **synchronization at the level of thousands of tables**
It also optimizes performance (up to 2x faster than Apache Flink), provides dynamic complex event processing (CEP), and extends the ecosystem of connectors.
While both Ververica Cloud CDC and Flink open-source CDC use change data capture technologies, the key differences between them are performance, architecture, and ease of use and seamless operations.
Flink open-source CDC requires manual setup and configuration and places the responsibility of managing infrastructure and scaling on users. This solution works best for users who have deep knowledge and expertise with Flink’s ecosystem.
On the other hand, Veverica Cloud CDC offers additional features and enhancements beyond the core Flink CDC. It abstracts complexities related to deployment, configuration, infrastructure management, scalability, fault tolerance, and maintenance, making it more accessible for users who prioritize ease of use and streamlined workflows.
For more information about Ververica CDC and its features, use cases, and practical implementation, refer to the Veverica [documentation](https://docs.ververica.com/introduction/about-vera) or [contact us.](https://www.ververica.com/contact)
## The future of Flink CDC
Flink CDC is entering a new chapter with enhanced focus and capabilities, benefiting from Apache's governance, community, and ecosystem support.
As Alexander Walden, CEO of Ververica, put it, “The donation of Flink CDC to the Apache Software Foundation marks a milestone in our journey towards building a more open, collaborative, and innovative data integration landscape. We are excited to see Flink CDC flourish within the Apache ecosystem, benefiting from and contributing to the collective wisdom and effort of the global developer community. This step reinforces our commitment to open source and the belief that together, we can achieve greater advancements and wider adoption of streaming data technologies."
### About Veverica
Veverica enables its customers to unlock the value of their data. Ververica’s comprehensive streaming data platform supports a wide range of options from a fully-managed, cloud-native service ([Ververica Cloud](https://www.ververica.com/product/deployment/cloud)) to on-premise software ([Ververica Platform](https://www.ververica.com/product)).
Founded by the original creators of open-source Apache Flink®, Ververica has the experience and knowledge to continue leading the innovation of streaming data technologies. This leadership is demonstrated through contributions to open-source software projects, an extensive streaming data learning environment ([Ververica Academy](https://www.ververica.academy/app)), and leading the Apache Flink and streaming data conference, Flink Forward. Discover more at [www.ververica.com](http://www.ververica.com/).
---
---
title: "Building real-time data views with Streamhouse"
description: "Learn how to build real-time data views using Streamhouse and Apache Paimon. Discover how to implement a data analytics pipeline."
lastUpdated: 2026-07-20T10:47:25.000Z
source_url:
html: "https://www.ververica.com/blog/building-real-time-data-views-with-streamhouse"
md: "https://www.ververica.com/blog/building-real-time-data-views-with-streamhouse.md"
---
## Use Case
Imagine an e-commerce company operating globally, we want to see, in near real-time, the amount of revenue generated per country while the order management system is processing ongoing customer orders. Order data is stored in streaming sources like Kinesis or Kafka. Customer data is coming from an OLTP database like MySQL. The goal is to calculate the total amount of revenue per country in real-time, and then share this data to a visualization layer.
## Solution Overview
In this blog post, we will walk you through our solution implemented in [Ververica Cloud](https://www.ververica.com/product/deployment/cloud), a fully managed ultra-high performance cloud-native service for real-time data processing. In Ververica Cloud, **VERA** (Ververica Runtime Assembly) is our next-generation stream processing engine based on Apache Flink. It enables real-time data processing with performance 2x better than Apache Flink. The included Flink CDC supports processing Change-Data-Capture streams out of the box. The Apache Paimon table format integrated in Ververica Cloud enables the use of cheap storage like S3 or similar and brings features of the data warehouses on top of it, such as ACID transactions, row upserts, data cataloging, time traveling, and more. In this [Streamhouse](https://www.ververica.com/blog/streamhouse-unveiled), we will use VERA and Flink CDC to ingest data into Paimon and process them, then show the real-time view in a visualization layer.
Because Paimon is the foundation for building the Streamhouse architecture, I sometimes use the terms Paimon and Streamhouse interchangeably.
> **NOTE:** Note: the target audience for this remainder of this blog post is mainly data engineers and data architects.
## High-Level Data Pipeline Design
Let's walk through how you can build this pipeline in three stages.
1. Ingestion - bring in data from different sources into the Streamhouse environment.
1. Aggregation - build data tables to share with your target users.
1. Visualization - present the data in an easy-to-read format to your users.
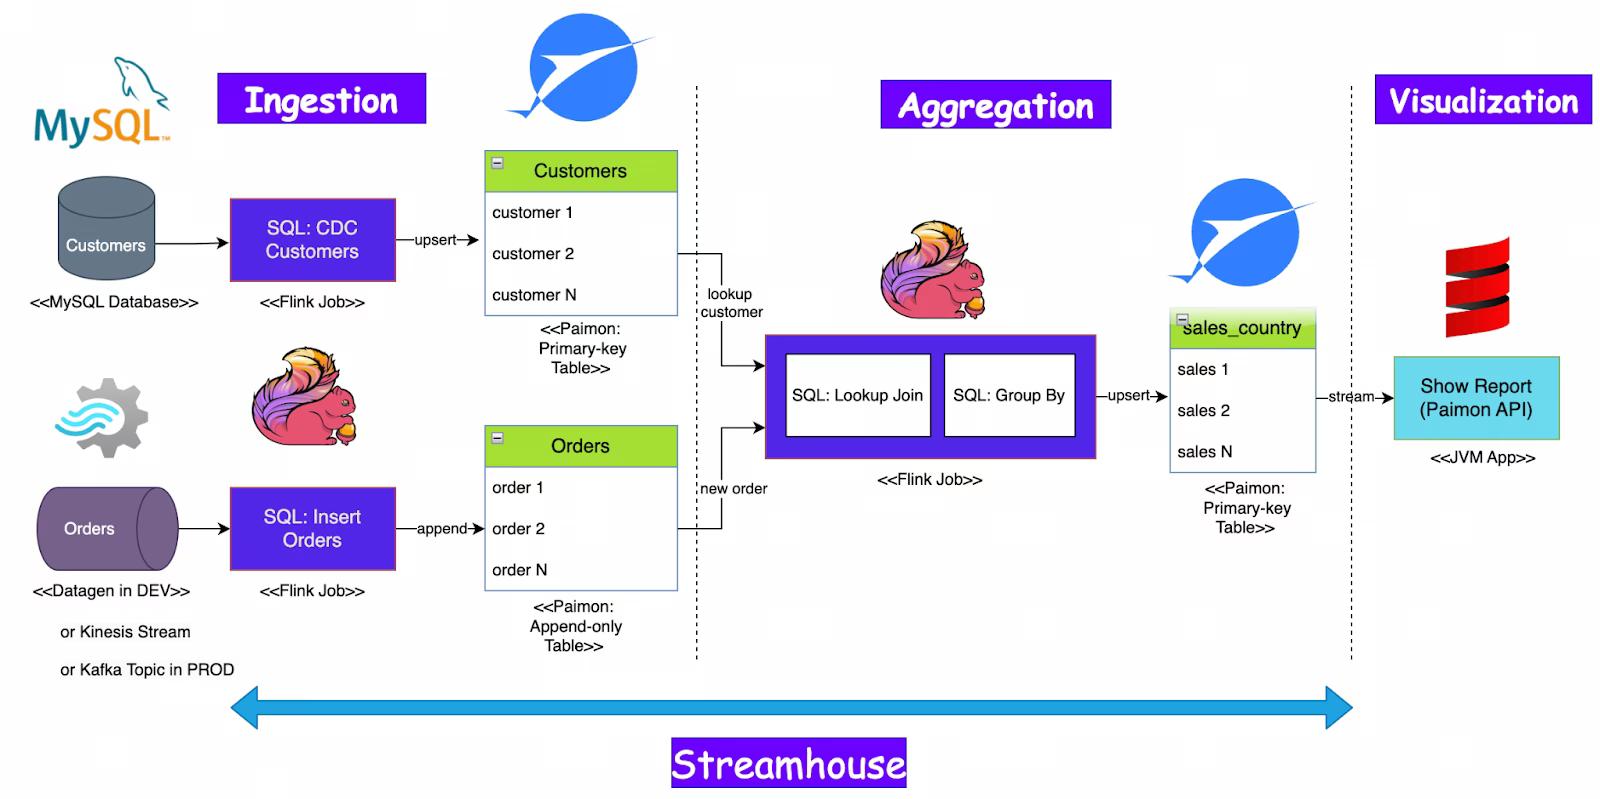
As shown in the diagram, the ingestion stage includes collecting the customer order data from the MySQL database, generating the customer data using a Flink job, and then creating Paimon tables to store the data. The customer data is coming in a streaming way using Flink Change-Data-Capture(CDC). This is a crucial feature to implement an end-to-end streaming pipeline even consuming data from relational databases like MySQL. After ingesting the data, a Flink job joins two source tables and calculates the revenue per country and then builds a Paimon output table. Lastly, the Paimon Java API creates a graph to visualize the results. As the entire pipeline runs in streaming mode, there is no need to schedule some jobs recurrently, i.e. there are no batch jobs needed.
The rest of this blog provides example code for how to do this.
## Create Paimon Catalog
Go to SQL Editor in Ververica Cloud, create a new SQL draft with the following SQL script to create Paimon catalog and orders table:
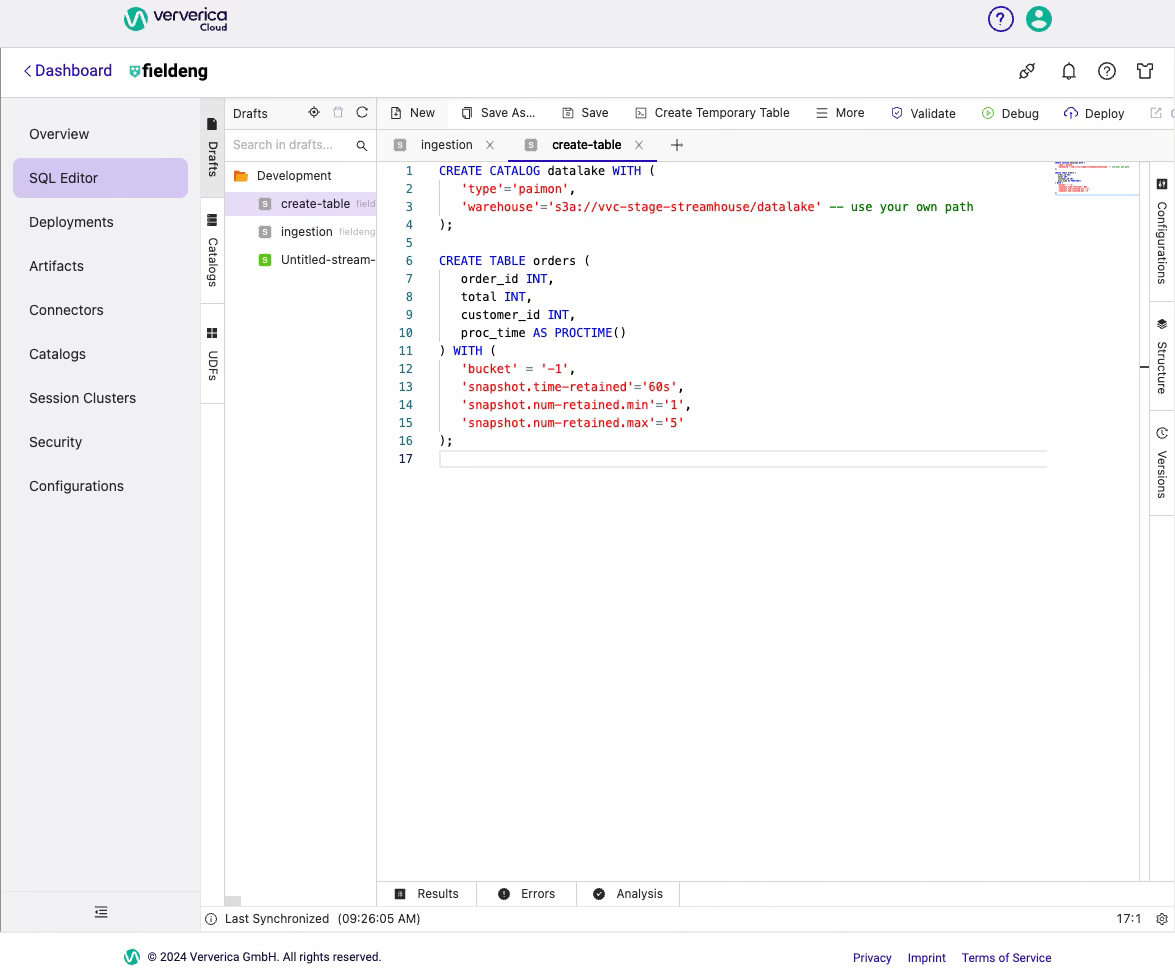
## Ingestion
Ingestion into the streamhouse could be done by the Flink “filesystem” sink connector. However, a set of stored files alone does not give the required properties needed to build a streamhouse architecture. The right storage format for streaming data has been an issue for a long time - until Apache Paimon was created. Paimon is fully integrated in Ververica Cloud. It brings completely new opportunities to the stream processing world.
Please note that the ingestion layer stores data that can be reused for multiple purposes, so that we just copy the data as is.
### Customer Order Data
Go to SQL Editor in Ververica Cloud, create a new SQL draft with the following SQL script to implement the “orders” table data ingestion:
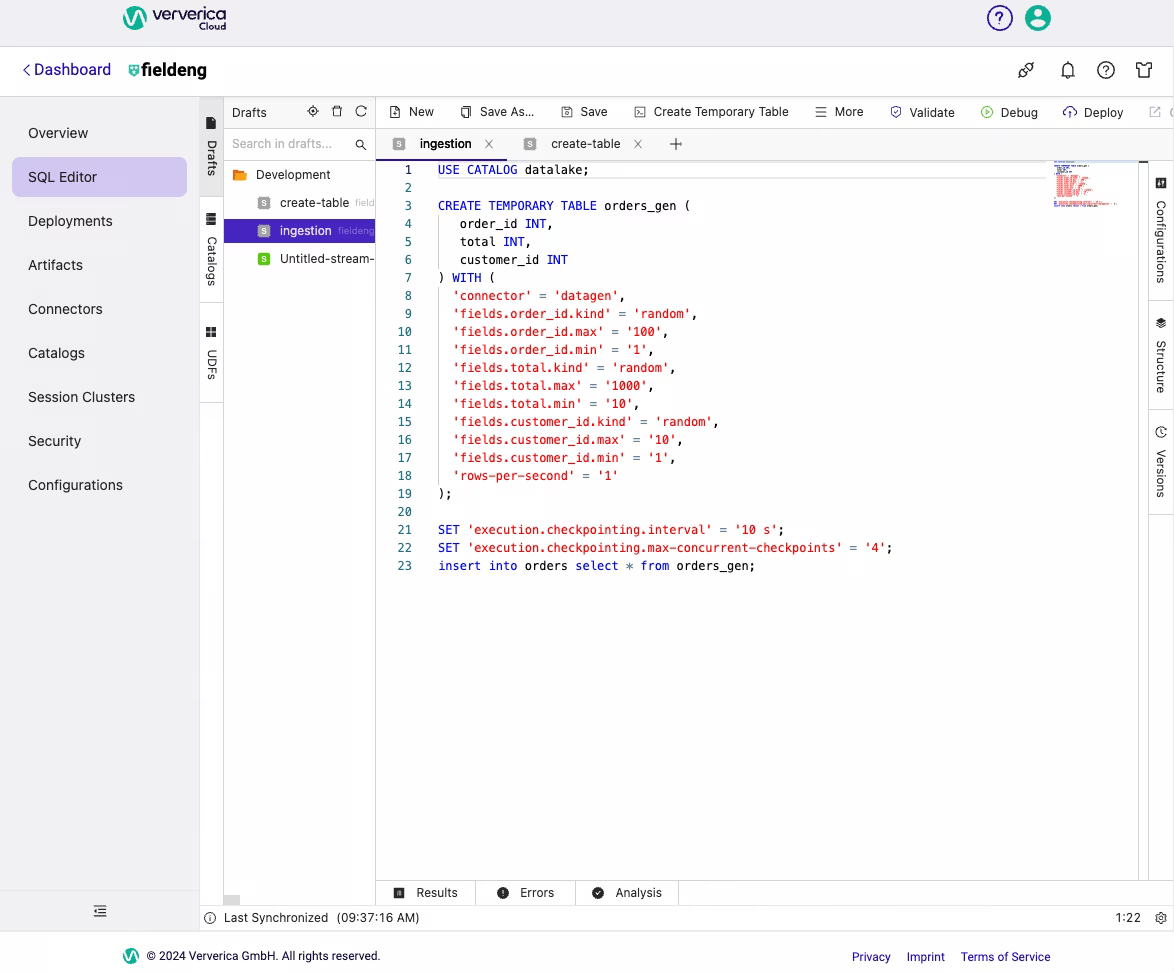
You can find full source code for ingestion in this file: [https://github.com/ververica/lab-paimon-analytics/blob/main/flink-sql/ingestion.sql](https://github.com/ververica/lab-paimon-analytics/blob/main/flink-sql/ingestion.sql)
Then click Deploy at the top right corner and confirm deployment:
Click Deployments in the main left menu and then start your just created deployment:
Flink SQL job results in the following Flink job graph:
The Orders table inherits the catalog’s configuration and has its own special configuration. Bucket “-1” makes writing to this table by using a single bucket on the file storage as well as skipping data ordering guarantees. This makes writing more efficient. Using this table type works for our use case since our goal is to ingest orders into a streamhouse as fast as possible. Also, this table is set to Append Only Mode for Scale; it does not have a primary key. Since we do not need to control order_id uniqueness for our use case, we let the datagen connector generate these ids within the fixed small range.
Other “orders” table properties include a configuration for the file compaction process, which is done by the Paimon writer automatically. You can see an example of this on the Flink job graph as Compaction Coordinator Source. The Paimon table may create many small files which need to be periodically compacted to achieve adequate query performance.
### Customer Data
This table is coming from the MySQL database. In order to prepare some data, we will use an auxiliary Flink SQL job to generate it.
This is the SQL code for the Flink Job to generate data for the customers table in MySQL database:
Use the above SQL code to create a new Deployment in VVC and then start it.
Next, create the Paimon “customers” table to store data from the MySQL database into our Streamhouse catalog:
There is an important setting set for the Paimon table to generate changelog files through the “input” source, as we are going to use this table later in the Lookup Join query. The “Input” producer type in our particular case relies on the change log data coming from the CDC connector, so we just reuse the input-based change log.
To execute a CDC action to copy data into the Streamhouse, launch a Flink job with the following parameters:
The same parameters in text can be found in the [Makefile](https://github.com/ververica/lab-paimon-analytics/blob/main/Makefile).
Once new deployment is created, go to Deployments and change this deployment configuration by setting “Checkpoint interval” to 10 seconds.
The launch configuration above results in the following Flink job graph:
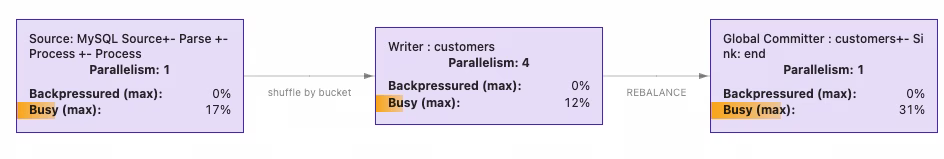
If we query the Paimon **customers** table, the following data displays:
Please note, the generated country names will mostly likely be different in your try
## Aggregation
After ingesting the data, the next step is to use our data to start performing various aggregations, data cleaning, filtering, and building different data views for downstream users. In this example, we will join two source tables to calculate the revenue per country and store the results in another Paimon output table.
Firstly, create table by running below code in any SQL Editor window:
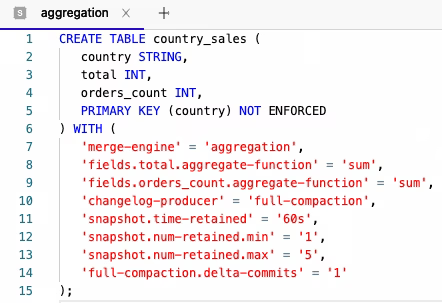
Similarly showed before, create another Flink SQL job in Ververica Cloud with the following Flink SQL code to get the revenue per country:
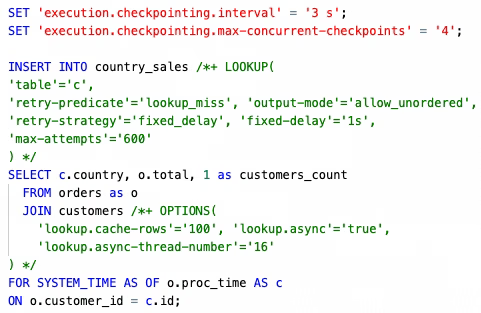
Full source code can be found here: [https://github.com/ververica/lab-paimon-analytics/blob/main/flink-sql/aggregation.sql](https://github.com/ververica/lab-paimon-analytics/blob/main/flink-sql/aggregation.sql)
Let’s break down the code snippets above.
First, the primary-key table uses “country” as the natural primary key with the following settings
- merge-engine=aggregation is set to automatically aggregate newly inserted records using the aggregate function’s “sum” (defined separately).
- changelog-producer=full-compaction is set to produce change log files and automatically compact them when writers insert new data into the table.
- snapshot.* properties are set to control how the compaction should work.
Next, the INSERT query is configured with SQL hints to control how the lookup should work:
- **LOOKUP** hint is used to retry data read if there are missing records from the customers table.
- OPTIONS hint is setting dynamic options to cache looked-up rows from customers. Also, the look-up operation is set to run in asynchronous mode not to block the entire Flink job. More on this here: [https://paimon.apache.org/docs/master/flink/sql-lookup/#async-retry-lookup](https://paimon.apache.org/docs/master/flink/sql-lookup/#async-retry-lookup)
- **FOR SYSTEM AS OF** is used to look up customers at the point of time of a specific order processing time. This logic is important for our example but can be unnecessary for another use case, where the latest customer version should be used regardless of the order processing time.
The INSERT query produces the following Flink job graph:
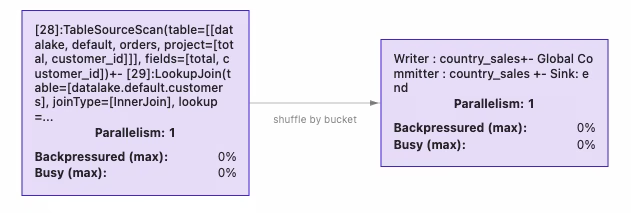
## Visualization
Now that we have the target data, our goal is almost achieved. The remaining step is to visualize the resulting table for the end users so that they can see the revenue in real-time.
One of the standard ways to show this data to users is to use a business intelligence tool like Tableau, Power BI, or another similar tool. In order to read the Paimon table, you can either add integration with Paimon to those BI tools or come up with a way to share Paimon data in a format which those tools already support. For example, a set of JSON files can be exported and then read by Tableau.
Other users may prefer to visualize data in real-time using their web application. Paimon already has a solution for that, which is the [Paimon Java API](https://paimon.apache.org/docs/master/program-api/java-api/). You can build a JVM-based backend which would provide an HTTP endpoint to pull the current table into a Web UI. Moreover, using web-sockets you can also stream updates from the Paimon table on your backend service continuously to the web-socket client.
Below, you will find a Scala script which uses Paimon Java API to stream-read a Paimon table and print current table rows continuously into the console.
[https://github.com/ververica/lab-paimon-analytics/blob/main/readStream.sc](https://github.com/ververica/lab-paimon-analytics/blob/main/readStream.sc)
You can use [Ammonite](https://ammonite.io/#Ammonite) script-launcher to execute this script via such command:
> amm readStream.sc
Approximately every 6 seconds (2 secs - script scan interval + 3 secs - Flink Job checkpoint) it prints country_sales table below:
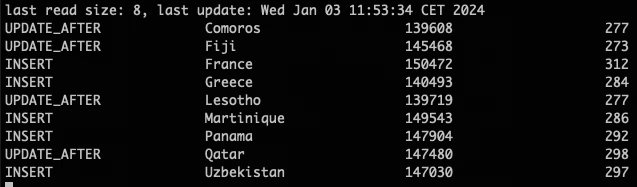
We finished the implementation. Every new order produces updates to the resulting country_sales table, and every update to the customer MySQL table makes updates to the resulting view.
## Customer Table Changes
Let’s make a test to see what happens if we change the country name for one of the existing customers in the MySQL table:
```sql
mysql> update customers set country = 'China' where id = 7;
Query OK, 1 row affected (0.02 sec)
Rows matched: 1 Changed: 1 Warnings: 0
```
You can see that a new row was inserted for ‘China’ with 4 orders and a total of 1815 revenue. The data was streamed and shown automatically from the country_sales table.
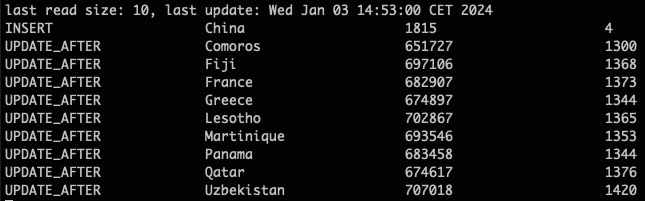
Note that the previous country name for the customer with 7 was France and it’s still there in the resulting table. If you want to see only the current countries in the customers table, then you can remove rows from the country_sales by using the Paimon Merge action.
It is currently available as a Flink DataStream batch job which can be executed as new VVC Deployment:
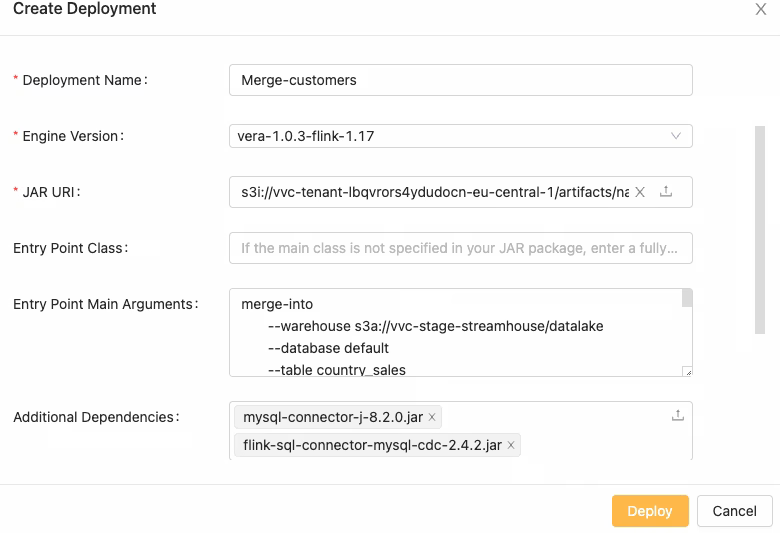
Do not forget to set Checkpoint Interval before starting the deployment:

The main logic of the Paimon action above is to merge the customers table into the country_sales table by:
1. Inserting a new country with 0 revenue in the country_sales table
1. Deleting the country from the country_sales table
For example, ‘France’ no longer occurs in the customer table, so it is going to be deleted from country_sales after the merge action is executed.
Before executing this Paimon action, let’s also add a new customer with a new id and a new country name which is not already used by the order data generation job. This allows us to get a new country name with 0 revenue in the country_sales table:
```sql
mysql> insert into customers values(11, 'Santa', 'North Pole', '000001');
Query OK, 1 row affected (0.01 sec)
```
Now you can run the merge action.
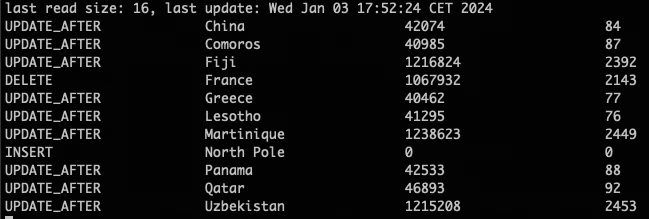
After the merge, you can see the expected outcome:
1. Country name ‘France’ and its row is removed
1. Country name ‘North Pole’ (fictional) is added with 0 revenue
By doing it this way, we synced the customers table with the country_sales table without using the orders table.
## What Apache Paimon unlocks for Data Teams
You no longer need a compute-expensive data storage system like Apache Kafka (or similar) to apply stream processing while working with intermediate data sets. This can be achieved by using Paimon “Append Only” tables. They allow replacing message queues for data ingestion to the streamhouse. This is of course, only applicable if you can tolerate data delays which depend on Flink checkpoint interval (it is configurable).
Paimon treats Flink as the reference implementation of the stream processing framework and supports core Flink functionality for streaming and batch data processing. Storing data in Paimon tables allows you to leverage cheap storage services like S3 and at the same time you get the main OLAP/data warehouse properties, which are crucial to implement data analytics and machine learning applications on top of the streamhouse.
---
---
title: "Streamhouse: Data Processing Patterns"
description: "Learn about Streamhouse, a data processing pattern that combines real-time stream processing with the structured nature of data warehouses."
lastUpdated: 2026-04-30T12:51:15.000Z
source_url:
html: "https://www.ververica.com/blog/streamhouse-data-processing-patterns"
md: "https://www.ververica.com/blog/streamhouse-data-processing-patterns.md"
---
## Introduction
In October, at Flink Forward 2023, Streamhouse was officially [introduced](https://www.ververica.com/blog/streamhouse-unveiled) by Jing Ge, Head of Engineering at Ververica. In his keynote, Jing highlighted the need for Streamhouse, including how it sits as a layer between real-time stream processing and Lakehouse architectures, and discussed the business value it provides.
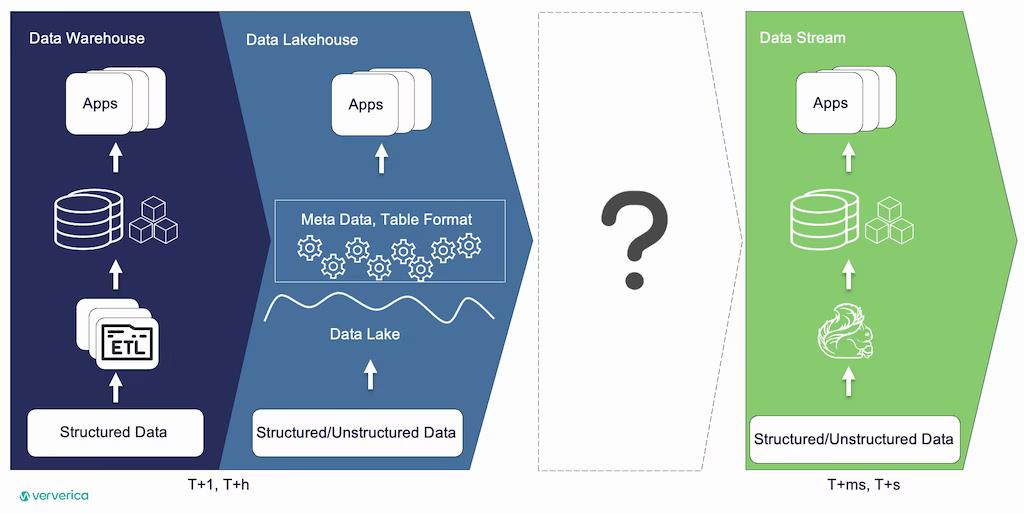
The three musketeers of Streamhouse architecture were also introduced: Apache Flink®️, Flink CDC, and Apache Paimon. Apache Paimon was created as a Lakehouse table format, but it is much more than that.
It extends Apache Flink’s capabilities on the datalake and allows developers to truly leverage stream processing on the datalake. In this blog post, we will try to better understand what this means in practice by taking a streaming patterns-based approach.
## Business Layers of Lakehouse
Before we dive into the different stream processing patterns, let’s make a quick recap of Lakehouse Architecture.
Lakehouse combines the structured nature of data warehouses with the cheap and durable storage of data lakes. Streamhouse builds on this concept, providing stream processing capabilities when near-real-time results are acceptable by the business.
The following illustration highlights the different business layers that you typically see in a data warehouse, and these can keep updating in near-real time on the data lake.
This brings a few benefits, like reduced engineering maintenance effort, which makes the developer's life easier.
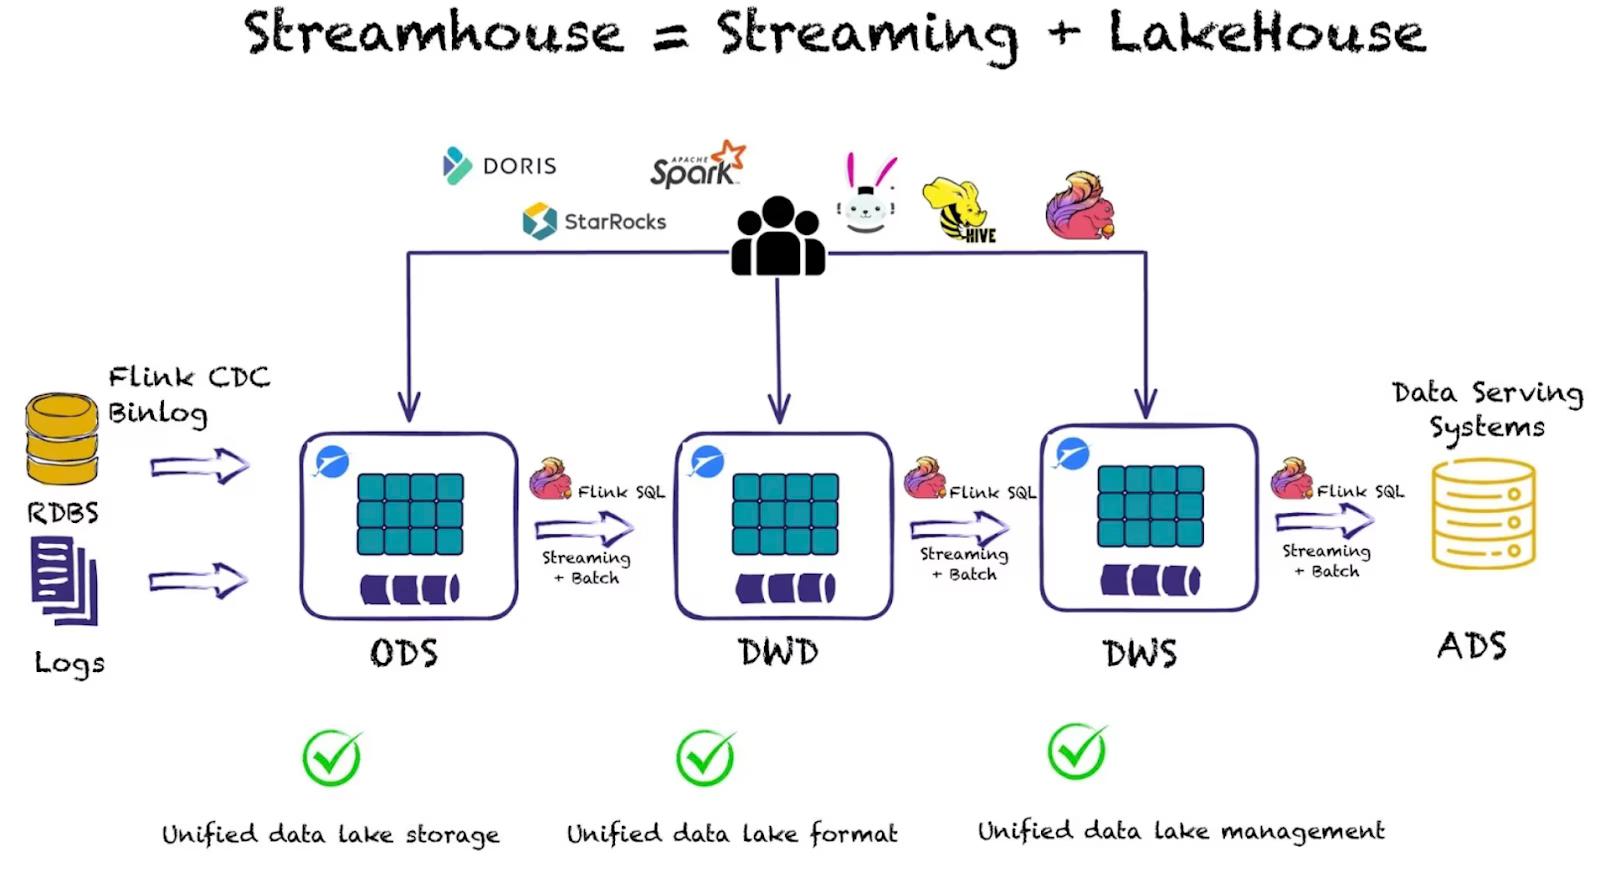
We can observe the following business layers: **Operational Data Store (ODS)**, **Data Warehouse Detail (DWD)**, **Data Warehouse Summary (DWS)**, and **Application Data Service (ADS)**.
### ODS
This is typically where the raw, unstructured data gets ingested. The structure of a data table at the ODS layer is the same as the structure of a data table in which the raw data is stored. The ODS layer serves as the staging area for the data warehouse.
### DWD
At this layer, data models are built based on the business activities of an enterprise. You can create a fact table that uses the highest granularity level based on the characteristics of a specific business activity. You can duplicate some key attribute fields of dimensions in fact tables and create wide tables based on the data usage habits of the enterprise. You can also associate fact tables with dimension tables as little as possible to improve the usability of fact tables.
### DWS
At this layer, data models are built based on specific subject objects that you want to analyze. You can create a general aggregate table based on the metric requirements of upper-layer applications and products.
Some general dimensions can be abstracted at the ODS layer based on preliminary classification and a summary of user behavior. At the DWS layer, you can add multi-granularity aggregate tables on top of general aggregate tables to improve the calculation efficiency
### ADS
This layer stores the metric data of products and generates various reports.
## Streaming Patterns on the Lake
### Pattern 1: Event Deduplication
Event deduplication is about removing duplicate events. Apache Paimon includes two merge engines to support that, i.e. the **deduplicate** and the **first-row** merge engines.
```sql
-- Deduplicate (also the Default) Merge Engine
CREATE TABLE test (
key INT,
field_a INT,
field_b INT,
field_c INT,
field_d INT,
PRIMARY KEY (key) NOT ENFORCED
) WITH (
'merge-engine' = 'deduplicate',
...
);
-- First-Row Merge Engine
CREATE TABLE test (
key INT,
field_a INT,
field_b INT,
field_c INT,
field_d INT,
PRIMARY KEY (key) NOT ENFORCED
) WITH (
'merge-engine' = 'first-row',
'changelog-producer' = 'lookup'
);
```
- **Deduplicate (default)**: When two events with the same key arrive, only the latest entry is retained.
- **First-row:** Always retains the first entry around.
### Pattern 2: Table Widening
[Star schemas](https://en.wikipedia.org/wiki/Star_schema) are a popular way of normalizing data within a data warehouse. At the center of a star schema is a fact table whose rows contain metrics, measurements, and other facts about the world. Surrounding fact tables are one or more dimension tables that have metadata useful for enriching facts when computing queries.
Similarly, when dealing with streaming data, you might have an append-only stream, (for example, coming from Kafka,) and you want to “widen” this stream with data that live in other sources (one example is Kafka topics).
The way to achieve this would be to run a streaming join which is quite an expensive computation, especially if your tables are large, since the data needs to be stored in state.
Things get even more complicated if we come across data skew, because some keys have way more data than others, resulting in some tasks having to process far bigger workloads than others.
Paimon has done lots of work on this and has introduced the concept of the **partial-update** merge engine.
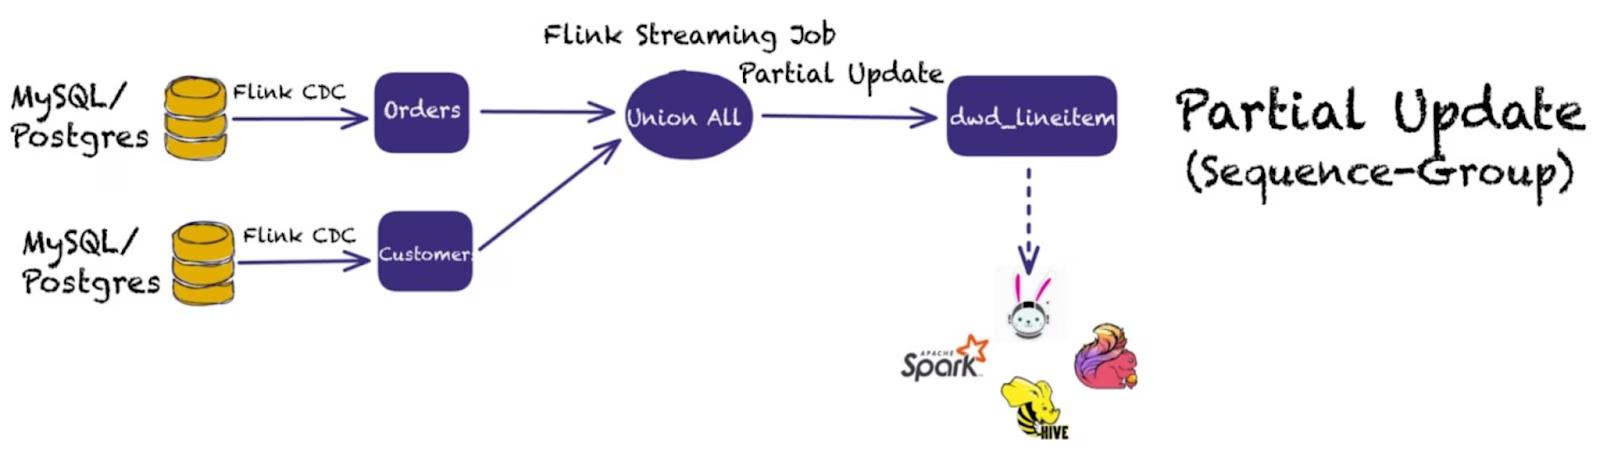
Instead of running a streaming join, with the **partial-update** merge engine, users have the ability to update columns of a record through multiple updates until the record is complete. This is achieved by updating the value fields one by one, using the latest data under the same primary key. However, null values do not overwrite existing non-null values.
For example, suppose Paimon receives three records, with **one** and **three** coming from the primary topic, while the **second** record contains more information we want in order to widen our table:
- <1, 23.0, 10, NULL>
- <1, NULL, NULL, 'This is a book'>
- <1, 25.2, NULL, NULL>
Assuming that the first column is the primary key, the final result would be:
**<1, 25.2, 10, 'This is a book'>**
The **partial-update** merge engine also has the concept of **sequence groups** as we will see next, in order to better control updates and out-of-order events.
### Pattern 3: Out-of-Order Event Handling
When dealing with streaming data, we often come across scenarios in which some events arrive late and out of order into our system due to some delay.
Apache Paimon helps address event ordering by allowing users to specify **sequence fields**. By specifying a sequence field (for example the event timestamp), Paimon knows whether events arrive late and out of order, to better ensure result correctness.
Following is an example of how to specify a sequence field upon table creation.
```sql
-- Sequence Fields
CREATE TABLE test (
pk BIGINT,
v1 DOUBLE PRECISION,
V2 BIGING,
dt TIMESTAMP(3),
PRIMARY KEY (pk) NOT ENFORCED
) WITH (
'sequence.field' = 'dt',
...
);
```
As mentioned for the **partial update** merge engine, Paimon also offers the concept of sequence groups. A **sequence field** may not solve the “out-of-order” problem of the **partial update** merge engine with multiple stream updates, because the latest data of another stream may overwrite the sequence field during a multi-stream update.
Sequence groups allow **handling events arriving out-of-order during multi-stream updates** as each stream can define its own sequence group and define how different columns should be updated.
The following code snippet depicts an example of using the **partial update** merge engine**,** along with **sequence groups:**
```sql
-- Sequence Groups
CREATE TABLE test (
k INT,
a INT,
b INT,
g_1 TIMESTAMP_LTZ(3),
c INT,
d INT,
g_2 TIMESTAMP_LTZ(3),
PRIMARY KEY (k) NOT ENFORCED
) WITH (
'merge-engine'='partial-update',
'changelog-producer'='lookup',
'fields.g_1.sequence-group'='a,b',
'fields.g_2.sequence-group'='c,d',
...
);
INSERT INTO test
VALUES
(1, 1, 1, CAST('2023-11-13 10:08:22.001' AS TIMESTAMP(3)), 1, 1, CAST('2023-11-13 10:08:22.001' AS TIMESTAMP(3)));
-- output 1, 1, 1, 2023-11-13 10:08:22.001, 1, 1, 2023-11-13 10:08:22.001
SELECT * FROM test
-- g_2 timestamp is smaller, c, d should not be updated
INSERT INTO test
VALUES
(1, 2, 2, CAST('2023-11-13 11:08:22.001' AS TIMESTAMP(3)), 2, 2, CAST('2023-11-13 9:08:22.001' AS TIMESTAMP(3)));
-- output 1, 2, 2, 2023-11-13 11:08:22.001, 1, 1, 2023-11-13 10:08:22.001
SELECT * FROM test
-- g_1 timestamp is smaller, a, b should not be updated
INSERT INTO test
VALUES
(1, 3, 3, CAST('2023-11-13 09:08:22.001' AS TIMESTAMP(3)), 3, 3, CAST('2023-11-13 12:08:22.001' AS TIMESTAMP(3)));
-- output 1, 2, 2, 2023-11-13 11:08:22.001, 3, 3, 2023-11-13 12:08:22.001
SELECT * FROM test;
```
### Pattern 4: Automatic Aggregations
Business layers like the **DWS** and **ADS** might require business aggregates or reports to be generated. Paimon helps with that through the **aggregation** merge engine.
When creating a table using the **aggregation** merge engine, it allows configuring aggregation functions. These aggregation functions will be applied automatically, every time a new record arrives.
The following code snippet depicts an example of using the aggregation merge engine to create a table that keeps a **purchase summary** on the **ADS** layer.
```sql
CREATE TABLE `purchase_summary.ads` (
user_id STRING NOT NULL,
user_session STRING,
full_name STRING NOT NULL,
event_types STRING,
num_of_purchases INTEGER,
products STRING,
price_sum DECIMAL(15,2) NOT NULL,
min_price DECIMAL(15,2) NOT NULL,
max_price DECIMAL(15,2) NOT NULL,
PRIMARY KEY (user_session) NOT ENFORCED
) WITH (
'bucket' = '1',
'bucket-key' = 'user_session',
'file.format' = 'parquet',
'merge-engine' = 'aggregation',
'changelog-producer' = 'lookup',
'fields.user_id.aggregate-function'='last_value',
'fields.full_name.aggregate-function'='last_value',
'fields.event_types.aggregate-function'='listagg',
'fields.num_of_purchases.aggregate-function'='sum',
'fields.products.aggregate-function'='listagg',
'fields.price_sum.aggregate-function'='sum',
'fields.max_price.aggregate-function'='max',
'fields.min_price.aggregate-function'='min'
);
```
Notice how we can specify different aggregation functions for different column types. For example, we can specify that we want all the event_types to be collected as a list and how for the min, max, and price sum we use the **min**, **max,** and **sum** aggregation functions respectively**.**
### Pattern 5: Message Queue on the Data Lake
Apache Paimon’s **append-only** table allows implementing message queue functionality on the data lake.
Similar to Kafka’s topics and partitions, Paimon has tables and buckets.
Users can create multiple buckets, and within each bucket, every record is in strict order. Streaming reads will propagate the records downstream in the exact order of writing.
Similar to the partition number in a topic, the bucket number in a table defines the number of parallelism for processing and the user can define a **bucket key** for splitting the data across multiple buckets.
The following illustration depicts this functionality.
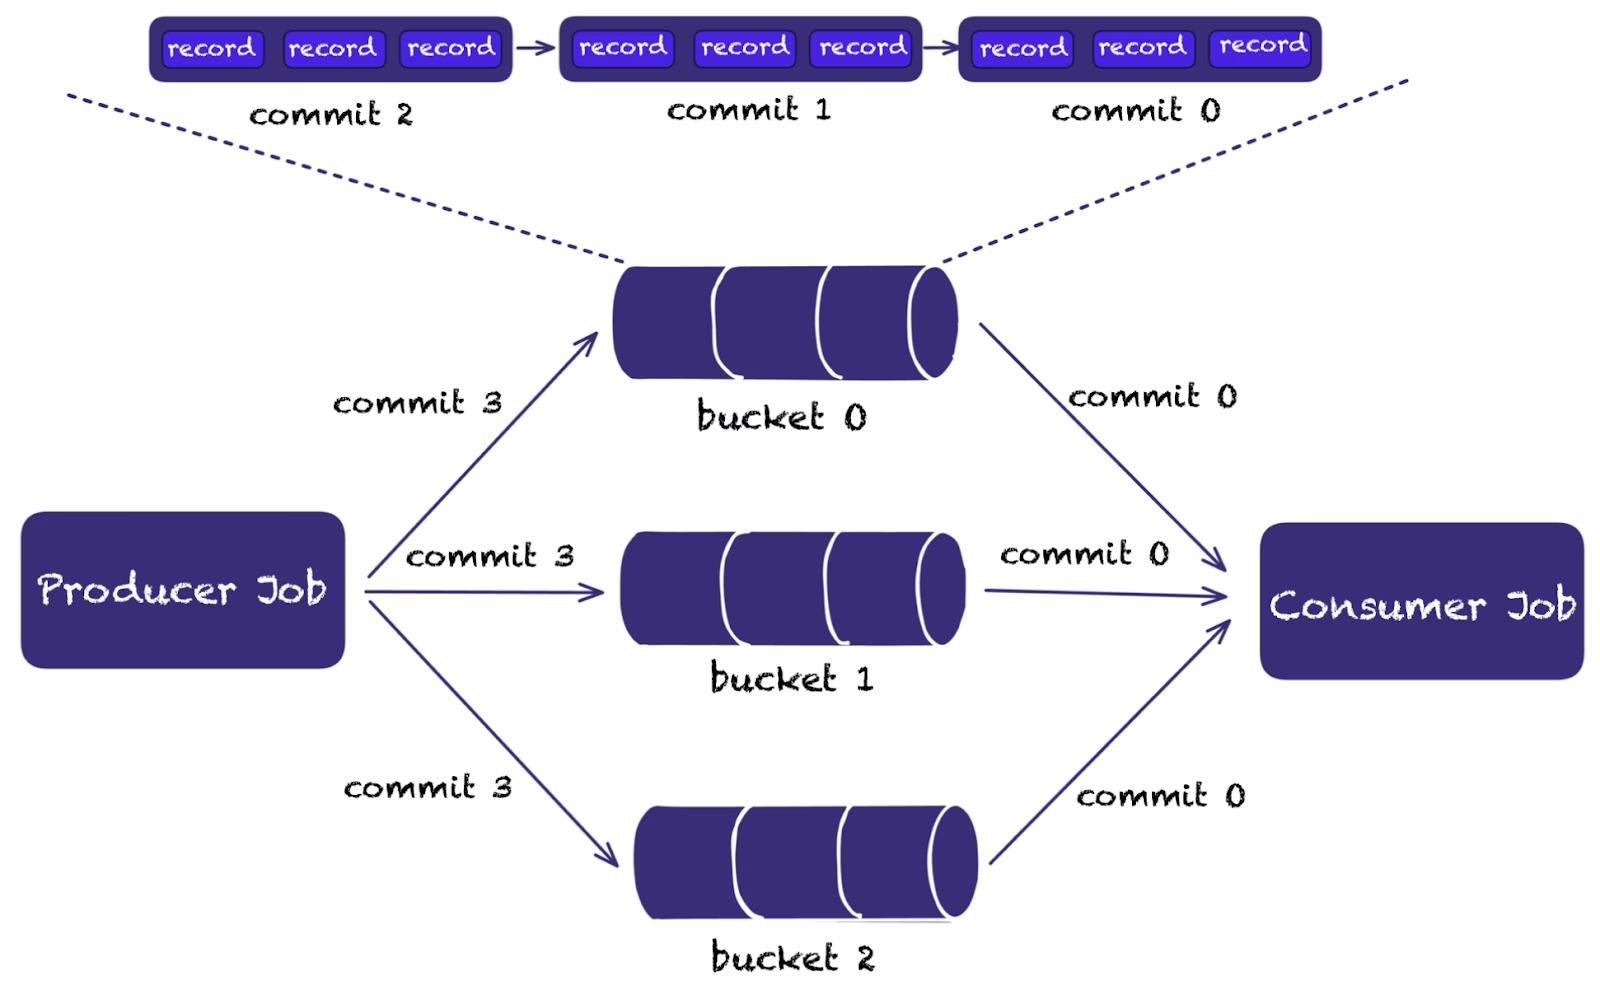
### Pattern 6: Data Backfilling and Correction with Time Travel
Another important functionality is querying the state of your tables at different points in time or identifying what changed between different snapshots. This helps with use cases when you want to perform data backfills, identify data corruptions, and restore to previous versions. For example, you might want to analyze the finances of your business across different quarters, identify data that has been corrupted or deleted, or reproduce business reports.
**MERGE INTO** functionality is also supported if you want to fix errors that might have been introduced accidentally.
Apache Paimon allows querying previous versions by leveraging snapshots or by creating tags. The difference is that tags are persistent, while snapshots can be deleted when they are no longer needed by different data files.
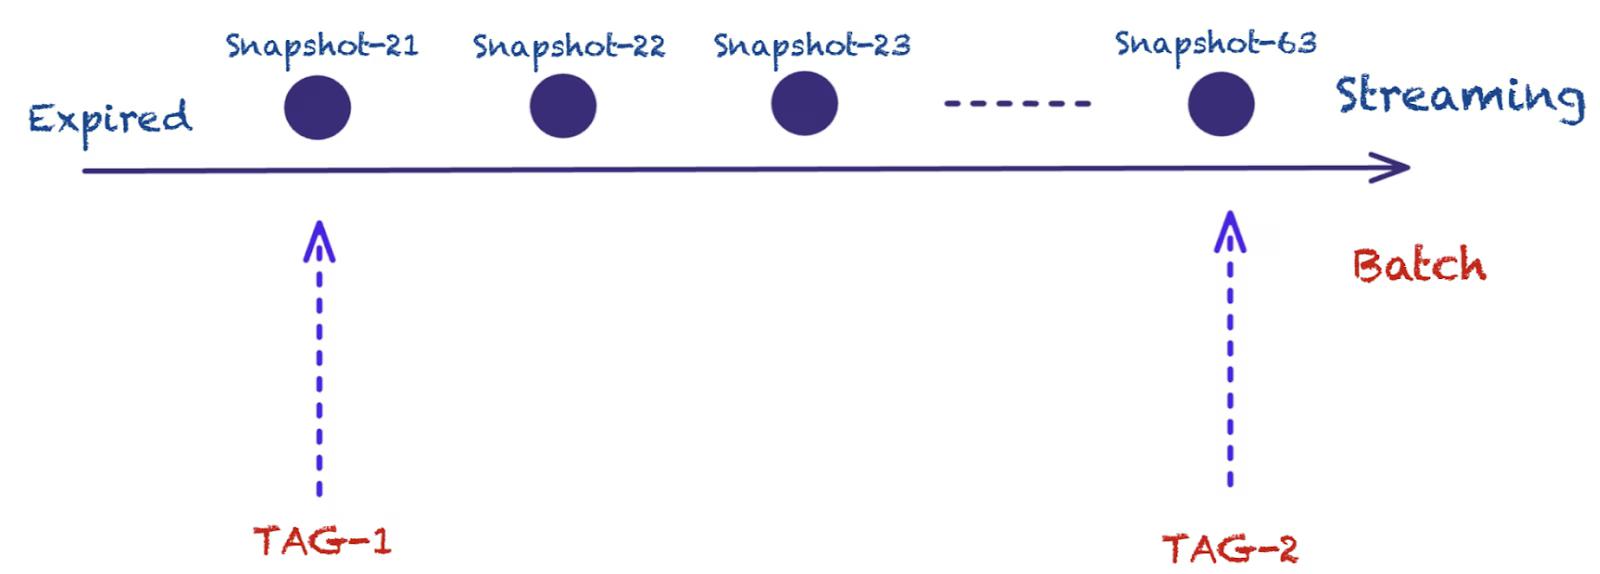
Users can create tags either manually or automatically.
In order to create tags automatically, the user needs to specify some configuration options during the table creation process.
The following code snippet depicts a table that supports automatic tag creation, using a daily interval based on processing time. Then the user can query previous versions of the table by specifying the date.
```sql
-- Flink SQL
CREATE TABLE MyTable (
k INT PRIMARY KEY NOT ENFORCED,
f0 INT,
...
) WITH (
'tag.automatic-creation' = 'process-time',
'tag.creation-period' = 'daily',
'tag.creation-delay' = '10 m',
'tag.num-retained-max' = '90'
);
INSERT INTO MyTable SELECT * FROM KafkaTable;
-- Read latest snapshot
SELECT * FROM MyTable;
-- Read Tag snapshot
SELECT * FROM MyTable VERSION AS OF '2023-07-26';
```
At the same time, the user can create tags manually, running a command similar to the following code snippet, by specifying a tag name and the snapshot, based on which tag needs to be created.
```
./bin/flink run \
-D execution.runtime-mode=batch \
./jars/paimon-flink-action-0.5.0-incubating.jar \
create-tag \
--warehouse file:///opt/flink/temp/paimon \
--database default \
--table test \
--tag-name secondtag \
--snapshot 2
```
Assuming two tags are created, **firsttag** and **secondtag,** we can query based on the tags instead of specifying a timestamp, while also getting the incremental changes between two tags.
```sql
SET 'execution.runtime-mode' = 'batch';
-- read changes from snapshot id 1L
SELECT * FROM test ORDER BY id;
SELECT * FROM test /*+ OPTIONS('scan.tag-name' = 'firsttag') */;
SELECT * FROM test /*+ OPTIONS('scan.tag-name' = 'secondtag') */;
SELECT *
FROM test /*+ OPTIONS('incremental-between' = 'firsttag,secondtag') */
```
One benefit of Apache Paimon compared to other table formats is the use of the LSM data structure. Due to the LSM level hierarchy, minor compaction only affects upper levels that contain the incremental data. Unless there is a huge amount of incremental data, that will affect lower-levels - which contain the large files, these files can just be reused across multiple tags. This results in lower storage requirements and thus costs.
### Pattern 7: CDC Data Lake Ingestion with Schema Evolution
Change data capture is a typical pattern of data ingestion. Typical use cases include capturing changes directly with [Flink CDC](https://github.com/ververica/flink-cdc-connectors) connectors or consuming CDC data from Kafka. Apache Paimon provides a strong integration with both. At the time of writing, it supports CDC along with automatic Schema Evolution handling for MySQL, MongoDB, and Apache Kafka (with Postgres and Apache Pulsar coming in the next releases).
For Kafka, it allows integrating many different formats Canal, Debezium, Maxwell, and OGG.
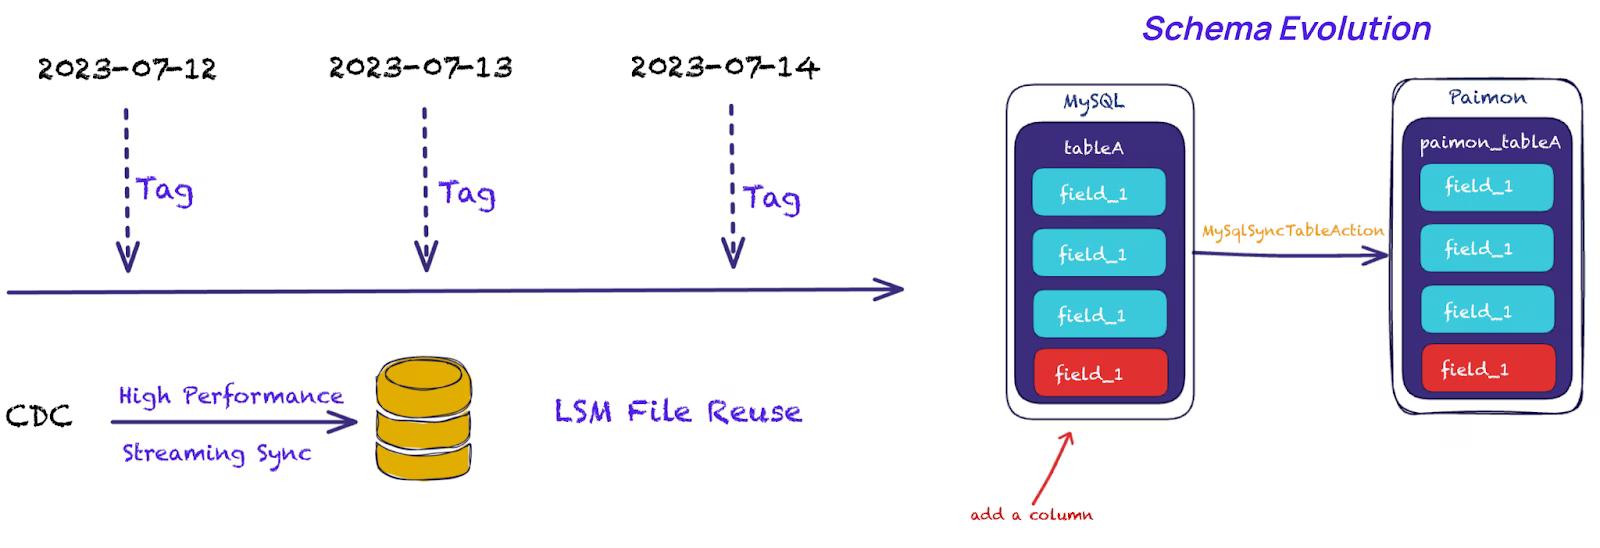
Users can also integrate with other CDC source systems by leveraging the **RichCdcRecord** class.
### Pattern 8: Data Enrichment with Lookup Joins
Data Enrichment is another popular pattern in Stream Processing. Paimon supports Lookup joins and requires one table to have a processing time attribute. Paimon builds a Rocksdb index for Lookup Joins, which has better performance than Flink’s state.
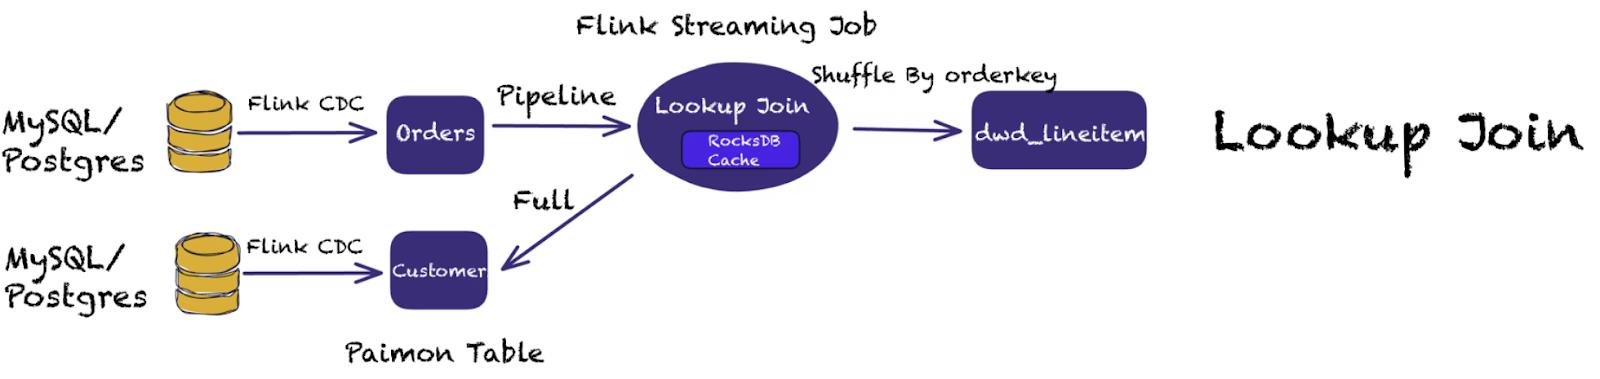
Paimon also supports async lookups. Since we are dealing with streaming data and, in many cases, some records in the lookup table might be late to arrive, it allows using retries to account for these scenarios.
The following code snippet shows how you can perform an async lookup joins along with retries:
```sql
-- enrich each order with customer information
SELECT /*+ LOOKUP(
'table'='c',
'retry-predicate'='lookup_miss',
'output-mode'='allow_unordered',
'retry-strategy'='fixed_delay',
'fixed-delay'='1s',
'max-attempts'='600'
) */
o.order_id, o.total, c.country, c.zip
FROM Orders AS o
JOIN customers /*+ OPTIONS(
'lookup.async'='true',
'lookup.async-thread-number'='16'
) */
FOR SYSTEM_TIME AS OF o.proc_time AS c
ON o.customer_id = c.id;
```
### Pattern 9: Scalable Table for OLAP
In **Pattern 5**, we discussed how Paimon’s append-only table can implement message queue functionality. This is ideal for scenarios that require append-only log ingestion and implement message queue functionality.
However, some use cases might require running OLAP queries on that log ingested data and replacing Hive or Iceberg-like functionality. Once more, Paimon has this covered.
By defining **bucket=-1**, you can use the **unaware-bucket mode**.
In this mode, the concept of the bucket doesn’t exist, and data will not be shuffled in buckets. >This accelerates insertion but does not guarantee ordering any more.
We regard this as a batch offline table (although we can still perform streaming reads/writes) to run OLAP queries.
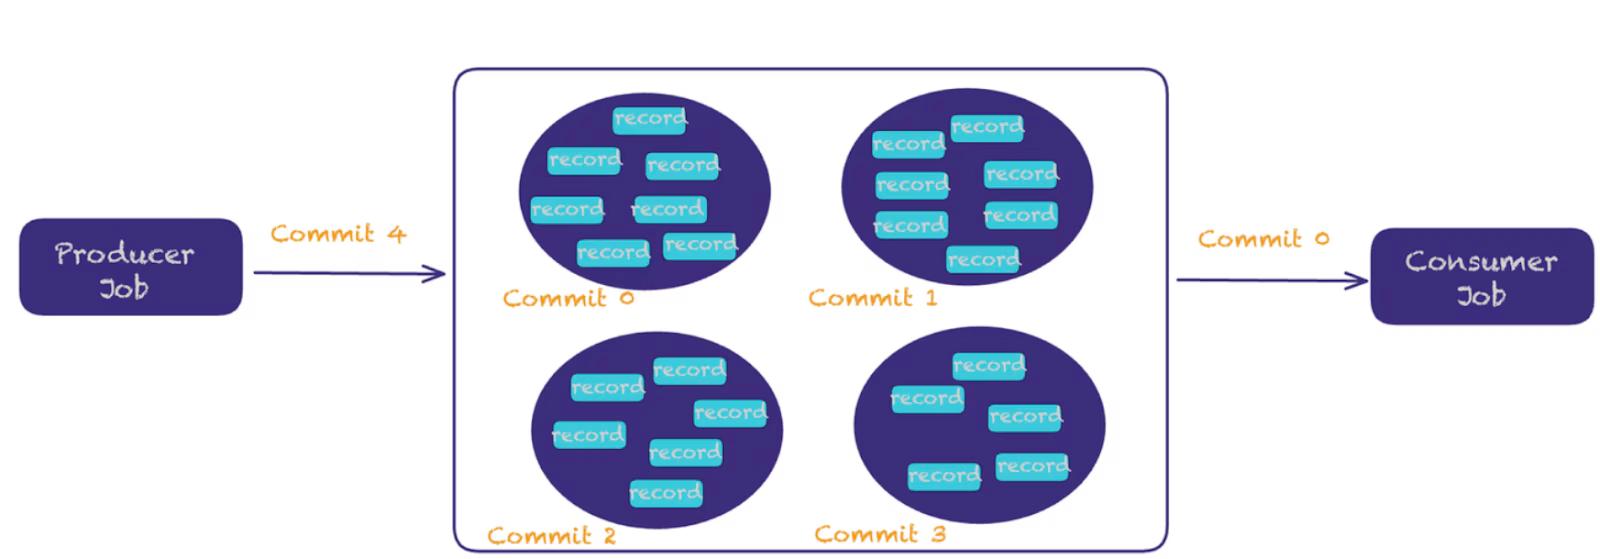
## Conclusion
In this blog post, we explained that Apache Paimon is more than a table format. It allows the implementation of stream processing directly on the data lake. We hope that taking a pattern-based approach helps users better understand what business use cases Apache Flink and Apache Paimon help to implement directly on the data lake.
We also explored Streamhouse, which is the combination of Apache Flink, Flink CDC, and Paimon and provides the foundation that allows the extension of stream processing on the data lake when sub-second latency (like processing events directly from Kafka) is not required by the business.
The end result is significant cost reduction, and more potential use cases unlocked for data teams to explore!
---
---
title: "Apache Paimon 0.6 Released"
description: "Apache Paimon, the powerful streaming lakehouse that combines the flexibility of data lakes and the optimization of data warehouses, releases version 0.6!"
lastUpdated: 2026-05-06T08:14:27.000Z
source_url:
html: "https://www.ververica.com/blog/apache-paimon-0-6-released"
md: "https://www.ververica.com/blog/apache-paimon-0-6-released.md"
---
## Introduction
As the original creators of Apache Flink®, Ververica is proud to support technologies that enhance the capabilities of Flink. With this in mind, we’re excited to highlight the release of Apache Paimon Version 0.6! Congratulations to the Apache Software Foundation and the community for this accomplishment.
[Apache Paimon](https://paimon.apache.org/) provides a streaming storage layer that enables Flink to perform stream processing directly on the data lake. With this release, Paimon reaches a new level of maturity and continues to raise the bar on streaming storage.
## Key Highlights of Apache Paimon 0.6:
- The Paimon change data capture (CDC) integration now provides support for mainstream data ingestion and integrates with Flink, Kafka, Pulsar, and Mongo.
- Paimon extends Flink as a batch read and streaming source. It also supports the Flink time travel query and call procedures to optimize performance.
- The updates to the primary key table help maintain high throughput performance, speed up queries with read-optimized tables, perform special aggregations on fields, and improve compaction by over 20%.
- The introduction of a new metrics system for measuring read and write behavior enhances the built-in metrics to measure operations.
- New modules now support Paimon Spark, Paimon Trino, and Paimon Presto.
## Paimon + Streamhouse
We believe that Paimon has the potential to extend Ververica’s Enterprise Streaming and Analytics platform to encompass a concept we call Streamhouse. We envision Streamhouse as a solution for bridging the cost/latency gap between data lakehouse batch processing and real-time stream processing. For an overview of Streamhouse, [see our recent blog](https://www.ververica.com/blog/streamhouse-unveiled).
Ready to learn more about Ververica and test our capabilities for yourself? Get started with [Ververica Cloud](https://www.ververica.com/product/deployment/cloud).
## Resources
- Looking for an introduction to Paimon? Check out: [Apache Paimon: The Streaming Lakehouse](https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse)
- Curious to learn more about Streamhouse? Read: [Streamhouse Unveiled](https://www.ververica.com/blog/streamhouse-unveiled)
- [Apache Paimon Website](https://paimon.apache.org/)
- [Apache Paimon on Github](https://github.com/apache/incubator-paimon)
- [Watch Getting Started with Apache Paimon](https://www.youtube.com/watch?v=7cD7eFzaNew&t=891s)
- [Become an Apache Flink Expert at Ververica Academy](https://www.ververica.com/academy)
---
---
title: "Streamhouse Unveiled"
description: ""
lastUpdated: 2026-05-06T08:47:56.000Z
source_url:
html: "https://www.ververica.com/blog/streamhouse-unveiled"
md: "https://www.ververica.com/blog/streamhouse-unveiled.md"
---
## Apache Flink: History of Reliability
Every year, Apache Flink® sets new records in its development journey. Standing as a testament to its growing popularity, Flink now boosts over 1.6k contributors, 21k GitHub stars, and 1.4M downloads. In operational environments, Flink clusters are reaching impressive scales, with some individual clusters surpassing 2000 nodes. The largest known Flink infrastructure in production boasts over 4 million CPU cores, processing a staggering 4.1B events per second. If scalability is a concern, Flink has proven itself in the industry and stands as a reliable choice.
Over the past few years, Flink has witnessed widespread adoption across diverse industries, ranging from e-commerce and finance to gaming and healthcare. Mature solutions powered by Flink, such as personalized recommendations and robust risk control systems, now play a pivotal role in shaping the daily experiences of individuals.
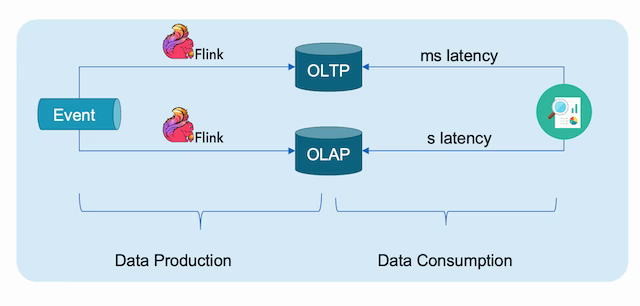
As an industry-proven and de facto standard for streaming data processing, Flink is seamlessly integrated into various scenarios. Whether it's processing data and storing results in OLTP databases for consumption by online applications, or sinking results into OLAP databases for analytics applications, Flink continues to be a driving force behind real-time decision making based on streaming data.
## Foundational Architecture
Before delving into the future of Flink, let's explore its foundational architecture. Flink boasts incredible features for streaming data processing, including stateful computation and exactly-once semantics. Of particular interest is its unified approach to batch and stream processing, where batch is treated as a specialized case of streaming. This means a single engine can seamlessly handle both bounded and unbounded data. Given Flink's prowess in streaming data processing, our focus will now shift toward enhancing batch capabilities.
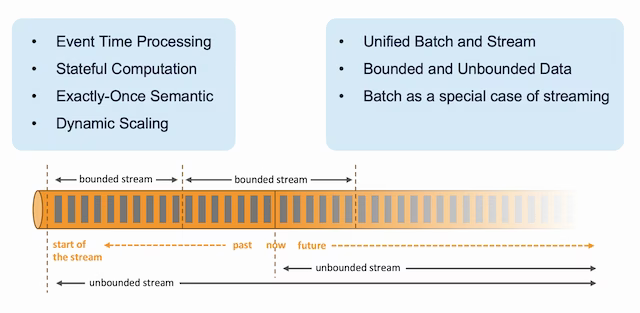
In the realm of batch data processing, data warehouses and data lakes play pivotal roles. Data warehouses process structured data through ETL pipelines, with the results serving as fodder for other applications. As the data landscape evolves, especially with the surge in AI requirements, data lakes have emerged to store raw data of varied structures, including structured, semi-structured, and unstructured.
Enter the Lakehouse, an evolution of the data lake that aims to unify the strengths of data warehouses and data lakes. Lakehouses offers the scalability and flexibility inherent to data lakes, coupled with metadata and table formats.
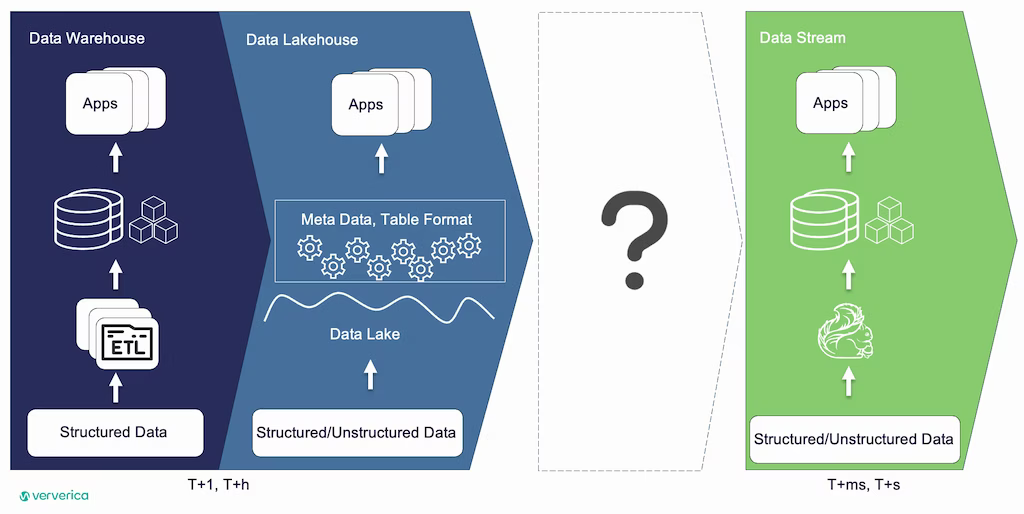
Bringing data streaming processing into the mix with data warehouses and Lakehouses reveals a distinction. Traditional Lakehouses exhibit daily or hourly data latency, while data streaming achieves remarkable second or even millisecond latency. This creates a noticeable gap between them.
## Cost and Latency
In the realm of data processing, two crucial factors always come into play: cost and result latency. Visualizing this relationship, we can refer to it as the data processing triangle. If cost is a primary concern, the choice leans towards a Lakehouse; if latency takes precedence, real-time streaming becomes the preferred option. Real-time streams are indispensable for specific business cases such as risk control, while Lakehouses, through batch data processing, cater to a myriad of other scenarios and use cases.
As businesses grow and their dynamics become clearer, the need for low-latency data arises. The immediate consideration is often migrating jobs from a Lakehouse to a real-time stream. But does this transition truly make sense?
In large organizations running hundreds of thousands of batch jobs, the scarcity of streaming jobs is questioned. The common response attributes this scarcity to the absence of real-time business requirements. However, this seems paradoxical, as faster decision making inherently accelerates business operations—time is money, after all. An alternative perspective posits that perhaps the lack of readiness in streaming infrastructure is impeding the recognition of real-time business needs. The counterargument to this is that streaming jobs are typically expensive, leading to a dilemma: is it justified to invest significantly in building infrastructure when the business requirement is uncertain?
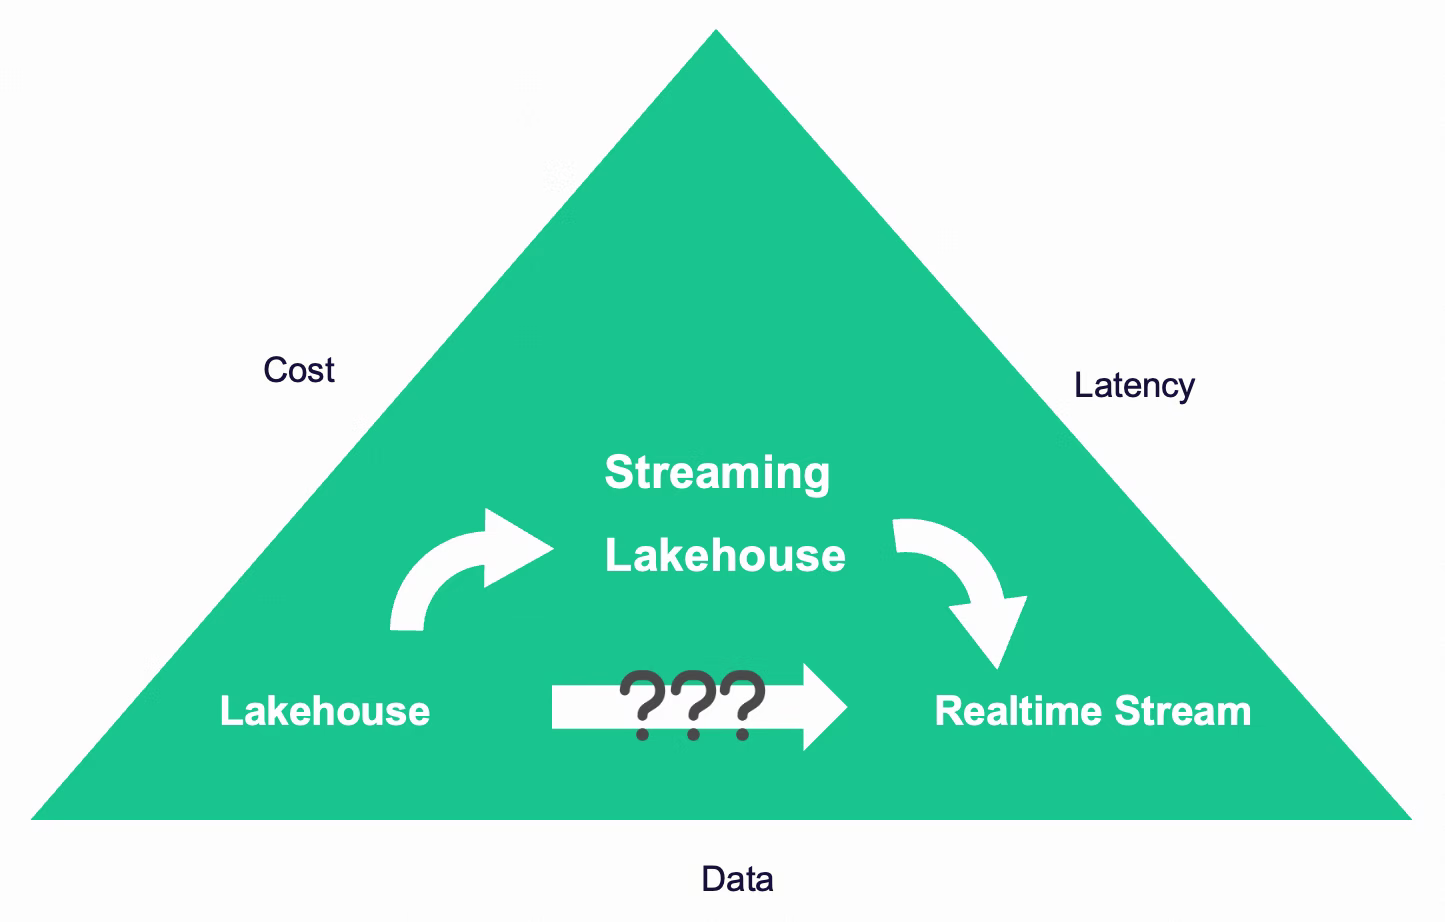
This predicament resembles a chicken-and-egg scenario: no business requirements, no streaming infrastructure; no streaming infrastructure, no recognition of real-time business needs. The crux lies in Return on Investment (ROI) and managing costs.
The overarching question emerges: is there a more efficient, cost-effective, and consequently, low-risk method to facilitate system upgrades?
## Major Disruptor: Introducing Streamhouse
Streamhouse disrupts the deadlock by providing a solution to upgrade high-latency batch jobs to Streamhouse with near-real-time latency. This allows businesses to assess its suitability by running operations and gauging results. After obtaining business outcomes, an evaluation of the ROI becomes feasible. The decision then rests on either adhering to Streamhouse with optimized costs or progressing further to real-time streaming computation. The seamless migration facilitated by the Flink unified engine and Flink SQL minimizes the effort involved.
This approach aligns with the data processing triangle concept, leading to the evolution of a data processing architecture pattern termed LSR (Lakehouse, Streamhouse, and Real-time stream). The cost increment occurs progressively from Lakehouse to Streamhouse and then to real-time streaming.
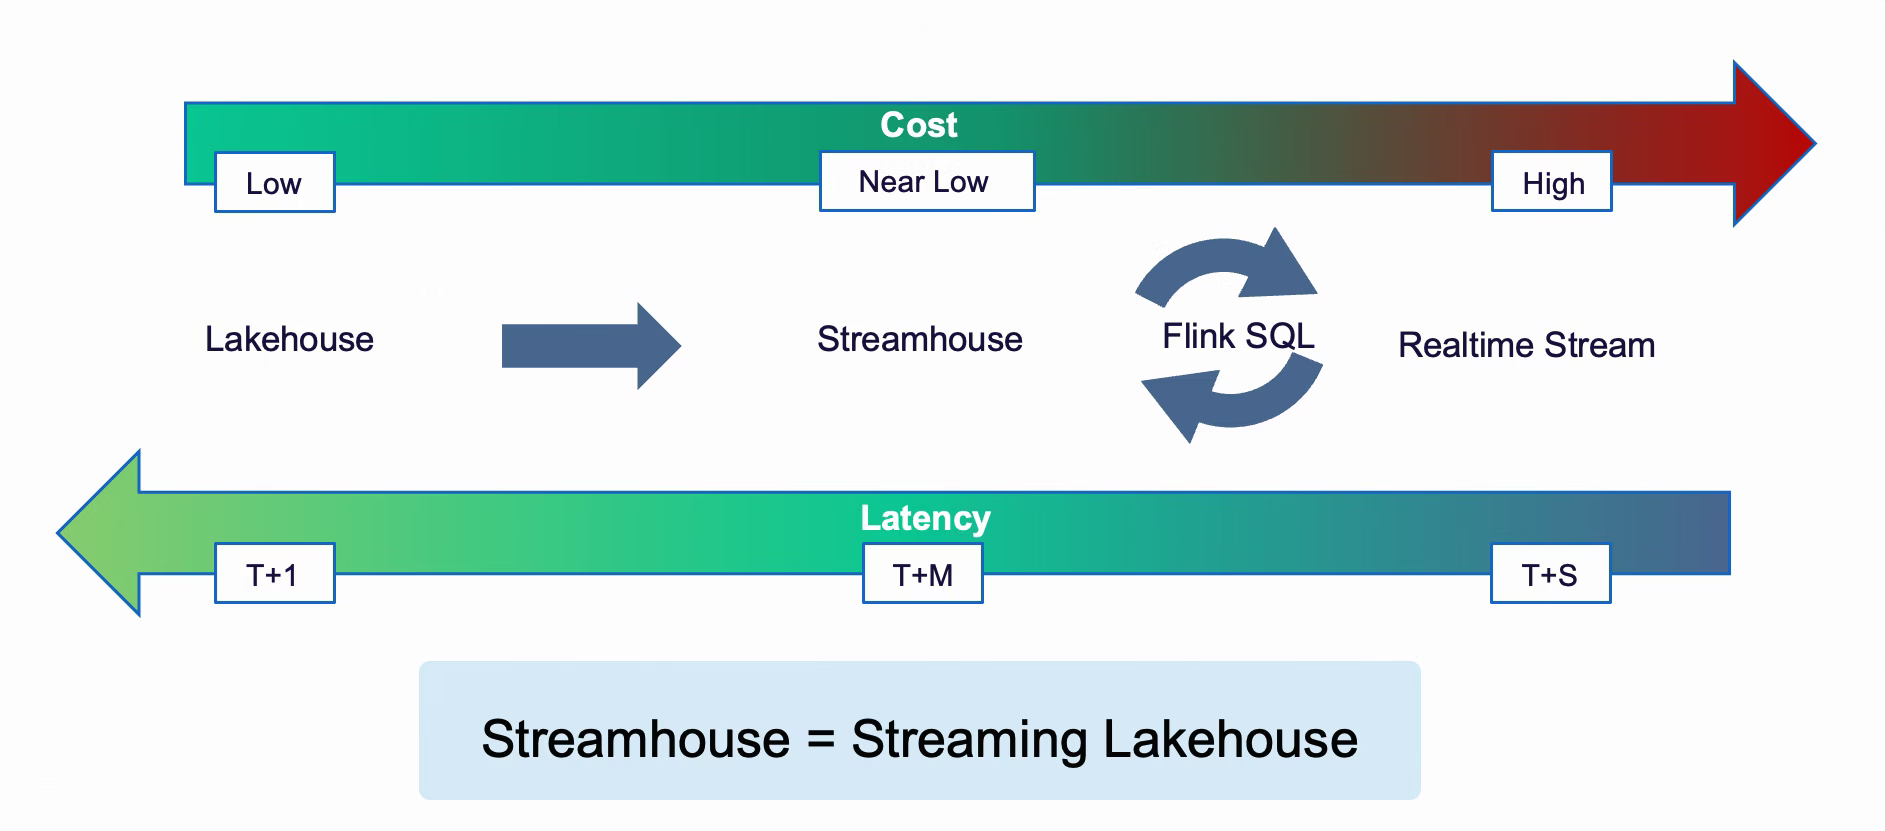
The advantages of utilizing Streamhouse are twofold. Firstly, the significant improvement in latency from days to minutes outweighs the increased cost compared to Lakehouse. Secondly, leveraging Flink SQL provides users with flexibility, allowing them to transition between Streamhouse and real-time stream based on evolving business requirements.
## Four Components of a Data Processing Pipeline
In any data processing pipeline, four key components play crucial roles: data ingestion, data computation, metadata, and data storage. Lakehouse and streaming data processing differ in their approaches. Lakehouse relies on batch ETL, batch data processing, and batch table format, saving data in object storage. On the other hand, streaming involves ingesting data in streaming mode, supporting Change Data Capture (CDC). Streaming processing engines like Flink process the data, with additional services like schema registry managing the schema, and data stored in the message system.
## Streamhouse: Best of Both Worlds
Streamhouse integrates aspects of both approaches. It processes data in both batch and streaming modes, with the table format aligning with streaming concepts. While data can be saved into tiered object storage, cost-effective object storage is typically sufficient for most cases.
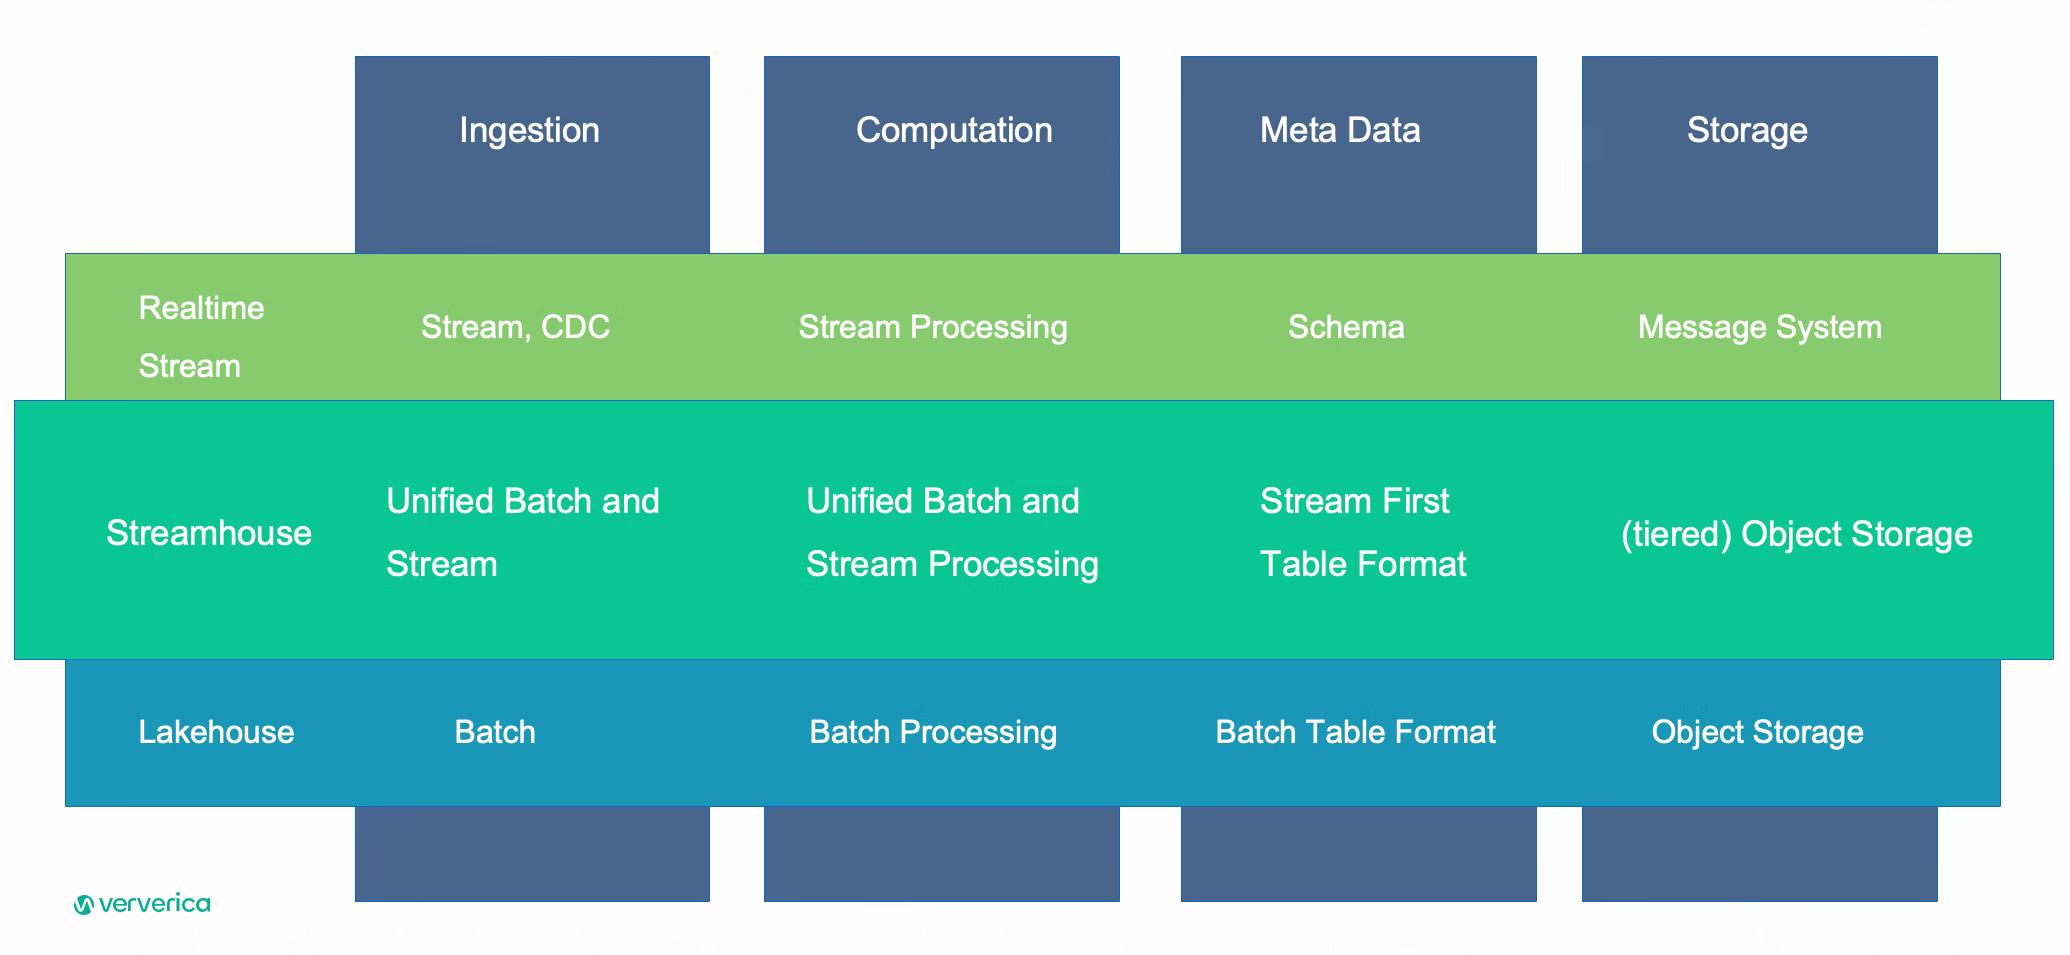
To implement Streamhouse, Flink serves as the ideal computation engine due to its unified batch and stream architecture. We've extended Flink's capabilities by developing Flink CDC, facilitating unified batch and stream data ingestion. Additionally, we've introduced Apache Paimon as the stream-native data lake platform surrounding Flink.
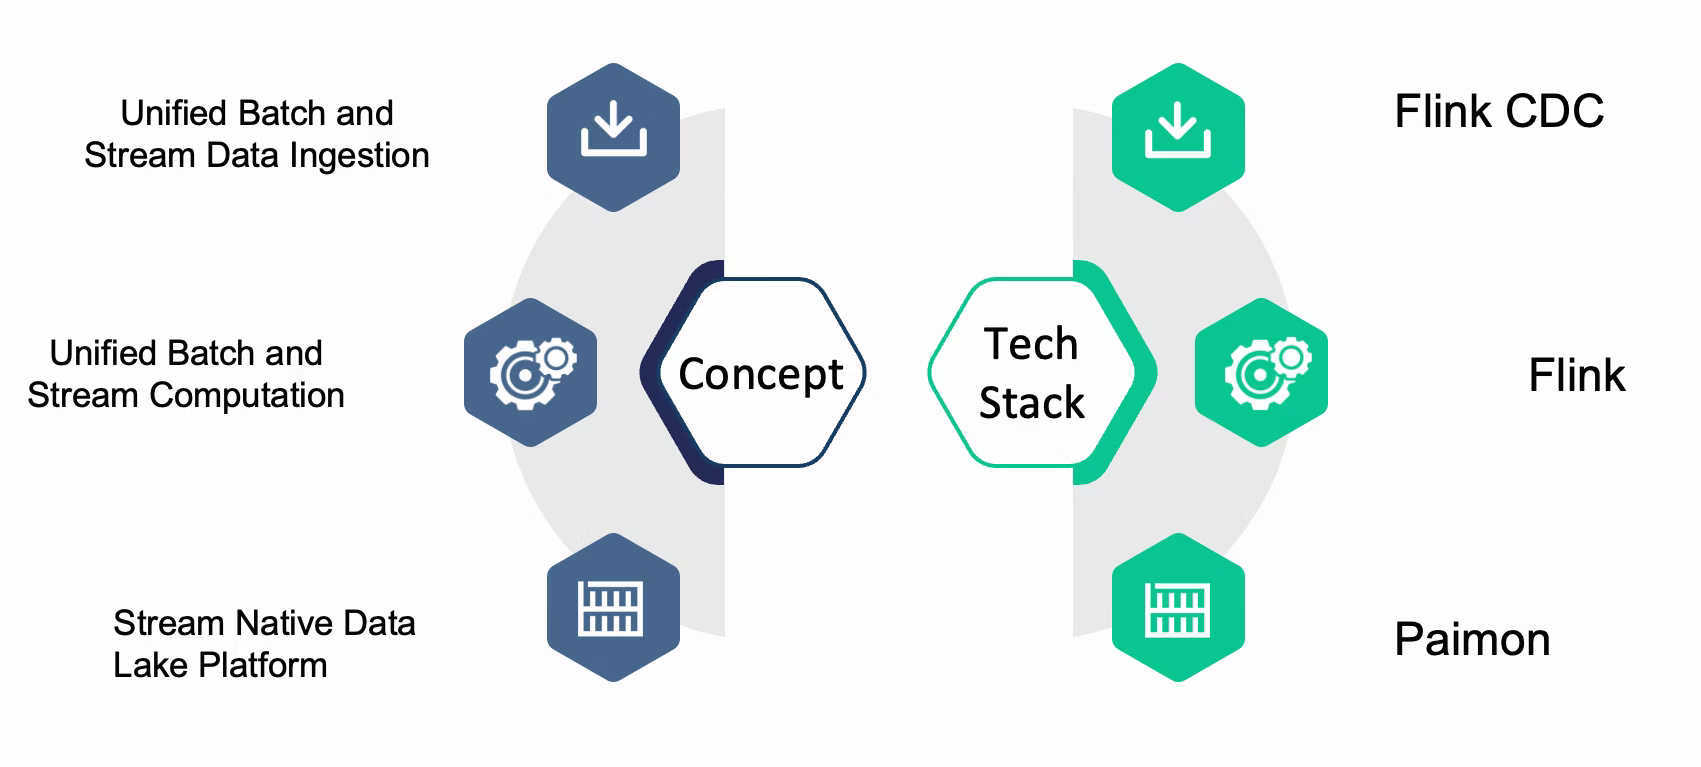
## Flink CDC
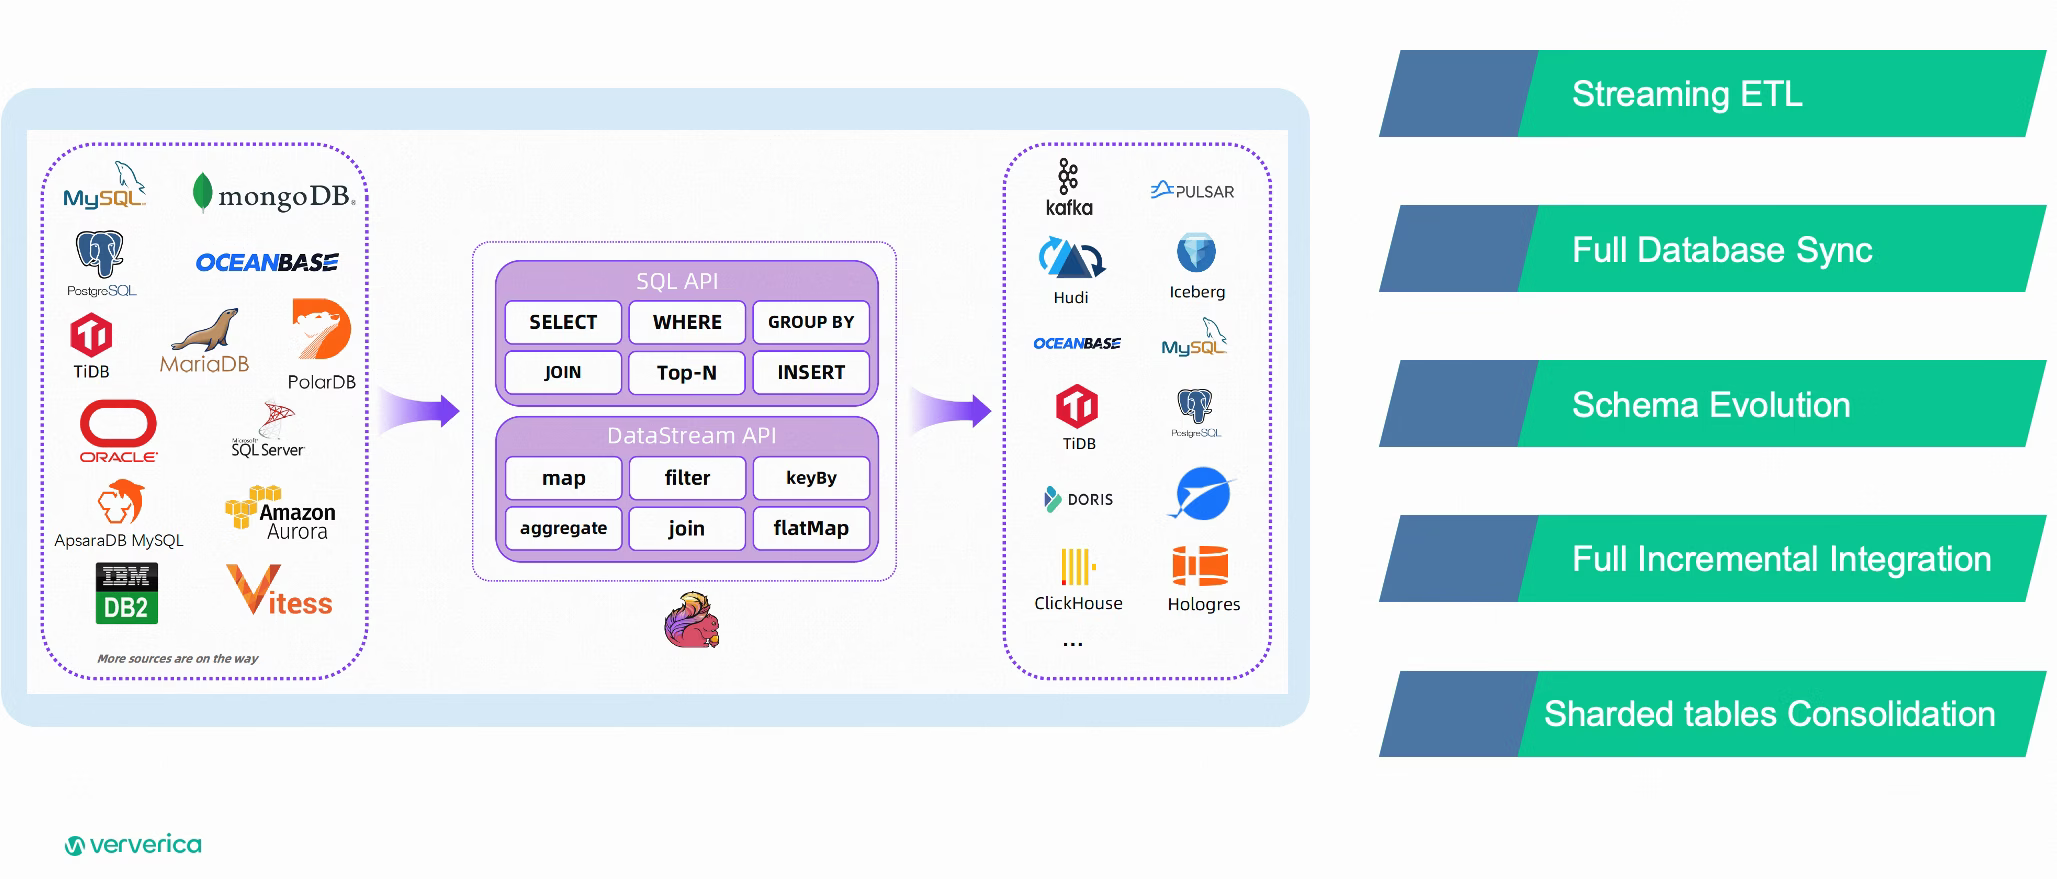
Flink CDC stands as the initial component in the Streamhouse tech stack. Its primary responsibility lies in ingesting data in both batch and stream formats. The transition between batch initial load and incremental load is smooth and devoid of locks. Flink CDC offers compatibility with a majority of mainstream databases and incorporates numerous features crafted in response to real business needs. Examples include full database synchronization and the consolidation of sharded tables.
To propel Flink into the Streamhouse era, our efforts extend beyond refining the core engine; we're dedicated to unifying batch and streaming functionalities.
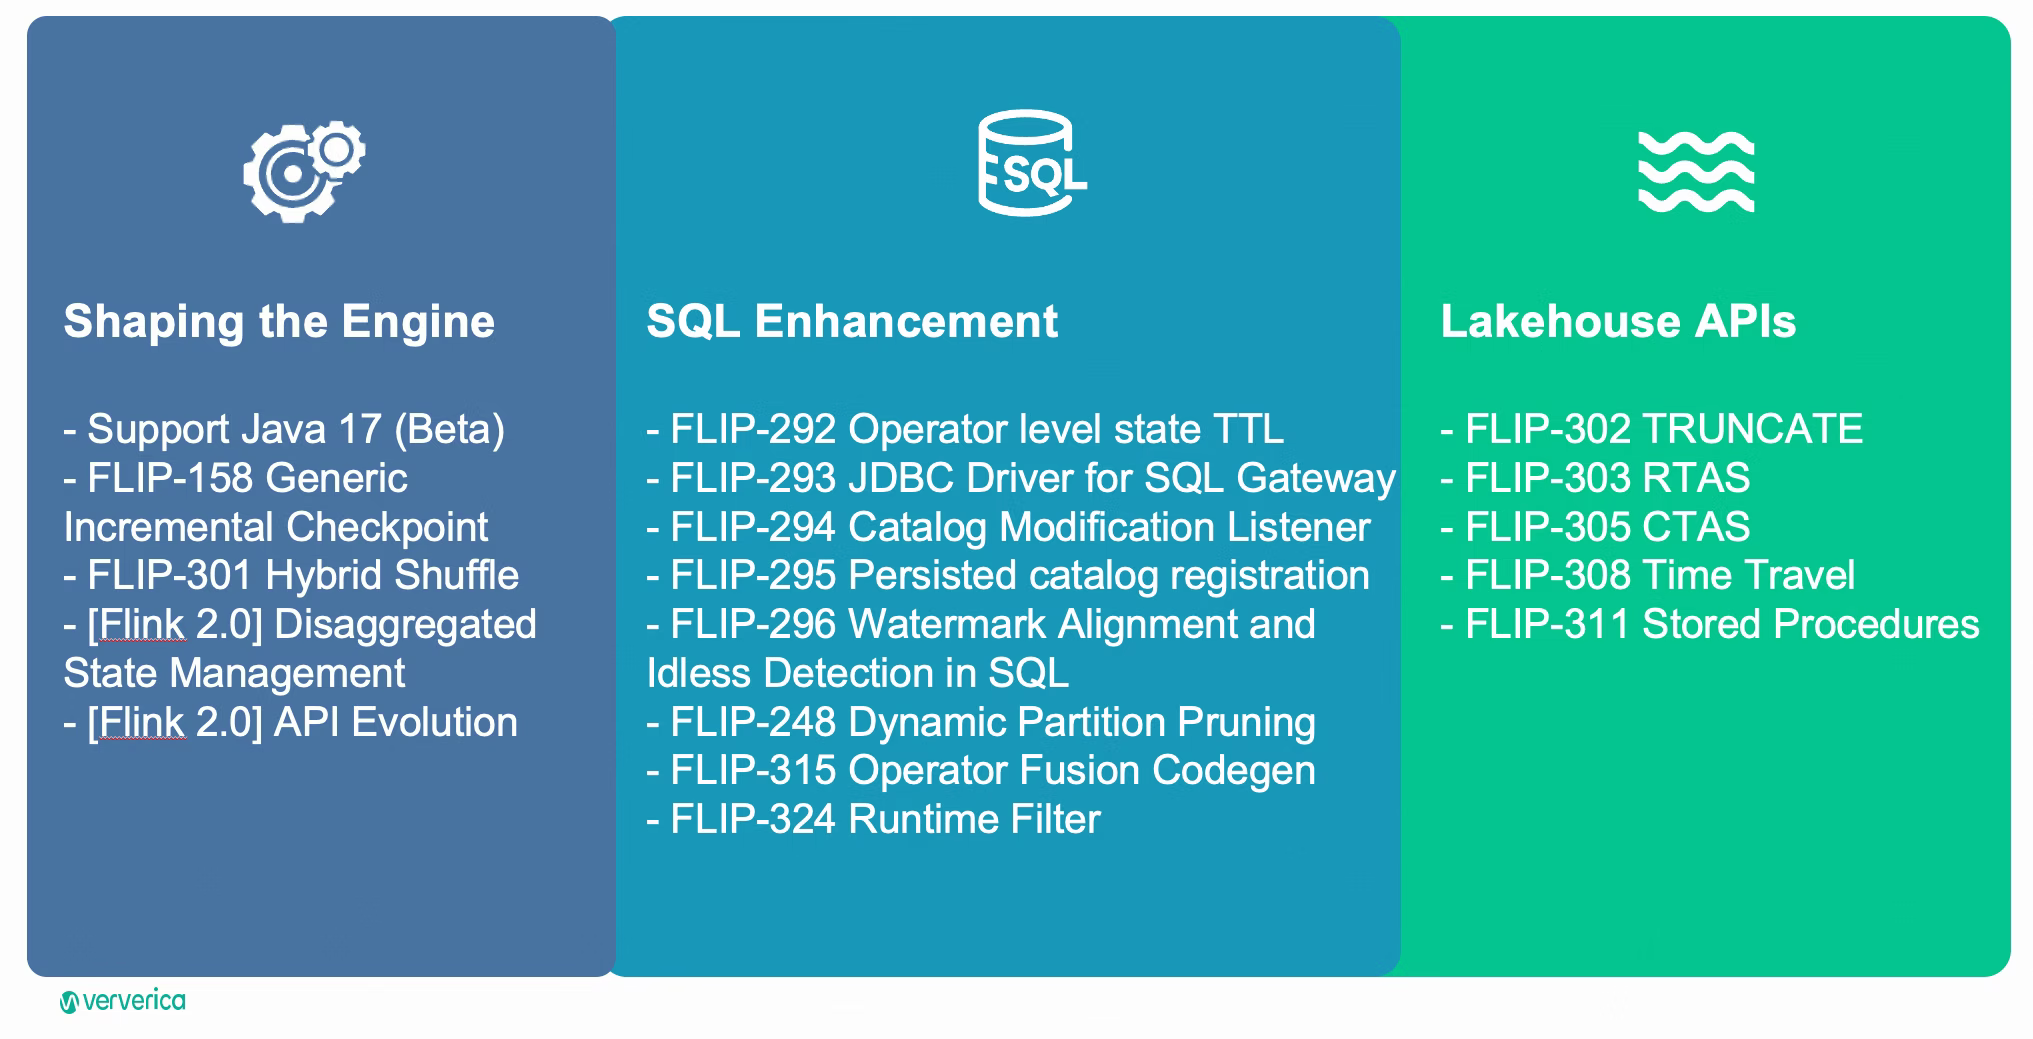
For instance:
- Elevating SQL capabilities with enhancements such as dynamic partition pruning and runtime filters to minimize redundant data IO and network transmissions.
- Implementing an operator fusion code generator to harness the full potential of modern CPUs.
- Actively constructing APIs to align with the Lakehouse concept.
Let's explore more details about the engine and the improvements made in Flink SQL.
The checkpoint duration plays a crucial role in end-to-end latency. A shorter checkpoint duration translates to lower latencies for transactional sinks, more predictable checkpoint intervals for daily operations, and less data to recover. Improving checkpoint duration involves addressing two major factors: the travel time of barriers through the pipeline and the time taken for checkpoints.
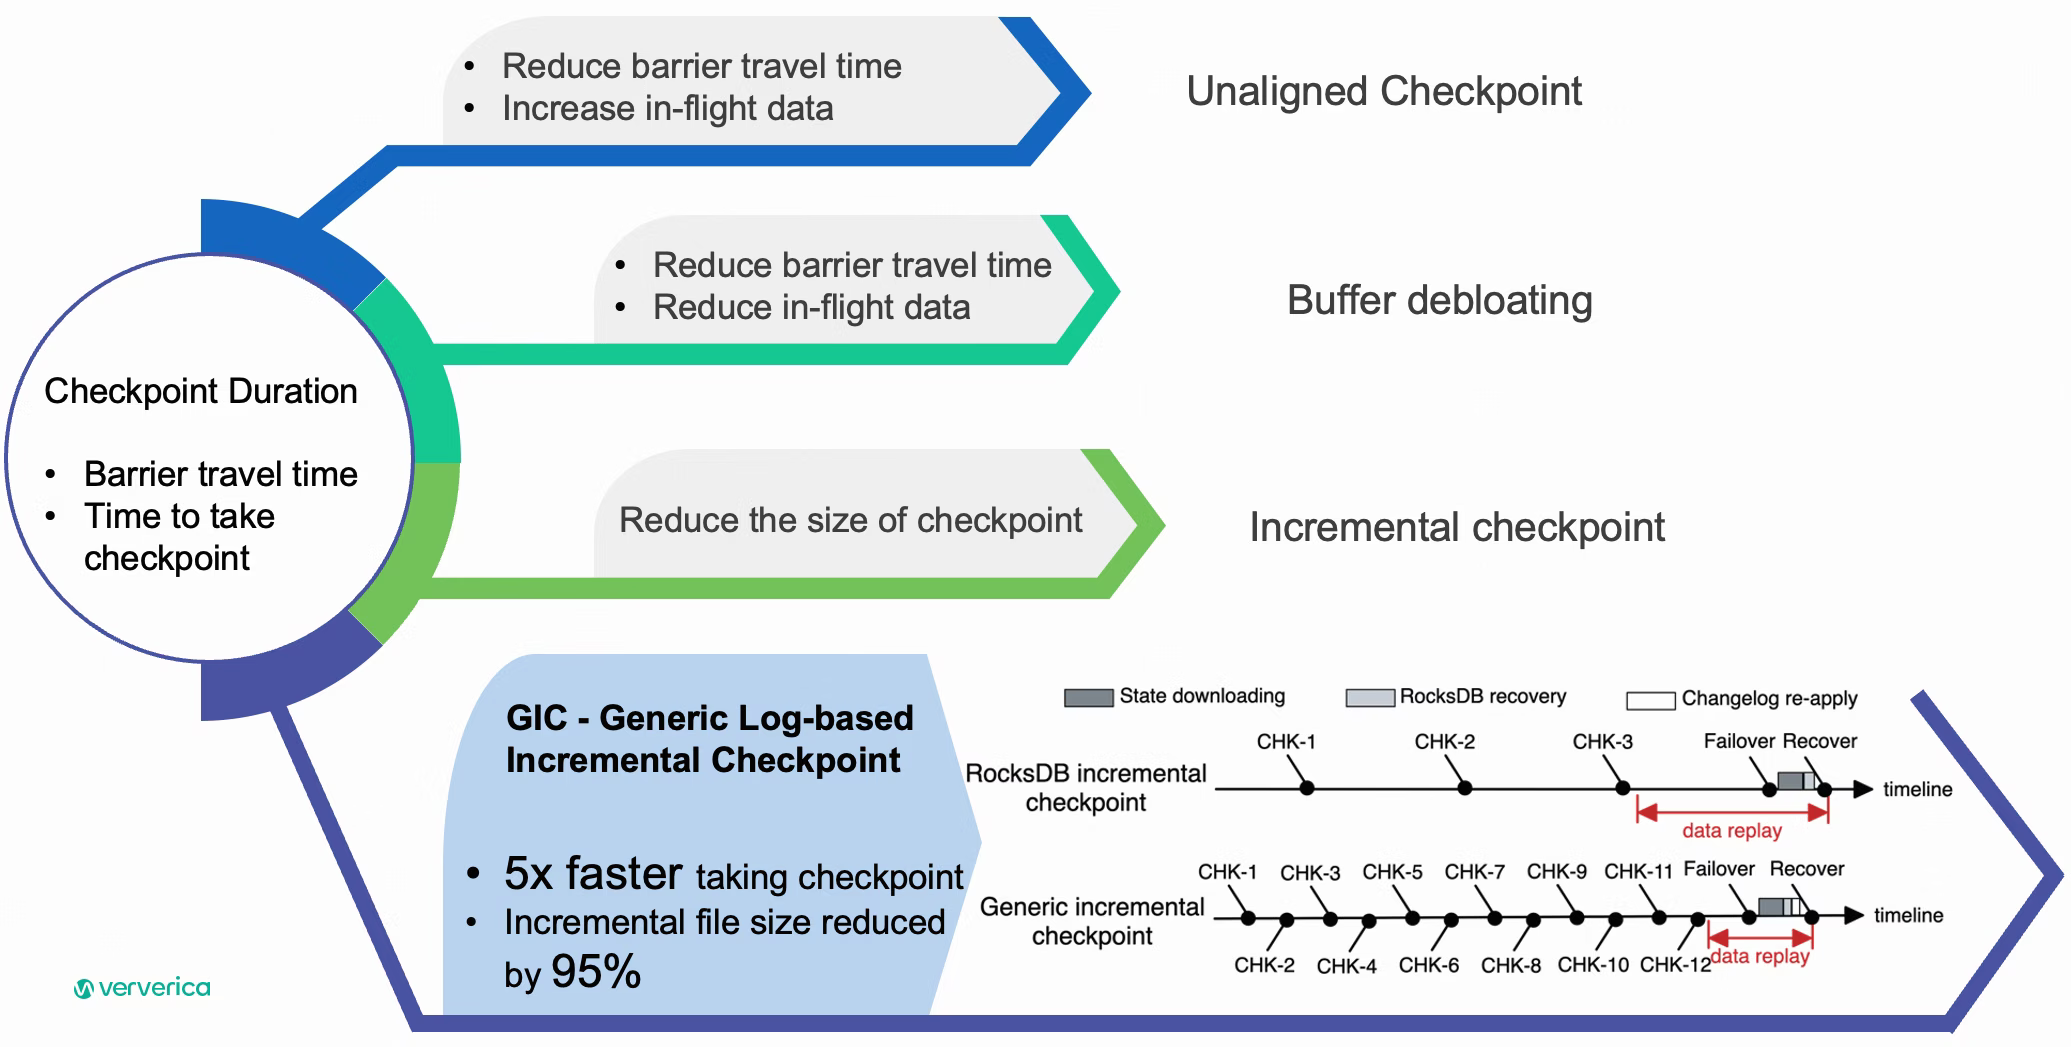
The Flink community has undertaken significant optimization efforts based on these factors. Unaligned checkpoints, while reducing barrier travel time, may increase in-flight data as a side effect. Buffer debloating uses dynamic buffer size management to reduce both barrier travel time and in-flight data. Incremental checkpoints leverage the RocksDB LSM tree to persist only newly created SSTABLE files, thereby reducing checkpoint size.
The GIC (Generic Log-based Incremental Checkpoint) introduces a state changelog, further reducing checkpoint duration and supporting an even shorter checkpoint interval. Statistics indicate that GIC could provide five times faster checkpointing, with the incremental file size significantly reduced by 95%.
Hybrid Shuffle emerges as a pivotal feature in the unification of batch and stream processing. While Pipeline Shuffle offers superior performance, it demands more resources as all interconnected tasks must start simultaneously. The allure of using Pipeline Shuffle in batch execution is tempered by challenges, especially in production environments where resource availability isn't guaranteed. The competition among multiple tasks for resources can even lead to deadlocks.
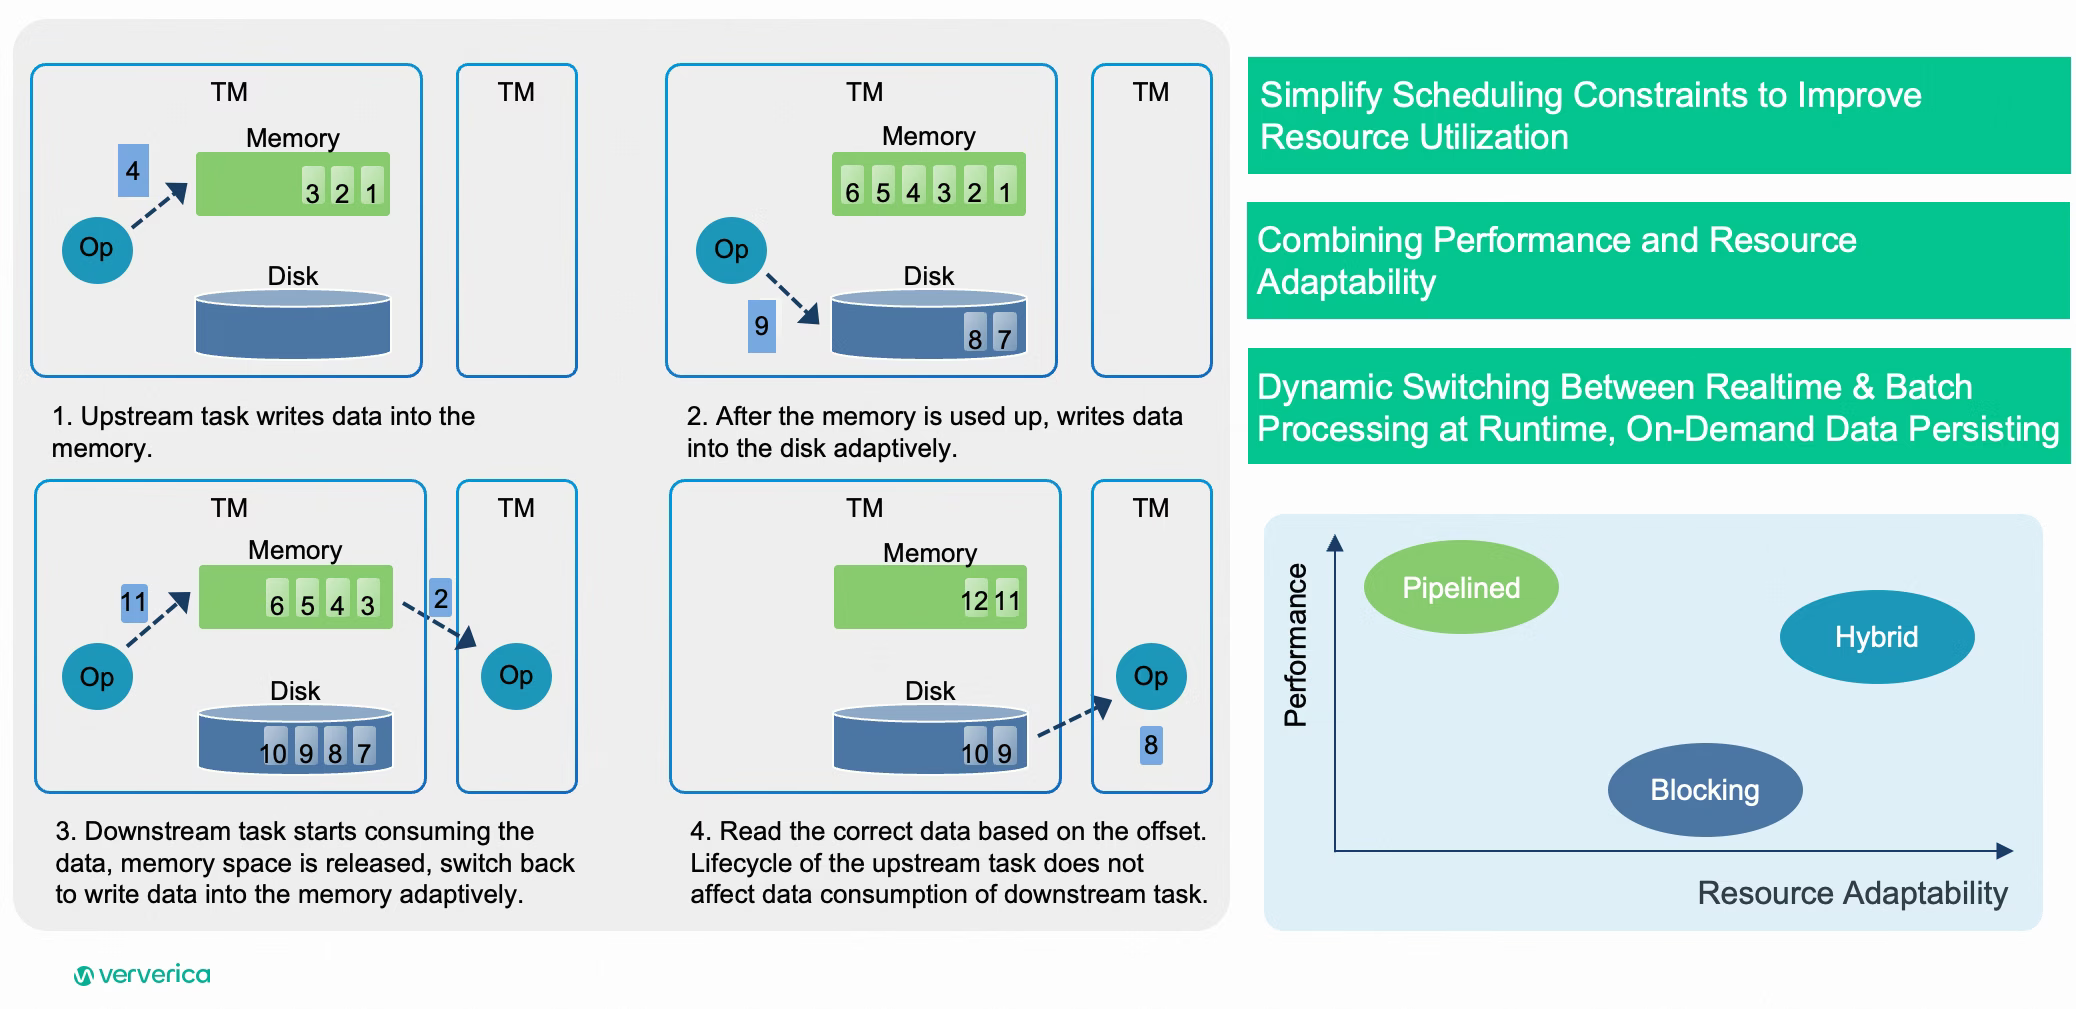
## Apache Flink 2.0
In Flink 2.0, the community is set to elevate the Flink state storage management system by transitioning to a fully decoupled storage and computation architecture, aligning with the demands of a cloud-native environment.
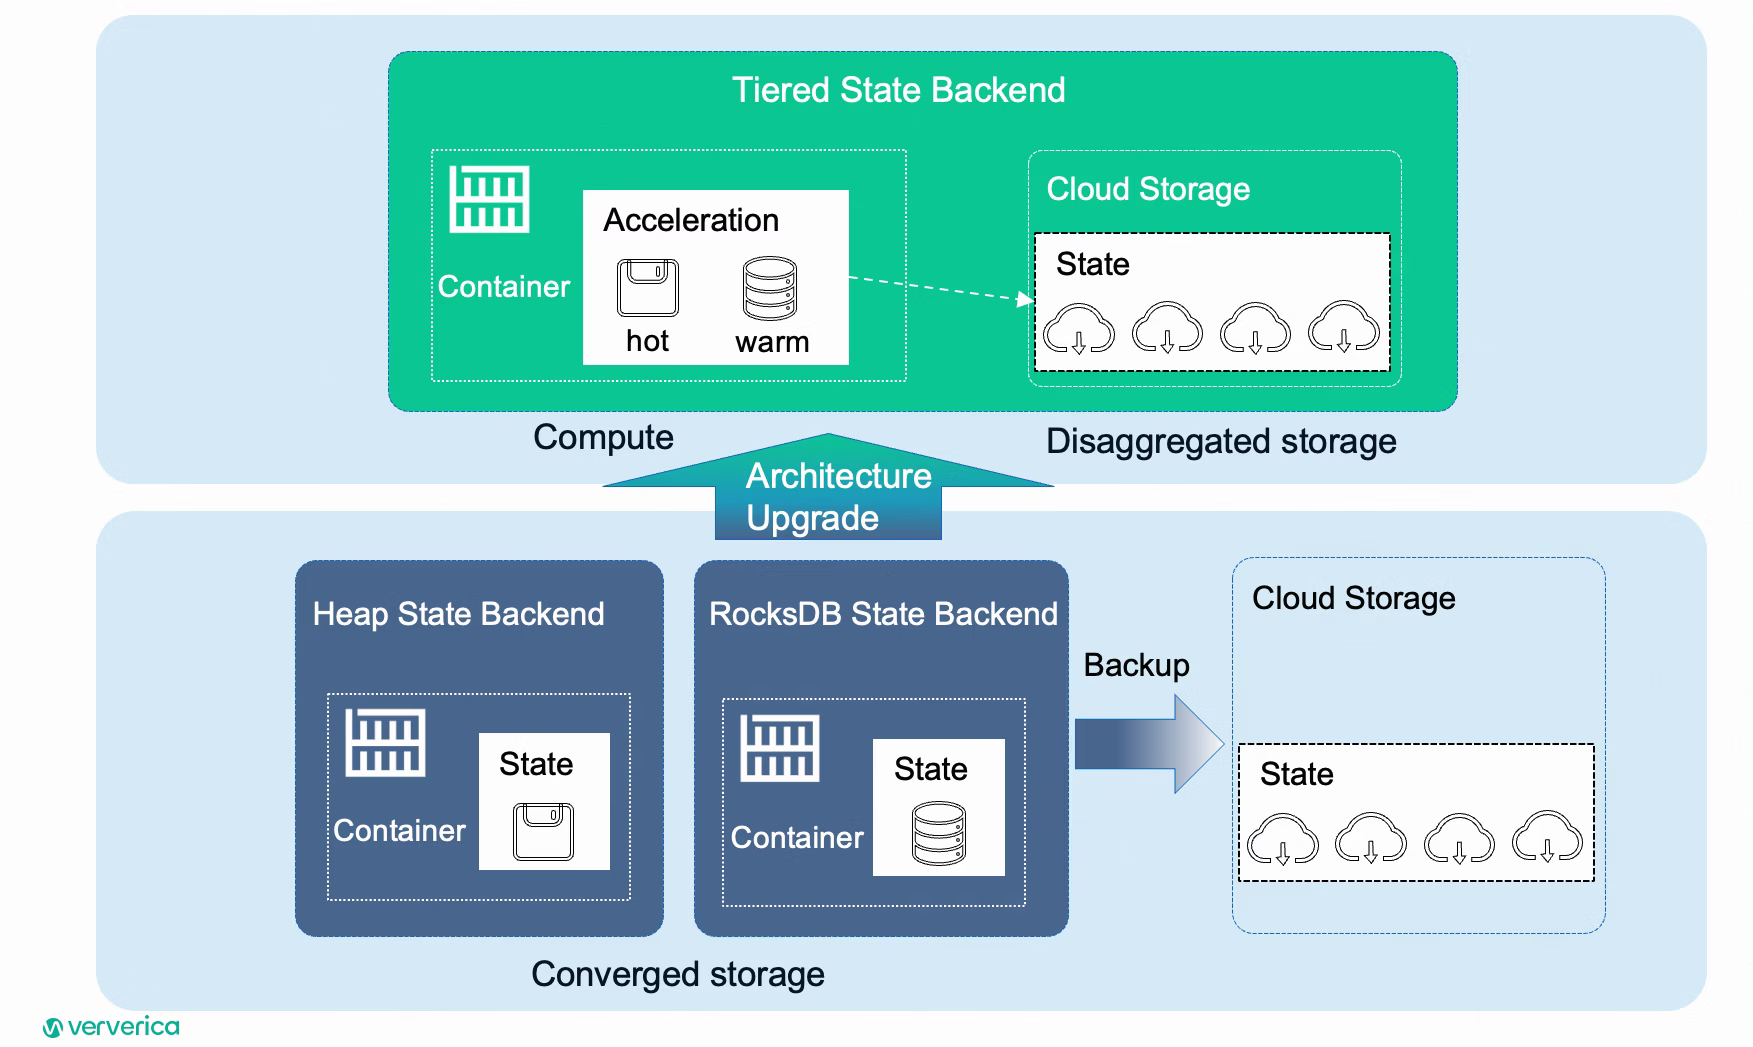
Currently, Flink's state storage system doesn't fully embody a storage-computation separation architecture. All state data resides in local RocksDB instances, and only incremental data is transferred to remote storage during distributed snapshots to guarantee complete state data storage remotely. Looking ahead, Flink envisions relocating its state data entirely to remote storage, reserving local disks and memory exclusively for caching and acceleration.
This transformative move will establish a tiered storage system referred to as the 'Tiered State Backend' architecture.
**Key Enhancements Envisioned:**
- Implementation of a tiered storage system where data with varying temperatures will be stored on different hardware to optimize access performance.
- Introduction of query optimizations such as hash indexing or sorted indexing to further enhance performance.
In Flink 2.0, a significant objective is the execution of API Evolution, which involves restructuring the API into four distinct categories:
- **Low-Level API**: Includes functionalities like processFunction and DataStream.
- **High-Level API**: Encompasses Table and SQL functionalities.
- **Connector API**: Covers e.g. Source- and Sink-functions, for example.
- **Operation API**: Includes metrics, configuration, and RESTful API.
The evolution unfolds in two phases:
- **Phase one: Breaking Changes**
- Removal of legacy API elements like DataSet, SourceFunction and SinkFunction, TableSource, and TableSink.
- Cleanup of deprecated classes, methods, fields in the Java API, along with deprecated configuration options, metrics, and REST API endpoints.
- **Phase two: API Redesign**:
- Introduction of a new queryable state API post the implementation of Disaggregated State.
- Refactoring the DataStream API with a new ProcessFunction, eliminating internal dependencies and preventing the exposure of internal APIs.
- Introduction of a new, clean configuration layer.
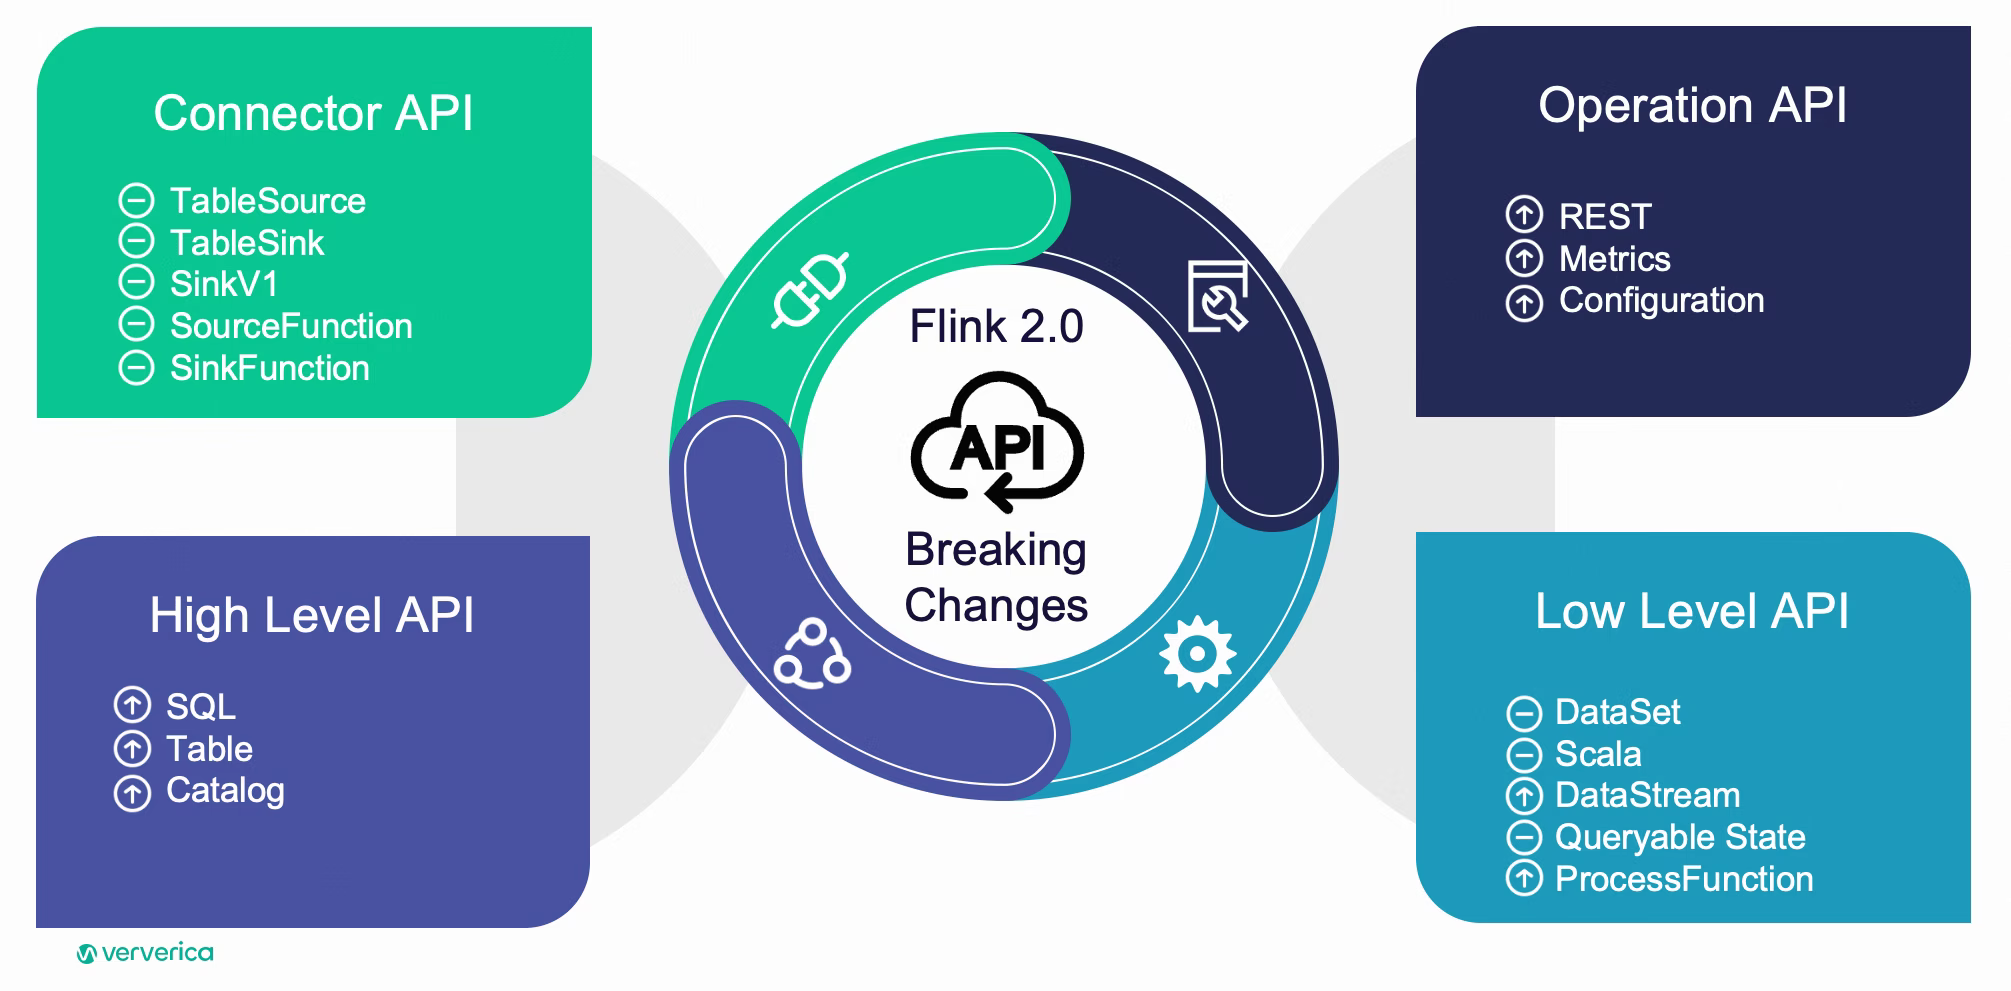
Flink, renowned for its prowess in streaming data processing, offers a robust framework for low-level data stream manipulation. However, for the majority of end users, Flink SQL is the recommended approach. Why SQL? Because it provides a high-level, declarative API that allows users to concentrate on their specific business logics, leveraging domain expertise in areas like feature engineering in AI, user behavior in e-commerce, and clinical research in the medical field. In these scenarios, where strong domain expertise is crucial, users prefer not to grapple with the intricacies of the underlying technologies.
By adopting SQL as the abstraction layer, Flink creates a symbiotic relationship. Users can focus solely on their business requirements, while Flink relentlessly concentrates on data processing and continuous optimization.
Regarding SQL capabilities, Flink already offers an extensive set of syntax, including DDL, DML, aggregation, joins, and more. Yet the full potential of Flink SQL is often underestimated. It can be categorized into four main types:
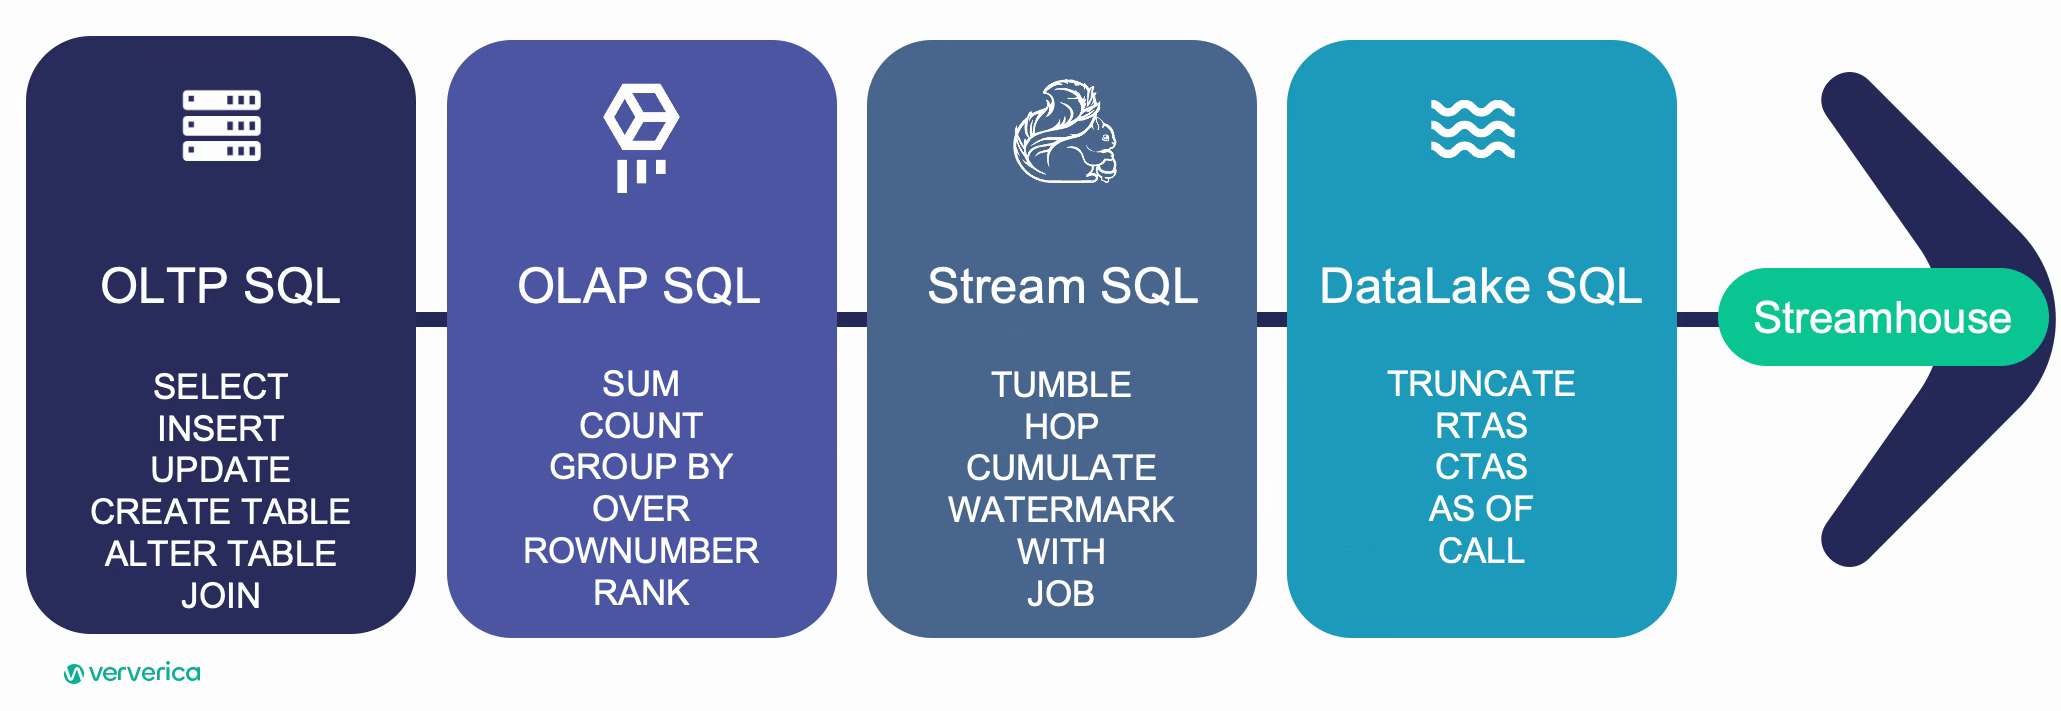
- **OLTP SQL**: for traditional data manipulation and querying.
- **OLAP SQL**: for data warehouse ETL processes.
- **Stream SQL**: for unique streaming data processing logic, such as tumble or hop windows.
- **Data Lake SQL**: for executing common lake house tasks, like creating a table as select.
With these powerful SQL capabilities, users can accomplish a wide array of tasks.
## Apache Paimon
Having delved into Flink CDC and Flink, let's explore the storage platform integral to the Streamhouse - [Apache Paimon](https://paimon.apache.org/). Born as a Flink sub-project under the moniker "Table Store," Paimon has evolved into an [Apache incubator project](https://paimon.apache.org/).
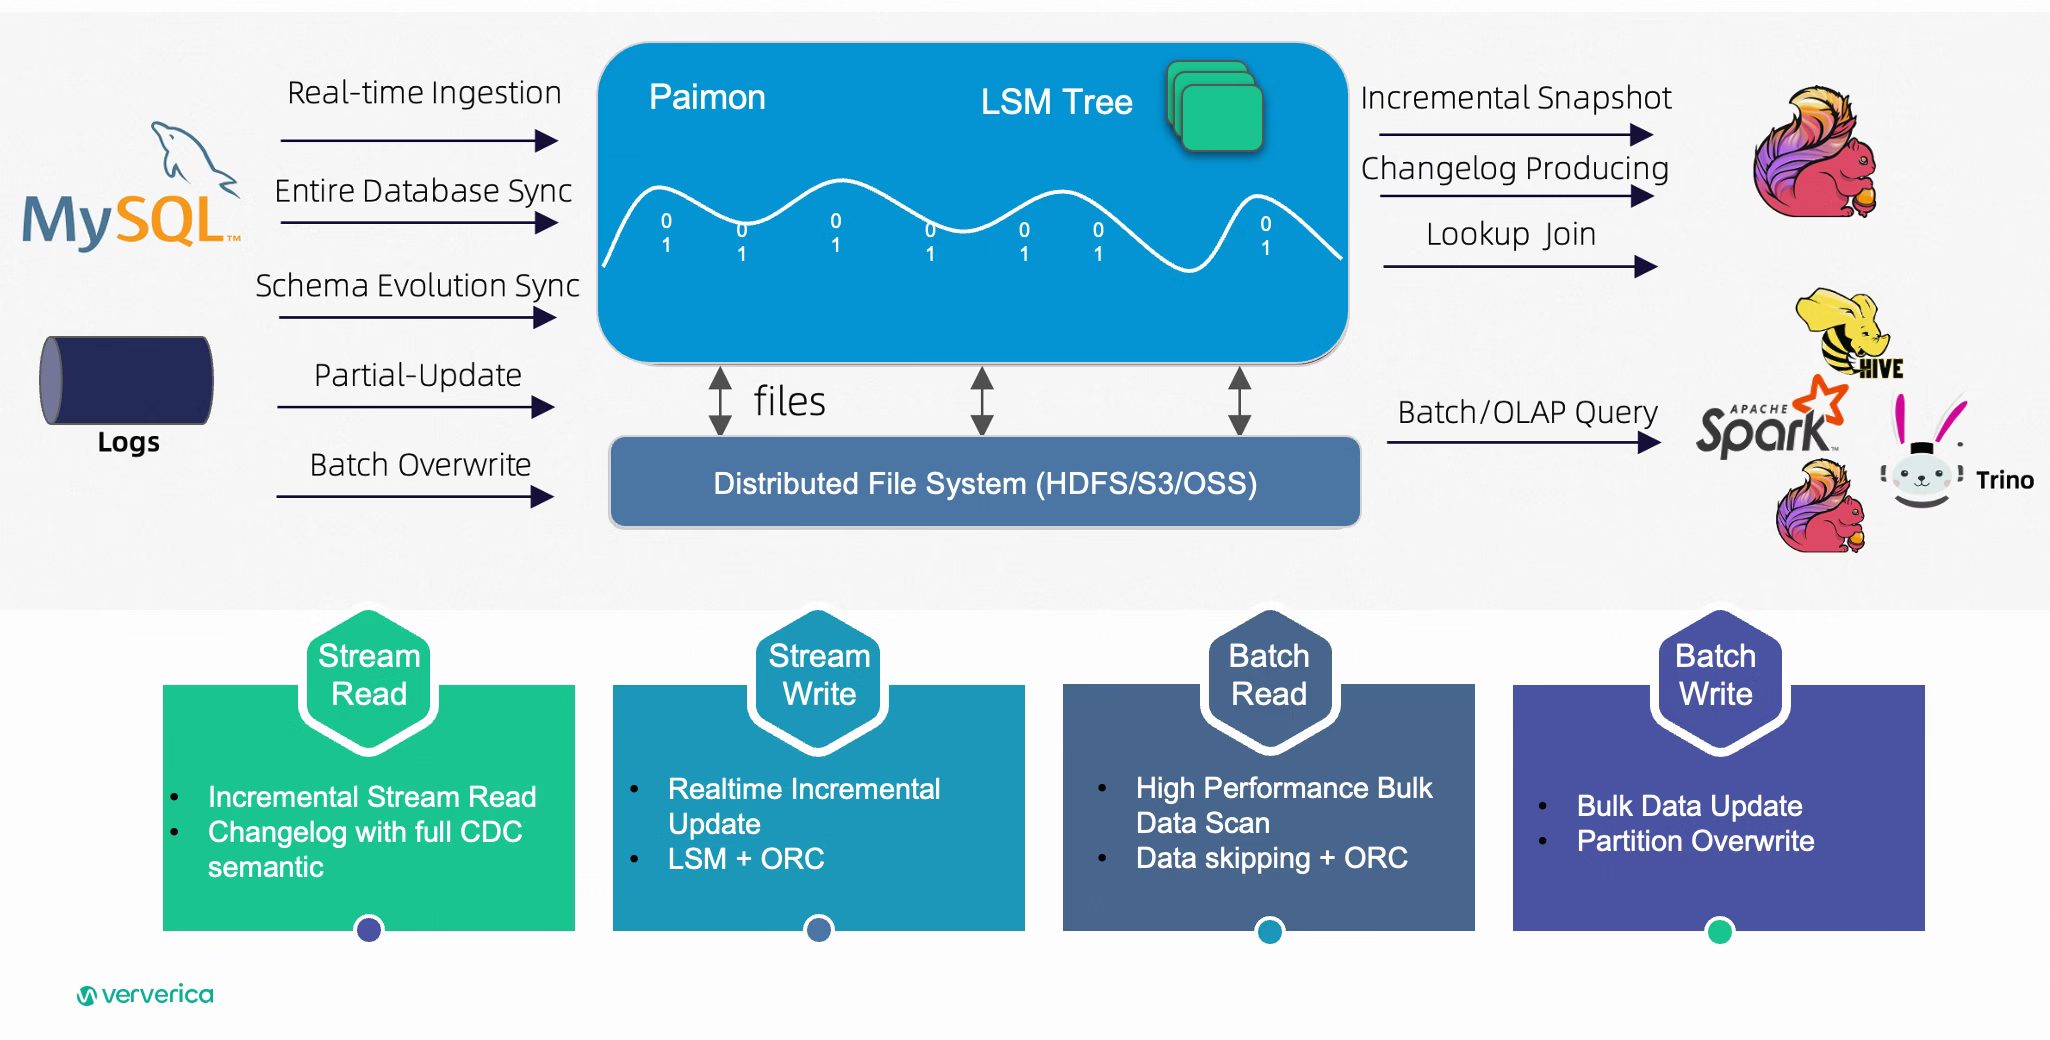
While the internal table format draws strong inspiration from Apache Iceberg, incorporating concepts like snapshots and manifest files, its underlying data structure aligns with log-structured merge-trees (LSM), tailor made for streaming.
This architecture positions Paimon as a unified batch and stream data lake platform, boasting various exciting features:
- Adept support for both batch read/write and stream read/write operations.
- Provision of scalable metadata by leveraging cost-effective data lake storage.
- Enhanced versatility, through the use o rich merge engines, such as deduplication (retraining the last entry), partial update, and aggregation.
- Simplified construction of streaming pipelines through Changelog producers, offering various patterns like 'input,' 'lookup,' and 'full-compaction.' This ensures easy creation and management of changelogs for your data.
Examining common data processing pipelines involving ODS ingestion, DWD transformation, and DWS, several intriguing scenarios emerge:
- **Scenario 1**: Solely leverage Flink CDC and Paimon for CDC data ingestion. Continue utilizing Spark to read operational data from ODS and execute Spark batch processing.
- **Scenario 2**: Deploy Flink SQL for streaming or batch ETL from ODS to DWD. Allow OLAP engines to consume DWD, resulting in a significant reduction in end-to-end data latency.
- **Scenario 3**: Utilize Flink SQL to construct end-to-end streaming mixed ETL processing (streaming and batch). Employ a unified technology for diverse data processing tasks, effectively reducing both development and operational costs.
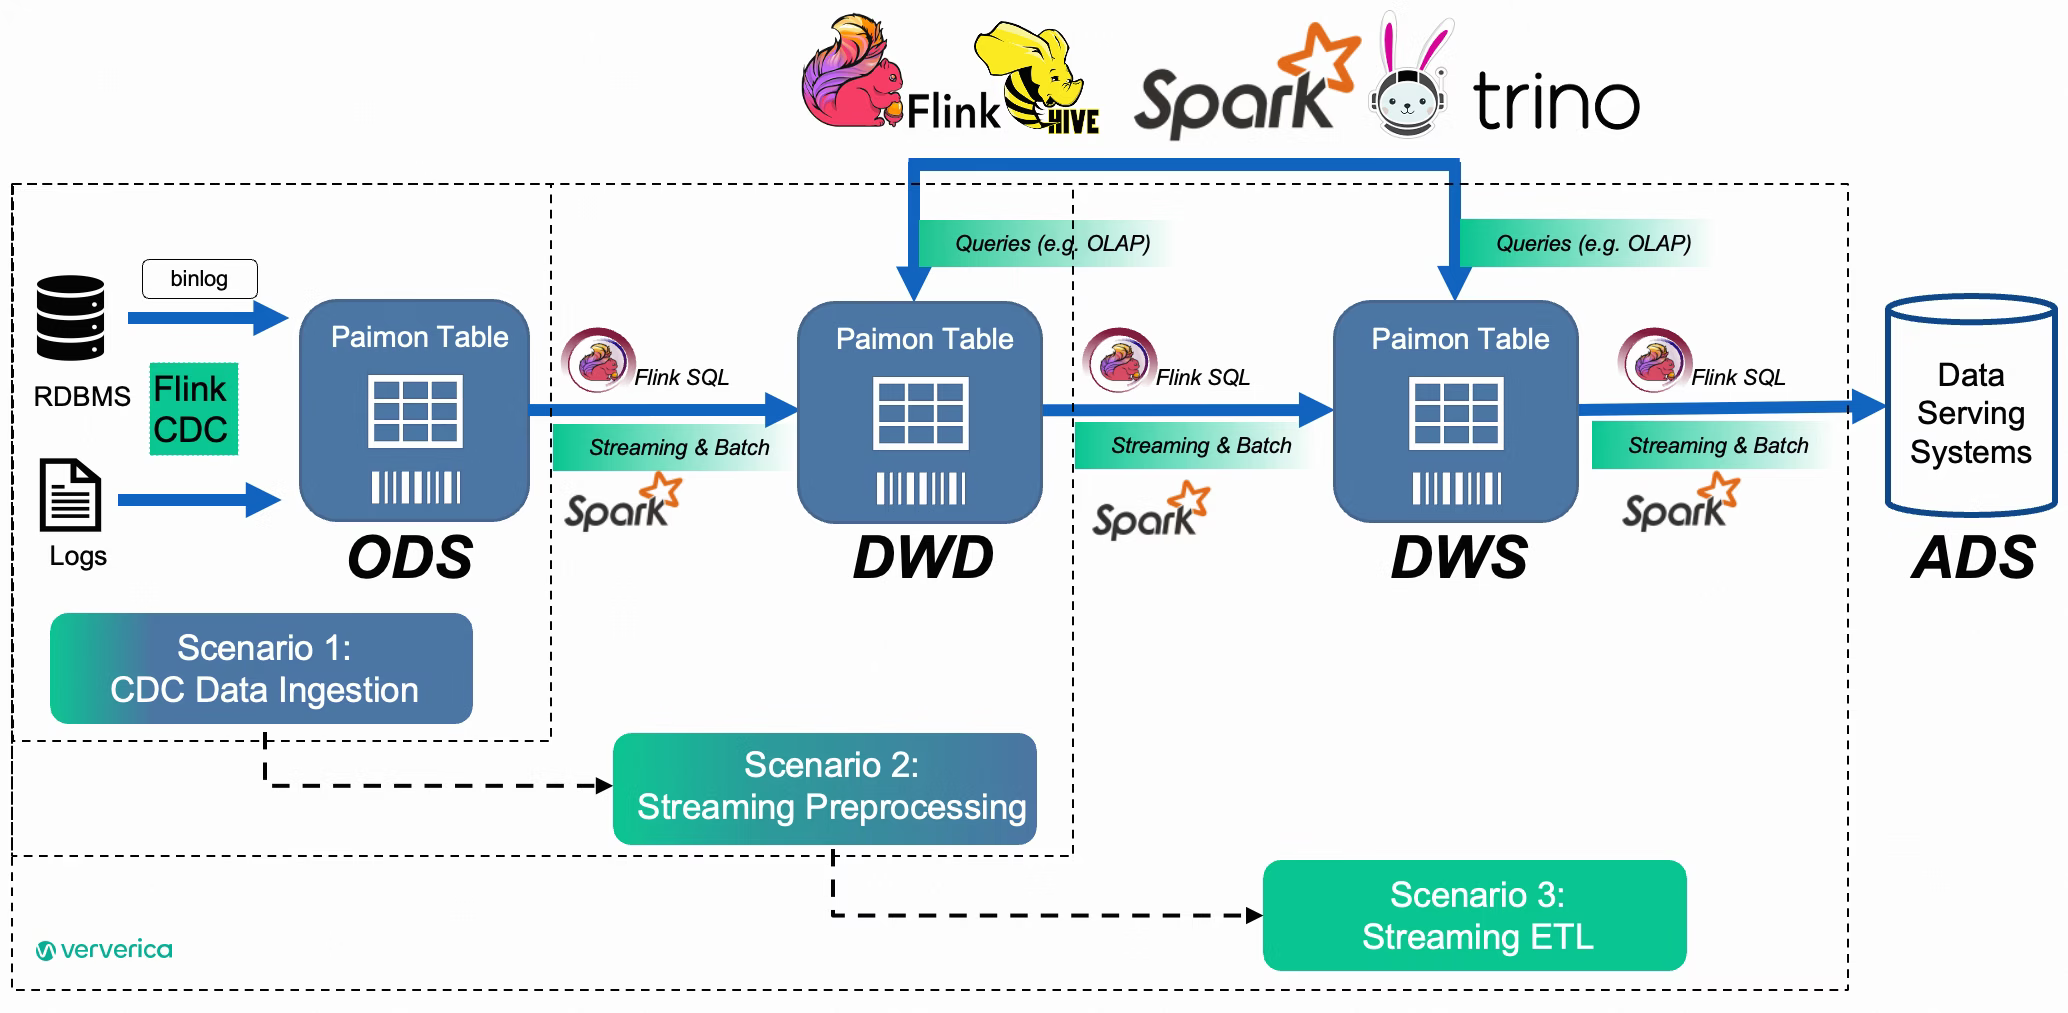
The Flexible FFP Architecture empowers you to enhance end-to-end data latency at your own pace, aligning with real business requirements. The beauty lies in the graceful progression within your existing Lakehouse, allowing step-by-step improvements that generate tangible business value. This approach instills confidence, making it easier to venture into more advanced stages.
## Welcome to Streamhouse!
The Streamhouse concept was introduced as a result of recognizing the gap between Lakehouse and real-time streaming data processing. Streamhouse was implemented by reshaping Flink and introducing tools like Flink CDC and Paimon. The result is a comprehensive evolution of the LSR data processing architecture—one driven by business value.
The architecture's flexibility shines when cost considerations take center stage, a crucial aspect in the current global economy. While there are use cases justifying direct investment in real-time streaming, the majority of batch data processing scenarios find effective solutions in the Lakehouse. Illustrating this point with examples like Iceberg and Spark, it's apparent that you might have your own tech stack for the Lakehouse.
As your business expands and the need for fresher data grows, the Streamhouse becomes an appealing choice to improve data latency from a daily to a minute-by-minute scale. Every element, from conceptual understanding to real tech stacks, is readily available. Importantly, leveraging the same Flink technology ensures smooth upgrades to real-time streaming with minimal effort.
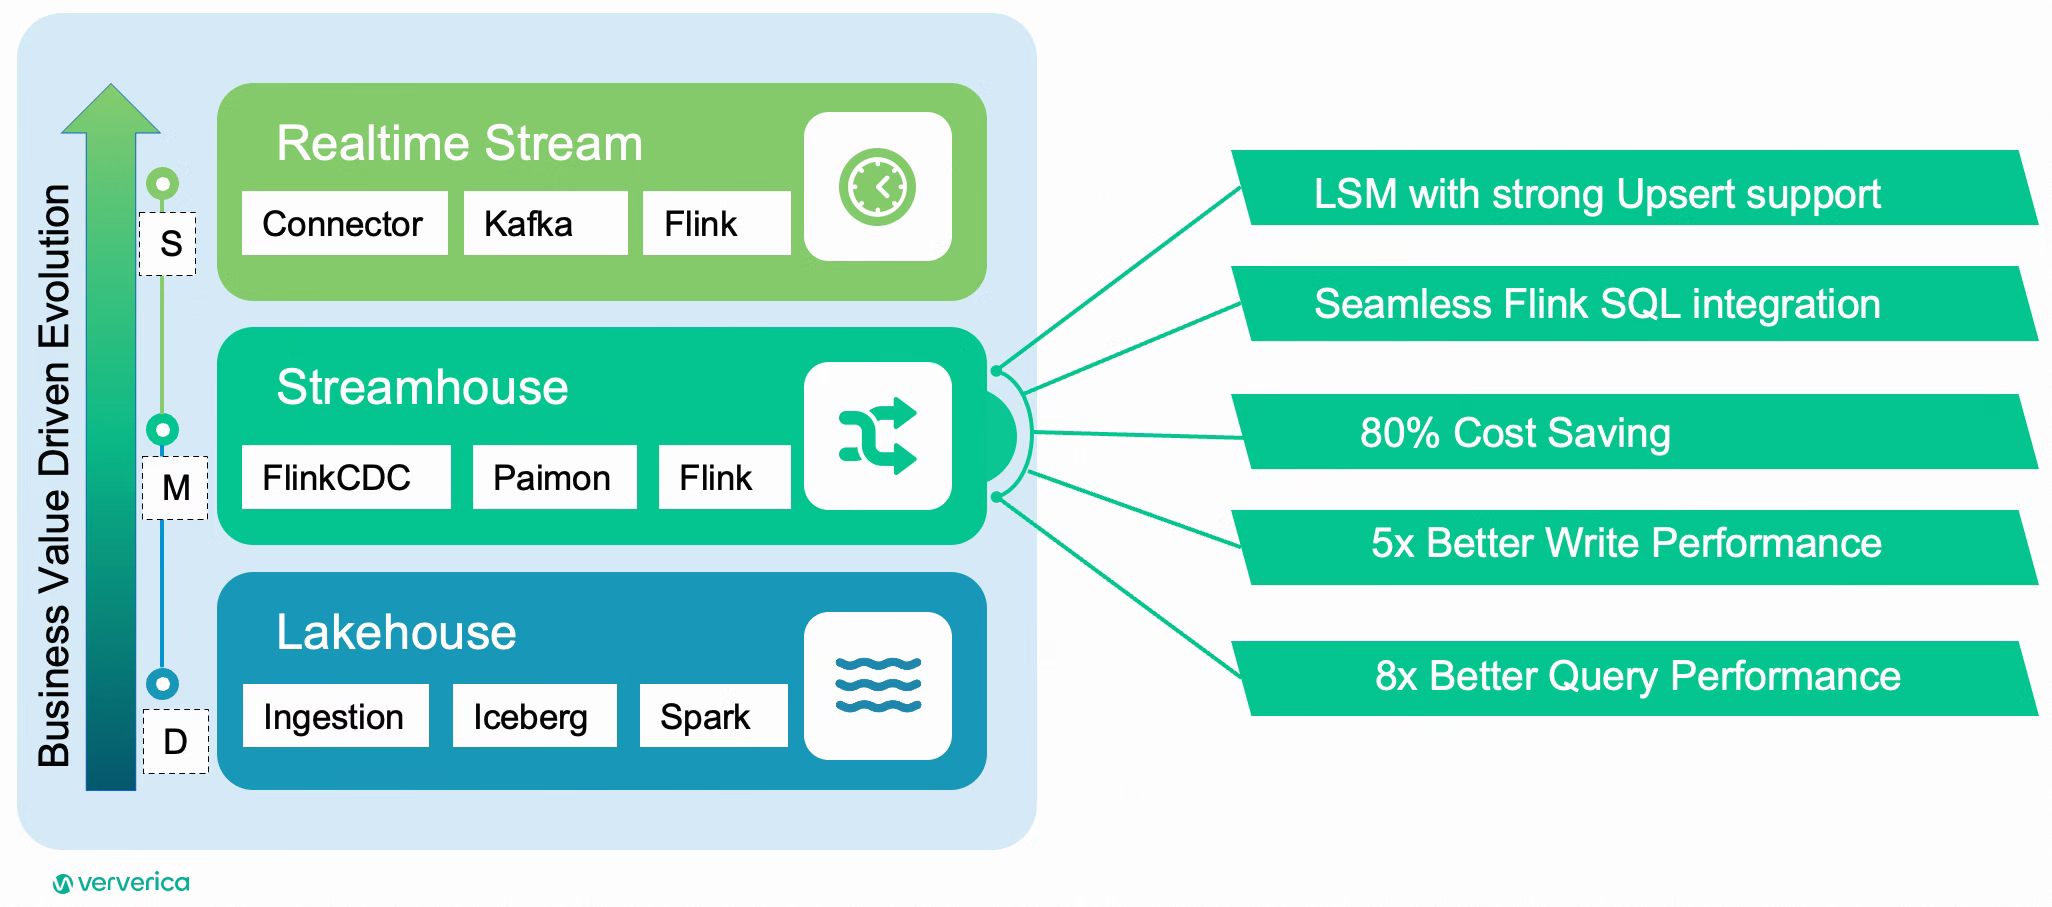
The work accomplished at Ververcia demonstrates that, with an acceptable minute data latency, Streamhouse can **significantly cut costs by 80%** compared to real-time streaming. Employing streaming preprocessing within the Streamhouse yields five times better write performance and eight times better query performance when contrasted with traditional batch Lakehouses.
### Ververica Cloud
Based on these insights, Ververica built the next-generation data platform, [Ververica Cloud](https://www.ververica.com/product/deployment/cloud), with a vision to empower customers to run their jobs anywhere, enhancing both development and operational efficiency. Ververica Cloud's architecture is open and flexible, supporting fully managed, semi-managed, and on-premises deployment modes. This architecture abstracts the diversity of cloud providers, allowing users to execute jobs directly in any cloud where their data is stored.
Ververica Runtime Assembly (VERA), the enterprise engine, is 100% Flink compatible and offers superior performance. Certain features of VERA will be contributed back to the open-source community in the future. At the platform level, Ververica Cloud introduces services like Autopilot, which leverages user data to train AI models for automatic resource scheduling, and Advisor, a repository of troubleshooting knowledge providing hints and suggestions for Flink job issues.
As a cost-effective product, Ververica Cloud offers flexible pricing options, including Pay-As-You-Go (PAYG) and Reserved Capacity (RC), tailored to diverse business requirements. Larger companies even have the option to bring their own cloud (BYOC) and integrate it with the Ververica ecosystem.
Additionally, at the conceptual level, Ververica Cloud is the first and only platform that supports both real-time streaming and Streamhouse. As customers, you will have the flexibility to start with Streamhouse and then decide to upgrade to real-time streaming or simply kick off with real-time streaming directly.
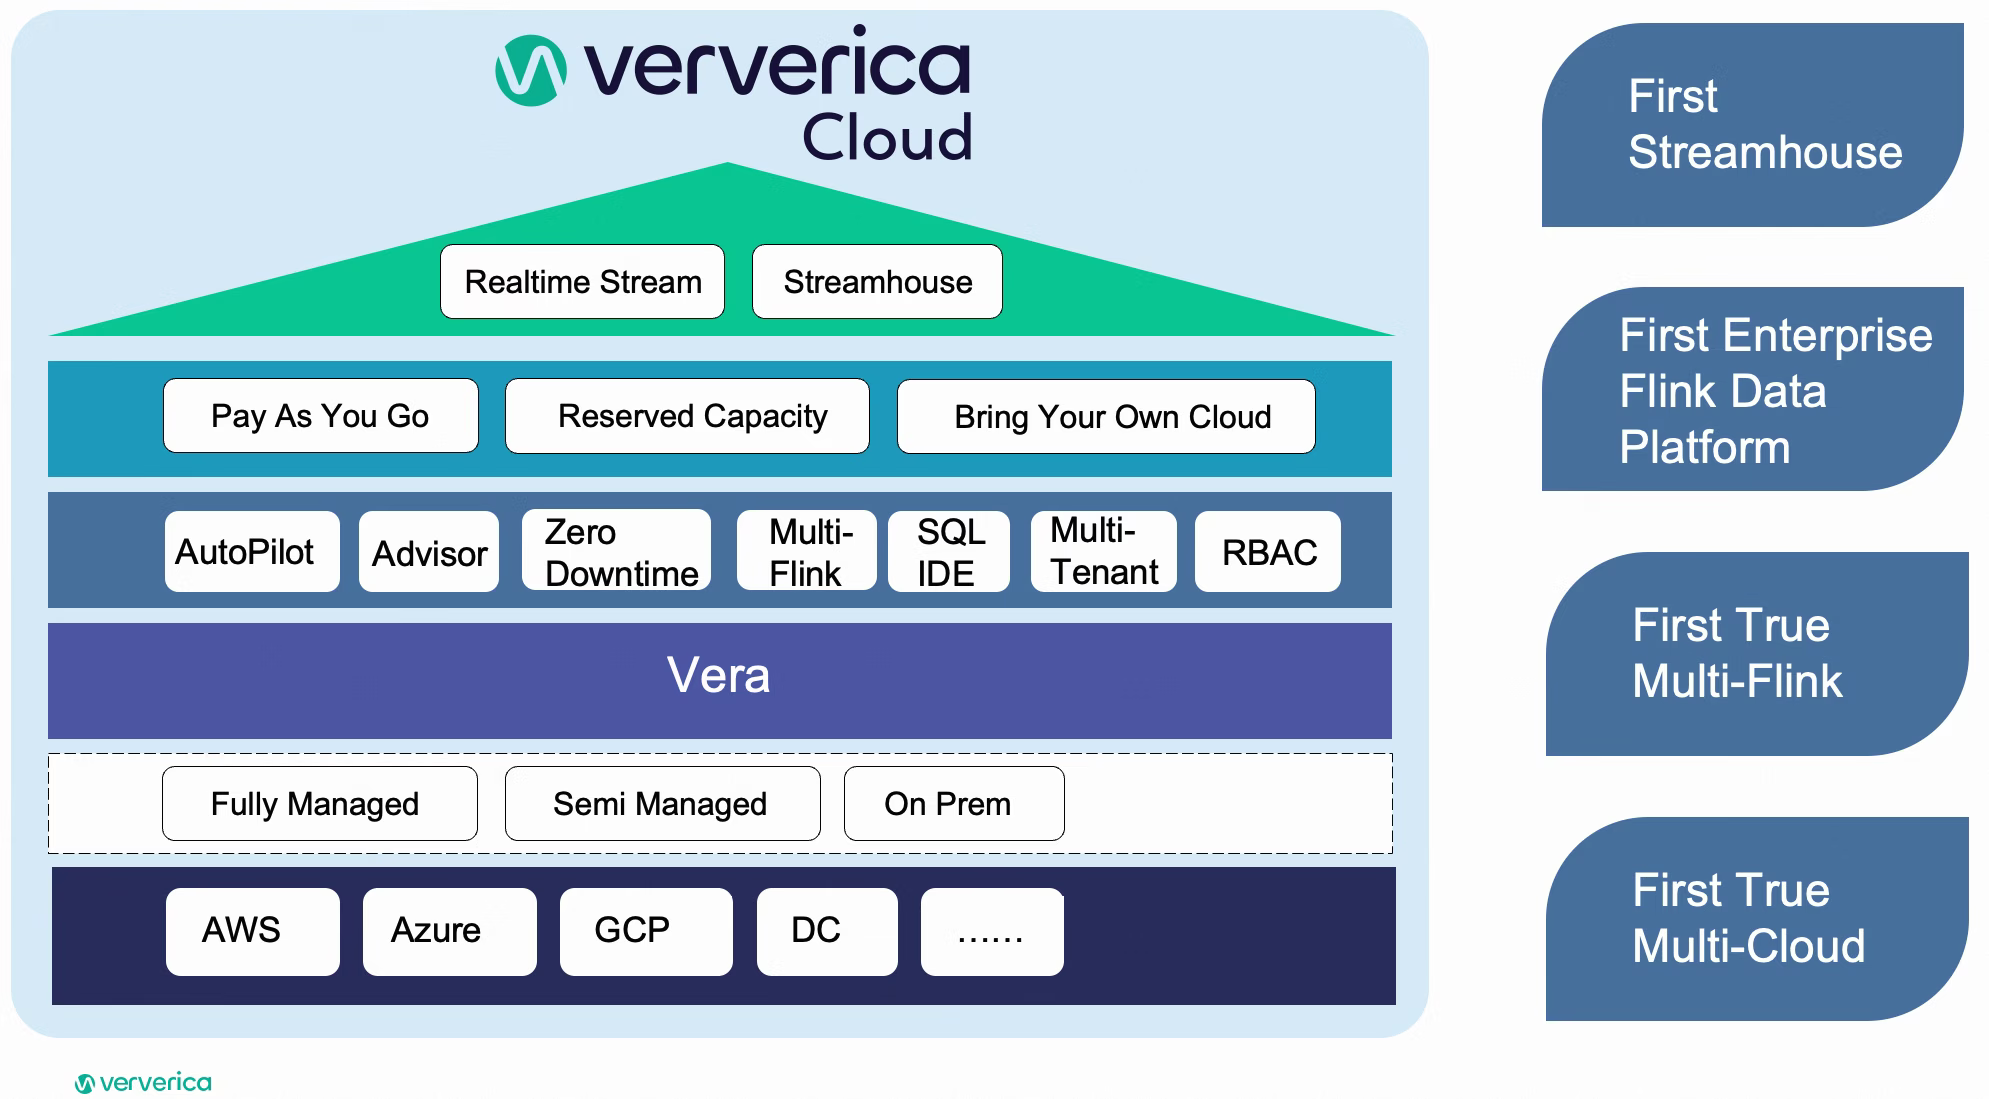
Lastly, at Ververica, we will continue our efforts on Streamhouse, both within Ververica Cloud and open-source Apache Flink, to support a broader range of business scenarios, consistently optimizing costs and improving value.
Ready to reach speeds of up to 2x faster than open source Apache Flink? Sign up for [Ververica Cloud](https://www.ververica.com/product/deployment/cloud) for free and receive $400 cloud credit.
## More Resources
- To explore the most recent updates and features, please visit [Ververica Documentation.](https://docs.ververica.com/)
- [Learn more about Ververica Cloud.](https://www.ververica.com/product/deployment/cloud)
---
---
title: "Apache Paimon: the Streaming Lakehouse"
description: "Discover Apache Paimon, the powerful streaming lakehouse that combines the flexibility of data lakes and the optimization of data warehouses. "
lastUpdated: 2026-05-06T09:28:15.000Z
source_url:
html: "https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse"
md: "https://www.ververica.com/blog/apache-paimon-the-streaming-lakehouse.md"
---
## Introduction
Since its inception, Apache Flink has undergone significant evolution. Today, it not only serves as a unified engine for both batch and streaming data processing but also paves the way toward a new era of [streaming data warehouses](https://flink.apache.org/2023/03/23/announcing-the-release-of-apache-flink-1.17/#towards-streaming-warehouses).
Apache Flink has the concept of [Dynamic Tables](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/concepts/dynamic_tables/#dynamic-tables), which bear resemblance to materialized views in databases. However, unlike materialized views, Dynamic Tables are not directly queryable. Recognizing the need to support querying of intermediate tables, progress towards streaming warehouses, and broaden the horizons for data teams, the community proposed [FLIP-188: Introduce Built-in Dynamic Table Storage](https://cwiki.apache.org/confluence/display/FLINK/FLIP-188%3A+Introduce+Built-in+Dynamic+Table+Storage).
This initiative subsequently evolved into what is now known as [Apache Paimon](https://paimon.apache.org/).
## Why Apache Paimon?
The idea is simple yet powerful; Provide Apache Flink with a storage layer that leverages a table format, so intermediate data in dynamic tables is directly accessible. This storage design, known as the Lakehouse paradigm, is not new and is already established in the industry. It combines the flexibility and scalability of data lakes on cheap storage like S3 with the optimization and structured queries data warehouses offer. Technologies like [Apache Iceberg](https://iceberg.apache.org/), [Delta Lake](https://delta.io/), and [Apache Hudi](https://hudi.apache.org/) already provide that.
**So why create a new project from scratch?** The vision was clear and a solution was needed that would be a good fit for high-speed data ingestion, fast analytical queries, strong upsert support, and a strong integration with Flink and Flink CDC. Flink needed to be a first-class citizen to unlock its full potential. The community evaluated solutions already established in the industry, like Apache Iceberg and Apache Hudi, but there were a few limitations in order for them to be used as the streaming storage layer for Flink. Going through the details is beyond the scope of this blog post. Still, with these challenges in mind, **Flink Table Store** was born under the Apache Flink project umbrella and later became its own project, entering the Apache Incubator as Apache Paimon.
If you look into the official documentation, you will see the following about Paimon.
A streaming data lake platform that supports:
- high-speed data ingestion
- change data tracking
- and efficient real-time analytics
Paimon offers the following core capabilities:
- **Unified Batch & Streaming:** Paimon supports batch read and writes, as well as streaming write changes and streaming read table changelogs.
- **Data Lake:** As a data lake storage, Paimon has the following advantages: low cost, high reliability, and scalable metadata.
- **Merge Engines:** Paimon supports rich Merge Engines. By default, the last entry of the primary key is reserved. You can also use the “partial-update” or “aggregation” engines.
- **Changelog producer:** Paimon supports rich Changelog producers, such as “lookup” and “full-compaction”. The correct changelog can simplify the construction of a streaming pipeline.
- **Append Only Tables:** Paimon supports Append Only tables, automatically compacts small files, and provides orderly stream reading. You can use this to replace message queues.
All these properties enable the Lakehouse to evolve with a streaming-first design, resulting in the **Streamhouse**.
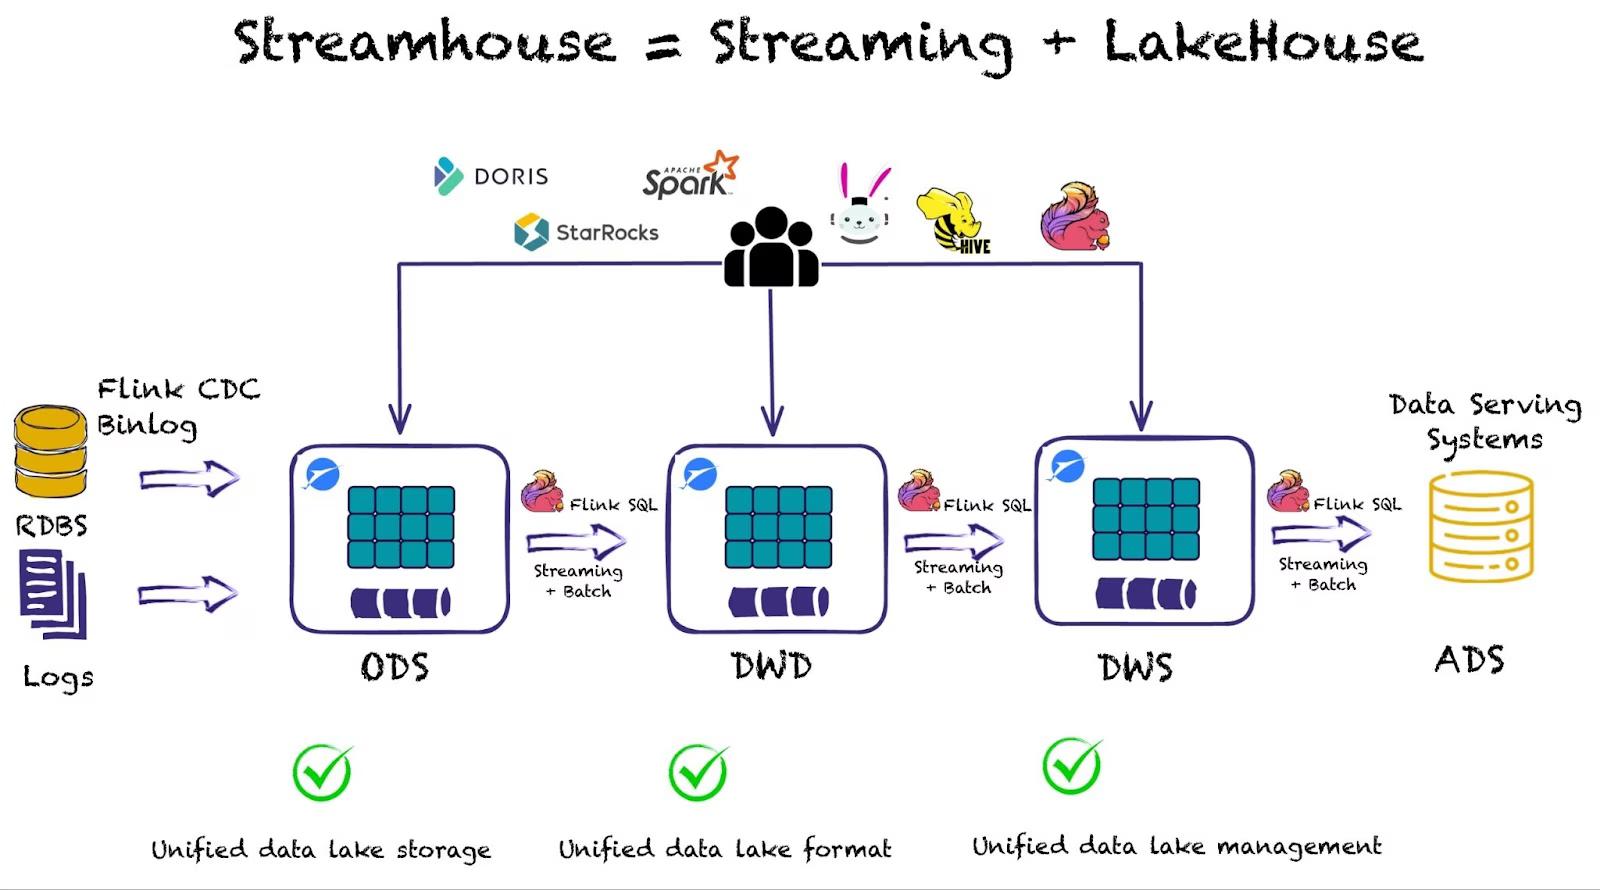
The Streamhouse architecture combines Apache Flink for Stream Processing and Apache Paimon as the streaming storage layer.
The core idea of the Streamhouse is streaming ETL and data ingestion from CDC or log data into cheap storage, like s3, in an easy and simple way using a one-line statement.
When data gets into the data lake users can create different jobs to create different business layers - i.e., ODS, DWD, DWS, and ADS - that take care of updates while data flows.
At the same time, you can add any query engine you want on top as the data is directly accessible - OLAP systems like Apache Doris and StarRocks or query engines like Flink SQL, Spark, Trino, or Hive - to run batch or incremental queries on snapshots of the Dynamic Tables.
## Apache Paimon Features
Let’s take a closer look at some basic concepts to help us better understand what Apache Paimon offers.
### Paimon Key Concepts
#### Snapshots
A snapshot captures the state of a table at some point in time. Users can access the latest data of a table through the latest snapshot and leverage time travel in order to access the previous state of a table through an earlier snapshot.
#### Partitions
Paimon adopts the same partitioning concept as Apache Hive to separate data.
Partitioning is an optional way of dividing a table into related parts based on the values of particular columns like date, city, and department. Each table can have one or more partition keys to identify a particular partition.
By partitioning, users can efficiently operate on a slice of records in the table.
#### Bucket
Unpartitioned tables, or partitions in partitioned tables, are subdivided into buckets to provide extra structure to the data for more efficient querying.
A bucket is the smallest storage unit for reads and writes, so the number of buckets sets the maximum processing parallelism.
#### Consistency Guarantees
Paimon writers use the two-phase commit protocol to commit a batch of records to the table atomically. Each commit produces, at most, two [snapshots](https://paimon.apache.org/docs/master/concepts/basic-concepts/#snapshot) at commit time.
For any two writers modifying a table at the same time, as long as they do not modify the same bucket, their commits can occur in parallel. If they modify the same bucket, only snapshot isolation is guaranteed. The final table state may be a mix of the two commits, but no changes are lost.
Paimon uses snapshots to provide access to different versions of any table, and groups data files into partitions and buckets, with consistency guarantees.
It leverages an [LSM](https://en.wikipedia.org/wiki/Log-structured_merge-tree) (Log-Structured Merge Tree) data structure to achieve performance for streaming data. Each bucket basically contains an LSM tree and its changelog files.
The following figure shows the file layout of Paimon and how everything fits together.
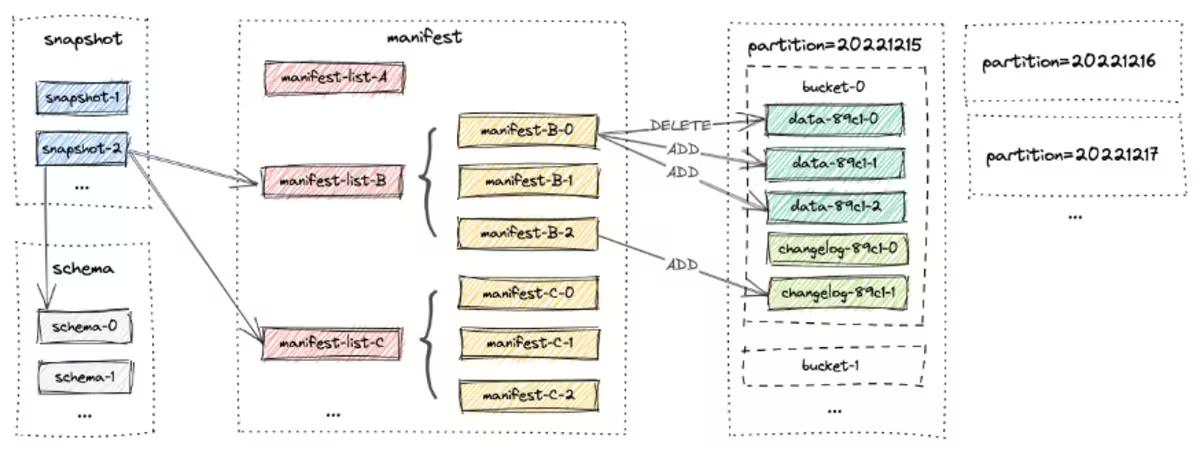
### Paimon Table Types
#### Primary Key Tables
This is basically a changelog table and is the default. Users can **insert**, **update,** or **delete** records in the table.
Primary keys consist of a set of columns that contain unique values for each record. Paimon enforces data ordering by sorting the primary key within each bucket, allowing users to achieve high performance by applying filtering conditions on the primary key.
Since this table is used to store changelog streams, Paimon offers a variety of **merge engines** when two or more records with the same primary key arrive.
[Changelog Producers](https://paimon.apache.org/docs/master/concepts/primary-key-table/#changelog-producers), also play an important role here, but we will discuss them in detail in a future blog post.
#### Append-Only Tables
An append-only table is a table without a primary key. This table allows only **insert** operations. **Delete** or **update** operations are not supported. This type of table is suitable for use cases that do not require updates, such as log data synchronization.
#### External Log Systems
Along with the aforementioned table types, Paimon also supports external log systems. When using external log systems and writing the data on the data lake, the data will also be written to a system like Kafka. If using an external log system, table files and the log system record all writes, but the changes produced by the streaming queries will come from the log system instead of the table files.
## Data Lake Ingestion
With some core concepts in place, let’s switch gears and see the core functionality of Apache Paimon.
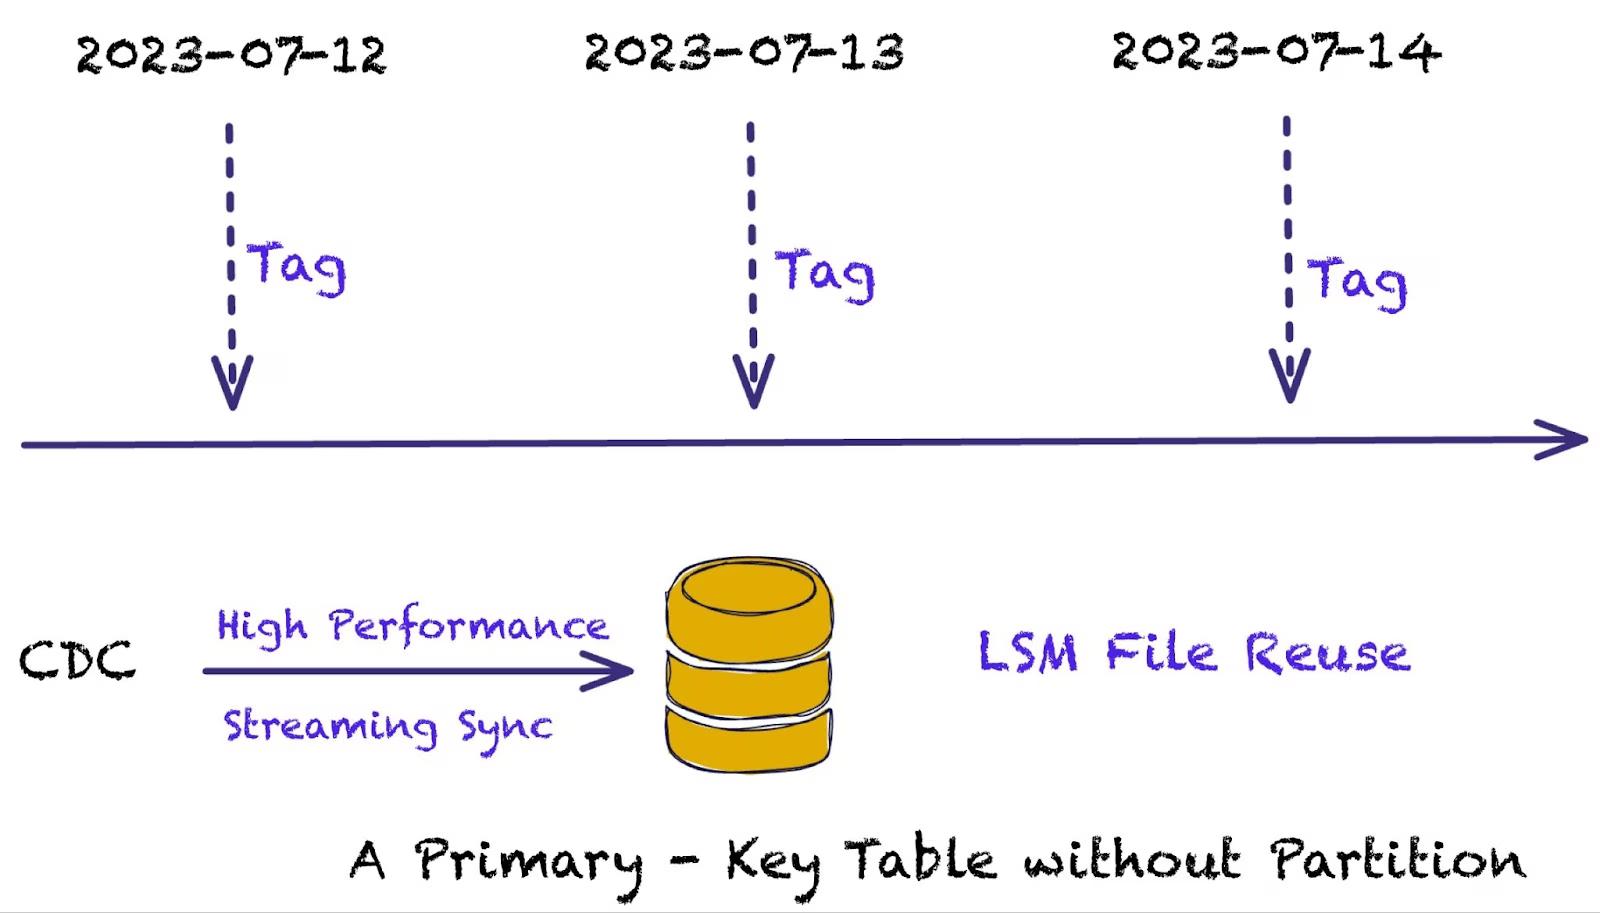
As already mentioned, Paimon writes data in the data lake by leveraging partitions and buckets, where each bucket contains an LSM tree. When data is written, it allows the creation of tags (which we will explain in more detail shortly) and the LSM layered structure allows for file reuse to optimize performance and reduce the creation of many files. Compared to other architectures, it doesn’t require defining a partitioned table, it only requires a primary key.
The tables can be streamed in real-time with low latency and allow real-time queries, batch queries, and incremental queries. There is lots of flexibility in parameter tuning for data lake ingestion, allowing users to balance between write performance, query performance, and storage amplification.
For example, when users know the job is under pressure, they can choose Paimon's [dynamic bucket mode](https://paimon.apache.org/docs/master/concepts/primary-key-table/#dynamic-bucket) or set a suitable bucket size. If the backpressure continues, they can adjust the Checkpoint Interval, or tune the Paimon compaction parameters so doesn’t block, and ensure better write performance.
Overall, Paimon is highly configurable, allowing users to make tradeoffs according to streaming reads, batch reads, and update scenarios.
### Tags and Time Travel
Apache Paimon leverages the concept of Tags in order to allow access to different offline views. An offline view is basically a snapshot of the table at some point in time that allows historical data queries. Tags allow users to time travel to previous versions of the table in time.
Tags can be created and expired automatically and they are based on snapshots. The tag will maintain the manifests and data files of the snapshot.
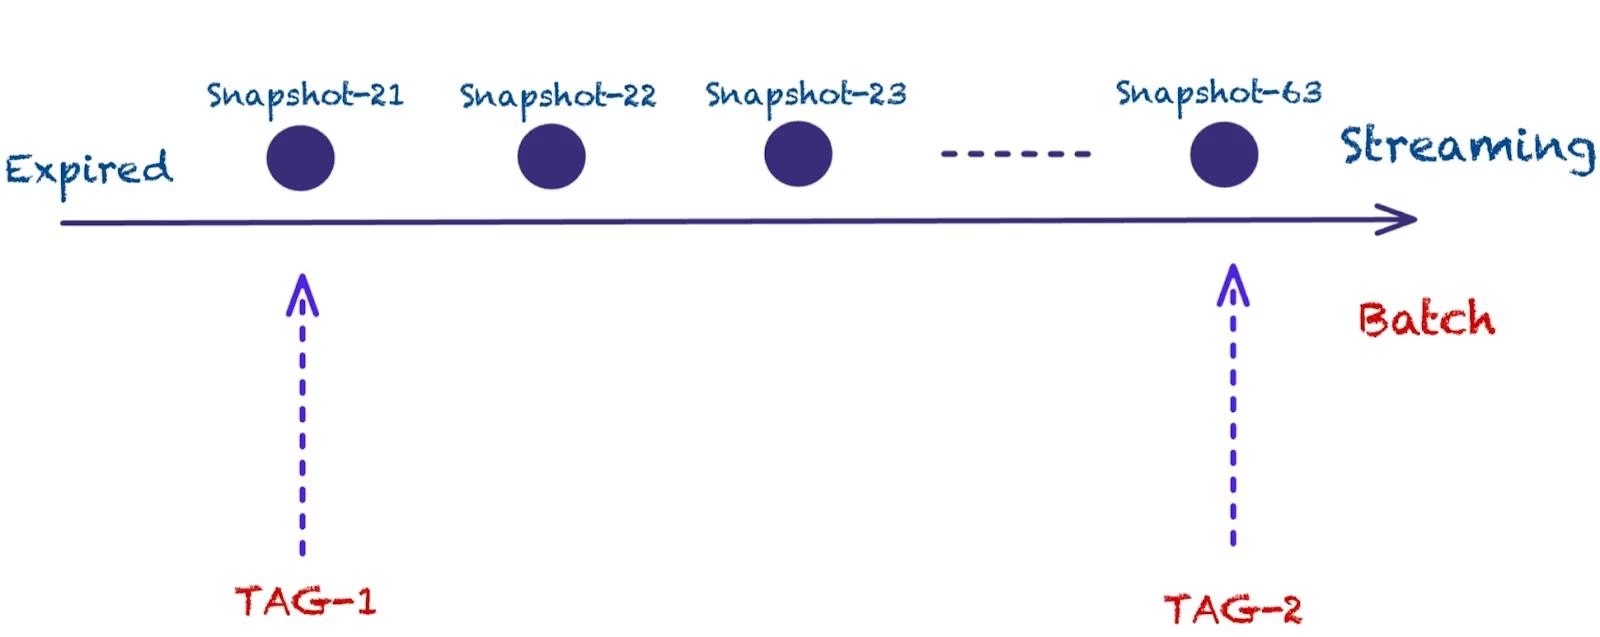
The following code snippet demonstrates that when creating a table, users can specify automatically created tags, for example, per day.
```sql
CREATE TABLE MyTable (
id INT PRIMARY KEY NOT ENFORCED,
...
) WITH (
'tag.automatic-creation' = 'processing-time',
'tag.creation-period' = 'daily',
'tag.creation-delay' = '10 m',
'tag.num-retained-max' = '90'
);
INSERT INTO MyTable SELECT * FROM kafkaTable;
-- Read latest snapshot
SELECT * FROM MyTable;
-- Read Tag snapshot
SELECT * FROM MyTable VERSION AS OF '2023-07-26';
-- Read Incremental data between Tags
SELECT * FROM MyTable paimon_incremental_query ('2023-07-25', '2023-07-26');
```
When these tags are created on snapshots, they remain until the expiration policy takes effect (if specified).
While present, users have the ability to run queries on streaming data, on historic data by specifying previous snapshots, and also incremental changes between different snapshots.
### Change Data Capture
One of the most essential aspects of Apache Paimon is data lake ingestion through Change Data Capture. Paimon integrates with [Flink CDC](https://github.com/ververica/flink-cdc-connectors), which is an open-source CDC technology that supports a large variety of data sources.
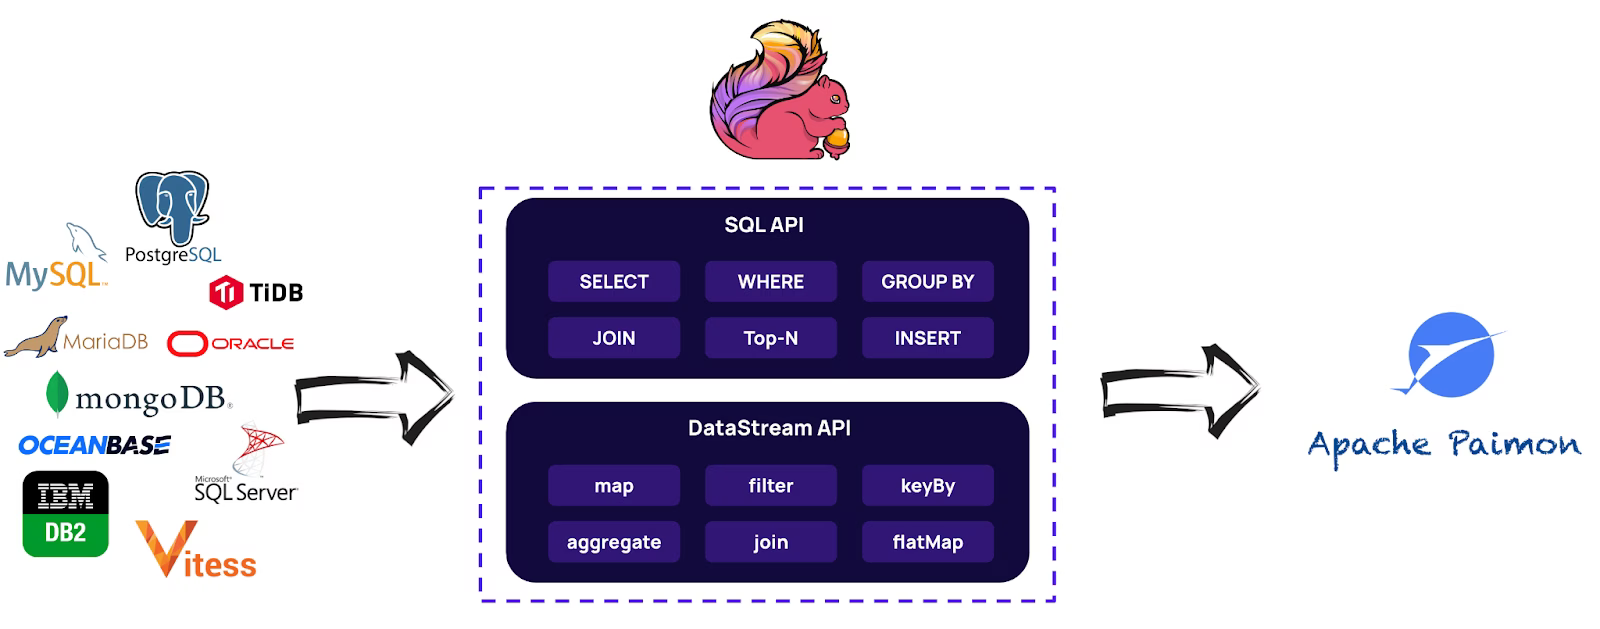
When dealing with change data capture technologies, it’s hard to read large tables with historical data and start reading the incremental data afterward.
At the same time, we need a way to read large tables incrementally and, when the database contains hundreds or thousands of tables, minimize the open connections to the database and not put too much pressure on the system.
Flink CDC can achieve this by leveraging an **Incremental Snapshot Algorithm** that is unique to the project.
The Incremental Snapshot Algorithm sits at the heart of Flink CDC.
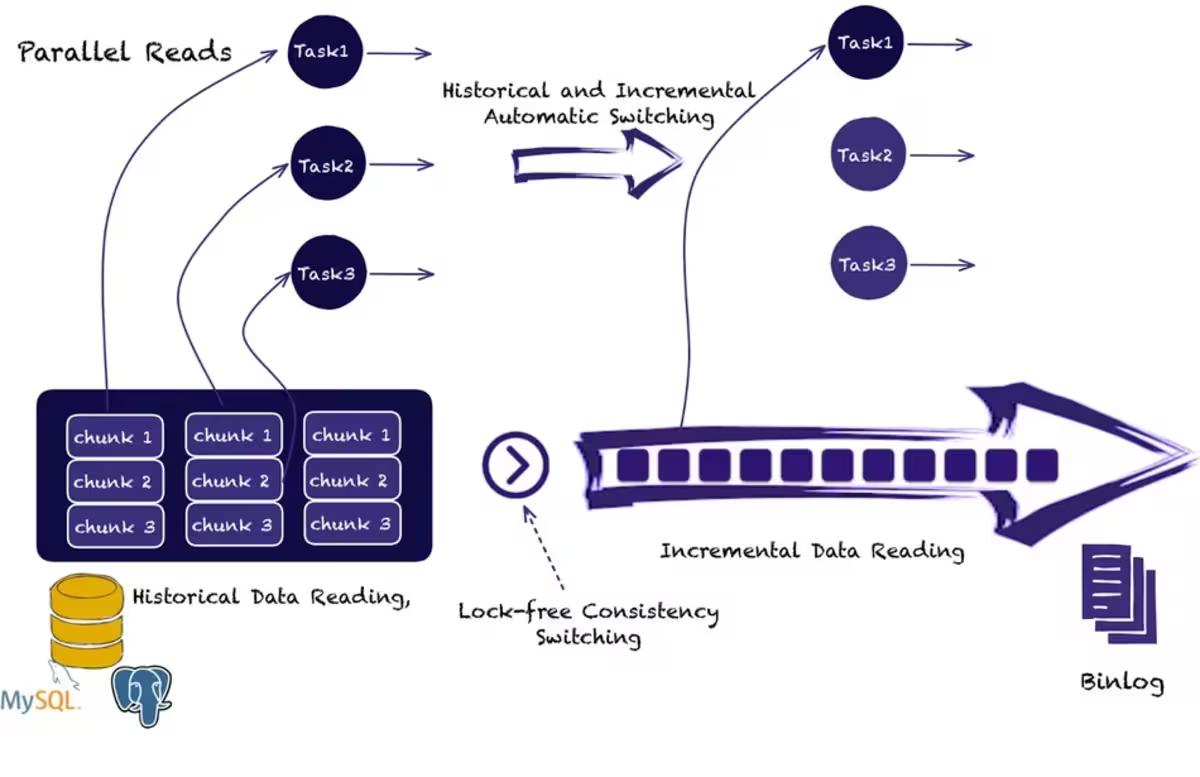
It reads the historical data, and then, automatically without locking the database, continues to read the incremental changes from the Binlog. As depicted in the illustration, the Incremental Snapshot Algorithm allows splitting large tables into smaller chunks and read them in parallel. When the automatic switching occurs, only one task is required in order to read the incremental changes.
Currently, Paimon is in the 0.5 release and supports CDC with MySQL and MongoDB, with more databases (like Postgres) to be supported soon.
Kafka CDC is also supported and if the users need to integrate with other CDC source systems they can leverage the **RichCdcRecord.**
### LSM and Hierarchical File Reuse
Next, we will take a look at the multiplexing of Paimon LSM file storage.
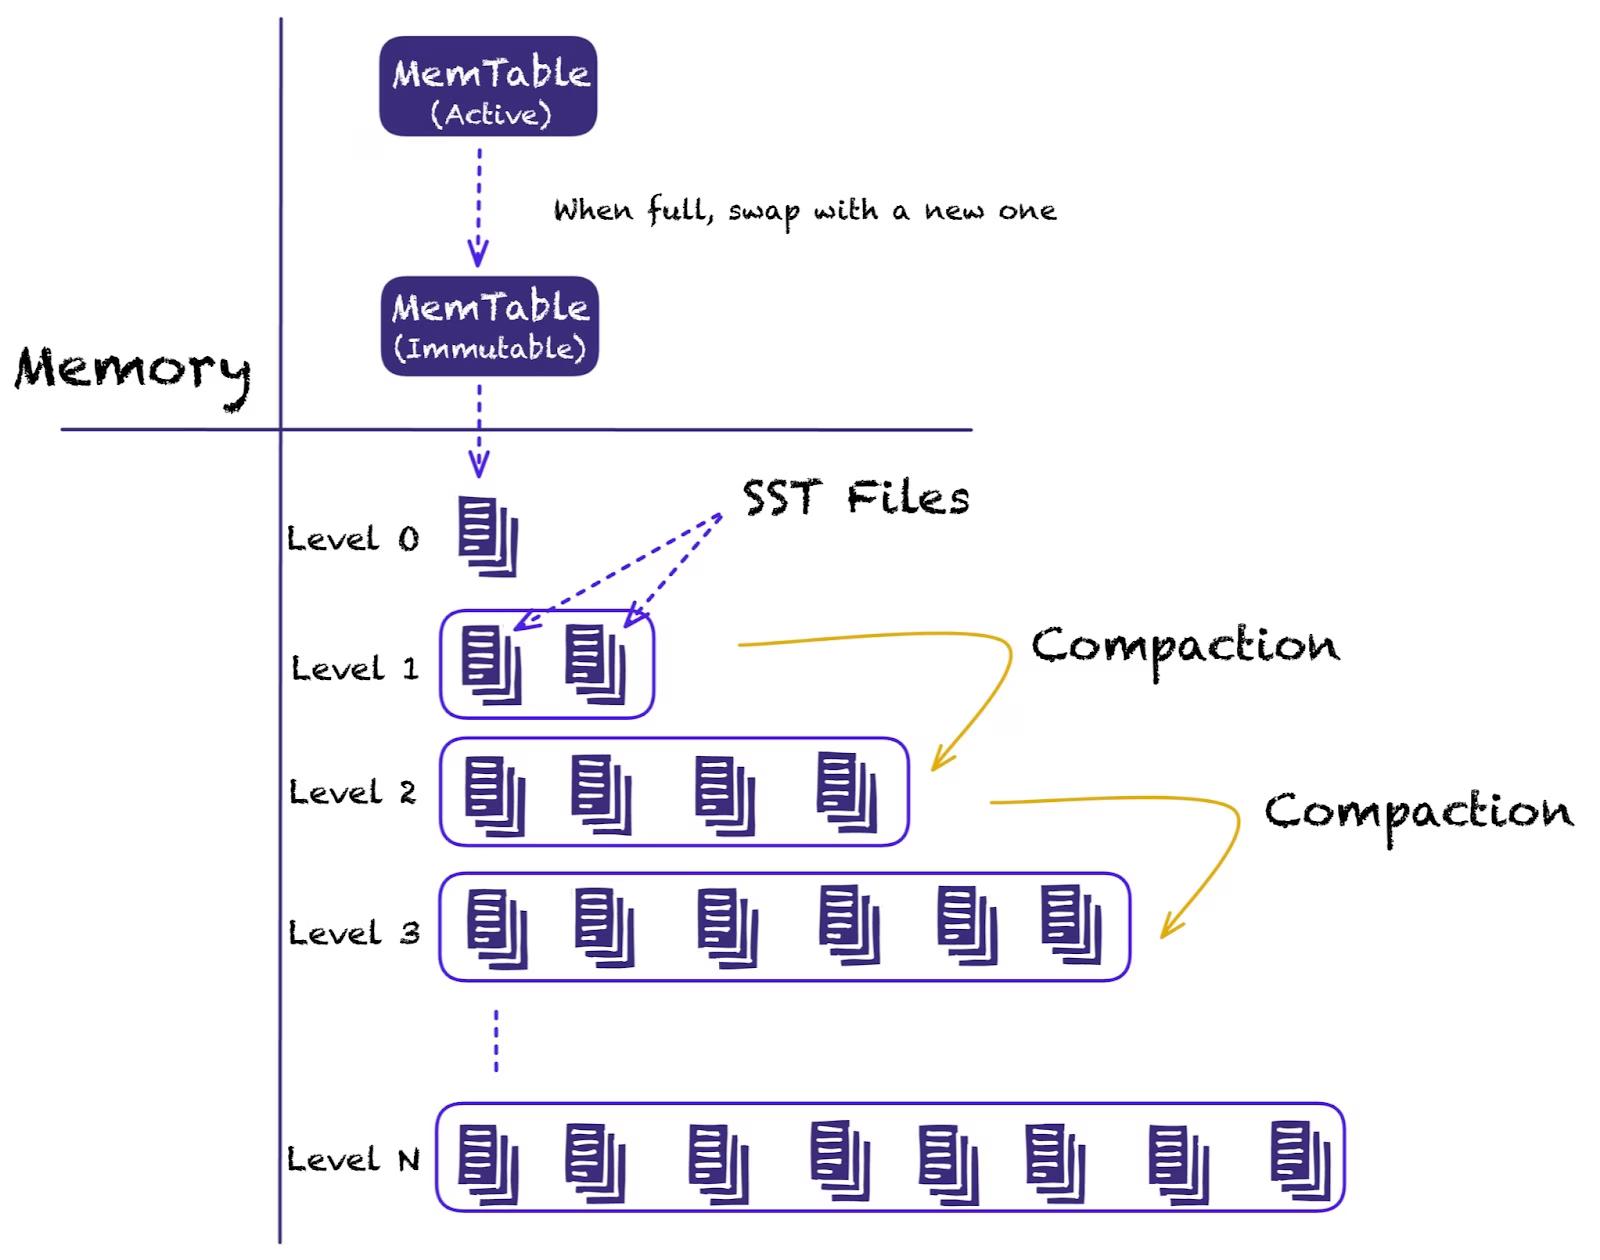
Paimon leverages LSM (Log Structured Merge trees) for file storage and uses leveled compaction similar to RocksDB. One feature of the LSM data structure is that when incremental data arrives, it does not necessarily need to be merged into the lower levels.
This allows lower-level files to be reused between two tags as they don’t always get affected by compaction.
## Stream Processing Use Cases
### Streaming Joins
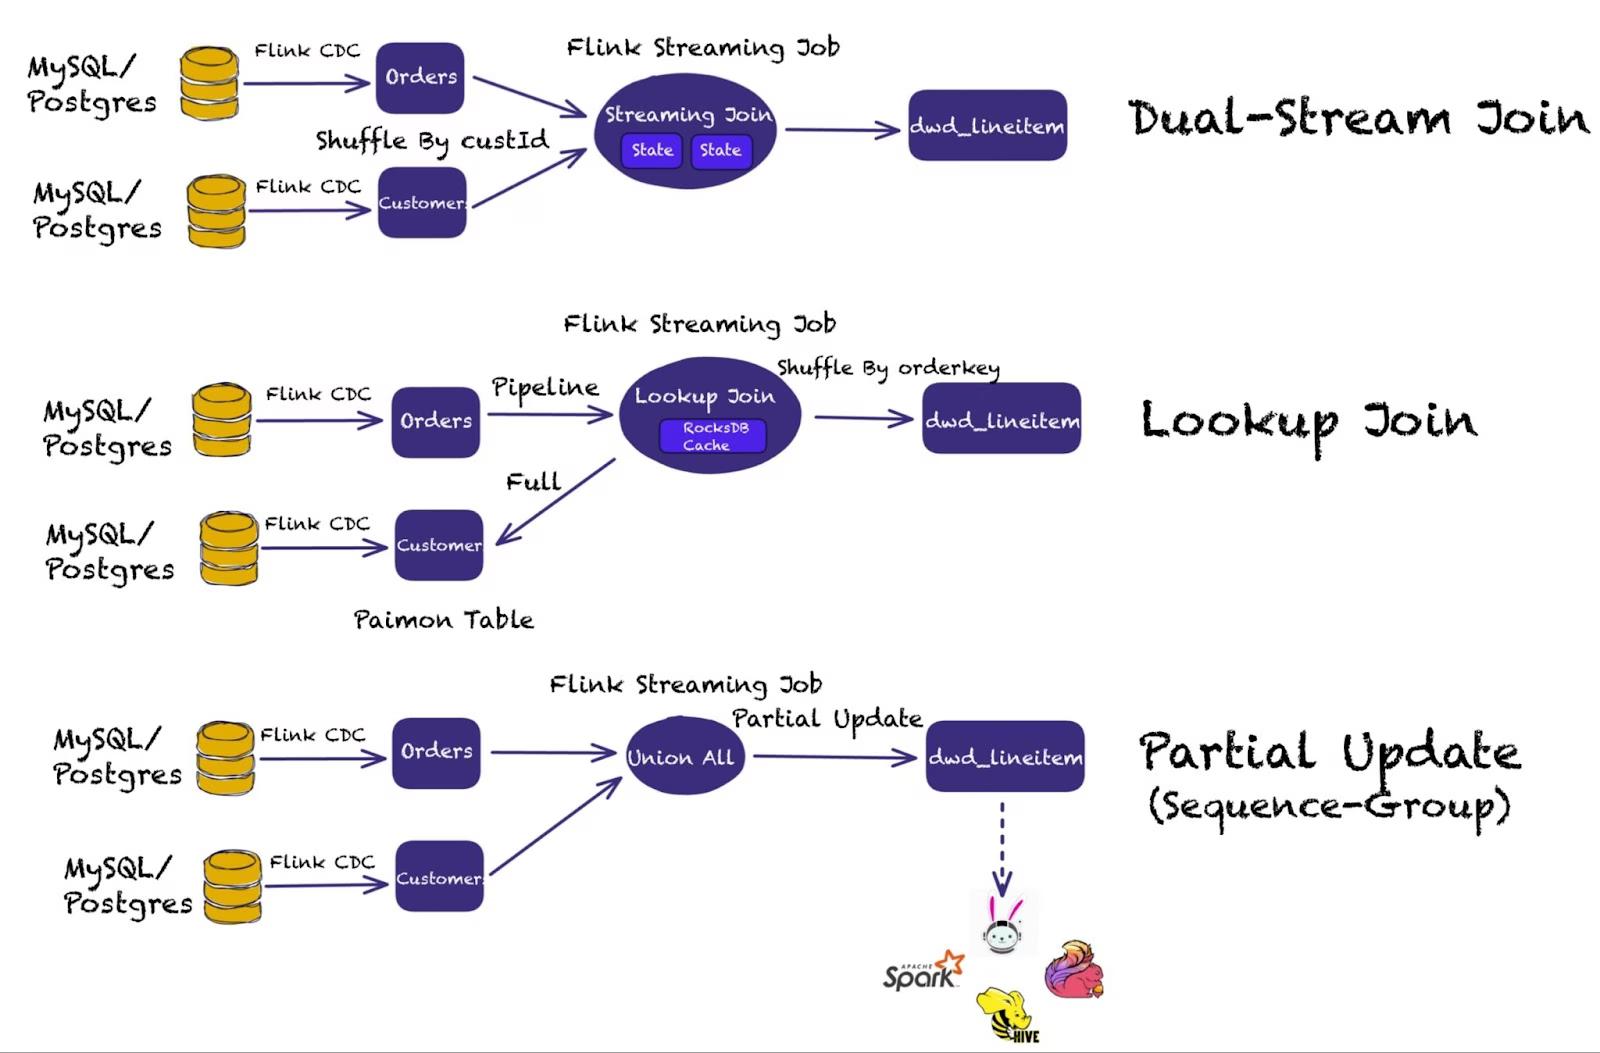
Table data widening (for use cases like data enrichment) is quite common in streaming ETL. Paimon supports **Dual-Stream Joins** (or regular joins), **Lookup Joins,** and **Partial Update** (leveraging Sequence-Groups).
**Dual-stream joins** require both sides of the streaming join query to be kept in memory. As the state grows too large, the cost of running joins increases as well. Paimon allows querying data directly from the data lake storage.
**Lookup Join** allows performing the lookup of Paimon tables through the Flink Lookup Join. One thing to keep in mind with the Lookup Join is that when the dimension table is updated, changes are not reflected downstream.
**Partial Update** is a method for updating the same component. It uses Sequence-Groups, which enables each field to use a different update method, and it also supports various merge engines. It provides high throughput and near-real-time level latency.
For example, suppose Paimon receives three records:
- <1, 23.0, 10, NULL>
- <1, NULL, NULL, 'This is a book'>
- <1, 25.2, NULL, NULL>
Assuming that the first column is the primary key, the final result would be:
<1, 25.2, 10, 'This is a book'>
In addition to the above, Paimon does a lot of work to provide users with the ability to operate on foreign keys in the future, which should help address even more use cases efficiently.
### Paimon as a Message Queue
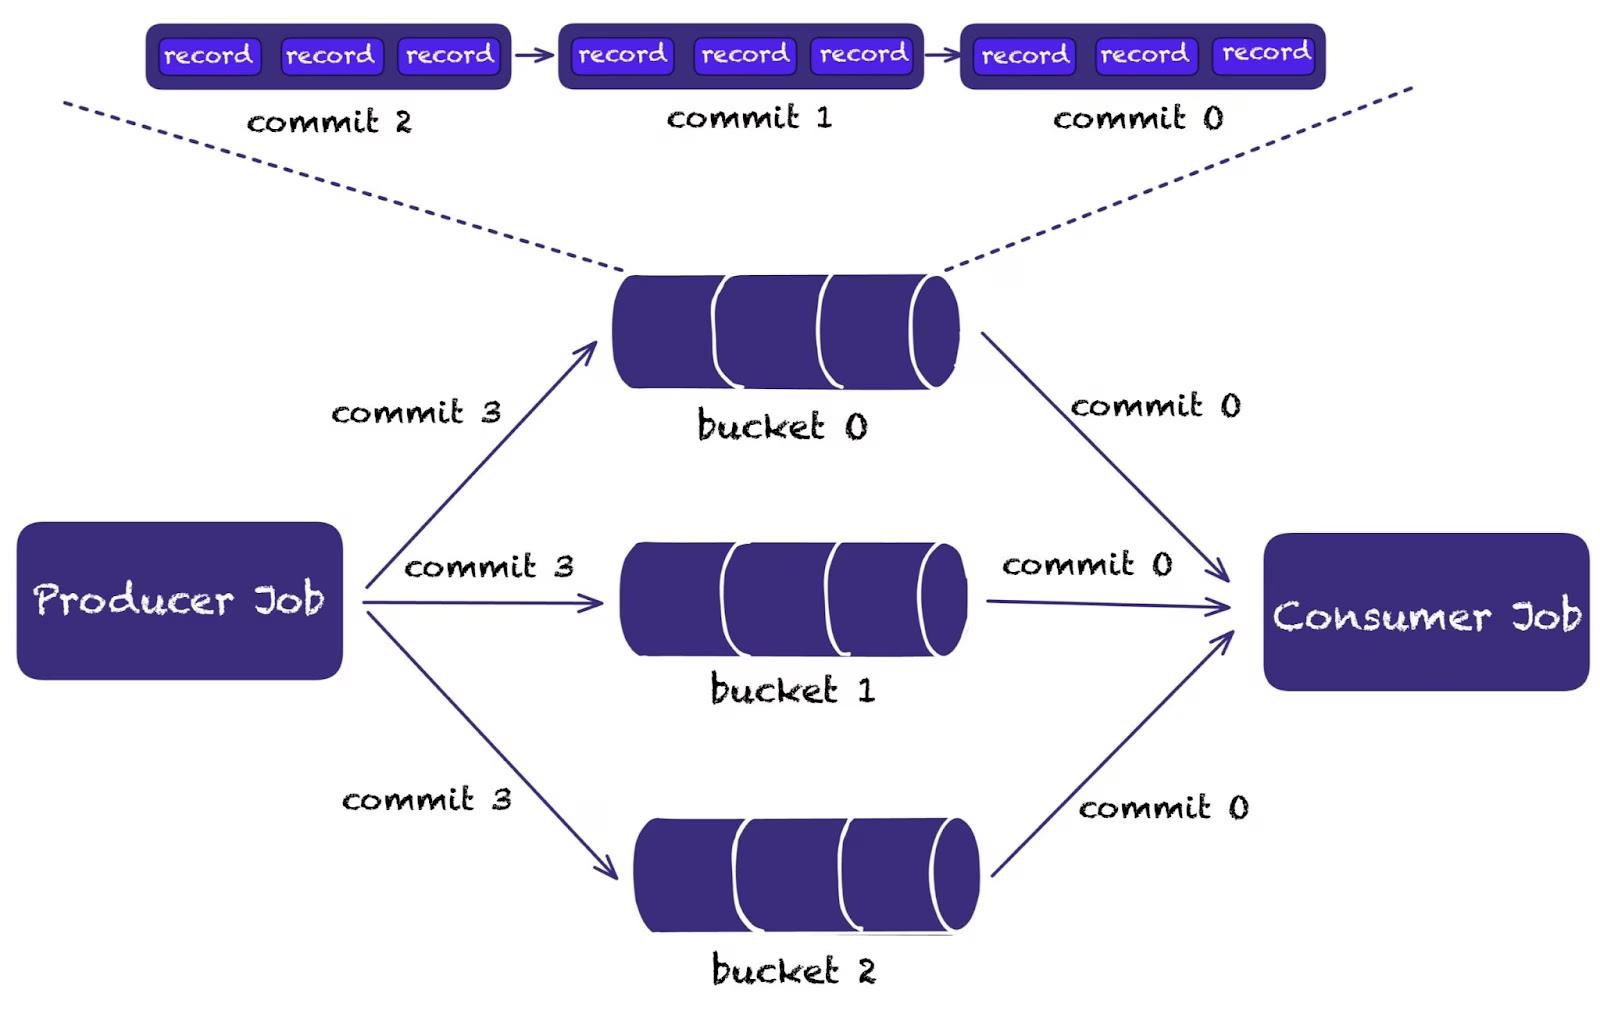
Since Paimon is oriented towards real-time processing, some people will inevitably compare Paimon and Kafka architectures, as Paimon has done a lot of work here.
For example, it supports Append-only tables, which allows creating a table **without** a primary key, only specifying the bucket number.
Buckets are similar to partitions in Kafka. They provide strict order preservation, which is the same as Kafka's message ordering, but they also support Watermarks and Watermark alignment. At the same time, there is also support for Consumer IDs.
During the writing process, small files can be automatically merged.
Therefore, it can be seen from the illustration above that its overall architecture, allows users to replace Kafka with Paimon for certain use cases.
Kafka's real ability is to provide latency on the order of seconds. When the business use cases don’t require second-level latency, you can consider using Paimon to achieve message-queue functionality.
Apache Paimon typically operates on minute-level latency, as writing to the data lake depends on the checkpoint interval. The recommended checkpoint interval is typically one minute in order to avoid generating many small files that affect the read query performance.
If you don’t care about read performance you can consider setting lower-level checkpoint intervals, by also leveraging newer Flink versions that support new features like the [changelog state backend](https://www.ververica.com/blog/generic-log-based-incremental-checkpoint).
## Summary
Apache Flink evolved to be more than compute, and Apache Paimon was born to act as the storage layer. Even though in it’s early days the project has seen lots of adoption and is already used in production in large-scale companies.
The community embraces the “**Streamhouse”** and you can keep an eye on the Paimon [roadmap](https://paimon.apache.org/docs/master/project/roadmap/) and [PIPs](https://cwiki.apache.org/confluence/display/PAIMON/Paimon+Improvement+Proposals).
## References
[Apache Paimon](https://paimon.apache.org/)
[Apache Paimon Github](https://github.com/apache/incubator-paimon)
[Paimon Improvement Proposals](https://cwiki.apache.org/confluence/display/PAIMON/Paimon+Improvement+Proposals)
[Generic Log-based Incremental Checkpoint --- Performance Evaluation & Analytics](https://www.ververica.com/blog/generic-log-based-incremental-checkpoint)
---
---
title: "Bootstrap Data Pipeline via Flink HybridSource"
description: "Learn how to easily bootstrap a data pipeline using Apache Flink's HybridSource. This blog post provides a step-by-step guide and code examples."
lastUpdated: 2026-05-11T12:56:40.000Z
source_url:
html: "https://www.ververica.com/blog/bootstrap-data-pipeline-via-flink-hybridsource"
md: "https://www.ververica.com/blog/bootstrap-data-pipeline-via-flink-hybridsource.md"
---
A common requirement in the area of data engineering is to first process existing historical data before processing continuously live data. Processing existing data first is also referred to as bootstrapping the system.
How to easily achieve this with Apache Flink? In this blog-post we will look at Flink's [HybridSource](https://nightlies.apache.org/flink/flink-docs-master/docs/connectors/datastream/hybridsource/) which is specifically designed for such a task. If you want to clone the [repository](https://github.com/ververica/lab-flink-hybridsource) with the code from this blog post, use
```bash
git clone https://github.com/ververica/lab-flink-hybridsource.git
```
## Dataflow
As a demo example, we will implement the following data pipeline as a Flink Job.
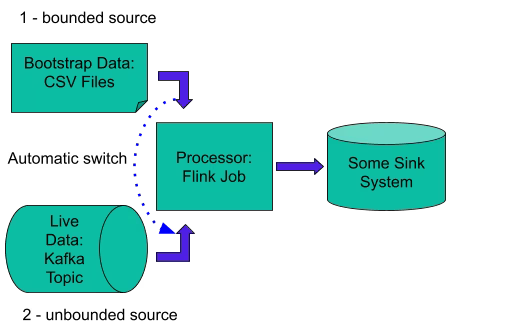
In order to process data sources sequentially and switch from one to another as per the job graph topology, we will first add a FileSource with CSV data files and then a KafkaSource which is going to provide an unbounded source of data.
## Data Preparation
In order to prepare data files in CSV format, we will write a special one-time Flink Job.
For all code examples we will use Scala and its awesome [scala-cli](https://scala-cli.virtuslab.org/install) tool. Please install the latest version of it in your environment, if you want to reproduce code examples yourself.
Create file **gen-data.sc** with the following code:
```scala
//> using dep "org.flinkextended::flink-scala-api:1.17.1_1.0.0"
//> using dep "org.apache.flink:flink-clients:1.17.1"
//> using dep "org.apache.flink:flink-csv:1.17.1"
//> using dep "org.apache.flink:flink-connector-files:1.17.1"
//> using dep "org.apache.flink:flink-table-runtime:1.17.1"
//> using dep "org.apache.flink:flink-table-planner-loader:1.17.1"
import org.apache.flink.table.api._
import org.apache.flink.connector.datagen.table.DataGenConnectorOptions
import org.apache.flink.api._
import org.apache.flink.api.serializers._
import _root_.java.lang.{Long => JLong}
val env = StreamExecutionEnvironment.getExecutionEnvironment
val settings = EnvironmentSettings.newInstance.inStreamingMode.build
val table = TableEnvironment.create(settings)
```
Then append this block of code which represents record schema:
```scala
val schema = Schema.newBuilder
.column("id", DataTypes.INT())
.column("bid_price", DataTypes.DOUBLE())
.column("order_time", DataTypes.TIMESTAMP(2))
.build
```
As you can see, our record contains three columns: id, bid_price and order_time.
Then append one more block of code which is using Table API and [datagen](https://nightlies.apache.org/flink/flink-docs-master/docs/connectors/table/datagen/) connector to store data in CSV format into a specific file system path:
```scala
table.createTemporaryTable(
"SourceTable",
TableDescriptor
.forConnector("datagen")
.schema(schema)
.option(DataGenConnectorOptions.NUMBER_OF_ROWS, JLong(1000))
.option("fields.id.kind", "sequence")
.option("fields.id.start", "1")
.option("fields.id.end", "10000")
.build
)
val currentDirectory = _root_.java.io.File(".").getCanonicalPath
table.createTemporaryTable(
"SinkTable",
TableDescriptor
.forConnector("filesystem")
.schema(schema)
.option("format", "csv")
.option("sink.rolling-policy.file-size", "124 kb")
.option("path", s"file://$currentDirectory/sink-table")
.build
)
table.executeSql("insert into SinkTable select * from SourceTable").print
```
Assuming that gen-data.sc file is in your current shell directory, run **scala-cli** via the following command:
_scala-cli gen-data.sc_
Once this script is executed, we get the following set of CSV files in the current shell sink-table directory:
Below are data records in one of the CSV files:
Each file is part of the generated data set. The number of files can be controlled by changing the values of **sink.rolling-policy.file-size**and **DataGenConnectorOptions.NUMBER_OF_ROWS** in the **gen-data.sc** code.
Now let’s generate similar data for the second source, which is the Kafka topic. For that you would need to have a Kafka cluster which you can use for further steps in this blog post. The Kafka version used to test all code examples in this blog-post is 2.7. One Kafka broker will be enough for testing.
In the same Scala file that we used for CSV data generation, replace SinkTable with the following:
```scala
val brokers = ":9092"
table.createTemporaryTable(
"SinkTable",
TableDescriptor
.forConnector("kafka")
.schema(schema)
.option("properties.bootstrap.servers", brokers)
.option("topic", "bids")
.option("format", "csv")
.option("value.format", "csv")
.build
```
Enter your Kafka broker hostnames as a comma-separated list. The hostname(s) must be accessible from the machine where the Scala script is executed. After running the updated script, we get data in the Kafka topic “bids”. Below we can see an example of data stored in the topic:
```
# kafka-console-consumer --bootstrap-server $BOOTSTRAP_SERVER --topic bids --from-beginning
10002,1.312920916299031E308,"2023-08-15 14:37:35.411"
10012,2.495268527292221E307,"2023-08-15 14:37:35.412"
10022,3.9478571741612126E307,"2023-08-15 14:37:35.412"
```
## Flink Job Implementation
Create one more Scala script called **hybridSouce.sc** and paste below content into it:
```scala
//> using dep "org.flinkextended::flink-scala-api:1.17.1_1.0.0"
//> using dep "org.apache.flink:flink-clients:1.17.1"
//> using dep "org.apache.flink:flink-csv:1.17.1"
//> using dep "org.apache.flink:flink-connector-files:1.17.1"
//> using dep "org.apache.flink:flink-connector-kafka:1.17.1"
import org.apache.flink.api._
import org.apache.flink.api.serializers._
import org.apache.flink.connector.file.src.FileSource
import org.apache.flink.connector.file.src.reader.TextLineInputFormat
import org.apache.flink.connector.file.src.impl.StreamFormatAdapter
import org.apache.flink.connector.kafka.source.KafkaSource
import org.apache.flink.connector.kafka.source.enumerator.initializer.OffsetsInitializer
import org.apache.flink.connector.base.source.hybrid.HybridSource
import org.apache.flink.api.common.serialization.SimpleStringSchema
import org.apache.flink.api.common.eventtime.WatermarkStrategy
import org.apache.flink.core.fs.Path
val currentDirectory = _root_.java.io.File(".").getCanonicalPath
val fileSource = FileSource
.forBulkFileFormat(
StreamFormatAdapter(TextLineInputFormat()),
Path(s"$currentDirectory/sink-table")
)
.build
val switchTimestamp = -1L
val brokers = ":9092"
val kafkaSource = KafkaSource
.builder[String]()
.setBootstrapServers(brokers)
.setTopics("bids")
.setStartingOffsets(OffsetsInitializer.timestamp(switchTimestamp + 1))
.setValueOnlyDeserializer(SimpleStringSchema())
.build
val hybridSource = HybridSource
.builder(fileSource)
.addSource(kafkaSource)
.build
val env = StreamExecutionEnvironment.getExecutionEnvironment
env
.fromSource(hybridSource, WatermarkStrategy.noWatermarks(), "combined")
.print()
env.execute()
```
Let’s review this code to understand what it does:
1. First of all we define two Flink sources: one for files and one for the Kafka topic. The Kafka topic offset is eventually set to 0, but it can be based on some user-defined offset in case the production pipeline needs to skip some historical data when starting to consume a Kafka topic.
1. Then we combine both sources via HybridSource builder. There can be as many sources as needed. **The main idea here is that all sources are bounded and the last source in the chain should be unbounded**. Such composition allows Flink to switch data consumption once a bounded data source is fully consumed.
1. Finally, we use the hybrid source to create a DataStream via the “fromSource” method.
There is an important point that the hybrid source API requires all combined sources to be based on the same type T; in the above example it is String type. If you have different record types among the sources these can be tackled by still using String as the input type and adding a “map” operator right after the hybrid source, to convert the string value into some typed value based on Scala case class or Java class.
Change the “brokers” variable value by setting your real Kafka hostname into it. Now let’s run this Flink Job via the following command:
```
> scala-cli hybridSource.sc
```
This results in the following console output:
```
…
2> 935,1.3486879258636198E308,"2023-08-15 13:58:38.741"
2> 945,1.2010058239019397E308,"2023-08-15 13:58:38.741"
2> 955,4.153541843468437E307,"2023-08-15 13:58:38.741"
…
9> 10970,2.2001341438733312E307,"2023-08-15 14:37:35.414"
9> 10980,1.129258179257586E308,"2023-08-15 14:37:35.414"
9> 10990,1.3994484424740486E308,"2023-08-15 14:37:35.414"
9> 11000,1.6970222740482843E308,"2023-08-15 14:37:35.414"
```
We can see that at the beginning of the data output we have the “id” column (first column from the left) within a range of 1 … 10000, which comes from the CSV files. Closer to the end of the output there is data with the “id” column in the range of 10001 … 20000, which comes from the Kafka topic.
## Conclusion
Using [HybridSource](https://nightlies.apache.org/flink/flink-docs-release-1.17/docs/connectors/datastream/hybridsource/) we can easily bootstrap a Fink Job state from different data sources before switching to the main data source. HybridSource was introduced in Flink v1.14. Before that you needed to implement a source switch somewhere in the user space by writing some tricky SourceFunction, which increased the overall Flink job complexity.
For more information on HybridSource see Flink Improvement Process Page [FLIP-150](https://cwiki.apache.org/confluence/display/FLINK/FLIP-150%3A+Introduce+Hybrid+Source)
---
---
title: "Ververica Academy: Pioneering the Future of Apache Flink® Education"
description: "Learn the fundamentals of Apache Flink® and stream processing in this engaging course. Develop high-performance applications and explore Flink SQL."
lastUpdated: 2026-05-11T12:56:26.000Z
source_url:
html: "https://www.ververica.com/blog/ververica-academy-is-available-now"
md: "https://www.ververica.com/blog/ververica-academy-is-available-now.md"
---
The world of data processing is in constant evolution, with real-time data streaming at the helm of this transformation. As businesses strive to harness the power of real-time analytics, the demand for proficient Apache Flink professionals is soaring. Catering to this burgeoning need, we are thrilled to introduce Ververica Academy - an elite online training hub for Apache Flink, complete with a badge recognition system!
## The Birth of Ververica Academy
Understanding the intricacies of Apache Flink requires not just theoretical knowledge but a comprehensive practical understanding. And who better to guide you than the original creators of Apache Flink? At Ververica Academy, our mission is to bridge the gap between eager learners and industry-leading expertise, providing a flexible platform to study at one's own pace.
## Dive Deep with Our Courses
### 1. Introduction to Apache Flink® and Stream Processing
Whether you’re stepping into the world of real-time data processing or are an enthusiast looking to hone your skills, this course is tailor-made for you. Dive into the heart of data streaming with a course that provides:
- A comprehensive understanding of Apache Flink fundamentals.
- Knowledge of building blocks essential to process data streams in real-time.
- Skills to build high-performance, low-latency applications.
### 2. Introduction to Apache Flink® SQL
For those who wish to delve into Flink applications and data streaming pipelines without the intricacies of Java or Scala, this course is a beacon. It encompasses:
- Detailed guidance on the fundamentals of Flink SQL.
- Demonstrations on leveraging Flink SQL for streaming applications.
- Real-world use-case applications.
## Why Choose Ververica Academy?
**Learning from the Pros:** Each course at Ververica Academy is curated and led by professionals who have worked closely with the original creators of Apache Flink. This ensures learners get insights straight from the source.
**Flexible Learning Modules:** We understand the constraints of time and commitments. That's why our courses are self-paced, allowing you to learn anywhere, anytime.
**Practical Curriculum:** Theory goes hand in hand with practice. Our curriculum doesn't just focus on knowledge acquisition but also on its practical application, supplemented with examples and exercises.
## Earn and Showcase Your Achievements
We believe in celebrating your progress and milestones. As you navigate through our courses, you'll earn badges—testaments to your hard work and newly-acquired skills. And guess what? You can proudly flaunt these badges on professional platforms like LinkedIn. Let the world witness your dedication, progress, and expertise in Apache Flink.
## Looking Ahead: A Future Full of Learning
While the courses we've launched set the foundation, this is merely the beginning. Stay tuned as we unveil a plethora of training content in the coming months, ranging from beginner to expert levels, ensuring a holistic learning experience for all.
---
---
title: "Batch Processing vs Stream Processing"
description: "Batch processing and stream processing are two different models for processing data. This blog post explores their differences, provides use case examples"
lastUpdated: 2026-05-11T12:56:11.000Z
source_url:
html: "https://www.ververica.com/blog/batch-processing-vs-stream-processing"
md: "https://www.ververica.com/blog/batch-processing-vs-stream-processing.md"
---
**Batch processing** and **stream processing** are two very different models for processing data. Both have their strengths but suit different use cases. In this post we cover the differences, provide examples of use cases, and look at the ways the two models can work together.
## Technology Evolution
Batch processing has its roots in the early days of computing. Batch systems automate repetitive tasks by periodically processing large numbers of records in a single batch. This opened the way for business process and office automation.
This kind of data processing is still relevant; the “payroll run” hasn’t gone away, but today you’re just as likely to find a batch processing system being used to assemble, move, and ingest data collections within a data pipeline.
The emergence of those data pipelines has brought an alternative model to center stage: stream processing. Instead of batching records, stream processing handles data as it comes in, in real time. In contrast to the predictable sources of batch data, stream data arrives from real-world sources, driven by real-world behaviors.
The modern data processing landscape is very different to the one from which batch systems emerged. Two key challenges dominate the technology choices:
- The need to manage and store massive volumes of data.
- The need to process massive volumes of data in real time.
## Batch Processing
Batch processing operates in a relatively slow cycle, typically measured in hours, days or weeks. A typical batch job processes stored data and persists the results as newly stored data – whether making updates in place, as in database processing, or generating new files or records, as in a billing system. Updates or changes are applied immediately to all selected records, files or bytes in the batch. Efficient storage management is typically more critical than processing time, as long as the job can be performed within the designated period; daily jobs should complete within 24 hours, weekly jobs can’t take longer than a week.
Batch systems are common across retail, banking, and other service industries, where they manage order and transaction reconciliation, for example overnight matching of orders, accounts, and despatch. Conventional batch processing also drives reporting cycles within businesses, as well as longer term business trend analysis.
### Modern Batch Processing
Alongside those more conventional functions, batch processing is important in modern data processing, where it is used to collect, assemble, and move data. Data pipelines rely heavily on cloud data stores, and batch processes are often at the heart of data management within and between cloud storage silos.
Batch processing can also play more than a back-end role; batch windows might sit alongside stream transaction windows in hybrid pipelines that perform backend reconciliation, while delivering real-time status updates to end users. Think of credit card swipes, online purchases, delivery tracking notifications, or inventory updates for warehouse workers – or robots!
## Stream Processing
Stream processing emerged as a technology in the early years of this millennium. The typical use cases that drove it centered on financial market data, telecoms, and IP network traffic from the still-emerging World Wide Web, all of which generated massive volumes of dynamically changing time-series data. Most of the techniques used today can be traced back to those beginnings.
### Stream Data Analytics
Unlike batch systems which wait for data to be collected and assembled before processing it, stream processing systems process data as soon as it is produced, generating real-time outputs from real-time data sources.
Think of a FinTech company detecting fraudulent transactions in real time, or a streaming service mining real-time insights from stream data analytics – the Netflix “You might also like…”.
## The Modern Data Context
Across both private and public sectors, “Data Driven” has become the new mantra – from telecoms to healthcare, finance to transport, energy to entertainment – not just your favorite movie channel, but your kids’ favorite multiplayer online games.
Take a look at the graph of [worldwide data volumes](https://www.statista.com/statistics/871513/worldwide-data-created) over the last decade and a half. The numbers are startling:
- Data volumes doubled roughly every two years, from two zettabytes in 2010 to 64 zettabytes in 2020.
- In the following decade, the numbers are on track to slow somewhat to between 20% and 25% growth year-on-year, to a predicted 181 zettabytes or more by 2030.
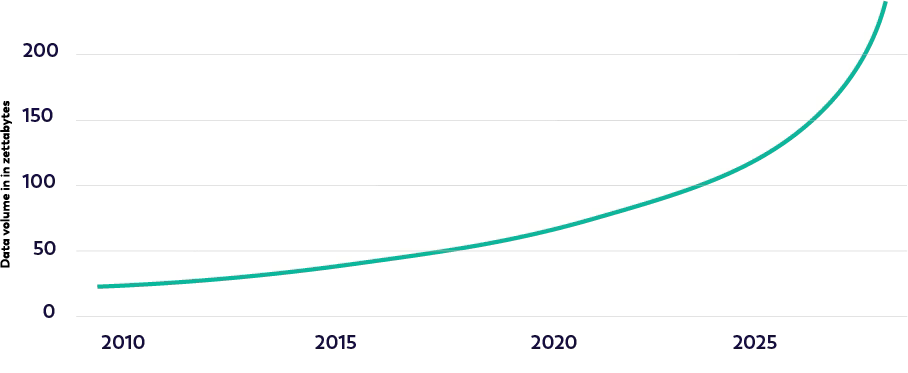
These are big numbers. A zettabyte is 1021 bytes, or a billion trillion bytes.
Let’s note too how little of that data survives beyond temporary storage: the same report estimates that just two percent of data was retained. Modern data is overwhelmingly transient. It's not a new idea that [data has a half-life](https://nucleusresearch.com/wp-content/uploads/2018/05/m36-Guidebook-Measuring-the-half-life-of-data.pdf), where the decay rate measures data relevance. It's a useful way to understand what drives the streaming data model.
### Transient Data
Transient data arises in real time from our everyday actions, and from the technologies we embed in our environment. We touch in and touch out of locations (transport systems), swipe cards (shops), click online (shopping, searching), trigger checkpoints (urban low emissions zones and tolls for drivers), install smart meters and even smart doorbells. We use our smartphones to initiate and take calls, and send and read messages, but we also use them to browse the web, shop, do our banking, and generally manage our online and real-world existence. All these interactions generate huge trails of data. Our life stories are in our data.
### Technology Head to Head
All technologies have an upside and downside and everything has its place. If you are instrumenting a particle accelerator, a batch job is not your primary tool. But if you are googling the science, batch jobs have likely built the index.
### Pros and Cons of Batch Processing
#### Pros
- Simplicity
- Scales efficiently
- Lossless, there’s no inherent time bound after which data is lost
- Deeper analysis – huge datasets can be processed and complex/deep calculations performed
- Schedule for cost, efficiency, or convenience – run in quiet times to reduce the load on your systems, or off-peak when electricity is cheap
- Requires minimal human interaction
#### Cons
- Timebound – large scale computation and large scale ingestions are slow
- Potential peak loads – batch windows are peaky and can push systems to their limits
### Pros and Cons of Stream Processing
#### Pros
- Real-time results – modern stream platforms drive processing latencies to milliseconds for highly time-critical data
- More uniform loads – streams may have cycles, but overall loads are more uniform and predictable
#### Cons
- Complexity – real time _anything_ is more complex, from design through developing and testing to support
- Potentially lossy – data not processed inside the given real-time bounds is lost by default
- One-touch – no multi-stage processing
- No rollbacks – failures can be difficult to troubleshoot, and the data may be gone
## One Size Doesn’t Fit All
There is no **one-size-fits-all** solution for any data processing requirement, but asking the right questions will help you focus on the critical choices.
In practice batch and stream processing are often complementary and can be mixed and matched. For example, a modern retail business might use _stream_ processing to capture real time purchase data, _batch_ processing for overnight inventory management, and _batch_ processing for monthly billings.
Even within a single data pipeline, as we saw from the example of cloud data management, batch and stream processing are not mutually exclusive. But it’s useful to identify the basic characteristics of each and match them against the data requirements.
### Is real-time processing really needed?
If you don’t need to make real-time decisions – maybe overnight is good enough – batch processing might be your best option.
### Is the loss of one record critical?
Stream processing may skip or miss data. Collect-and-batch offers greater resilience.
### Do you have many concurrent data sources?
Concurrency flags a potential streaming requirement. Batch processing can handle multiple data sources, but not simultaneously.
### Is your data unpredictable, unshaped, or unbounded?
Batch processing expects uniform and finite data. It excels at the ordinary. Extraordinary requirements need extraordinary solutions. Stream processing is your friend.
## Welcome to Ververica!
Ververica Platform and Ververica Cloud are built on [award winning Apache Flink®](https://2023.sigmod.org/sigmod_awards.shtml). Whether your data applications depend on pure batch or stream processing or require a mixed processing model, Ververica combines proven open source technologies with proprietary enhancements based on our expertise in powering massive scale data and transaction processing applications.
### Ververica Platform
Ververica Platform is the leading private cloud solution for high data throughput stateful streaming applications and hybrid stream/batch processing. Streamline and simplify your Flink deployments and enjoy the speed advantage of our highly optimized processing engines compared to vanilla [Apache Flink®](https://2023.sigmod.org/sigmod_awards.shtml).
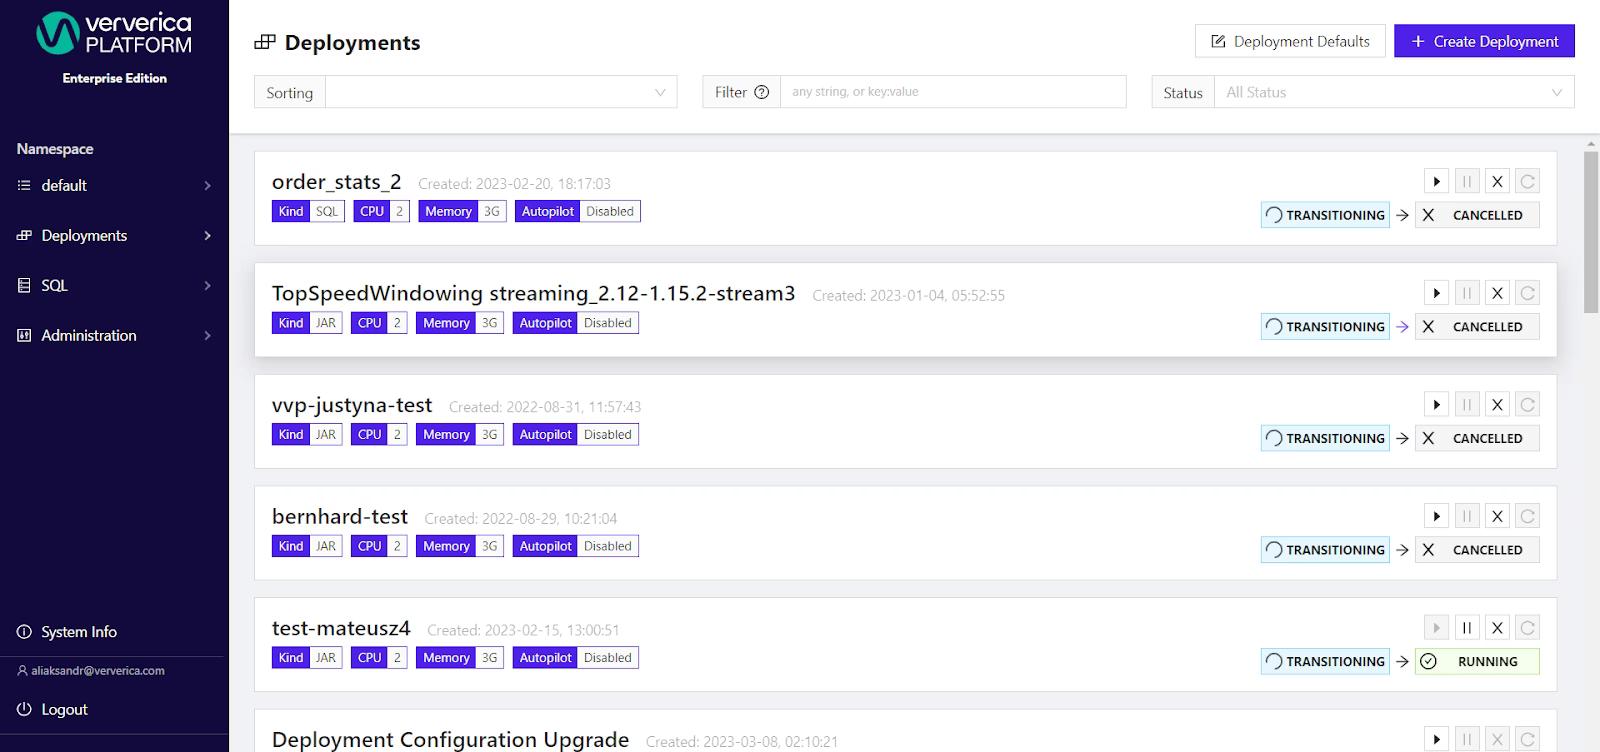
erverica Platform powers production systems across the spectrum to enable global businesses from ecommerce and fintech to cloud IoT and more.
### Ververica Cloud
[Ververica Cloud](https://www.ververica.com/product/deployment/cloud) builds on the same core Ververica technologies to deliver a fully managed cloud-native service, designed for easy deployment and management of your Flink applications.
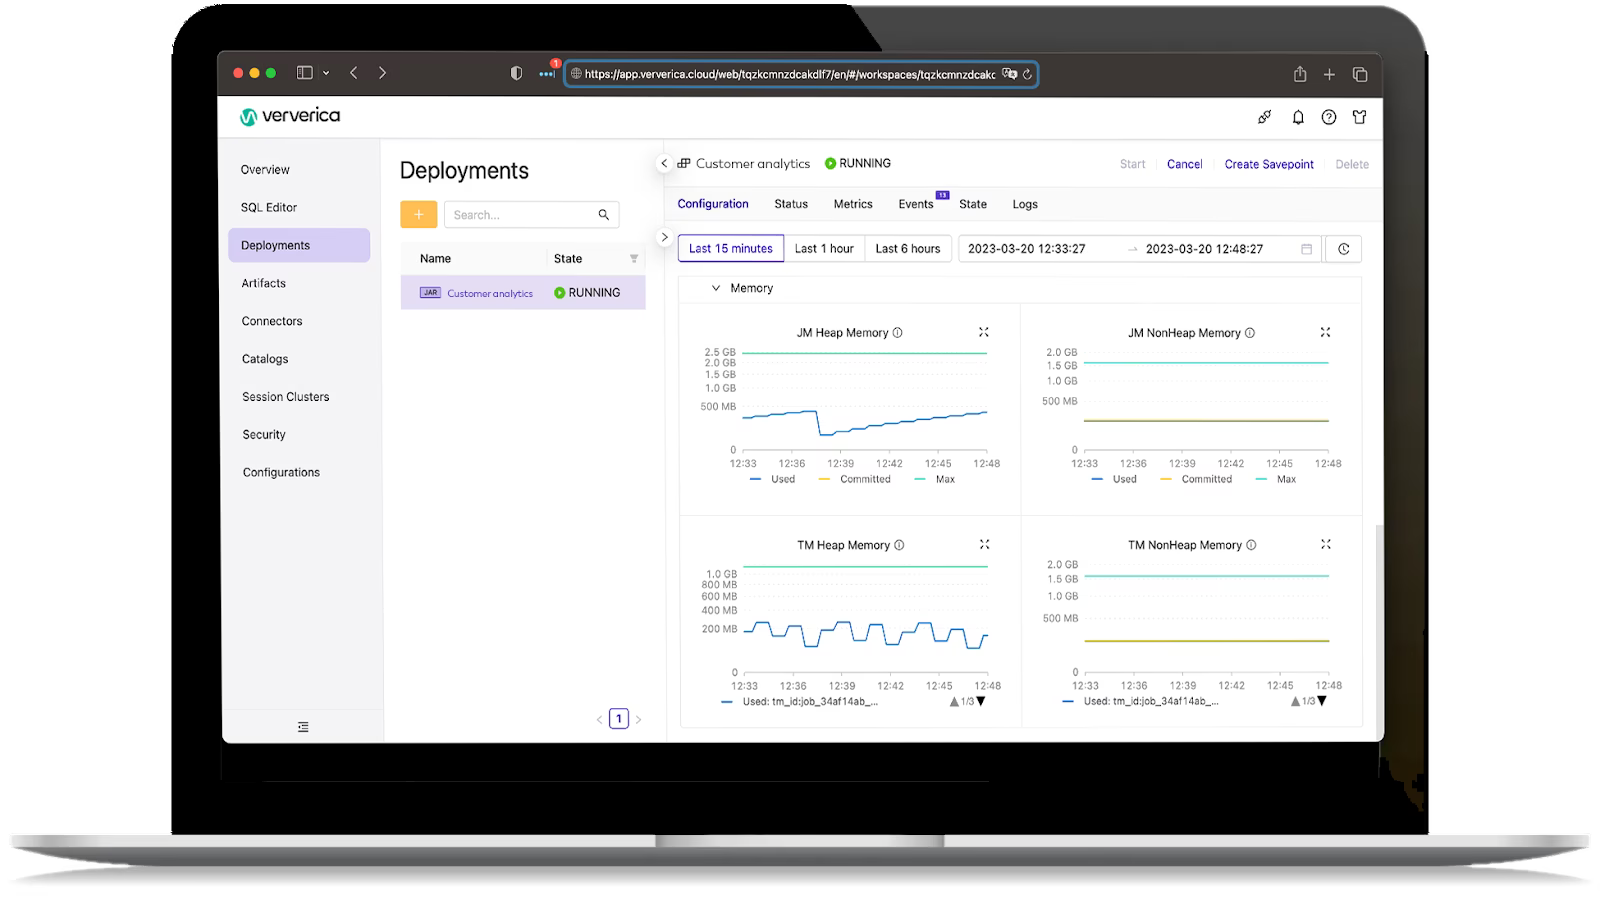
With all the advantages of Ververica Platform, it offers a turnkey cloud solution for maximum ease and speed of deployment.
---
---
title: "Stream Enrichment in Flink"
description: "Stream enrichment in Apache Flink breathes life into data, transforming it from grayscale to full color. Discover the three ways to access reference data."
lastUpdated: 2026-05-12T09:37:18.000Z
source_url:
html: "https://www.ververica.com/blog/stream-enrichment-in-flink"
md: "https://www.ververica.com/blog/stream-enrichment-in-flink.md"
---
Imagine a photo without its vibrant colors; intriguing but lacking depth. Stream enrichment works similarly for data. It infuses raw data streams with added context, transforming them from grayscale to full color.
Going beyond the simple transmission of information, stream enrichment breathes life into data, augmenting it with additional context and details. By embedding supplementary data into an existing data stream, businesses and organizations can paint a clearer picture, driving enhanced understanding and decision-making. Let's explore this transformative process.
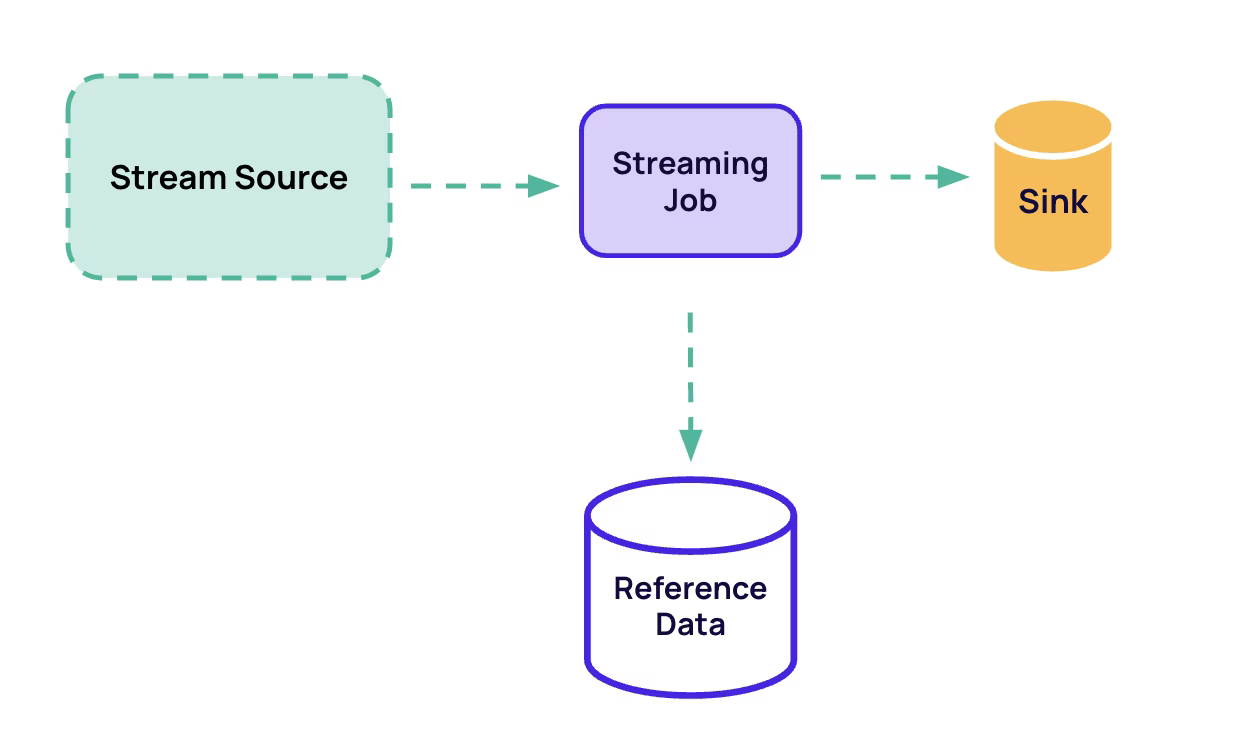
## Questions to ask yourself before implementing stream enrichment in Apache Flink®
Enrichment is a fundamental task in many data processing pipelines, and Apache Flink provides multiple ways to achieve it. The “best” solution depends on many factors such as data size, throughput, latency, desired output format, and many more.
You should first ask yourself these five questions before you jump into the nuts and bolts of the technical execution of stream enrichment.
1. Where is the ground truth for the reference data?
1. What sort of load can that database or service handle?
1. Is it okay to enrich with stale data?
1. What sort of throughput and latency are required?
1. Would it make sense to completely mirror the data into Flink state?
## Three ways to access reference data
1. Preload the entire reference dataset into memory on start-up
2. Perform per-record lookups, requesting reference data as needed
3. Stream in the reference data and store it in Flink state
## Preloading of Reference Data
Issue at hand: We're uncertain about the specific keys needed for data retrieval.
Enrichment in Apache Flink is challenging when dealing with large reference datasets. When a task requires looking up a large number of values from a reference dataset, preloading the reference data from a database in the open() of a RichFlatMapFunction may be an option.
This approach does have its drawbacks, as it requires knowledge of which keys to look up in advance. Let’s see how we can solve this problem.
### Solution 1: Fetch all the data
One solution to the problem at hand is to simply fetch all the data from the reference dataset in the open() of the RichFlatMapFunction. This allows us to look up any key without knowing it beforehand. The downside of this approach is that it can be very inefficient if the reference dataset is large.
```java
public class EnrichmentWithPreloading extends RichFlatMapFunction {
private Map referenceData;
@Override
public void open(final Configuration parameters) throws Exception {
super.open(parameters);
referenceData = loadReferenceData();
}
@Override
public void flatMap(
final Event event,
final Collector collector) throws Exception {
SensorReferenceData sensorReferenceData =
referenceData.get(sensorMeasurement.getSensorId());
collector.collect(new EnrichedEvent(event, sensorReferenceData));
}
```
### Solution 2: Use a custom partitioner
Another solution is to use a custom partitioner to determine which task will be responsible for each key. This partitioner will be used to distribute the reference data across the tasks. This approach is more efficient than the first solution, as it only requires fetching the data for the keys that are relevant to the task. Additionally, this approach allows for the data to be processed in parallel, which can result in faster processing times.
```java
public interface Partitioner extends java.io.Serializable, Function {
/**
* Computes the partition for the given key.
*
* @param key The key.
* @param numPartitions The number of partitions to partition into.
* @return The partition index.
*/
int partition(K key, int numPartitions);
}
```
Applying custom partitioning
```java
private static class SensorIdPartitioner implements Partitioner {
@Override
public int partition(final Long event, final int numPartitions) {
return Math.toIntExact(event % numPartitions);
}
}
public static void main(String[] args) throws Exception {
...
DataStream events = env.addSource(new SensorEventSource(...));
DataStream enrichedEvents = events
.partitionCustom(new SensorIdPartitioner(), measurement -> measurement.getSensorId())
.flatMap(new EnrichmentFunctionWithPartitionedPreloading());
public class EnrichmentWithPartitionedPreloading extends RichFlatMapFunction {
private Map referenceData;
@Override
public void open(final Configuration parameters) throws Exception {
super.open(parameters);
referenceData = loadReferenceData(
getRuntimeContext().getIndexOfThisSubtask(),
getRuntimeContext().getNumberOfParallelSubtasks()
);
}
@Override
public void flatMap(
final Event event,
final Collector collector) throws Exception {
SensorReferenceData sensorReferenceData = referenceData.get(sensorMeasurement.getSensorId());
collector.collect(new EnrichedEvent(event, sensorReferenceData));
}
```
Preloading of reference data is only suitable for certain use cases, i.e., rarely changing data that fits in memory. Pros of these solutions include simplicity, high throughput, low latency, and the ability to enrich streaming data with data from databases. Cons include the potential to enrich stale data, the need for the reference dataset to fit in memory, and the inability to use it to bootstrap keyed state.
## Per-record Lookup of Reference Data
Per-record lookup of reference data involves looking up related information from a reference dataset for each record of the input data. This approach offers the advantage of having up-to-date data as the reference dataset can be updated independently of the input data. On the downside, this approach can be more resource-intensive and can lead to longer processing times.
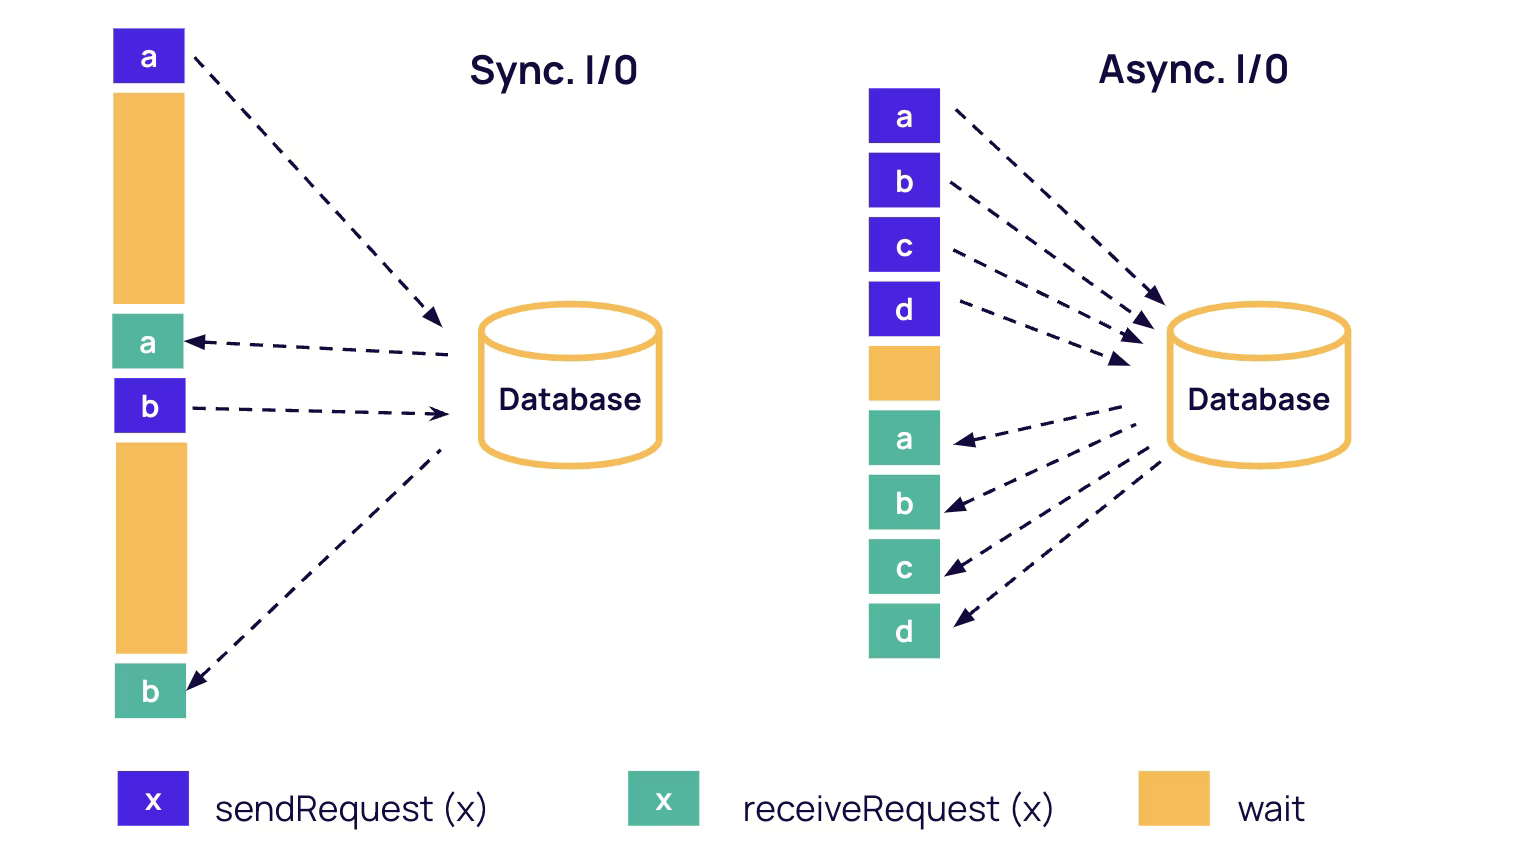
Flink SQL supports both synchronous and asynchronous lookup of reference data, allowing users to select the best approach for their use case. Synchronous lookup is easy to implement using the RichFlatMapFunction, while asynchronous lookup is supported by Flink's Async I/O operator.
## Calling an AsyncFunction
Calling an AsyncFunction is another common way of enriching data in Apache Flink. This approach involves calling an asynchronous function for each record of the input data. It provides enhanced throughput since the AsyncFunction can handle multiple records at once. Additionally, it can make use of a configurable timeout and capacity parameters, which allows the user to control the trade-off between latency and throughput.
```java
DataStream enrichedEvents =
AsyncDataStream.(un)orderedWait(
events,
new AsyncEnrichmentFunction(),
1000, TimeUnit.MILLISECONDS, // timeout
100 // max number of in-flight requests
);
```
Flink avoids potential pitfalls by maintaining correct watermarking. With unorderedWait(), Flink takes care not to allow watermarks to be emitted too early or too late. The out-of-orderness introduced by unorderedWait() is only allowed between watermarks. Flink also stays clear of potential pitfalls by ensuring fault tolerance. The Futures for in-flight requests are stored in state snapshots, and re-triggered during recovery.
```java
public class AsyncEnrichmentFunction extends RichAsyncFunction {
private ReferenceDataClient client;
@Override
public void open(final Configuration parameters) throws Exception {
super.open(parameters);
client = new ReferenceDataClient();
}
@Override
public void asyncInvoke(final Event event, final ResultFuture resultFuture) {
client.asyncGetReferenceDataFor(
event.getReferenceId(),
new Consumer() {
@Override
public void accept(final ReferenceData referenceData) {
resultFuture.complete(Collections.singletonList(new EnrichedEvent(
event,
referenceData)));
}
});
}
}
```
## Capture Reference Data as a Stream
Apache Flink provides multiple ways to join two streams and perform enrichment.
- Key both streams and implement a DIY join with [CoProcessFunction](https://nightlies.apache.org/flink/flink-docs-release-1.16/docs/dev/datastream/operators/process_function/)
- Key one stream and broadcast the other, using [KeyedBroadcastProcessFunction](https://nightlies.apache.org/flink/flink-docs-release-1.16/docs/dev/datastream/fault-tolerance/broadcast_state/#the-broadcast-state-pattern)
- The [DataStream API](https://nightlies.apache.org/flink/flink-docs-release-1.16/docs/dev/datastream/overview/) offers time-windowed joins
- The [SQL/Table APIs](https://nightlies.apache.org/flink/flink-docs-release-1.16/docs/dev/table/overview/) provide several types of joins
- regular INNER + OUTER joins
- time-windowed INNER + OUTER joins
- temporal joins with versioned tables
- lookup joins with external databases
Enrichment via lookup
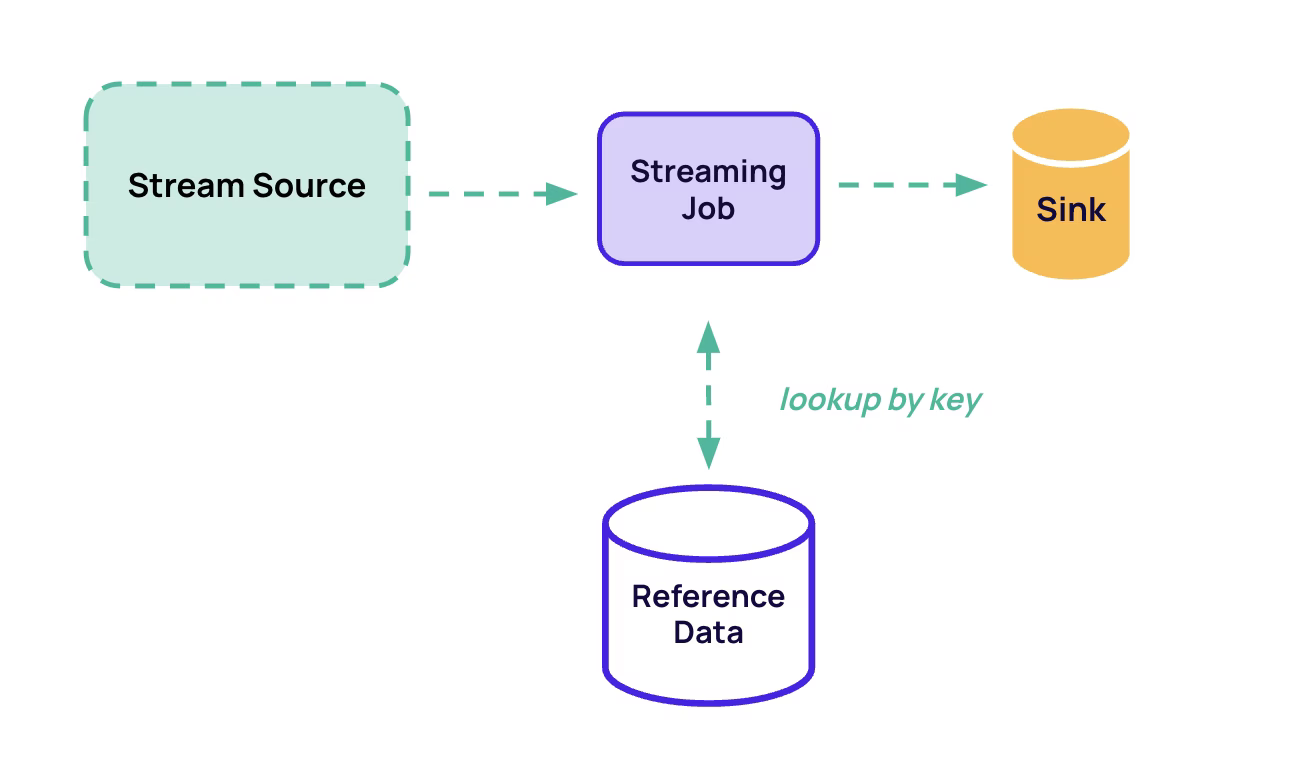
Enrichment via reference data source
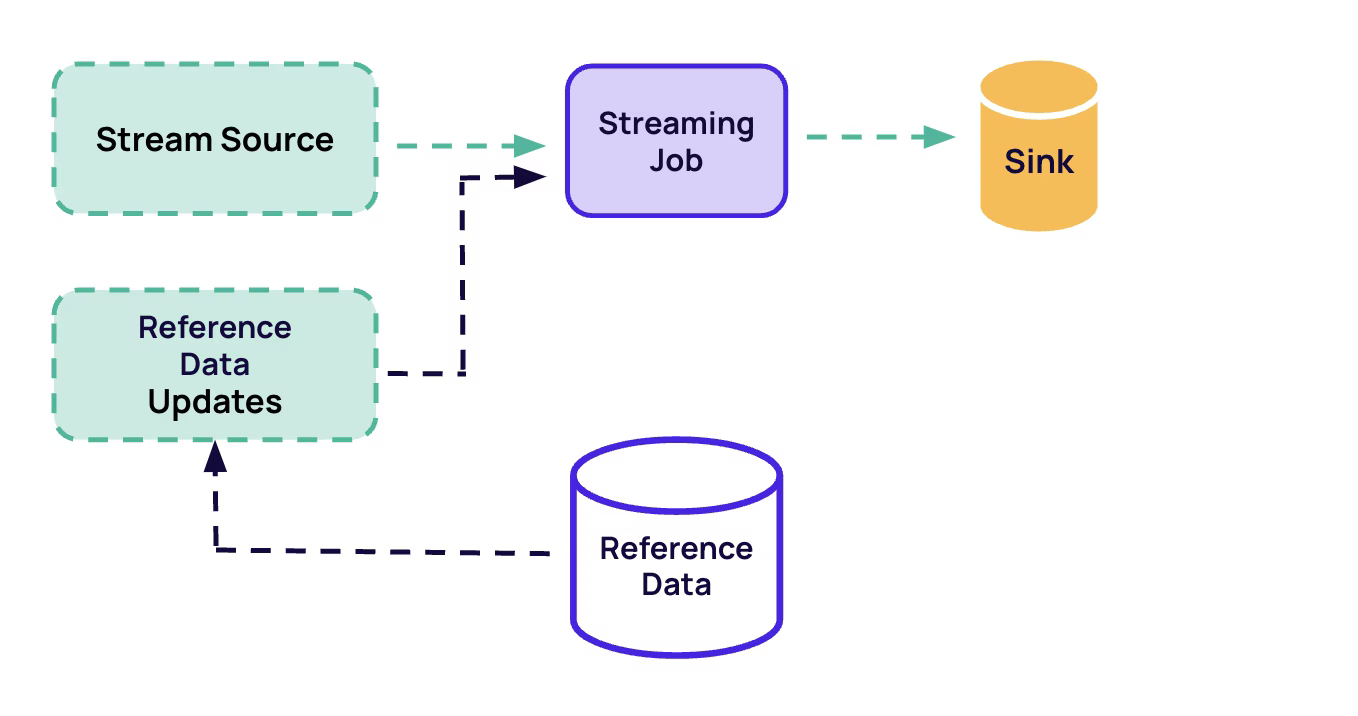
Flink provides connectors for popular streaming sources such as Compacted Kafka Topics, Debezium, Maxwell's Daemon, and Canal.
When working with a bootstrap state, you should use the bootstrap state for enrichment by reading from some stream until it is "caught up". Then, you should begin to process the main stream, using that enrichment state while continuing to receive updates for the enrichment stream.
However, Flink doesn't make this easy but you can use the State Processor API to build an initial savepoint from a DB dump. Also, you can prepare a special bootstrapping version of your job that reads from the enrichment stream until the state is ready. Then, you can create a savepoint, and start your real job from that savepoint making sure the stateful operators in both jobs have matching UIDs.
## Conclusion
Overall, Apache Flink is a great choice for stream enrichment and data processing for any application that requires real-time data processing. Stream enrichment is a great way to add context to data streams, enabling better decision-making and deeper insights; ultimately increasing the value of your data.
---
---
title: "All You Need to Know About PyFlink"
description: "If you find yourself needing real-time computing solutions and you're comfortable with the Python or want to use some handy Python libraries in the process"
lastUpdated: 2026-05-12T09:54:20.000Z
source_url:
html: "https://www.ververica.com/blog/all-you-need-to-know-about-pyflink"
md: "https://www.ververica.com/blog/all-you-need-to-know-about-pyflink.md"
---
PyFlink serves as a Python API for Apache Flink, providing users with a medium to develop Flink programs in Python and deploy them on a Flink cluster.
In this post, we will introduce PyFlink from the following aspects:
- The structure of a fundamental PyFlink job and some basic knowledge surrounding it
- The operational mechanisms of PyFlink jobs, the high-level architecture, and its internal workings
- Essential performance optimization strategies for PyFlink
- Future projections for PyFlink
By the end of this article, you should have a firm grasp on PyFlink and its potential applications.
If you find yourself needing real-time computing solutions, such as real-time ETL, real-time feature engineering, real-time data warehouse, real-time prediction, and you're comfortable with the Python language or want to use some handy Python libraries in the process, PyFlink is an excellent starting point as it merges the worlds of Flink and Python.
PyFlink was first introduced into Flink in Flink 1.9, dating back to 2019. This inaugural version offered only limited functionalities. Since then, the Flink community has strived to continually enhance PyFlink. After nearly four years of diligent development, it has become more and more mature. Currently, it encompasses most functionalities found in the Flink Java API. Additionally, PyFlink exclusively provides several features, like Python user-defined function support, among other functionalities.
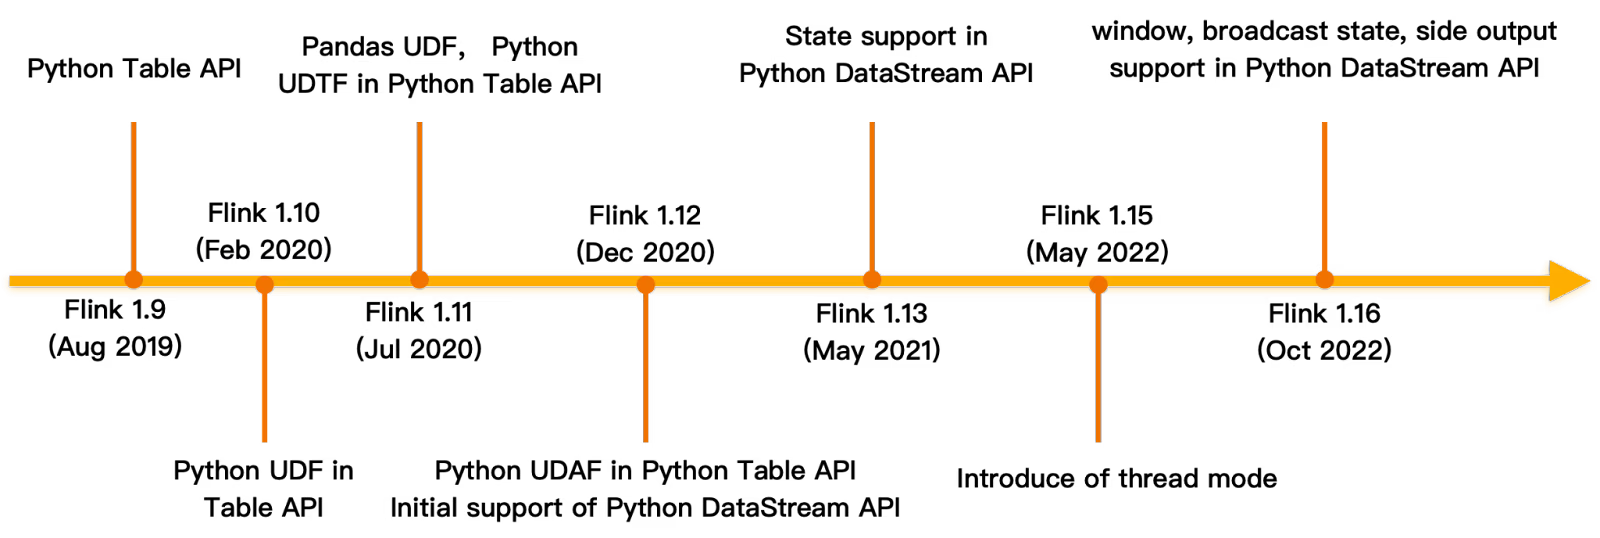
## Getting Started with PyFlink
PyFlink is integrated into current versions of Ververica Platform. If you want to get a feel for PyFlink’s capabilities and are working in a Kuberbetes capable environment, you can download Community Edition for free and spin up a [minikube](https://minikube.sigs.k8s.io/docs/) playground in minutes.
If you prefer to work with vanilla Flink, then you can install PyFlink from PyPI:
```bash
$ pip install apache-flink
```
For the latest Flink 1.17 you’ll need a Python version later than Python 3.6, up to and including Python 3.10; Flink 1.16 supports Python versions from 3.6 to 3.9. Note that Python/PyFlink must be available to each node in the cluster. The most flexible way to do this is to pass in a Python environment when you submit a PyFlink job, but if you have many deep Python dependencies it may be simpler just to preinstall the Python environment to each cluster node.
You can alternatively [build PyFlink from source](https://nightlies.apache.org/flink/flink-docs-stable/docs/flinkdev/building/#build-pyflink), which you may want to do if you maintain your own fork of Flink or need to cherry-pick commits which are still not released.
## Flink Basics for PyFlink
If you are new to Flink, there are a few basic concepts it’s good to understand and which are relevant also to PyFlink:
- Flink offers two different APIs, the procedural and relatively low level **DataStream API** and the relational/declarative **Table API**. Don’t be misled by their names: both APIs can be applied to either stream or batch processing, and both have PyFlink APIs.
- Flink is a distributed computing engine. It has no storage besides the state which provides the immediate context during processing. Data is assumed to flow from an external **data source** to (typically, but it’s not required) an external **data sink**. A Flink/PyFlink job needs at least a data source.
- At the heart of any Flink/PyFlink application are the **data transformations** that compute the desired results from the source data – which can involve reshaping or sampling data, merging and enriching, comparing or modeling, processing transactions, or any of the countless other ways you might want to perform computations over unbounded data streams or massive data sets.
### Define Data Source and Sink
The first step for any PyFlink job is to define the data source, and optionally the data sink to which the execution results will be written.
PyFlink fully supports both the Table API and the DataStream API. Both APIs provide many different ways to define sources and sinks, and a single job can combine both APIs, for example converting between Table API reads and DataStream API writes, or DataStream API reads and Table API writes.
Below is a typical read and write example for each API. The examples assume Kafka streams provide the source/sink.
Reading from Kafka using Table API:
```bash
env_settings = EnvironmentSettings.in_streaming_mode()
t_env = TableEnvironment.create(env_settings)
t_env.create_temporary_table(
'kafka_source',
TableDescriptor.for_connector('kafka')
.schema(Schema.new_builder()
.column('id', DataTypes.BIGINT())
.column('data', DataTypes.STRING())
.build())
.option('properties.bootstrap.servers', 'localhost:9092')
.option('properties.group.id', 'my-group')
.option('topic', 'input-topic')
.option('scan.startup.mode', 'earliest-offset')
.option('value.format', 'json')
.build())
table = t_env.from_path("kafka_source")
```
Reading from Kafka using DataStream API:
```bash
source = KafkaSource.builder() \
.set_bootstrap_servers("localhost:9092") \
.set_topics("input-topic") \
.set_group_id("my-group") \
.set_starting_offsets(KafkaOffsetsInitializer.earliest()) \
.set_value_only_deserializer(
JsonRowDeserializationSchema.builder()
.type_info(Types.ROW([Types.LONG(), Types.STRING()]))
.build()) \
.build()
env = StreamExecutionEnvironment.get_execution_environment()
ds = env.from_source(source, WatermarkStrategy.no_watermarks(), "Kafka Source")
```
Writing to Kafka using Table API:
```bash
env_settings = EnvironmentSettings.in_streaming_mode()
t_env = TableEnvironment.create(env_settings)
t_env.create_temporary_table(
'kafka_sink',
TableDescriptor.for_connector('kafka')
.schema(Schema.new_builder()
.column('id', DataTypes.BIGINT())
.column('data', DataTypes.STRING())
.build())
.option('properties.bootstrap.servers', 'localhost:9092')
.option('topic', 'output-topic')
.option('value.format', 'json')
.build())
table.execute_insert('kafka_sink')
```
Writing to Kafka using DataStream API:
```bash
sink = KafkaSink.builder() \
.set_bootstrap_servers('localhost:9092') \
.set_record_serializer(
KafkaRecordSerializationSchema.builder()
.set_topic("topic-name")
.set_value_serialization_schema(
JsonRowSerializationSchema.builder()
.with_type_info(Types.ROW([Types.LONG(), Types.STRING()]))
.build())
.build()
) \
.set_delivery_guarantee(DeliveryGuarantee.AT_LEAST_ONCE) \
.build()
ds.sink_to(sink)
```
Refer to the [Apache Table API documentation](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/python/table/intro_to_table_api/#create-tables) for more details about Table API connectors, and to the [Apache DataStream API documentation](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/python/datastream/intro_to_datastream_api/#create-a-datastream) for more about DataStream API connectors. The [Apache API conversion documentation](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/python/datastream/intro_to_datastream_api/#conversion-between-datastream-and-table)[shows how to](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/python/datastream/intro_to_datastream_api/#conversion-between-datastream-and-table)combine Table API/DataStream API reads/writes.
There are a few things to notice:
- The Table API examples define source/sink properties as key/value pairs. All Table API connectors follow that pattern To use a different connector, or to define a new connector that is not officially supported in PyFlink, just configure appropriate key/value pairs.
- The DataStream API connectors are less regular; each connector provides a stack of completely different APIs. Refer to the [specific connector page](https://nightlies.apache.org/flink/flink-docs-stable/docs/connectors/datastream/overview/) to see which APIs are provided. To use a connector not supported by PyFlink you need to write a Python wrapper for the corresponding Java API, see the [supported connectors](https://github.com/apache/flink/tree/master/flink-python/pyflink/datastream/connectors) for examples.
### Transformations
Both APIs support a wide range of transformations.
The [DataStream API](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/datastream/operators/overview/#map) includes the following functionality:
- map: Convert one element into another
- flat map: Takes one element as input and produce zero, one, or more elements
- filter: Evaluates a boolean function for each element and filter out the ones which return false
- aggregation: Accumulating multiple elements
- [windowing](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/datastream/operators/windows/): Group elements into different windows and perform calculations for each group
- [connect](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/datastream/operators/overview/#connect): Connect two different streams, allows sharing state between two streams
- [process](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/datastream/operators/process_function/): Similar to flat map, however, is more flexible as it allows access to low level operations, e.g. timer, state, etc.
- [broadcast](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/datastream/fault-tolerance/broadcast_state/): Broadcast one stream to all the subtasks of another stream
- [side output](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/datastream/side_output/): In addition to the main stream, produce additional side output result stream
- [async io](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/datastream/operators/asyncio/): This is still not supported in PyFlink.
The [Table API](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/tableapi/) is a relational API with a SQL-like flavor. It includes the following functionality:
- projection: Similar to map in DataStream API
- filter: similar to filter in DataStream API
- aggregation: Similar to SQL GROUP BY, group elements on the grouping keys and perform aggregations for each group
- [window aggregation](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/tableapi/#group-windows): Group elements into different windows and perform aggregations for each window
- [regular join](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/tableapi/#joins): Similar to SQL JOIN, joins two streams
- [lookup (stream-table) join](https://nightlies.apache.org/flink/flink-docs-release-1.16/docs/dev/table/sql/queries/joins/#lookup-join): Joins a stream with a static table
- [temporal join](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/joins/#temporal-joins): Join a stream with a versioned table, similar to lookup join, however, it allows join a table at a certain point in time
- [window join](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/window-join/): Join elements of two streams belonging to the same window
- [interval join](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/tableapi/#interval-join): Join elements of two streams with a time constraint
- [topn](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/topn/) and [windowed](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/window-topn/)[topn](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/window-topn/): N smallest or largest values ordered by columns
- [deduplication](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/deduplication/) and [windowed deduplication](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/window-deduplication/): Removes elements that duplicate over a set of columns
- [pattern recognition](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/match_recognize/): Detect elements of a specific pattern in one stream
Again there are a few things to notice:
- If you need fine-grained control of the transformations or access to low level functionality, e.g. timer, state, etc, choose the DataStream API. Otherwise, Table API is a good choice in most cases.
- The Table API also supports [executing SQL queries](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/python/table/intro_to_table_api/#write-sql-queries) directly , providing access to functions not currently available via the API, e.g. deduplication, pattern recognition, topn, etc. Although the API will continue to grow, using SQL provides an immediate solution.
### Job Submission
Flink is a distributed compute engine which executes Flink/PyFlink jobs in a standalone cluster.. Flink jobs are executed lazily; you must explicitly submit jobs for execution. This is a little different from the more interactive/exploratory scripting style that many Python users are used to.
For example, if you have a PyFlink job defined by a Python script word_count.py, you can execute it locally via the Flink console with $ python word_count.py or by right clicking and executing in the Flink IDE. Flink will launch a mini Flink cluster which runs in a single process and executes the PyFlink job.
You can also submit a PyFlink job to a remote cluster using [Flink’s command line tool](https://nightlies.apache.org/flink/flink-docs-stable/docs/deployment/cli/#submitting-pyflink-jobs).
Here is a simple example that shows how to submit a PyFlink job to an Apache YARN cluster for execution:
```bash
./bin/flink run-application -t yarn-application \
-Djobmanager.memory.process.size=1024m \
-Dtaskmanager.memory.process.size=1024m \
-Dyarn.application.name= \
-Dyarn.ship-files=/path/to/shipfiles \
-pyarch shipfiles/venv.zip \
-pyclientexec venv.zip/venv/bin/python3 \
-pyexec venv.zip/venv/bin/python3 \
-pyfs shipfiles \
-pym word_count
```
See the [Apache documentation](https://pyflink.readthedocs.io/en/main/getting_started/installation/index.html) for more about job submission in Flink.
You can read more about how to define and run a Python script as a PyFlink job in the LINK of PyFlink blog post.
### Debug and Logging
At the beginning, Python user-defined functions are executed in separate Python processes which are launched during job startup. This is not easy to debug as users have to [make some changes](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/python/debugging/#remote-debug) to the Python user-defined functions to enable remote debugging.
Since Flink 1.14, it has supported to execute Python user-defined functions in the same Python process on the client side in local mode. Users could set breakpoints in any places where they want to debug, e.g. PyFlink framework code, Python user-defined functions, etc. This makes debugging PyFlink jobs very easy, just like debugging any other usual Python programs.
Users could also use [logging](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/python/debugging/#server-side-logging) inside the Python user-defined functions for debugging purposes. It should be noted that the logging messages will appear in the logging file of the TaskManagers instead of the console.
```java
import logging
@udf(result_type=DataTypes.BIGINT())
def add(i, j):
logging.info("i: " + i + ", j: " + j)
return i + j
```
Besides, it also supports [Metrics](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/python/table/metrics/) in the Python user-defined functions. This is very useful for long running programs and could be used to monitor specific statistics and configure alerts.
### Managing Dependencies
For a production job you will almost certainly want to refer to third party Python libraries. Possibly you may also need to use data connectors whose jar files are not part of the Flink distribution - for example connectors for Kafka, HBase, Hive, and Elasticsearch are not bundled in the Flink distribution.
Because PyFlink jobs are executed in a distributed cluster, dependencies also need to be managed across the cluster. PyFlink provides a number of ways to manage dependencies.
#### JAR Files
You can include JAR files with a PyFlink job:
```bash
# Table API
t_env.get_config().set("pipeline.jars", "file:///my/jar/path/connector.jar;file:///my/jar/path/udf.jar")
# DataStream API
env.add_jars("file:///my/jar/path/connector1.jar", "file:///my/jar/path/connector2.jar")
```
You must include all the transitive dependencies. For connectors, use the fat JAR whose name usually includes **sql**, e.g. **flink-sql-connector-kafka-1.16.0.jar** for the Kafka connector in preference to **flink-connector-kafka-1.16.0.jar**.
#### Third-Party Python Libraries
Add the Python dependencies to the PyFlink venv virtual environment:
```bash
# Table API
t_env.add_python_file(file_path)
# DataStream API
env.add_python_file(file_path)
```
The environment, with the specified libraries included, will be distributed across the cluster nodes during execution.
#### Zipped Python Libraries
If you need to include a large number of Python libraries it’s good practice to pass them in archived form to the virtual environment:
```bash
# Table API
t_env.add_python_archive(archive_path="/path/to/venv.zip")
t_env.get_config().set_python_executable("venv.zip/venv/bin/python3")
# DataStream API
env.add_python_archive(archive_path="/path/to/venv.zip")
env.set_python_executable("venv.zip/venv/bin/python3")
```
### Other tips
Like Python itself, PyFlink offers great flexibility and adaptability. As you explore the APIs, here are some useful tips.
#### Use **Open()** for Initialization
If your Python code depends on a big resource, e.g. a machine learning model, use the **open()**to load it once at during job initialization:
```python
# DataStream API
class MyMapFunction(MapFunction):
def open(self, runtime_context: RuntimeContext):
import pickle
with open("resources.zip/resources/model.pkl", "rb") as f:
self.model = pickle.load(f)
def map(self, value):
return self.model.predict(value)
# Table API
class Predict(ScalarFunction):
def open(self, function_context):
import pickle
with open("resources.zip/resources/model.pkl", "rb") as f:
self.model = pickle.load(f)
def eval(self, x):
return self.model.predict(x)
predict = udf(Predict(), result_type=DataTypes.DOUBLE())
```
This is more efficient than opening it directly in your Python function:
```python
with open("resources.zip/resources/model.pkl", "rb") as f:
model = pickle.load(f)
@udf(result_type=DataTypes.DOUBLE())
def predict(x):
return mode.predict(x)
```
The simplistic approach causes the resource to be serialized and distributed with the Python function itself and loaded with each invocation; using open() ensures it is only loaded once.
#### Watermarks
Watermarks trigger the calculation of specific operators e.g. window, pattern recognition, etc when event time is enabled. Be sure to define the watermark generator, otherwise your job may have no output.
PyFlink gives you several different ways to define the watermark generator:
- SQL DDL: See [Watermark](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/create/#watermark) section for more details.
- Table API: Refer to this [example](https://github.com/apache/flink/blob/master/flink-python/pyflink/examples/table/windowing/tumble_window.py#L55) for more details.
- DataStream API: Refer to this [example](https://github.com/apache/flink/blob/master/flink-python/pyflink/examples/datastream/windowing/tumbling_time_window.py#L69) for more details.
If your watermark generator is defined correctly but the watermark isn’t advancing as expected, then possibly your job does not have enough data. This can be true during testing if you have a small test sample. Try setting the parallelism of the job to 1 or [configure source idleness](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/datastream/event-time/generating_watermarks/#dealing-with-idle-sources) to work around the problem during the test phase. See ‘[Timely Stream Processing](https://nightlies.apache.org/flink/flink-docs-stable/docs/concepts/time/)’ for more about watermark behavior.
### Flink Web UI
The Web UI is a rich source of information – showing how long the job has run, whether there are any exceptions, the number of input / output elements for each operator, etc.
How you access it depends on the deployment mode:
- Local: The web port is set randomly. You can find it in the log file at **/path/to/python-installation-directory/lib/python3.7/site-packages/pyflink/log/.local.log**):
> **INFO:** INFO org.apache.flink.runtime.dispatcher.DispatcherRestEndpoint [] - Web frontend listening at http://localhost:55969.
- Standalone: Configured via configuration **rest.port** which is 8081 by default.
- Apache YARN: From the Web Ui of the YARN Resource Manager, find the application corresponding to the PyFlink job and then click the link under the “Tracking UI” column.
- Kubernetes: The Web UI may be exposed via any of the following: ClusterIP, NodePort and LoadBalancer. See the Kubernetes [documentation](https://nightlies.apache.org/flink/flink-docs-stable/docs/deployment/resource-providers/native_kubernetes/#accessing-flinks-web-ui) for more details.
## Architecture and Internals
Some background understanding may help you answer questions like:
- What’s the difference between Python API and Java API and which one should I use?
- How to use a custom connector in PyFlink?
- Where to find the logging messages printed in the Python user-defined functions?
- How to tune the performance of PyFlink jobs?
Note that we will not talk about basic Flink concepts here, for example the [architecture of Flink](https://nightlies.apache.org/flink/flink-docs-stable/docs/concepts/flink-architecture/), [stateful streaming processing](https://nightlies.apache.org/flink/flink-docs-stable/docs/concepts/stateful-stream-processing/), [event time and watermark](https://nightlies.apache.org/flink/flink-docs-stable/docs/concepts/time/)[which are described in detail in](https://nightlies.apache.org/flink/flink-docs-stable/docs/concepts/time/)the official Flink documentation.
## Architecture Diagram
PyFlink is composed of two main parts:
- Job compiling: Converts a PyFlink program into a JobGraph
- Job execution: Accepts a JobGraph and converts it into a graph of Flink operators which run in a distributed manner
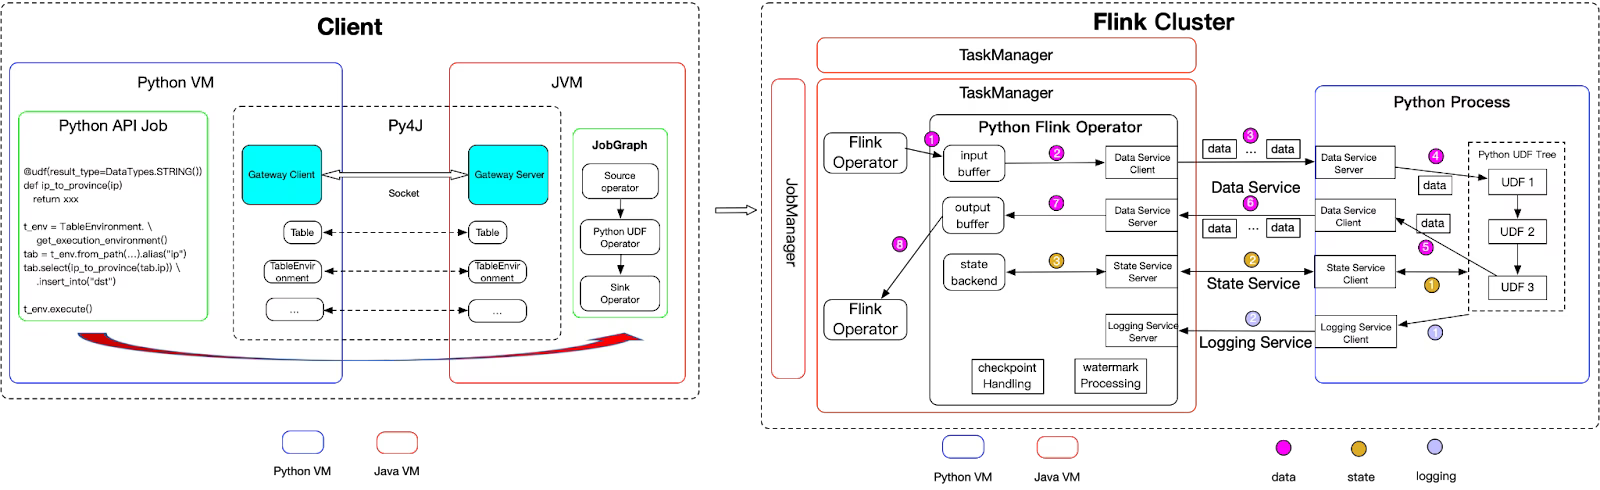
### Job compiling
Think of JobGraph as the protocol between a client and a Flink cluster. It contains all the necessary information to execute a job:
- A graph of transformations which represents the processing logic the user wants to perform
- The name and configuration of the job
- Dependencies required to execute the job, e.g. JAR files, Python dependencies, etc
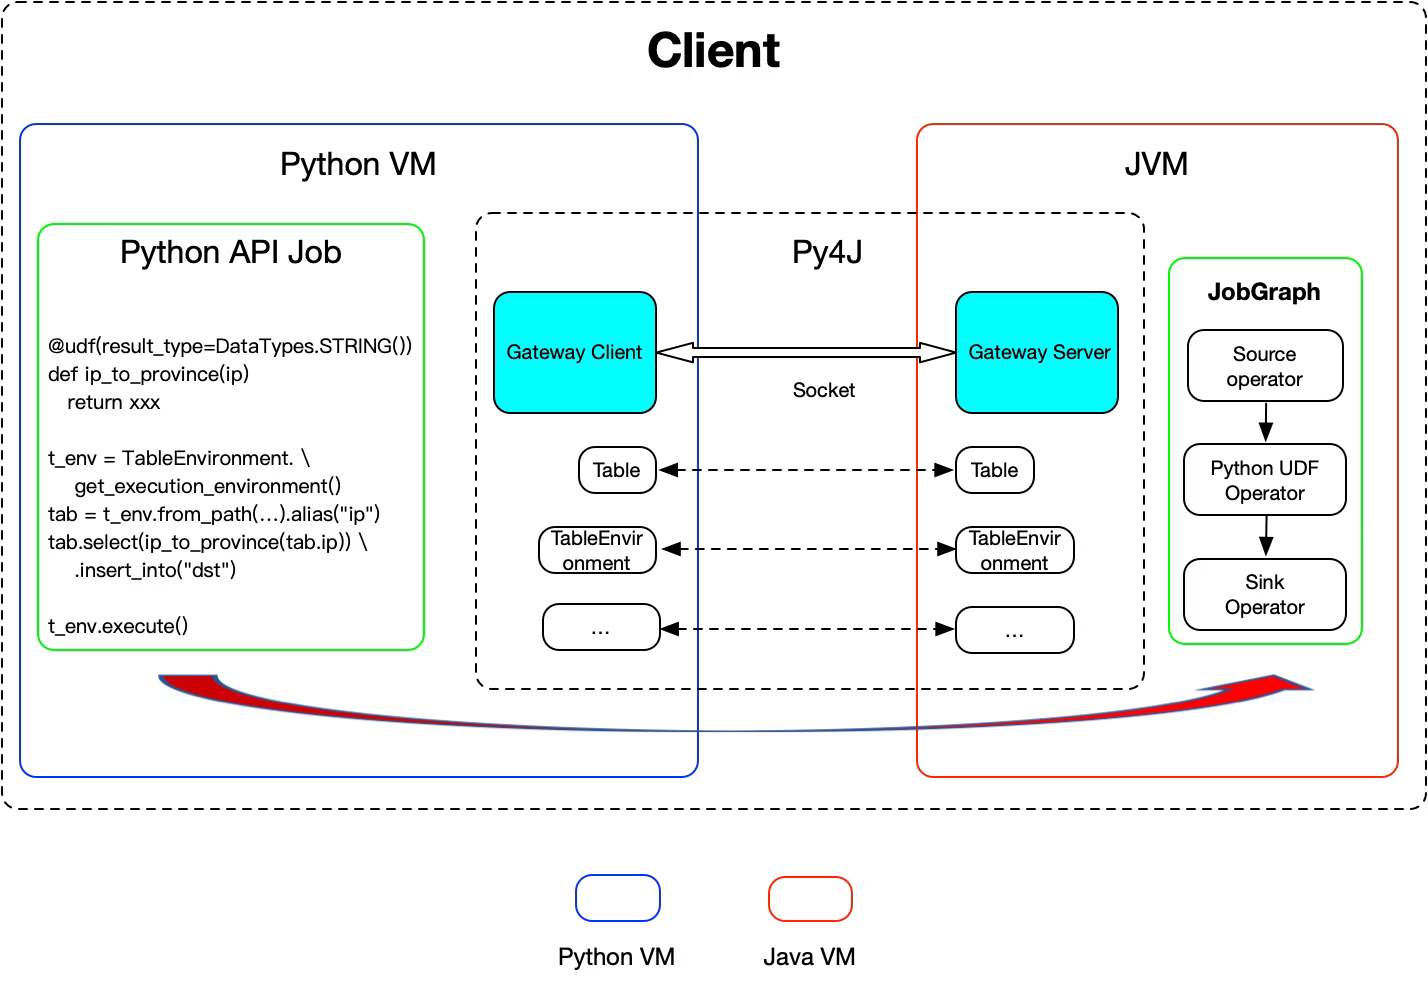
At present, there is no multiple language support for JobGraph, which only supports Java. PyFlink reuses the existing job compiling stack of the Java API by leveraging [Py4J](https://www.py4j.org/) to enable Python programs running in a Python process to access the Java objects in a JVM.
Methods are called as if the Java objects resided in the Python process. Each Java API is wrapped by a corresponding Python API. When a Python program makes a PyFlink API call the corresponding Java object is created in the JVM and the method is called on it.
Internally it will create a corresponding Java object in JVM and then call the corresponding API on the Java object. So it reuses the same job compiling stack as the Java API.
This means that:
- If you use the PyFlink Table API but execute only Java code the performance should be just the same as the Java Table API
- If there is a Java class you want to use, e.g. custom connectors, that is not yet supported in PyFlink, you can just wrap it yourself
### Job execution
Mostly, wrapping the Java API works well. However, there are some exceptional cases. Let’s look at the following example:
```bash
source = KafkaSource.builder() \
.set_bootstrap_servers("localhost:9092") \
.set_topics("input-topic") \
.set_group_id("my-group") \
.set_starting_offsets(KafkaOffsetsInitializer.earliest()) \
.set_value_only_deserializer(
JsonRowDeserializationSchema.builder()
.type_info(Types.ROW([Types.LONG(), Types.STRING()]))
.build()) \
.build()
env = StreamExecutionEnvironment.get_execution_environment()
ds = env.from_source(source, WatermarkStrategy.no_watermarks(), "Kafka Source")
ds.map(lambda x: x[1]).print()
env.execute()
```
Here, all the Python methods can be mapped to Flink’s Java API except for **map()** which passes a lambda function **ds.map(lambda x: x[1])**. Java expects a Java MapFunction. To make this work in Java, we need to serialize **lambda x: x[1]** and wrap it with a Java wrapper object that spawns a Python process to execute it during job execution.
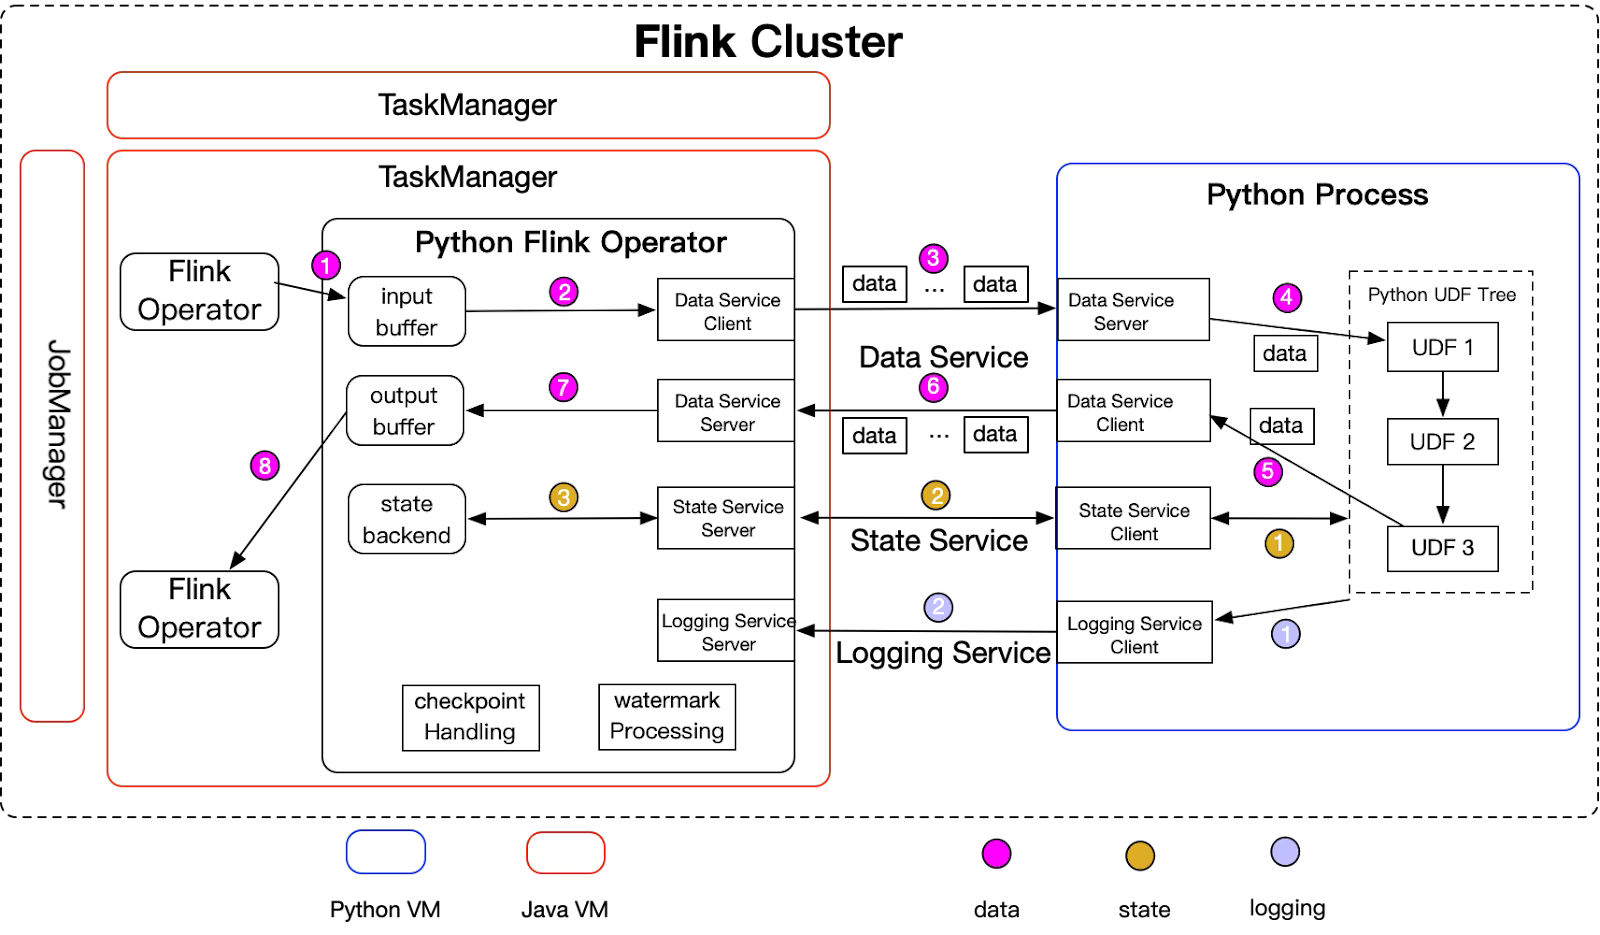
### Flink and PyFlink Operators
During execution, a Flink job is composed of a series of Flink operators. Each operator accepts inputs from upstream operators, transforms them and produces outputs to the downstream operators. For transformations where the processing logic is Python, a specific Python operator will be generated:
- During initialization phase, the operator will spawn a Python process and send the metadata i.e. the Python functions to be executed, to the Python process
- After receiving data from upstream operators, the operator will send it to the Python process for execution. The data is sent to the Python process asynchronously; the operator doesn’t wait to receive the execution results for one data item before sending the next one.
- The operator supports access to the Python state, but the Python operator runs in the JVM. Unlike data communication, state access is synchronous. The state may be cached in the Python process to improve the performance.
- The Python operator also supports the use of logging in the Python functions. The logging messages are sent to the Python operator which runs in the JVM, and so the messages will finally appear in the log file of the TaskManagers.
Note that:
- The Python functions will be serialized during job compiling and deserialized during job execution. Keep resource usage light (see the notes on using open() above), and only use instance variables that are serializable.
- Multiple Python functions will be chained where possible to avoid unnecessary serialization/deserialization as well as communication overhead.
### Thread Mode
Launching Python functions in a separate process works well in most cases, but again there are some exceptional cases:
- The additional serialization/deserialization and communication overhead can be a problem with large data e.g. image processing where the image size may be very large, long strings, etc.
- Inter-process communication also means the latency may be higher. Additionally the Python operator usually needs to buffer data to improve the network performance which adds more latency.
- The extra process and inter-process communication creates challenges for stability.
To address these problems, Flink 1.15 thread mode is introduced as an option for executing Python functions in the JVM. By default thread mode is disabled; to use it, configure **python.execution-mode: thread**.
With thread mode enabled, Python functions are executed very differently than in process mode:
- Data is processed one row at a time which increases latency.
- But, serialization/deserialization and communication overhead are removed.
Note that thread mode has specific limitations, which is why it’s not enabled by default:
- It only supports the CPython interpreter because it depends on the CPython runtime to execute Python functions.
- Because the CPython runtime can only be loaded once in a process, thread mode doesn’t support session mode well, where multiple jobs may need to use separate Python interpreters
See the blog post [Exploring the thread mode in PyFlink](https://flink.apache.org/2022/05/06/pyflink-1.15-thread-mode.html) for more details about thread mode.
### State Access & Checkpoint
State access is supported for Python functions. This example uses state to calculate the average value of each group:
```python
from pyflink.common.typeinfo import Types
from pyflink.datastream import StreamExecutionEnvironment, RuntimeContext, MapFunction
from pyflink.datastream.state import ValueStateDescriptor
class Average(MapFunction):
def __init__(self):
self.sum_state = None
self.cnt_state = None
def open(self, runtime_context: RuntimeContext):
self.sum_state = runtime_context.get_state(ValueStateDescriptor("sum", Types.INT()))
self.cnt_state = runtime_context.get_state(ValueStateDescriptor("cnt", Types.INT()))
def map(self, value):
# access the state value
sum = self.sum_state.value()
if sum is None:
sum = 0
cnt = self.cnt_state.value()
if cnt is None:
cnt = 0
sum += value[1]
cnt += 1
# update the state
self.sum_state.update(sum)
self.cnt_state.update(cnt)
return value[0], sum / cnt
env = StreamExecutionEnvironment.get_execution_environment()
env.from_collection([(1, 3), (1, 5), (1, 7), (2, 4), (2, 2)]) \
.key_by(lambda row: row[0]) \
.map(Average()) \
.print()
env.execute()
```
Here both **sum_state** and **cnt_state** are PyFlink state objects. States can be accessed during job execution and also recovered after job failover:
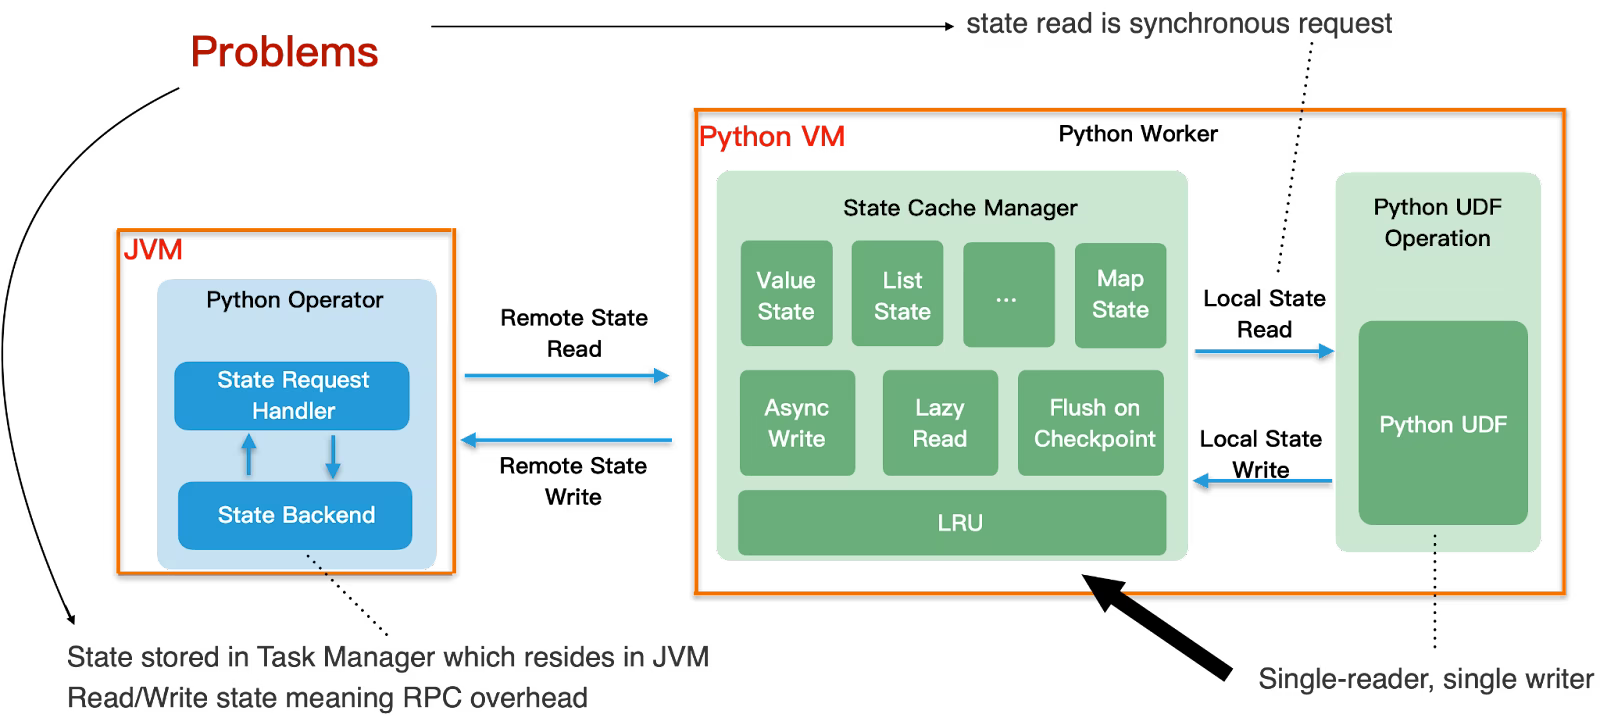
From the above diagram, we can see that:
- The source of truth for state is the Python Operator running in the JVM
- State access is synchronous from the user perspective
The following optimizations have been introduced to improve the performance of state access:
- Async write: Maintains a LRU cache of the latest states and state modifications which is written back to the Python Operator asynchronously
- Lazy read: As well as the LRU cache, MapState is read lazily to avoid unnecessary state requests
### Performance Tuning
In general tuning PyFlink jobs is the same as tuning Flink Java jobs. One exception is tuning Python operator performance.
### Memory Tuning
Python operators launch a separate Python process to execute Python functions. Python functions that depend on large resources can potentially occupy a lot of memory.If too little memory is configured for the Python process then the stability of the job will be affected.
If a PyFlink job is run in a Kubernetes or Apache YARN deployment which strictly limits memory usage, the Python process may crash because its memory requirement exceeds the limit.
You need to design your Python code carefully. Additionally, use the following configuration options to help tune Python memory usage:
- [taskmanager.memory.process.size](https://nightlies.apache.org/flink/flink-docs-stable/docs/deployment/config/#taskmanager-memory-process-size): Total process memory size for the TaskExecutors.
- [taskmanager.memory.managed.fraction](https://nightlies.apache.org/flink/flink-docs-stable/docs/deployment/config/#taskmanager-memory-managed-fraction): Fraction of total memory to be used as managed memory. (Memory of Python process is also part of managed memory)
- [taskmanager.memory.jvm-overhead.fraction](https://nightlies.apache.org/flink/flink-docs-stable/docs/deployment/config/#taskmanager-memory-jvm-overhead-fraction): Fraction of total memory to be reserved for JVM Overhead. (Reserved memory which is not used explicitly)
- [taskmanager.memory.managed.consumer-weights](https://nightlies.apache.org/flink/flink-docs-stable/docs/deployment/config/#taskmanager-memory-managed-consumer-weights): Managed memory weights for different kinds of consumers. This configuration can be used to adjust the fraction of managed memory allocated to the Python process.
### Bundle Size
In process mode, the Python operator sends data to the Python process in batches. To improve network performance it buffers data before sending it.t.
During a checkpoint, it must wait before all the buffered data is processed. If there are many elements in a batch and the Python processing logic is inefficient then the checkpoint time will be extended. If you notice very long or even failed checkpoints, try tuning the bundle size configuration [python.fn-execution.bundle.size](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/python/python_config/#python-fn-execution-bundle-size).
### Execution Mode
Thread mode can improve performance in cases where the data size is large or when you need to reduce latency. Set configuration **python.execution-mode: thread** to enable it.
## What’s Next for PyFlink
PyFlink already has rich functionality. In the next phase of its evolution the community focus will be on:
- Better support for interactive programing, e.g. retrieving only the few leading rows of an unbounded table.
- Improved ease of use, e.g. make the API more Pythonic, improve the documentation, and add more examples.
---
---
title: "Stream Processing Scalability: Challenges and Solutions"
description: "Discover the challenges and solutions in developing stream processing systems and how Ververica's Platform and Cloud can simplify the process."
lastUpdated: 2026-05-12T11:00:12.000Z
source_url:
html: "https://www.ververica.com/blog/stream-processing-scalability-challenges-and-solutions"
md: "https://www.ververica.com/blog/stream-processing-scalability-challenges-and-solutions.md"
---
## What is Stream Processing
Stream processing is a programming paradigm which views data streams, or sequences of events in time, as the central input and output objects of computation.
This enables organizations to harness the value of data immediately, making it a valuable tool for time-sensitive applications and scenarios requiring up-to-the-minute insights. Stream processing systems excel at handling high-velocity, unbounded data streams, such as click streams, log streams, live sensor data, social media feeds, event streams, transactional data, and IoT device data.
## Why Stream Processing?
Organizations are constantly striving to extract timely and actionable insights from their data to gain a competitive edge. Traditional data pipelines, based on batch processing, have long been the go-to approach for data integration and analysis. However, with the increasing demand for real-time insights, companies are now shifting towards stream processing.
### Real-Time Insights for Enhanced Decision-Making
A key motivation for companies to embrace stream processing is the ability to obtain real-time insights. Traditional batch processing pipelines operate on static datasets, which may lead to delays in data analysis. Conversely, stream processing allows organizations to both process data and analyze data as it arrives, enabling immediate access to up-to-the-minute insights. This capability enhances decision-making processes, enabling organizations to respond swiftly to changing market conditions, customer demands, and emerging opportunities.
### Improved Operational Agility
Stream processing offers unparalleled operational agility, allowing organizations to react swiftly to critical events and anomalies. By continuously processing and analyzing data in real-time, companies can identify patterns, trends, and anomalies as they occur, thus enabling proactive decision-making. Additionally, real-time monitoring and alerting mechanisms provided by stream processing systems enable organizations to promptly detect and respond to operational issues, fraud attempts, security breaches, and other time-critical events, consequently minimizing potential damages and optimizing operational efficiency.
### Enhanced Customer Experience
In today's fast-paced digital landscape, delivering exceptional customer experiences is paramount. Stream processing enables organizations to personalize and customize interactions with customers in real-time. By analyzing customer data as it flows, companies can gain deeper insights into customer behavior, preferences, and needs, allowing for personalized recommendations, targeted promotions, and optimized customer journeys. This level of real-time engagement and personalization helps drive customer satisfaction, loyalty, and ultimately, business growth.
### Seamless Integration with Modern Technologies
Stream processing seamlessly integrates with modern technologies such as Internet of Things (IoT), real-time analytics, and machine learning. As organizations embrace IoT devices and generate massive amounts of sensor data, stream processing is therefore crucial for real-time data ingestion, analysis, and decision-making. Moreover, stream processing systems serve as a foundation for implementing advanced analytics techniques, such as real-time predictive modeling, anomaly detection, and sentiment analysis. This convergence of stream processing with cutting-edge technologies empowers companies to unlock the full potential of their data assets.
## Challenges in Developing Stream Processing Systems
Good streaming processing systems may be difficult to develop, thus we have highlighted the main challenges below:
### Fault Tolerance and Resilience
Stream processing systems must exhibit fault tolerance to withstand failures and disruptions. However, achieving fault tolerance in real-time environments is challenging due to the constant flow of data and stringent latency requirements. Implementing fault tolerance mechanisms, such as replication, state management, and checkpointing, is crucial for maintaining data integrity and system availability. Ensuring resilience in the face of failures, network issues, or hardware malfunctions is essential to prevent data loss, maintain consistent processing, and provide uninterrupted insights to downstream applications.
### Scalability and Handling Data Volume
Stream processing systems need to handle ever-increasing data volumes while ensuring optimal performance. As data volume grows, the system must scale horizontally to accommodate the load. However, scaling a stream processing system introduces its own challenges. Distributing the workload across multiple processing nodes and managing the dynamic allocation of resources require careful design and implementation. Efficient load balancing, adaptive resource allocation, and parallel processing techniques are vital to achieving scalability without compromising data accuracy or processing speed.
### Dynamic Workload Management
Stream processing systems often experience fluctuating workloads due to varying data arrival rates or bursty traffic. Handling such dynamic workloads is crucial for maintaining system stability and performance. Effective workload management strategies, such as load shedding, backpressure, or dynamic resource allocation, are essential to balance the system's processing capacity with the incoming data flow. Proactive monitoring, adaptive buffering, and intelligent workload distribution mechanisms help ensure reliable and efficient data processing in the face of workload variations.
### Network and Communication Challenges
Stream processing systems operate in distributed environments, often spanning multiple nodes or clusters. Ensuring reliable communication and continuous data transfer across the network is crucial for fault tolerance, scalability, and reliability. Challenges such as network congestion, latency, or communication failures can significantly impact system performance and data integrity. Implementing robust network protocols, efficient data serialization techniques, and fault-tolerant data transfer mechanisms mitigate these challenges and ensure seamless communication between components.
### State Management and Recovery
Stream processing systems often rely on maintaining state for processing real-time streaming data. Managing and recovering state in the event of failures or system restarts is a critical challenge. Stateful stream processing introduces complexities such as consistency, durability, and fault recovery. Implementing reliable state management mechanisms, such as durable storage, distributed snapshots, or event sourcing, ensures that the system can recover state and resume processing from the last known consistent checkpoint, minimizing data loss, and maintaining system reliability.
### Monitoring and Observability
Monitoring the health, performance, and behavior of a stream processing system is crucial for maintaining fault tolerance, scalability, and reliability. Effective monitoring and observability enable proactive detection of anomalies, performance bottlenecks, or resource constraints. Incorporating monitoring tools, logging frameworks, and real-time analytics of system metrics and logs into streaming data architecture allows organizations to identify and address issues promptly, ensuring system stability and reliability.
## Ververica’s Solutions
### Ververica Platform
[Ververica Platform](https://www.ververica.com/platform), a leading Flink-based stream processing platform, offers a comprehensive set of features and capabilities that make it an excellent choice for organizations looking to harness the power of real-time data analytics.
Ververica Platform is based on Apache Flink®, an open-source data streaming engine that has become an industry standard for stream processing, used by tech giants such as **Uber, Ebay**, **Alibaba**, top financial institutions, and more. While based on Apache Flink®, it operates with significantly faster speed and better performance than the open-source Apache Flink®, but maintaining full compatibility with it.
Ververica Platform delivers high-throughput and low-latency stream processing solutions, as well as these leading features:
- Stream Processing SimplicityVerverica Platform simplifies the complexities associated with stream processing. With its user-friendly interface and intuitive design, organizations can easily develop, deploy, and manage stream processing applications without the need for extensive expertise in distributed systems or complex programming. The platform provides a visual interface for developing and monitoring streaming workflows, making it easy to use by all engineers, developers and architects
- Scalability and ElasticityVerverica Platform is a market leader in handling large-scale stream processing workloads. It leverages Apache Flink, and extends it with additional capabilities for scalability and elasticity. The platform allows organizations to dynamically scale their processing clusters based on workload demands, ensuring high throughput and low latency even as raw data volumes grow significantly. This scalability feature is particularly valuable in scenarios where real-time processing of massive data streams is required.
- Fault Tolerance and High AvailabilityVerverica Platform incorporates robust fault tolerance mechanisms, which are crucial for maintaining data integrity and ensuring uninterrupted processing. It leverages the fault tolerance features inherent in Apache Flink, including checkpointing and stateful recovery, to handle failures and system disruptions effectively. By providing high availability and seamless fault recovery, the platform virtually eliminates data loss and guarantees reliable stream processing in the face of unexpected events.
- Advanced Stream Processing CapabilitiesVerverica Platform has advanced features and capabilities that enhance stream processing workflows. It provides support for event time-based operations, allowing organizations to handle out-of-order events and perform time-based aggregations accurately. The platform also facilitates complex event processing with its ability to handle patterns, enrichments, and real-time analytics. These capabilities enable organizations to extract meaningful insights from streaming event data and drive actionable outcomes.
- Integration and Ecosystem CompatibilityVerverica Platform seamlessly integrates with various data sources, messaging systems, and storage systems commonly used in the data ecosystem. It provides connectors and integrations with popular technologies like Apache Kafka®, Amazon Kinesis®, and more, enabling organizations to leverage their existing data warehouse infrastructure. This compatibility allows for easy integration and interoperability, reducing the complexities of data ingestion and enabling smooth data flow into the stream processing pipelines.
- Monitoring and ObservabilityVerverica Platform emphasizes comprehensive monitoring and observability capabilities, critical for ensuring the health and performance of stream processing applications. It offers real-time monitoring dashboards and metrics, enabling organizations to gain insights into the state and behavior of their streaming workflows. With detailed logging, alerting, and visualization features, the platform facilitates proactive monitoring and troubleshooting, empowering organizations to detect and address issues immediately.
- Enterprise-Grade Security and ComplianceVerverica Platform prioritizes security and compliance, making it suitable for enterprise-level deployments. The platform provides robust security measures, including authentication, authorization, and encryption, to protect sensitive data and ensure compliance with regulatory requirements. Organizations can confidently deploy stream processing applications on the platform, knowing that their data is secure and their operations align with industry standards.
### Ververica Cloud
Ververica Cloud is a high-performance, Flink-based cloud-native service for real-time data processing. It democratizes stream processing, making it accessible to all engineers, developers, and architects in companies, big and small. It also maintains full compatibility with open-source Apache Flink, while offering superior performance.
Ververica Cloud offers all the benefits of Ververica Platform. What is more:
- Ververica Cloud is fully managed. It is a ready-to-use cloud platform with no complex infrastructure set-up, just log in and build your streaming application.
- Ververica Cloud is cloud native. With Ververica Cloud, you can easily deploy and manage your data streaming applications on the cloud, and take advantage of the scalability, flexibility, and cost savings that cloud deployment offers.
- Ververica Cloud has even higher performance than Ververica Platform.
- The Ververica team is working hard to add unique new features to Ververica Cloud.
This is a glance of Ververica Cloud’s architecture:
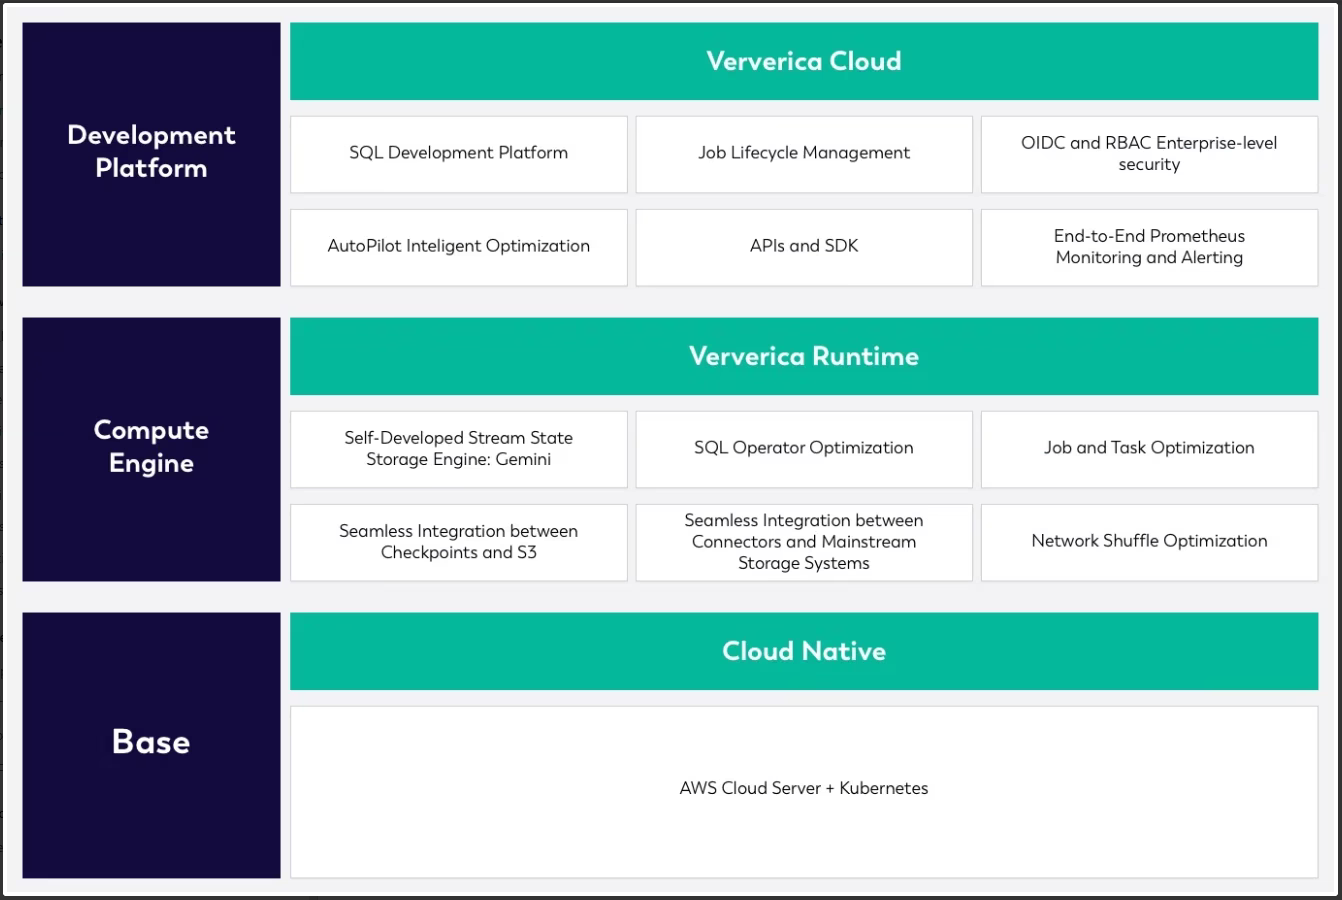
## Example
A shipping service company, codenamed as SuperFast, wants to develop a new feature in their application to show the users how many stops the delivery is away from the final destination.
At a high level, SuperFast needs to reason the number of remaining stops per package from the information about shipping events and shipping routes, and then send updates about the number of remaining stops to the downstream application which would show the information to the customers.
If they try to develop a stream processing system for this use case from ground up and run it in production, they are likely to face some, or all the challenges, that were discussed earlier.
We will show you how it can be done in Ververica Cloud using Flink SQL.
### Solve it with Ververica Cloud - the SQL way!
Let us analyze some foundational information briefly:
1. Each package has a unique tracking number;
1. Each package is assigned a shipping route;
1. Each shipping route has a list of ordered stops;
1. Each stop has an ID, which is a unique sequence number in its route;
1. We can calculate the number of remaining stops for a package by taking the difference between the end stop ID and the current stop ID;
1. Each shipping event is an event about a package;
1. All events feed into SuperFast’s shipping system as event streams;
1. The package tracking system that we are developing is called SuperFastPTS.
SuperFastPTS will consume events from a stream and output into another stream to be consumed by downstream applications.
In this solution, we will abstract all streams into virtual tables, so that we can handle them in SQL.
#### Abstracting a Stream
Suppose that the shipping event information is to be consumed from an Amazon Kinesis stream (it can be from Kafka or any data sources that are supported by Ververica Cloud as well). We will abstract it into a table named ShipEvent as the following:
```sql
CREATE TABLE `ShipEvent` (
`trackingNumber` BIGINT,
`occurredAt` TIMESTAMP(3),
`eventCode` STRING,
`statusCode` STRING,
`statusDescription` STRING,
`carrierCode` STRING,
`country` STRING,
`state` STRING,
`city` STRING,
`postalCode` STRING,
`currentStopId` INT
)
WITH (
'connector' = 'kinesis',
'stream' = 'us-w-ShipEvent',
'aws.region' = 'us-west-1',
'format' = 'csv'
);
```
Brief procedure in Ververica Cloud:
In the Ververica Cloud workspace:
1. Open the SQL Editor;
1. Create a new script;
1. Write the CREATE TABLE statement in the script and save it;
1. Execute the statement;
1. This abstracts the stream into the table ShipEvent so that we can use it in Flink SQL queries.
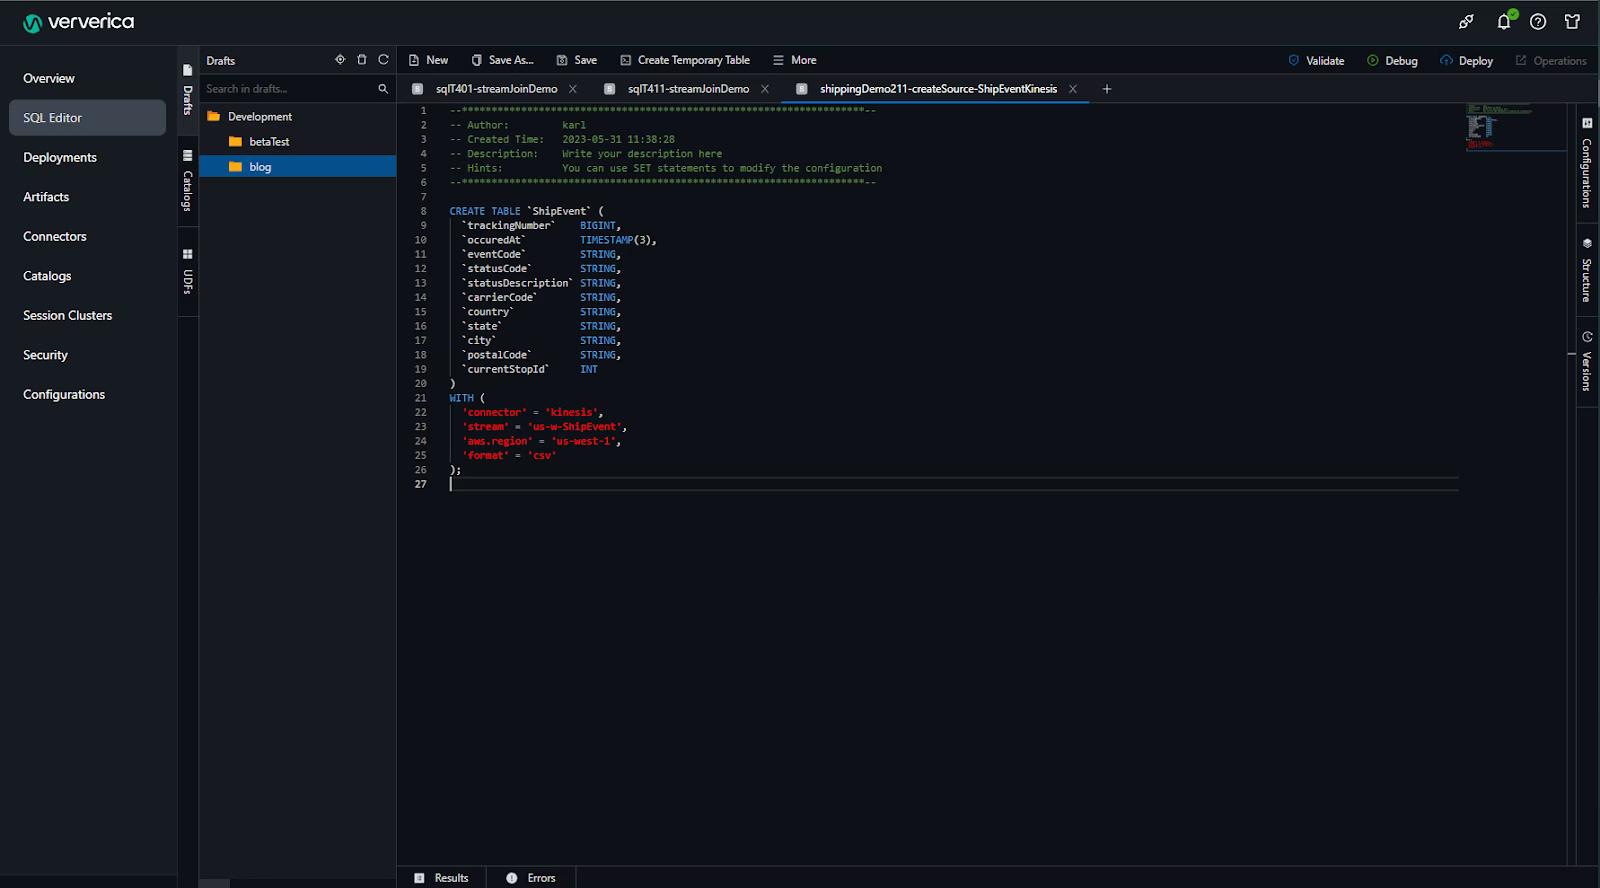
#### Defining the Stream Processing Job in SQL
Assume that the shipping route information is in an existing table. It may be backed by an external database table or another stream. The (simplified) table structure is illustrated by the following SQL query:
```sql
CREATE TABLE `ShipRoute` (
`routeId` BIGINT,
`trackingNumber` BIGINT,
`endStopId` INT
)
WITH (
-- Details are skipped.
);
```
We can then find the number of remaining stops per package and write the results into an output table which is named “Report”, by the following query. The Report table is an abstraction of another stream (just like ShipEvent) which would be consumed by the downstream application to deliver the updates. Each record in the Report contains:
- A package tracking number
- The number of remaining stops of the package
- The time when it occurred
```sql
INSERT INTO Report
SELECT e.trackingNumber, e.occurredAt, (r.endStopId - e.currentStopId) AS numberOfRemainingStops
FROM ShipEvent e
JOIN ShipRoute r ON e.trackingNumber = r.trackingNumber
GROUP BY e.trackingNumber;
```
Brief procedure in Ververica Cloud:
In the same Ververica Cloud SQL Editor:
1. Create a new script;
1. Write the above query in the script and save it;
1. Click the Deploy button;
1. A deploy dialog will guide you to deploy the query as a job.
We have now deployed a stream processing job which consumes certain streams (ShipEvent) and outputs to another stream (Report).
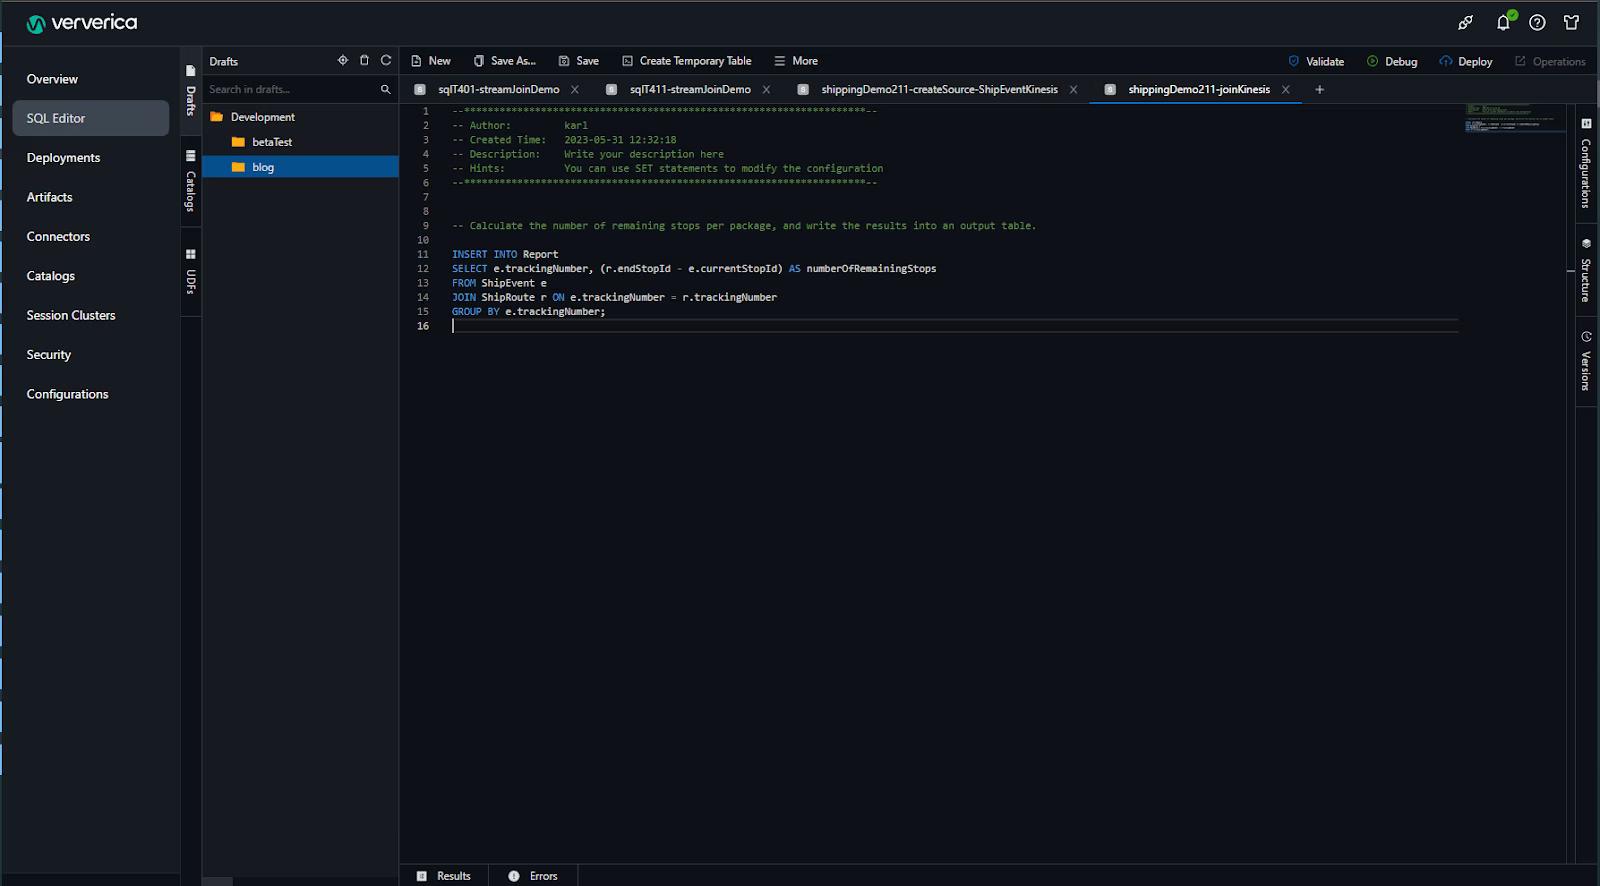
As SuperFastPTS is expected to process high volumes of data with low latency, it needs to distribute the workload into a number of computing nodes for efficient parallel processing and aggregate the partial results from those nodes together. In such a distributed system, failure is the norm, and therefore consistency and fault tolerance must be considered into the system design.
- What if some sub tasks fail?
- What if some computing nodes fail?
- What if a whole computer cluster fails?
Ververica Cloud covers all those complexities and heavy-lifting automatically. So the SuperFast team can develop and release new features quickly in SQL or other programming languages of their choice.
#### Consistency and Fault Tolerance
In order to ensure their service reliability, the SuperFast team defined their requirements of consistency and fault tolerance. Then they can meet the requirements simply by configuring the job parameters for checkpointing, state expiration, and restart policy in Ververica Cloud.
#### Scaling Up
As SuperFast’s business continued to grow, so did the data volume and system workload. They need more computing power to keep the SuperFastPTS fast and efficient.
With Ververica Cloud, they just needed to configure the resources for the streaming jobs according to their workload. And Ververica Cloud will manage the underlying infrastructure properly.
#### Managing and Monitoring the Jobs
To start the job:
1. Click “Deployments” from the left menu to go to the Deployments page;
1. The new SQL deployment should appear at the top of the deployment list;
1. Click the “Start” button on the right to run the job.
The SuperFast team can use Ververica Cloud to manage the whole lifecycle of their deployments. For example, Ververica Cloud has a built-in graphical user interface to monitor the metrics of the deployments, as seen below.
As you can see Veverica Cloud greatly simplifies the development and management of stream processing applications, handling the complexity so that you can focus on your business.
For more detailed instructions on how to use Ververica Cloud, you may view [Ververica Cloud documentation](https://docs.ververica.cloud/guide/basics/intro.html).
---
---
title: "Joining Highly Skewed Streams in Flink SQL"
description: "Learn how to handle data skews in stream joining for aggregation-related cases with Flink SQL. Discover potential solutions and how to implement them."
lastUpdated: 2026-05-12T11:19:10.000Z
source_url:
html: "https://www.ververica.com/blog/joining-highly-skewed-streams-in-flink-sql"
md: "https://www.ververica.com/blog/joining-highly-skewed-streams-in-flink-sql.md"
---
Flink SQL is a powerful tool which unifies batch and stream processing. It provides low-code data analytics while complying with the SQL standard.
In production systems, our customers found that as the workload scales, the SQL jobs that used to work well may slow down significantly, or even fail. And data skews is a common and important reason.
Data skew refers to the asymmetry of the probability distribution of a variable about its mean. In other words, the data is unevenly distributed in terms of some attributes. This article discusses and analyzes the implications of data skews to stream joining for aggregation-related cases, and the potential solutions.
If you are new to this field, or interested in learning more about Flink or Flink SQL, please check out the Related Information at the end of this article too.
## Joining with a Stream Having Key Skews
Consider the following scenario: we have a Users table which contains information about users of some business application. And we have a GenOrders table which contains information about orders (buy/sell something). We would like to know the number of orders per user in the Users table. The (simplified) query may look like the following:
```sql
CREATE TABLE `Users` (
`uid` BIGINT,
`name` STRING,
`country` STRING,
`zcode` STRING
)
WITH (
-- Details are skipped.
);
CREATE TEMPORARY TABLE `GenOrders` (
`uid` BIGINT,
`oid` BIGINT,
`category` STRING,
`price` DECIMAL(3, 2)
)
COMMENT ''
WITH (
'connector' = 'datagen',
'fields.price.max' = '99',
'fields.price.min' = '1',
'rows-per-second' = '1',
'number-of-rows' = '100000'
);
SELECT o.uid, COUNT(o.oid)
FROM GenOrders o
JOIN Users u ON o.uid = u.uid
GROUP BY o.uid;
```
In the context of stream joining, it is important to understand that both tables represent continuous flows of information. In Flink, aggregations (such as COUNT and SUM) are performed by aggregation operators. An aggregation operator is a stateful operator, which stores the intermediate aggregate results in its state. By default, the streaming aggregation operators process input records one by one. When a record comes in, the operator goes through the following steps: (1) retrieve the accumulator from the state, (2) accumulate/retract the record to the accumulator, and (3) store the accumulator back to the state.
Each read/write of the state comes with a certain cost.
### Data Skew
And in large scale Flink applications, the streams are often divided based on specific keys, and distributed into multiple tasks for parallel processing. We refer to such a key as a “Grouping Key”. If the distribution of records is uneven, then some tasks would be heavier than others. And the heavier tasks take longer to complete, and can potentially become the bottlenecks of the data pipeline. When this happens, we say that the data is **skewed**. Furthermore, if the data is distributed based on some keys, we refer to it as “**key skew**”.
For the above use case, we can distribute the records by user ID to aggregation tasks for parallel processing. Since we are looking for the number of orders per user, it makes sense to group the data by user ID.
In the graph below, we use colors to indicate data records for different users. We can see that the Red user has 8 records, which is considerably more than other users’. In this case, we say that the data is skewed on user ID. If we distributed the data by user ID, the top aggregation task which processes Red records, would process more data, and would likely take longer than others.
How to deal with it?
### MiniBatch Aggregation
MiniBatch Aggregation puts the input records into a buffer and does the aggregation operation after the buffer is full or after some time. This way, the records with the same key value (value for the key) in the buffer are processed together, so we only have one state write per key value per batch.
MiniBatch Aggregation boosts the throughput as aggregation operators have fewer state accesses, and output fewer records, especially when there are retraction messages and the performance of downstream operators is suboptimal.
The following graph demonstrates it.
We can use the following options to implement it:
```bash
table.exec.mini-batch.enabled: true # Enable mini-batch
table.exec.mini-batch.allow-latency: 5s # Put the records into a buffer and do an aggregation within 5 seconds
table.exec.mini-batch.size: 10000 # [Optional] The maximal number of input records that can be buffered for MiniBatch
```
> **CAUTION:** Caution: The downside of MiniBatch is that it increases latency, because the aggregation operators start processing the records when the buffer is full or when the buffer times out, rather than processing them immediately.
#### How to implement it in Ververica Platform
To learn how to create and deploy Flink SQL jobs in Ververica Platform, please go to [Getting Started - Flink SQL on Ververica Platform](https://docs.ververica.com/getting_started/sql_development.html) in [Ververica Platform Documentation](https://docs.ververica.com/index.html).
To implement the discussed techniques in Ververica Platform Web UI,
1. Go to **Deployments**
1. Click the job that you would like to apply the techniques to
1. Click **Configure** button
1. Click **Advanced** tab
1. Set the options in **Additional Configuration**
### Local/Global Aggregation
In the above example, the first aggregation task (also known as the “hot” task) processes more data than the other, because of the key skew, and becomes a bottleneck. If each upstream task can aggregate the records for each key value before sending them to the aggregation tasks, then the aggregation tasks will receive much fewer records per key value, and thus reduce the load of the “hot” task. This technique is called Local/Global Aggregation.
The following graph demonstrates it.
We do not maintain state for the local aggregations, so that we can avoid the cost of the state accesses there, and bear the cost only in global aggregations.
We can use the following options to implement it together with MiniBatch:
```bash
table.exec.mini-batch.enabled: true # enable mini-batch
table.exec.mini-batch.allow-latency: 5s # put the records into a buffer and do an aggregation within 5 seconds
table.optimizer.agg-phase-strategy: TWO_PHASE/AUTO # enable Local/Global Aggregation
```
> **NOTE:** Note: All aggregation functions in a query must implement the merge method in order for the query to leverage Local/Global Aggregation. Many built-in functions support Local/Global Aggregation, such as COUNT, MAX, MIN, SUM and AVG.
### Joining with a Stream Having Distinct Key Skews
Consider the same Users table and GenOrders table, this time we would like to know the number of distinct categories for each user. The (simplified) query may look like the following:
```sql
CREATE TABLE `Users` (
`uid` BIGINT,
`name` STRING
)
WITH (
-- Details are skipped.
);
CREATE TEMPORARY TABLE `GenOrders` (
`uid` BIGINT,
`oid` BIGINT,
`category` STRING,
`price` DECIMAL(3, 2)
)
COMMENT ''
WITH (
'connector' = 'datagen',
'fields.price.max' = '99',
'fields.price.min' = '1',
'rows-per-second' = '1',
'number-of-rows' = '100000'
);
SELECT o.uid, COUNT(DISTINCT o.category)
FROM GenOrders o
JOIN Users u ON o.uid = u.uid
GROUP BY o.uid;
```
If we have many distinct values for the user-category combination, then some aggregation tasks may produce many records. We refer to it as “**distinct key skew**”.
The following graph demonstrates it.
And Local/Global Aggregation cannot solve this problem. How to deal with it?
### Split Distinct Aggregation
We can split the aggregation into two phases. First, we divide the records into buckets, based on the grouping key and a bucket key. The bucket key is the hash code of the distinct key modulo the number of buckets, i.e.
Bucket_Key = HASH_CODE(distinct_key) % NUMBER_OF_BUCKETS
Then we aggregate each bucket in parallel into partial results (first phase aggregation / **partial aggregation**). We divide the partial results based on the grouping key, and aggregate them into final results (second phase aggregation / **final aggregation**). This technique is called Split Distinct Aggregation.
The following graph demonstrates it.
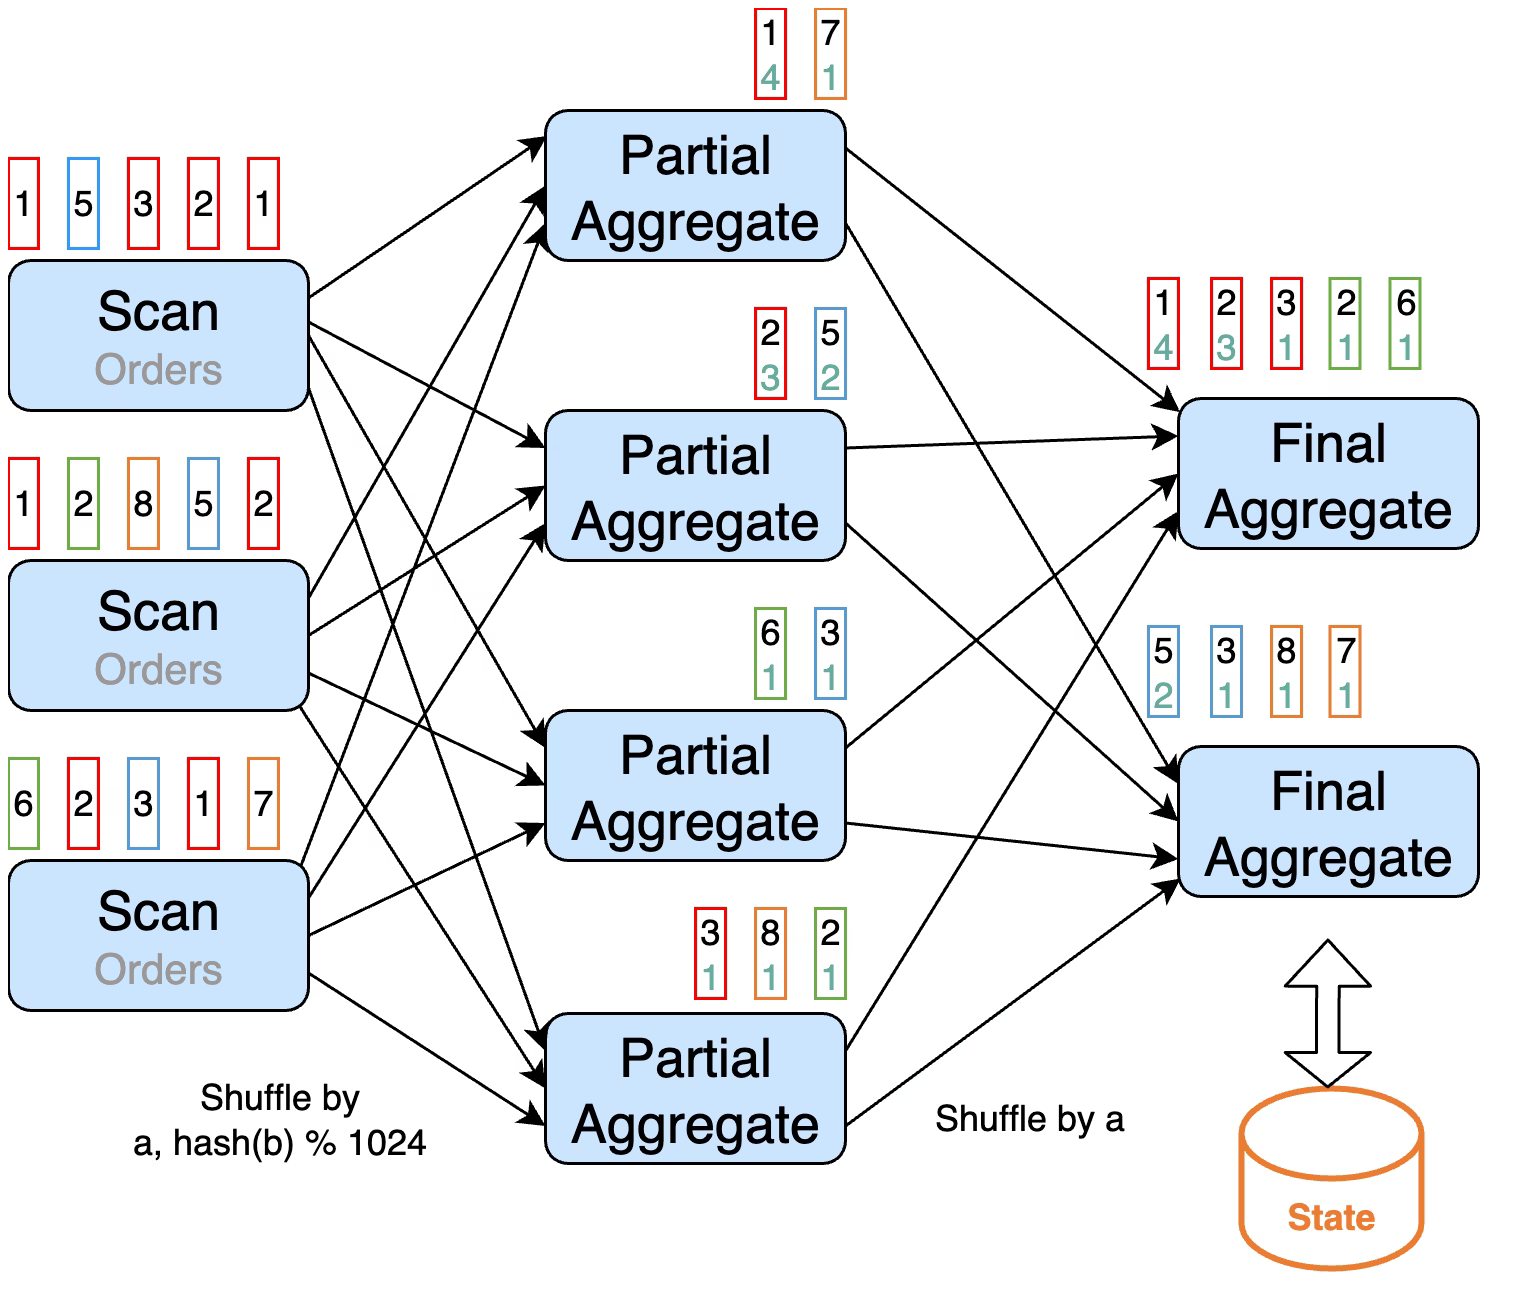
We can use the following options to implement it:
```bash
table.optimizer.distinct-agg.split.enabled: true # enable Split Distinct Aggregation
table.optimizer.distinct-agg.split.bucket-num: 1024 # number of bucket
```
> **NOTE:** Note: All aggregate functions in the query must be built-in aggregation functions and must be splittable, e.g. AVG, SUM, COUNT, MAX, MIN, in order for the query to leverage Split Distinct Aggregation.
> **CAUTION:** Caution: Split Distinct Aggregation has the overhead of state access and stream shuffling for the partial aggregation. Hence we do not recommend it if there is no distinct key skew or when the input data set is small.
### Incremental Aggregation
The state for partial aggregations can potentially become large because of distinct key skews. One solution for that is to have three phases of aggregations. First, each upstream task does a local aggregation for each distinct key value. No state is maintained for local aggregations. Those results are divided by grouping key and bucket key, and sent to the second phase aggregation (called incremental aggregation). Incremental aggregation only stores the distinct keys in its state. The results of incremental aggregation are divided by grouping key, and sent to the third phase aggregation (final aggregation), which keeps the aggregation function values in the state.
This technique is called Incremental Aggregation.
The following graph demonstrates it.
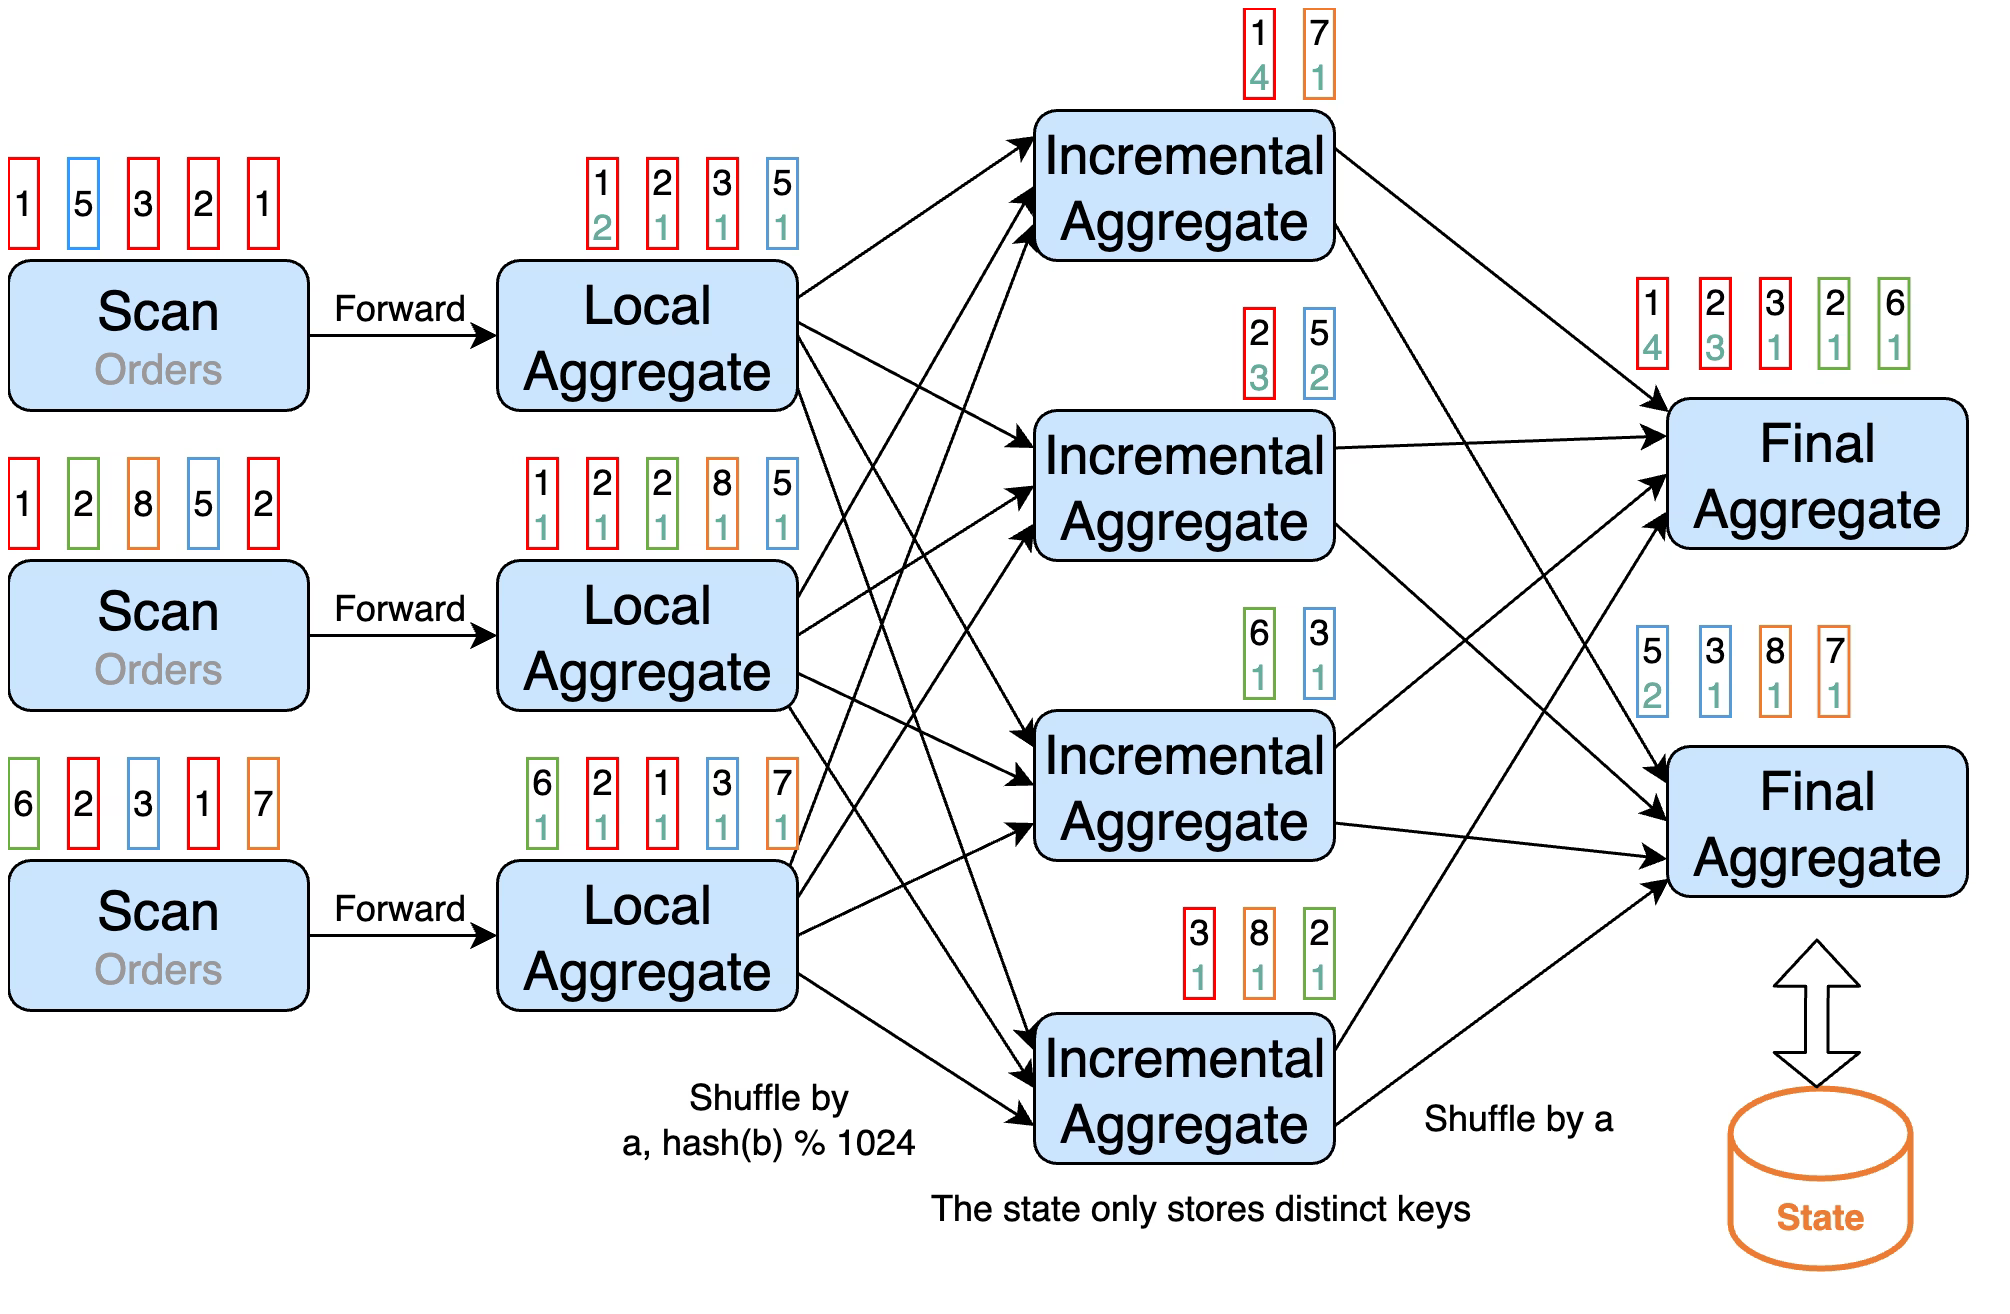
We can use the following options to leverage Incremental Aggregation, together with MiniBatch Aggregation, Local/Global Aggregation and Split Distinct Aggregation:
```bash
table.exec.mini-batch.enabled: true # enable mini-batch
table.exec.mini-batch.allow-latency: 5s # put the records into a buffer and do an aggregation within 5 seconds
table.exec.mini-batch.size: 10000
table.optimizer.agg-phase-strategy: TWO_PHASE/AUTO # enable Local/Global Aggregation
table.optimizer.distinct-agg.split.enabled: true # enable Split Distinct Aggregation
table.optimizer.distinct-agg.split.bucket-num: 1024 # number of bucket
table.optimizer.incremental-agg-enabled: true # enable incremental agg, default is true
```
> **NOTE:** Note: The query must support MiniBatch Aggregation, Local/Global Aggregation and Split Distinct Aggregation too. Please see the requirements for those optimizations in the corresponding sections of this article.
## Conclusion
We discussed key skews, distinct key skews, their implications to joins with aggregations, potential solutions, and how to implement them in Ververica Platform.
We will discuss this topic further in future articles. Stay tuned.
In case you are interested in learning more about Flink SQL, the following resources may help:
- [Getting Started - Flink SQL on Ververica Platform](https://docs.ververica.com/getting_started/sql_development.html)
- [Flink SQL Cookbook](https://github.com/ververica/flink-sql-cookbook)
- [Flink Forward Talk: One SQL, Unified Analytics](https://youtu.be/rOzA4CIeXOw?t=924)
- [Only SQL: Empower data analysts end-to-end with Flink SQL](https://youtu.be/KvaDe7QCwBQ)
- [The official Flink SQL documentation](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/overview/)
We strongly encourage you to try your queries in Ververica Platform. The installation is as simple as [these steps](https://docs.ververica.com/getting_started/installation.html).
---
---
title: "Flink's Test Harnesses Uncovered"
description: "We will demonstrate how to use Fink's test harnesses to verify the correctness of Flink's built-in operators and custom user-defined functions (UDFs)."
lastUpdated: 2026-05-12T11:48:24.000Z
source_url:
html: "https://www.ververica.com/blog/flinks-test-harnesses-uncovered"
md: "https://www.ververica.com/blog/flinks-test-harnesses-uncovered.md"
---
When working with Apache Flink, developers often face challenges while testing user-defined functions (UDFs) that utilize state and timers. In this article we will answer a question "How to test user-defined functions (UDFs) using **Flink's test harnesses**".
## Using Flink’s test harnesses
Testing User-Defined Functions (UDFs) that use Flink state and timers can be complex, especially when using functions such as `KeyedProcessFunction`. Flink includes a set of test harnesses that are specifically designed to make this task easier. These test harnesses were created to help verify the correctness of Flink's built-in operators, but they can also be used to test custom UDFs that use Flink state and timers. By using these test harnesses, developers can ensure that their UDFs are working correctly and are able to handle different types of input data. This can save time and effort during the development process and help ensure that the UDFs are reliable and accurate.
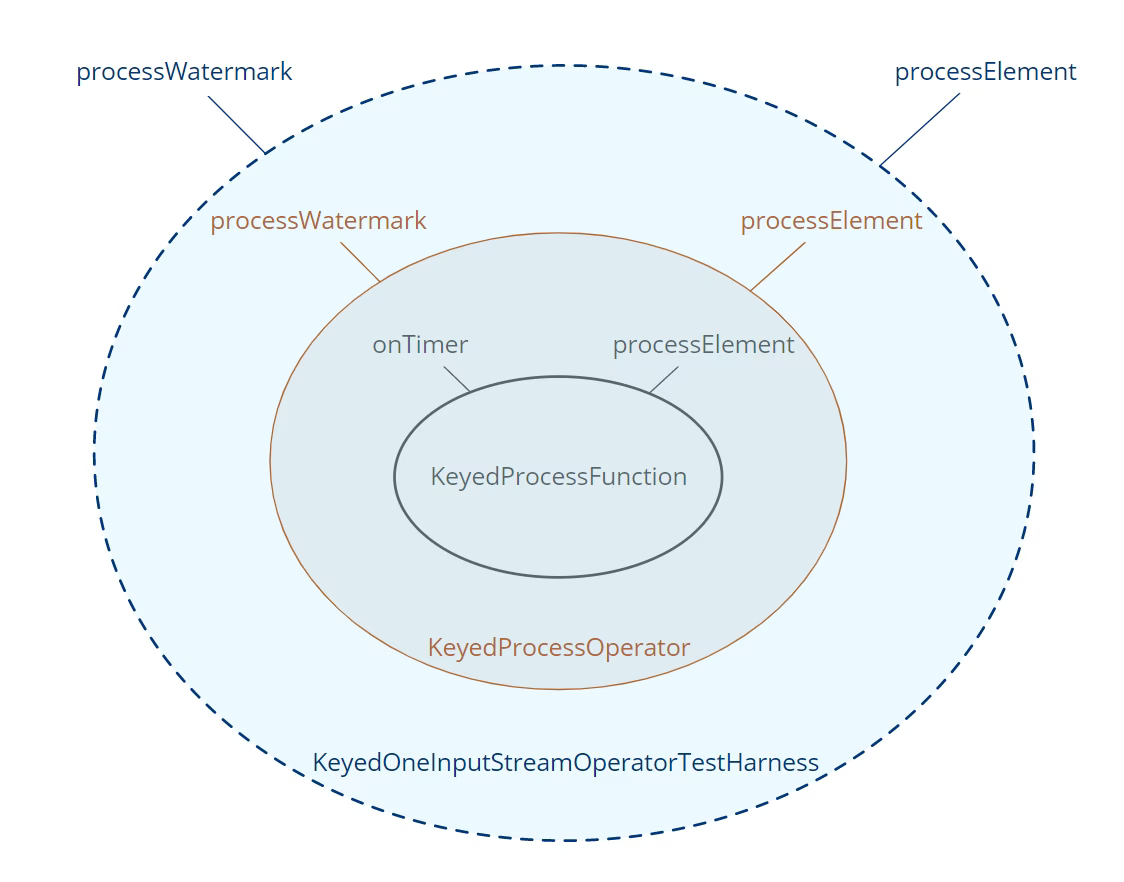
The graph illustrates that the KeyedOneInputStreamOperatorTestHarness encompasses a KeyedProcessOperator, which in turn contains the KeyedProcessFunction slated for evaluation.
## Configurations for the Test Harnesses
You need to add [some dependencies](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/configuration/testing/) to your project in order to leverage the test harnesses.
To test DataStream jobs, you may add the following in the dependencies block of pom.xml for your Maven project:
```xml
org.apache.flink
flink-test-utils
1.17.0
test
```
To test Table/SQL jobs, you may add the following in the dependencies block of pom.xml for your Maven project, in addition to the aforementioned flink-test-utils:
```xml
org.apache.flink
flink-table-test-utils
1.17.0
test
```
> **NOTE:** Note: The module flink-table-test-utils was introduced in Flink 1.15 and is considered experimental.
Testing user functions through an operator can be a useful approach, as it allows you to test the function in the context of the operator and see how it behaves when used in a Flink pipeline.
It's important to note that Flink only provides test harnesses for operators, so you will need to manually instantiate the appropriate operator in order to use these test harnesses. This means that you will need to create an instance of the operator and configure it with the necessary inputs and parameters. Once you have done this, you can use the test harnesses to verify the correctness of your user function. It's worth noting that this approach can be more complex than using other testing methods, as it requires you to manually set up the operator and configure it with the appropriate inputs.
```java
@Test
public void testMyProcessFunction() throws Exception {
KeyedProcessOperator operator =
new KeyedProcessOperator<>(new MyKeyedProcessFunction());
// setup test harness
// push in data
// verify results
}
```
To test a user function in Flink, it is first necessary to create the appropriate TestHarness. Once you have created the TestHarness, you can use it to test various aspects of the user function and the operator it is used in. For example, you can test that processing an element with the operator creates a state and that this state is later cleared. To do this, you can use the TestHarness to send test data through the operator and then check the state to ensure that it has been properly created and later cleared. This can be an important step in the testing process, as it helps to ensure that the operator and user function are working correctly and can handle the state properly.
```java
public class MyKeyedProcessFunctionTest {
private KeyedOneInputStreamOperatorTestHarness testHarness;
@Before
public void setupTestHarness() throws Exception {
KeyedProcessOperator operator =
new KeyedProcessOperator<>(MyKeyedProcessFunction);
testHarness =
new KeyedOneInputStreamOperatorTestHarness<>(operator, e -> e.key, Types.LONG);
testHarness.open();
}
@Test
public void testingStatefulFunction() throws Exception {
assertThat(testHarness.numKeyedStateEntries(), is(0));
testHarness.setProcessingTime(0L);
testHarness.processElement(2L, 100L);
assertThat(testHarness.numKeyedStateEntries(), is(not(0)));
testHarness.setProcessingTime(3600000L);
assertThat(testHarness.numKeyedStateEntries(), is(0));
}
}
```
## Testing timer behavior
When testing a user function in Flink, it is essential to test various aspects of its behavior. One common thing to test is the creation and firing of timers. You can use the TestHarness to send test data through the operator and verify that a timer is created. You can then advance the watermark and verify that the timer has fired. In addition to testing timers, you may also want to test that processing an element creates a state and verify the results of this processing.
Suppose we expect a timer to be fired for our test target within 20 milliseconds. The example code below demonstrates how we can test it with a test harness.
```java
@Test
public void testTimelyOperator() throws Exception {
// setup initial conditions
testHarness.processWatermark(0L);
assertThat(testHarness.numEventTimeTimers(), is(0));
// send in some data
testHarness.processElement(3L, 100L);
// verify timer
assertThat(testHarness.numEventTimeTimers(), is(1));
// advance the time to 20 in order to fire the timer.
testHarness.processWatermark(20);
assertThat(testHarness.numEventTimeTimers(), is(0));
// verify results
assertThat(testHarness.getOutput(), containsInExactlyThisOrder(3L));
assertThat(testHarness.getSideOutput(new OutputTag<>("invalidRecords")), hasSize(0))
}
```
## Limits
There are a few caveats to keep in mind when using Flink's test harnesses to test user functions. One important thing to note is that these test harnesses only allow you to test a single operator, rather than a whole pipeline of operators. This means that if you want to test a user function that is used in a pipeline of operators, you'll need to set up and test each operator separately.
It's also important to note that these test harnesses are considered internal, which means that the API could change between minor versions of Flink. While these changes are generally backward compatible, it's possible that you may need to make some updates to your tests if you upgrade to a new minor version of Flink. Overall, it's a good idea to keep an eye on the Flink documentation and release notes to stay informed about any changes to the test harnesses and other internal APIs.
## Conclusion
In conclusion, ensuring that a Flink application is working correctly is essential, and testing is a crucial part of this process. There are various tools available for testing Flink applications, including Flink's test harnesses and the ability to test user functions through an operator. It is important to test the application at multiple levels, including unit testing functions that use state and timers, [integration testing](https://www.ververica.com/blog/how-to-test-flink-sql-application), and performance testing. This multi-level testing approach helps to ensure that the application is working as expected and is ready for production.
---
---
title: "Flink SQL Secrets: Mastering the Art of Changelog Event Out-of-Orderness"
description: "Explore the complexities of changelog event out-of-orderness in Flink SQL and discover solutions to ensure reliable real-time data processing."
lastUpdated: 2026-05-25T07:38:10.000Z
source_url:
html: "https://www.ververica.com/blog/flink-sql-secrets-mastering-the-art-of-changelog-events"
md: "https://www.ververica.com/blog/flink-sql-secrets-mastering-the-art-of-changelog-events.md"
---
## Introduction
Alice is a data engineer taking care of real-time data processing in her company. She found that Flink SQL sometimes can produce **update** (with regard to keys) events. But, with the early versions of Flink, those events can not be written to Kafka directly because Kafka is an append-only messaging system essentially. Fortunately, the Flink community released the connector `upsert-kafka` in a later version that supports writing update events. Later, she found that the Flink SQL jobs that read `upsert-kafka` events for join operations occasionally produce errors. This made her doubt the reliability of Flink SQL. She reported the problem to the community and it was confirmed to be a changelog event out-of-orderness issue, which was subsequently resolved in the new version. Finally, she can continue to work with Flink SQL happily again.
From Alice's experience with Flink SQL, we can learn that real-time data processing is not always smooth and straightforward. To make Flink SQL more understandable, this article tries to solve the mystery around the changelog event out-of-orderness issue in Flink SQL. We will start with the introduction of changelog in Flink SQL, followed by the demonstration of the changelog event out-of-orderness issue and the solution to it. In the end, we will present the best practices with regard to this issue to help you better understand and use Flink SQL for real-time data processing.
## Changelog in Flink SQL
Changelog is _not_ a new concept invented by Flink SQL. In the relational database world, MySQL uses the well-known binlog (binary log) to record all modification operations in the database, including INSERT, UPDATE, and DELETE operations. Similarly, changelog in Flink SQL is also used to record these data changes in order to achieve incremental data processing.
In MySQL, binlog can be used for data backup and recovery, synchronization, and replication. Incremental data synchronization and replication can be achieved by reading and parsing the operation records in binlog. Change Data Capture (CDC) is a commonly used data synchronization technology that monitors data changes in the database and converts those changes into event streams for real-time processing. CDC tools can be used to transfer data changes in relational databases to other systems or data warehouses in real-time to support real-time analysis and reporting. Common CDC tools include [Debezium](https://debezium.io/) and [Maxwell](https://github.com/zendesk/maxwell). Flink’s CDC support, added via [FLINK-15331](https://issues.apache.org/jira/browse/FLINK-15331), allows integration with external systems' CDC data in real-time and achieves real-time data synchronization and analysis through Flink.
### Produce and Process Changelog Events in Flink SQL
While the aforementioned binlog and CDC are external changelog data sources that are integrated with Flink, Flink SQL internally also generates changelog data. To distinguish whether an event is an update event, we refer to the changelogs that contain only INSERT-type events as **append streams**, while the changelogs that additionally contain other types (e.g., UPDATE) of events are referred to as **update streams**. Some operations in Flink such as group aggregation and deduplication can produce update events. Operators that generate update events typically maintain state, and we generally refer to them as stateful operators. It is important to note that not all stateful operators support processing update streams as input. For example, over-window aggregation and interval join currently do not support update streams as input (yet).
Here is a table showing Flink SQL operations, the corresponding runtime streaming operators, and whether they support consuming or producing update streams, as of Flink 1.16.1:
> **NOTE:** Stateless operators only pass through event types and do not actively generate update events, that is, the output event type remains the same as the input one.
Flink SQL introduced the retraction mechanism via [FLINK-6047](https://www.mail-archive.com/issues@flink.apache.org/msg102914.html). It implemented the incremental update algorithm for streaming SQL operators. The corresponding events use two physical types: INSERT and DELETE (although the data source only supports INSERT events). When an event needs to be updated after processing by the operator, the update event is physically split into two independent events DELETE and INSERT. From then on, Flink has always been using two physical event types to express the three operation requirements of INSERT, UPDATE, and DELETE. Since [FLINK-16987](https://issues.apache.org/jira/browse/FLINK-16987), the changelog event type was refactored into four types which form a complete changelog event type that eases the connection to the CDC ecosystem.
```java
/**
* A kind of row in a changelog.
*/
@PublicEvolving
public enum RowKind {
/**
* Insertion operation.
*/
INSERT,
/**
* Previous content of an updated row.
*/
UPDATE_BEFORE,
/**
* New content of an updated row.
*/
UPDATE_AFTER,
/**
* Deletion operation.
*/
DELETE
}
```
Users who are familiar with [Debezium](https://github.com/debezium/debezium) data format (or the database binlog parsing) may wonder why Flink does not use a composite UPDATE event type (like what databases do) that includes both UPDATE_BEFORE (UB) and UPDATE_AFTER (UA) and is more compact. In fact, we have carefully evaluated this option when designing and implementing Flink's retraction mechanism. Composite UPDATE events are indeed more compact in some scenarios and can solve specific problems (e.g., [FLINK-9528](https://issues.apache.org/jira/browse/FLINK-9528)), but the reasons we choose not to use it are mainly due to the following two aspects:
1. The split events have the same event structures regardless of event types (only RowKind is different) which makes serialization simpler. If composite UPDATE events are used, either the events are heterogeneous or INSERT/DELETE are also modeled as UPDATE events (e.g., INSERT events have only UA, DELETE events have UB only)
1. In distributed environments, data shuffling operations (e.g., join, aggregate) are frequently involved. Even if composite UPDATE events are used, they still have to be split into separate DELETE and INSERT events when shuffling in some scenarios.
Here's an example showing a scenario where composite UPDATE events have to be split into DELETE and INSERT events. The remainder of this blog post will use this example SQL job to discuss the out-of-orderness issue and present the corresponding solution.
```sql
-- CDC source tables: s1 & s2
s1: id BIGINT, level BIGINT, PRIMARY KEY(id)
s2: id BIGINT, attr VARCHAR, PRIMARY KEY(id)
-- sink table: t1
t1: id BIGINT, level BIGINT, attr VARCHAR, PRIMARY KEY(id)
-- join s1 and s2 and insert the result into t1
INSERT INTO t1
SELECT
s1.*, s2.attr
FROM s1 JOIN s2
ON s1.level = s2.id
```
Assuming the changelog of the record with `id=1` in the source table `s1` is at time `t0`, '`(id=1, level=10)`' is inserted, and then at time `t1`, the row is updated to '`(id=1, level=20)`'. This corresponds to three split events:
`+I (id=1, level=10) // +I: INSERT`
`-U (id=1, level=10) // -U: UPDATE_BEFORE`
`+U (id=1, level=20) // +U: UPDATE_AFTER`
Looking at the SQL statement in the example, the primary key of the source table `s1` is `id`, but the join operation needs to be shuffled by column `level` (see the `ON` clause).
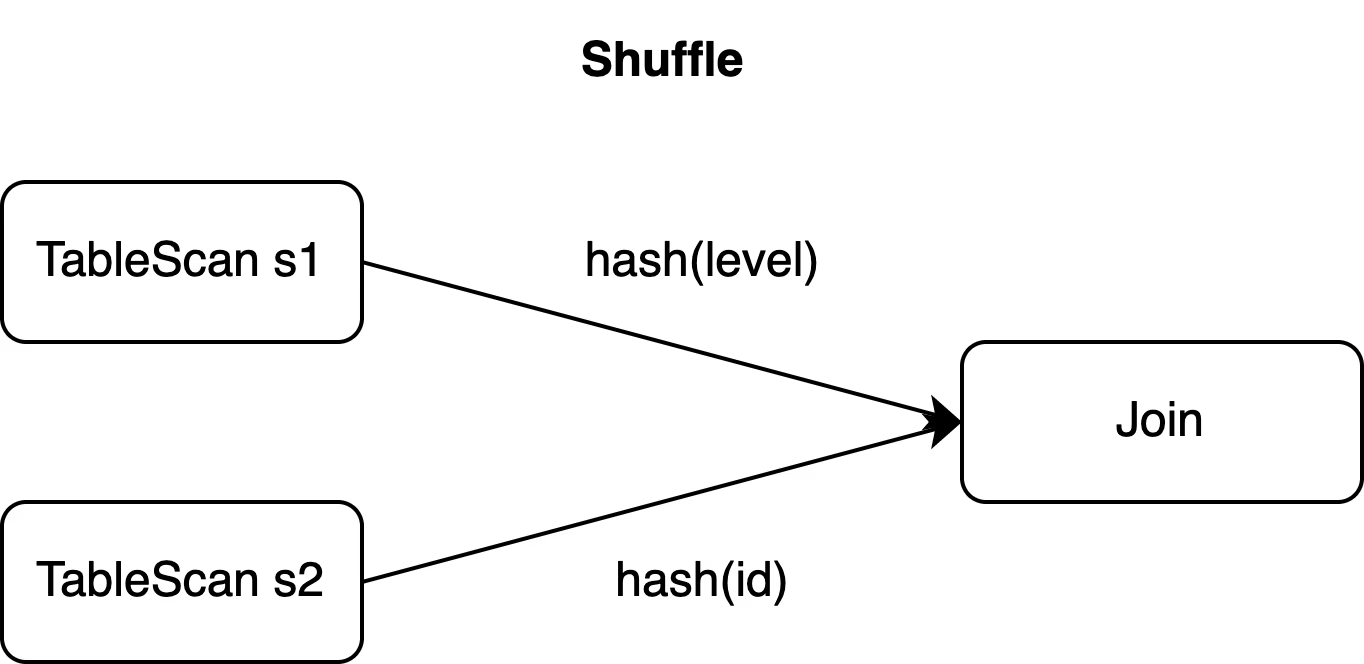
In this example, if the join operator runs with a parallelism of two, the above three events could be sent to two tasks. In this case, even if composite UPDATE events are used, they still need to be split in order to be shuffled to different tasks for parallel processing.
## The Changelog Event Out-of-Orderness Issue
### How the Issue Occurs
Continuing with the previous example, suppose there are two rows in table `s2`:
`+I(id=10, attr=a1)`
`+I(id=20, attr=b1)`
The join operator receives the following three changelog events from table `s1`:
`+I(id=1, level=10)`
`-U(id=1, level=10)`
`+U(id=1, level=20)`
In a distributed environment, the actual join is processed in parallel on two tasks. See the figure below. The sequence of the events received by the downstream operator (Sink task in this case) has a few possibilities as indicated at the bottom of the figure. While the sequence of events in (1) is the same as the one in sequential processing, (2) and (3) show the scenarios where the changelog event arrives out-of-order at the Sink operator in Flink SQL.
If the downstream operator does not take the out-of-ordermess into account in its implementation, it may lead to incorrect results. For example, if the primary key declared by the Sink table is id, and the external storage is updated by upsert. In scenarios (2) and (3), without additional countermeasures, the row with `id=1` will be deleted from the external storage incorrectly while the expected result is '`(id=1, level=20, attr='b1')`'.
### Fix the Issue with SinkUpsertMaterializer
The join operator in the aforementioned example SQL job produces an update stream because its output contains not only INSERT-style events (`+I`), but also UPDATE-style events (`-U` and `+U`). As mentioned before, out-of-orderness can cause a correctness issue if it is not handled properly.
Before presenting the solution, we will briefly introduce two terms first. [_**Unique keys**_](https://en.wikipedia.org/wiki/Unique_key) denote the column or the combination of columns guaranteed to meet the UNIQUE constraint after an SQL operation. In the SQL world, unique keys help to determine whether to update an existing row or insert a new row when a row comes. For example, the following three sets of keys are all unique keys of the joining output in the example SQL job:
`(s1.id)`
`(s1.id, s1.level)`
`(s1.id, s2.id)`
In the traditional relational database world, binlog (or something similar) maintained a sequential and ordered update history for a primary key of a table. Flink SQL's changelog mechanism is based on the same idea but has a simplified implementation. Flink does not record the timestamp of each update like binlog. Instead, Flink determines the ordering of update history received on the primary key through a global analysis in the planner. If the ordering on some unique keys is maintained, the corresponding keys are called _**upsert keys**_. In the presence of upsert keys, downstream operators can correctly tell the update history of the upsert keys in the order of reception. If a shuffle operation breaks the ordering of unique keys, upsert keys will be empty. In this case, downstream operators need to use an algorithm such as a [counting algorithm](http://dl.acm.org/citation.cfm?id=170066) to achieve the final consistency.
In the example SQL job, the rows in table `s1` are shuffled based on column `level`, and the join operator will produce multiple rows with the same `s1.id.` As a result, the upsert key of the join output is empty (meaning no ordering exists on a unique key after joining). What Flink does, in this case, is to store all input records, then check and compare all columns to distinguish between update and insertion.
Furthermore, the sink table has column `id` as its primary key. This leads to a mismatch between the upsert keys of the join output and the primary key of the sink table. It is clear that something has to be done here to correctly convert the rows from the join output to the rows needed by the sink table.
Based on what we discussed so far when the output of the join operator (or another SQL operation) is an update stream and its upsert key is different from the primary key of the sink table, an intermediate step is needed to (1) eliminate the effect caused by out-of-orderness, and (2) produce new output changelog events based on the primary key of the sink table. Flink’s answer to this is adding the operator SinkUpsertMaterializer between the join operator and the sink operator ([FLINK-20374](https://mail-archives.apache.org/mod_mbox/flink-issues/202105.mbox/%3CJIRA.13342795.1606382363000.518358.1622156762973@Atlassian.JIRA%3E)). Looking at the changelog events illustrated in the figure before, we can see that the out-of-orderness of the changelog events follows this rule: for a given upsert key (or all columns if the upsert key is empty), the ADD events (`+I, +U`) always occur before its RETRACT events (`-D, -U`) and they are always processed by the same task even if a data shuffle is involved. This also explains why there are no other combinations of those three changelog events except for three cases as illustrated before. SinkUpsertMaterializer was implemented based on this rule and works as follows:
SinkUpsertMaterializer maintains a list of RowData in its state. When a row enters this operator, depending on whether it is an ADD or RETRACT event, it checks its internal state for this row based on the deduced upsert keys or the entire row if the upsert key is empty (the step “find prev row”), then it adds/updates the row in the state in case of ADD or removes it from the state in case of RETRACT. Finally, it emits the changelog events based on the primary key of the sink table. See the source code of [SinkUpsertMaterializer](https://github.com/apache/flink/blob/release-1.17/flink-table/flink-table-runtime/src/main/java/org/apache/flink/table/runtime/operators/sink/SinkUpsertMaterializer.java) for more details.
The figure below shows how the output changelog events from the join operator are processed and transformed into the input changelog events to the sink table. Particularly, in the second scenario, when the row removed from the state is the last row, it emits the 2nd last row downstream. In the third scenario, when `+U (id=1,level=20, attr='b1')` is processed, SinkUpsertMaterializer emits it as it is. When `-U (id=1,level=10, attr='a1')` comes, it removes the row from the state without emitting any event as the required output has already been omitted before.
## Best Practices
As shown in the previous section, SinkUpsertMaterializer maintains a list of `RowData` in its state. Potentially, this can lead to a large state size thereof the state access I/O overhead and the reduced job throughput. Therefore, we should try to avoid using it if possible.
### Proactively Avoid Using SinkUpsertMaterializer
The addition of SinkUpsertMaterializer is controlled by the configuration option `table.exec.sink.upsert-materialize` which has a default value of “auto”. This means, by default, Flink’s SQL engine deduces the existence of out-of-orderness from the correctness perspective and adds SinkUpsertMaterializer if necessary. Note that the automatic addition of SinkUpsertMaterializer does not necessarily mean that the actual data are out-of-order. For example, in some user queries, when the SQL planner deduces the upsert keys, there may not be targeted optimization, such as using the [grouping sets](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/hive-compatibility/hive-dialect/queries/group-by/#grouping-sets) syntax combined with [coalesce](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/functions/systemfunctions/) to convert null values. In this case, the planner cannot determine whether the upsert key generated by grouping sets combined with coalesce can match the primary key of the sink table. For the reasons of correctness, Flink will add SinkUpsertMaterializer. But if a job can produce the correct output without using SinkUpsertMaterializer, then it is better to run the job with `table.exec.sink.upsert-materialize: non` to force Flink not to add SinkUpsertMaterializer.
Other ways to avoid using SinkUpsertMaterializer include:
- Make sure the partition key used for deduplication, group aggregation, etc. is the same as the sink table's primary key.
- If the sink operator and the upstream deduplication/group aggregation/other operators are chained together and there is no data correctness issue in Flink 1.13.2 or earlier, you can refer to the original resource configuration and change `table.exec.sink.upsert-materialize` to `none` to migrate the job to Flink 1.13.3 or later.
If SinkUpsertMaterializer has to be added:
- Avoid adding columns generated by non-deterministic functions (such as CURRENT_TIMESTAMP or NOW) to the data written to the sink, as this can cause abnormal inflation in the state of SinkUpsertMaterializer in Flink 1.14 or earlier.
- Try to increase the job parallelism if the state of SinkUpsertMaterializer is already large and causes performance issues.
### Known Issues of SinkUpsertMaterializer
While SinkUpsertMaterializer fixes the changelog event out-of-orderness issue, it can potentially lead to a continuous state increase. This is mainly due to two factors. The state retention time is too long (no state TTL or a very long one is set). Note that [Enabling TTL](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/config/#table-exec-state-ttl) can impact data integrity. A short TTL can lead to the problem described in [FLINK-29225](https://issues.apache.org/jira/browse/FLINK-29225) where dirty data that should have been deleted remain in the state. This occurs when the time interval between the DELETE event of a message and its ADD event exceeds the configured TTL. In this case, Flink produces a warning message in the logs:
```bash
int index = findremoveFirst(values, row);
if (index == -1) {
LOG.info(STATE_CLEARED_WARN_MSG);
return;
}
```
Flink may not deduce the upsert keys correctly before Flink 1.16 in some scenarios. For example, when there are non-deterministic columns in the input update stream, it will not be able to correctly delete historical data (that is, “prev row exists” always return “False” in the flow chart). This results in a continuous state increase. This has been fixed by [FLINK-28569](https://issues.apache.org/jira/browse/FLINK-28569) in Flink 1.16 or later.
## Summary
This article provided answers to several changelog-related questions that Flink SQL users frequently encounter in real-time data processing:
- What is a changelog stream? How does it relate to the binlog in the relational database?
- How does changelog event out-of-orderness occur?
- How does Flink SQL solve the out-of-orderness issue?
- What are the best practices to deal with the changelog event out-of-orderness issue?
## Acknowledgments
Thanks to community users for their feedback on the related issues and to Jingsong Lee for his contribution to fixing the out-of-orderness issues in Flink and numerous sessions of offline discussions.
---
---
title: "How-to guide: Synchronize MySQL sub-database and sub-table using Flink CDC"
description: "This tutorial will show you how to use Flink CDC to build a real-time data lake to synchronize MySQL sub-database and sub-table"
lastUpdated: 2026-05-29T09:08:50.000Z
source_url:
html: "https://www.ververica.com/blog/how-to-guide-synchronize-mysql-sub-database-and-sub-table-using-flink-cdc"
md: "https://www.ververica.com/blog/how-to-guide-synchronize-mysql-sub-database-and-sub-table-using-flink-cdc.md"
---
In the Online Transaction Processing (OLTP) system, to solve the problem of a large amount of data in a single table, the method of sub-database and table is usually used to split a single large table to improve the throughput of the system. However, to facilitate data analysis, it is generally necessary to merge the table splits from the sub-databases and sub-tables into a large table when synchronizing to the data warehouse or data lake.
This tutorial will show you how to use Flink CDC to build a real-time data lake for the above-presented scenario. The examples in this article will all be based on Docker with the use of Flink SQL. There is no need for a line of Java/Scala code or installation of an IDE. The entire content of this guide contains the docker-compose file.
The whole process will be shown by synchronizing data from MySQL to [Iceberg](https://iceberg.apache.org/), as shown in the diagram below.
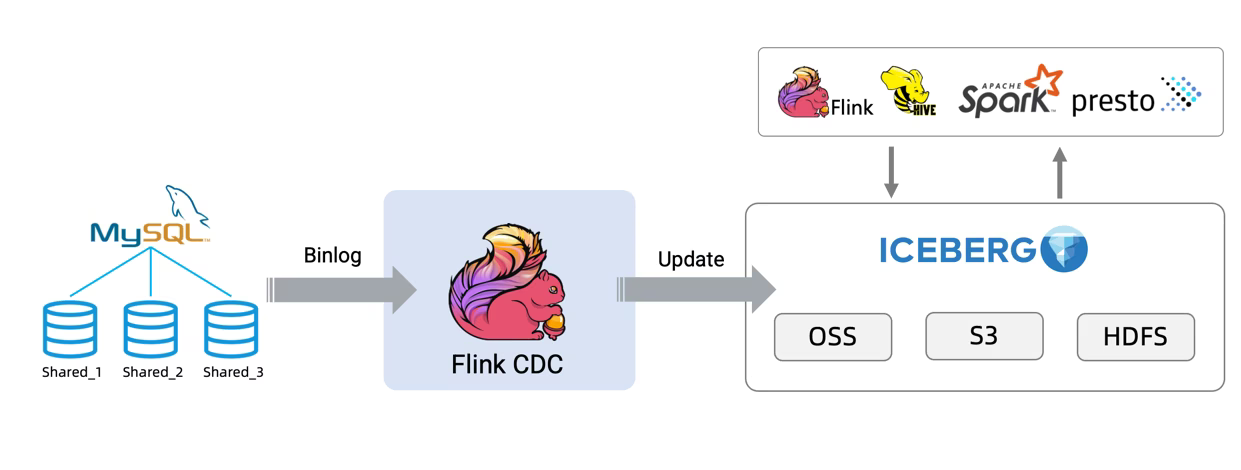
## Prerequisites
- Preferably, a clean Linux installation on bare metal or virtual machine
- Install [Docker Engine](https://docs.docker.com/engine/install/) or [Docker Desktop](https://docs.docker.com/desktop/install/mac-install/)
- Download [flink-shaded-hadoop-2-uber-2.7.5-10.0.jar](https://4757017.hs-sites.com/hubfs/JAR%20files/JAR/flink-shaded-hadoop-2-uber-2.7.5-10.0.jar)
- Download [iceberg-flink-1.13-runtime-0.13.0-SNAPSHOT.jar](https://4757017.hs-sites.com/hubfs/JAR%20files/JAR/iceberg-flink-1.13-runtime-0.13.0-SNAPSHOT.jar)
- Download [flink-sql-connector-mysql-cdc-2.4-SNAPSHOT.jar](https://4757017.hs-sites.com/hubfs/JAR%20files/JAR/flink-sql-connector-mysql-cdc-2.4-SNAPSHOT.jar)
## Step 1: Create a docker-compose.yml file
Create a Docker Compose file (`docker-compose.yml`) with the following content:
```yaml
version: '2.1'
services:
sql-client:
user: flink:flink
image: yuxialuo/flink-sql-client:1.13.2.v1
depends_on:
- jobmanager
- mysql
environment:
FLINK_JOBMANAGER_HOST: jobmanager
MYSQL_HOST: mysql
volumes:
- shared-tmpfs:/tmp/iceberg
jobmanager:
user: flink:flink
image: flink:1.13.2-scala_2.11
ports:
- "8081:8081"
command: jobmanager
environment:
- |
FLINK_PROPERTIES=
jobmanager.rpc.address: jobmanager
volumes:
- shared-tmpfs:/tmp/iceberg
taskmanager:
user: flink:flink
image: flink:1.13.2-scala_2.11
depends_on:
- jobmanager
command: taskmanager
environment:
- |
FLINK_PROPERTIES=
jobmanager.rpc.address: jobmanager
taskmanager.numberOfTaskSlots: 2
volumes:
- shared-tmpfs:/tmp/iceberg
mysql:
image: debezium/example-mysql:1.1
ports:
- "3306:3306"
environment:
- MYSQL_ROOT_PASSWORD=123456
- MYSQL_USER=mysqluser
- MYSQL_PASSWORD=mysqlpw
volumes:
shared-tmpfs:
driver: local
driver_opts:
type: "tmpfs"
device: "tmpfs"
```
The containers in this docker-compose file include:
- SQL-Client: Flink SQL Client, used to submit SQL queries and view SQL execution results
- Flink Cluster: contains Flink JobManager and Flink TaskManager to execute Flink SQL
- MySQL: as the data source of sub-database and sub-table, store the user table
> **NOTE:** If you want to run this guide in your own Flink environment, you need to download the packages listed below and put them in the lib directory of the Flink directory, i.e., FLINK_HOME/lib/.
flink-sql-connector-mysql-cdc-2.4-SNAPSHOT.jar
flink-shaded-hadoop-2-uber-2.7.5-10.0.jar
iceberg-flink-1.13-runtime-0.13.0-SNAPSHOT.jar
All Docker Compose-related commands used in this tutorial will need to be executed in the directory where `docker-compose.yml` is located.
Execute the following command where `docker-compose.yml` is located to start the components needed for this guide:
```bash
docker-compose up -d
```
This command will automatically start all containers defined in the Docker Compose file in the detached mode.
## Step 2: Prepare data in the MySQL database
Enter the MySQL container
```bash
docker-compose exec mysql mysql -uroot -p123456
```
Create data, tables, and populate the data.
```sql
CREATE DATABASE db_1;
USE db_1;
CREATE TABLE user_1 (
id INTEGER NOT NULL PRIMARY KEY,
name VARCHAR(255) NOT NULL DEFAULT 'flink',
address VARCHAR(1024),
phone_number VARCHAR(512),
email VARCHAR(255)
);
INSERT INTO user_1 VALUES (110,"user_110","Shanghai","123567891234","user_110@foo.com");
CREATE TABLE user_2 (
id INTEGER NOT NULL PRIMARY KEY,
name VARCHAR(255) NOT NULL DEFAULT 'flink',
address VARCHAR(1024),
phone_number VARCHAR(512),
email VARCHAR(255)
);
INSERT INTO user_2 VALUES (120,"user_120","Shanghai","123567891234","user_120@foo.com");
```
```sql
CREATE DATABASE db_2;
USE db_2;
CREATE TABLE user_1 (
id INTEGER NOT NULL PRIMARY KEY,
name VARCHAR(255) NOT NULL DEFAULT 'flink',
address VARCHAR(1024),
phone_number VARCHAR(512),
email VARCHAR(255)
);
INSERT INTO user_1 VALUES (110,"user_110","Shanghai","123567891234", NULL);
CREATE TABLE user_2 (
id INTEGER NOT NULL PRIMARY KEY,
name VARCHAR(255) NOT NULL DEFAULT 'flink',
address VARCHAR(1024),
phone_number VARCHAR(512),
email VARCHAR(255)
);
INSERT INTO user_2 VALUES (220,"user_220","Shanghai","123567891234","user_220@foo.com");
```
## Step 3: Create tables using Flink DDL with Flink SQL CLI
Use the following command to enter the Flink SQL CLI container:
```bash
docker-compose exec sql-client ./sql-client
```
You will see the following interface:
Turn on the checkpoint and do a checkpoint every 3 seconds. The checkpoint is not enabled by default, and we need to enable the checkpoint to allow Iceberg to submit the transactions. Moreover, MySQL-CDC must wait for a complete checkpoint before the binlog reading phase starts to avoid out-of-order binlog records.
```sql
SET execution.checkpointing.interval = 3s;
```
Create a source table `user_source` to capture the data of all databases and tables in MySQL and use regular expressions to match these databases and tables used in the configuration items of the table. Moreover, the table also defines a metadata column to distinguish which database and table the data comes from.
```sql
CREATE TABLE user_source (
database_name STRING METADATA VIRTUAL,
table_name STRING METADATA VIRTUAL,
`id` DECIMAL(20, 0) NOT NULL,
name STRING,
address STRING,
phone_number STRING,
email STRING,
PRIMARY KEY (`id`) NOT ENFORCED
) WITH (
'connector' = 'mysql-cdc',
'hostname' = 'mysql',
'port' = '3306',
'username' = 'root',
'password' = '123456',
'database-name' = 'db_[0-9]+',
'table-name' = 'user_[0-9]+'
);
```
Create a sink table `all_users_sink` to load data into Iceberg. In this sink table, we define a composite primary key (`database_name`, `table_name`, `id`) where the values of `id` fields may be the same.
```sql
CREATE TABLE all_users_sink (
database_name STRING,
table_name STRING,
`id` DECIMAL(20, 0) NOT NULL,
name STRING,
address STRING,
phone_number STRING,
email STRING,
PRIMARY KEY (database_name, table_name, `id`) NOT ENFORCED
) WITH (
'connector'='iceberg',
'catalog-name'='iceberg_catalog',
'catalog-type'='hadoop',
'warehouse'='file:///tmp/iceberg/warehouse',
'format-version'='2'
);
```
## Step 4: Stream to Iceberg
Use the following Flink SQL statement to write data from MySQL to Iceberg.
```sql
-- Flink SQL
INSERT INTO all_users_sink select * from user_source;
```
The command above will start a streaming job to continuously synchronize the full and incremental data in the MySQL database to Iceberg. You can see this running job in the [Flink UI](http://localhost:8081/#/job/running):
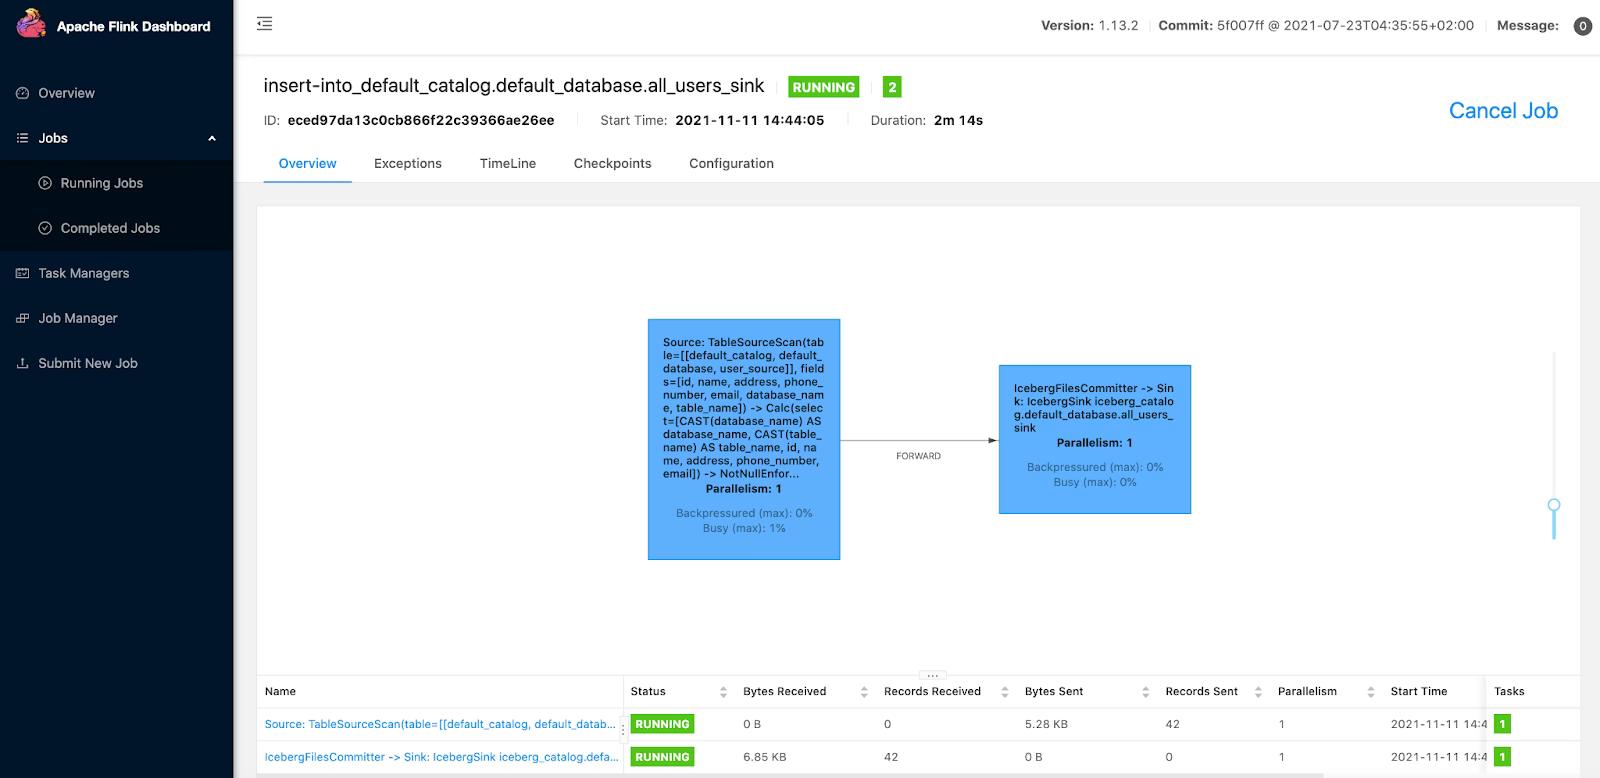
Use the following command to see the written files in Iceberg.
```bash
docker-compose exec sql-client tree /tmp/iceberg/warehouse/default_database/
```
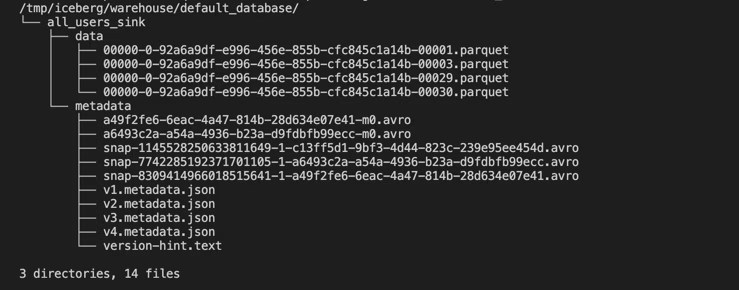
> **NOTE:** In your environment, the actual files may differ from the screenshot above, but the overall directory structure should be similar.
We can see the following query results in the Flink SQL CLI.
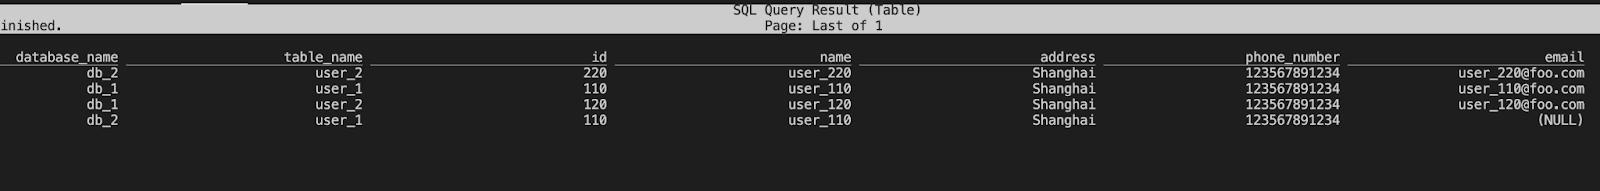
Insert a new row into the `db_1.user_1` table.
```sql
INSERT INTO db_1.user_1 VALUES (111,"user_111","Shanghai","123567891234","user_111@foo.com");
```
Update `db_1.user_2 table` data.
```sql
UPDATE db_1.user_2 SET address='Beijing' WHERE id=120;
```
Delete a row in the `db_2.user_2` table.
```sql
DELETE FROM db_2.user_2 WHERE id=220;
```
The final query results are as follows.
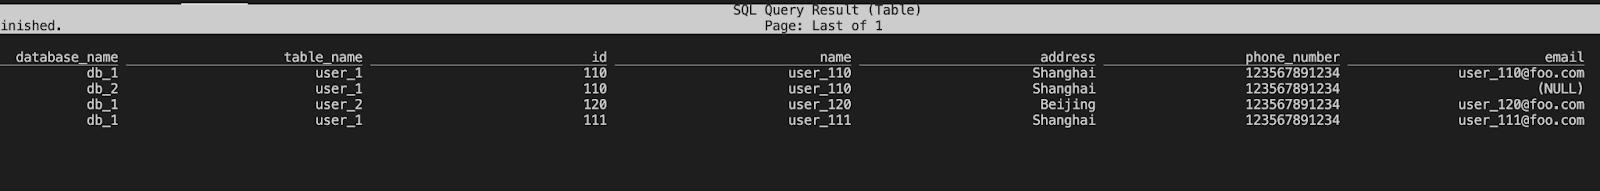
From the latest results of Iceberg, you can see that the new record has been added, the address has been updated, and the old record has been deleted, which is exactly the same as the data update we made in MySQL.
## Step 5: Clean the environment
You can clean the environment by executing the following command in the directory where the docker-compose.yml file is located to stop all containers.
```bash
docker-compose down
```
---
---
title: "How-to guide: Build Streaming ETL for MySQL and Postgres based on Flink CDC"
description: "Learn how to build a real-time streaming ETL pipeline for MySQL and Postgres using Flink CDC, integrating data into Elasticsearch without coding."
lastUpdated: 2026-05-29T09:38:34.000Z
source_url:
html: "https://www.ververica.com/blog/how-to-guide-build-streaming-etl-for-mysql-and-postgres-based-on-flink-cdc"
md: "https://www.ververica.com/blog/how-to-guide-build-streaming-etl-for-mysql-and-postgres-based-on-flink-cdc.md"
---
This tutorial will show how to quickly build streaming ETL for MySQL and Postgres based on Flink CDC. The examples in this article will all be done using the Flink SQL CLI, requiring only SQL and no Java/Scala code or the installation of an IDE.
Let’s assume that you are running an e-commerce business. The data of products and orders is stored in MySQL and the shipments corresponding to the orders are stored in Postgres. In order to make an analysis of the order table easier, you need to combine it with the relevant commodity and logistics data to create a new table and write it to ElasticSearch in real time.
The overall architecture of the system can be summarized in the following figure:
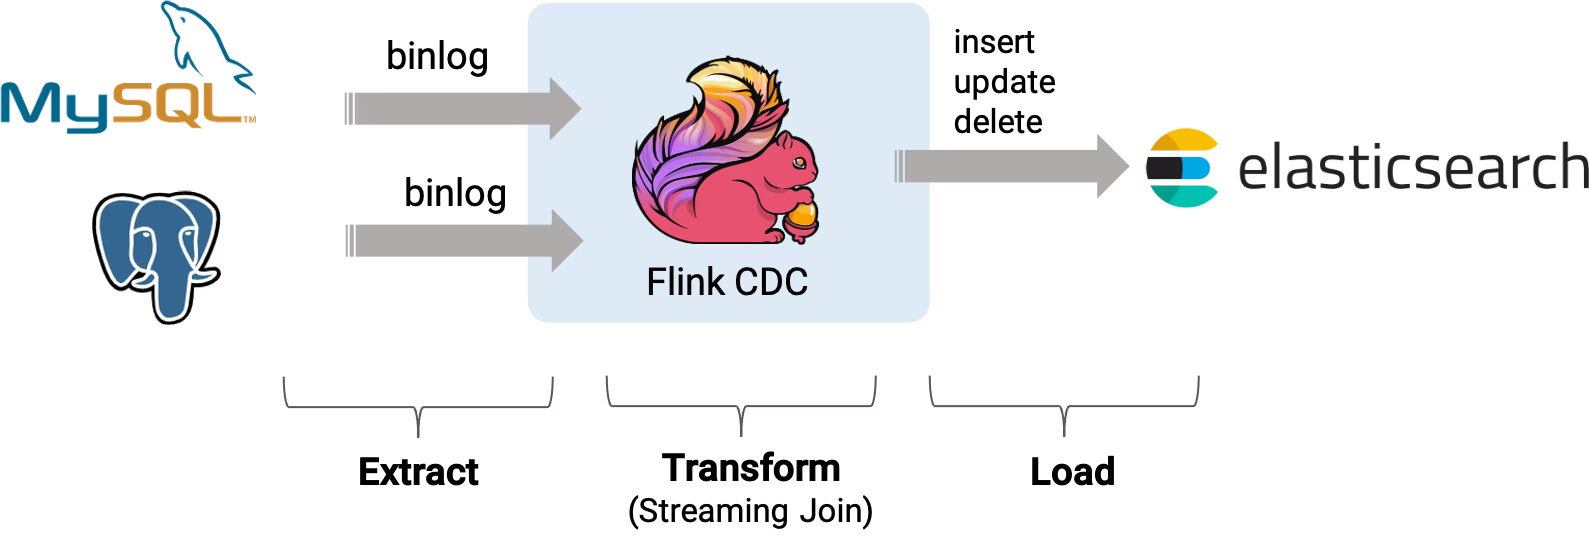
## Prerequisites
- preferably, a clean Linux installation on bare metal or virtual machine
- install [Docker Engine](https://docs.docker.com/engine/install/)
- download [Flink 1.16.0](https://archive.apache.org/dist/flink/flink-1.16.0/flink-1.16.0-bin-scala_2.12.tgz)
- download [flink-sql-connector-elasticsearch7-1.16.0.jar](https://4757017.hs-sites.com/hubfs/JAR%20files/flink-sql-connector-elasticsearch7-1.16.0.jar)
- download [flink-sql-connector-mysql-cdc-2.4-SNAPSHOT.jar](https://4757017.hs-sites.com/hubfs/JAR%20files/flink-sql-connector-mysql-cdc-2.4-SNAPSHOT.jar)
- download [flink-sql-connector-postgres-cdc-2.4-SNAPSHOT.jar](https://4757017.hs-sites.com/hubfs/JAR%20files/flink-sql-connector-postgres-cdc-2.4-SNAPSHOT.jar)
## Step 1: Create a docker-compose.yml file
Copy the following content into your docker-compose.yml file:
```yaml
version: '2.1'
services:
postgres:
image: debezium/example-postgres:1.1
ports:
- "5432:5432"
environment:
- POSTGRES_DB=postgres
- POSTGRES_USER=postgres
- POSTGRES_PASSWORD=postgres
mysql:
image: debezium/example-mysql:1.1
ports:
- "3306:3306"
environment:
- MYSQL_ROOT_PASSWORD=123456
- MYSQL_USER=mysqluser
- MYSQL_PASSWORD=mysqlpw
elasticsearch:
image: elastic/elasticsearch:7.6.0
environment:
- cluster.name=docker-cluster
- bootstrap.memory_lock=true
- "ES_JAVA_OPTS=-Xms512m -Xmx512m"
- discovery.type=single-node
ports:
- "9200:9200"
- "9300:9300"
ulimits:
memlock:
soft: -1
hard: -1
nofile:
soft: 65536
hard: 65536
kibana:
image: elastic/kibana:7.6.0
ports:
- "5601:5601"
```
The containers in this docker-compose file include:
- MySQL: products table and order table will be stored in this database
- Postgres: shipments table will be stored in this database
- Elasticsearch: the final enriched_orders table will be written to Elasticsearch
- Kibana: will be used to visualize ElasticSearch data
Create a directory for this project, e.g. directory and move the docker-compose file to that directory.
Execute the following command in the same directory to install the components needed for this how-to guide:
```bash
docker-compose up -d
```
This command will automatically start all containers defined in the Docker Compose configuration in the detached mode. You can use “docker ps” to observe whether the mentioned containers are running or not, visit [http://localhost:5601/](http://localhost:5601/) to check Kibana.
## Step 2: Download Flink and the required dependencies
Download [Flink 1.16.0](https://archive.apache.org/dist/flink/flink-1.16.0/flink-1.16.0-bin-scala_2.12.tgz) and extract it in your directory.The extracted directory will simply be called Flink 1.16.0.
```bash
tar -xvf flink-1.16.0-bin-scala_2.12.tgz
```
Download the dependencies listed below:
- [flink-sql-connector-elasticsearch 7-1.16.0.jar,](https://4757017.hs-sites.com/hubfs/JAR%20files/flink-sql-connector-elasticsearch7-1.16.0.jar)
- [flink-sql-connector-mysql-cdc-2.4-SNAPSHOT.jar](https://4757017.hs-sites.com/hubfs/JAR%20files/flink-sql-connector-mysql-cdc-2.4-SNAPSHOT.jar),
- [flink-sql-connector-postgres-cdc-2.4-SNAPSHOT.jar](https://4757017.hs-sites.com/hubfs/JAR%20files/flink-sql-connector-postgres-cdc-2.4-SNAPSHOT.jar),
> **NOTE:** You can also compile the snapshots locally. Clone the repository and follow these instructions. Remember that the snapshots must be 2.4 CDC version.
Place these dependencies in
```
flink-1.16.0/lib/
```
## Step 3: Check MySQL server timezone
Make sure that the MySQL server has a timezone offset that matches the configured time zone on your machine.
Enter the MySQL container.
```bash
sudo docker-compose exec mysql bash
```
Check MySQL timezone of My SQL time by running one of the commands below:
```sql
mysql -e "SELECT @@global.time_zone;" -p123456
```
or
```sql
mysql -e "SELECT NOW();" -p123456
```
Set the time that matches your local machine if there is a time discrepancy. Remember to change the UTC accordingly in the command below.
```sql
mysql -e "SET GLOBAL time_zone = '+1:00';" -p123456
```
Make sure that the timezone has been set.
```sql
mysql -e "SELECT @@global.time_zone;" -p123456
```
Leave the container.
```sql
exit
```
## Step 4: Prepare data in the MySQL database
Enter the MySQL container.
```bash
docker-compose exec mysql mysql -uroot -p123456
```
Create a database, products table, orders table, and insert data.
```sql
-- MySQL
CREATE DATABASE mydb;
USE mydb;
CREATE TABLE products (
id INTEGER NOT NULL AUTO_INCREMENT PRIMARY KEY,
name VARCHAR(255) NOT NULL,
description VARCHAR(512)
);
ALTER TABLE products AUTO_INCREMENT = 101;
INSERT INTO products
VALUES (default,"scooter","Small 2-wheel scooter"),
(default,"car battery","12V car battery"),
(default,"12-pack drill bits","12-pack of drill bits with sizes ranging from #40 to #3"),
(default,"hammer","12oz carpenter's hammer"),
(default,"hammer","14oz carpenter's hammer"),
(default,"hammer","16oz carpenter's hammer"),
(default,"rocks","box of assorted rocks"),
(default,"jacket","water resistent black wind breaker"),
(default,"spare tire","24 inch spare tire");
CREATE TABLE orders (
order_id INTEGER NOT NULL AUTO_INCREMENT PRIMARY KEY,
order_date DATETIME NOT NULL,
customer_name VARCHAR(255) NOT NULL,
price DECIMAL(10, 5) NOT NULL,
product_id INTEGER NOT NULL,
order_status BOOLEAN NOT NULL -- Whether order has been placed
) AUTO_INCREMENT = 10001;
INSERT INTO orders
VALUES (default, '2020-07-30 10:08:22', 'Jark', 50.50, 102, false),
(default, '2020-07-30 10:11:09', 'Sally', 15.00, 105, false),
(default, '2020-07-30 12:00:30', 'Edward', 25.25, 106, false);
```
Leave the container.
```sql
exit
```
## Step 5: Prepare data in the Postgres database
Enter the Postgres container.
```bash
docker-compose exec postgres psql -h localhost -U postgres
```
Create a shipments table and insert data.
```sql
-- PG
CREATE TABLE shipments (
shipment_id SERIAL NOT NULL PRIMARY KEY,
order_id SERIAL NOT NULL,
origin VARCHAR(255) NOT NULL,
destination VARCHAR(255) NOT NULL,
is_arrived BOOLEAN NOT NULL
);
ALTER SEQUENCE public.shipments_shipment_id_seq RESTART WITH 1001;
ALTER TABLE public.shipments REPLICA IDENTITY FULL;
INSERT INTO shipments
VALUES (default,10001,'Beijing','Shanghai',false),
(default,10002,'Hangzhou','Shanghai',false),
(default,10003,'Shanghai','Hangzhou',false);
```
Leave the Container.
```bash
exit
```
## Step 6: Start Flink cluster and Flink SQL CLI
Use the following command to change to the Flink directory.
```bash
cd flink-16.0
```
Start the Flink cluster with the following command:
```bash
./bin/start-cluster.sh
```
If the start-up is successful, you can access the Flink Web UI at [http://localhost:8081/](http://localhost:8081/), as shown below.
```
```
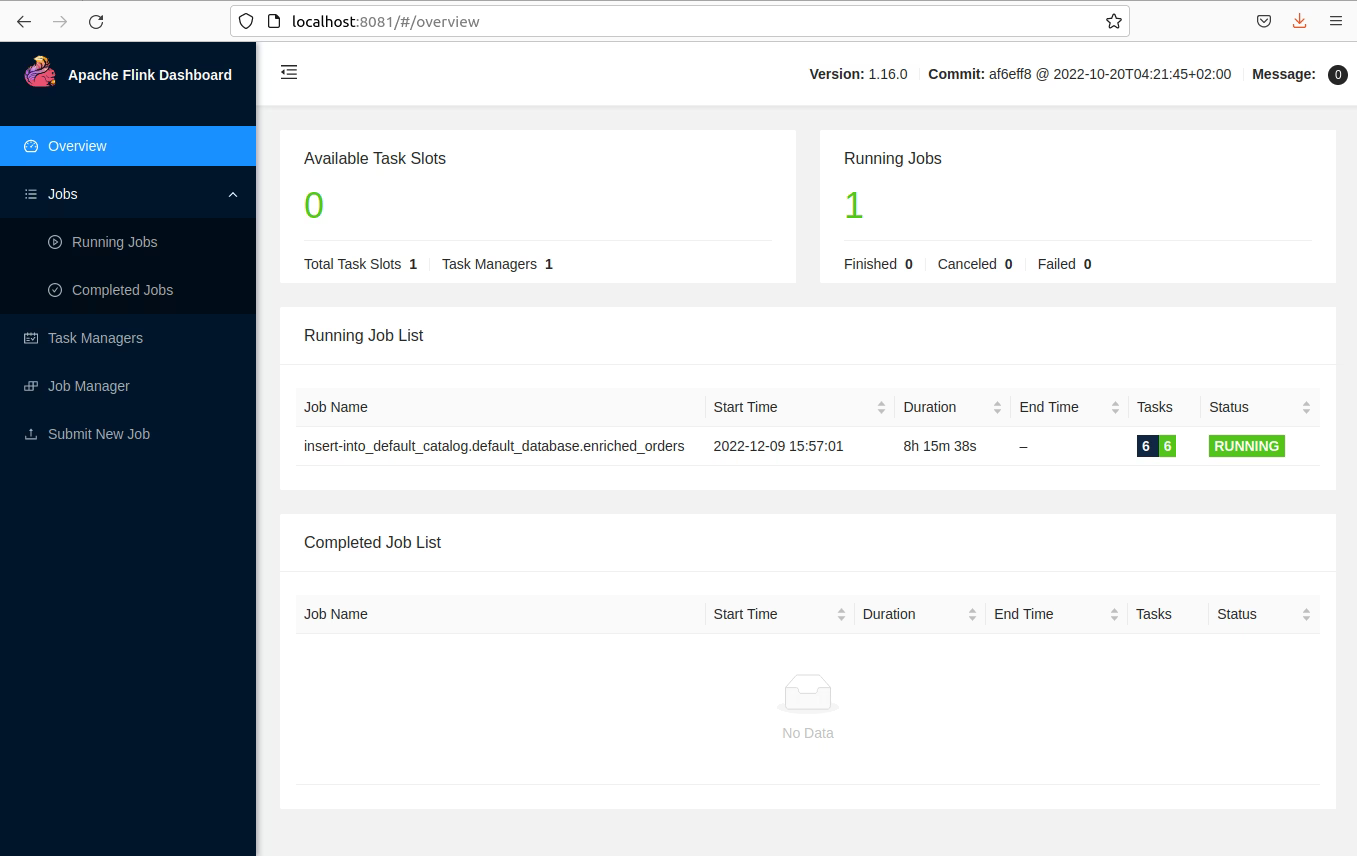
Start the Flink SQL CLI with the following command.
```bash
./bin/sql-client.sh
```
After the start-up is successful, you can see the following page:

## Step 7: Create tables using Flink DDL in Flink SQL CLI
First turn on the checkpoint and do a checkpoint every 3 seconds.
```sql
SET execution.checkpointing.interval = 3s;
```
Using the Flink SQL CLI, create tables that correspond to the products, orders, and shipments tables in the database for the purpose of synchronizing the data from these databases.
```sql
CREATE TABLE products (
id INT,
name STRING,
description STRING,
PRIMARY KEY (id) NOT ENFORCED
) WITH (
'connector' = 'mysql-cdc',
'hostname' = 'localhost',
'port' = '3306',
'username' = 'root',
'password' = '123456',
'database-name' = 'mydb',
'table-name' = 'products'
);
CREATE TABLE orders (
order_id INT,
order_date TIMESTAMP(0),
customer_name STRING,
price DECIMAL(10, 5),
product_id INT,
order_status BOOLEAN,
PRIMARY KEY (order_id) NOT ENFORCED
) WITH (
'connector' = 'mysql-cdc',
'hostname' = 'localhost',
'port' = '3306',
'username' = 'root',
'password' = '123456',
'database-name' = 'mydb',
'table-name' = 'orders'
);
CREATE TABLE shipments (
shipment_id INT,
order_id INT,
origin STRING,
destination STRING,
is_arrived BOOLEAN,
PRIMARY KEY (shipment_id) NOT ENFORCED
) WITH (
'connector' = 'postgres-cdc',
'hostname' = 'localhost',
'port' = '5432',
'username' = 'postgres',
'password' = 'postgres',
'database-name' = 'postgres',
'schema-name' = 'public',
'table-name' = 'shipments'
);
```
Finally, create an enriched_orders table to write the associated orders data to Elasticsearch.
```sql
CREATE TABLE enriched_orders (
order_id INT,
order_date TIMESTAMP(0),
customer_name STRING,
price DECIMAL(10, 5),
product_id INT,
order_status BOOLEAN,
product_name STRING,
product_description STRING,
shipment_id INT,
origin STRING,
destination STRING,
is_arrived BOOLEAN,
PRIMARY KEY (order_id) NOT ENFORCED
) WITH (
'connector' = 'elasticsearch-7',
'hosts' = 'http://localhost:9200',
'index' = 'enriched_orders'
);
```
## Step 8: Join the orders data and write it to Elasticsearch
Use** Flink SQL** to join the orders table with the product table and shipments table, and write the enriched_orders table into Elasticsearch.
```sql
INSERT INTO enriched_orders
SELECT o.*, p.name, p.description, s.shipment_id, s.origin, s.destination, s.is_arrived
FROM orders AS o
LEFT JOIN products AS p ON o.product_id = p.id
LEFT JOIN shipments AS s ON o.order_id = s.order_id;
```
Visit Kibana on your local machine (http://localhost:5601/app/kibana#/management/kibana/index_pattern) to create an index pattern `enriched_orders`.
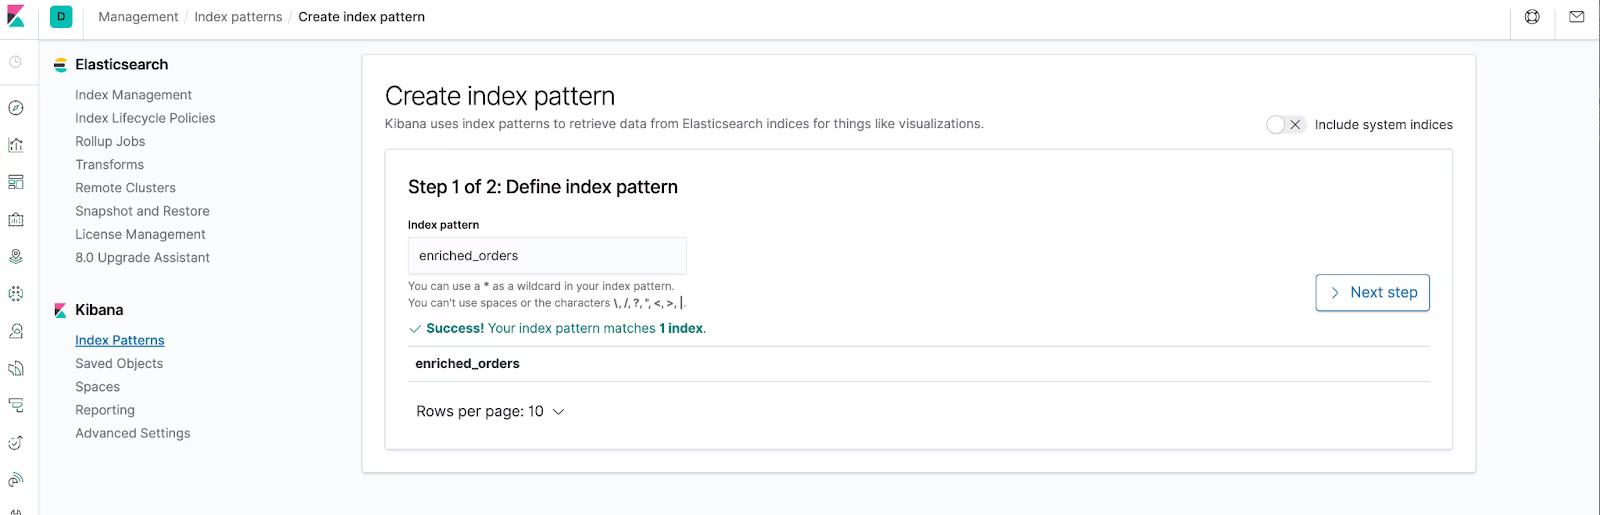
You can see the written data at [http://localhost:5601/app/kibana#/discover](http://localhost:5601/app/kibana#/discover).
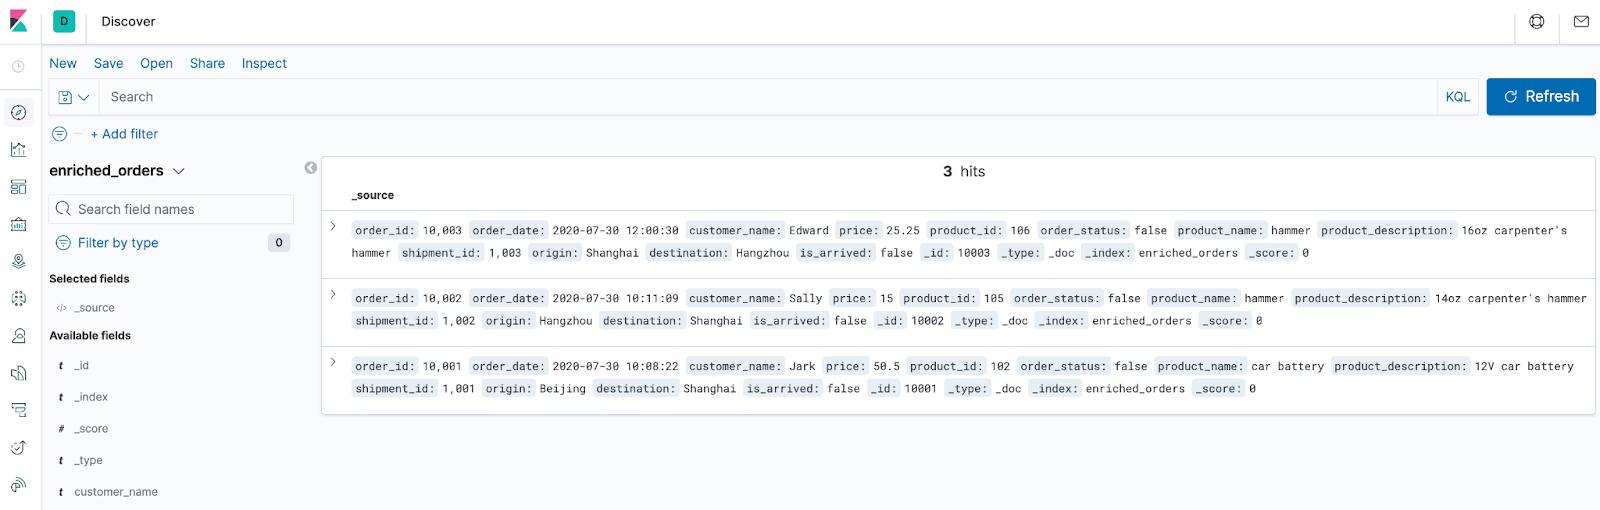
Next, modify the data in the tables in the MySQL and Postgres databases and the orders data displayed in Kibana will also be updated in real time.
Insert a piece of data into a MySQL orders table
```sql
INSERT INTO orders
VALUES (default, '2020-07-30 15:22:00', 'Jark', 29.71, 104, false);
```
Update the status of an order in the MySQL orders table
```sql
UPDATE orders SET order_status = true WHERE order_id = 10004;
```
Insert a piece of data into the Postgres shipments table
```sql
INSERT INTO shipments
VALUES (default,10004,'Shanghai','Beijing',false);
```
Update the status of a shipment in the Postgres shipments table
```sql
UPDATE shipments SET is_arrived = true WHERE shipment_id = 1004;
```
Delete a piece of data in the MYSQL orders table.
```sql
DELETE FROM orders WHERE order_id = 10004;
```
Refresh Kibana to see the updated data.
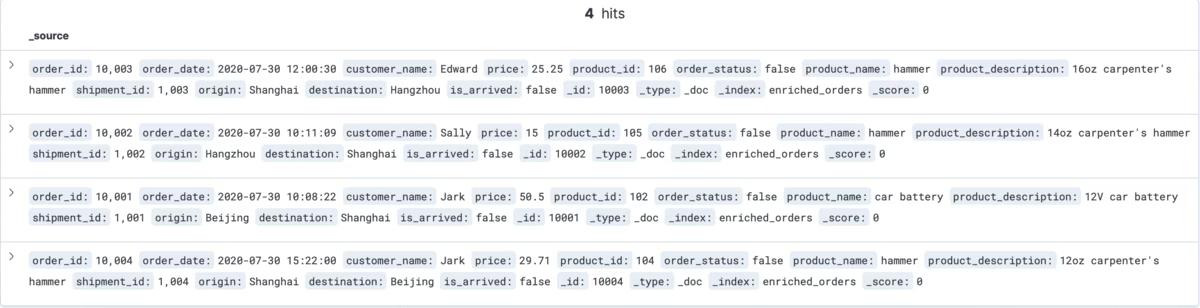
## Step 9: Clean the environment
After performing all the steps, run the following command in directory to stop all the containers.
```bash
docker-compose down
```
Change directory to flink-1.16.0 and execute the following command to stop the Flink cluster.
```bash
./bin/stop-cluster.sh
```
---
---
title: "Streaming modes of Flink-Kafka connectors"
description: "Explore the Flink-Kafka connectors in the Table API, focusing on append and upsert modes, and learn which is best for your data streaming needs."
lastUpdated: 2026-05-29T11:03:33.000Z
source_url:
html: "https://www.ververica.com/blog/streaming-modes-of-flink-kafka-connectors"
md: "https://www.ververica.com/blog/streaming-modes-of-flink-kafka-connectors.md"
---
This blog post will guide you through the Kafka connectors that are available in the Flink Table API. By the end of this blog post, you will have a better understanding of which connector is more suitable for a specific application.
Flink DataStream API provides Kafka connector, which works in _append_ mode and can be used by your Flink program written in the Scala/Java API. Besides that, Flink has the Table API which offers two Kafka connectors:
- [Kafka](https://nightlies.apache.org/flink/flink-docs-master/docs/connectors/table/kafka/) - unbounded **source,** uses "append mode” for **sink**
- [Upsert Kafka](https://nightlies.apache.org/flink/flink-docs-master/docs/connectors/table/upsert-kafka/)- unbounded **source,** uses “upsert mode” for **sink**
This blog post will exclusively concentrate on Kafka connectors for the Table API. I will also attempt to answer the question of when to use a Kafka connector (append) or opt for an Upsert Kafka connector.
## Simple Kafka Connector - Append Mode
The following example is copying data from a generated in-memory data stream to an output Kafka topic. In production scenarios, input data can be enriched or aggregated, but we are going to keep this example simple to show Flink’s behavior when it uses the first Kafka connector.
First, create a table with orders as a source of streaming data that are generated by the datagen connector:
```sql
CREATE TABLE `orders` (
`id` INT,
bid_price DOUBLE,
`order_time` AS TIMESTAMPADD(DAY, CAST(FLOOR(RAND() * -3 + 5) * -1 AS INTEGER), CURRENT_TIMESTAMP)
)
COMMENT ''
WITH (
'connector' = 'datagen',
'fields.id.kind' = 'random',
'fields.id.max' = '100',
'fields.id.min' = '1',
'rows-per-second' = '100'
);
```
Then, create an output table as a sink to store input data with the kafka connector:
```sql
CREATE TABLE orders_sink_append (
`id` INT,
bid_price DOUBLE,
`order_time` TIMESTAMP(3)
)
COMMENT ''
WITH (
'connector' = 'kafka',
'key.format' = 'csv',
'key.fields' = 'id',
'properties.bootstrap.servers' = '....kafka.svc.cluster.local:9092',
'topic' = 'orders_sink_append',
'scan.startup.mode' = 'earliest-offset',
'properties.group.id' = 'orders-sink-append',
'value.format' = 'csv'
);
```
In order to run all Flink code examples in this post, you will need to use Ververica Platform (VVP), which can be easily installed on any Kubernetes cluster:
- [VVP Documentation: Installation](https://docs.ververica.com/installation/index.html)
- [Getting Started with Ververica Platform on Google Kubernetes Engine](https://www.ververica.com/blog/getting-started-with-da-platform-on-google-kubernetes-engine)
Execute above table DDLs to register new tables in VVP’s built-in catalog. This can be done by opening VVP -> SQL -> Editor window. Then select every “CREATE TABLE … ;” statement separately and click “Run Selection” on the right hand-side.
Now we can create and start a Flink SQL Deployment in VVP with the following SQL script. It will store the generated data stream continuously to a Kafka topic with Kafka connector, i.e., running in the append mode. Run below SQL query by selecting it and clicking “Run Selection”.
```sql
INSERT INTO orders_sink_append SELECT * FROM orders;
```
VVP will take you through the new VVP Deployment process. Just follow it and click the Start button.
Here is the overview of the VVP Deployment created from the SQL query above:
and the Job Graph:
Let’s check how the output from _**orders_sink_append**_ topic/table looks like:
```sql
SELECT * FROM orders_sink_append;
```
You can see that the client session in the VVP SQL Editor identifies all the data in the table with Kafka connector as **Inserts** (note +I in the _Kind_ column). It implies that consumers should treat all the input data as appends.
To fulfill a business requirement of obtaining the most recent value for each key, consumers must use deduplication/grouping logic per order_id. This can be done by an external program which does this in memory, as well as by another Flink job which would group records by _order_id_ and sort them over _order_time_ using it as event time. So there are a couple options which could be applied further to get the latest _bid_price_ per _order_id_.
## Kafka Connector - Upsert Mode
Let’s look at another connector and what it makes different.
The input table definition stays the same, but the sink connector is set to “upsert-kafka”. For clarity, let’s create a clone table with the “upsert-kafka” connector.
```sql
CREATE TABLE orders_sink_upserts (
`id` INT,
bid_price DOUBLE,
`order_time` TIMESTAMP(3),
PRIMARY KEY (`id`) NOT ENFORCED
)
COMMENT ''
WITH (
'connector' = 'upsert-kafka',
'key.format' = 'csv',
'properties.bootstrap.servers' = '....kafka.svc.cluster.local:9092',
'topic' = 'order_upserts',
'properties.group.id' = 'order-upserts-consumers',
'value.format' = 'csv'
);
```
Similar to the previous section, we create another VVP Deployment to store data into the table orders_sink_upserts with the “upsert-kafka” connector and the following SQL statement
```sql
INSERT INTO orders_sink_upserts SELECT * FROM orders;
```
The overview of the VVP deployment and the job graph looks similar as before:
Topology of the Flink Job graph remains the same:
Below, you will find the output from _**orders_sink_upsert**_ topic/table:
```sql
SELECT * FROM orders_sink_upsert;
```
You can see that the VVP SQL Editor session is showing 100 Inserts (-I) and then the rest of the changes are Updates (+U, -U). There are 100 unique order Ids configured in **datagen**. That is the reason for getting 100 inserts only here and all the rest are updates to those 100 unique orders.
This is the main difference between the two streaming modes “append” and “upsert”, when you are working with a Kafka backed SQL table. Upsert mode makes it easy to get either the latest changes or understand whether streaming data is new or should be treated as an update or deletion. Deletion would be detected when any value for a specific key is NULL.
How does “upsert-kafka” detect the upserts? First of all, any Table using “upsert-kafka” connector must have a primary key. In case of the example above, it is:
```sql
PRIMARY KEY (`id`) NOT ENFORCED
```
You can also see that Flink injects one more operator “ChangeLogNormalize'' when consuming data from the “upsert-kafka” table. Injected operator aggregates input data and returns the latest record for a specific primary key. Below is one more VVP Deployment to show this effect. It prints the data from upsert table to the standard output:
```sql
CREATE TEMPORARY TABLE SinkTable WITH ('connector' = 'print') LIKE orders_sink_upserts (EXCLUDING OPTIONS);
INSERT INTO SinkTable SELECT * FROM orders_sink_upserts;
```
In contrast, if you read data from table `orders_sink_append` where the kafka connector works in the append mode, Flink does not inject ChangelogNormalize operator into the job graph:
```sql
CREATE TEMPORARY TABLE SinkTable
WITH ('connector' = 'print')
LIKE orders_sink_append
(EXCLUDING OPTIONS);
INSERT INTO SinkTable SELECT * FROM orders_sink_append;
```
## Join tables: upsert vs. append mode
The two different streaming modes make a big difference when multiple tables are joined together. This difference may lead to data duplication. The following example is showing how to avoid data duplication when joining two Flink tables backed by Kafka topics. Here is an example Flink SQL job about Taxi rides. We have a registry of cars, each has a carClass “Blue” or “Black” in the first table. Hypothetically, each car class has its own ride rate. The second table contains car assignments across New York City boroughs (Brooklyn, Queens, etc.). As cars move, an assignment event is generated and transmitted to our streaming pipeline. This allows us to keep track of the changing location of the cars. Ultimately, the business goal is to answer the question which cars are currently assigned to a particular borough.
Below are minimized table DDLs to get an idea of table schemas, full definitions are defined further:
```sql
CREATE TABLE `cars` (
`carId` INT NOT NULL,
`carClass` VARCHAR(50)
)...
CREATE TABLE `assignments` (
`carId` INT NOT NULL,
`borough` VARCHAR(50)
)...
```
Business query:
```sql
SELECT
borough, carClass, collect(carId) AS carIds
FROM (
SELECT c.carId, borough, carClass
FROM cars c JOIN assignments a
ON c.carId = a.carId
)
GROUP BY borough, carClass;
```
## Using Append Mode
First, look at the append mode. When joining append-based tables you may end up with duplicates unless you apply deduplication logic as part of the business logic. Duplicates arise when a car changes its borough, i.e. the same car Id over the time may have different borough assigned.
Append mode sink table:
```sql
CREATE TABLE cars (
carId INT NOT NULL,
carClass VARCHAR(50)
) WITH (
'connector' = 'kafka',
'key.format' = 'csv',
'key.fields' = 'carId',
'properties.group.id' = 'sample-group-cars',
'scan.startup.mode' = 'earliest-offset',
'properties.bootstrap.servers' = '....kafka.svc.cluster.local:9092',
'topic' = 'cars',
'value.format' = 'csv'
);
CREATE TABLE assignments (
carId INT NOT NULL,
borough VARCHAR(50)
) WITH (
'connector' = 'kafka',
'key.format' = 'csv',
'key.fields' = 'carId',
'properties.group.id' = 'sample-group',
'scan.startup.mode' = 'earliest-offset',
'properties.bootstrap.servers' = ....kafka.svc.cluster.local:9092',
'topic' = 'assignments',
'value.format' = 'csv'
);
```
Set your own Kafka servers in _properties.bootstrap.servers_ property, if you want to try this example yourself.
Next, let’s define, another SQL script to generate data and store into both tables:
```sql
CREATE TEMPORARY TABLE assignments_log (
carId INT NOT NULL,
borough VARCHAR(50)
) WITH (
'connector' = 'faker',
'rows-per-second' = '1',
'fields.carId.expression' = '#{number.numberBetween ''1'',''10''}',
'fields.borough.expression' = '#{regexify ''(Brooklyn|Queens|Staten Island|Manhattan|Bronx){1}''}'
);
BEGIN STATEMENT SET;
INSERT INTO cars VALUES
(1, 'Blue'), (2, 'Black'), (3, 'Premium'),
(4, 'Blue'), (5, 'Black'), (6, 'Premium'),
(7, 'Blue'), (8, 'Black'), (9, 'Premium');
INSERT INTO assignments SELECT * FROM assignments_log;
END;
```
Running the _business query_ you defined earlier:
You can see a problem here. Why is the same car (id = 1 or 2) assigned to multiple boroughs as it should be assigned to a single borough at a time?
## Investigation
Aggregation function “collect” returns a [multiset](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/types/#multiset), which contains key value pairs. Each key is the value from the respective table column (i.e., carId). Each value in the pair is a number of occurrences for that key. A multiset “{1=27, 3=56}” for the Staten Island borough means a car with an id equal to ‘1’ is assigned 27 times and carId with id ‘3’ is assigned 56 times in the Staten Island borough. That means that the same car exists in 27 places at the same time, which is not possible as long as we are in the same universe 😂. Taxi cars are unique, they have unique ids. We want to see **where** a particular car is assigned at the current moment. In order to solve this, we can deduplicate _assignment_ events based on a time attribute, which needs to be added. Official [“Deduplication”](https://nightlies.apache.org/flink/flink-docs-release-1.16/docs/dev/table/sql/queries/deduplication/) recipe from Flink documentation can be applied too. However, we can solve this problem without manual deduplication, by just using “upsert-kafka” tables instead.
## Using Upsert Mode
Let’s re-create the input tables with the upsert-kafka connector:
```sql
CREATE TABLE assignments (
carId INT NOT NULL,
borough VARCHAR(50),
PRIMARY KEY (carId) NOT ENFORCED
) WITH (
'connector' = 'upsert-kafka',
'key.format' = 'csv',
'properties.group.id' = 'sample-group',
'properties.bootstrap.servers' = '....kafka.svc.cluster.local:9092',
'topic' = 'assignments',
'value.format' = 'csv'
);
CREATE TABLE cars (
carId INT NOT NULL,
carClass VARCHAR(50),
PRIMARY KEY (carId) NOT ENFORCED
) WITH (
'connector' = 'upsert-kafka',
'key.format' = 'csv',
'properties.group.id' = 'sample-group-cars',
'properties.bootstrap.servers' = '....kafka.svc.cluster.local:9092',
'topic' = 'cars',
'value.format' = 'csv'
);
```
Finally, let’s run the same business query. This time, you get desired car assignments in real time:
There are no cars (car ids) which exist more than one time at any given borough. Above animation is recorded within 12 seconds. Every second, you get a migration of one of the cars to another borough which makes real sense, as a new event is generated and sent to the “assignment” table/topic per second. The values in the multiset are always equal to 1, which is another test case that proves the query’s correctness.
Below is the Job Graph for the business query using tables that are backed by the upsert-kafka connector:
Both input tables are first normalized before they are joined by the join operator.
## Summary
The Kafka connector in Flink SQL can work in two streaming modes. **Upsert mode** allows us to get the latest value for a specific entity automatically without any manual deduplication. One of the typical scenarios where you can leverage this mode is a SQL join of two tables, where one of the tables is keeping history of changes per some entity id. Once you join on such an entity id which is non-unique by design, you get unwanted rows, but you usually want to see the latest value of that entity. With upsert mode, Flink automatically normalizes before the tables are joined. Eventually it allows you to easily answer typical business questions on getting a real-time view of the shared resources like cars, planes, workers, etc.
**Append mode** is still an option to go with, if a business query does not need to filter out all historical events, but rather show the history of changes at the end. In this scenario, query may run faster with append mode, as Flink does not need to do any changelog normalization.
---
---
title: "How to test your Flink SQL Application"
description: "Learn effective methods for testing your Apache Flink SQL applications, including manual and automated testing techniques and best practices for different Flink versions."
lastUpdated: 2026-05-29T11:38:01.000Z
source_url:
html: "https://www.ververica.com/blog/how-to-test-flink-sql-application"
md: "https://www.ververica.com/blog/how-to-test-flink-sql-application.md"
---
Testing your Apache Flink SQL code is a critical step in ensuring that your application is running smoothly and provides the expected results. Flink SQL applications are used for a wide range of data processing tasks, from complex analytics to simple SQL jobs. A comprehensive testing process can help identify potential issues early in the development process and ensure that your application works as expected.
This post will go through several testing possibilities for your Flink SQL application.
## Manual vs Automated Testing
Using a SQL client is an effective way to quickly and easily test your Flink SQL code. SQL clients are designed to provide an interactive environment where you can run SQL queries and view the results. This makes it easy to test your code and make changes quickly.
However, you can mostly only perform manual testing with SQL clients. For more comprehensive testing, you should use automated testing tools. Automated testing tools can provide a way to test your code with multiple data sets and various scenarios. This can help identify issues that may not be immediately visible in manual testing.
Automated tests include unit and integration testing. Unit tests are used to test individual components of the application, while integration tests are used to test the integration between different components. Both of them help identify issues related to data processing, such as incorrect SQL syntax or incorrect data transformation.
## Testing via Unit & Integration Tests
This testing method involves using unit and integration tests to validate the behavior of your code. It is easy to automate, which makes it a convenient option for testing smaller units, such as parts of a query or function. Additionally, it is highly customizable, allowing you to define individual test scenarios with specific input data without changelog streams and control over row time attributes.
Another benefit of this approach is that it allows for quick turnaround times when developing user-defined functions. This can help you identify type inferencing problems and other issues early in the development process.
However, this testing method involves using non-SQL code, which may require some knowledge of Java or Scala to use it effectively. This could include understanding the syntax and basic concepts of these programming languages, as well as any specialized libraries or frameworks that are used with them. While this may require some upfront investment in learning, it can be a great way for those who are familiar with these languages and are looking to automate certain processes or tasks.
### Unit & Integration Tests in Flink 1.12 or below
If you need to supply input data for testing purposes, one option is to use the `TableEnvironment.fromValues()` method. However, it is important to note that this method only supports inserts and does not allow for changelog streams. Additionally, it does not provide any control over the order of the data, which may be necessary in some cases. Furthermore, there are no rowtime or watermarking options available.
An alternative approach is to use the values connector with the `TestValuesTableFactory`. This allows you to define input tables using the full range of options available in the table DDL. This includes the ability to specify rowtime and watermarking attributes, as well as any other specialties of the table DDL. However, it is important to note that this is a non-public API, which means it is not intended for use in production environments and may not be fully supported by the vendor.
If you want to collect the results of a query or operation in a table, one option is to use the `TableResult.collect()`method. This method retrieves the results as a `CloseableIterator`, which is a specialized iterator that allows you to iterate over the rows in the result set.
To create a shared Flink cluster, you will need to follow a few steps:
1. **Initialize the stream environment:** This involves creating an instance of the `StreamExecutionEnvironment`class and configuring it with the appropriate settings, such as the parallelism and checkpointing parameters.
1. **Initialize the table environment:** This involves creating an instance of the `StreamTableEnvironment` class and linking it to the stream environment allowing you to use the Table API to define and manipulate tables.
1. **Define the input table:** This involves creating a table from data in an external source, such as a file or a database. You can use the table API or SQL to define the schema and transform the data as needed.
1. **Run the query and retrieve the results:** Once you have defined the input table, you can run a query or perform some other operation on it. You can then use the `collect()` method or another method to retrieve the results as a `TableResult`object.
1. **Test and verification:** Finally, you will want to verify that the results are correct and meet your expectations. You can do this by manually inspecting the results, comparing them to expected values, or using automated testing techniques.
```java
import org.junit.Before;
import org.junit.ClassRule;
import org.junit.Test;
import static org.hamcrest.Matchers.containsInAnyOrder;
import static org.junit.Assert.assertThat;
/** Integration test for the built-in LISTAGG function. */
public class ListAggITCase112 {
@ClassRule
public static MiniClusterWithClientResource flinkCluster =
new MiniClusterWithClientResource(
new MiniClusterResourceConfiguration.Builder()
.setNumberSlotsPerTaskManager(4)
.setNumberTaskManagers(1)
.build());
protected StreamExecutionEnvironment env;
protected StreamTableEnvironment tEnv;
@Before
public void setUp() {
env = StreamExecutionEnvironment.getExecutionEnvironment();
// configure environment as needed
env.setParallelism(4);
env.getConfig().setRestartStrategy(RestartStrategies.noRestart());
env.setStateBackend(new RocksDBStateBackend((StateBackend) new MemoryStateBackend()));
// create table environment
tEnv =
StreamTableEnvironment.create(
env, EnvironmentSettings.newInstance().useBlinkPlanner().inStreamingMode().build());
TestValuesTableFactory.clearAllData();
// initialize and register any UDFs you need, e.g.
// tEnv.createTemporaryFunction("MyUDF", MyUDF.class);
}
private void createSource(Row... inputData) {
// can use this instead if there are only inserts and no need for row times, watermarks,...:
// tEnv.createTemporaryView("input", tEnv.fromValues((Object[]) inputData));
final String createSource =
String.format(
"CREATE TABLE input ( \n"
+ " `name` STRING,\n"
+ " `age` INT"
+ ") WITH (\n"
+ " 'connector' = 'values',\n"
+ " 'data-id' = '%s',\n"
+ " 'changelog-mode' = 'I,UA,UB,D'\n"
+ ")", TestValuesTableFactory.registerData(Arrays.asList(inputData)));
tEnv.executeSql(createSource);
}
private List getResult() throws Exception {
TableResult resultTable =
tEnv.executeSql("SELECT age, LISTAGG(DISTINCT name) FROM input GROUP BY age");
return getRowsFromTable(resultTable);
}
private static List getRowsFromTable(TableResult resultTable) throws Exception {
try (CloseableIterator rowCloseableIterator =
resultTable.collect()) {
List results = new ArrayList<>();
rowCloseableIterator.forEachRemaining(results::add);
return results;
}
}
@Test
public void testListAgg() throws Exception {
createSource(
Row.ofKind(RowKind.INSERT, "john", 32),
Row.ofKind(RowKind.UPDATE_BEFORE, "john", 32),
Row.ofKind(RowKind.UPDATE_AFTER, "john", 33));
assertThat(
getResult(),
containsInAnyOrder(
Row.ofKind(RowKind.INSERT, 32, "john"),
Row.ofKind(RowKind.DELETE, 32, "john"),
Row.ofKind(RowKind.INSERT, 33, "john")));
}
}
```
### Unit & Integration Tests in Flink 1.13 or above
If you need to supply input data for testing purposes in Flink 1.13 (or later), one option is to use the `TableEnvironment.fromValues()`method. However, it is important to note that this method has the same limitations as in previous versions of Flink (1.12 or earlier).
An alternative approach is to use the `StreamTableEnvironment.fromChangelogStream()` method, which allows you to define the input as a `DataStream` or `DataStream` with RowKind attributes. This method offers automatic type conversion and preserves event-time and watermarks across operations. Furthermore, it allows you to define custom schema definitions just like in a table DDL, providing greater flexibility and control over the input data. Overall, using the `fromChangelogStream()` method can be a more powerful and versatile way to supply input data for testing in Flink 1.13 (or later).
If you want to collect the results of a query or operation in a table, one option is to use the `TableResult.collect()` method. This method retrieves the results as a `CloseableIterator`, which is a specialized iterator that allows you to iterate over the rows in the result set.
One of the advantages of using the `collect()` method is that it allows for fine-grained comparisons of the results, including the RowKind attributes. RowKinds are used to indicate the type of change that occurred to a row in a changelog stream, and can have values such as "+I" (insert), "-U" (update), "+U" (update), and "-D" (delete). By comparing the RowKinds of the actual results to the expected values, you can more easily identify any discrepancies or issues with the query or operation.
```java
protected StreamExecutionEnvironment env;
protected StreamTableEnvironment tEnv;
/** Integration test for the built-in LISTAGG function. */
public class ListAggITCase112 {
@ClassRule
public static MiniClusterWithClientResource flinkCluster =
new MiniClusterWithClientResource(
new MiniClusterResourceConfiguration.Builder()
.setNumberSlotsPerTaskManager(4)
.setNumberTaskManagers(1)
.build());
@Before
public void setUp() {
env = StreamExecutionEnvironment.getExecutionEnvironment();
// configure environment as needed
env.setParallelism(4);
env.getConfig().setRestartStrategy(RestartStrategies.noRestart());
env.setStateBackend(new EmbeddedRocksDBStateBackend());
env.getCheckpointConfig().setCheckpointStorage(new JobManagerCheckpointStorage());
// create table environment
// use EnvironmentSettings.newInstance().useBlinkPlanner() to get the planner if using Flink 1.13 or 1.14
tEnv =
StreamTableEnvironment.create(
env, EnvironmentSettings.newInstance().inStreamingMode().build());
// initialize and register any UDFs you need, e.g.
// tEnv.createTemporaryFunction("MyUDF", MyUDF.class);
}
private void createSource(Row... inputData) {
DataStreamSource changelogStream = env.fromElements(inputData);
tEnv.createTemporaryView("input",
tEnv.fromChangelogStream(changelogStream).as("name", "age"));
}
private List getResult() throws Exception {
Table resultTable = tEnv.sqlQuery("SELECT age, LISTAGG(DISTINCT name) FROM input GROUP BY age");
DataStream resultStream = tEnv.toChangelogStream(resultTable);
return getRowsFromDataStream(resultStream);
}
private static List getRowsFromDataStream(DataStream resultStream) throws Exception {
try (CloseableIterator rowCloseableIterator = resultStream.executeAndCollect()) {
List results = new ArrayList<>();
rowCloseableIterator.forEachRemaining(results::add);
return results;
}
}
@Test
public void testListAgg() throws Exception {
createSource(
Row.ofKind(RowKind.INSERT, "john", 32),
Row.ofKind(RowKind.UPDATE_BEFORE, "john", 32),
Row.ofKind(RowKind.UPDATE_AFTER, "john", 33));
assertThat(
getResult(),
containsInAnyOrder(
Row.ofKind(RowKind.INSERT, 32, "john"),
Row.ofKind(RowKind.DELETE, 32, "john"),
Row.ofKind(RowKind.INSERT, 33, "john")));
}
```
> **NOTE:** Use EnvironmentSettings.newInstance().useBlinkPlanner() to get the planner if you are using Flink 1.13 or 1.14.
## Conclusion
There are several testing possibilities for SQL queries and Table API constructs in Flink. One option is to manually verify the results by executing the queries and inspecting the output. This can be a quick and easy way to test small changes or simple queries, but it may not be practical for larger or more complex cases.
Another option is to use automated tests written in Java or Scala. This can be more efficient and allow you to test a wider range of scenarios, including edge cases and error conditions. Automated tests can be run as part of a continuous integration or delivery pipeline, helping to ensure that your code is reliable and behaves as expected.
The specific APIs and tools available for testing may vary depending on the version of Flink that you are using. For example, in Flink 1.12 (or earlier), you may have access to certain testing APIs and utilities that are not available in Flink 1.13 (or later). It is important to familiarize yourself with the testing capabilities of your specific version of Flink in order to choose the best approach for your needs.
## Resources and further reading:
- [DataStreamJavaITCase](https://github.com/apache/flink/blob/release-1.13.0/flink-table/flink-table-planner-blink/src/test/java/org/apache/flink/table/planner/runtime/stream/sql/DataStreamJavaITCase.java) is an elaborate example of unit-testing with fromChangelogStream()/toChangelogStream() and similar DataStream interoperability tools
- [SQL/Table API ↔ DataStream conversion](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/data_stream_api/)
- [DataStream API Testing](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/datastream/testing/)
---
---
title: "Flink SQL: Detecting patterns with MATCH_RECOGNIZE"
description: "Discover how to use MATCH_RECOGNIZE in Flink SQL for detecting patterns in data, enabling real-time insights through effective event processing."
lastUpdated: 2026-06-02T06:41:32.000Z
source_url:
html: "https://www.ververica.com/blog/flink-sql-match-recognize"
md: "https://www.ververica.com/blog/flink-sql-match-recognize.md"
---
[Flink SQL](https://www.ververica.com/apache-flink-sql-on-ververica-platform#bgimage3) has emerged as the de facto standard for [low-code data analytics](https://www.ververica.com/ververica-platform-enterprise-stream-processing-and-streaming-analytics). It has managed to unify batch and stream processing while simultaneously staying true to the SQL standard. In addition, it provides a rich set of advanced features for real-time use cases. In a nutshell, Flink SQL is the best of both worlds: it gives you the ability to **process streaming data using SQL, but it also supports batch processing.**
Ververica Platform makes Flink SQL even more accessible and efficiently scalable across teams. The platform comes with additional tools for developing SQL scripts, managing user-defined functions (UDFs), catalogs and connectors, as well as operating the resulting long-running queries.
We have seen that there are many [use cases](https://youtu.be/AxBNj6yOEZI) for Flink SQL, and we are excited to see what you will build with it. In this blog post, we will show you what you can do with the [MATCH_RECOGNIZE](https://nightlies.apache.org/flink/flink-docs-release-1.16/docs/dev/table/sql/queries/match_recognize/) function.
## What is MATCH_RECOGNIZE?
MATCH_RECOGNIZE is a clause in the SQL standard that allows you to detect patterns in your data. It is similar to the regular expression functionality in many programming languages.
MATCH_RECOGNIZE allows you to:
- Define patterns
- Match data against those patterns
- Extract parts of the data that match the patterns
- Perform actions on the data that match the patterns
For example, you could use MATCH_RECOGNIZE to find all the rows in a table that represent a stock price trend. You could then extract the data that matched the pattern and perform further analysis on it.
A common (but historically complex) task in SQL day-to-day work is to identify meaningful sequences of events in a data set — also known as [Complex Event Processing](https://nightlies.apache.org/flink/flink-docs-master/docs/libs/cep/) (CEP). This becomes even more relevant when dealing with streaming data because you want to react quickly to known patterns or changing trends to deliver up-to-date business insights. In Flink SQL, you can easily perform this kind of task using the standard SQL clause [MATCH_RECOGNIZE](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/streaming/match_recognize.html).
## An example of how to use MATCH_RECOGNIZE
In this example, you will use Flink SQL and MATCH_RECOGNIZE to find users that downgraded their service subscription from one of the premium tiers (`type IN ('premium ',' platinum')`) to the basic tier.
### The full Flink SQL query
The source table (subscriptions) is backed by the [faker connector](https://flink-packages.org/packages/flink-faker), which continuously generates rows in memory based on Java Faker expressions.
```sql
CREATE TABLE subscriptions (
id STRING,
user_id INT,
type STRING,
start_date TIMESTAMP(3),
end_date TIMESTAMP(3),
payment_expiration TIMESTAMP(3),
proc_time AS PROCTIME()
) WITH (
'connector' = 'faker',
'fields.id.expression' = '#{Internet.uuid}',
'fields.user_id.expression' = '#{number.numberBetween ''1'',''50''}',
'fields.type.expression'= '#{regexify ''(basic|premium|platinum){1}''}',
'fields.start_date.expression' = '#{date.past ''30'',''DAYS''}',
'fields.end_date.expression' = '#{date.future ''15'',''DAYS''}',
'fields.payment_expiration.expression' = '#{date.future ''365'',''DAYS''}'
);
SELECT *
FROM subscriptions
MATCH_RECOGNIZE (PARTITION BY user_id
ORDER BY proc_time
MEASURES
LAST(PREMIUM.type) AS premium_type,
AVG(TIMESTAMPDIFF(DAY,PREMIUM.start_date,PREMIUM.end_date)) AS premium_avg_duration,
BASIC.start_date AS downgrade_date
AFTER MATCH SKIP PAST LAST ROW
--Pattern: one or more 'premium' or 'platinum' subscription events (PREMIUM)
--followed by a 'basic' subscription event (BASIC) for the same `user_id`
PATTERN (PREMIUM+ BASIC)
DEFINE PREMIUM AS PREMIUM.type IN ('premium','platinum'),
BASIC AS BASIC.type = 'basic');
```
### Input
The input argument of `MATCH_RECOGNIZE` will be a row pattern table based on `subscriptions`. As a first step, logical partitioning and ordering must be applied to the input row pattern table to ensure that event processing is correct and deterministic:
```sql
PARTITION BY user_id
ORDER BY proc_time
```
### Output
Row pattern columns are then defined in the `MEASURES` clause, which can be thought of as the `SELECT` of `MATCH_RECOGNIZE`. If you're interested in getting the type of premium subscription associated with the last event before the downgrade, you can fetch it using the [logical offset](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/streaming/match_recognize.html#logical-offsets) operator `LAST`. The downgrade date can be extrapolated from the `start_date` of the first basic subscription event following any existing premium one(s).
The `AFTER MATCH SKIP` clause specifies where pattern matching resumes after a non-empty match is found. The default option is `AFTER MATCH SKIP PAST LAST ROW`, which specifies that pattern matching starts from the row after the last row of the match.
```sql
MEASURES
LAST(PREMIUM.type) AS premium_type,
AVG(TIMESTAMPDIFF(DAY,PREMIUM.start_date,PREMIUM.end_date)) AS premium_avg_duration,
BASIC.start_date AS downgrade_date
AFTER MATCH SKIP PAST LAST ROW
```
### Pattern Definition
Patterns are specified in the `PATTERN` clause using row-pattern variables (i.e. event types) and regular expressions. These variables must also be associated with the matching conditions that events must meet to be included in the pattern, using the `DEFINE` clause. Here, you are interested in matching one or more premium subscription events (`PREMIUM+`) followed by a basic subscription event (`BASIC`):
```sql
PATTERN (PREMIUM+ BASIC)
DEFINE PREMIUM AS PREMIUM.type IN ('premium','platinum'),
BASIC AS BASIC.type = 'basic');
```
### Ververica Platform SQL Editor
This is how the query looks when executed in the Ververica Platform SQL editor:
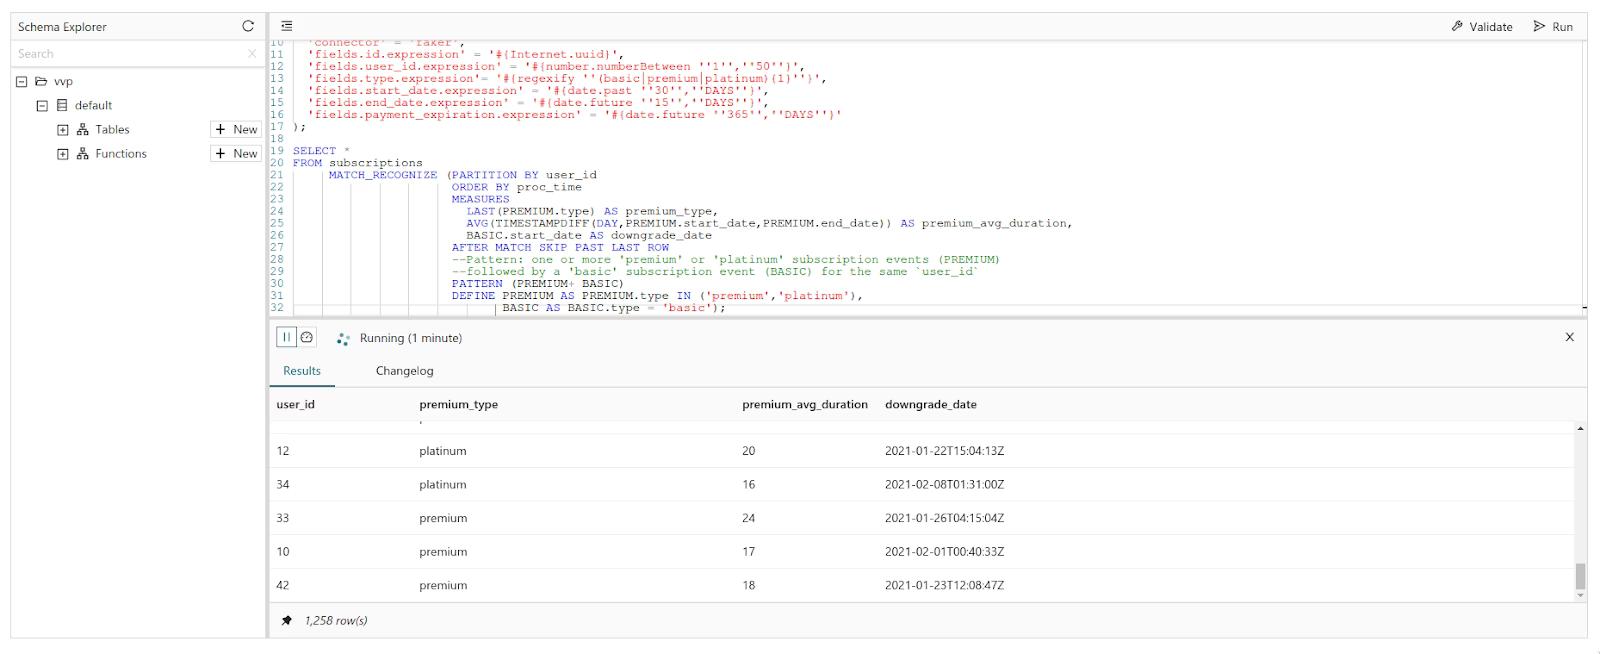
## Conclusion
In this article, you learned about detecting patterns with the MATCH_RECOGNIZE function. You also saw how to use Flink SQL to write queries for this type of problem.
---
---
title: "Flink SQL: Queries, Windows, and Time - Part 2"
description: "Explore the intricacies of Flink SQL with in-depth examples on time windows, including chained, non-chained, hopping, and rolling aggregations for effective data analysis."
lastUpdated: 2026-06-02T06:42:03.000Z
source_url:
html: "https://www.ververica.com/blog/flink-sql-queries-and-time-part-2"
md: "https://www.ververica.com/blog/flink-sql-queries-and-time-part-2.md"
---
In the [previous article](https://4757017.hs-sites.com/blog/flink-sql-queries-and-time), we covered some aspects of time windows and time attributes that you should consider when planning your data collection strategy. This article will provide a more in-depth look at how to create a time window.
> **NOTE:** A time window is the period of time over which data is collected. The length of the time window will depend on the type of data being collected and the purpose of the study. For example, if you are interested in studying the effects of a new product on consumer behavior, you would need to collect data over a longer period of time than if you were interested in studying the effects of a new marketing campaign on sales.
When selecting a time window for your case, you should consider the following attributes:
- **Frequency of the data**: If the data is collected daily, weekly, monthly, etc.
- **Seasonality of the data**: If the data is affected by seasonality (e.g. sales data is typically higher during the holiday season), you will need to take this into account when selecting a time window.
- **Stability of the data**: If the data is volatile (e.g. stock prices), you will need to take this into account when selecting a time window.
- **Length of the time window**: The length of the time window will depend on the type of data being collected and the purpose of the study.
Once you have considered the attributes of the data, you can select the most appropriate time window for your case.
## How to create chained (event) time windows
> **INFO:** This example will show you how to efficiently aggregate time series data on two different levels of granularity.
In this example, the source table (`server_logs`) is backed by the [faker connector](https://flink-packages.org/packages/flink-faker), which continuously generates rows in memory based on Java Faker expressions.
In the `server_logs` table, the average request size over one minute as well as five minute (event) windows will be computed. For this, you could run two queries, similar to the one in [Aggregating Time Series Data](https://github.com/ververica/flink-sql-cookbook/blob/main/aggregations-and-analytics/01_group_by_window/01_group_by_window.md) from the Flink SQL cookbook. At the end of the page, you will find the script and the resulting JobGraph from this approach.
In the main part of the query, you will follow a slightly more efficient approach that chains the two aggregations: the one-minute aggregation output serves as the five-minute aggregation input.
Chained operators can be more efficient than using non-chained operators in terms of both latency and memory utilization.
Regarding latency, chained event time windows can reduce the overall processing time by allowing for multiple window operations to be performed in a single pass over the data. This can lead to a reduction in the amount of time it takes for the final results to be produced.
As for memory utilization, chained operators can also be more efficient because one UDF can call another UDF directly. Otherwise, each of them will run in its own threads.
You will then use a [Statements Set](https://github.com/ververica/flink-sql-cookbook/blob/main/foundations/08_statement_sets/08_statement_sets.md) to write out the two result tables. To keep this example self-contained, you will use two tables of type `blackhole` (instead of `kafka`, `filesystem`, or any other [connectors](https://ci.apache.org/projects/flink/flink-docs-stable/docs/connectors/table/overview/)).
```sql
CREATE TEMPORARY TABLE server_logs (
log_time TIMESTAMP(3),
client_ip STRING,
client_identity STRING,
userid STRING,
request_line STRING,
status_code STRING,
size INT,
WATERMARK FOR log_time AS log_time - INTERVAL '15' SECONDS
) WITH (
'connector' = 'faker',
'fields.log_time.expression' = '#{date.past ''15'',''5'',''SECONDS''}',
'fields.client_ip.expression' = '#{Internet.publicIpV4Address}',
'fields.client_identity.expression' = '-',
'fields.userid.expression' = '-',
'fields.request_line.expression' = '#{regexify ''(GET|POST|PUT|PATCH){1}''} #{regexify ''(/search\.html|/login\.html|/prod\.html|cart\.html|/order\.html){1}''} #{regexify ''(HTTP/1\.1|HTTP/2|/HTTP/1\.0){1}''}',
'fields.status_code.expression' = '#{regexify ''(200|201|204|400|401|403|301){1}''}',
'fields.size.expression' = '#{number.numberBetween ''100'',''10000000''}'
);
CREATE TEMPORARY TABLE avg_request_size_1m (
window_start TIMESTAMP(3),
window_end TIMESTAMP(3),
avg_size BIGINT
)
WITH (
'connector' = 'blackhole'
);
CREATE TEMPORARY TABLE avg_request_size_5m (
window_start TIMESTAMP(3),
window_end TIMESTAMP(3),
avg_size BIGINT
)
WITH (
'connector' = 'blackhole'
);
CREATE TEMPORARY VIEW server_logs_window_1m AS
SELECT
TUMBLE_START(log_time, INTERVAL '1' MINUTE) AS window_start,
TUMBLE_ROWTIME(log_time, INTERVAL '1' MINUTE) AS window_end,
SUM(size) AS total_size,
COUNT(*) AS num_requests
FROM server_logs
GROUP BY
TUMBLE(log_time, INTERVAL '1' MINUTE);
CREATE TEMPORARY VIEW server_logs_window_5m AS
SELECT
TUMBLE_START(window_end, INTERVAL '5' MINUTE) AS window_start,
TUMBLE_ROWTIME(window_end, INTERVAL '5' MINUTE) AS window_end,
SUM(total_size) AS total_size,
SUM(num_requests) AS num_requests
FROM server_logs_window_1m
GROUP BY
TUMBLE(window_end, INTERVAL '5' MINUTE);
BEGIN STATEMENT SET;
INSERT INTO avg_request_size_1m SELECT
window_start,
window_end,
total_size/num_requests AS avg_size
FROM server_logs_window_1m;
INSERT INTO avg_request_size_5m SELECT
window_start,
window_end,
total_size/num_requests AS avg_size
FROM server_logs_window_5m;
END;
```
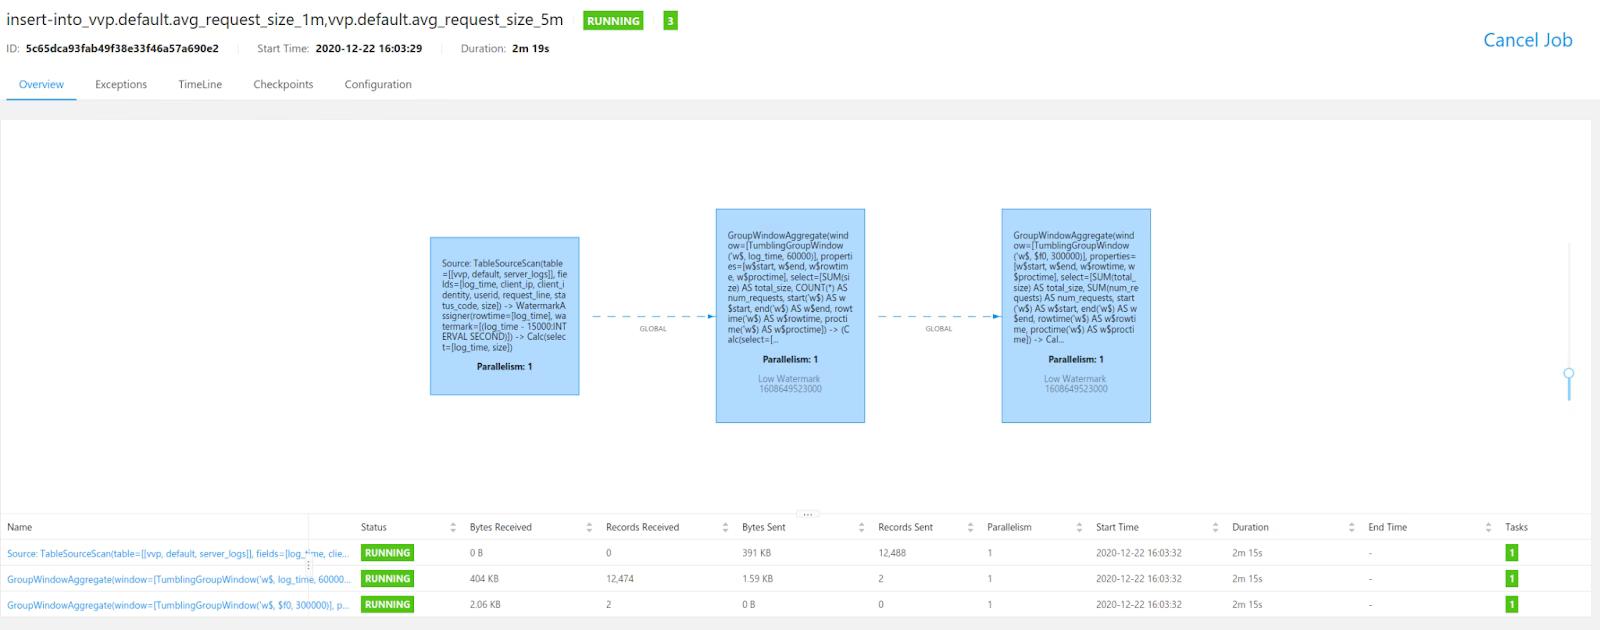
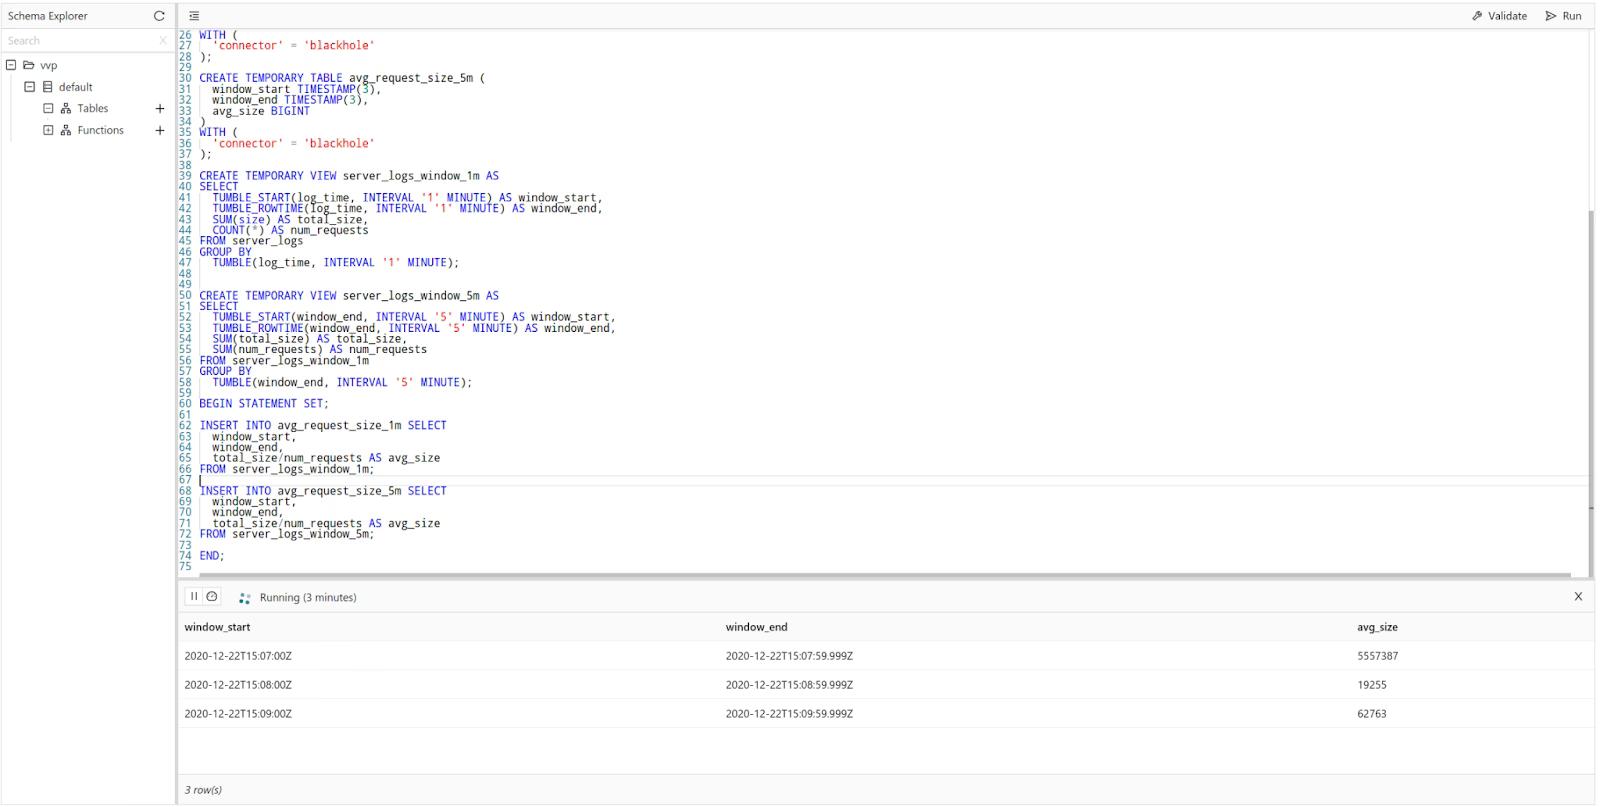
### How to create non-chained windows
```sql
CREATE TEMPORARY TABLE server_logs (
log_time TIMESTAMP(3),
client_ip STRING,
client_identity STRING,
userid STRING,
request_line STRING,
status_code STRING,
size INT,
WATERMARK FOR log_time AS log_time - INTERVAL '15' SECONDS
) WITH (
'connector' = 'faker',
'fields.client_ip.expression' = '#{Internet.publicIpV4Address}',
'fields.client_identity.expression' = '-',
'fields.userid.expression' = '-',
'fields.log_time.expression' = '#{date.past ''15'',''5'',''SECONDS''}',
'fields.request_line.expression' = '#{regexify ''(GET|POST|PUT|PATCH){1}''} #{regexify ''(/search\.html|/login\.html|/prod\.html|cart\.html|/order\.html){1}''} #{regexify ''(HTTP/1\.1|HTTP/2|/HTTP/1\.0){1}''}',
'fields.status_code.expression' = '#{regexify ''(200|201|204|400|401|403|301){1}''}',
'fields.size.expression' = '#{number.numberBetween ''100'',''10000000''}'
);
CREATE TEMPORARY TABLE avg_request_size_1m (
window_start TIMESTAMP(3),
window_end TIMESTAMP(3),
avg_size BIGINT
)
WITH (
'connector' = 'blackhole'
);
CREATE TEMPORARY TABLE avg_request_size_5m (
window_start TIMESTAMP(3),
window_end TIMESTAMP(3),
avg_size BIGINT
)
WITH (
'connector' = 'blackhole'
);
CREATE TEMPORARY VIEW server_logs_window_1m AS
SELECT
TUMBLE_START(log_time, INTERVAL '1' MINUTE) AS window_start,
TUMBLE_ROWTIME(log_time, INTERVAL '1' MINUTE) AS window_end,
SUM(size) AS total_size,
COUNT(*) AS num_requests
FROM server_logs
GROUP BY
TUMBLE(log_time, INTERVAL '1' MINUTE);
CREATE TEMPORARY VIEW server_logs_window_5m AS
SELECT
TUMBLE_START(log_time, INTERVAL '5' MINUTE) AS window_start,
TUMBLE_ROWTIME(log_time, INTERVAL '5' MINUTE) AS window_end,
SUM(size) AS total_size,
COUNT(*) AS num_requests
FROM server_logs
GROUP BY
TUMBLE(log_time, INTERVAL '5' MINUTE);
BEGIN STATEMENT SET;
INSERT INTO avg_request_size_1m SELECT
window_start,
window_end,
total_size/num_requests AS avg_size
FROM server_logs_window_1m;
INSERT INTO avg_request_size_5m SELECT
window_start,
window_end,
total_size/num_requests AS avg_size
FROM server_logs_window_5m;
END;
```
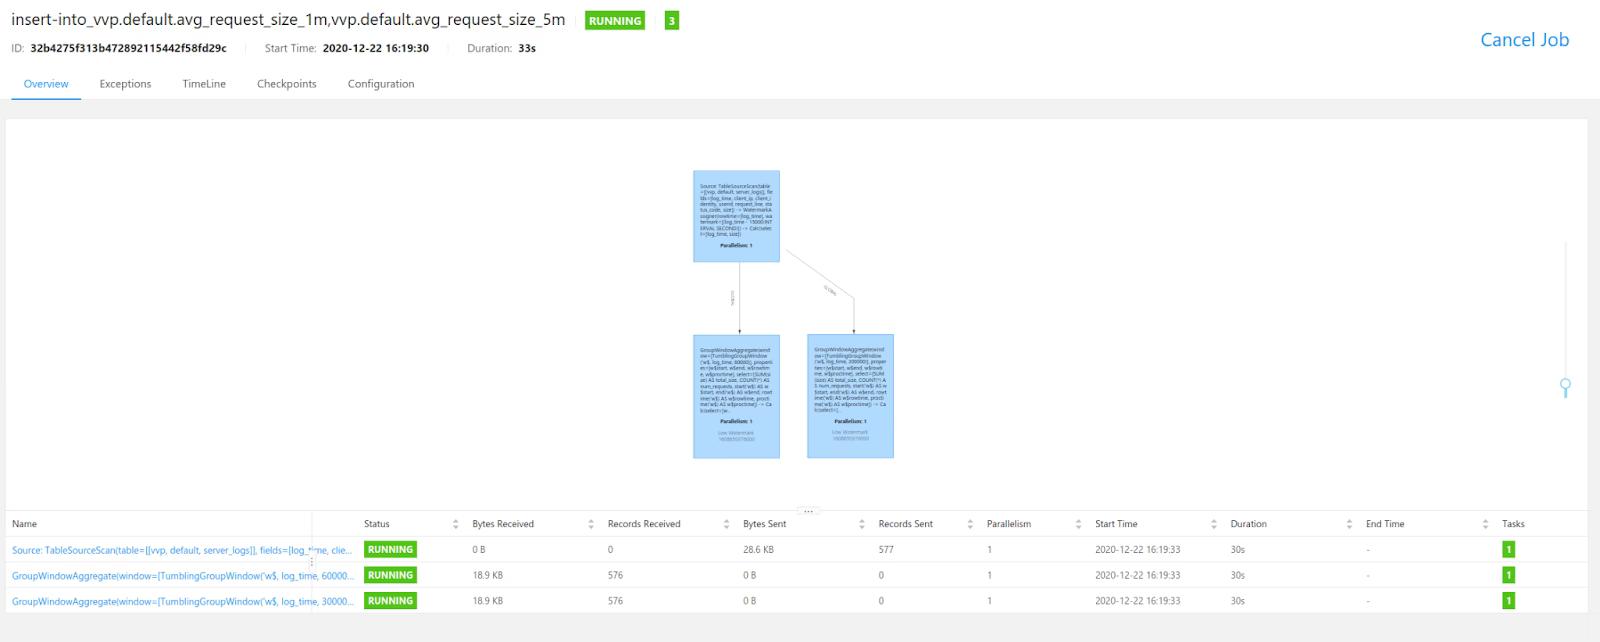
## How to create hopping time windows
> **INFO:** This example will show you how to calculate a moving average in real-time using a HOP window.
In this example, the source table (`bids`) is backed by the [faker connector](https://flink-packages.org/packages/flink-faker), which continuously generates rows in memory based on Java Faker expressions.
In one of our previous recipes, we've shown how you can [aggregate time series data](https://github.com/ververica/flink-sql-cookbook/blob/main/aggregations-and-analytics/01_group_by_window/01_group_by_window_tvf.md)using `TUMBLE`. To display every 30 seconds the moving average of bidding prices per currency per 1 minute, you will use the built-in `HOP`[function](https://ci.apache.org/projects/flink/flink-docs-stable/docs/dev/table/sql/queries/window-agg/).
The difference between a `HOP`and a `TUMBLE`function is that with a HOP you can "jump" forward in time. That's why you have to specify both the length of the window and the interval you want to jump forward. When using a `HOP`function, records can be assigned to multiple windows if the interval is smaller than the window length, like in this example. A tumbling window never overlaps and records will only belong to one window.
```sql
CREATE TABLE bids (
bid_id STRING,
currency_code STRING,
bid_price DOUBLE,
transaction_time TIMESTAMP(3),
WATERMARK FOR transaction_time AS transaction_time - INTERVAL '5' SECONDS
) WITH (
'connector' = 'faker',
'fields.bid_id.expression' = '#{Internet.UUID}',
'fields.currency_code.expression' = '#{regexify ''(EUR|USD|CNY)''}',
'fields.bid_price.expression' = '#{Number.randomDouble ''2'',''1'',''150''}',
'fields.transaction_time.expression' = '#{date.past ''30'',''SECONDS''}',
'rows-per-second' = '100'
);
SELECT window_start, window_end, currency_code, ROUND(AVG(bid_price),2) AS MovingAverageBidPrice
FROM TABLE(
HOP(TABLE bids, DESCRIPTOR(transaction_time), INTERVAL '30' SECONDS, INTERVAL '1' MINUTE))
GROUP BY window_start, window_end, currency_code;
```
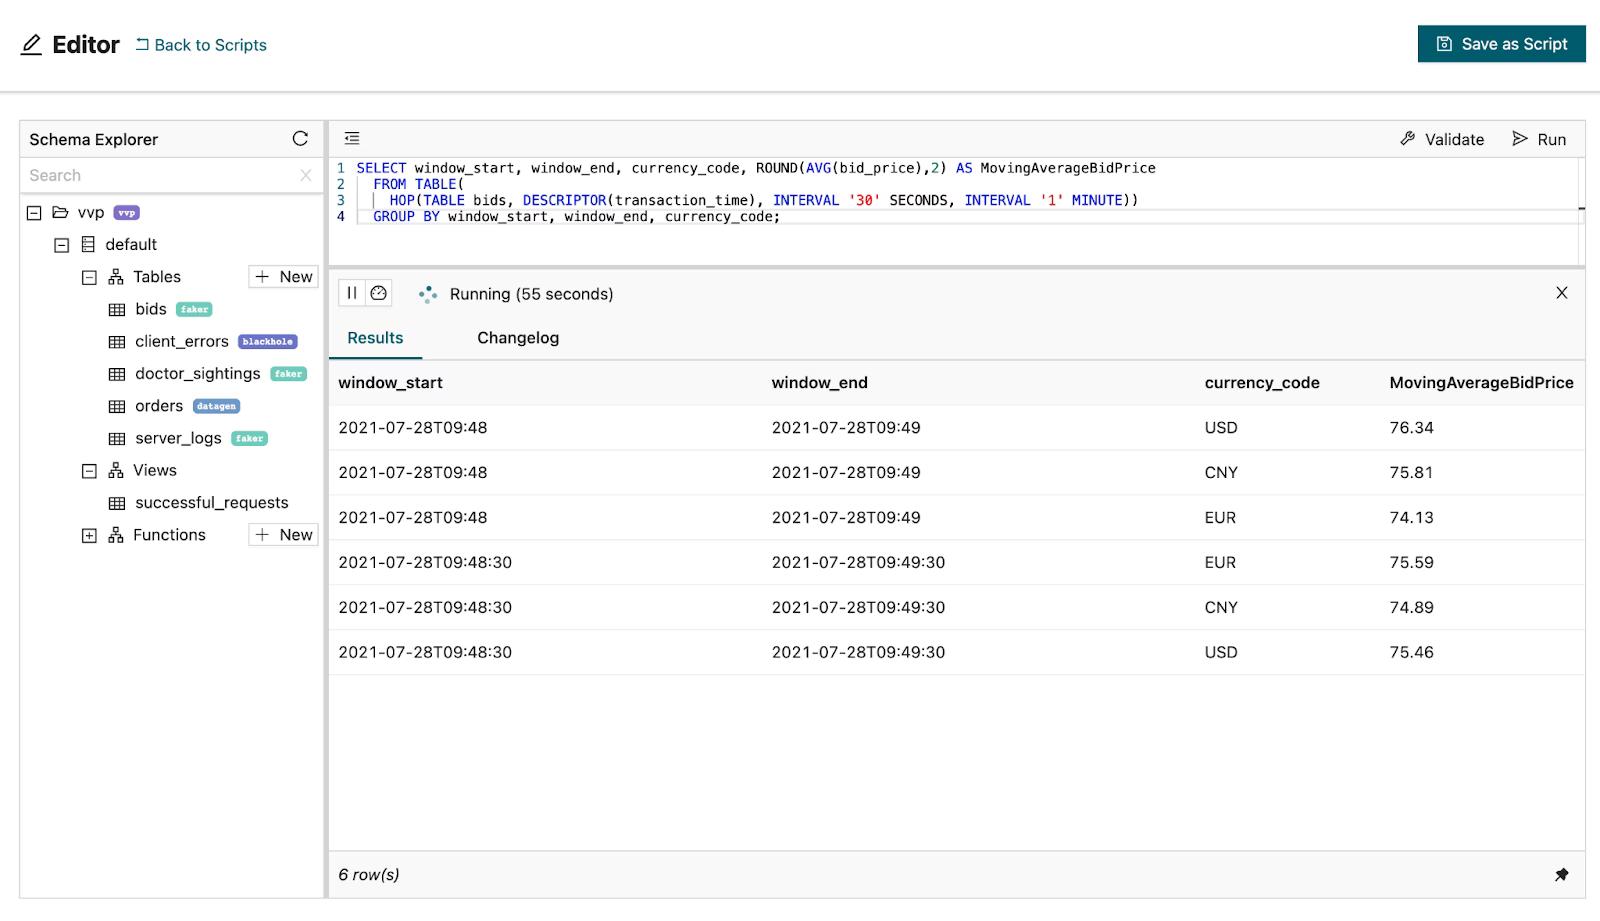
## How to perform rolling aggregations on time series data
> **INFO:** This example will show you how to calculate an aggregate or cumulative value based on a group of rows using an OVER window. A typical use case is rolling aggregations.
The source table (`temperature_measurements`) is backed by the [faker connector](https://flink-packages.org/packages/flink-faker), which continuously generates rows in memory based on Java Faker expressions.
OVER window aggregates compute an aggregated value for every input row over a range of ordered rows. In contrast to GROUP BY aggregates, OVER aggregates do not reduce the number of result rows to a single row for every group. Instead, OVER aggregates produce an aggregated value for every input row.
The order needs to be defined by a [time attribute](https://docs.ververica.com/user_guide/sql_development/table_view.html#time-attributes). The range of rows can be defined by a number of rows or a time interval.
In this example, you are trying to identify outliers in the `temperature_measurements` table. For this, you will use an OVER window to calculate, for each measurement, the maximum (`MAX`), minimum (`MIN`) and average (`AVG`) temperature across all measurements, as well as the standard deviation (`STDDEV`), for the same city over the previous minute.
```sql
CREATE TEMPORARY TABLE temperature_measurements (
measurement_time TIMESTAMP(3),
city STRING,
temperature FLOAT,
WATERMARK FOR measurement_time AS measurement_time - INTERVAL '15' SECONDS
)
WITH (
'connector' = 'faker',
'fields.measurement_time.expression' = '#{date.past ''15'',''SECONDS''}',
'fields.temperature.expression' = '#{number.numberBetween ''0'',''50''}',
'fields.city.expression' = '#{regexify ''(Chicago|Munich|Berlin|Portland|Hangzhou|Seatle|Beijing|New York){1}''}'
);
SELECT
measurement_time,
city,
temperature,
AVG(CAST(temperature AS FLOAT)) OVER last_minute AS avg_temperature_minute,
MAX(temperature) OVER last_minute AS min_temperature_minute,
MIN(temperature) OVER last_minute AS max_temperature_minute,
STDDEV(CAST(temperature AS FLOAT)) OVER last_minute AS stdev_temperature_minute
FROM temperature_measurements
WINDOW last_minute AS (
PARTITION BY city
ORDER BY measurement_time
RANGE BETWEEN INTERVAL '1' MINUTE PRECEDING AND CURRENT ROW
);
```
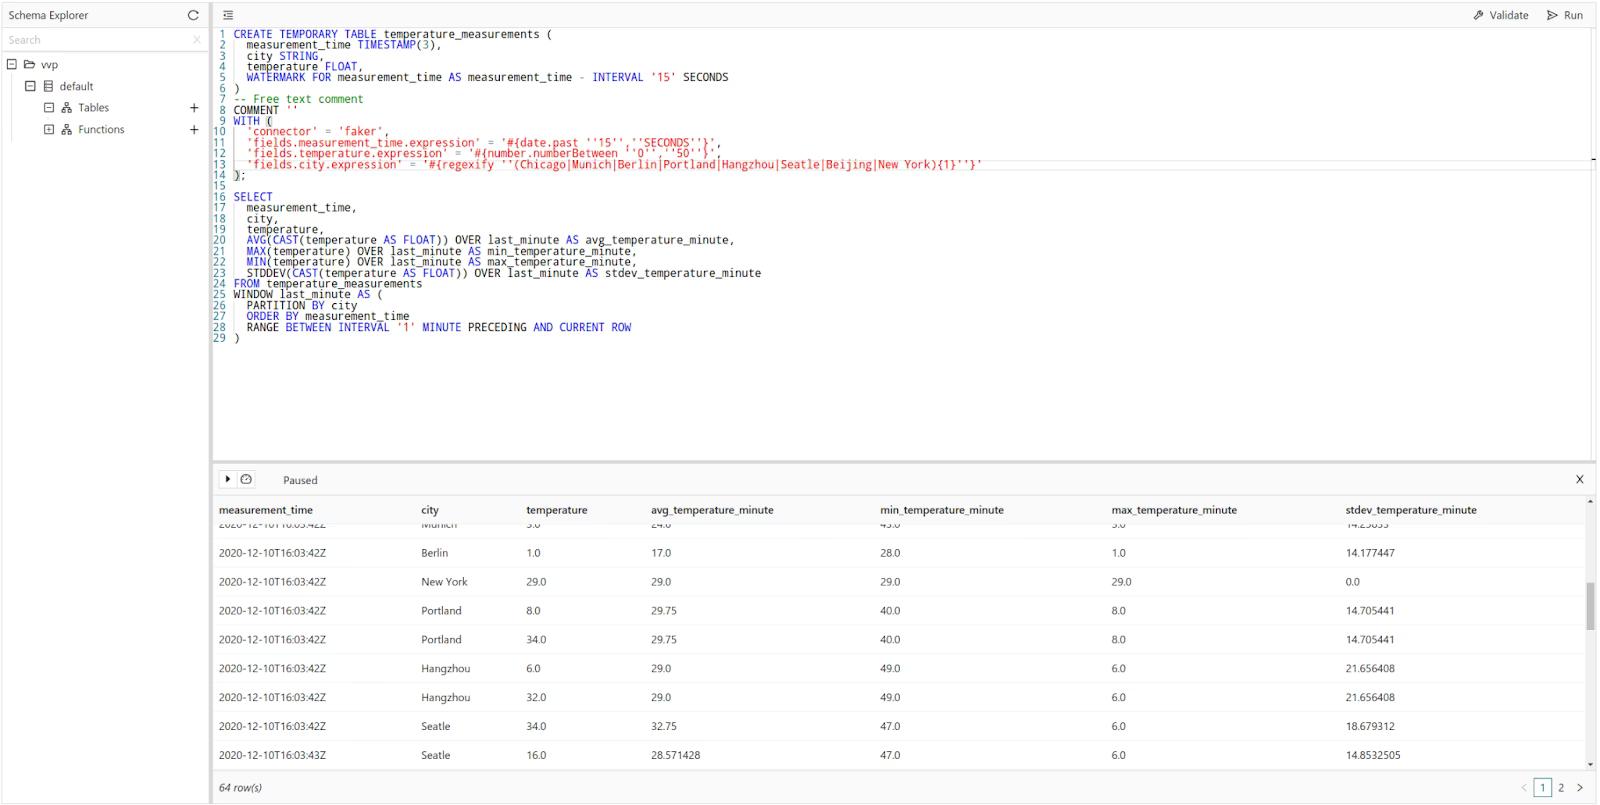
## Conclusion
In this article, we have shown you a couple of Flink SQL examples for creating time windows, which can be useful in different situations. We have also shown you how to perform a chained windowing operation and a non-chained windowing operation.
---
---
title: "Flink SQL: Queries, Windows, and Time - Part 1"
description: "Explore the significance of time in stream processing with Flink SQL, covering timestamps, time attributes, and temporal operators for real-time data analysis."
lastUpdated: 2026-06-02T08:36:39.000Z
source_url:
html: "https://www.ververica.com/blog/flink-sql-queries-and-time"
md: "https://www.ververica.com/blog/flink-sql-queries-and-time.md"
---
Time is a critical element in stream processing since data is processed as it arrives and must be processed quickly to avoid delays. The ubiquity of time in stream processing means that data processing must be designed to take into account the time factor. Time-based windowing is a common technique used in stream processing to ensure that data is processed in a timely manner.
Stream processing can be used for a variety of applications, such as monitoring systems, fraud detection, and any application that wants to provide real-time insights. The ubiquity of time in stream processing presents challenges and opportunities for data processing. With the right design, stream processing can be used to provide real-time insights into data streams.
In this post, we will take a look at how time can be taken into account when using Flink SQL.
## Timestamps and Queries
In stream processing, timestamps are used to record when an event occurred. This information can be used to determine how long it took for an event to be processed, or to monitor the performance of a stream processing system. Timestamps can also be used to order events that happened at the same time.
Examples:
- **User interactions:** clicks, (mobile) apps
- **Logs:** applications, machines
- **Transactions:** credit cards, ad serving
- **Sensors:** mobile phones, cars, IoT
Queries involving time in stream processing are typically used to analyze data over a period of time. This could involve finding trends or patterns in the data, or comparing data from different time periods. Stream processing systems typically provide ways to window the data, so that only data from a certain time period is considered. This makes it possible to perform real-time analysis of data as it comes in, or to perform analysis on historical data.
Examples:
- Average over the last minute
- Join with most recent exchange rate
- Alert after 3 unsuccessful attempts within 5 minutes
## Time Attributes
There are a few different types of time attributes in stream processing. These are event time, processing time, and ingestion time. Event time is the timestamp of when an event happened. Processing time is the timestamp of when the event was processed. Ingestion time is the timestamp of when the event was ingested into the system.
Event time is the only time attribute that is completely under the control of the user. All other time attributes are controlled by the system. Event time allows the user to control when an event happens, which can be very important in some situations.
Processing time can be affected by the speed of the system. In some cases, the system might be slow and processing time might be delayed. In other cases, the system might be fast and processing time might be earlier than expected.
Ingestion time is completely out of the control of the user. Ingestion time is controlled by the system and is dependent on the speed of the system.
### Event time attributes
An event time attribute is a TIMESTAMP or a TIMESTAMP_LTZ with an associated watermark. The watermarking uses a bounded-out-of-orderness watermarking strategy
A [TIMESTAMP](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/timezone/#timestamp-type) is a data type that records a date and time down to the fractional seconds, while a [TIMESTAMP_LTZ](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/timezone/#timestamp_ltz-type) (Local Time Zone) is a data type that stores the date, time, and local time zone of the client. Visit the official [Flink documentation website](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/timezone/#timestamp-vs-timestamp_ltz) to learn more.
```sql
CREATE TABLE clicks (
user STRING,
url STRING,
cTime TIMESTAMP_LTZ(3),
WATERMARK FOR cTime AS cTime - INTERVAL '2' MINUTE
)
```
### Processing time attributes
A processing time attribute is a computed column and does not hold data; the local machine time is queried whenever the attribute is accessed. A processing time attribute can be used like a regular TIMESTAMP_LTZ
```sql
CREATE TABLE clicks (
user STRING,
url STRING,
cTime AS PROCTIME()
)
```
As time moves forward, state can be expired, for example, counting clicks per user in hour-long windows.
Event time windows
- clicks are counted toward the hour in which they occurred
- watermarks trigger closing windows and discarding their state
Processing time windows
- clicks are counted toward the current hour as they are processed
- the local system clock triggers closing windows and discarding their state
Without a time attribute in the input table, the window operator wouldn't know when windows are complete.
## Timestamps vs. time attributes
There are two common ways to represent time in stream processing: timestamps and time attributes. A timestamp is a point in time that is associated with an event, while while [time attributes](https://nightlies.apache.org/flink/flink-docs-release-1.16/docs/dev/table/concepts/time_attributes/#introduction-to-time-attributes) can be present in each table schema. Timestamps are more precise, but time attributes are more flexible and can be used to represent complex temporal relationships.
The values in a timestamp column are fixed to specific moments in time with no guarantee that the column is (even roughly) ordered by time.
A time attribute column is connected to the forward progress of time:
- a processing time attribute is connected to the system clock via PROCTIME()
- an event time attribute is connected to the watermarks
## Temporal Operators
In stream processing, temporal attributes are often used to identify patterns and trends over time. For example, if a stream of data contains a series of values that increase or decrease over time, a temporal attribute could be used to identify this trend. Similarly, if a stream of data contains a series of values that fluctuate over time, a temporal attribute could be used to identify the period of time during which the fluctuations occur.
Temporal attributes can be used to identify patterns and trends not only in the data itself, but also in the relationships between different data streams. For example, if two streams of data are correlated, a temporal attribute could be used to identify the time lag between the two streams.
The use of temporal attributes in stream processing can be a powerful tool for identifying patterns and trends that would otherwise be difficult to detect.
Temporal operators use time attributes to associate records with each other and are a way of handling time-based data in stream processing. There are a few different types of temporal operators:
Windows:
- GROUP BY windows
- OVER windows
- window table-valued functions (since Flink 1.13)
Joins:
- interval JOIN
- JOIN with a temporal table (versioned joins)
Pattern matching (CEP with MATCH_RECOGNIZE)
Temporal operators track progress in time to decide when input is complete. They emit final result rows that can not be updated and are able to discard state (records and results) that is no longer needed.
## Window examples
### GROUP BY window aggregation
Below, you will find a query to count clicks per hour and users with TUMBLE and TUMBLE_END as built-in window functions. These window functions are using cTime, our table's time attribute.
```sql
SELECT
user,
TUMBLE_END(cTime, INTERVAL '1' HOUR) AS endT,
COUNT(url) AS cnt
FROM clicks
GROUP BY
TUMBLE(cTime, INTERVAL '1' HOUR),
user
```
### Types of GROUP BY windows
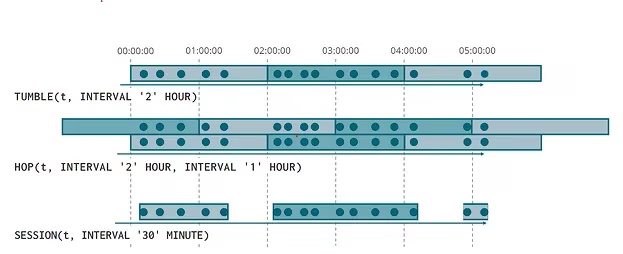
**Tumbling**: In tumbling windows, the windows are non-overlapping and of a fixed size. For example, if we have a stream of data and we want to calculate the average value of the data points in that stream over the last five minutes, we would use a tumbling window of size five minutes.
**Hopping**: In hopping windows, the windows are overlapping and of a invariable size. For example, if we have a stream of data and we want to calculate the average value of the data points in that stream over the last five minutes, but we want that calculation to be updated every minute, we would use a hopping window of size five minutes with a one-minute hop.
**Session**: In session windows, the windows are based on the activity of the data stream. A session window opens with an input and automatically extends if a subsequent input is received within the ensuing gap time. When there is a static gap duration and no input is received within the specified time following the latest input, the session window shuts.
### Selecting window boundaries
**These functions return TIMESTAMPs**
```sql
TUMBLE_START(time_attr, interval)
HOP_START(time_attr, interval, interval)
SESSION_START(time_attr, interval)
```
```sql
TUMBLE_END(time_attr, interval)
HOP_END(time_attr, interval, interval)
SESSION_END(time_attr, interval)
```
These timestamps are useful in reports, but can't be used as inputs to other temporal operators because they are not time attributes.
**These functions return time attributes**
```sql
TUMBLE_ROWTIME(time_attr, interval)
HOP_ROWTIME(time_attr, interval, interval)
SESSION_ROWTIME(time_attr, interval)
```
```sql
TUMBLE_PROCTIME(time_attr, interval)
HOP_PROCTIME(time_attr, interval, interval)
SESSION_PROCTIME(time_attr, interval)
```
These time attributes can be used wherever a time attribute is needed, e.g., GROUP BY windows, OVER windows, window table-valued functions, interval, and temporal joins.
## Window table-valued functions
_A conceptual example_
```sql
SELECT * FROM TABLE(
TUMBLE(TABLE clicks, DESCRIPTOR(cTime), INTERVAL '1' HOUR));
```
```sql
SELECT
user, window_start, window_end, count(url) AS cnt
FROM TABLE(
TUMBLE(TABLE clicks, DESCRIPTOR(cTime), INTERVAL '1' HOUR))
GROUP BY
user, window_start, window_end;
```
The window table-valued functions (WTVF) are a special class of functions that return a table. Below, you can see some examples:
- TUMBLE(TABLE data, DESCRIPTOR(timecol), size)
- HOP(TABLE data, DESCRIPTOR(timecol), slide, size [, offset ])
- CUMULATE(TABLE data, DESCRIPTOR(timecol), step, size)
- Session windows are not yet supported ([FLINK-24024](https://issues.apache.org/jira/browse/FLINK-24024))
If we compare window TVFs to GROUP BY windows, window TVFs are better optimized as they use mini-batch aggregation and two phase (local-global) aggregation. Window TVFs support [grouping by](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/window-agg/#grouping-sets) GROUPING SETS, ROLLUP, and CUBE. Also, you can apply [Window Top-N](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/sql/queries/window-topn/) to the results, e.g. find the top 3 users with the most clicks every hour.
## Conclusion
In summary, streaming applications often have a requirement to process events in a specific order based on the time they occurred. Time attributes, such as event time and processing time, are essential for making SQL viable in this context and are defined in the table schema. Temporal operations, which rely on these time attributes to associate related input rows, allow for the real-time analysis and processing of data. The results of these operations are final and emitted rows are never updated. The state of these operations is managed automatically, simplifying the development process. Overall, time attributes and temporal operations are crucial for working with streaming data in SQL.
---
---
title: "Flink SQL: Deduplication"
description: "Learn how to effectively deduplicate data in stream processing with Flink SQL, enhancing data quality and performance in your analytics workflows."
lastUpdated: 2026-06-05T11:27:29.000Z
source_url:
html: "https://www.ververica.com/blog/flink-sql-deduplication"
md: "https://www.ververica.com/blog/flink-sql-deduplication.md"
---
Flink SQL has emerged as the de facto standard for [low-code data analytics](https://www.ververica.com/product). It has managed to unify batch and stream processing while simultaneously staying true to the SQL standard. In addition, it provides a rich set of advanced features for real-time use cases. In a nutshell, Flink SQL provides the best of both worlds: it gives you the ability to **process streaming data using SQL, but it also supports batch processing.**
Ververica Platform makes Flink SQL even more accessible and efficiently scalable across teams. The platform comes with additional tools for developing SQL scripts, managing [user-defined functions (UDFs)](https://docs.ververica.com/user_guide/sql_development/functions.html#user-defined-functions-udfs), [catalogs](https://docs.ververica.com/user_guide/sql_development/catalogs.html) and [connectors](https://docs.ververica.com/user_guide/sql_development/connectors.html), as well as operating the resulting long-running queries.
We have seen that there are many [use cases](https://youtu.be/AxBNj6yOEZI) for Flink SQL, and we are excited to see what you will build with it. In this blog post, we will explain what deduplication is and show how you can accomplish this with Flink SQL.
## What is deduplication in stream processing?
Deduplication is a process of removing duplicate data from a dataset. This is usually done to improve the quality of the data. In stream processing, data deduplication is a very important process because it can help improve the performance of the system.
Data deduplication works by identifying and removing duplicate records from the data stream. This is usually done by comparing the data in the stream to a reference dataset. When a duplicate record is found, it is removed from the stream.
### Benefits of deduplication
There are many benefits to deduplicating data, including:
- improved performance – by removing duplicate data, you can reduce the amount of data that needs to be processed, which can improve performance
- reduced storage requirements – duplicate data takes up unnecessary space, so removing it can free up valuable storage space
- higher accuracy – duplicate data can lead to inaccurate results, so removing it can improve the accuracy of your data analysis
- boosted efficiency – deduplicating data can make data processing more efficient by reducing the amount of data that needs to be processed
## How to deduplicate data with Flink SQL
There are different ways that duplicate events can end up in your data sources, from human error to application bugs. Regardless of the origin, unclean data can have a real impact on the quality (and correctness) of your results.
In some cases, data producers generate records with the same ID for streaming data changes. These records may include Insert, Update, and Delete records, and they may need to be deduplicated as part of the business logic in the pipeline before being aggregated or joined with other streams. The purpose of deduplication in this context is to ensure that only unique records are processed and to avoid any issues that may arise from duplicate data.
Suppose that your order system occasionally generates duplicate events with the same `order_id`, but you're only interested in keeping the most recent event for downstream processing.
As a first step, you can use a combination of the `COUNT` function and the `HAVING` clause to check if and which orders have more than one event, and then filter out these events using `ROW_NUMBER()`. In practice, deduplication is a special case of [Top-N aggregation](https://github.com/ververica/flink-sql-cookbook/blob/main/aggregations-and-analytics/05_top_n/05_top_n.md), where N is 1 (`rownum = 1`) and the ordering column is either the processing or event time of events.
In the example query below, the source table `orders` is backed by the built-in [datagen connector](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/connectors/datagen.html), which continuously generates rows in memory.
```sql
CREATE TABLE orders (
id INT,
order_time AS CURRENT_TIMESTAMP,
WATERMARK FOR order_time AS order_time - INTERVAL '5' SECONDS
)
WITH (
'connector' = 'datagen',
'rows-per-second'='10',
'fields.id.kind'='random',
'fields.id.min'='1',
'fields.id.max'='100'
);
--Check for duplicates in the `orders` table
SELECT id AS order_id,
COUNT(*) AS order_cnt
FROM orders o
GROUP BY id
HAVING COUNT(*) > 1;
--Use deduplication to keep only the latest record for each `order_id`
SELECT
order_id,
order_time
FROM (
SELECT id AS order_id,
order_time,
ROW_NUMBER() OVER (PARTITION BY id ORDER BY order_time) AS rownum
FROM orders
)
WHERE rownum = 1;
```
## Summary
In this article, you learned about the deduplication of data. You've also seen how to use Flink SQL to write queries for this type of problem.
---
---
title: "How to run PyFlink Jobs and Python UDFs on Ververica Platform"
description: ""
lastUpdated: 2026-06-05T12:00:03.000Z
source_url:
html: "https://www.ververica.com/blog/how-to-run-pyflink-jobs-and-python-udfs-on-ververica-platform"
md: "https://www.ververica.com/blog/how-to-run-pyflink-jobs-and-python-udfs-on-ververica-platform.md"
---
[PyFlink](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/dev/python/overview/) is a Python API for Apache Flink. It provides a way to write Flink programs in Python and execute them on a Flink cluster.
Some existing Ververica Platform users may be wondering whether they can run PyFlink jobs on Ververica Platform while other non-users may think that it is not possible to run their Flink jobs coded in Python on the platform. This tutorial will show you how you can run PyFlink jobs and Python User Defined Functions (UDFs) via a custom Flink Docker image with Python and PyFlink installed.
We will show you two ways to run Python code in your Flink jobs on Ververica Platform:
1. run PyFlink jobs directly
1. call Python UDFs in your Table API programs written in Java
If you would like to follow along, you can download the [full example code from this post](https://github.com/ververica/lab-vvp-pyflink). We will be using Ververica Platform 2.8, Flink 1.15.2, and Python 3.8 in our example. Please change accordingly if you use different versions.
## Prerequisites
This tutorial assumes that you have the following:
- A recent Ververica Platform installed and running with a [Universal Blob Storage](https://docs.ververica.com/platform_operations/blob_storage.html) configured. Refer to [the Ververica Platform Getting Started instructions](https://docs.ververica.com/getting_started/installation.html) if you do not have this set up yet.
- Familiarity with the Flink job lifecycle management on Ververica Platform. This [short video](https://www.youtube.com/watch?v=BgXuxCZXNS0) will help you get started if you are not.
If you are running Ververica Platform 2.8 or earlier, or Ververica Platform 2.9 with Flink 1.13 or 1.14, you will need:
- A [docker runtime](https://docs.docker.com/engine/install/) to build Docker images
- A container registry to push your Docker images to
## Create a custom Flink image that includes Python and PyFlink
In order to run PyFlink jobs or call Python UDFs, you first need a Python interpreter and PyFlink. These are included in the Flink 1.15.3 (or later) images that come with Ververica Platform 2.9 (or later). You can skip this section and use the built-in Flink images if you are using these Ververica Platform versions.
If you are using Ververica Platform 2.8 or earlier, or if you are using Flink 1.13/1.14 with Ververica Platform 2.9, follow these steps to build new Flink images that include a Python interpreter and PyFlink.
In your terminal, create an empty directory. In the directory, create a file named Dockerfile with the following content:
```dockerfile
FROM registry.ververica.com/v2.8/flink:1.15.2-stream4-scala_2.12-java11
USER root:root
RUN apt update \
&& apt -y install python3.8 python3-pip \
&& python3.8 -m pip install apache-flink==1.15.2 \
&& apt clean \
&& ln -s /usr/bin/python3.8 /usr/bin/python \
&& rm -rf /var/lib/apt/lists/*
USER flink:flink
```
This Dockerfile uses a Flink 1.15.2 image (provided by Ververica Platform 2.8) as its base image.
Build the docker image by using the `docker build` command:
```dockerfile
docker build -t 1.15.2-stream4-scala_2.12-java11-python3.8-pyflink .
```
Once the image is built, you can tag and push the image to a public or private container registry that is reachable by Ververica Platform:
```dockerfile
docker tag
1.15.2-stream4-scala_2.12-java11-python3.8-pyflink:latest
/flink:1.15.2-stream4-scala_2.12-java11-python3.8-pyflink
docker push
/flink:1.15.2-stream4-scala_2.12-java11-python3.8-pyflink
```
## Create a Python UDF
In PyFlink, a Python UDF is a function written in Python that can be used in a Flink program. PyFlink provides a number of APIs for defining and using Python UDFs in Flink programs. Python UDFs are useful when you want to perform custom operations on your data that are not provided by the built-in functions in Flink, or when you want to use existing Python libraries in your Flink programs.
Throughout this tutorial, you will use a simple Python UDF which takes a string as input and returns it in capitalized form. This UDF can [be found here](https://github.com/ververica/lab-vvp-pyflink/blob/main/python-udf/my_udfs.py) if you want to follow along.
```python
from pyflink.table.udf import udf
from pyflink.table import DataTypes
@udf(result_type=DataTypes.STRING())
def py_upper( str ):
"This capitalizes the whole string"
return str.upper()
```
The annotation `@udf(result_type=DataTypes.STRING())` is the glue that is needed to make this function available as a Python UDF. For other ways to define Python UDFs, please consult the official [Flink documentation](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/dev/python/table/udfs/python_udfs/#scalar-functions).
## Run PyFlink Jobs on Ververica Platform
You will be running this [PyFlink job](https://github.com/ververica/lab-vvp-pyflink/blob/main/pyflink-job/pyflink_table_example.py) on Ververica Platform. This job relies on the aforementioned Python UDF to work. You will run it with Flink’s PythonDriver in [flink-python_2.12-1.15.2.jar](https://repo1.maven.org/maven2/org/apache/flink/flink-python_2.12/1.15.2/flink-python_2.12-1.15.2.jar). This is also how Apache Flink runs Python pipelines internally.
First, upload [pyflink_table_example.py](https://github.com/ververica/lab-vvp-pyflink/blob/main/pyflink-job/pyflink_table_example.py) and [my_udfs.py](https://github.com/ververica/lab-vvp-pyflink/blob/main/python-udf/my_udfs.py) to Ververica Platform’s [Universal Blob Storage](https://docs.ververica.com/platform_operations/blob_storage.html) via the menu bar on the left: **Deployments > Artifacts**
Then create your deployment with the following values:
The screenshot below is an example of how to do it on the Ververica Platform UI:
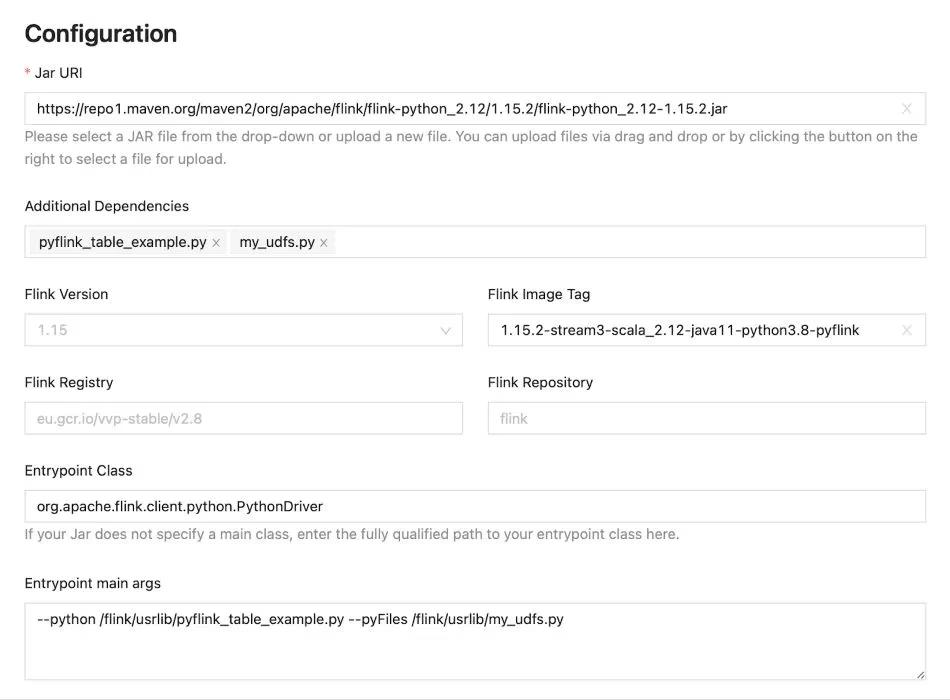
The directory `/flink/usrlib` is used in main args. When a Flink job starts, Ververica Platform will download the artifacts from its [Universal Blob Storage](https://docs.ververica.com/platform_operations/blob_storage.html) to `/flink/usrlib`.
Now, you can start this deployment, which will run the PyFlink job. Since the job has a bounded data input, the deployment will eventually go to the FINISHED state with Flink pods being torn down. But you should be able to get the following result in the logs of the JobManager pod where the city column is capitalized as expected:
```
+----+----------------------+--------------------------------+
| op | id | city |
+----+----------------------+--------------------------------+
| +I | 1 | BERLIN |
| +I | 2 | SHANGHAI |
| +I | 3 | NEW YORK |
| +I | 4 | HANGZHOU |
+----+----------------------+--------------------------------+
```
## Call Python UDFs in a Java Table API Job
Now that you have seen how to run PyFlink jobs on Ververica Platform, you can try calling Python UDFs from a Table API program written in Java. This is useful when several teams collaborate on Python UDFs. For example, one team of domain experts may develop Python UDFs and provide them to another team of Java developers for use in their Table API jobs. You will use this [Table API job](https://github.com/ververica/lab-vvp-pyflink/blob/main/java-table-job/src/main/java/com/ververica/JavaTableExample.java) in this example, which also calls the aforementioned Python UDF `my_udfs.py`.
Before you run the Table API job, let's go over the essential pieces that make this work.
The first step is to add a job dependency. More specifically, youneed to add the dependency `flink-python` into our project and package it into the job jar. See the full [pom.xml](https://github.com/ververica/lab-vvp-pyflink/blob/main/java-table-job/pom.xml) file for details. The dependency is where Flink’s PythonDriver exists.
```xml
org.apache.flink
flink-python_2.12
1.15.2
compile
```
Then, in the Table API job [JavaTableExample](https://github.com/ververica/lab-vvp-pyflink/blob/main/java-table-job/src/main/java/com/ververica/JavaTableExample.java), you need to inform your job where it can look for any UDF files. You can do this via PyFlink’s configuration [python.files](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/dev/python/python_config/#python-files). Remember, `/flink/usrlib` is the directory where Ververica Platform downloads the artifacts to when it starts a Flink job.
```python
tableEnv.getConfig().getConfiguration()
.setString("python.files", "/flink/usrlib/my_udfs.py");
```
Next, call `executeSql()` to map the Python function `my_udfs.py_upper` (since the Python UDF is in a separate file, youneed to reference it with this format python_module.function_name) to a temporary system function `PY_UPPER` in Flink SQL.
```python
tableEnv.executeSql("create temporary system function PY_UPPER as
'my_udfs.py_upper' language python");
```
Now that `PY_UPPER` is registered in Flink SQL, you can use the function in your SQL statement.
```python
tableEnv.sqlQuery(
"SELECT user, PY_UPPER(product), amount FROM " + table)
```
Before you can run the job, you need to upload the Python UDF file `my_udfs.py` to Ververica Platform’s [Universal Blob Storage](https://docs.ververica.com/platform_operations/blob_storage.html). You can skip this if you have done so by following the steps in the earlier part of this blog post.
Then, package the job as a jar: go to the directory with the `pom.xml` file, run `mvn clean package`, and you will get the JAR file `JavaTableExample-1.0-SNAPSHOT.jar` under the directory `target`.
With the produced jar file, you can create a deployment as you normally do with any other jar-based deployments. The only two differences here are that you have to:
1. make sure the custom Flink image `1.15.2-stream4-scala_2.12-java11-python3.8-pyflink` (or the built-in one if it has Python and PyFlink included) is used
1. add the Python UDF file `my_udfs.py` as an additional dependency.
Now start this deployment. The Python UDF will be called during the job run. Similar to the previous example, this job also has a bounded data input, so the deployment will eventually go to the FINISHED state with Flink pods being torn down. But you should be able to get the following result in the Jobmanager pod logs where the product column is capitalized as expected:
```
+----+----------------------+--------------------------------+-------------+
| op | user | product | amount |
+----+----------------------+--------------------------------+-------------+
| +I | 1 | BEER | 3 |
| +I | 2 | APPLE | 4 |
+----+----------------------+--------------------------------+-------------+
```
## Review the steps
Hopefully, you have successfully gone through this guide and have now seen how to run PyFlink jobs and Python UDFs on Ververica Platform. Let’s review the steps we just covered:
1. Create a custom Flink container image with Python and PyFlink installed
1. Run PyFlink jobs
1. Upload PyFlink jobs and its UDFs to Ververica Platform’s [Universal Blob Storage](https://docs.ververica.com/platform_operations/blob_storage.html)
1. Use Flink’s PythonDriver to run PyFlink Jobs
1. Reference the Python files in the main args.
1. Deploy with the Python files as additional dependencies.
1. Call Python UDFs in a Java based Table API program
1. Upload Python UDFs to Ververica Platform’s [Universal Blob Storage](https://docs.ververica.com/platform_operations/blob_storage.html)
1. Include `flink-python_2.12` as a dependency and package it into the job jar
1. Set `python.files` and register Python UDFs in the table environment
1. Deploy with the Python files as additional dependencies.
## Summary
In this tutorial you created a custom Flink image with a Python interpreter and PyFlink in it. You then ran Python code in Flink jobs on Ververica Platform in two different ways:
1. run PyFlink jobs with Flink’s PythonDriver
1. call Python UDFs in a Java-based Table API program
Ververica Platform 2.9 makes it easier by providing a Python interpreter and PyFlink in its Flink 1.15.3 images out of the box.
As a next step, we are working on the native integration of PyFlink into Ververica Platform in order to further improve the overall PyFlink user experience. Stay tuned!
---
---
title: "Flink SQL: Joins Series 3 (Lateral Joins, LAG aggregate function)"
description: "Explore how to utilize lateral joins and the LAG function in Flink SQL for dynamic data analysis and trend detection. Enhance your data processing skills today."
lastUpdated: 2026-07-06T13:24:18.000Z
source_url:
html: "https://www.ververica.com/blog/flink-sql-joins-part-3-0"
md: "https://www.ververica.com/blog/flink-sql-joins-part-3-0.md"
---
[Flink SQL](https://www.ververica.com/apache-flink-sql-on-ververica-platform#bgimage3) has emerged as the de facto standard for [low-code data analytics](https://www.ververica.com/ververica-platform-enterprise-stream-processing-and-streaming-analytics). It has managed to unify batch and stream processing while simultaneously staying true to the SQL standard. In addition, it provides a rich set of advanced features for real-time use cases. In a nutshell, Flink SQL provides the best of both worlds: it gives you the ability to **process streaming data using SQL, but it also supports batch processing.**
[Ververica Platform](https://ververica.com/platform) makes Flink SQL even more accessible and efficiently scalable across teams. The platform comes with additional tools for developing SQL scripts, managing [user-defined functions (UDFs)](https://docs.ververica.com/user_guide/sql_development/functions.html#user-defined-functions-udfs), [catalogs](https://docs.ververica.com/user_guide/sql_development/catalogs.html) and [connectors](https://docs.ververica.com/user_guide/sql_development/connectors.html), as well as operating the resulting long-running queries.
We have seen that there are many [use cases](https://youtu.be/AxBNj6yOEZI) for Flink SQL, and we are excited to see what you will build with it. In this three-part series of blog posts, we will show you different types of joins in Flink SQL and how you can use them to process data in a variety of ways.
> **TIP:** Make sure to check out our other articles on Flink SQL:
Flink SQL: Window Top-N and Continuous Top-N
Flink SQL: Joins Series 1 (Regular, Interval, Look-up Joins)
Flink SQL: Joins Series 2 (Temporal Table Join, Star Schema Denormalization)
## What is a Lateral Join?
Lateral joins are a type of SQL join that allow you to specify a subquery in the FROM clause. This subquery is then executed for each row in the outer query. Lateral joins can be used to improve the performance of SQL queries by reducing the number of table scans.
In other words, you can think of lateral join as a foreach loop in SQL that iterates through a collection, applies some transformation on each iteration, and produces an output. Lateral join is very useful in processing data that is stored in a hierarchical or nested format.
## How to perform a lateral table join
> **NOTE:** This example will show how you can correlate events using a LATERAL join.
Given a table with people's addresses, you need to find the two most populous cities for each state and continuously update those rankings as people move. The input table of `People` contains a uid for each person and their address and when they moved there.
The first step is to calculate each city's population using a [continuous aggregation](https://github.com/ververica/flink-sql-cookbook/blob/main/foundations/05_group_by/05_group_by.md). While this is simple enough, the real power of Flink SQL comes when people move. By using [deduplication](https://github.com/ververica/flink-sql-cookbook/blob/main/aggregations-and-analytics/06_dedup/06_dedup.md) Flink will automatically issue a retraction for a person's old city when they move. So if John moves from New York to Los Angeles, the population for New York will automatically go down by 1. This gives us the power of Change-Data-Capture without having to invest in the actual infrastructure of setting it up!
With this dynamic population table at hand, you are ready to solve the original problem using a `LATERAL` table join. Unlike a normal join, lateral joins allow the subquery to correlate with columns from other arguments in the `FROM` clause. And unlike a regular subquery, as a join, the lateral can return multiple rows. You can now have a subquery correlated with every individual state, and for every state it ranks by population and returns the top 2 cities.
```sql
CREATE TABLE People (
id INT,
city STRING,
state STRING,
arrival_time TIMESTAMP(3),
WATERMARK FOR arrival_time AS arrival_time - INTERVAL '1' MINUTE
) WITH (
'connector' = 'faker',
'fields.id.expression' = '#{number.numberBetween ''1'',''100''}',
'fields.city.expression' = '#{regexify ''(Newmouth|Newburgh|Portport|Southfort|Springfield){1}''}',
'fields.state.expression' = '#{regexify ''(New York|Illinois|California|Washington){1}''}',
'fields.arrival_time.expression' = '#{date.past ''15'',''SECONDS''}',
'rows-per-second' = '10'
);
CREATE TEMPORARY VIEW CurrentPopulation AS
SELECT
city,
state,
COUNT(*) as population
FROM (
SELECT
city,
state,
ROW_NUMBER() OVER (PARTITION BY id ORDER BY arrival_time DESC) AS rownum
FROM People
)
WHERE rownum = 1
GROUP BY city, state;
SELECT
state,
city,
population
FROM
(SELECT DISTINCT state FROM CurrentPopulation) States,
LATERAL (
SELECT city, population
FROM CurrentPopulation
WHERE state = States.state
ORDER BY population DESC
LIMIT 2
);
```
## What is a LAG() function?
`LAG(column_name, offset)` is a function that is used to access data from a previous row in the same table.
This function is useful for comparisons where you want to compare values in the current row with values in a previous row. For example, you might want to find out how much a given stock price has increased or decreased over time.
LAG() is easy to use. Simply specify the column you want to access data from and the number of rows back you want to go. For example, LAG(sales, 1) would return the sales data from the previous row.
### How to retrieve a previous row value with the LAG() function
> **NOTE:** This example will demonstrate how to retrieve the previous value and compute trends for a specific data partition.
The source table (`fake_stocks`) is backed by the [faker connector](https://flink-packages.org/packages/flink-faker), which continuously generates fake stock quotations in memory based on Java Faker expressions.
In this example, you are going to create a table which contains stock ticker updates for which we want to determine if the new stock price has gone up or down compared to its previous value.
First, create the table, then use a select statement including the [LAG](https://nightlies.apache.org/flink/flink-docs-stable/docs/dev/table/functions/systemfunctions/#aggregate-functions) function to retrieve the previous stock value. Finally, use the `case` statement in the final select to compare the current stock price against the previous value to determine the trend.
```sql
CREATE TABLE fake_stocks (
stock_name STRING,
stock_value double,
log_time AS PROCTIME()
) WITH (
'connector' = 'faker',
'fields.stock_name.expression' = '#{regexify ''(Deja\ Brew|Jurassic\ Pork|Lawn\ \&\ Order|Pita\ Pan|Bread\ Pitt|Indiana\ Jeans|Thai\ Tanic){1}''}',
'fields.stock_value.expression' = '#{number.randomDouble ''2'',''10'',''20''}',
'fields.log_time.expression' = '#{date.past ''15'',''5'',''SECONDS''}',
'rows-per-second' = '10'
);
WITH current_and_previous as (
select
stock_name,
log_time,
stock_value,
lag(stock_value, 1) over (partition by stock_name order by log_time) previous_value
from fake_stocks
)
select *,
case
when stock_value > previous_value then '▲'
when stock_value < previous_value then '▼'
else '='
end as trend
from current_and_previous;
```

## Summary
In this article, you learned about a lateral table join and a LAG() function. You've also seen how to use Flink SQL to write queries for both of these types of scenarios.
We encourage you to run these examples on Ververica Platform. You can follow [these simple steps](https://docs.ververica.com/getting_started/installation.html) to install the platform.
To learn more about Flink SQL, check out the following resources:
- [Flink SQL Cookbook](https://github.com/ververica/flink-sql-cookbook)
- [Getting Started - Flink SQL on Ververica Platform](https://docs.ververica.com/getting_started/sql_development.html)
- [The official Flink SQL documentation](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/overview/)
- [Flink Forward Talk: One SQL, Unified Analytics](https://youtu.be/rOzA4CIeXOw?t=924)
---
---
title: "Flink SQL Joins - Part 2"
description: "Explore Flink SQL joins in this detailed guide, including temporal table joins and real-time star schema denormalization for enhanced data processing."
lastUpdated: 2026-07-08T07:18:53.000Z
source_url:
html: "https://www.ververica.com/blog/flink-sql-joins-part-2-0"
md: "https://www.ververica.com/blog/flink-sql-joins-part-2-0.md"
---
[Flink SQL](https://www.ververica.com/apache-flink-sql-on-ververica-platform#bgimage3) has emerged as the de facto standard for [low-code data analytics](https://www.ververica.com/ververica-platform-enterprise-stream-processing-and-streaming-analytics). It has managed to unify batch and stream processing while simultaneously staying true to the SQL standard. In addition, it provides a rich set of advanced features for real-time use cases. In a nutshell, Flink SQL provides the best of both worlds: it gives you the ability to **process streaming data using SQL, but it also supports batch processing.**
[Ververica Platform](https://ververica.com/platform) makes Flink SQL even more accessible and efficiently scalable across teams. The platform comes with additional tools for developing SQL scripts, managing [user-defined functions (UDFs)](https://docs.ververica.com/user_guide/sql_development/functions.html#user-defined-functions-udfs), [catalogs](https://docs.ververica.com/user_guide/sql_development/catalogs.html) and [connectors](https://docs.ververica.com/user_guide/sql_development/connectors.html), as well as operating the resulting long-running queries.
We have seen that there are many [use cases](https://youtu.be/AxBNj6yOEZI) for Flink SQL, and we are excited to see what you will build with it. In this three-part series of blog posts, we will show you different types of joins in Flink SQL and how you can use them to process data in a variety of ways.
In this article, you will learn:
- what is a non-compacted and compacted Kafka topic
- what is a temporal table
- how to perform a temporal table join between a non-compacted and compacted Kafka topic
- what is real time star schema denormalization
- how to perform real time star schema denormalization
## Temporal table joins and non-compacted and compacted Kafka Topics
Apache Kafka's most fundamental unit of organization is the topic, which is something like a table in a relational database. A Kafka Topic can be compacted or non-compacted. A compacted topic retains all messages, even if they are deleted, for a certain time period. A non-compacted topic only retains messages that have not been deleted. In order to join a compacted and non-compacted topic, you can use a temporal table join.
A temporal table is a table that evolves over time. This is also known as a dynamic table in Flink. Rows in a temporal/dynamic table are associated with one or more temporal periods. The temporal table contains one or more versioned table snapshots.
A temporal table join is a feature that allows for data from two different temporal tables to be joined together on a common key, with the data from the second table being automatically inserted into the first table at the appropriate temporal period, or relevant version in the versioned table. This can be useful when integrating data from multiple sources, or when dealing with data that changes over time. This also means a table can be enriched with changing metadata and retrieve its value at a certain point in time.
### How to perform a temporal table join between a non-compacted and compacted Kafka Topic
> **NOTE:** This example will show how to correctly enrich records from one Kafka topic with the corresponding records of another Kafka topic when the order of events matters.
Temporal table joins take an arbitrary table (left input/probe site) and correlate each row to the corresponding row’s relevant version in a versioned table (right input/build side). Flink uses the SQL syntax of `FOR SYSTEM_TIME AS OF` to perform this operation.
In this recipe, you will join each transaction (`transactions`) to its correct currency rate (`currency_rates`, a versioned table) as of the time when the transaction happened. A similar example would be to join each order with the customer details as of the time when the order happened. This is exactly what an event-time temporal table join does. A temporal table join in Flink SQL provides correct, deterministic results in the presence of out-of-orderness and arbitrary time skew between the two tables.
Both the `transactions` and `currency_rates` tables are backed by Kafka topics, but in the case of rates this topic is compacted (e.g. only the most recent messages for a given key are kept as updated rates flow in). Records in `transactions` are interpreted as inserts only, and so the table is backed by the [standard Kafka connector](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/connectors/kafka.html) (`connector` = `kafka`); while the records in `currency_rates` need to be interpreted as upserts based on a primary key, which requires the [Upsert Kafka connector](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/connectors/upsert-kafka.html) (`connector` = `upsert-kafka`).
Flink SQL
```sql
CREATE TEMPORARY TABLE currency_rates (
`currency_code` STRING,
`eur_rate` DECIMAL(6,4),
`rate_time` TIMESTAMP(3),
WATERMARK FOR `rate_time` AS rate_time - INTERVAL '15' SECOND,
PRIMARY KEY (currency_code) NOT ENFORCED
) WITH (
'connector' = 'upsert-kafka',
'topic' = 'currency_rates',
'properties.bootstrap.servers' = 'localhost:9092',
'key.format' = 'raw',
'value.format' = 'json'
);
CREATE TEMPORARY TABLE transactions (
`id` STRING,
`currency_code` STRING,
`total` DECIMAL(10,2),
`transaction_time` TIMESTAMP(3),
WATERMARK FOR `transaction_time` AS transaction_time - INTERVAL '30' SECOND
) WITH (
'connector' = 'kafka',
'topic' = 'transactions',
'properties.bootstrap.servers' = 'localhost:9092',
'key.format' = 'raw',
'key.fields' = 'id',
'value.format' = 'json',
'value.fields-include' = 'ALL'
);
SELECT
t.id,
t.total * c.eur_rate AS total_eur,
t.total,
c.currency_code,
t.transaction_time
FROM transactions t
JOIN currency_rates FOR SYSTEM_TIME AS OF t.transaction_time AS c
ON t.currency_code = c.currency_code;
```
#### Data Generators
The two topics are populated using a Flink SQL job, too. We use the [faker connector](https://flink-packages.org/packages/flink-faker) to generate rows in memory based on [Java Faker](https://github.com/DiUS/java-faker) expressions and write those to the respective Kafka topics.
##### currency_rates Topic
Flink SQL
```sql
CREATE TEMPORARY TABLE currency_rates_faker
WITH (
'connector' = 'faker',
'fields.currency_code.expression' = '#{Currency.code}',
'fields.eur_rate.expression' = '#{Number.randomDouble ''4'',''0'',''10''}',
'fields.rate_time.expression' = '#{date.past ''15'',''SECONDS''}',
'rows-per-second' = '100'
) LIKE currency_rates (EXCLUDING OPTIONS);
INSERT INTO currency_rates SELECT * FROM currency_rates_faker;
```
Kafka Topic
```bash
➜ bin ./kafka-console-consumer.sh --bootstrap-server localhost:9092 --topic currency_rates --property print.key=true --property key.separator=" - "
HTG - {"currency_code":"HTG","eur_rate":0.0136,"rate_time":"2020-12-16 22:22:02"}
BZD - {"currency_code":"BZD","eur_rate":1.6545,"rate_time":"2020-12-16 22:22:03"}
BZD - {"currency_code":"BZD","eur_rate":3.616,"rate_time":"2020-12-16 22:22:10"}
BHD - {"currency_code":"BHD","eur_rate":4.5308,"rate_time":"2020-12-16 22:22:05"}
KHR - {"currency_code":"KHR","eur_rate":1.335,"rate_time":"2020-12-16 22:22:06"}
```
##### transactions Topic
Flink SQL
```sql
CREATE TEMPORARY TABLE transactions_faker
WITH (
'connector' = 'faker',
'fields.id.expression' = '#{Internet.UUID}',
'fields.currency_code.expression' = '#{Currency.code}',
'fields.total.expression' = '#{Number.randomDouble ''2'',''10'',''1000''}',
'fields.transaction_time.expression' = '#{date.past ''30'',''SECONDS''}',
'rows-per-second' = '100'
) LIKE transactions (EXCLUDING OPTIONS);
INSERT INTO transactions SELECT * FROM transactions_faker;
```
Kafka Topic
```bash
➜ bin ./kafka-console-consumer.sh --bootstrap-server localhost:9092 --topic transactions --property print.key=true --property key.separator=" - "
e102e91f-47b9-434e-86e1-34fb1196d91d - {"id":"e102e91f-47b9-434e-86e1-34fb1196d91d","currency_code":"SGD","total":494.07,"transaction_time":"2020-12-16 22:18:46"}
bf028363-5ee4-4a5a-9068-b08392d59f0b - {"id":"bf028363-5ee4-4a5a-9068-b08392d59f0b","currency_code":"EEK","total":906.8,"transaction_time":"2020-12-16 22:18:46"}
e22374b5-82da-4c6d-b4c6-f27a818a58ab - {"id":"e22374b5-82da-4c6d-b4c6-f27a818a58ab","currency_code":"GYD","total":80.66,"transaction_time":"2020-12-16 22:19:02"}
81b2ce89-26c2-4df3-b12a-8ca921902ac4 - {"id":"81b2ce89-26c2-4df3-b12a-8ca921902ac4","currency_code":"EGP","total":521.98,"transaction_time":"2020-12-16 22:18:57"}
53c4fd3f-af6e-41d3-a677-536f4c86e010 - {"id":"53c4fd3f-af6e-41d3-a677-536f4c86e010","currency_code":"UYU","total":936.26,"transaction_time":"2020-12-16 22:18:59"}
```
## Real Time Star Schema Denormalization (N-Way Join)
A real-time star schema denormalization is a process of joining two or more tables in a star schema so that the data in the resulting table is denormalized. This can be done for performance reasons, to make it easier to query the data, or both. Denormalization can be used to improve the performance of queries that join large numbers of tables, by reducing the number of joins that need to be performed. It can also make it easier to query the data, by providing a single table that contains all the data that would otherwise be spread across multiple tables.
The process of denormalization can be applied to any schema, but it is most commonly used with star schemas, which are schemas that have a central fact table surrounded by a number of dimension tables. The fact table contains the data that is being analyzed, and the dimension tables contain data that can be used to describe the data in the fact table. When denormalizing a star schema, the data in the dimension tables is combined into the fact table.
### How to perform real-time star schema denormalization
> **NOTE:** This example will show how you can denormalize a simple star schema with an n-way temporal table join.
[Star schemas](https://en.wikipedia.org/wiki/Star_schema) are a popular way of normalizing data within a data warehouse. At the center of a star schema is a **fact table** whose rows contain metrics, measurements, and other facts about the world. Surrounding fact tables are one or more **dimension tables** which have metadata useful for enriching facts when computing queries.
Imagine, you are running a small data warehouse for a railroad company which consists of a fact table (`train_activity`) and three dimension tables (`stations`, `booking_channels`, and `passengers`). All inserts to the fact table, and all updates to the dimension tables, are mirrored to Apache Kafka. Records in the fact table are interpreted as inserts only, and so the table is backed by the [standard Kafka connector](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/connectors/kafka.html) (`connector` = `kafka`);. In contrast, the records in the dimensional tables are upserts based on a primary key, which requires the [Upsert Kafka connector](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/connectors/upsert-kafka.html) (`connector` = `upsert-kafka`).
With Flink SQL you can now easily join all dimensions to our fact table using a 5-way temporal table join. Temporal table joins take an arbitrary table (left input/probe site) and correlate each row to the corresponding row’s relevant version in a versioned table (right input/build side). Flink uses the SQL syntax of `FOR SYSTEM_TIME AS OF` to perform this operation. Using a temporal table join leads to consistent, reproducible results when joining a fact table with more (slowly) changing dimensional tables. Every event (row in the fact table) is joined to its corresponding value of each dimension based on when the event occurred in the real world.
```sql
CREATE TEMPORARY TABLE passengers (
passenger_key STRING,
first_name STRING,
last_name STRING,
update_time TIMESTAMP(3),
WATERMARK FOR update_time AS update_time - INTERVAL '10' SECONDS,
PRIMARY KEY (passenger_key) NOT ENFORCED
) WITH (
'connector' = 'upsert-kafka',
'topic' = 'passengers',
'properties.bootstrap.servers' = 'localhost:9092',
'key.format' = 'raw',
'value.format' = 'json'
);
CREATE TEMPORARY TABLE stations (
station_key STRING,
update_time TIMESTAMP(3),
city STRING,
WATERMARK FOR update_time AS update_time - INTERVAL '10' SECONDS,
PRIMARY KEY (station_key) NOT ENFORCED
) WITH (
'connector' = 'upsert-kafka',
'topic' = 'stations',
'properties.bootstrap.servers' = 'localhost:9092',
'key.format' = 'raw',
'value.format' = 'json'
);
CREATE TEMPORARY TABLE booking_channels (
booking_channel_key STRING,
update_time TIMESTAMP(3),
channel STRING,
WATERMARK FOR update_time AS update_time - INTERVAL '10' SECONDS,
PRIMARY KEY (booking_channel_key) NOT ENFORCED
) WITH (
'connector' = 'upsert-kafka',
'topic' = 'booking_channels',
'properties.bootstrap.servers' = 'localhost:9092',
'key.format' = 'raw',
'value.format' = 'json'
);
CREATE TEMPORARY TABLE train_activities (
scheduled_departure_time TIMESTAMP(3),
actual_departure_date TIMESTAMP(3),
passenger_key STRING,
origin_station_key STRING,
destination_station_key STRING,
booking_channel_key STRING,
WATERMARK FOR actual_departure_date AS actual_departure_date - INTERVAL '10' SECONDS
) WITH (
'connector' = 'kafka',
'topic' = 'train_activities',
'properties.bootstrap.servers' = 'localhost:9092',
'value.format' = 'json',
'value.fields-include' = 'ALL'
);
SELECT
t.actual_departure_date,
p.first_name,
p.last_name,
b.channel,
os.city AS origin_station,
ds.city AS destination_station
FROM train_activities t
LEFT JOIN booking_channels FOR SYSTEM_TIME AS OF t.actual_departure_date AS b
ON t.booking_channel_key = b.booking_channel_key;
LEFT JOIN passengers FOR SYSTEM_TIME AS OF t.actual_departure_date AS p
ON t.passenger_key = p.passenger_key
LEFT JOIN stations FOR SYSTEM_TIME AS OF t.actual_departure_date AS os
ON t.origin_station_key = os.station_key
LEFT JOIN stations FOR SYSTEM_TIME AS OF t.actual_departure_date AS ds
ON t.destination_station_key = ds.station_key;
```
SQL Client
JobGraph
#### Data Generators
The four topics are populated with Flink SQL jobs, too. We use the [faker connector](https://flink-packages.org/packages/flink-faker) to generate rows in memory based on Java Faker expressions and write those to the respective Kafka topics.
##### train_activities Topic
Flink SQL
```sql
CREATE TEMPORARY TABLE train_activities_faker
WITH (
'connector' = 'faker',
'fields.scheduled_departure_time.expression' = '#{date.past ''10'',''0'',''SECONDS''}',
'fields.actual_departure_date.expression' = '#{date.past ''10'',''5'',''SECONDS''}',
'fields.passenger_key.expression' = '#{number.numberBetween ''0'',''10000000''}',
'fields.origin_station_key.expression' = '#{number.numberBetween ''0'',''1000''}',
'fields.destination_station_key.expression' = '#{number.numberBetween ''0'',''1000''}',
'fields.booking_channel_key.expression' = '#{number.numberBetween ''0'',''7''}',
'rows-per-second' = '1000'
) LIKE train_activities (EXCLUDING OPTIONS);
INSERT INTO train_activities SELECT * FROM train_activities_faker;
```
Kafka Topic
```bash
➜ bin ./kafka-console-consumer.sh --bootstrap-server localhost:9092 --topic train_actitivies --property print.key=true --property key.separator=" - "
null - {"scheduled_departure_time":"2020-12-19 13:52:37","actual_departure_date":"2020-12-19 13:52:16","passenger_key":7014937,"origin_station_key":577,"destination_station_key":862,"booking_channel_key":2}
null - {"scheduled_departure_time":"2020-12-19 13:52:38","actual_departure_date":"2020-12-19 13:52:23","passenger_key":2244807,"origin_station_key":735,"destination_station_key":739,"booking_channel_key":2}
null - {"scheduled_departure_time":"2020-12-19 13:52:46","actual_departure_date":"2020-12-19 13:52:18","passenger_key":2605313,"origin_station_key":216,"destination_station_key":453,"booking_channel_key":3}
null - {"scheduled_departure_time":"2020-12-19 13:53:13","actual_departure_date":"2020-12-19 13:52:19","passenger_key":7111654,"origin_station_key":234,"destination_station_key":833,"booking_channel_key":5}
null - {"scheduled_departure_time":"2020-12-19 13:52:22","actual_departure_date":"2020-12-19 13:52:17","passenger_key":2847474,"origin_station_key":763,"destination_station_key":206,"booking_channel_key":3}
```
##### passengers Topic
Flink SQL
```sql
CREATE TEMPORARY TABLE passengers_faker
WITH (
'connector' = 'faker',
'fields.passenger_key.expression' = '#{number.numberBetween ''0'',''10000000''}',
'fields.update_time.expression' = '#{date.past ''10'',''5'',''SECONDS''}',
'fields.first_name.expression' = '#{Name.firstName}',
'fields.last_name.expression' = '#{Name.lastName}',
'rows-per-second' = '1000'
) LIKE passengers (EXCLUDING OPTIONS);
INSERT INTO passengers SELECT * FROM passengers_faker;
```
Kafka Topic
```bash
➜ bin ./kafka-console-consumer.sh --bootstrap-server localhost:9092 --topic passengers --property print.key=true --property key.separator=" - "
749049 - {"passenger_key":"749049","first_name":"Booker","last_name":"Hackett","update_time":"2020-12-19 14:02:32"}
7065702 - {"passenger_key":"7065702","first_name":"Jeramy","last_name":"Breitenberg","update_time":"2020-12-19 14:02:38"}
3690329 - {"passenger_key":"3690329","first_name":"Quiana","last_name":"Macejkovic","update_time":"2020-12-19 14:02:27"}
1212728 - {"passenger_key":"1212728","first_name":"Lawerence","last_name":"Simonis","update_time":"2020-12-19 14:02:27"}
6993699 - {"passenger_key":"6993699","first_name":"Ardelle","last_name":"Frami","update_time":"2020-12-19 14:02:19"}
```
##### stations Topic
Flink SQL
```sql
CREATE TEMPORARY TABLE stations_faker
WITH (
'connector' = 'faker',
'fields.station_key.expression' = '#{number.numberBetween ''0'',''1000''}',
'fields.city.expression' = '#{Address.city}',
'fields.update_time.expression' = '#{date.past ''10'',''5'',''SECONDS''}',
'rows-per-second' = '100'
) LIKE stations (EXCLUDING OPTIONS);
INSERT INTO stations SELECT * FROM stations_faker;
```
Kafka Topic
```bash
➜ bin ./kafka-console-consumer.sh --bootstrap-server localhost:9092 --topic stations --property print.key=true --property key.separator=" - "
80 - {"station_key":"80","update_time":"2020-12-19 13:59:20","city":"Harlandport"}
33 - {"station_key":"33","update_time":"2020-12-19 13:59:12","city":"North Georgine"}
369 - {"station_key":"369","update_time":"2020-12-19 13:59:12","city":"Tillmanhaven"}
580 - {"station_key":"580","update_time":"2020-12-19 13:59:12","city":"West Marianabury"}
616 - {"station_key":"616","update_time":"2020-12-19 13:59:09","city":"West Sandytown"}
```
##### booking_channels Topic
Flink SQL
```sql
CREATE TEMPORARY TABLE booking_channels_faker
WITH (
'connector' = 'faker',
'fields.booking_channel_key.expression' = '#{number.numberBetween ''0'',''7''}',
'fields.channel.expression' = '#{regexify ''(bahn\.de|station|retailer|app|lidl|hotline|joyn){1}''}',
'fields.update_time.expression' = '#{date.past ''10'',''5'',''SECONDS''}',
'rows-per-second' = '100'
) LIKE booking_channels (EXCLUDING OPTIONS);
INSERT INTO booking_channels SELECT * FROM booking_channels_faker;
```
Kafka Topic
```bash
➜ bin ./kafka-console-consumer.sh --bootstrap-server localhost:9092 --topic booking_channels --property print.key=true --property key.separator=" - "
1 - {"booking_channel_key":"1","update_time":"2020-12-19 13:57:05","channel":"joyn"}
0 - {"booking_channel_key":"0","update_time":"2020-12-19 13:57:17","channel":"station"}
4 - {"booking_channel_key":"4","update_time":"2020-12-19 13:57:15","channel":"joyn"}
2 - {"booking_channel_key":"2","update_time":"2020-12-19 13:57:02","channel":"app"}
1 - {"booking_channel_key":"1","update_time":"2020-12-19 13:57:06","channel":"retailer"}
```
## Summary
In this article, you learned about temporal table joins between a non-compacted and compacted Kafka topic, and real-time star schema denormalization. You've also seen how to use Flink SQL to write queries for both of these types of scenarios.
We encourage you to run these examples on Ververica Platform. You can follow [these simple steps](https://docs.ververica.com/getting_started/installation.html) to install the platform.
To learn more about Flink SQL, check out the following resources:
- [Flink SQL Cookbook](https://github.com/ververica/flink-sql-cookbook)
- [Getting Started - Flink SQL on Ververica Platform](https://docs.ververica.com/getting_started/sql_development.html)
- [The official Flink SQL documentation](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/overview/)
- [Flink Forward Talk: One SQL, Unified Analytics](https://youtu.be/rOzA4CIeXOw?t=924)
- [Only SQL: Empower data analysts end-to-end with Flink SQL](https://youtu.be/KvaDe7QCwBQ)
---
---
title: "How to write fast Flink SQL"
description: "Discover key strategies to optimize Flink SQL performance, including sub-plan reuse, fast aggregation, and advanced techniques for efficient data processing."
lastUpdated: 2026-07-06T12:08:15.000Z
source_url:
html: "https://www.ververica.com/blog/how-to-write-fast-flink-sql"
md: "https://www.ververica.com/blog/how-to-write-fast-flink-sql.md"
---
[Flink SQL](https://ververica.com/blog/apache-flink-sql-past-present-and-future) is the most widely used relational API based on standard SQL. It provides unified batch processing and stream processing, which makes it easy to develop applications, and is already widely used for various use cases.
Unlike the DataStream API, which offers the primitives of stream processing in a relatively low-level imperative programming API, the Flink SQL API offers a relatively high-level declarative API. This means that a program written with the DataStream API will transform into an execution graph without any optimizations, whereas a program written with [Flink SQL](https://ververica.com/blog/apache-flink-sql-past-present-and-future) must undergo rich transformations before it becomes an execution graph. Currently, the SQL planner provides different optimization techniques and, thanks to that, these optimization methods will help you write efficient SQL code.
Six main factors that improve the performance for a Flink job are:
1. Avoiding duplicate computing
1. Reducing invalid data
1. Solving data skew issues
1. Improving operator throughput
1. Reducing state access (streaming only)
1. Reducing state size (streaming only)
In this post, we will introduce some SQL/operator improvements based on the above factors. We will also give you insights into Flink SQL including how it works under the hood, its workflows, best practices when writing your queries, and what is in store for the future.
## Flink Operator Execution Mode
Before going into the optimization details, let's first gain a basic understanding of the execution mode of Flink operators and the optimization process of Flink SQL, which will help us better understand Flink SQL.
Flink is a unified batch and streaming processing engine, it provides a unified API, unified operator description, and unified execution framework. But the operator execution mode for batch and streaming is different.
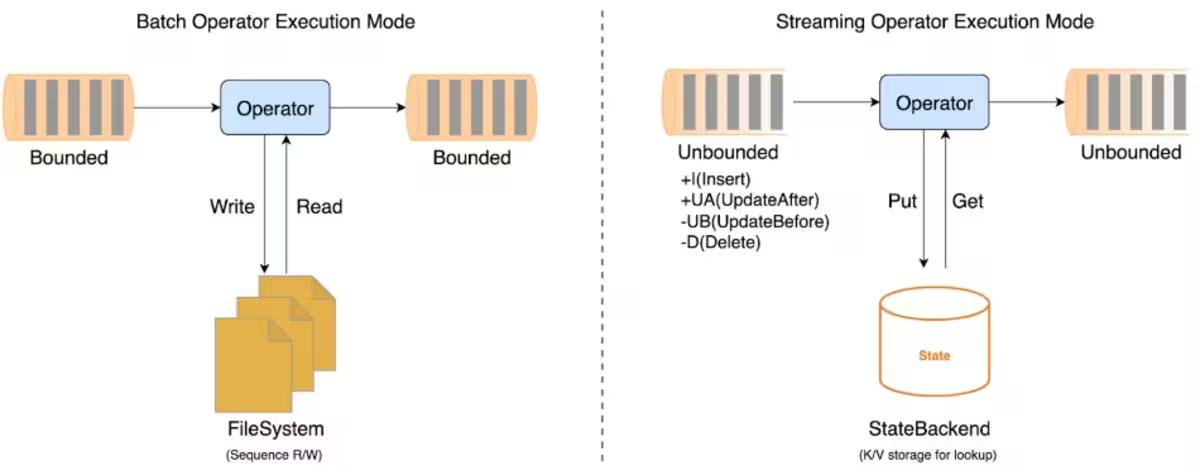
A batch operator will receive a bounded dataset as input and produce a bounded dataset as output. For the current implementation, the operator will process the all input data as a batch, and the data will be spilled to disk once the memory runs out. When designing and implementing batch operators, we should try to avoid disk access to improve performance.
A streaming operator, on the other hand, will take an unbounded dataset as input (also known as a Changelog) and output an unbounded dataset. Since the operator cannot buffer every piece of input data even with a disk, they will each be processed individually by the operator. The streaming operators must rely on State to store the intermediate computation results. When designing and implementing streaming operators, we should try to avoid state access to improve performance. The Changelog not only contains INSERT messages, but also retraction(UPDATE_BEFORE, UPDATE_AFTER, DELTE) messages. The matter of reducing the retraction messages also falls into the remit of streaming operators.
## Flink SQL Workflow
In order to better help you understand how SQL code becomes an efficient Flink job, the following graph shows the internal Flink SQL workflow.
The transformation is deterministic from SQL text to _LogicalPlan_, and from _ExecPlan_ to _JobGraph_. The optimizer is crucial even if there are numerous uncertainty transitions from LogicalPlan to ExecPlan. Now Let's take a rough look at the workflow of the optimizer.
## Flink SQL Optimizer
A [Flink SQL](https://ververica.com/blog/apache-flink-sql-past-present-and-future) job may contain multiple insert statements, which are parsed and converted into multiple logical trees, i.e. Directed Acyclic Graph (DAG). So, we call the optimizer a DAG optimizer. The DAG optimizer takes LogicalPlan, Flink Conf, Constraints and Statistics as input, and generates the optimized ExecPlan as output.
Flink uses Apache Calcite for relational algebra optimization, which can only accept a single logical expression tree. Therefore, after the optimizer receives a DAG, it will first break up the DAG into multiple logical expression trees based on the view, and then use Calcite to optimize the tree one by one. View-based breakup will reduce duplicate computing. After all the relational algebra expression trees are optimized, they will be reassembled into a DAG of the physical plan, and reduce repeated calculations through subgraph reuse technology to form an ExecPlan. Based on ExecPlan, we will make changes and write.
In the Calcite optimizer, we have implemented a large number of optimization rules and attribute derivation to help us generate the optimal execution plan.
## Best Practices
Now, we will introduce some optimization options to improve the performance of Flink SQL jobs based on some high-frequency SQL cases used in our production.
### Sub-Plan Reuse
_Sub-Plan Reuse_ is mainly used for reducing duplicate computing, we will explain the details with the following simple example.
```sql
INSERT INTO sink1 SELECT * FROM my_table WHERE a > 10;
INSERT INTO sink2 SELECT * FROM my_table WHERE a > 10 AND b < 100;
```
The statements can be converted to the following execution plan, we can easily see that the _Scan_ node will be executed twice, that is duplicate computing part (see the red dotted box).
We can turn on Sub-plan Reuse by setting configuration _table.optimizer.reuse-sub-plan-enabled=true_ (default is true), and the optimizer will automatically find and reuse the duplicate part in the DAG.
In the picture above, we can see that the scan operator is reused, but there is still a duplicate computing part (_a > 10_) after sub-plan reuse. It's very hard for the optimizer to find the duplicate computing expression in an operator, especially when the query is complex and various push down optimizations (e.g. filter push down, projection push down) are applied.
We recommend users to leverage View to solve the problem above. Views can not only improve the readability of the queries, but also help the optimizer find reusable parts. The query can be rewritten as the following:
```sql
CREATE TEMPORARY VIEW v1 SELECT * FROM my_table WHERE a > 10;
INSERT INTO sink1 SELECT * FROM v1;
INSERT INTO sink2 SELECT * FROM v1 WHERE b < 100;
```
The execution plan will be optimized as:
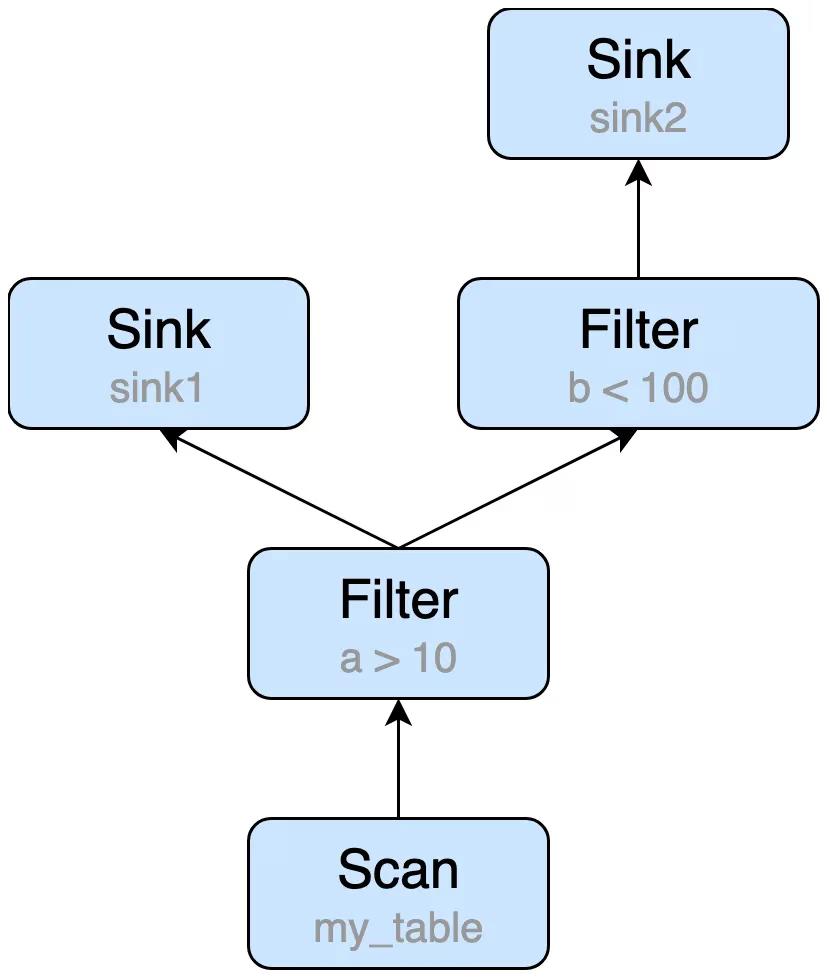
### Fast Aggregation
Aggregate queries are widely used in [Flink SQL](https://ververica.com/blog/apache-flink-sql-past-present-and-future). We will introduce some useful streaming aggregate optimization methods which could bring great improvement in some cases.
Streaming aggregation operator is a stateful operator, which uses state to store the intermediate aggregate results. By default, the streaming aggregation operators process input records one by one. When a record comes in, the operator will (1) read the accumulator from state, (2) accumulate/retract the record to the accumulator, (3) write the accumulator back to state. This processing pattern may cause performance problems of StateBackend, especially when State access is time-consuming and data skew exists after shuffling.
```sql
SELECT color, SUM(num) FROM my_table GROUP BY color;
```
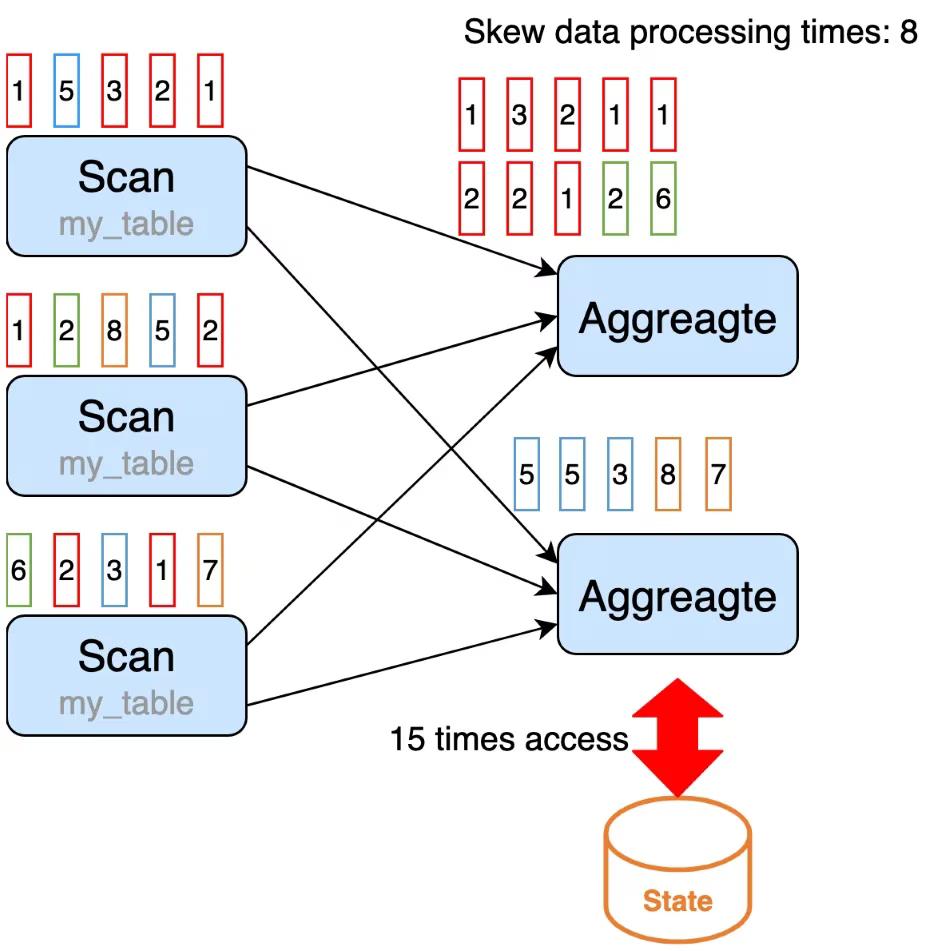
In order to solve the above-mentioned problems, we have introduced various optimization options for different scenarios.
Note: The streaming aggregation optimizations mentioned in this section are all supported for [Group Aggregations](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/group-agg/) and [Window TVF Aggregations](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/window-tvf/) now. We can also see the introduction in the [Flink documentation](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/tuning/).
### MiniBatch Aggregation
To reduce state access, we can introduce MiniBatch aggregation, which puts the input record into a buffer and triggers the aggregation operation after the buffer is full. The records with the same key in the buffer will be handled together, so only one operation per key to access state is needed.
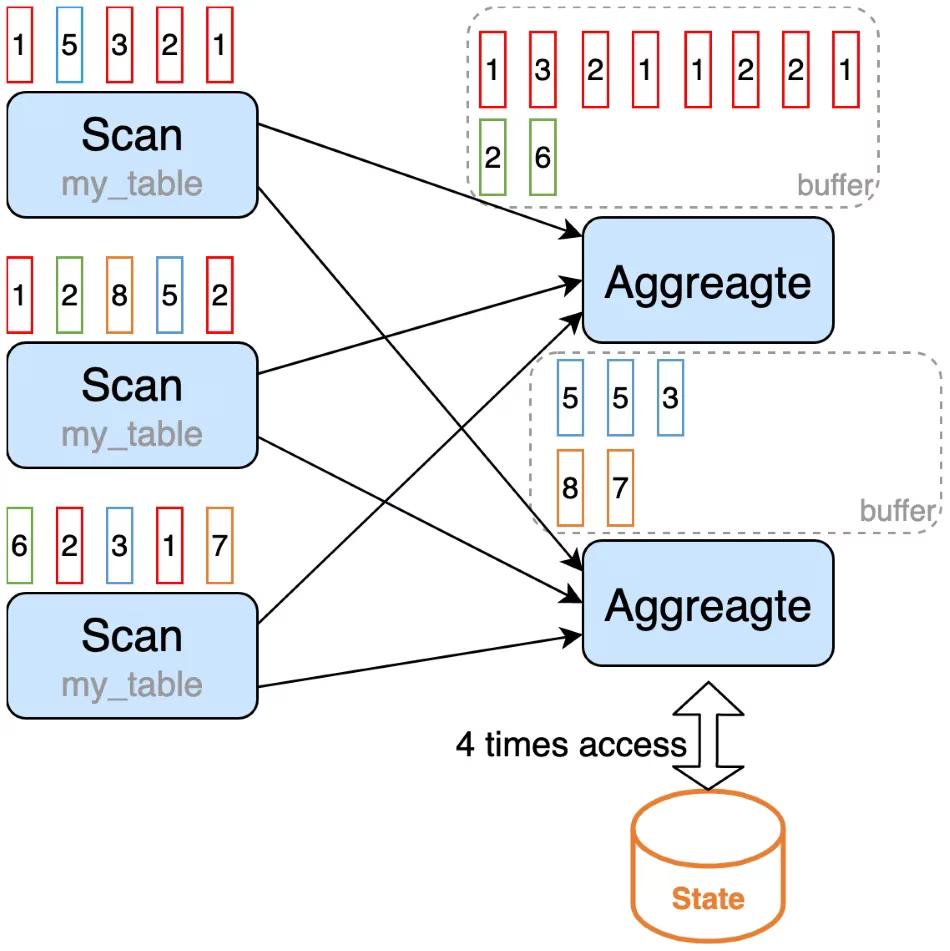
MiniBatch Aggregation is disabled by default, we should set the following options to enable it.
```
table.exec.mini-batch.enabled: true // enable mini-batch
table.exec.mini-batch.allow-latency: 5s // put the records into a buffer within 5 seconds
```
MiniBatch can significantly reduce the state access and get better throughput. However, this will increase latency because the operator starts processing the records until the buffer is full instead of processing them in an instant. It is a trade-off between throughput and latency. Another benefit of MiniBatch is that the aggregation operator will output fewer records, especially in scenarios where there are retraction messages and the processing performance of downstream operators is insufficient.
### Local/Global Aggregation
In the example above, the data is skewed after shuffling, the first aggregate operator instance will process more data than other instances. This may cause performance problems.
To solve this, we can introduce Local/Global aggregation, which divides the aggregation into two stages, that is doing local aggregation in upstream (before shuffling) firstly, and followed by global aggregation in downstream (after shuffling). The local aggregation is chained with its upstream operator, this could avoid data skew caused by shuffling.
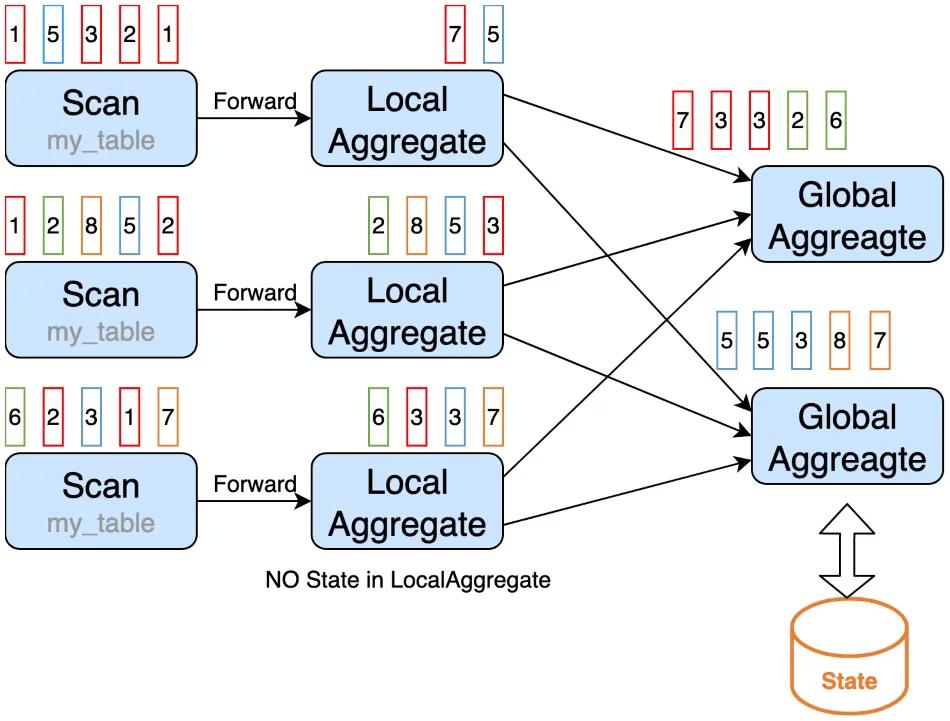
Local/Global Aggregation is disabled by default, we can set the following options to enable it, while making sure that all aggregate functions in a query must implement the _merge_ method.
```
table.exec.mini-batch.enabled: true // enable mini-batch
table.exec.mini-batch.allow-latency: 5s // do a local aggregation within 5 seconds
table.optimizer.agg-phase-strategy: TWO_PHASE/AUTO // enable two phase aggregation
```
Local/Global Aggregation cannot solve the data-skew issues for distinct aggregation if the distinct key is sparse, the following example illustrates this problem.
```sql
SELECT color, COUNT(DISTINCT id) FROM my_table GROUP BY color;
```
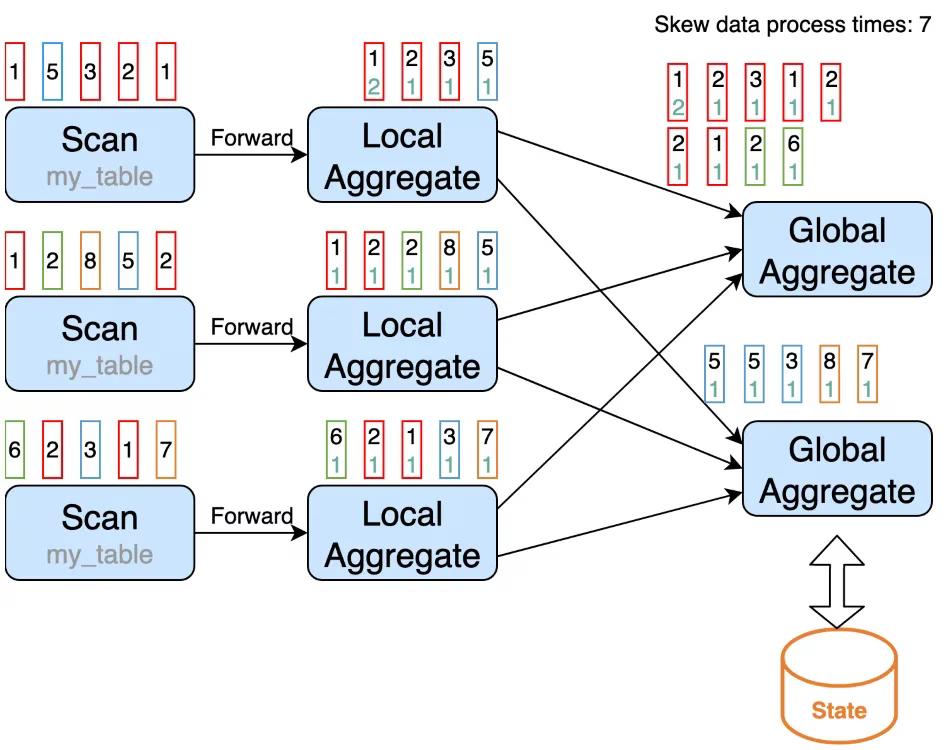
To solve this, we can introduce partial/final aggregation, which splits the distinct aggregation into two levels. The first aggregation (called partial aggregation) is shuffled by group key and an additional bucket key, which is _HASH_CODE(distinct_key) % BUCKET_NUM_. The second aggregation (called final aggregation) is shuffled by group key, and uses _SUM_ to aggregate _COUNT DISTINCT_ values from different buckets. The capacity to scale the job to solve data skew in distinct aggregations depends on the bucket key.
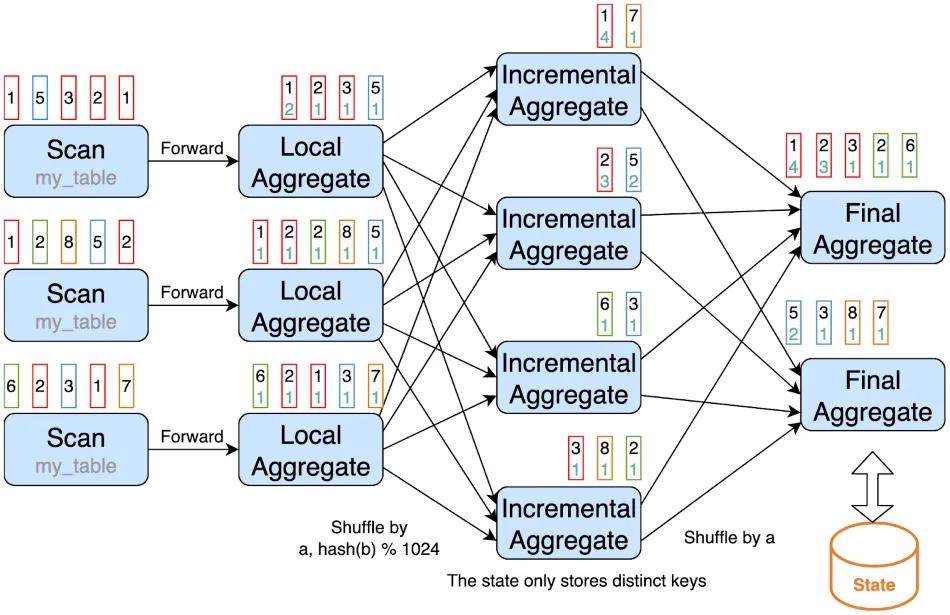
We can manually rewrite the above query into the following to enable partial/final aggregation.
```sql
SELECT color, SUM(cnt) FROM (
SELECT color, COUNT(DISTINCT id) as cnt
FROM my_table
GROUP BY color, MOD(HASH_CODE(id), 1024)
) GROUP BY color;
```
Or, we can set the following options to enable it, while making sure that all aggregate functions in a query must be built-in aggregation functions and be splittable, e.g. AVG, SUM, COUNT, MAX, MIN.
```
table.optimizer.distinct-agg.split.enabled: true // enable partial/final aggregation
table.optimizer.distinct-agg.split.bucket-num: 1024 // bucket number
```
> **NOTE:** Different from local aggregation, partial aggregation has state and shuffling cost, we do not recommend enabling partial/final aggregation if the input dataset is small or there are no data skew issues for the distinct aggregate.
### Incremental Aggregation
The state for partial aggregation may be very large if the distinct key is very sparse. We can introduce incremental aggregation to reduce the state size of partial aggregation. The state of incremental aggregation only stores the distinct keys, the aggregation function values will be stored in final aggregation.
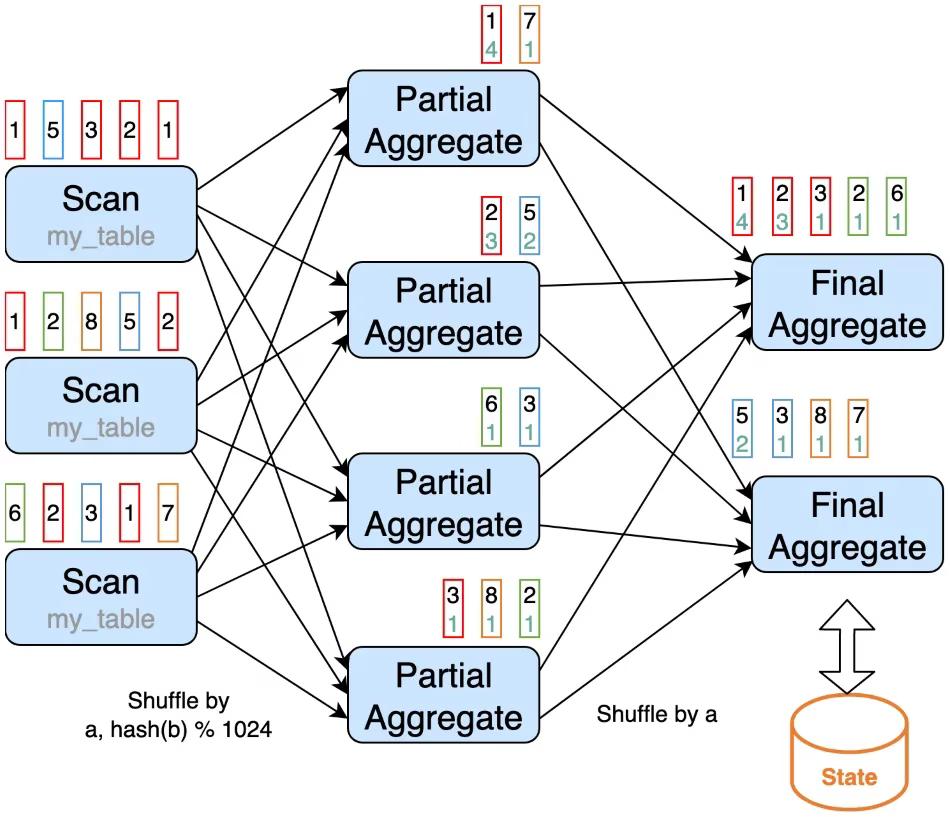
To enable incremental aggregation, we should set the following options, and also make sure the query supports MiniBatch optimization, Local/Global optimization and Partial/Final optimization at the same time.
```
table.exec.mini-batch.enabled: true // enable mini-batch
table.exec.mini-batch.allow-latency: 5s // do a local aggregation within 5 seconds
table.optimizer.agg-phase-strategy: TWO_PHASE/AUTO // enable two phase aggreation
table.optimizer.distinct-agg.split.enabled: true // enable partail/final aggregation
table.optimizer.distinct-agg.split.bucket-num: 1024 // bucket number
table.optimizer.incremental-agg-enabled: true // enable incremental agg, default is true
```
### Distinct Aggregate Function with FILTER
In some cases, a query calculates distinct results based on the same value but different dimensions. Such as: a user wants to calculate the number of UV (unique visitor) from different dimensions, e.g. UV from App, UV from Web and the total UV. Many users choose _CASE WHEN_ to support this, for example:
```sql
SELECT
day,
COUNT(DISTINCT user_id) AS total_uv,
COUNT(DISTINCT CASE WHEN flag = 'app' THEN user_id ELSE NULL END) AS app_uv,
COUNT(DISTINCT CASE WHEN flag = 'web' THEN user_id ELSE NULL END) AS web_uv
FROM my_table
GROUP BY day;
```
For the query above, the state corresponding to the same function with the same distinct field is stored independently in an aggregation operator. The state structure is shown in the figure below.
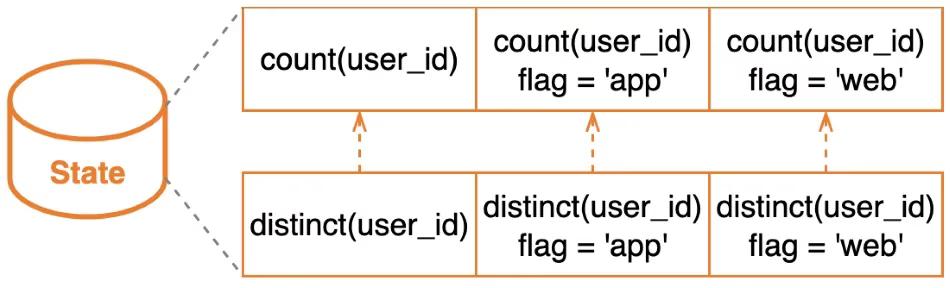
We recommend using _FILTER_ syntax instead of _CASE WHEN_ to let the planner do more optimizations to reduce the state size. Besides, _FILTER_ is more compliant with the SQL standard.
```sql
SELECT
day,
COUNT(DISTINCT user_id) AS total_uv,
COUNT(DISTINCT) FILTER (WHERE flag = 'app') AS app_uv,
COUNT(DISTINCT) FILTER (WHERE flag = 'web') AS web_uv
FROM my_table
GROUP BY day;
```
After the query is rewritten, the state corresponding to the same function with the same different fields will be stored and shared in an aggregate operator. The new state structure can be improved as follows.
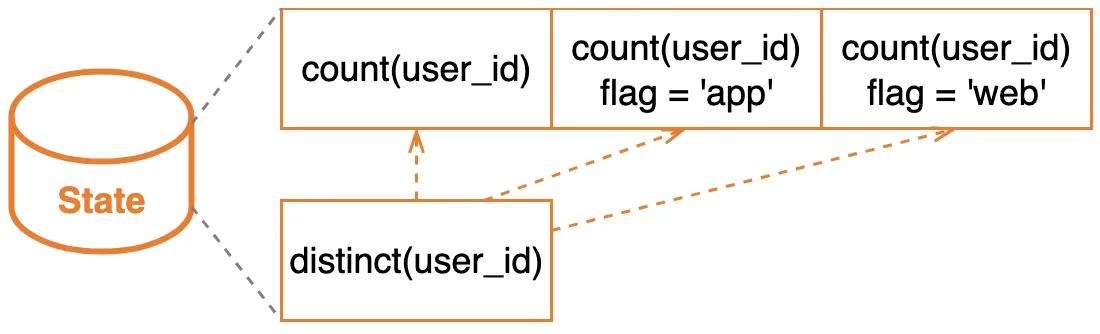
### Fast Join
[Join queries](https://www.ververica.com/blog/flink-sql-joins-part-1) are widely used in FLINK SQL. There are different types of joins in streaming queries, the join in batch processing is called [regular join](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/joins/#regular-joins) in stream processing. Regular join is the most generic type of join in which any new record, or changes to either side of the join, are visible and affect the entirety of the join result. The state of regular join keeps both sides of the join input forever. The required state for computing the query result might grow infinitely depending on the number of distinct input rows of all input tables and intermediate join results. Reducing the state size is the key to optimize regular join performance.
There are three suggestions to reduce the state size of regular join:
1. Please make sure the join key contains the primary key or the join input has the primary key. In the following figure, we can see the state size for each case.
1. Only keep the necessary fields before join operation.
1. In addition to regular join, Flink also provides other types of joins, such as: Lookup Join, Temporal Join, Interval Join, Window Join If you can make some trade-offs in business, join can be rewritten as other joins.
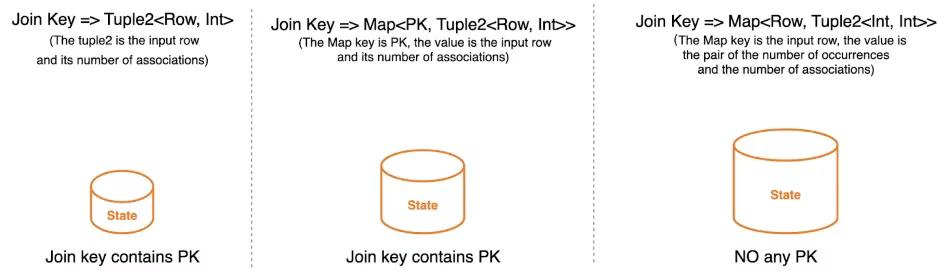
```sql
SELECT *
FROM my_table1 t1
JOIN my_table2 t2
ON t1.a = t2.c;
```
- Regular joins are rewritten as [temporal joins](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/joins/#temporal-joins). Temporal joins allow joining against a [versioned table](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/concepts/versioned_tables/), records from the probe side are always joined with the build side’s version at the time specified by the time attribute. As time passes, versions of the record that are no longer needed (for the given primary key) will be removed from the state. So the state size of temporal joins is less than regular joins.
```sql
SELECT *
FROM my_table1 t1
JOIN my_table2 FOR SYSTEM_TIME AS OF t1.row_time t2
ON t1.a = t2.c;
```
- Regular joins are rewritten as [lookup joins](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/joins/#lookup-join). Lookup joins are typically used to enrich or filter the main-stream (a.k.a probe side) data. Records from the probe side are always joined with the latest version in the lookup source connector. Different from other joins, only the probe side can trigger the join operation, and the build side will not trigger even if it receives a new record. So lookup joins don't need state to store the input records. Please see "Fast Lookup Join" for more optimization.
```sql
SELECT *
FROM my_table1 t1
JOIN my_table2 FOR SYSTEM_TIME AS OF t1.proctime AS t2
ON t1.a = t2.c;
```
- Regular joins are rewritten as [Interval joins](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/joins/#interval-joins). Interval joins allow joining the elements of two streams that share a common key and are within a time range. Interval joins only support append-only tables with time attributes. Since time attributes are quasi-monotonic increasing, Flink can remove old values from its state without affecting the correctness of the result. So the state size of interval joins is less than regular joins.
```sql
SELECT *
FROM my_table1 t1
JOIN my_table2 t2
ON t1.a = t2.c AND t1.row_time BETWEEN t2.row_time - INTERVAL '10' MINUTE AND t2.row_time;
```
- Regular joins are rewritten as [window joins](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/window-join/). Windows joins allow joining the elements of two streams that share a common key and are in the same window. Unlike other joins on continuous tables, window join does not emit intermediate results but only emits final results at the end of the window. Moreover, window join purges all intermediate states when no longer needed. So the state size of window joins is also less than regular joins.
```sql
SELECT * FROM (
SELECT * FROM TABLE(TUMBLE(TABLE my_table1, å
DESCRIPTOR(row_time), INTERVAL '10' MINUTES))
) t1 JOIN (
SELECT * FROM TABLE(TUMBLE(TABLE my_table2,
DESCRIPTOR(row_time), INTERVAL '10' MINUTES))
) t2
ON t1.window_start = t2.window_start
AND t1.window_end = t2.window_end
AND t1.a = t2.c;
```
### Fast Lookup Join
Compared with other types of join, lookup join is the most widely used in production, so here is a further introduction to its optimization. We provide multiple optimization options to improve throughput:
1. Use Sync and Async Lookup Function
Lookup function can support both synchronous (sync) mode and asynchronous (async), their operating mechanism is as follows, and we can see the asynchronous mode has higher throughput.
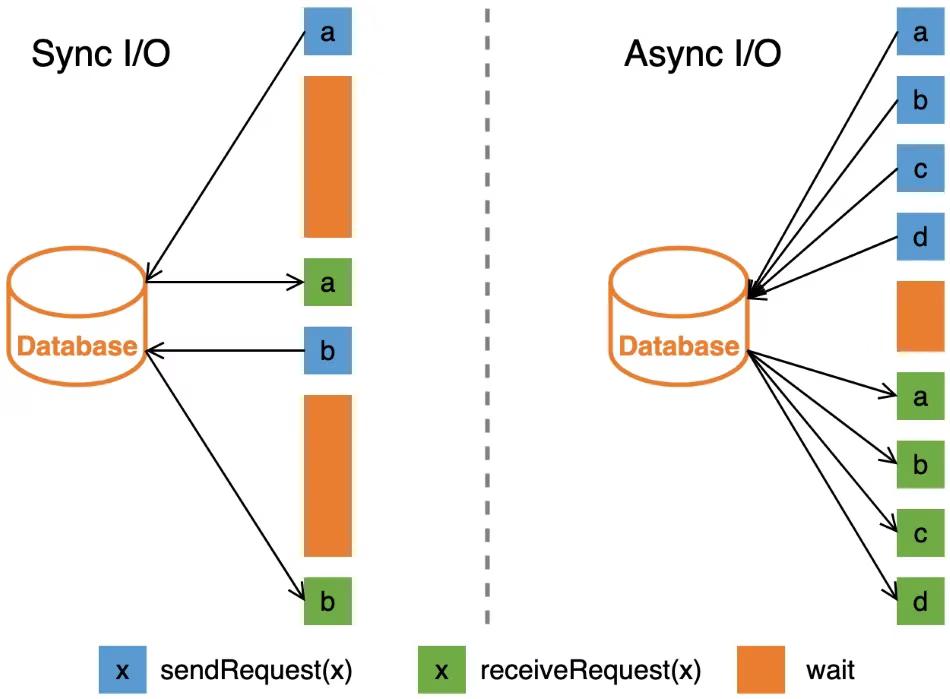
If the connector has async lookup capability, we can use [_LOOKUP_](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/hints/#1-use-sync-and-async-lookup-function) [hints](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/hints/#1-use-sync-and-async-lookup-function) to suggest the planner to use the async lookup function.
```sql
-- use async mode
SELECT /*+ LOOKUP('table'='my_table2', 'async'='true') */ *
FROM my_table1 AS t1 JOIN my_table2
FOR SYSTEM_TIME AS of t1.proctime AS t2 ON t1.a = t2.c;
-- use sync mode
SELECT /*+ LOOKUP('table'='my_table2', 'async'='false') */ *
FROM my_table1 AS t1 JOIN my_table2
FOR SYSTEM_TIME AS of t1.proctime AS t2 ON t1.a = t2.c;
```
2. Use ordered mode and unordered mode for async output mode.
In async mode, there are two modes to control in which order the resulting records are emitted:
- **Ordered**: Result records are emitted in the same order as the asynchronous requests are triggered (the order of the operators input records).
- **Unordered**: Result records are emitted as soon as the asynchronous request finishes. The order of the records in the stream may be different after the async I/O operator than before. It has higher throughput than ordered mode.
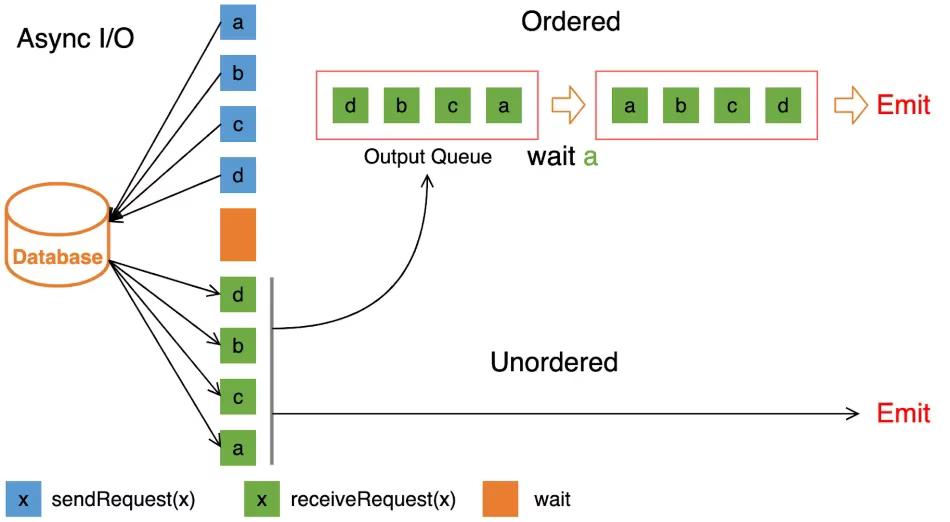
We can also use [_LOOKUP_](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/hints/#2-configure-the-async-parameters) [hints](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/hints/#2-configure-the-async-parameters) to suggest the planner to use the unordered mode.
```sql
-- use unordered mode
SELECT /*+ LOOKUP('table'='my_table2', 'async'='true')
'output-mode'='allow_unordered', 'capacity'='100',
'timeout'='180s') */ *
FROM my_table1 AS t1 JOIN my_table2
FOR SYSTEM_TIME AS of t1.proctime AS t2 ON t1.a = t2.c;
-- use ordered mode
SELECT /*+ LOOKUP('table'='my_table2', 'async'='true')
'output-mode'='ordered', 'capacity'='100',
'timeout'='180s') */ *
FROM my_table1 AS t1 JOIN my_table2
FOR SYSTEM_TIME AS of t1.proctime AS t2 ON t1.a = t2.c;
```
3. Use CACHE
Caching is a common solution to reduce I/O and speed up lookup performance. Flink provides three caching strategies, FULL caching for small dataset, PARTIAL caching for large dataset, and NONE caching to disable it. We can also use [rich options](https://cwiki.apache.org/confluence/display/FLINK/FLIP-221%3A+Abstraction+for+lookup+source+cache+and+metric) to control caching behavior.
### Fast Deduplication
The upstream jobs may not have end-to-end exactly-once, which will result in data duplication in the source table. So we often encounter the requirement to keep the first or last row. Flink SQL does not provide deduplication syntax. In previous versions, Flink used an aggregation query with FIRST_VALUE to find the first row for a key or with LAST_VALUE to find the last row for a key.
```sql
-- find the first row per key
SELECT key, FIRST_VALUE(a), FIRST_VALUE(b) FROM my_table GROUP BY key;
-- find the last row per key
SELECT key, LAST_VALUE(a), LAST_VALUE(b) FROM my_table GROUP BY key;
```
From the "Fast Aggregation" section, we can see the aggregation operator will store a complete row for each key, which will cause the large state size. The FIRST_VALUE and LAST_VALUE aggregate function will ignore null values, which will cause wrong results if some columns have null values.
Now, Flink SQL uses ROW_NUMBER() to remove duplicates, just like the way of the [Top-N query](https://www.ververica.com/blog/flink-sql-recipe-window-top-n-and-continuous-top-n).
```sql
-- find the first row per key
SELECT a, b, c FROM (
SELECT a, b, c,
ROW_NUMBER() OVER (PARTITION BY a ORDER BY time_attr ASC) AS rn
FROM my_table)
WHERE rn = 1;
-- find the last row per key
SELECT a, b, c FROM (
SELECT a, b, c,
ROW_NUMBER() OVER (PARTITION BY a ORDER BY time_attr DESC) AS rn
FROM my_table)
WHERE rn = 1;
```
For the first row, the operator only needs to store the first row of each key, and for the last row, the operator only needs to store the last row for each key. At the same time, there is no problem with wrong results.
### Fast TOP-N
[Top-N](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/topn/) (a.k.a Rank) queries are always used to get the N smallest or largest values. Flink SQL does not provide Top-N specific syntax but uses the combination of an OVER window clause and a filter condition to express a [Top-N query](https://ververica.com/blog/flink-sql-recipe-window-top-n-and-continuous-top-n). Now Flink SQL provides 3 kinds of rank algorithms with their performance decreasing sequentially.
1. AppendRank: Only this algorithm is supported for insert-only changes input. The state of the rank operator stores the N smallest or largest records for each key.
1. UpdateFastRank: Only this algorithm is supported iff the following requirements are met:
- The input produces update changes,
- The upsert key of input must contain the partition key for the over query,
- The order-by fields in the OVER query are monotonic, and the monotonic direction is opposite to the order-by direction.
The following query can be converted to the UpdateFastRank operator.
```sql
SELECT a, b, c FROM (
SELECT a, b, c,
ROW_NUMBER() OVER (
-- The upsert key from upstream contains partition key
PARTITION BY a, b
-- c is monotonically increasing, while the order-by
-- direction is monotonically decreasing
ORDER BY c DESC) AS rn
FROM (
SELECT a, b,
-- Declare the argument of sum to be a positive number,
-- So that the result of sum is monotonically increasing
SUM(c) FILTER (WHERE c >= 0) AS c
FROM my_table
-- Produce upsert stream, the upsert key is a, b
GROUP BY a, b))
WHERE rn < 10;
```
The state of UpdateFastRank stores a map, its key is order key and its value is the record and the order number. The state size is greater than AppendRank, but less than RetractRank.
1. RetractRank: This algorithm is supported for all queries. The state will store all the input data, so the state size may be very large. For optimization, the planner will try best to convert a given query into an AppendRank first, and then UpdateFastRank.
In addition to modifying the query to meet different rank algorithms, there are also some other optimization techniques to reduce state size or speed up state access.
1. Do not output a rank number. This significantly reduces the amount of data that is to be written to the result table. The results can be sorted when they are finally displayed in the frontend.
1. Increase the cache size of the rank operator. Rank operator provides a cache mechanism to reduce state access. The following formula is used to calculate the cache hit ratio:
```
cache_hit = cache_size * parallelism / top_n_num / partition_key_num
```
The state size is configured by _table.exec.rank.topn-cache-size_, the default value is 10000. If the parallelism is 50 and the top-n number is 100 and the number of partition key is 100000, we can get the cache hit is _10000 * 50 / 100 / 100000 = 5%_. In this case, 95% requests will access the state backend directly. If we increase the cache size to 200000, the cache hit will be _200000 * 50 / 100 / 100000 = 100%_, which indicates no request will access the state backend.
Please note that heap memory of the task manager needs to increase with the increase of cache size, otherwise OOM exceptions may occur.
Include a time field in the PARTITION BY clause. By default, the data in state has nothing to do with time, and the state of the rank operator cannot be cleaned, otherwise it will produce the wrong results. If we can add a time field in the PARTITION BY clause, we can also configure the time-to-live (TTL) to clean the outdated state data. Such as, we add the Day field to PARTITION BY and configure the TTL as 1.5 days.
### Efficient User Defined Connector
Flink SQL provides multiple interfaces to optimize user defined source connectors. You should implement the following interfaces as needed:
1. SupportsFilterPushDown: The planner will push the filters into the table source connector to avoid reading invalid **data** and reduce scan I/O.
1. SupportsProjectionPushDown: The planner will push the needed fields into the table source connector to avoid reading invalid **columns** and reduce scan I/O.
1. SupportsPartitionPushDown: The planner will push the needed partition list into the table source connector to avoid reading invalid **partitions** and reduce scan I/O.
1. SupportsDynamicFiltering: The planner will push the dynamic filtering information into the table source connector to avoid reading invalid partitions and reduce scan I/O. Different from SupportsPartitionPushDown, filtering invalid partitions will happen at runtime rather than at the static planning stage.
1. SupportsLimitPushDown: The planner will push the limit information into the table source connector to avoid reading redundant data, only the number of limit records will be read for each source instance.
1. SupportsAggregatePushDown: The planner will push the aggregate functions into the table source connector to reduce scan I/O.
1. SupportsStatisticReport: The planner could get statistics from the table source connector, and can generate a better execution plan.
## Use Hints Well
Flink SQL supports changing execution behavior via [hints.](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/hints/) There are two kinds of hints:
1. Table Hints: Table Hints (a.k.a Dynamic table options) allows to specify or override table options dynamically. For example, we can use _/*+ OPTIONS('lookup.cache'='FULL') */_ to change the cache strategy of the lookup table.
1. Query Hints: Query hints can be used to suggest the optimizer to affect query execution plans within a specified query scope. _LOOKUP_ hint is used to change lookup join operator behavior. For example, use _/*+ LOOKUP('table_'_=_'_my_table2', 'async_'_=_ '_true_'_) */_ to enable the async lookup function. _BROADCAST, SHUFFLE_HASH, SHUFFLE_MERGE_ and _NEST_LOOP_ hints are used to choose batch join strategy. For example, use _/*+ BROADCAST(t1)*/_ to suggest the optimizer chooses Broadcast Hash Join.
## Future Developments
In the future, we will continue to improve the planner and focus on three areas:
1. Deeper optimization: We will continue to work hard on the depth of optimization, such as incremental join, multiple joins.
1. Richer optimization: We will closely combine more business scenarios for optimization.
1. Smarter optimization: We will combine dynamic information at runtime for optimization, such as dynamic planning optimization.
---
---
title: "Flink SQL Joins - Part 1"
description: "Discover how to effectively use Regular, Interval, and Lookup Joins in Flink SQL for seamless data processing across streams and batches. Enhance your analytics capabilities today."
lastUpdated: 2026-07-06T11:10:39.000Z
source_url:
html: "https://www.ververica.com/blog/flink-sql-joins-part-1"
md: "https://www.ververica.com/blog/flink-sql-joins-part-1.md"
---
[Flink SQL](https://www.ververica.com) has emerged as the de facto standard for [low-code data analytics](https://www.ververica.com/product). It has managed to unify batch and stream processing while simultaneously staying true to the SQL standard. In addition, it provides a rich set of advanced features for real-time use cases. In a nutshell, Flink SQL provides the best of both worlds: it gives you the ability to **process streaming data using SQL, but it also supports batch processing.**
[Ververica Platform](https://ververica.com/platform) makes Flink SQL even more accessible and efficiently scalable across teams. The platform comes with additional tools for developing SQL scripts, managing [user-defined functions (UDFs)](https://docs.ververica.com/user_guide/sql_development/functions.html#user-defined-functions-udfs), [catalogs](https://docs.ververica.com/user_guide/sql_development/catalogs.html) and [connectors](https://docs.ververica.com/user_guide/sql_development/connectors.html), as well as operating the resulting long-running queries.
Since Flink SQL stayed true to the ANSI-SQL 2011 standard, all features from compliant databases should work. This includes inner and outer joins, and all the other join types that are described in the SQL standard. In this three-part series of blog posts, we will show you different types of joins in Flink SQL and how you can use them to process data in a variety of ways. This post will focus on [regular joins](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/joins/#regular-joins), [interval joins](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/joins/#interval-joins), and [lookup joins](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/joins/#lookup-join).
We have seen that there are many [use cases](https://youtu.be/AxBNj6yOEZI) for Flink SQL, and we are excited to see what you will build with it.
> **NOTE:** Make sure to check out our previous articles on Flink SQL: Flink SQL: Window Top-N and Continuous Top-N
## Regular Joins
The four types of joins commonly used in SQL are: INNER and [FULL|LEFT|RIGHT] OUTER.
- INNER JOIN: Returns all rows from both tables where the key columns match
- LEFT JOIN: Returns all rows from the left table, and the matching rows from the right table
- RIGHT JOIN: Returns all rows from the right table, and the matching rows from the left table
- FULL JOIN: Returns all rows from both tables, whether the key columns match or not
Joins are used in SQL to combine data from two or more tables. When you use a join, you specify the columns from each table that you want to use to create the new table.
You can also use joins to create a single table that contains data from multiple tables. For example, if you had a table that contained information on customers and another table that contained information on orders, you could use a join to create a single table that contained both customer information and order information.
### How to use Flink SQL to write Regular Joins
> **NOTE:** This example will show how you can use joins to correlate rows across multiple tables.
Flink SQL supports complex and flexible join operations over continuous tables. There are several different types of joins to account for the wide variety of semantics that queries may require.
Regular joins are the most generic and flexible types of join. These include the standard `INNER` and `[FULL|LEFT|RIGHT] OUTER` joins that are available in most modern databases.
Suppose we have a [NOC list](https://en.wikipedia.org/wiki/Non-official_cover) of secret agents all over the world. Your mission if you choose to accept it, is to join this table with another containing the agents’ real name.
In Flink SQL, this can be achieved using a simple `INNER JOIN`. Flink will join the tables using an equi-join predicate on the `agent_id` and output a new row every time there is a match.
However, there is something to be careful of. Flink must retain every input row as part of the join to potentially join it with the other table in the future. This means the queries’ resource requirements will grow indefinitely and will eventually fail. While this type of join is useful in some scenarios, other joins are more powerful in a streaming context and significantly more space-efficient.
In this example (which uses [flink-faker](https://github.com/knaufk/flink-faker) to generate record values based on defined expressions), both tables are bounded to remain space efficient.
```sql
CREATE TABLE NOC (
agent_id STRING,
codename STRING
)
WITH (
'connector' = 'faker',
'fields.agent_id.expression' = '#{regexify ''(1|2|3|4|5){1}''}',
'fields.codename.expression' = '#{superhero.name}',
'number-of-rows' = '10'
);
CREATE TABLE RealNames (
agent_id STRING,
name STRING
)
WITH (
'connector' = 'faker',
'fields.agent_id.expression' = '#{regexify ''(1|2|3|4|5){1}''}',
'fields.name.expression' = '#{Name.full_name}',
'number-of-rows' = '10'
);
SELECT
name,
codename
FROM NOC
INNER JOIN RealNames ON NOC.agent_id = RealNames.agent_id;
```
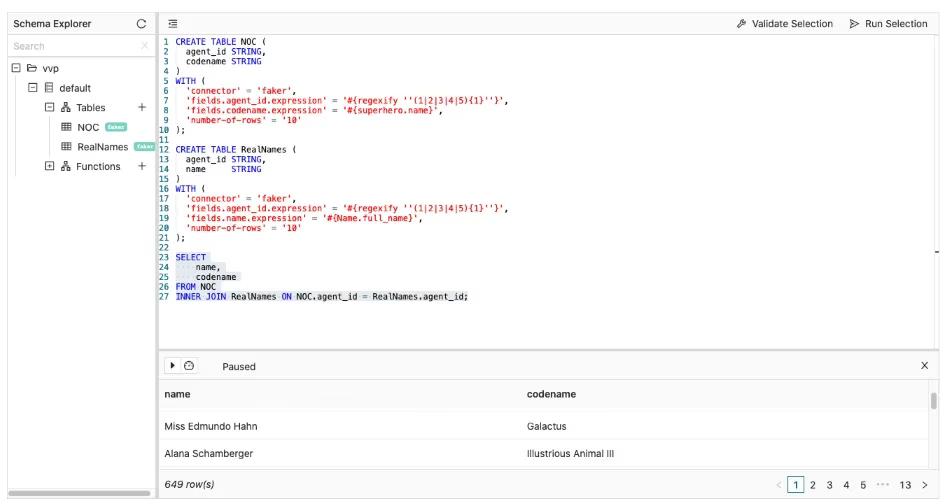
## Interval Joins
[Interval joins](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/streaming/joins.html#interval-joins) in Flink SQL are joins that are performed on two sets of data, where each set is divided into intervals. The intervals are defined by a start and end time, and the data in each set is assigned to an interval based on its timestamp. Interval joins are used to compare data in two sets that are separated by a certain amount of time.
For example, consider two sets of data, one for sales data and one for customer data. The sales data set is divided into intervals of one hour, and the customer data stream is divided into intervals of one day. Interval joins can be used to join the sales data for each hour with the customer data for the corresponding day.
### How to use Flink SQL to write Interval Joins
> **NOTE:** This example will show how you can perform joins between tables with events that are related in a temporal context.
In the above-mentioned example, you learned about using regular joins in Flink SQL. This kind of join works well for some scenarios, but for others a more efficient type of join is required to keep resource utilization from growing indefinitely.
One of the ways to optimize joining operations in Flink SQL is to use [interval joins](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/streaming/joins.html#interval-joins). An interval join is defined by a join predicate that checks if the time attributes of the input events are within certain time constraints, i.e. a time window.
Suppose you want to join events of two tables that correlate to each other in the [order fulfillment lifecycle](https://en.wikipedia.org/wiki/Order_fulfillment) (`orders` and `shipments`) and that are under a Service-level Agreement (SLA) of 3 days. To reduce the amount of input rows Flink has to retain and optimize the join operation, you can define a time constraint in the `WHERE` clause to bound the time on both sides to that specific interval using a `BETWEEN` predicate.
In the query below, the source tables (`orders` and `shipments`) are backed by the built-in [datagen connector](https://nightlies.apache.org/flink/flink-docs-master/docs/connectors/table/datagen/), which continuously generates rows in memory.
```sql
CREATE TABLE orders (
id INT,
order_time AS TIMESTAMPADD(DAY, CAST(FLOOR(RAND()*(1-5+1)+5)*(-1) AS INT), CURRENT_TIMESTAMP)
)
WITH (
'connector' = 'datagen',
'rows-per-second'='10',
'fields.id.kind'='sequence',
'fields.id.start'='1',
'fields.id.end'='1000'
);
CREATE TABLE shipments (
id INT,
order_id INT,
shipment_time AS TIMESTAMPADD(DAY, CAST(FLOOR(RAND()*(1-5+1)) AS INT), CURRENT_TIMESTAMP)
)
WITH (
'connector' = 'datagen',
'rows-per-second'='5',
'fields.id.kind'='random',
'fields.id.min'='0',
'fields.order_id.kind'='sequence',
'fields.order_id.start'='1',
'fields.order_id.end'='1000'
);
SELECT
o.id AS order_id,
o.order_time,
s.shipment_time,
TIMESTAMPDIFF(DAY,o.order_time,s.shipment_time) AS day_diff
FROM orders o
JOIN shipments s ON o.id = s.order_id
WHERE
o.order_time BETWEEN s.shipment_time - INTERVAL '3' DAY AND s.shipment_time;
```
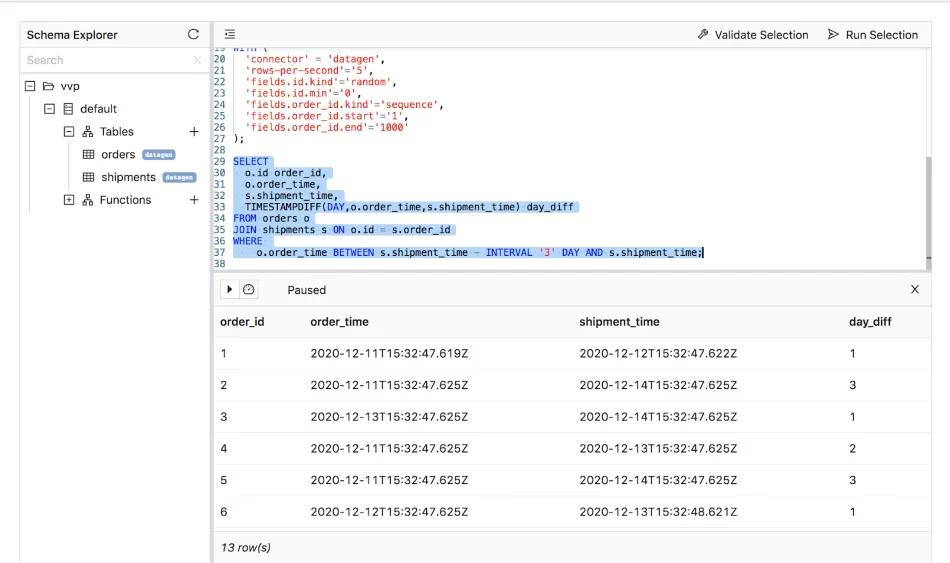
## Lookup Joins
In Flink SQL, [lookup joins](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/queries/joins/#lookup-join) are used to join two data sets on a common key. The first set is joined with a static table, and the second set is joined with a [dynamic table](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/concepts/dynamic_tables/).
For example, consider two sets of data, one for sales data and one for customer data. The sales data set contains a customer ID column, which can be used to join with the customer data set. The customer data set is defined as a lookup table, meaning that it is static and does not change over time. The sales data is then joined with the customer data set on the customer ID column.
### How to use Flink SQL to write Lookup Joins
> **NOTE:** This example will show how you can enrich a stream with an external table of reference data (i.e. a lookup table)
Not all data changes frequently, even when working in real-time: in some cases, you might need to enrich streaming data with static — or _reference_ — data that is stored externally. For example, `user` metadata may be stored in a relational database that Flink needs to join against directly. Flink SQL allows you to look up reference data and join it with a stream using a _lookup join_. The join requires one table to [have a processing time](https://docs.ververica.com/user_guide/sql_development/table_view.html#processing-time-attributes) attribute and the other table to be backed by a [lookup source connector](https://docs.ververica.com/user_guide/sql_development/connectors.html#id1), like the JDBC connector.
In this example, you will look up reference user data stored in MySQL to flag subscription events for users that are minors (`age < 18`). The `FOR SYSTEM_TIME AS OF` clause uses the processing time attribute to ensure that each row of the `subscriptions` table is joined with the `users` rows that match the join predicate at the point in time when the `subscriptions` row is processed by the join operator. The lookup join also requires an equality join predicate based on the `PRIMARY KEY` of the lookup table (`usub.user_id = u.user_id`). Here, the source does not have to read the entire table and can lazily fetch individual values from the external table when necessary.
In the script below, the source table (`subscriptions`) is backed by the [faker connector](https://flink-packages.org/packages/flink-faker), which continuously generates rows in memory based on Java Faker expressions. The `users` table is backed by an existing MySQL reference table using the [JDBC connector](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/connectors/jdbc.html)
```sql
CREATE TABLE subscriptions (
id STRING,
user_id INT,
type STRING,
start_date TIMESTAMP(3),
end_date TIMESTAMP(3),
payment_expiration TIMESTAMP(3),
proc_time AS PROCTIME()
) WITH (
'connector' = 'faker',
'fields.id.expression' = '#{Internet.uuid}',
'fields.user_id.expression' = '#{number.numberBetween ''1'',''50''}',
'fields.type.expression'= '#{regexify ''(basic|premium|platinum){1}''}',
'fields.start_date.expression' = '#{date.past ''30'',''DAYS''}',
'fields.end_date.expression' = '#{date.future ''365'',''DAYS''}',
'fields.payment_expiration.expression' = '#{date.future ''365'',''DAYS''}'
);
CREATE TABLE users (
user_id INT PRIMARY KEY,
user_name VARCHAR(255) NOT NULL,
age INT NOT NULL
)
WITH (
'connector' = 'jdbc',
'url' = 'jdbc:mysql://localhost:3306/mysql-database',
'table-name' = 'users',
'username' = 'mysql-user',
'password' = 'mysql-password'
);
SELECT
id AS subscription_id,
type AS subscription_type,
age AS user_age,
CASE
WHEN age < 18 THEN 1
ELSE 0
END AS is_minor
FROM subscriptions usub
JOIN users FOR SYSTEM_TIME AS OF usub.proc_time AS u
ON usub.user_id = u.user_id;
```
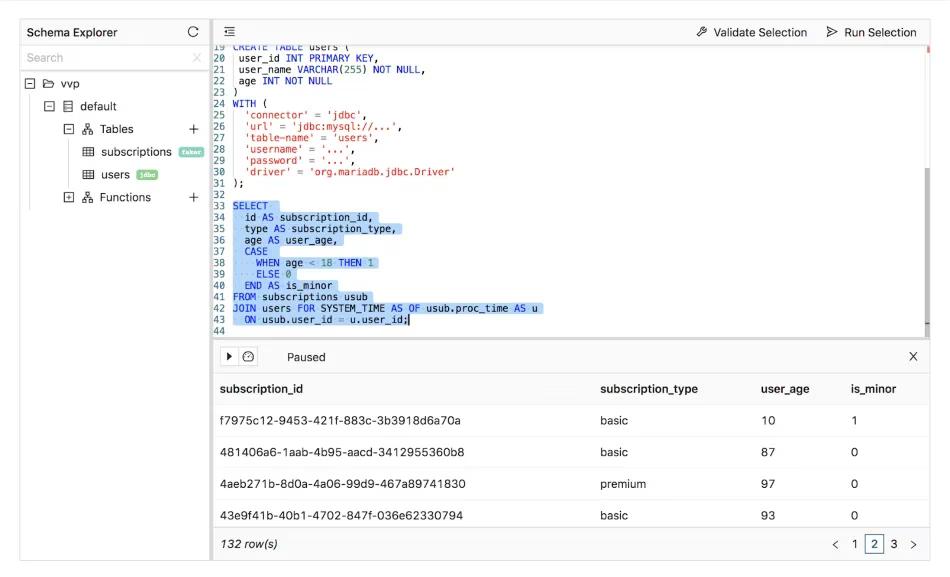
## Summary
In this article, you learned about Regular, Interval, and Lookup Joins. You also saw how to use Flink SQL to write queries with them.
We encourage you to run these examples on Ververica Platform. You can follow [these simple steps](https://docs.ververica.com/getting_started/installation.html) to install the platform.
To learn more about Flink SQL, check out the following resources:
- [Flink SQL Cookbook](https://github.com/ververica/flink-sql-cookbook)
- [Getting Started - Flink SQL on Ververica Platform](https://docs.ververica.com/getting_started/sql_development.html)
- [The official Flink SQL documentation](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/overview/)
- [Flink Forward Talk: One SQL, Unified Analytics](https://youtu.be/rOzA4CIeXOw?t=924)
- [Only SQL: Empower data analysts end-to-end with Flink SQL](https://youtu.be/KvaDe7QCwBQ)
---
---
title: "The Release of Flink CDC v2.3"
description: "Flink CDC v2.3 enhances real-time data integration with new connectors, improved stability, and performance optimizations. Discover the latest features and future plans."
lastUpdated: 2026-07-06T10:40:36.000Z
source_url:
html: "https://www.ververica.com/blog/the-release-of-flink-cdc-2-3"
md: "https://www.ververica.com/blog/the-release-of-flink-cdc-2-3.md"
---
[Flink CDC](https://github.com/ververica/flink-cdc-connectors) is a change data capture (CDC) technology based on database changelogs. It is a data integration framework that supports reading database snapshots and smoothly switching to reading binlogs (binary logs thatcontain a record of all changes to data and structure in the databases). This is useful for capturing and propagating committed changes from a database to downstream consumers and helps keep multiple datastores in sync and avoiding dual writes. With powerful Flink pipelines and its rich upstream and downstream ecosystems, [Flink CDC](https://ververica.com/blog/a-deep-dive-on-change-data-capture-with-flink-sql-during-flink-forward) can efficiently realize the real-time integration of massive data.
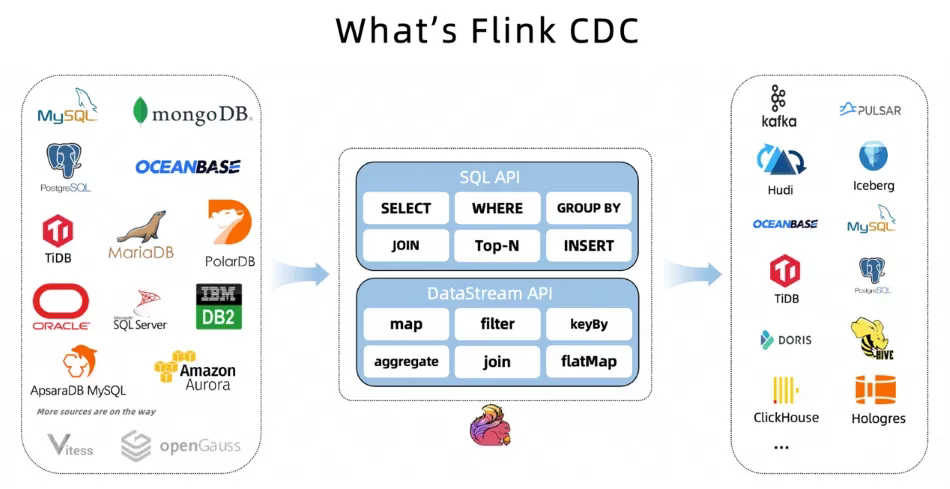
As a next generation real-time data integration framework, Flink CDC has technical advantages such as lock-free reading, parallel reading, table schema auto synchronization, and distributed architecture. It also has its own standalone documentation [which you can find here](https://github.com/apache/flink-cdc). The Flink CDC community has grown rapidly since Flink CDC became open source more than 2 years ago and currently has 76 contributors, 7 maintainers, and more than 7800 users in the DingTalk user group.
With joint efforts from the community, [Flink CDC 2.3.0 was officially released](https://github.com/ververica/flink-cdc-connectors/releases/tag/release-2.3.0).
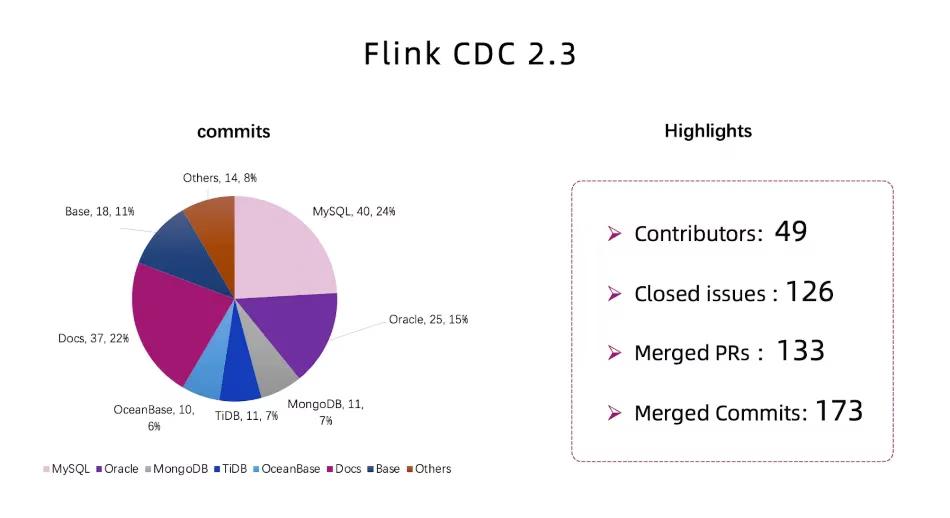
From the perspective of code distribution, we could see both new features and improvements in MySQL CDC, MongoDB CDC, Oracle CDC, incremental snapshot framework (flink-cdc-base), and the document module.
With so many improvements and features, this blog post will go over the major improvements and core features in this release and what the future holds.
## Key Features and Improvements
For the purpose of this post, we will explore the four most important features of this release.
### Introduction of the DB2 CDC Connector
[DB2](https://www.ibm.com/products/db2) is a relational database management system developed by IBM. The DB2 CDC connector can capture row-level changes of tables in the DB2 database. DB2 enables SQL Replication based on the ASN Capture/Apply agents, which generates a change-data table for tables in capture mode, and stores change events in the change-data table. The DB2 CDC connector first reads the historical data in the table through JDBC, then reads the incremental change data from the change-data table.
### Incremental Snapshot Algorithm Support from MongoDB CDC and Oracle CDC Connectors
In Flink CDC version 2.3, the MongoDB CDC connector and Oracle CDC connector are docked into the Flink CDC incremental snapshot framework and implement the incremental snapshot algorithm. This means that now they support lock-free reading, parallel reading, and checkpointing. Now, we have more Flink CDC sources supporting incremental snapshot algorithms. The community is also planning to migrate more connectors to the incremental snapshot framework in the future.
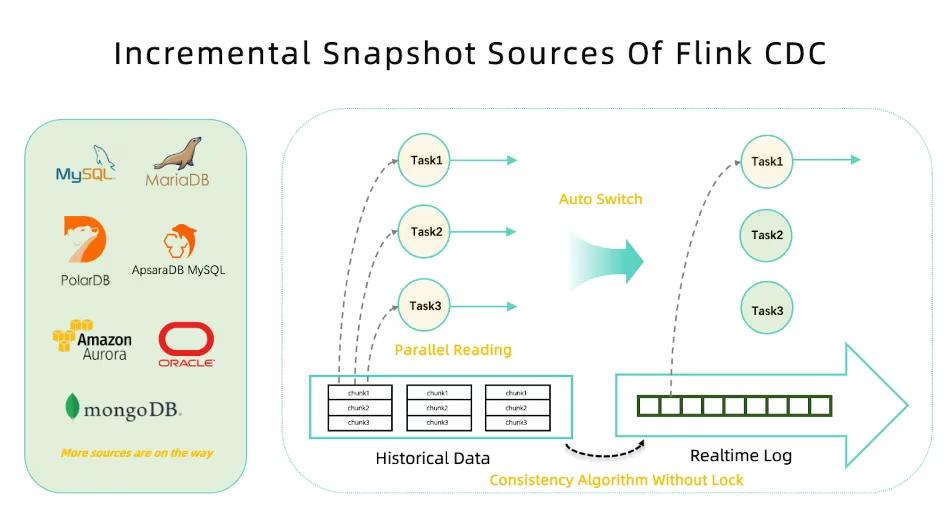
### Stability Improvements to the MySQL CDC Connector
As the most popular connector in the Flink CDC project, the MySQL CDC connector introduces many advanced features in version 2.3, and has many improvements on performance and stability.
- Support starting from specific offset
This connector now supports starting jobs from the specified position of the binlog. You can specify the starting binlog position by timestamp, binlog offset, or binlog gtid. You can also set it to start from the earliest binlog offset.
- Optimization of chunk splitting algorithm
You can now optimize the chunk splitting algorithm in the snapshot phase. The current synchronous algorithm is changed to asynchronous, and you can choose a column in the primary keys as the split column of the chunk splitting algorithm. The splitting process supports checkpointing, which resolves the performance problem caused by synchronous chunk splitting blocking in the snapshot phase.
- Stability improvements
The connector now supports mapping all character sets to Flink SQL, which unlocks more user scenarios. It can handle default values in different types to improve job tolerance on the irregular DDL, and automatically obtains the time zone of the database server to solve time zone problems.
- Performance improvements
This version focuses on optimizing memory and read performance, reducing memory usage of the JobManager and the TaskManager through improvements on meta multiplexing in the JobManager and streaming reading in the TaskManager. At the same time, binlog reading performance is improved by optimizing binlog parsing logic.
### Other improvements
- Flink CDC version 2.3 is compatible with the four major versions of Flink (1.13, 1.14, 1.15, 1.16). This greatly reduces upgrade and maintenance costs for users.
- OceanBase CDC connector fixes the time zone problem, maps all data types to Flink SQL, and provides more options for a more flexible configuration, such as the newly added "table-list" configuration for reading multiple OceanBase tables.
- MongoDB CDC connector supports more data types and optimizes the filtering process of capture tables.
- TiDB CDC connector fixes the data loss problem with switching after the snapshot phase and supports region switching during reading.
- Postgres CDC connector supports geometry type, more options are added, and changelog mode can be configured to filter data.
- SQL Server CDC connector supports more SQL Server versions and refines the document.
- MySQL CDC and OceanBase CDC connectors include documentation in Chinese as well as video tutorials for OceanBase CDC connectors.
## Future Plans
The development of Flink CDC could not be achieved without contributions and feedback from the community and the open source spirit of maintainers. Currently, the Flink CDC community is already making [plans for version 2.4](https://github.com/ververica/flink-cdc-connectors/issues/1728). All users and contributors are welcome to participate and provide feedback. The main direction of the project will be from the following aspects:
- Perfect data source - We plan to support more data sources and migrate more connectors to the incremental snapshot framework to unlock lock-free reading and parallel reading.
- Observability improvements - We want to provide a reading rate limiting function to reduce the query pressure on the database during the snapshot phase. The new version will provide more abundant monitoring indicators to let users obtain indicators related to task progress and monitor task status.
- Performance improvements - The snapshot phase supports the use of batch mode in the new version, which will improve performance in the snapshot phase and release idle readers’ resources automatically after the snapshot phase.
- Usability improvements - Improve the ease of use of connectors, such as simplifying out-of-the-box options and providing examples in DataStream API.
Ververica Platform is scheduled to support Flink CDC in version 2.11.
### Acknowledgements:
Thanks to all 49 community contributors who contributed to version 2.3 of Flink CDC, especially the four maintainers of the community (Ruan Hang, Sun Jiabao, Gong Zhongqiang, Ren Qingsheng) who have done outstanding work for this release.
### List of contributors:
01410172, Amber Moe, Dezhi Cai, Enoch, Hang Ruan, He Wang, Jiajia, Jiabao Sun, Junwang Zhao, Kyle Dong, Leonard Xu, Matrix42, Paul Lin, Qingsheng Ren, Qishang Zhong, Rinka, Sergey Nuyanzin, Tigran Manasyan, camelus, dujie, ehui, embcl, fbad, gongzhongqiang, hehuiyuan, hele.kc, hsldymq, jiabao.sun, legendtkl, leixin, leozlliang, lidoudou1993, lincoln lee, lxxawfl, lzshlzsh, molsion, molsionmo, pacino, rookiegao, skylines, sunny, vanliu, wangminchao, wangxiaojing, xieyi888, yurunchuan, zhmin, Ayang, Mo Xianbin
---
---
title: "Flink SQL Recipe: Window Top-N and Continuous Top-N"
description: "Discover how to leverage Flink SQL for Window Top-N and Continuous Top-N queries, enabling real-time data analysis and insights in diverse applications."
lastUpdated: 2026-07-06T10:08:10.000Z
source_url:
html: "https://www.ververica.com/blog/flink-sql-recipe-window-top-n-and-continuous-top-n"
md: "https://www.ververica.com/blog/flink-sql-recipe-window-top-n-and-continuous-top-n.md"
---
[Flink SQL](https://ververica.com/apache-flink-sql-on-ververica-platform#bgimage3) has emerged as the standard for [**low-code streaming analytics**](https://ververica.com/ververica-platform-enterprise-stream-processing-and-streaming-analytics) and managed to unify batch and stream processing while simultaneously staying true to the SQL standard. In addition, it provides a rich set of advanced features for real-time data analysis. In a nutshell, Flink SQL is the best of both worlds: it gives you the ability to **process streaming data using SQL, but it also supports batch processing.**
[Ververica Platform](https://ververica.com/platform) makes Flink SQL even more accessible and efficiently scalable across teams. The platform comes with additional tools for developing SQL scripts, managing user-defined functions (UDFs), catalogs and connectors, as well as operating resulting long-running queries.
We have seen many [use cases for Flink SQL](https://ververica.com/use-cases), and we are excited to show you what you can build with it. In this series of blog posts, we will explore how to use Flink SQL to process data in a variety of ways. This post, in particular, will focus on two queries: Window Top-N and Continuous Top-N.
## What are Window Top-N and Continuous Top-N queries?
Window Top-N and Continuous Top-N are two similar but slightly different ways of processing data. In both cases, we want to find the top N items in a stream of data but there are some key differences:
- In Window Top-N, we process data in fixed-size windows. For example, we might want to find the top 10 items every minute.
- In Continuous Top-N, we process data continuously. We don't use windows, but instead process data as it arrives.
Continuous Top-N is more difficult to implement than Window Top-N, but it has some advantages. For example, it can give us results more quickly, since we don't have to wait for a window to close before we can see the results.
## Common use cases for Window Top-N and Continuous Top-N queries
Window Top-N and Continuous Top-N queries are both useful for a variety of tasks. For example, they can be used for:
- [**Fraud detection**](https://ververica.com/download-one-mount-group-success-story)[:](https://ververica.com/download-one-mount-group-success-story) In a stream of financial transactions, we might want to find the top 10 transactions by amount every minute. _What can it help us with? - identify suspicious activity._
- **Recommendations**: In a stream of user interactions, we might want to find the top 10 items that are being viewed or purchased. _What can it help us with? - make recommendations to users._
- **Anomaly detection**: In a stream of sensor readings, we might want to find the top 10 sensors with the highest readings. _What can it help us with? - identify sensors that are malfunctioning_
- [**Monitoring**](https://ververica.com/blog/monitoring-large-scale-apache-flink-applications-part-1-concepts-continuous-monitoring): In a stream of log messages, we might want to find the top 10 log messages by volume. _What can it help us with? - identify system issues_.
## How to use Flink SQL to write Window Top-N queries
Let's start by looking at how to use Flink SQL to write Window Top-N queries. We'll show you how to calculate the Top 3 suppliers who have the highest sales for every tumbling 5 minutes window.
```sql
CREATE TABLE orders (
bidtime TIMESTAMP(3),
price DOUBLE,
item STRING,
supplier STRING,
WATERMARK FOR bidtime AS bidtime - INTERVAL '5' SECONDS
) WITH (
'connector' = 'faker',
'fields.bidtime.expression' = '#{date.past ''30'',''SECONDS''}',
'fields.price.expression' = '#{Number.randomDouble ''2'',''1'',''150''}',
'fields.item.expression' = '#{Commerce.productName}',
'fields.supplier.expression' = '#{regexify ''(Alice|Bob|Carol|Alex|Joe|James|Jane|Jack)''}',
'rows-per-second' = '100'
);
SELECT *
FROM (
SELECT *, ROW_NUMBER() OVER (PARTITION BY window_start, window_end ORDER BY price DESC) as rownum
FROM (
SELECT window_start, window_end, supplier, SUM(price) as price, COUNT(*) as cnt
FROM TABLE(
TUMBLE(TABLE orders, DESCRIPTOR(bidtime), INTERVAL '5' MINUTES))
GROUP BY window_start, window_end, supplier
)
) WHERE rownum <= 3;
```
The source table (`orders`) is backed by the [faker connector](https://flink-packages.org/packages/flink-faker), which continuously generates rows in memory based on Java Faker expressions.
> **NOTE:** This example leverages the Window Top-N feature to display the top 3 suppliers with the highest sales every 5 minutes.
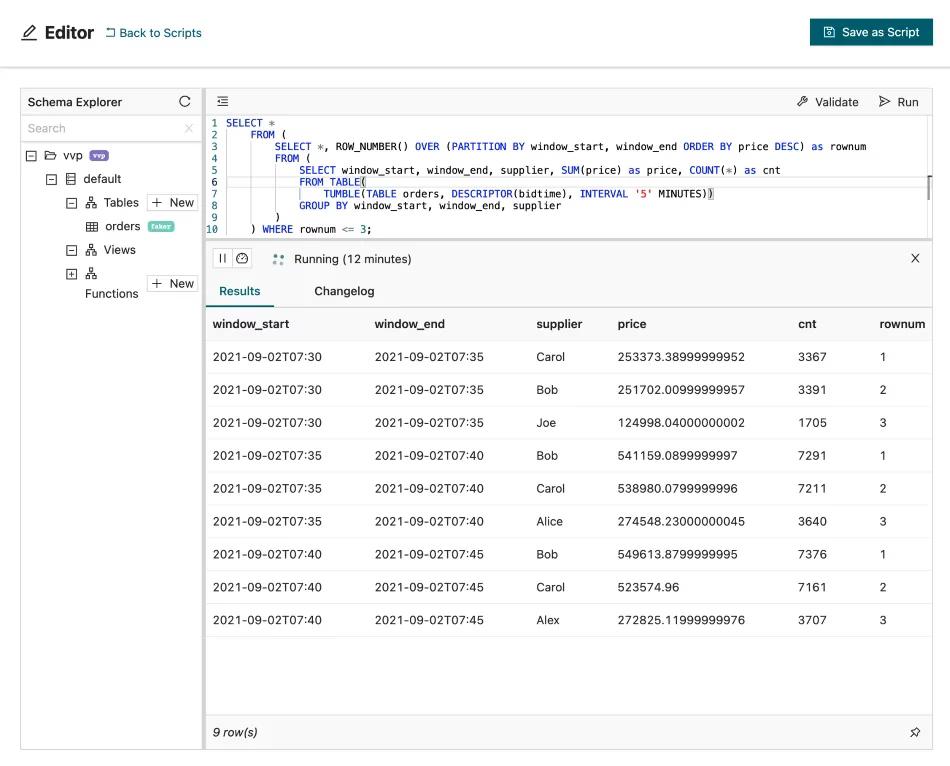
## How to use Flink SQL to write Continuous Top-N queries
Writing Continuous Top-N queries is more difficult than writing Window Top-N queries. The reason for this is that, in Continuous Top-N, we process data as it arrives instead of using windows.
.This example will take us into the realm of magic as stream processing is often considered to be by the uninitiated. However, it is really just a set of instructions to be executed on a stream of data. We will show how to continuously calculate the "Top-N" rows based on a given attribute, using an `OVER` window and the `ROW_NUMBER()` function.
The source table (`spells_cast`) is backed by the [faker connector](https://flink-packages.org/packages/flink-faker), which continuously generates rows in memory based on Java Faker expressions.
The Ministry of Magic tracks every spell a wizard casts throughout Great Britain and wants to know every wizard's Top 2 all-time favorite spells.
Flink SQL can be used to calculate continuous [aggregations](https://github.com/ververica/flink-sql-cookbook/blob/main/foundations/05_group_by/05_group_by.md), so if we know each spell a wizard has cast, we can maintain a continuous total of how many times they have cast that spell.
```sql
SELECT wizard, spell, COUNT(*) AS times_cast
FROM spells_cast
GROUP BY wizard, spell;
```
This result can be used in an `OVER` window to calculate a [Top-N](https://docs.ververica.com/user_guide/sql_development/queries.html#top-n). The rows are partitioned using the wizard column, and are then ordered based on the count of spell casts (`times_cast DESC`). The built-in function ROW_NUMBER() assigns a unique, sequential number to each row, starting from one, according to the rows' ordering within the partition. Finally, the results are filtered for only those rows with a row_num <= 2 to find each wizard's top 2 favorite spells.
Where Flink is most potent in this query is its ability to issue retractions. As wizards cast more spells, their top 2 will change. When this occurs, Flink will issue a retraction, modifying its output, so the result is always correct and up to date.
```sql
CREATE TABLE spells_cast (
wizard STRING,
spell STRING
) WITH (
'connector' = 'faker',
'fields.wizard.expression' = '#{harry_potter.characters}',
'fields.spell.expression' = '#{harry_potter.spells}'
);
SELECT wizard, spell, times_cast
FROM (
SELECT *,
ROW_NUMBER() OVER (PARTITION BY wizard ORDER BY times_cast DESC) AS row_num
FROM (SELECT wizard, spell, COUNT(*) AS times_cast FROM spells_cast GROUP BY wizard, spell)
)
WHERE row_num <= 2;
```
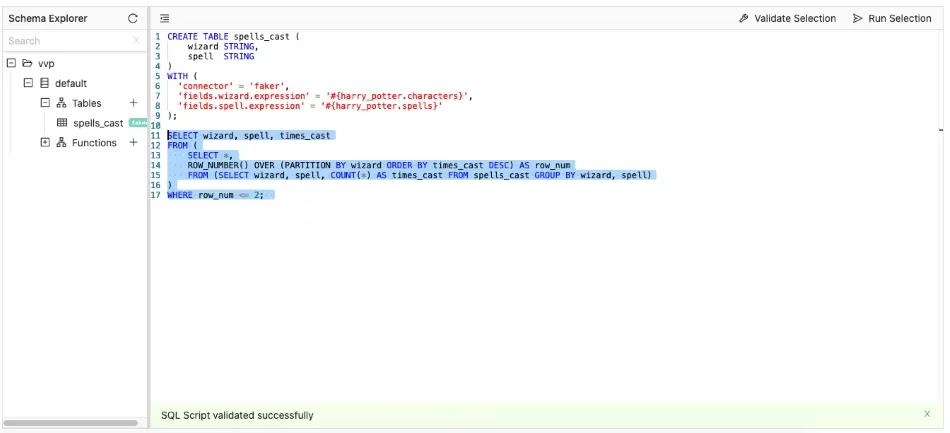
## Conclusion
In this article, you've learned about Window Top-N and Continuous Top-N. You've also seen how to use Flink SQL to write queries for both of these types of problems.
If you're interested in learning more about Flink SQL, we recommend the following resources:
- [Flink SQL Cookbook](https://github.com/ververica/flink-sql-cookbook)
- [Getting Started - Flink SQL on Ververica Platform](https://docs.ververica.com/getting_started/sql_development.html)
- [The official Flink SQL documentation](https://nightlies.apache.org/flink/flink-docs-master/docs/dev/table/sql/overview/)
- [Flink Forward Talk: One SQL, Unified Analytics](https://youtu.be/rOzA4CIeXOw?t=924)
- [Only SQL: Empower data analysts end-to-end with Flink SQL](https://youtu.be/KvaDe7QCwBQ)
---
---
title: "Apache Flink® SQL: Past, Present, and Future"
description: "Explore the evolution of Apache Flink SQL, from its early days to its current capabilities, and discover its impact on data analytics and stream-batch unification."
lastUpdated: 2026-07-06T09:45:06.000Z
source_url:
html: "https://www.ververica.com/blog/apache-flink-sql-past-present-and-future"
md: "https://www.ververica.com/blog/apache-flink-sql-past-present-and-future.md"
---
Recently the [Apache Flink](https://ververica.com/what-is-apache-flink) community announced the [release of Flink 1.16](https://flink.apache.org/news/2022/10/28/1.16-announcement.html), which continues to push the vision of stream and batch unification in [Flink SQL](https://ververica.com/apache-flink-sql-on-ververica-platform#bgimage3) to a new level. At this point, Flink SQL is one of the most sophisticated and powerful tools available for data analytics. It is ANSI SQL compliant, stream and batch unified, and supports hundreds of thousands of mission-critical stream and batch applications in [renowned companies across different industries globally](https://ververica.com/use-cases). Alibaba, for example, has over 30,000 Flink jobs running on 2 million+ CPU cores across the organization.
Flink SQL has come a long way to where it is today via tremendous efforts and collaborations across the entire Flink community over the years. Thus, it would be valuable to have a retrospective of the journey of Flink SQL. This post will try to summarize the important milestones of Flink SQL in the past years, show the critical issues and challenges that have arisen, understand where it is today, and demonstrate the path Flink SQL has been through and where it might head in the future, based on personal observation and opinions.
> **WARNING:** Disclaimer: this blog post is not meant to be an official chronology of Flink SQL nor is it an official roadmap of Flink SQL.
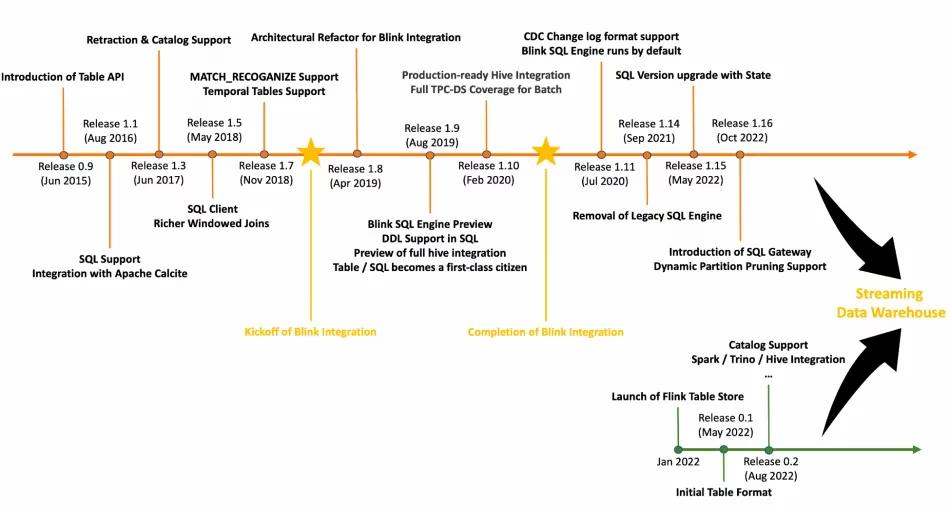
The diagram above shows selected milestones of Apache Flink and Flink Table Store. Among many memorable things in the history of Flink SQL, the merge of Blink (the Alibaba internal fork of Apache Flink which was later contributed back to Apache Flink in 2019), is probably the most important one that has profoundly impacted the development of Flink SQL. But let’s first go back a bit further and take a look at Flink SQL in the early days prior to the merge of Blink.
## Flink SQL in its early days
The idea to have another more expressive API in Flink in addition to the DataStream API and the DataSet API (now sunsetted) dates back to mid 2014. The idea finally landed about one year later in Flink 0.9 in which the Table API was first introduced. The [Table API](https://ververica.com/blog/introducing-ververica-platform-2.2-with-autoscaling-for-apache-flink#table_API) is a declarative API built on top of the DataStream API and the DataSet API for streaming and batch processing and allows users to write streaming programs in a SQL-like manner. Over the next several releases, more functionalities were added to build this declarative and relational API for stream processing.
Out of numerous features built and decisions made as a part of this effort, I’d like to highlight a few that have not only become the architectural cornerstones of Flink SQL today but have also inspired how streaming SQL should be done.
### Introducing SQL as a DSL on top of the Table API
It was not long after the Table API was introduced that the community realized building an actual SQL API on top of it looks like a reasonable step from a technical perspective. While it looks quite natural today to [use SQL for stream processing](https://ververica.com/what-is-stream-processing), it was not as obvious how far this idea can go at that time. Although the idea of having a fluent SQL-like API has been put in practice by a few projects by then, having a serious full function SQL for stream processing still sounded ambitious and faced a lot of challenges. In fact, the Flink Table API itself was considered as a proof-of-concept for quite a while and only supported stateless operations. Nevertheless, in Flink release 1.1, preliminary SQL support on top of the Table API was announced and the ball started rolling.
### Introducing Apache Calcite for Query Optimization
In Flink release 1.1, along with the release of the Flink SQL, Apache Calcite was introduced to perform relational plan optimization for Flink SQL queries. Thanks to the excellent pluggability of Calcite, Flink was able to integrate it into Flink SQL with a reasonable amount of effort, which significantly accelerated the development of Flink SQL.
### Retraction capabilities
This is probably one of the most important differentiators of Flink SQL compared with other solutions. Two fundamental characteristics of streaming data are _unboundedness_ and _out-of-order-ness_. These two characteristics demand stream computing to be able to modify (or “retract”) the results it has already produced upon the arrival of a new record in order to make sure the results are correct. Even though Flink uses watermarks to help reduce the chance of such modifications, it is still a must for stream processing. This demand is unique to stream processing since, in batch processing, the emitted results are always final.
Typically, such data retractions are computing logic specific and need to be done by the application authors. However, while it is easy to provide APIs in programming interfaces like the DataStream API and let users do retraction by themselves, when it comes to SQL, the computing engine itself has to take care of all the retractions for the users, because SQL does not have “retraction” in its standard semantic. This is non-trivial work considering most of the stateful operations will need to have retraction implemented, including ranking, joining, aggregation, etc. It took Apache Flink a couple of years before retraction was production ready. The integration of Blink further extended retraction to support CDC formats. As a result, Flink can execute the vast majority of SQL queries and produce correct results (e.g., arbitrary combination of aggregations and joins). To some extent, retraction is one of the features that distinguishes Flink SQL from others in this realm.
## The Blink project and its contributions back to [Apache Flink](https://ververica.com/what-is-apache-flink)
Despite all the cool stuff available in its early days, Flink SQL has always been an exploratory or experimental effort. It was not even shipped as a part of the Flink distribution. When Blink came into the picture, things changed.
Blink was created as an internal fork of Flink at Alibaba in 2015. The project grew rapidly inside the company and quickly became the backbone streaming engine of the entire company, processing billions of records per second, generating some mission critical financial dashboard and reports.
In late 2018, Alibaba made the decision to open source Blink and contribute it back to Apache Flink. The plan of merging Blink back to Apache Flink was announced in the beginning of 2019 and the work lasted for about one and a half years. The critical features in Blink were put into mailing list discussions and merged one by one back into Apache Flink. As a rough estimation, about 1 million lines of code changes were committed and the majority of them are SQL related.
The release of Flink 1.10 in early 2020 marks the completion of the Blink merge.
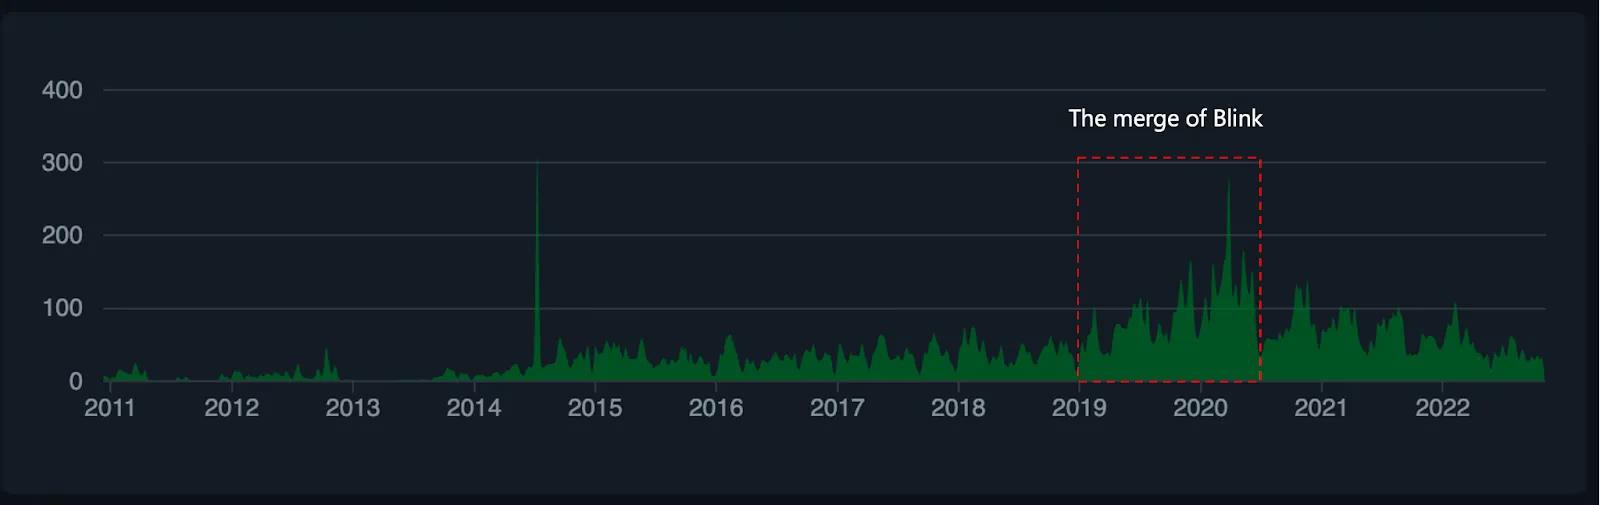
The Blink project has a profound impact on Flink SQL in many ways. It not only boosted the development of Flink SQL, made it 10x faster than it used to be, but also helped shape the Flink SQL to become the way it is today.
First of all, Blink was designed and developed based on SQL-first principles. A lot of its features address the immediate requirements of streaming SQL and make it production-ready. These include the entire execution planner, operator performance and stability improvements, various retraction support, solutions to data skew, complete support of ANSI SQL standard semantics on top of streaming data, etc.
Secondly, Blink pushed the exploration of stream and batch unification to a new level. By the time Blink was open sourced, it already had a full TPC-DS coverage. Furthermore, all the streaming and batch SQL execution are performed in streaming operators instead of split into DataSet and DataStream operators. This architectural change has also led to what Flink SQL is today, as well as the deprecation of the DataSet API.
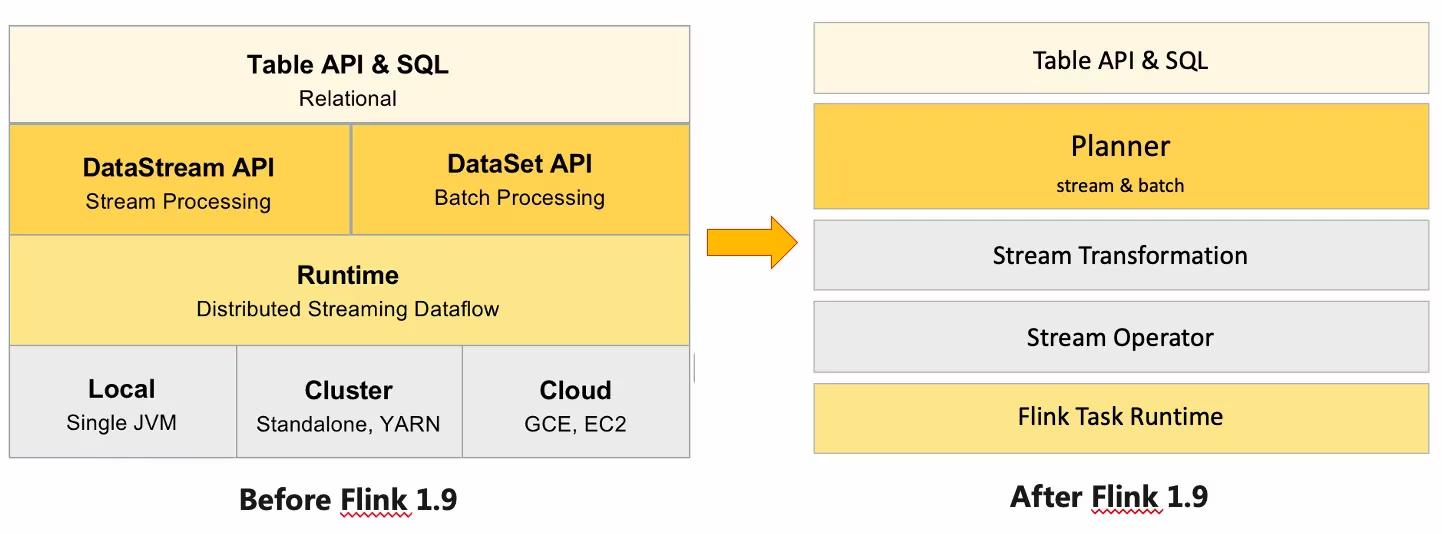
Another contribution of Blink that should not be underestimated is in the change in mindset. Being the first battle-tested large-scale streaming SQL practice in the industry, Blink proved that streaming SQL is not just an experiment for simple processing use cases, but that it can also perform sophisticated computations.
## Flink SQL Today
Flink SQL has continued to develop since the merge of Blink. Many useful features are now available in Flink SQL which helps it to cover a wide range of use cases. To name some:
- [**Analytics**](https://ververica.com/apache-flink-sql-on-ververica-platform)**.** Analytics is still the most prominent use case for Flink SQL. The project has built a complete infrastructure to run both streaming and batch queries with the same query statement. In addition, Flink SQL has been improving compatibility with Apache Hive. According to the recent release of Flink 1.16, [~94% Hive SQL statements](https://flink.apache.org/news/2022/10/28/1.16-announcement.html#hive-compatibility) can also run smoothly on Flink. In addition, the newly added SQL Gateway now also supports HiveServer2 protocols. That means the Hive ecosystem tools (such as Hive Beeline, Apache Zeppelin, and Apache Superset) can connect to Flink SQL Gateway and submit Hive SQL seamlessly.
- **Data Integration.** With the full Change Log Format support, as well as ecosystem projects such as [CDC Connectors for Apache Flink](https://github.com/ververica/flink-cdc-connectors) (a popular project with 3200+ stars now), Flink is rising as one of the most popular engines used for data integration. Users are leveraging its rich catalog and connector ecosystem to move around and transform data stored in dozens of different types of external storage systems.
- [**Pattern Matching**](https://ververica.com/blog/match_recognize-where-flink-sql-and-complex-event-processing-meet)**.** Flink SQL supports the MATCH_RECOGNIZE statement, which allows users to perform pattern matching on streaming data. This is especially useful for cases like risk control.
- [**Machine Learning**](https://ververica.com/download-humanai-success-story)**.** Nowadays, machine learning is becoming more and more real-time. Flink SQL has been used by many users to perform real-time feature generation and sample assembly when prompt result is critical to the machine learning system, for instance, real-time recommendation systems.
It would be difficult to give an exhaustive summary of the current status of Flink SQL with just this post, but I think the following topics would be worth diving into: Flink SQL adoption, stream & batch unification, and the remaining challenges.
### Flink SQL Adoption
One interesting thing I noticed is that while Flink has established itself as one of the top streaming engines in the industry and widely used globally, the Flink SQL adoption varies a lot in different regions. In China, Flink SQL is quite popular. It is very common to see Flink SQL account for 80% or higher of the streaming jobs in a company. On the other hand, in the rest of the regions such as the U.S. and Europe, DataStream API is still dominant for streaming jobs.
Regardless of the reason behind this difference, from the past experience with Flink SQL, using SQL for streaming application has demonstrated a few important benefits:
- **Easy to use**. SQL is the de facto language for analytics. It has clear semantics and is expressive. It does not require much programming skills. This significantly helped democratize stream processing because those who know how to query relational databases can easily analyze data streams without much additional effort.
- **More efficient in development.** Even for those who have the expertise of writing Java programs, switching to Flink SQL still helps improve productivity in most cases. This is because when writing Flink SQL, one can focus on the business logic instead of worrying about a lot of implementation details, especially when all the logic can be fulfilled by built-in functions and operations.
- **Maintenance and migration friendly.** SQL is a standard declarative DSL. This allows the computing engine to continuously evolve transparently to the end users. For example, when the computing engine changes to provide better query plans, faster operators, more performant query executions, the existing Flink SQL jobs can immediately benefit from such improvement by restarting the job with a new Flink version, without making any changes.
### Stream and Batch Unification
When we talk about stream and batch unification, there are usually three related things that need to be unified: API, computing engine, and storage. Unifying stream and batch processing helps to significantly reduce the complexity of the data systems, improve data quality, and contribute to lower total costs. Flink SQL addresses these problems by providing a unified SQL layer on top of [Apache Flink](https://ververica.com/what-is-apache-flink).
The basic idea is that batch is just a special case for streaming. This is not a new idea and is also quite an intuitive one - the results of batch processing are equivalent to the results of stream processing on the bounded streams containing the same records in those batches of data.
While conceptually speaking this is correct, it is not as simple as it looks like in practice. The equation may no longer stand if we take things like resource management, scheduling, and execution efficiency into consideration. For example, a batch processing job can run on any amount of physical resources because the whole job is divided into stages and tasks can run on the same physical resource one after another in a time-shared manner. In contrast, a streaming job typically needs to bring up all the tasks at the same time to run properly. There is a long list of differences between the best way to process stream and batch data. The operator behavior might be different depending on the boundedness of the data, the failure recovery strategy and shuffle strategy may be different, some operators may be prohibitively expensive for unbounded data, and so on.
Flink SQL as well as the Flink runtime has come a long way to address most of the above issues so it can run both streaming and batch jobs in the appropriate way.
### The remaining challenges
Even though Flink SQL has become one of the most sophisticated tools for [data analytics](https://ververica.com/blog/real-time-performance-monitoring-with-flink-sql-ad-tech-use-case), there are still a few remaining challenges yet to be tackled.
- **The accuracy of stream SQL**. Despite the long term efforts such as retraction support, there are still a few corner cases in which achieving strict accuracy is challenging. For example, when a dynamically changing dimensional table is involved, in case of failure recovery, inaccurate results may be emitted and not retractable. Another example is chained streaming SQL jobs: if the intermediate storage is unable to generate full change logs, the accuracy of downstream SQL jobs may not be guaranteed.
- **The cost of stream-to-stream joins.** At this moment, joining streams together is still quite expensive, especially when multiple streams are joined together. Addressing this case would be valuable since joining streams together is a very common usage pattern.
- **The complexity of streaming SQL semantics.** One thing that we commonly heard from Flink SQL users is that it is sometimes difficult to understand the output of a Flink SQL job. Although streaming SQL semantics is complex by nature, Flink SQL could probably improve in making the semantics clearer and more intuitive.
## What’s next in Flink SQL
Putting together all the work that the Flink community has done in Flink SQL, I think we can anticipate the following for Flink SQL.
**Further enhancements to stream and batch unification**
On the computing engine side, people have recognized that stream and batch unification is technically sound, valuable, and also achievable. Flink SQL is currently at the forefront of this endeavor and will continue to push the boundary of stream and batch unification, including addressing the remaining challenges in streaming SQL and further improving its batch capability.
**From Flink SQL to Streaming Data Warehouse**
The primary use case for Flink SQL is undoubtedly analytics on both streaming and batch data. However, even though Flink SQL has significantly lowered the bar of analyzing streaming data, it is still not so easy for people to work with streaming data compared with what they can do with batch data.
Although Data Warehouse is a popular and well-established architecture designed for analytics purposes, it could become a little clumsy today if one wants to handle streaming data. A typical setup can be illustrated below.
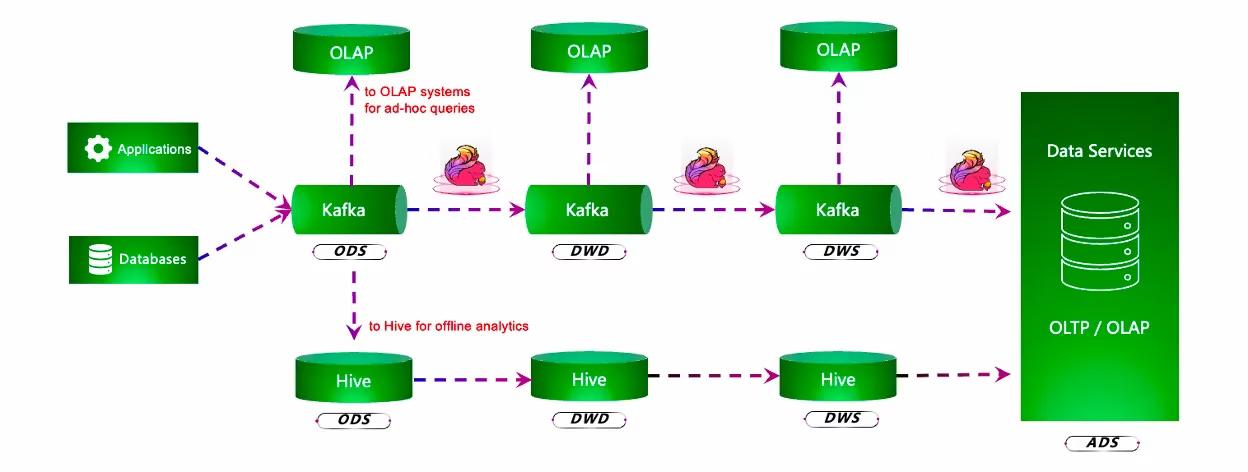
In the diagram above, the original data comes from two sources: the application logs (e.g. user behavior tracking logs) and the transactional databases. The data is streamed into the system from these two sources. There are several streaming jobs chained with a message queue like Apache Kafka sitting in between as the storage for streaming data. The pipeline composed of Flink and Kafka in this case can deliver low latency streaming analytics capability.
In addition to the streaming pipeline, a common use case is to archive the data in Kafka to an offline system which provides better efficiency for better computing. In this case, a common solution is to send a copy of the data from Kafka to Hive and have a separate batch computing pipeline, just like a typical data warehouse.
Users may also want to query the data in Kafka in an ad-hoc manner for purposes like data exploration or debugging. Unfortunately Kafka is not queryable by itself, so users would usually send another copy of data from Kafka to a system that one can directly query, such as ClickHouse or MySQL.
While this architecture seems intuitive and handles both streaming and batch data, it has a few caveats.
- There are multiple storage systems likely with different data guarantees and the data consistency and data quality could be challenging.
- There are multiple computing engines with different APIs, dialects, and semantics. This may result in higher cost in code development and maintenance, as well as more discrepancies in the logic.
- Due to the complexity of the architecture, the operational cost could also be high, and it might be hard to ensure system stability.
At the beginning of this year, a new subproject of Apache Flink called _Flink Table Store_ was launched. The goal of this project is to provide a stream and batch unified storage. It aims to serve all the analytical use cases well, including stream computing, batch computing, and ad-hoc queries. In order to achieve this, Flink Table Store needs to accept and generate full change logs from end to end, which is critical for stream processing to produce reliably correct results.
Combining Flink SQL and Flink Table Store, we can come up with an elegant architecture to unify stream and batch analytics.
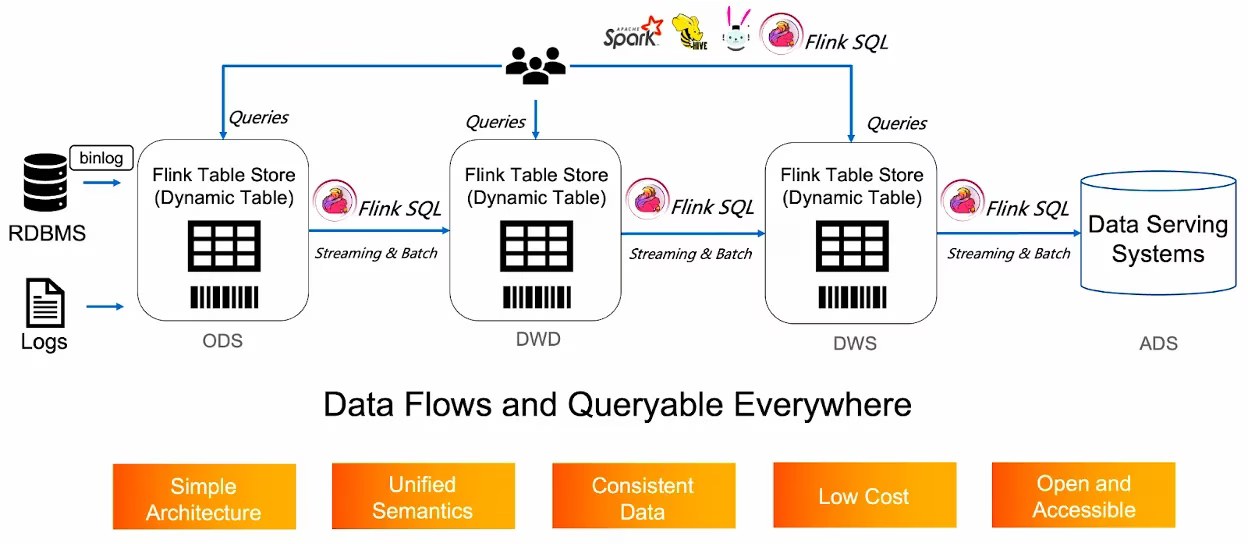
We call this architecture **Streaming Data Warehouse**. The idea behind this is treating every dataset as a _Dynamic Table_ backed by Flink Table Store. Each dynamic table can be read in three different ways:
- a message queue which emits full change logs
- a scannable with proper indexes for range scan, based on file systems or objects stores, for example.
- a K-V store for lookup based on keys
The interaction between Flink SQL and the dynamic tables are through different SQL statements:
- DDL which helps define the dynamic tables and how Flink SQL should perform IO on it.
- DML which manipulates the dynamic tables, such as altering schema, updating partial data, etc.
- DQL which performs the queries on the dynamic tables.
Streaming Data Warehouse helps address the shortcomings for the existing architecture. It is an architecture with complete stream and batch unification, equipped with a unified API, a unified computing engine, and a unified storage.
Although born from Flink SQL, Flink Table Store can also be used in other computing engines, such as Apache Spark or Trino, for read/write.
## Summary
Flink SQL has been through a long [journey](https://ververica.com/blog/a-journey-to-beating-flinks-sql-performance). This blog post only captures a glimpse of the work that has been done, the brilliant ideas thought of, the lessons learned, and [milestones](https://ververica.com/blog/apache-flinks-stream-batch-unification-powers-alibabas-11.11-in-2020) achieved.
Stay tuned for more deep dives into Flink SQL. We plan to explore the experiences and best practices from Flink veterans who not only contributed to Flink SQL features, but are also dealing with production Flink jobs from a wide range of companies on a daily basis.
## Acknowledgements
This blog post is impossible without the outstanding engineers who have made Flink SQL the way it is today. I’d like to thank the Flink Community and the Alibaba Blink team who have been relentlessly pushing Flink SQL forward.
---
---
title: "Monitoring Large-Scale Apache Flink Applications, Part 2"
description: "Explore advanced troubleshooting techniques for Apache Flink applications, focusing on JVM metrics, RocksDB insights, and Grafana dashboard setup for effective monitoring."
lastUpdated: 2026-07-06T07:49:46.000Z
source_url:
html: "https://www.ververica.com/blog/monitoring-large-scale-apache-flink-applications-part-2-metrics-for-troubleshooting"
md: "https://www.ververica.com/blog/monitoring-large-scale-apache-flink-applications-part-2-metrics-for-troubleshooting.md"
---
The [previous article in this series](https://ververica.com/blog/monitoring-large-scale-apache-flink-applications-part-1-concepts-continuous-monitoring) focused on continuous application monitoring and presented the most useful metrics from our point of view. However, Flink’s metrics system offers a lot more, and we would like to highlight a couple of useful metrics that help you specifically while troubleshooting applications. All of the metrics presented in the previous article are useful entry points for troubleshooting and point you in the right direction. The metrics we would like to focus on here extend on these and provide more insights so that you can identify resource bottlenecks and sources of errors.
[At the end of this blog post](https://ververica.com/blog/monitoring-large-scale-apache-flink-applications-part-2-metrics-for-troubleshooting?hs_preview=vIrKMpYq-74371465602#grafana), we will also share some details about the Grafana dashboard we are using and will share it with you so you can get started with your own application monitoring.
## JVM metrics (2): Troubleshooting
Let’s have a second look at JVM-level metrics. Before we continue, though, we first have to distinguish between the two types of processes a Flink application is running on: the JobManager (JM) and the TaskManager (TM).
### JobManager
There is usually not much that can go wrong with the JobManager, except for underprovisioning its resources in one of the following situations. If the number of TaskManagers to maintain is high, the JM needs more memory to maintain internal data structures but, most importantly, needs more CPU to process the various keep-alive messages and checkpoint messages and data which are orchestrated by the checkpoint coordinator sitting at the JobManager. Similarly, if you have many jobs to maintain (in a session cluster) or have high checkpoint frequencies, you may also want to increase the available (peak) CPU time. Speaking of checkpointing, depending on your job’s size and the configuration of `state.storage.fs.memory-threshold`, your JM may need more resources to build and write the inlined checkpoint data into the `_metadata` file. If you deploy in application mode, the JM will also execute user code and may need additional CPU, memory,… for that, depending on your business logic.
For all of these, you can inspect metrics such as system-level metrics, e.g., from Kubernetes, or Flink metrics like `Status.JVM.CPU.*`, `Status.JVM.Memory.*`, or `Status.JVM.GarbageCollector.*` in a dashboard like the following. They will help you identify situations like the ones mentioned above and then tune accordingly.
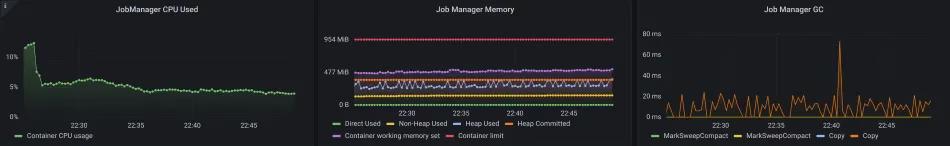
### TaskManager
On the TaskManager, the same system-level metrics can be used to identify problems with the actual data processing, e.g., load imbalances, memory leaks, problematic TMs, etc. While you may be tempted to set up alerts on the TMs’ CPU use, this may be too narrow. Monitoring your application's throughput is a much better indicator of bottlenecks since it includes all resources, e.g., disk, network, etc. While troubleshooting, however, you may want to identify the concrete resource bottleneck where `Status.JVM.CPU.Load` and others are useful again. Also recall that load measurements like this can be misleading since a value of 0.021, for example, may already mean a 100% load for a TM container with 1 CPU on a 48-core machine.
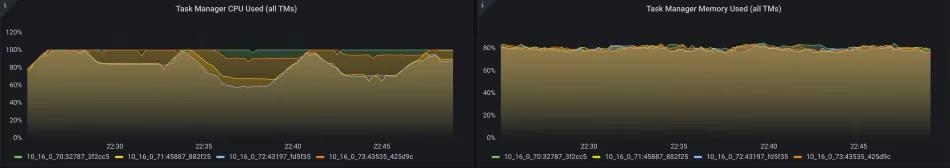
Depending on your state backend, you may need to focus on different metrics.
For Heap-based state backends, for example, the most important part is to monitor each TM’s `Status.JVM.Memory.Heap.Used` which is an indicator of the state size on that TM. It should not exceed the limits you set and you should scale before you hit them (setting up an alert for this may be helpful!). Growing heap/state sizes could either come from legitimate increases of the work your job is doing, e.g., more entities to process which lead to an increasing number of keys, or from Flink buffering more data for you due to an increasing event-time skew between different streams or a failure to clean up state (in your code!). Additional metrics on each of the tasks involved, e.g., `numRecordsIn/Out`will help you estimate the load characteristics of your job.
Since heap memory is involved, garbage collection (GC) may obviously also be problematic. There are a couple of JVM-level statistics to help you track these, e.g., `Status.JVM.GarbageCollector..[Count|Time]` and more details are also available in the JVM’s GC logs which need to be enabled separately. Since this is not too Flink-specific, I will defer to common literature in this regard.
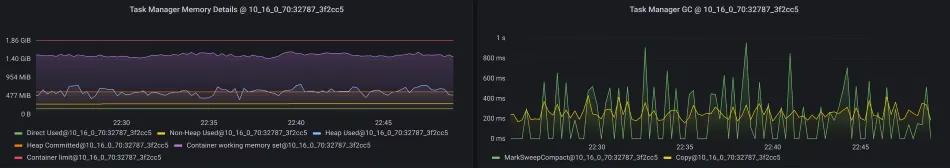
Even though Flink’s RocksDB state backend is operating off-heap, you should still keep an eye out on memory and GC. This is due to the unfortunate fact that even with the RocksDB upgrade of Flink 1.14 (to RocksDB 6.20.3), while doing its best, Flink is not able to fully control how RocksDB is using its memory. There may be situations where RocksDB wants to use more memory than allocated and may fail. In order to get notified early, i.e., before TMs get killed after hitting their assigned memory limit, you should set up alerts on the memory used vs. available and best use system-level metrics such as `container_memory_working_set_bytes` and `container_spec_memory_limit_bytes` from Kubernetes which include all types of memory your job acquires, including those that the JVM cannot track. If you see your job approaching the limit, for RocksDB, you can adjust the framework/task off-heap memory or the JVM overhead portion of the [TaskManager memory layout](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/deployment/memory/mem_setup_tm/).
Even without a heap-based state backend, you should keep an eye on garbage collection since high garbage collection pressure will lead to other problems! With RocksDB, this should only originate from Flink itself or your user code.
## RocksDB
RocksDB collects a vast number of low-level metrics that you can look at and make sense of after reading through its internals and studying its [tuning guide](https://github.com/facebook/rocksdb/wiki/RocksDB-Tuning-Guide). We'll try to give you the TL;DR version for a couple of key metrics. You can find the full set of RocksDB native metrics in the [Flink docs](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/deployment/config/#rocksdb-native-metrics) which explain how to enable them and indicate metrics that may have a negative effect on performance. Once enabled, metrics are exposed under the `..rocksdb` scope which we omit in the metric identifiers below.
- RocksDB is a log-structured merge tree that uses immutable files on disk. Deleted data will be marked as deleted in subsequent files; similarly, updated data will be written to subsequent files to shadow any previous versions. `estimate-live-data-size` helps you identify the actual state size without stale data. If this size is much smaller than the occupied size on disk (space amplification), you may want to think about letting RocksDB compact more often to clean up stale data. There is also the `total-sst-files-size` metric, but that may slow down queries if there are too many files.Alternatively, you can also use the previously mentioned checkpoint size metrics as an estimate but they will also include operator state (usually small) and anything else from memory, e.g., on-heap timers or user-managed state.
- The `background-errors` metric indicates low-level failures inside RocksDB. If you see those, you may want to inspect [RocksDB’s log file](https://kb.ververica.com/how-to-configure-rocksdb-logging-for-advanced-troubleshooting).
- RocksDB write operations are first added to an in-memory table which, when full, will be queued for flushing (and re-organizing) to disk. This queue has a limited size, and hence if flushing does not complete fast enough, it will back-pressure inside RocksDB. The `actual-delayed-write-rate` metric shows these write stalls which may be caused by slow disks.In these cases, it is often helpful to tune the number of threads for background jobs (flush and compaction) per stateful operator by changing the config value of `state.backend.rocksdb.thread.num`, which will add more concurrency here.
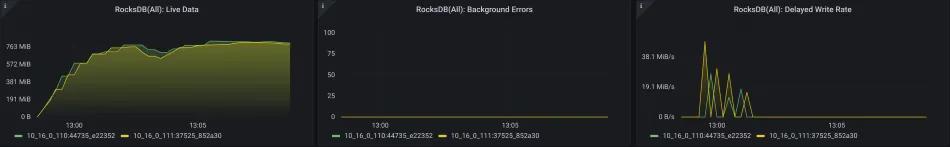
- Compaction is the process of removing stale data from disk by merging files together and keeping only the most-recent version of each data item. This is essential for read performance and can be inspected by looking at metrics such as `estimate-pending-compaction-bytes`, `num-running-compactions`, `compaction-pending` which indicate bottlenecks in the compaction processes. These could come from slow disks or low concurrency not saturating the available disks.Similarly to stalled write operations, `tuning` state.backend.rocksdb.thread.num may help to increase concurrency.
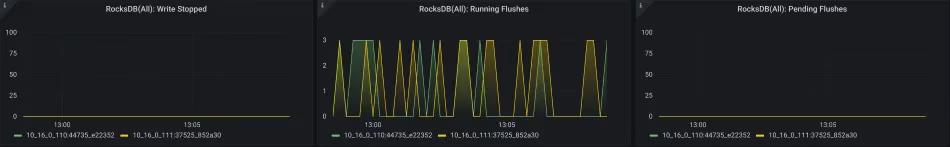
All the metrics above help you interpret what is going on inside RocksDB and help you identify knobs around the RocksDB tuning triangle of Space, Write, and Read Amplification. Actually, identifying the latter one is a bit of a challenge but if you see that your job is not write-heavy (or at least not stalled on write operations) and still performing slowly while spending most of its time inside RocksDB read operations, e.g., through [state access latency tracking](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/ops/metrics/#state-access-latency-tracking) or with the help of a profiler or Flink’s own [flame graphs](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/ops/debugging/flame_graphs/), that’s a good indicator of read amplification (and/or a disk bottleneck). Increasing compaction efforts may help but this is usually a case for [enabling bloom filters](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/deployment/config/#state-backend-rocksdb-use-bloom-filter) to reduce the amount of data to scan through.
> **TIP:** Check How to manage your RocksDB memory size in Apache Flink
## Getting started with a custom Grafana dashboard
We have baked our recommendations from the previous blog post and the metrics above into a Grafana dashboard for a Prometheus data source. Getting Flink metrics into Prometheus is relatively simple via the [Prometheus metric reporter](https://nightlies.apache.org/flink/flink-docs-stable/docs/deployment/metric_reporters/#prometheus) (either the pull or push version). At the simplest, you just provide the following Flink configuration and let Prometheus scrape the metrics from your Job and TaskManagers.
```yaml
metrics.reporter.prom.class: org.apache.flink.metrics.prometheus.PrometheusReporter
```
You can download our dashboard from [ververica-platform-playground/grafana-dashboard.json](https://github.com/ververica/ververica-platform-playground/blob/release-2.6/grafana-dashboard.json) and use it as a starting point for your own monitoring dashboards. In the following sections, we will explain a few more details of this dashboard and present a simple playground to test-drive it.
> **NOTE:** The dashboard you can find above is actually built for integration with Ververica Platform which raises the level of abstraction from Flink jobs to Flink applications (deployments) that may be comprised of multiple jobs over time, e.g., by doing application upgrades, rescaling operations, or reconfigurations. We are also deploying to Kubernetes and make sure that all the pods for these jobs are tagged with a unique Deployment ID which Prometheus is scraping as well. If you are not using Ververica Platform, you could alternatively rely on the Flink application name to bundle jobs together or just look at them individually. In the latter case, you will loose the combined overview across jobs and it may be more difficult to interpret the effects of application changes.
At the top of the dashboard, variables allow you to select the deployment to look at, a specific task to show details for (in various graphs of the following rows), RocksDB states to inspect (for low-level RocksDB statistics), and the TaskManager(s) to show detailed JVM statistics for. `All` provide a generic overview, but as soon as your application is scaling to a high number of resources, the graphs get too crowded, at least for troubleshooting purposes. You can, of course, also use Grafana’s abilities to filter out individual graphs.

If you introspect the panels, you will find a few details that are being taken care of, e.g., that the checkpoint statistics are guarded around `increase` functions because they will be reset after a job restart or quantiles that are being reported by subtask will just use `max` to show a single value across all of them. Usually, there is a panel with a generic overview of the whole job or all subtasks and, alternatively a second panel with more details per subtask for the selected `Task` at the top of the dashboard. This serves two purposes: (1) simplify grasping information quickly, doing continuous monitoring, and getting a high-level overview and (2) for looking at details to continue troubleshooting.
Please note that the `Latency` row’s first panels are visualizing a custom `eventTimeLag` metric that you may or may not have in your jobs. For our use cases, this has proven quite useful (for more information, refer to the [first part of this series](https://ververica.com/blog/monitoring-large-scale-apache-flink-applications-part-1-concepts-continuous-monitoring)). We also provide two variants of a more generic event time lag visualization using the built-in `currentOutputWatermark` metric, once in tabular form and once by plotting the difference between the latest watermark and the time this value was reported. As mentioned earlier, this is less accurate because Prometheus' granularity is at a second-level here and there may also be a delay from capturing the value inside Flink and capturing this timestamp. However, as a best-effort graph that works with every Flink application, it is usually good enough except for low-latency use cases. For these, we encourage you to provide your own `eventTimeLag` metric as described.
> **NOTE:** If your job is not creating watermarks, it will report Long.MIN_VALUE as the current watermark which will lead to graphs peaking at insane values that you can then ignore (or have to fix if you rely on event-time logic). This way, you are also able to find idle partitions.
In case you are wondering: throughput metrics are not showing any values for sinks because not all sinks support reporting output records or bytes yet. Also, the RocksDB row has a couple of more metrics than the ones introduced above. We decided to put all of the metrics available to Flink 1.14 into the graph in case you (enabled and) need them. They may be useful in specific situations but are less important in the regular case where it is enough to look at the ones we introduced.
A final word on some of the low-level Kubernetes metrics that we plot: metrics like `container_cpu_usage_seconds_total` or `container_memory_working_set_bytes` are reported per container. In the case where only pods are being annotated with the job/deployment IDs like here, we will need to join this metric together with one coming from a pod. We did so with the JVM status metrics and hence come up with Prometheus queries like the following one which purely uses the pod for connecting it to the deployment or TM but do not otherwise affect the result of the metric:
```sql
sum(
0*max({
__name__="flink_taskmanager_Status_JVM_CPU_Load",
deploymentId="$deploymentId"}) by (pod,tm_id)
+
on(pod)
group_left()
(
rate(
container_cpu_usage_seconds_total{
pod=~"job-.*-taskmanager-.*",
container=~"flink-taskmanager"}[5m]) * 1024 * 100
/
on(pod,id)
container_spec_cpu_shares{
pod=~"job-.*-taskmanager-.*",
container=~"flink-taskmanager"}
)
) by (deploymentId,tm_id)
```
Feel free to use this dashboard and extend it to your needs, e.g., by adding your own application-specific metrics that help you identify how your application is behaving.
## Test-driving the dashboard
If you want to try out the dashboard yourself, you can set up our [Ververica Platform playground](https://github.com/ververica/ververica-platform-playground) as described in our [Getting Started guide](https://docs.ververica.com/getting_started/installation.html). You can run this in any Kubernetes environment, also locally in Minikube as shown. Once up, you can upload your application’s jar file and [set up a new deployment](https://docs.ververica.com/getting_started/flink_operations.html) quickly. As soon as this is running, the “Metrics” link will become available and direct you to our Grafana dashboard showing all the metrics for your application.
Go ahead and try it out in various applications and different workloads.
## Summary
In this second part of our two-piece series on large-scale Apache Flink application monitoring, we focused on metrics that primarily help you troubleshooting application failures and performance issues. If you would like to refresh your knowledge on continuous application monitoring, please have a look at the [first part of this series](https://4757017.hs-sites.com/blog/monitoring-large-scale-apache-flink-applications-part-1-concepts-continuous-monitoring). We also introduced our Grafana monitoring and troubleshooting dashboard and made it available to you so that you can start quickly in your own efforts with a production-ready Flink application. We’re curious to hear how the dashboard is working for you and are looking forward to any feedback or suggestions of what you would like to see added.
## Resources
- Webinar video: [Webinar: Monitoring Large-Scale Apache Flink Applications](https://www.youtube.com/watch?v=XgumbKHE2Zw)
- [A Debuggers Guide to Apache Flink Streaming Applications](https://www.youtube.com/watch?v=bhcFfS1-eDY)
- Our Grafana dashboard: [ververica-platform-playground/grafana-dashboard.json](https://github.com/ververica/ververica-platform-playground/blob/release-2.6/grafana-dashboard.json)
---
---
title: "Monitoring Large-Scale Apache Flink Applications, Part 1"
description: "Learn best practices for monitoring large-scale Apache Flink applications, focusing on key metrics, troubleshooting, and effective tools for continuous monitoring."
lastUpdated: 2026-07-06T07:28:47.000Z
source_url:
html: "https://www.ververica.com/blog/monitoring-large-scale-apache-flink-applications-part-1-concepts-continuous-monitoring"
md: "https://www.ververica.com/blog/monitoring-large-scale-apache-flink-applications-part-1-concepts-continuous-monitoring.md"
---
As the original creators of Apache Flink, we are often asked for best practices around monitoring Flink applications and people want to know which metrics they should monitor for their applications at scale. In this two-piece blog post series based on a [previous monitoring webinar](https://www.youtube.com/watch?v=XgumbKHE2Zw), we would like to share our experiences around monitoring, focus on metrics to look at, and explain how to interpret them.
To get everyone on the same page, we will start detailing the concepts of monitoring and metrics with Apache Flink and answer the question of how to monitor Apache Flink. Then, we will turn our attention to metrics for continuous monitoring and explain their characteristics and how they help see what is going on. A follow-up blog post will touch on metrics that help during troubleshooting and present the dashboard we have been using here and for our Apache Flink training playground.
## Concepts
> **NOTE:** Application monitoring is a process that ensures that a software application processes and performs in an expected manner and scope. This technique routinely identifies, measures and evaluates the performance of an application and provides the means to isolate and rectify any abnormalities or shortcomings.
This is a rather generic area, so what makes monitoring Apache Flink special?
First of all, _Flink is a_ _**distributed**_ _stream processing framework_! So jobs may not only run at high parallelism on multiple machines with a vast set of different environments across several layers of abstractions (virtualization, Kubernetes,...), but also in different deployment modes (application, per-job, session mode). Larger jobs typically introduce several challenges for monitoring and interpreting what is going on underneath.
In addition to that, Flink jobs run arbitrary user code with custom business logic and vast differences in application behaviour that may affect the underlying resources and expose different bottlenecks.
### Common Tools
The toolset for monitoring large-scale applications is quite broad:
_Logging_ is very useful for debugging specific failures (so don't blindly disable or reduce it in order to decrease the size of the log). However, it is not really suitable for large-scale monitoring since you would typically have to log too much data to monitor your application continuously and it may be difficult to set up alerts based on that. A common metrics system typically has better tools in this regard.
_System-level and cluster metrics_ help you understand your application at a coarse-grained level, e.g., how the underlying Flink, Kubernetes, ... cluster behaves, but don't give you much insight into the application layer. This is why we recommend enriching your application with _custom application metrics_ that reflect the critical parts and states of your application. Based on these, you understand what your application is doing in a certain situation, e.g., when troubleshooting a problem.
Last but not least, _profilers_ may give you very detailed insights into your application to identify bottlenecks, thread-locks and congestion, troubleshoot memory leaks and GC issues, and much more. While they are very useful for troubleshooting and performance tunin , they are not really suitable for large-scale monitoring because they accumulate quite a lot of data which is difficult to use for alerting before problems occur.
### Flink's metrics system
Let's look at how Flink makes metrics available, which metric types are supported, and how these can be used.
First of all, Flink metrics are objects that pair an identifier with a measurement. There are 4 different types of metrics:
- _counters_ count things, e.g., `numRecordsIn`
- _meters_ both count and measure rates, e.g., `numRecordsInPerSecond`
- _histograms_ measure statistical distributions, e.g., latency distribution, and can easily provide percentiles
- a _gauge_ returns a value, e.g., uptime
Each metric is scoped to a specific context within the Flink runtime where the scope becomes a part of the metrics identifier as ` [+ ] + `. There are [system scopes](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/ops/metrics/#system-scope) for metrics at the JobManager (JM), JM+job, TaskManager (TM), TM+job, task, and operator. You can also fine-tune scope formats to adapt metrics identifiers to your need.
It is fairly easy to expose your own custom metric in Flink, and the [Flink docs](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/ops/metrics/#metric-types) already provide a couple of details on this topic, so we will not go into details here.
Metrics can be exported by a `MetricReporter`, the Flink REST API, or Flink’s web UI. While it’s clear that the REST API is available for automation, you may be tempted to use Flink’s web UI for monitoring your application (and cluster). Flink, however, is not a fully-fledged metrics system, nor does it try to provide a suitable dashboard for monitoring - it is ok to use the UI for occasional checks as part of your debugging experience; it lacks the appropriate functionality of a proper metrics system and dashboard. Therefore, any serious application monitoring goes through [metrics reporters](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/deployment/metric_reporters/), which write metric values into an external system. Flink bundles a vast set of such reporters, e.g., Prometheus, Datadoc, Ganglia, InfluxDB, etc., and it is also fairly easy to write your own should you need something else.
## Metrics for continuous monitoring
Flink includes a lot of metrics out-of-the-box. Here, we will look at some of the most useful examples you can use to continuously monitor your (large-scale) applications, set up alerts on, or use for troubleshooting. We will provide screenshots of our metrics dashboard and will share the full dashboard in a follow-up blog post that wraps up this series.
### Application health
The obvious things to keep an eye on for your Flink application are whether it is still running (`uptime`) or how often it was not running / restarting (`numRestarts`). You should set appropriate alerts for each of these.
There are a lot of different reasons why a job may restart. In a well-behaved system, though, most of these originate from transient failures and can be ignored. However, since these can happen at any time, you want to make sure that the recovery is fast, and this is what you can track with the `restartingTime` metric.
If the `restartingTime` is high and you have a latency-critical job, you may want to tune it in this regard.
Whenever a failure (transient or not) occurs and triggers a restart, fault-tolerant Flink applications will restart the job from the latest checkpoint or savepoint. For these cases you may want to make sure that you don't have to go back too far and reprocess a lot of data because that would effectively add to your job’s downtime You can track various (general) checkpointing metrics for this, e.g., `numberOfCompletedCheckpoints`, `numberOfFailedCheckpoints`, `numberOfInProgressCheckpoints` You may also want to track checkpoint failures in advance for jobs that restart on a pre-configured number of failed checkpoint attempts. Alerts can be set on some threshold of the number of failed checkpoints or on the last successful checkpoint being created too long ago.*
> **WARNING:** * Unfortunately, there is no direct metric for "time of last completed checkpoint". You can either extract this from the last increase of numberOfCompletedCheckpoints, retrieve it from Flink's REST API, or calculate it from your checkpoint frequency and set an alert on a number of consecutive checkpoint failures.
### Checkpointing
While we are looking at checkpointing, let’s explore some more details like duration, size, and alignment time: `lastCheckpointDuration` should be below the checkpoint timeout or a checkpoint will fail. You could set up alerts on this in case the duration keeps increasing but it may be safer, with respect to false alarms, to alert on actual checkpoint failures instead (see above). `lastCheckpointSize` can be used to estimate the current state size. For incremental checkpoints, however, this wasn’t too meaningful in the past and Flink 1.15 adds the new `lastCheckpointFullSize` metric which provides the full checkpoint size (including files shared with previous checkpoints) rather than the number of bytes in an incremental checkpoint. `checkpointAlignmentTime` is also more a metric for troubleshooting checkpoint failures.
### Latency
The most important part to look at if your job runs event-time logic is: "Are we making progress?".
For applications using event-time processing, it is important that the watermarks continue to advance. It is good to monitor the watermark at time-sensitive operators, such as process functions and windows, by watching the difference between the current timestamp and the watermark. If this _event-time skew_ or _event-time lag_ is unusually high, then this indicates that either (1) you are processing older events, perhaps during recovery from an outage, or (2) something upstream has not sent a watermark for a long time, e.g., a source has become idle. In the latter case, you need to find a workaround or fix your code.
To get the event-time lag from built-in metrics, we can plot the timestamp of gathering the value of the `currentOutputWatermark` metric versus the actual value and set an appropriate alert.
We can do so at different levels, e.g.,
- to gather information about how event-time is making _progress throughout the job graph_, we could group by the different operators of the job; or
- if we want to inspect _event-time skew_ among subtasks, then we plot each subtask of a particular operator as shown.
A downside of the built-in metrics approach, however, is that processing time timestamps, at least in Prometheus, only have second accuracy. For very low-latency use cases, this may not be enough...
In general, the event-time lag definition from above is working quite well, but it also includes the time that events spend while waiting in external systems (outside Flink, e.g., in your Kafka topic, or even before that one while writing to it). If you want a more fine-grained resolution, to solely look at the time spent in Flink, or monitor a different flavor of a _processing delay_, e.g., by excluding lag from Async I/O, late events handling, etc., or want to include delays from transactional sinks while operating in end-to-end exactly-once mode, you will need your own custom metric to reflect your definition.
In our [training exercises](https://github.com/ververica/flink-training/blob/8d28f02d7ebf32e0a24d87927db52b2072fe25e0/troubleshooting/introduction/src/main/java/com/ververica/flink/training/exercises/TroubledStreamingJob.java#L185-L190), for example, we create our own custom `eventTimeLag` metric, which we update whenever a window fires. Since we are using a histogram, we can also easily plot percentiles which may be useful for SLA management.
Alternatively, you can also look at Flink’s [built-in latency markers](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/ops/metrics/#end-to-end-latency-tracking), but they are more of a debugging tool and a bit special in their definition.
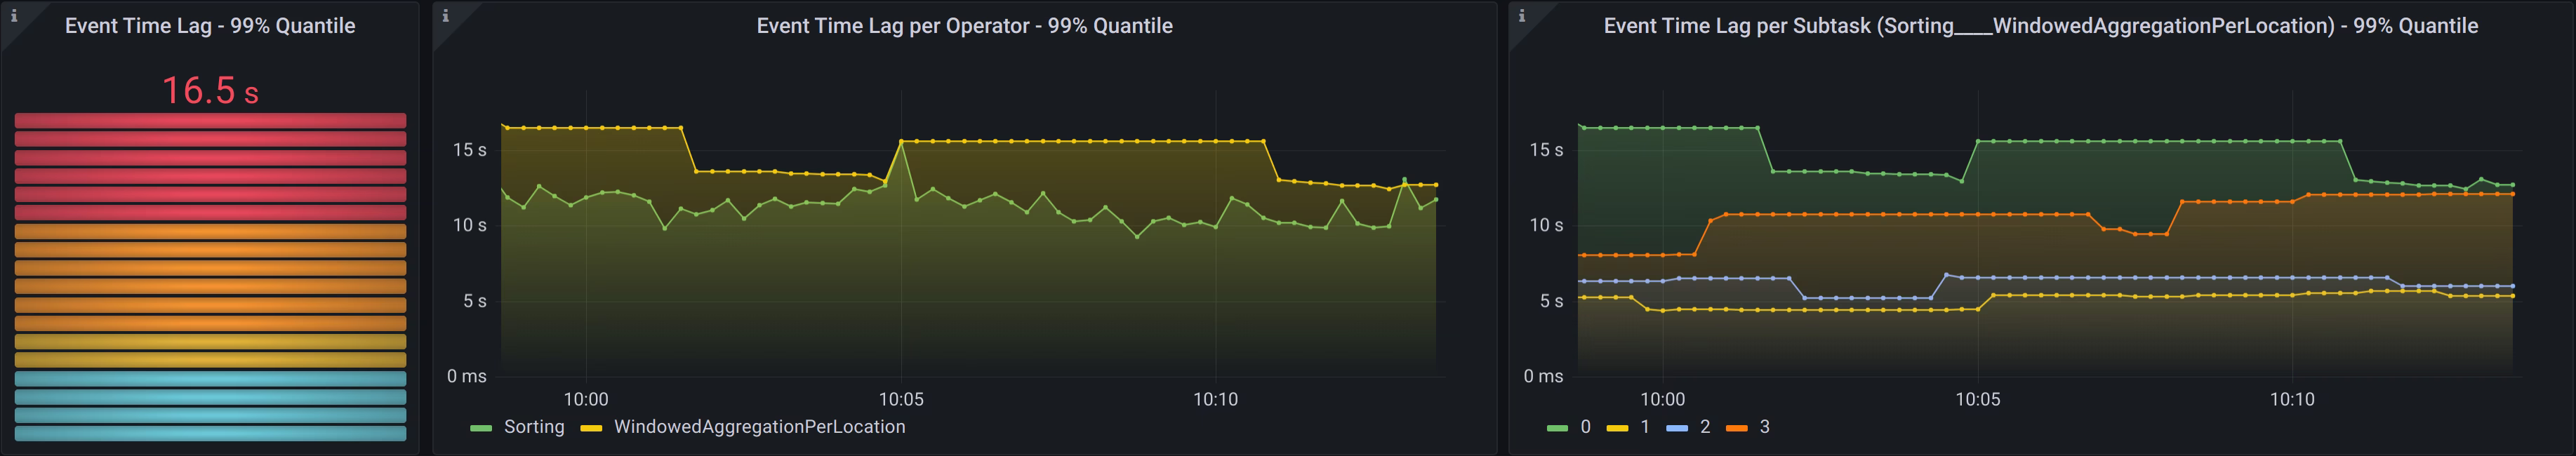
Last but not least, I would like to highlight a few connector-specific metrics to indicate whether we are keeping up with the external systems. While reading from Kafka or Kinesis, for example, `records-lag-max` and `millisBehindLatest`, respectively, indicate how far a consumer (group) is behind the head of the message queue. Flink forwards these connector metrics into Flink's metric system for convenience.
- `records-lag-max` shows the maximum lag in terms of the number of records for any partition. An increasing value over time is your best indication that the consumer group is not keeping up with the producers.
- `millisBehindLatest` shows the number of milliseconds a consumer is behind the head of the stream. For any consumer and Kinesis shard, this indicates how far it is behind the current time.
### Throughput
Any performance monitoring should come with throughput measurements!
Flink offers metrics such as `numRecords(In|Out)PerSecond` or `numRecords(In|Out)` for each subtask*. Although these are available for all tasks in your job, due to backpressure propagating upstream in Flink, it is usually enough to monitor the throughput on the output of the sources and configure alerting on that one. Additional details per task and/or subtask may help you during troubleshooting and performance tuning.
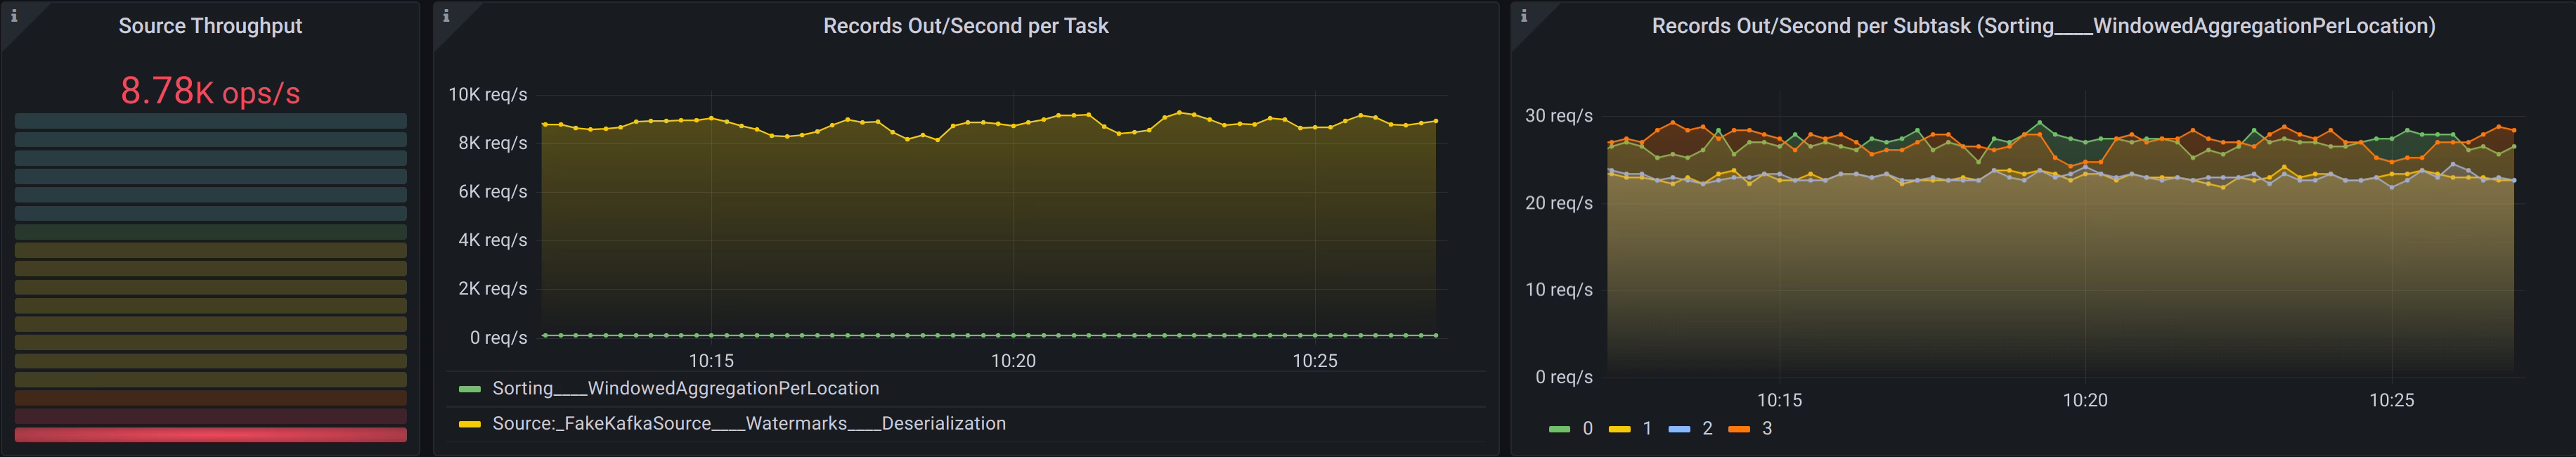
> **WARNING:** * Note: FLIP-27 and FLIP-143 allow sources and sinks to define meaningful metrics for their inputs and outputs, respectively (also see FLIP-33). Some of these sources and sinks already use that to provide input and output metrics but not everything has been ported yet.
### JVM metrics (1): Continuous monitoring
Going one level deeper, there are also a couple of system-level metrics to look at for continuous monitoring, starting at the JVM and going into further metrics such as those from the underlying deployment system, e.g., Kubernetes.
On Kubernetes, `container_memory_working_set_bytes` is an accurate snapshot of how much memory your pod's containers are using in total, including memory that the JVM can reach and those areas it cannot, e.g., native memory from RocksDB. A reasonable alert here would compare this with the value of `container_spec_memory_limit_bytes` and notify you early before a machine is being restarted or will help you troubleshoot why a restart occurred. Similarly, any of the `Status.JVM.Memory.*` metrics will help you keep an eye on the JVM memory and its components.
See [Metrics](https://nightlies.apache.org/flink/flink-docs-release-1.15/docs/ops/metrics/#system-metrics) for a full list of system metrics provided by Flink. Further metrics may be collected outside of Flink for underlying system components.
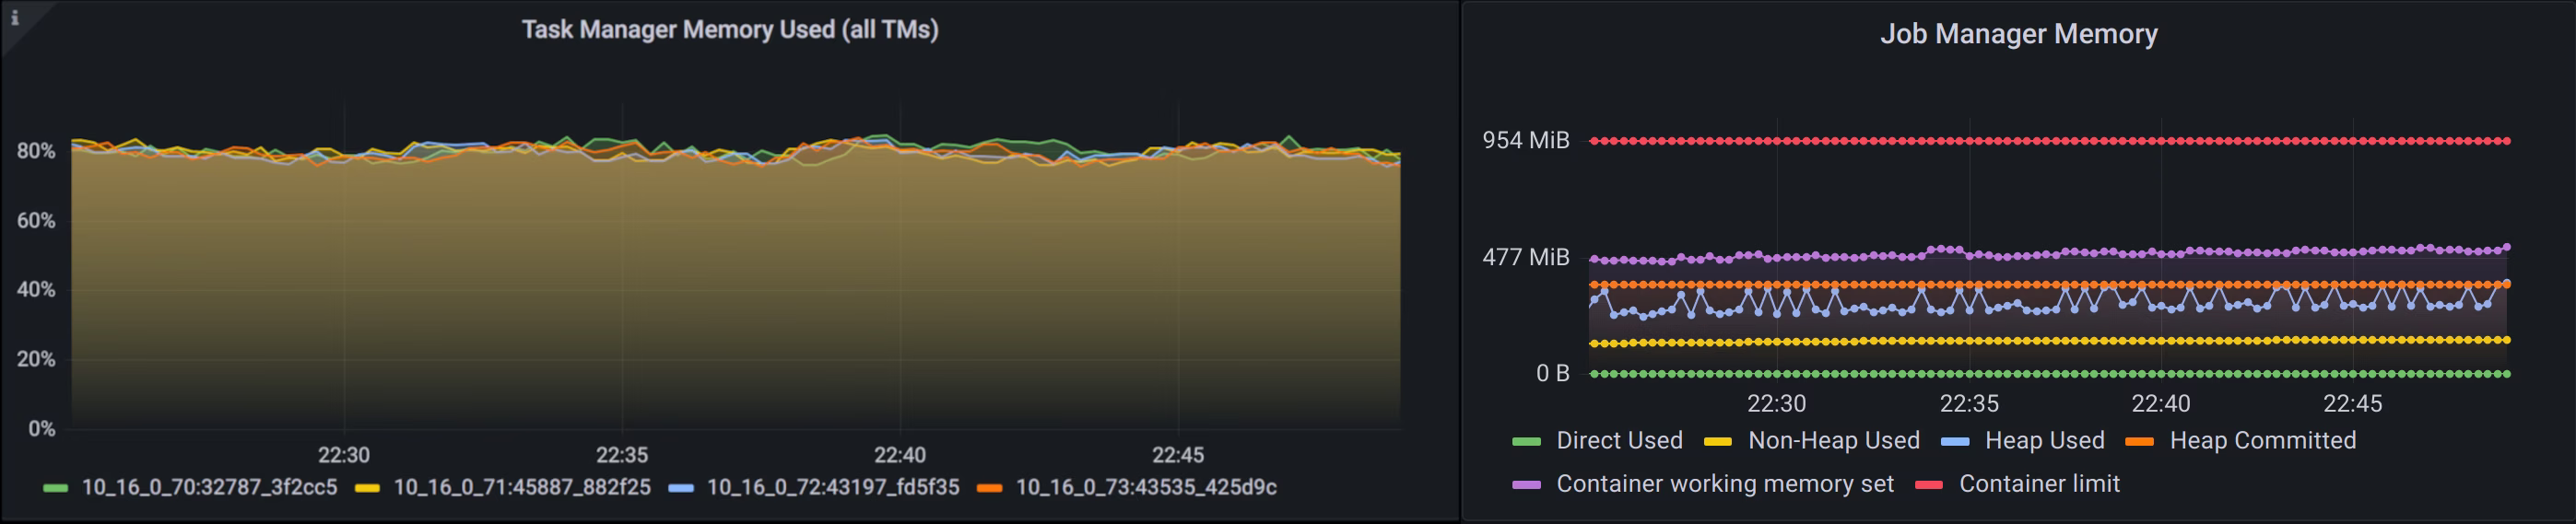
## Summary
In this first part of a two-piece blog post series on monitoring large-scale Apache Flink applications, we have presented the concepts around Flink’s metrics system and introduced various useful metrics for continuous monitoring. These metrics can be set up with proper alerts to inform you about imminent failures and allow you to monitor cluster and application health and checkpointing progress. We presented different ways to track latency and observe your application’s throughput for performance monitoring. These metrics also serve as a good starting point for troubleshooting failures or performance degradations, which we will extend in the [next part of this series](https://4757017.hs-sites.com/blog/monitoring-large-scale-apache-flink-applications-part-2-metrics-for-troubleshooting), where we will also go into some details of our dashboard and share that with you to start your own. Stay tuned!
## Resources
- Webinar video: [Webinar: Monitoring Large-Scale Apache Flink Applications](https://www.youtube.com/watch?v=XgumbKHE2Zw)
- [Metrics](https://nightlies.apache.org/flink/flink-docs-stable/docs/ops/metrics/)
- [Metric Reporters](https://nightlies.apache.org/flink/flink-docs-stable/docs/deployment/metric_reporters/)
---
---
title: "The Impact of Disks on RocksDB State Backend in Flink: A Case Study"
description: "Discover how disk performance affects Flink jobs using RocksDB as we analyze a throughput drop issue and uncover solutions to optimize state backend performance."
lastUpdated: 2026-07-07T05:30:18.000Z
source_url:
html: "https://www.ververica.com/blog/the-impact-of-disks-on-rocksdb-state-backend-in-flink-a-case-study"
md: "https://www.ververica.com/blog/the-impact-of-disks-on-rocksdb-state-backend-in-flink-a-case-study.md"
---
As covered in a [recent blog post](https://flink.apache.org/2021/01/18/rocksdb.html), RocksDB is a state backend in Flink that allows a job to have state larger than the amount of available memory as the state backend can spill state to local disk. This means disk performance may have an impact on the performance of Flink jobs using RocksDB. Through a case study, this blog post illustrates a throughput drop problem of a Flink job using RocksDB and demonstrates how we identified the performance of the underlying disk as the root cause.
## Job and Execution Environment
We were dealing with a typical Internet of Things (IoT) job that processes a stream of events emitted from millions of devices. Each event contains a device identifier (ID), an event type, and the timestamp when the event was generated. The job partitions the stream based on the device ID and stores in state a mapping from each event type to the latest timestamp when that type of event was received. There can be hundreds of event types. For each incoming event, the job needs to read the timestamp from state for the received event type and compare it with the incoming one. If the incoming timestamp is newer, it updates the timestamp stored in state.
The job runs on an [Amazon Elastic Kubernetes Service (EKS)](https://aws.amazon.com/eks) cluster created with the official AWS command line tool [eksctl](https://docs.aws.amazon.com/eks/latest/userguide/getting-started-eksctl.html#install-eksctl) with all default settings. The Flink TaskManager is allocated with 1.5 CPU cores and 4 GB memory. The job uses the RocksDB state backend, which is configured to use Flink’s managed memory. The `state.backend.rocksdb.localdir` configuration option is not explicitly set, so by default the /tmp directory on the root volume of the underlying EC2 instance is used for RocksDB in-flight state (i.e. working state).
## Symptoms
This job ran fine on EKS initially. But after some time — hours or days, depending on the incoming events — the job throughput suddenly dropped significantly. The drop could be easily reproduced. The throughput metrics graph below shows a drop from more than 10k events per second to a few hundred events per second shortly after 23:50 in a given day.
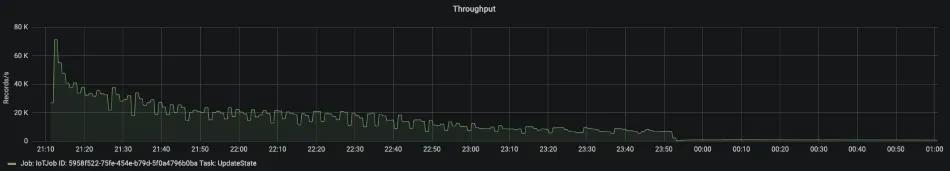
In addition, stopping the job with a savepoint and then resuming from it didn’t help: the job throughput remained low after the restart. Although high throughput was restored when the job was restarted from an empty state, this was not an option because (1) the job state would be lost and (2) the job throughput would drop again after a shorter period of time.
## Analysis
Checking the CPU metrics, we noticed that when the throughput dropped, the CPU utilization of the TaskManager container was also reduced. Since the TaskManager container can potentially use more CPU resources (same as before the throughput drop happened), the reduction of the CPU usage is rather a symptom here.
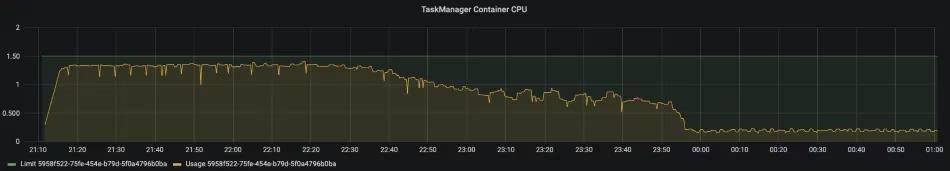
The memory usage of the TaskManager container reached the allocation limit a long time before the throughput drop happened, and it did not change significantly at around 23:50.
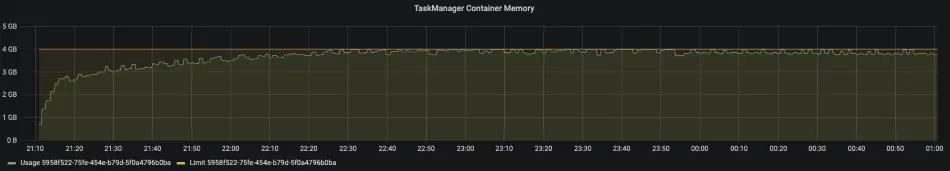
```yaml
env.java.opts.taskmanager: >-
-Dcom.sun.management.jmxremote
-Dcom.sun.management.jmxremote.authenticate=false
-Dcom.sun.management.jmxremote.ssl=false
-Dcom.sun.management.jmxremote.local.only=false
-Dcom.sun.management.jmxremote.port=1099
-Dcom.sun.management.jmxremote.rmi.port=1099
-Djava.rmi.server.hostname=127.0.0.1
```
Then we attached a local running VisualVM to the TaskManager and did a CPU sampling. As seen in the CPU sampling results below, 93% of CPU time was consumed by the thread `UpdateState`. This is the thread that runs the operator `UpdateState`, which reads and updates state in RocksDB.
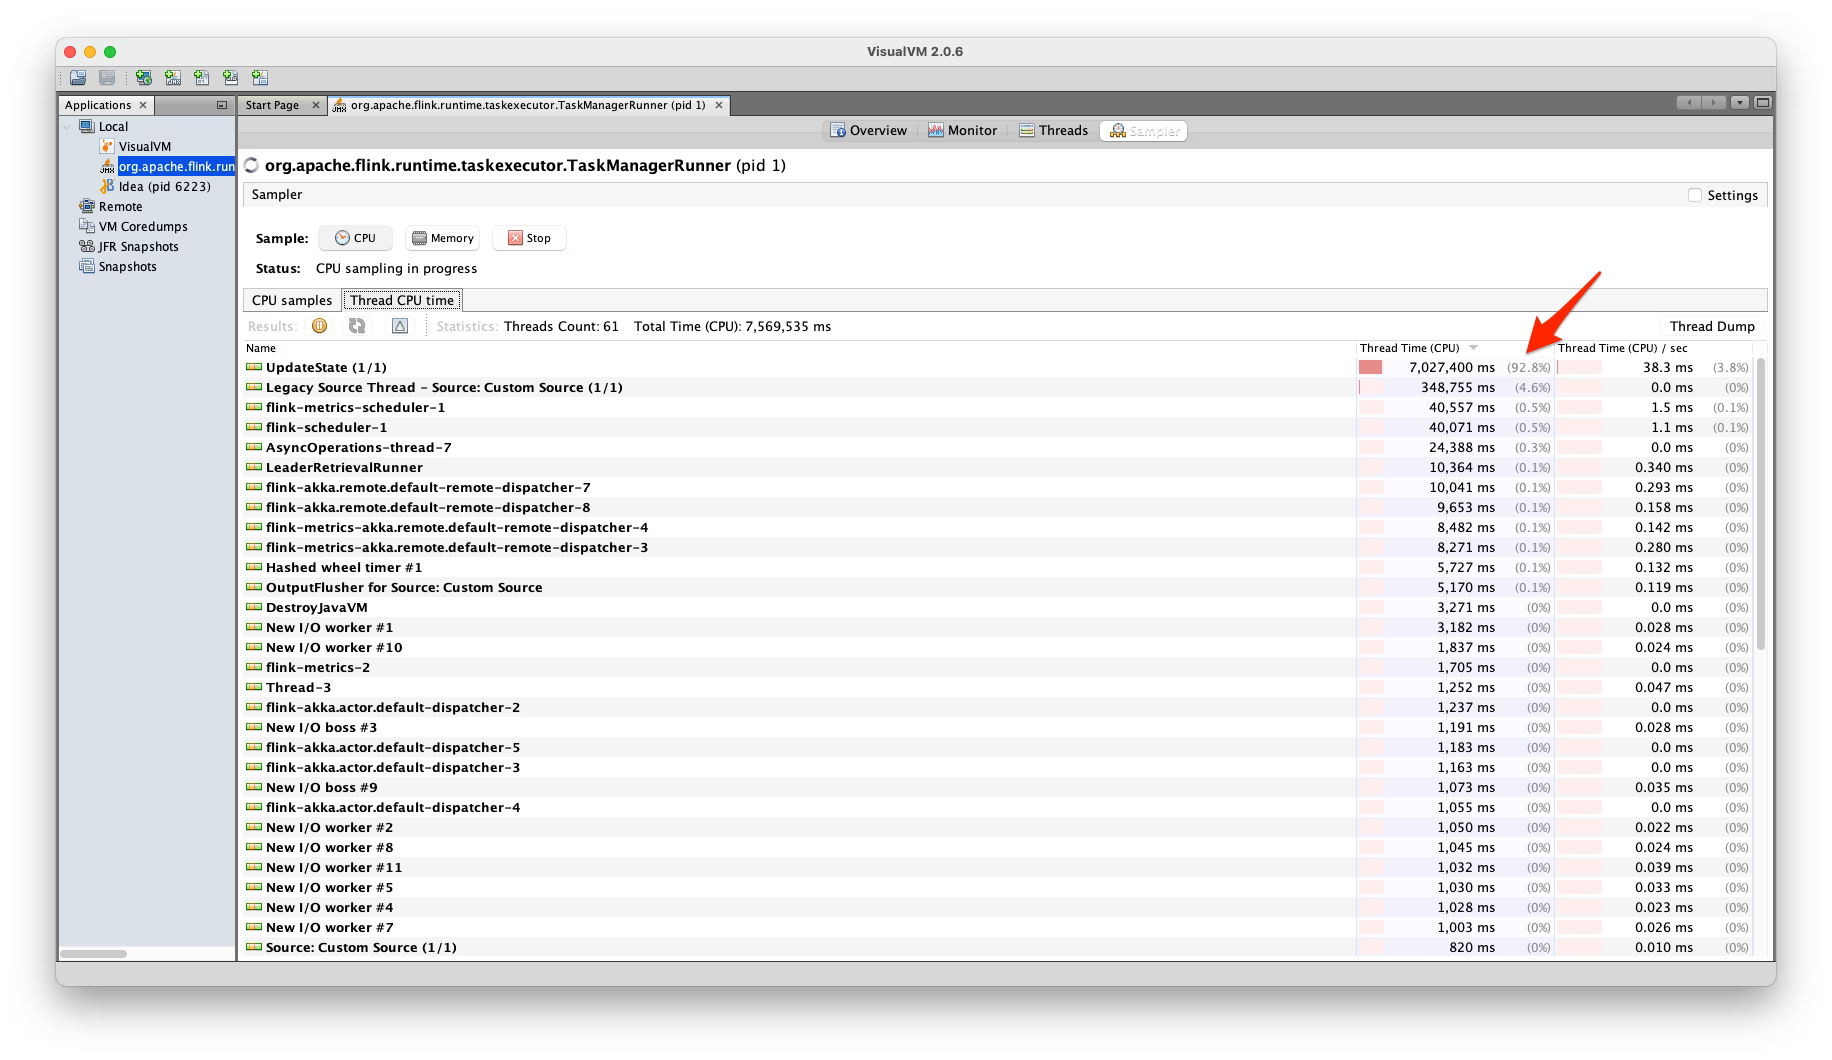
Inside the `UpdateState` thread, as seen in the screenshot below, almost all of the CPU time was taken by the native method `org.rocksdb.RocksDB.get()`. This tells us that the job was bottlenecked on reading state from RocksDB.
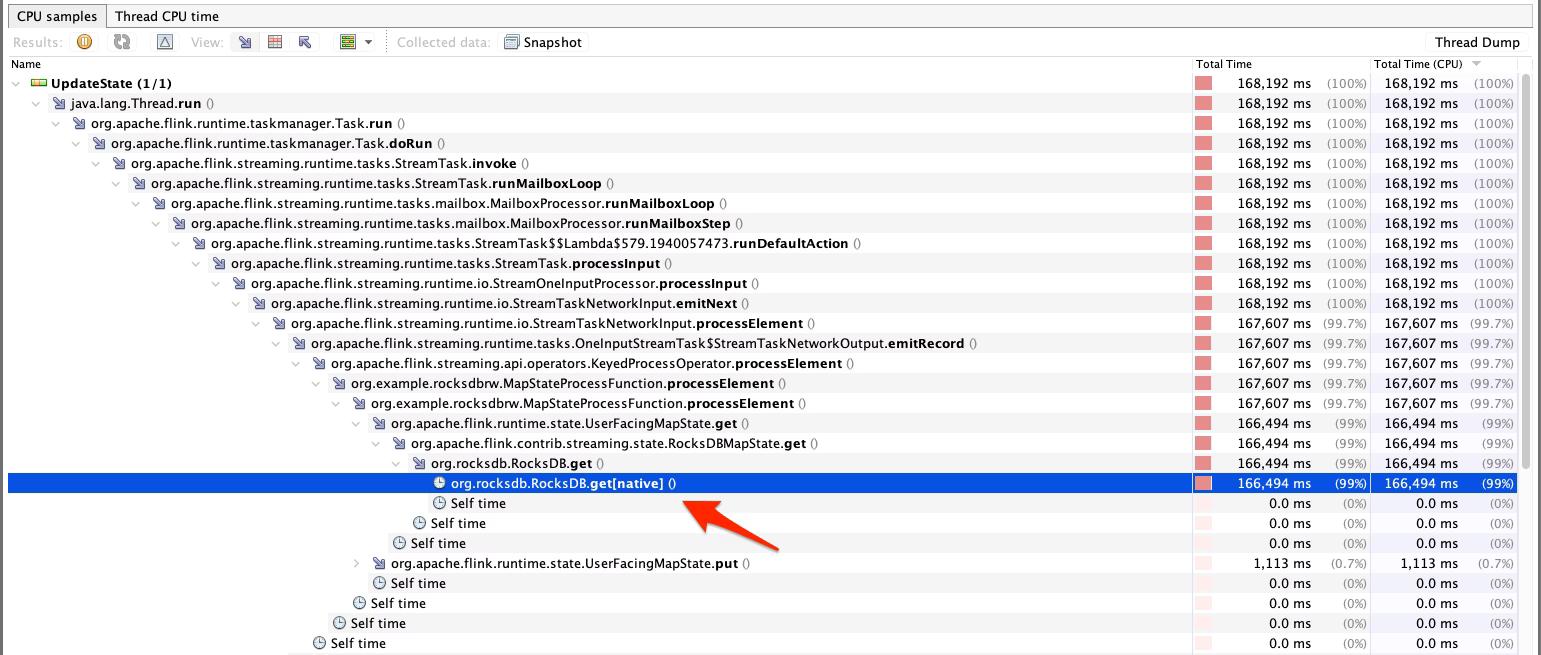
To further investigate where RocksDB was spending its time, we enabled the following [Flink RocksDB metrics](https://ci.apache.org/projects/flink/flink-docs-release-1.12/deployment/config.html#rocksdb-native-metrics):
```yaml
state.backend.rocksdb.metrics.block-cache-capacity: true
state.backend.rocksdb.metrics.block-cache-pinned-usage: true
state.backend.rocksdb.metrics.block-cache-usage: true
state.backend.rocksdb.metrics.estimate-table-readers-mem: true
```
The block cache is where RocksDB caches data in memory for reads. As seen in the following graph, the block cache was filled up quickly in the first few minutes when the job was started, mainly by the state entries. This still does not explain the sudden throughput drop at around 23:50.
> **WARNING:** RocksDB native metrics are disabled by default, as they may have a negative performance impact on your job. Use in production with caution.
When a state entry is not in the RocksDB block cache, reading it from RocksDB will involve disk IO operations. We moved ahead to check the disk metrics of the root volume. As seen in the following two graphs, the read throughput was dropped to around 230 operations per second at the time when the Flink job throughput dropped. The same happened on the write throughput, which dropped to around 10. Checking the disk Input/Output Operations Per Second (IOPS) capacity, we found that by default each EC2 instance in an EKS cluster created with eksctl is a [m5.large](https://aws.amazon.com/ec2/instance-types/) instance coming with a general-purpose ([gp2](https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/ebs-volume-types.html)) Elastic Block Store (EBS) root volume. The root volume has a size of 80GB and delivers a baseline rate of 240 IOPS. This confirmed that the disk was saturated and the Flink job was bottlenecked on disk IO.
The reason we could achieve higher IOPS at the beginning was due to the [initial I/O credits](https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/ebs-volume-types.html#EBSVolumeTypes_gp2) which AWS gives to every gp2 volume to sustain burst IO requests. The Burst Balance metrics below confirmed this: the initial I/O credits were exhausted and the burst balance dropped to 0 at the time when the issue happened. This also explains why a job restart did not help.
With the root cause identified, the solution to overcome this problem was to attach a dedicated volume with a high IOPS rate, e.g., a gp3 or io1/io2 volume and then set the Flink configuration `state.backend.rocksdb.localdir` to a directory on that volume.
## Conclusion
This blog post described a Flink job throughput drop problem and the investigation we did to find the root cause. As we can see, the disk performance had a significant impact on the performance of the RocksDB state backend in Flink. The key takeaway here is: when using the RocksDB state backend with large state and accessing state is expected to hit disk constantly (e.g., reading state from RocksDB randomly), you should set the Flink configuration `state.backend.rocksdb.localdir` to a directory on a volume with a high IOPS rate. Keep in mind that burstable disks are good for jobs with bursty IO. A burstable disk may bring you sufficient performance initially but overtime its performance may drop to its baseline when the burst I/O credits are ever exhausted.
---
---
title: "Simplifying Ververica Platform SQL Analytics with UDFs"
description: "Discover how to simplify SQL analytics on the Ververica Platform using user-defined functions (UDFs) for streamlined data extraction and insights."
lastUpdated: 2026-07-07T05:22:00.000Z
source_url:
html: "https://www.ververica.com/blog/simplifying-ververica-platform-sql-analytics-with-udfs"
md: "https://www.ververica.com/blog/simplifying-ververica-platform-sql-analytics-with-udfs.md"
---
While previous blog posts already covered [Getting started with Flink SQL on Ververica platform](https://www.ververica.com/blog/ververica-platform-2.3-getting-started-with-flink-sql-on-ververica-platform), [Creating data pipelines with Flink SQL](https://www.ververica.com/blog/data-pipelines-with-flink-sql-on-ververica-platform), and even a complete [AdTech Use Case for Real-Time Performance Monitoring](https://www.ververica.com/blog/real-time-performance-monitoring-with-flink-sql-ad-tech-use-case), here, we want to focus on sharing common functionality in user-defined functions (UDFs) to make your life even easier.
## Flink Community Data Analytics
Initially, this project started with analytics on the commits to [github.com/apache/flink](http://github.com/apache/flink) by using the Github API. To make things a bitmore interesting and to extract more valuable insights into Flink’s community, with the second version of this project, we added support for looking at pull requests and also at email messages from [Flink’s mailing lists](https://flink.apache.org/community.html#mailing-lists). When interpreting the `dev` mailing list, however, please beware that every ticket that is created in Flink’s Jira is also posted there and you can do basic analytics with it as well (created bug reports, feature requests,…).
We kept the original code for repository analytics in Java and can develop SQL jobs dynamically based on what we are interested in. The whole project is available on [Github](https://github.com/ververica/lab-flink-repository-analytics/tree/release-2.0) and can be built with `./gradlew clean check shadowJar` or the IDE of your choice. We also provide [pre-built packages](https://github.com/orgs/ververica/packages?repo_name=lab-flink-repository-analytics) for things like the data import and user-defined functions that we will use later on. The code and packages I’m describing and using here are from version 2.0 and I will present results from Ververica Platform 2.3.3 which executes SQL statements on Flink 1.11.3.
In order to make our life a bit easier and not have to worry about the Github API throttling our analytics along the way, we will import any data that we want to use into Kafka.
### Setting up Apache KafkaTopics
First, let’s create the Kafka topics we will use (replacing the `bootstrap-server` with one of your own):
```
kafka-topics --create --bootstrap-server YOUR_KAFKA_SERVER \
--topic flink-commits
kafka-topics --create --bootstrap-server YOUR_KAFKA_SERVER \
--topic flink-pulls
kafka-topics --create --bootstrap-server YOUR_KAFKA_SERVER \
--topic flink-mail-dev --config max.message.bytes=5242940
kafka-topics --create --bootstrap-server YOUR_KAFKA_SERVER \
--topic flink-mail-user --config max.message.bytes=5242940
kafka-topics --create --bootstrap-server YOUR_KAFKA_SERVER \
--topic flink-mail-user-zh --config max.message.bytes=5242940
```
Note that there are a few emails on the mailing lists that exceed Kafka’s default maximum message size, so make sure to either have a cluster with higher defaults or use the values above. You may also want to set the configuration parameters `retention.bytes` and `retention.ms`, depending on your global defaults because we want to do analytics on the whole (historical) data stream and that should still be available when we read it. I will also leave setting appropriate `--replication-factor` and `--partitions` to you, but for a simple demo, 1 should suffice.
### Importing the Data
The `import` sub-project ([code](https://github.com/ververica/lab-flink-repository-analytics/tree/release-2.0/import) / [package](https://github.com/ververica/lab-flink-repository-analytics/packages/541978?version=2.0)) exposes 3 Flink jobs:
- `com.ververica.platform.FlinkCommitsToKafka`This job uses the Github API to retrieve commit information from the `master` branch at [github.com/apache/flink](http://github.com/apache/flink) and writes it to a Kafka topic of your choice (we will present the schema further below). The job can be configured with main args like these: `--start-date 2013-04-17 --kafka-server YOUR_KAFKA_SERVER --kafka-topic flink-commits`
- `com.ververica.platform.FlinkPullRequestsToKafka`Similar to the Github commit log import job above, this uses the Github API to fetch pull request data towards Flink’s `master`. This job can be configured like the one above via main args like these:`--start-date 2013-04-17 --kafka-server YOUR_KAFKA_SERVER --kafka-topic flink-pulls`
- `com.ververica.platform.FlinkMailingListToKafka`The third import job will fetch mailing list archives for the `dev`, `user`, and `user-zh` mailing lists and write them to Kafka topics `flink-mail[-dev|-user|-user-sh]` in a single job with main args like these:`--start-date 2014-04 --kafka-server YOUR_KAFKA_SERVER --kafka-topic flink-mail`
All of these three jobs are streaming jobs that you could leave running and would then update the respective Kafka topics along the way. If you just want to work on a bounded data stream though, you can stop the import at any time, or stop with a savepoint and resume it at a later point in time. The current process is logged at INFO level as `Fetching commits since until `, `Fetching pull requests since `, and `Fetching mails from `.
### Making the Data Available to Flink SQL
As you may know, in order to make any data available to [Flink SQL](https://4757017.hs-sites.com/apache-flink-sql-on-ververica-platform#bgimage3), we have to create a (dynamic) table telling Flink how to access and de/serialize it. This can be easily done in a couple of [CREATE TABLE DDL statements](https://ci.apache.org/projects/flink/flink-docs-release-1.12/dev/table/sql/create.html#create-table) which can be executed one after another in Ververica Platform’s SQL editor. They will register the input streams with Ververica Platform’s internal [SQL catalog](https://docs.ververica.com/user_guide/sql_development/catalogs.html) so you can use these again in the future or make them available to your fellow colleagues.
> **NOTE:** If you do not want these tables to enter the SQL catalog, you can also register them as temporary tables that are just valid for the statement(s) you execute via CREATE TEMPORARY TABLE. This, however, makes executing selections a bit more difficult because you will always have to select the table statement as well.
The following two statements exemplify the table format for the commits table and the user mailing list table. A complete list of DDL statements to create all tables that were imported above is provided in our project’s [README file](https://github.com/ververica/lab-flink-repository-analytics/tree/release-2.0#output-table-definitions). As you can see, they also contain a few specialities, e.g. `flink_commits.filesChanged` is a structured type on its own (an array of rows). For our purposes, a watermark delay of 1 day is also sufficient to account for any late input but beware, that in this case, you would have to wait for 1 day to pass before getting statistics (feel free to adapt). Similarly, adapt if you do not always want to read from the earliest offset - actually, you can also override any connector settings in your queries by specifying [Dynamic Table Options](https://docs.ververica.com/user_guide/sql_development/table_view.html#hive-dynamic-table-options). For our demo here, though, we will always do the same and can thus simplify our queries with a proper default definition.
flink_commits
```sql
CREATE TABLE `flink_commits` (
`author` STRING,
`authorDate` TIMESTAMP(3),
`authorEmail` STRING,
`commitDate` TIMESTAMP(3),
`committer` STRING,
`committerEmail` STRING,
`filesChanged` ARRAY>
`sha1` STRING,
`shortInfo` STRING,
WATERMARK FOR `commitDate` AS `commitDate` - INTERVAL '1' DAY
)
COMMENT 'Commits on the master branch of github.com/apache/flink'
WITH (
'connector' = 'kafka',
'topic' = 'flink-commits',
'properties.bootstrap.servers' = 'YOUR_KAFKA_SERVER',
'properties.group.id' = 'flink-analytics',
'scan.startup.mode' = 'earliest-offset',
'format' = 'json',
'json.fail-on-missing-field' = 'false',
'json.ignore-parse-errors' = 'true'
);
```
flink_ml_dev
```sql
REATE TABLE `flink_ml_dev` (
`date` TIMESTAMP(3),
`fromEmail` STRING,
`fromRaw` STRING,
`htmlBody` STRING,
`subject` STRING,
`textBody` STRING,
WATERMARK FOR `date` AS `date` - INTERVAL '1' DAY
)
COMMENT 'Email summary of all messages sent to dev@flink.apache.org>'
WITH (
'connector' = 'kafka',
'topic' = 'flink-mail-dev',
'properties.bootstrap.servers' = 'YOUR_KAFKA_SERVER',
'properties.group.id' = 'flink-analytics',
'scan.startup.mode' = 'earliest-offset',
'format' = 'json',
'json.fail-on-missing-field' = 'false',
'json.ignore-parse-errors' = 'true'
);
```
### Verifying the Setup
You can use each of the following statements to evaluate the expected input data as well as checking whether the setup itself is working. If you are prompted to create a session cluster for the SQL preview, then follow along and come back to the editor after it is running.
```sql
SELECT * FROM flink_commits LIMIT 10;
SELECT * FROM flink_pulls LIMIT 10;
SELECT * FROM flink_ml_dev LIMIT 10;
SELECT * FROM flink_ml_user LIMIT 10;
SELECT * FROM flink_ml_user_zh LIMIT 10;
```
Note the preview can only show the result of one query at a time. You can select the query of interest and click “Run Selection” (or press `Ctrl+Enter`) to run the selection as shown below.
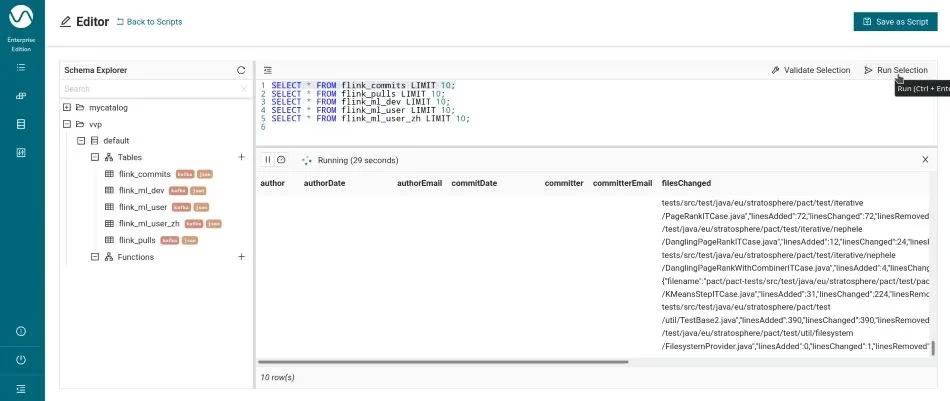
### First Analytics
Given the data sets we imported above and the power of Flink SQL, you can easily derive a lot of insights into the Flink community. I actually presented a couple of insights in my special [“A Year in Flink”](https://youtu.be/aDFv_-VHP8s) talk during [Flink Forward Global 2020](https://www.flink-forward.org/) which featured a live coding session. Let me name a few (more) examples here:
- number of distinct users/developers on the mailing list / the project, e.g. via
```sql
SELECT
TUMBLE_END(`date`, INTERVAL '365' DAY(3)) as windowEnd,
COUNT(DISTINCT fromEmail) AS numUsers
FROM flink_ml_user
GROUP BY TUMBLE(`date`, INTERVAL '365' DAY(3));
```
- emails on the user mailing list with no reply within 30 days (similarly, you can also check the number of emails which got a reply to interpret the numbers here), e.g. via
```sql
SELECT
SESSION_END(`date`, INTERVAL '30' DAY) AS windowEnd,
thread,
COUNT(*) as numMessagesInThread
FROM (
SELECT *,
REGEXP_REPLACE(
TRIM(subject),
'^(((?i)Re|AW):[ ]*)+',
'') AS thread
FROM flink_ml_user)
WHERE `date` > (CURRENT_TIMESTAMP - INTERVAL '1' YEAR)
GROUP BY SESSION(`date`, INTERVAL '30' DAY), thread
HAVING COUNT(*) < 2;
```
- commit activity per month and Flink component
```sql
SELECT
TUMBLE_END(commitDate, INTERVAL '30' DAY) AS windowEnd,
component,
SUM(linesChanged) AS linesChanged
FROM (
SELECT *,
REGEXP_EXTRACT(filename, '^('
|| '.+?(?=/src/.*|pom.xml|README.md)'
|| '|(?:flink-)?docs(?=/.*)'
|| '|tools(?=/.*)'
|| '|flink-python(?=/.*)'
|| '|flink-end-to-end-tests/test-scripts(?=/.*)'
|| '|flink-scala-shell(?=/start-script/.*)'
|| '|flink-container(?=/.*)'
|| '|flink-contrib/docker-flink(?=/.*)'
|| '|flink-table/flink-sql-client(?=/.*)'
|| '|flink-end-to-end-tests(?=/[^/]*\.sh)'
|| ')', 1) AS component
FROM flink_commits CROSS JOIN UNNEST(filesChanged) AS t)
WHERE commitDate > (CURRENT_TIMESTAMP - INTERVAL '1' YEAR)
GROUP BY TUMBLE(commitDate, INTERVAL '30' DAY), component
HAVING SUM(linesChanged) > 1000;
```
- Jira tickets created per month and Jira component
```sql
SELECT
TUMBLE_END(`date`, INTERVAL '30' DAY) as windowEnd,
component,
COUNT(*) as createdTickets
FROM (
SELECT *, `KEY`) AS component
FROM flink_ml_dev
CROSS JOIN UNNEST(
STR_TO_MAP(
COALESCE(
REGEXP_EXTRACT(textBody, '.* Components: ([^\n\r]*).*', 1),
''
),
', ', '$$$$THIS_SHOULD_NEVER_MATCH$$$$'))
)
WHERE `date` > (CURRENT_TIMESTAMP - INTERVAL '1' YEAR)
AND REGEXP(fromRaw, '"(.*)\s*\((?:Jira|JIRA)\)"\s*')
GROUP BY TUMBLE(`date`, INTERVAL '30' DAY), component
HAVING COUNT(*) > 10;
```
This seems rather complex and we will go into details further below where we see how to further simplify it with UDFs.
> **NOTE:** You can actually also make some of these requests Top-N queries to return the most active source code / Jira components, for example. This, however, will create a changelog-stream and the Ververica Platform preview only supports showing these from version 2.4 and up which will be released shortly.
As you can see, a few of these queries need some regular expressions to interpret the raw data that we got from our sources. The flavour to use here is [Java-based regular expressions](https://docs.oracle.com/javase/tutorial/essential/regex/index.html), something that your data analysts may or may not be comfortable with. It is quite powerful though and gives us access to data we would otherwise not have, e.g. the Flink source component which we derived from the filename.
## Using User-Defined Functions (UDFs)
For the remainder of this blog post, I would like to focus on leveraging user-defined functions to reduce the complexity of your SQL analytics, hide details like the Java-based regular expressions, and thus simplify usage for a wider audience.
Alternatively, you can already simplify a few things from SQL alone, e.g. by creating (temporary) views including derived fields so that your users can use these directly without knowing the details. Accounting for all derived fields may eventually become messy though. Your users can also create (temporary) views themselves but then need to know whenever the data format changes and need to adapt these views accordingly.
### UDFs for Community Data Analytics
We would like to use [user-defined functions](https://docs.ververica.com/user_guide/sql_development/functions.html#user-defined-functions-udfs) to abstract the data extraction details away. For this, our development team has written a couple of [Scalar Functions](https://ci.apache.org/projects/flink/flink-docs-release-1.12/dev/table/functions/udfs.html#scalar-functions) and put them into the `sql-functions` sub-project for us to use ([code](https://github.com/ververica/lab-flink-repository-analytics/tree/release-2.0/sql-functions) / [package](https://github.com/ververica/lab-flink-repository-analytics/packages/541979?version=2.0)). We will focus on the following subset of functions:
- `NormalizeEmailThread(subject): STRING` ([code](https://github.com/ververica/lab-flink-repository-analytics/blob/release-2.0/sql-functions/src/main/java/com/ververica/platform/sql/functions/NormalizeEmailThread.java))Takes the `subject` field from a mailing list table and returns the normalized email-thread name, e.g. stripping it from any “Re:” and removing whitespaces as above.If needed, this can be extended as desired to further rule out false-positives from e.g. mismatches in spaces in the middle of the subject or other subtleties.
- `GetSourceComponent(filename): STRING` ([code](https://github.com/ververica/lab-flink-repository-analytics/blob/release-2.0/sql-functions/src/main/java/com/ververica/platform/sql/functions/GetSourceComponent.java))Takes a `filename` (relative to the Flink repository) and returns the Flink source code component it is associated with.
- `IsJiraTicket(fromRaw): BOOLEAN` ([code](https://github.com/ververica/lab-flink-repository-analytics/blob/release-2.0/sql-functions/src/main/java/com/ververica/platform/sql/functions/IsJiraTicket.java))Takes the `fromRaw` field from the `dev` mailing list table and returns whether the message originated from a mirrored Jira interaction (rather than from a user/developer).
- `GetJiraTicketComponents(textBody): ARRAY` ([code](https://github.com/ververica/lab-flink-repository-analytics/blob/release-2.0/sql-functions/src/main/java/com/ververica/platform/sql/functions/GetJiraTicketComponents.java))Parses the `textBody` field from the `dev` mailing list table and searches for a list of components in emails that come from created Jira tickets. If `textBody` is `NULL`, the result will be `NULL` as well, if no match is found, the result will be an empty array. In order to reduce load and reduce the chance for false positive matches, we recommend filtering out non-Jira messages with the `IsJiraTicket` function above.
You can either use the binaries that you created when building the project as presented above, or use the binaries that we created with the help of Github Actions and that we publish to [Github Packages](https://github.com/ververica/lab-flink-repository-analytics/packages/541979?version=2.0).
> **NOTE:** Even though we only used Scalar Functions here, Flink SQL actually supports two more types of UDFs that can greatly extend the functionality of Flink SQL with custom logic: Table Functions can return an arbitrary number of rows, Aggregate Functions can map scalar values of multiple rows to a new scalar value (when grouping values). Even though they provide different functionality, all UDFs are integrated and can be used the same way in Ververica Platform (as described below).
### Making UDFs Available for Flink SQL in Ververica Platform
After retrieving (or building) the UDF artifact `flink-repository-analytics-sql-functions-2.0.jar`, we need to [register it with Ververica Platform](https://docs.ververica.com/user_guide/sql_development/functions.html#udf-artifacts) so that we can use it in SQL queries from then on. We will do that through Ververica Platform’s Web UI but you can also perform every of these steps in the REST API
- Navigate to the Ververica Platform Web UI → SQL → Functions
- Click “Register UDF Artifact” and select your `flink-repository-analytics-sql-functions-2.0.jar`. You should see the screen below
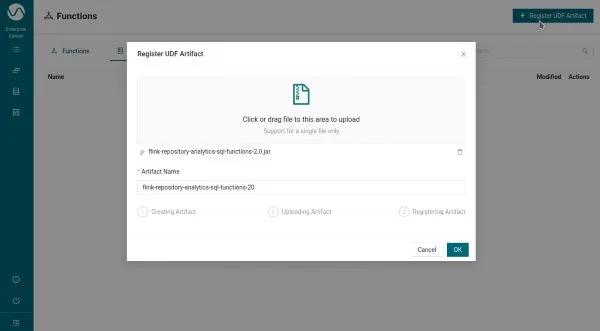
- After clicking OK, you will be taken to the next screen where you can choose which functions in your jar file you want to be made available. You can continue with the defaults (all of them) or select a subset as needed.
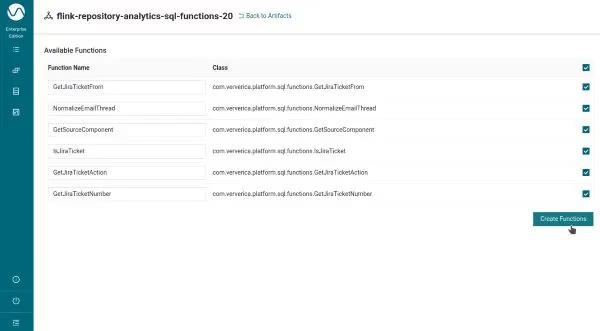
> **NOTE:** Feel free to customize the function names independently of the implementation class’ name if that one feels unnatural to SQL, and maybe use IS_JIRA_TICKET instead of IsJiraTicket, for example.
- Once created, you can go back to the SQL editor. You should see each of the registered functions in the default catalog:
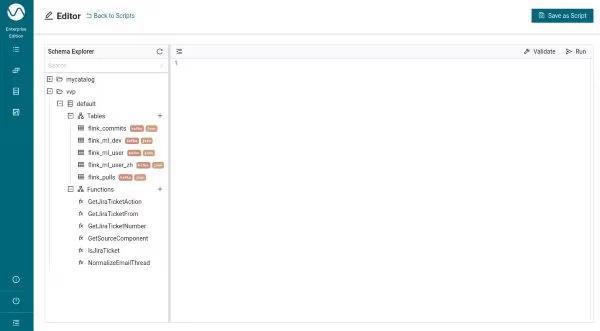
### Using UDFs in SQL Queries with Ververica Platform
Once your functions are available in a SQL catalog, you can just use them right-away. Let’s take them for a test-drive, simplifying the queries we introduced above.
**Emails on the user mailing list which haven’t received an answer within 30 days**
Since we do not have to repeat the (potentially complex) regular expression, we cannot only replace that with the UDF, but also flatten the query at the cost of repeating `NormalizeEmailThread(subject)` in two places. The query then simplifies to:
```sql
SELECT
SESSION_END(`date`, INTERVAL '30' DAY) AS windowEnd,
NormalizeEmailThread(subject) AS thread,
COUNT(*) as numMessagesInThread
FROM flink_ml_user
WHERE `date` > (CURRENT_TIMESTAMP - INTERVAL '1' YEAR)
GROUP BY SESSION(`date`, INTERVAL '30' DAY), NormalizeEmailThread(subject)
HAVING COUNT(*) < 2;
```
After putting this into the SQL editor, you can just run the query with a click (or `Ctrl+Enter`) and see the results building up in the preview pane. Note that if you write the query yourself (or create a new one), you will actually also get auto-completion for SQL keywords and functions including the UDF we registered.
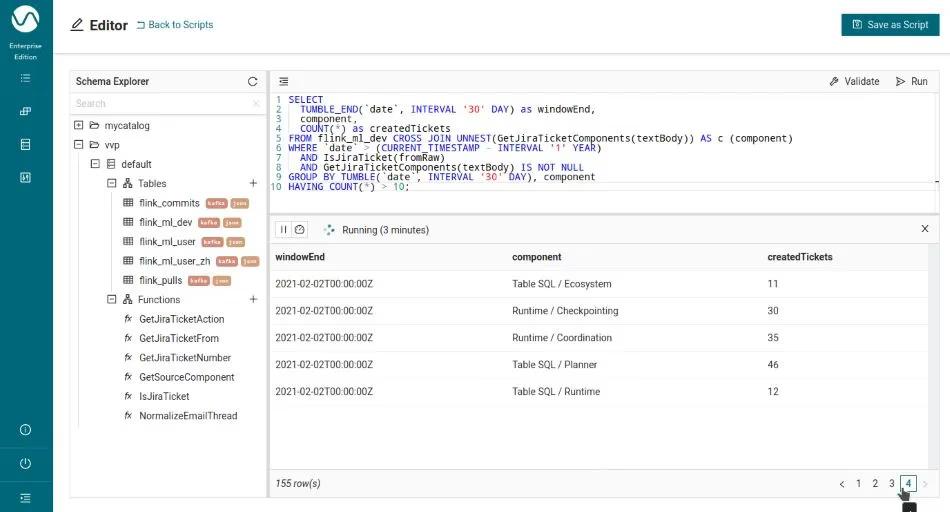
**Commit activity per month and Flink component**
This query can be simplified just like the query above, and once the UDF is available, we can concentrate on the actual analytics we want to do:
```sql
SELECT
TUMBLE_END(commitDate, INTERVAL '30' DAY) AS windowEnd,
GetSourceComponent(filename) AS component,
SUM(linesChanged) AS linesChanged
FROM flink_commits CROSS JOIN UNNEST(filesChanged) AS t
WHERE commitDate > (CURRENT_TIMESTAMP - INTERVAL '1' YEAR)
GROUP BY TUMBLE(commitDate, INTERVAL '30' DAY), GetSourceComponent(filename)
HAVING SUM(linesChanged) > 1000;
```
The results are also not surprising with most of the changed lines in `flink-runtime` as well as the `flink-table` submodules:
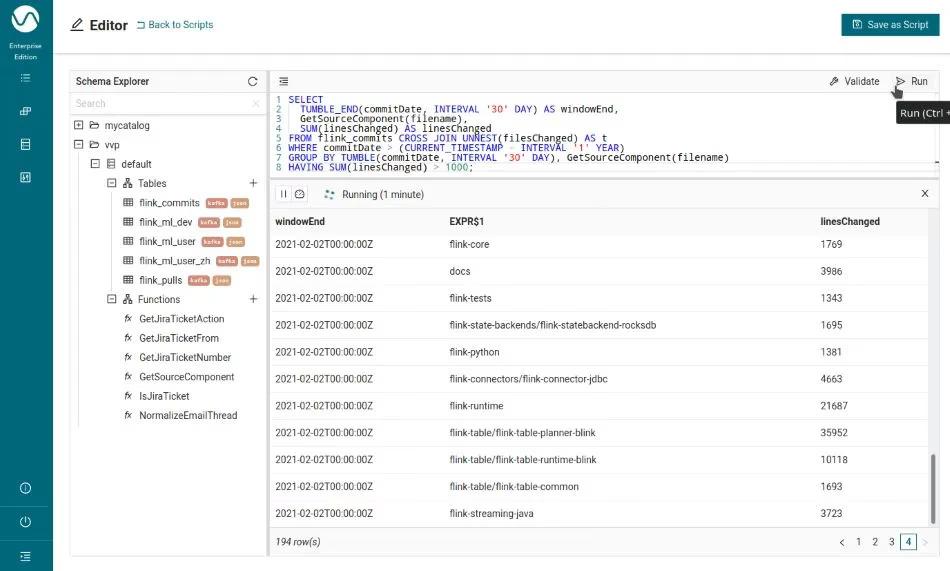
**Jira tickets created per month and Jira component**
First of all, let us digest the presented query a bit to understand it better. This is the original query:
```sql
SELECT
TUMBLE_END(`date`, INTERVAL '30' DAY) as windowEnd,
component,
COUNT(*) as createdTickets
FROM (
SELECT *, `KEY` AS component
FROM flink_ml_dev
CROSS JOIN UNNEST(
STR_TO_MAP(
COALESCE(
REGEXP_EXTRACT(textBody, '.* Components: ([^\n\r]*).*', 1),
''
),
', ', '$$$$THIS_SHOULD_NEVER_MATCH$$$$'))
)
WHERE `date` > (CURRENT_TIMESTAMP - INTERVAL '1' YEAR)
AND REGEXP(fromRaw, '"(.*)\s*\((?:Jira|JIRA)\)"\s*')
GROUP BY TUMBLE(`date`, INTERVAL '30' DAY), component
HAVING COUNT(*) > 10;
```
Although the source table `flink_ml_dev` contains a message for every created Jira ticket, this information is not structured and only available in the `textBody` field of the email such as this example:
```
Nico Kruber created FLINK-20099:
-----------------------------------
Summary: HeapStateBackend checkpoint error hidden under cryptic message
Key: FLINK-20099
URL: https://issues.apache.org/jira/browse/FLINK-20099
Project: Flink
Issue Type: Bug
Components: Runtime / Checkpointing, Runtime / State Backends
Affects Versions: 1.11.2
Reporter: Nico Kruber
Attachments: Screenshot_20201112_001331.png
```
Since this format is well-defined, we should be able to parse the ticket’s components out of the `textBody` field. For all content in the “Components” section, we use an appropriate regular expression that matches the start of the line and then extracts everything after “Components: “. What complicates things a little further is that there can actually be multiple components that are separated by commas. The [current list of built-in SQL functions](https://ci.apache.org/projects/flink/flink-docs-release-1.12/dev/table/functions/systemFunctions.html), however, does not include any that splits a string into an array of sub-strings based on a delimiter. We go around this by using `STR_TO_MAP` to create a map instead and put the substrings into its keys by using a key-value delimiter that never matches anything (alternatively, we could create our own SPLIT UDF and use that here, but once we start creating UDFs, we could just as well cover the whole use case as seen below). Finally, we can UNNEST this map with a `CROSS JOIN` as shown above.
Unfortunately, this query does not give us a perfect result either: there are a few Jira components that contain a comma themselves and break up into individual components with the code above. We are going to fix this in our UDF implementation where we have more possibilities to (iteratively) split strings up. You can find the details in the implementation of `GetJiraTicketComponents`. With that UDF and the additional help from the `IsJiraTicket` UDF to filter rows out early, the final SQL query simplifies to this:
```sql
-- Jira tickets created per month and Jira component with UDFs
SELECT
TUMBLE_END(`date`, INTERVAL '30' DAY) as windowEnd,
component,
COUNT(*) as createdTickets
FROM flink_ml_dev
CROSS JOIN UNNEST(GetJiraTicketComponents(textBody)) AS c (component)
WHERE `date` > (CURRENT_TIMESTAMP - INTERVAL '1' YEAR)
AND IsJiraTicket(fromRaw)
AND GetJiraTicketComponents(textBody) IS NOT NULL
GROUP BY TUMBLE(`date`, INTERVAL '30' DAY), component
HAVING COUNT(*) > 10;
```
If you run this query and compare the number of result rows in the preview pane with the number of the non-UDF query, you will also see that this gives fewer results which is due to the fixed matching of components that have commas in their names themselves. Feel free to browse through the set of pages at the bottom of the SQL editor to see further results. As more results come in, this list will be extended dynamically since any query you run here will be executed in streaming mode.

### Behind the Scenes
Using UDFs in Ververica Platform does feel natural and as a user of the SQL editor, you do not have to worry about the details of how this works. This is exactly how it should be. You should not feel any difference between a built-in SQL function and a user-defined SQL function and Ververica Platform aims at providing this experience. Behind the scenes, of course, a couple of things are executed in order to provide this seamless integration experience to our users.
UDFs are registered in your SQL catalogs, e.g. by uploading them through the UI as shown above. This basically creates a link between the function names and the function implementation (a class inside a `jar` file). From then on, whenever you use a UDF in the SQL editor, the platform knows which artifact to deploy alongside your SQL statements so that the Flink job they create has all the necessary code to run. This applies to the preview job that is running in a special session cluster, as well as any (long-lived) SQL streaming application you create a deployment for, through (multiple) `INSERT INTO` statements.
## Conclusion
In this blog post, we have shown how to do SQL analytics with user-defined functions (UDFs) in Ververica Platform. UDFs are a great way of sharing code across teams and projects, abstracting away complex logic, e.g. for parsing input data and extending the functionality of Flink’s SQL ecosystem in general. We have shown that, with the help of Ververica Platform, using UDFs is just as simple as using any other of Flink’s built-in functions. This allows you and your data scientists to get started easily without having to worry about the details behind the scenes. Make sure to also check our [next article](https://www.ververica.com/blog/sql-query-optimization-with-ververica-platform-2.4) that extends our SQL analytics application by exploring Flink SQL queries in Ververica Platform that produce changelog streams, such as non-windowed aggregations, top-n queries, and more.
We encourage you to try out the steps above and take a closer look into the Flink community by using Flink itself to do the analytics. You can look into the user and developer mailing lists, Flink repository commits and pull requests and initial ticket (created) information. We are curious to hear about anything new and interesting that you can find out about the community with the help of this toolkit.
---
---
title: "Autoscaling Apache Flink with Ververica Platform Autopilot"
description: "Discover how Ververica Platform's Autopilot automates the autoscaling of Apache Flink applications, ensuring optimal performance and resource utilization."
lastUpdated: 2026-07-08T05:14:58.000Z
source_url:
html: "https://www.ververica.com/blog/autoscaling-apache-flink-with-ververica-platform-autopilot"
md: "https://www.ververica.com/blog/autoscaling-apache-flink-with-ververica-platform-autopilot.md"
---
With the release of [Ververica Platform 2.2 in August 2020](https://www.ververica.com/blog/introducing-ververica-platform-2.2-with-autoscaling-for-apache-flink), we introduced Autopilot, a feature designed to automate the operationalization of Flink applications in production. With its current version, Ververica Platform automates the autoscaling of your Flink applications in a few simple easy steps. In this article, we discuss why autoscaling in Apache Flink is necessary and we take you through our journey of designing and building Autopilot in Ververica Platform. We finally discuss some of our future plans, ideas, and the functionality we plan for the next versions of Autopilot that aim to automate the many operational tasks of stream processing applications with Apache Flink.
## Why do you need an Autopilot for Apache Flink?
Before diving into the specifics of Ververica Platform Autopilot, let us take a step back and discuss why an Autopilot for Apache Flink is even necessary and why you should care about it early on. Stream processing applications are long-running and continuous by nature. As a result, the applications’ workloads will vary significantly over their lifetime due to, for example, changing load patterns (because of seasonal external factors, specific days of the week, etc.), or because one of the supported products or features might be gaining additional popularity over time, or finally due to a sudden and unexpected surge in the processing of real time data. Running your stream processing applications in production also means that your data engineering and DevOps teams need to ensure not only optimal end-to-end latency and throughput but also the optimum cost efficiency and resource utilization in terms of, for example, the number of CPU cores being utilized or the memory consumption of your stream processing applications.
Additionally, due to varying loads or data traffic in your streaming applications, you will need to keep in mind what the optimal resource utilization for your stream processing applications might be. In Figure 1 below, we explain two available options you can choose from:
1. **Overprovisioning your application to the peak traffic to ensure that specific end-to-end latency requirements are being met at all times.** This option, although resulting in optimal behavior across all expected scenarios, is neither cost-effective nor optimal in terms of resource utilization.
1. **Provisioning your streaming application for half of the expected peak load/traffic for better cost efficiency and resource footprint.** This solution, although being more efficient in terms of cost, can result in introducing backpressure during times with increased load or having data that is not immediately processed by Apache Flink and is being kept in some sort of message broker or queue for a longer period of time resulting in breaking your latency or throughput SLAs.
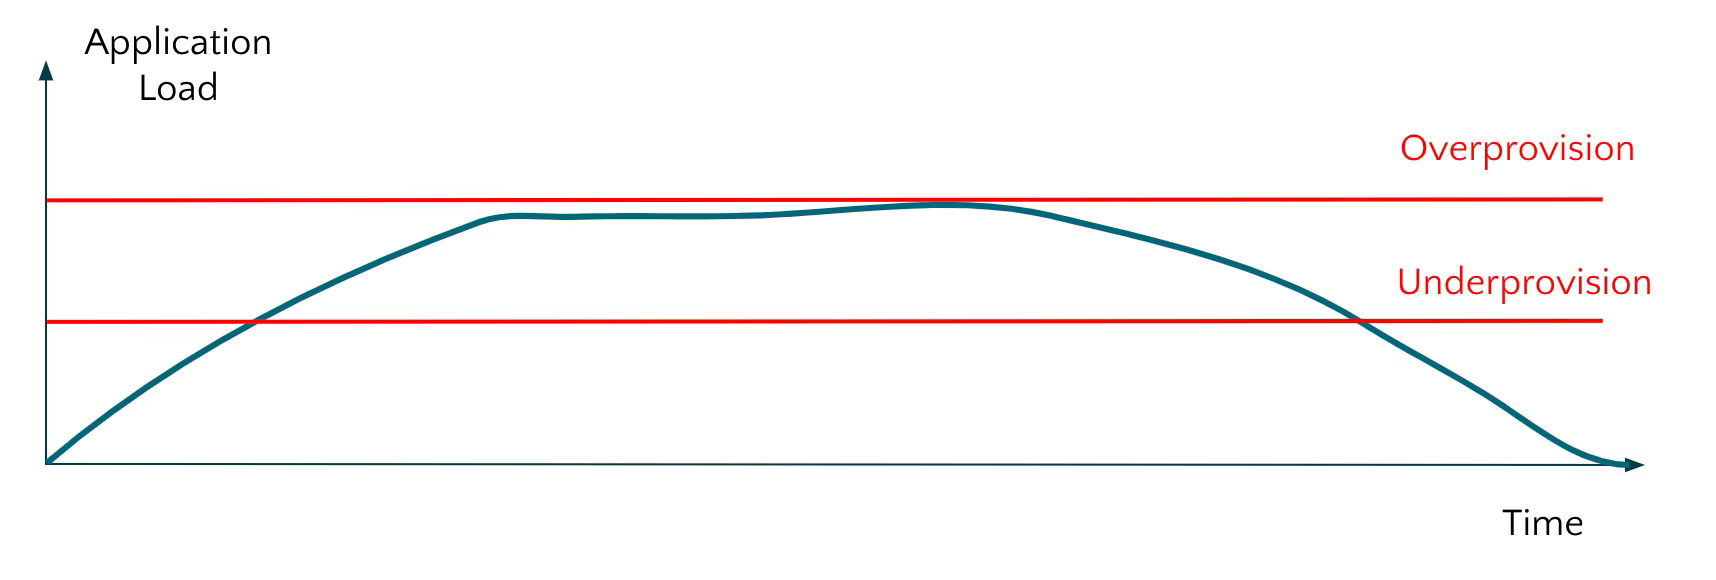
Because of all the above, having a mechanism that can automatically adjust and scale (upgrade or downgrade) your Flink applications in an automatic manner is paramount and a ‘must-have’ to ensure optimal application performance. To overcome this challenge of successfully scaling your Flink applications over time, Ververica Platform Autopilot comes to the rescue! Autopilot dynamically and automatically scales your Apache Flink application to ensure that specific SLAs are being met with an optimal resource utilization/footprint. Let us now describe the process of scaling your Flink applications, when you should consider scaling your application and where you can scale your application to.
## How to scale your Flink Applications
When you want to scale/rescale your stateful stream processing application in Apache Flink, you will need to perform the following steps:
1. Stop your application and trigger a savepoint
1. Write your application state — store in the savepoint — in a distributed file system or object store
1. Load the state from the distributed file system and reassign it to the scaled operators.
For more information and a deep-dive into rescaling application state in Apache Flink, you can refer to this post [here](https://flink.apache.org/features/2017/07/04/flink-rescalable-state.html). In general, transferring application state to and from operators are expensive operations that should ideally be minimized to ensure optimal resource utilization in your technology stack.
When designing and building Ververica Platform Autopilot we looked at the granularity of the scaling process with the aim to minimize the overall scaling steps. In our design process we had to choose among three options:
- **Operator scaling**: The job graph of your Flink application comprises multiple operators, making them the lowest, most granular level of your application. We tried scaling the operators of the graph (illustrated in Figure 2 below) but were faced with some significant downsides, namely breaking the operator chaining which led to multiple operators working on the same task, resulting in inter-process communication which we wanted to avoid.
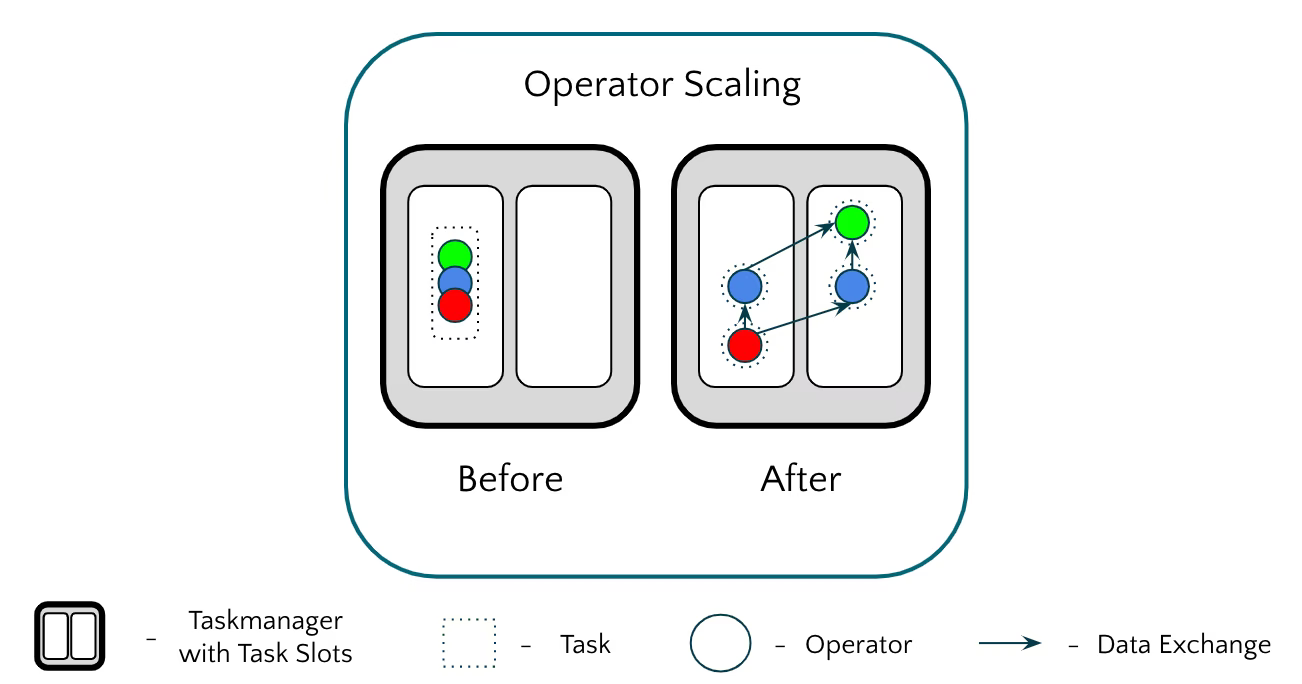
- **Task scaling**: The second alternative we looked into was task scaling in a Flink application. Although we initially saw some increased scaling and performance, we were later on faced with task slots being unbalanced which can result in task managers being unevenly balanced that can consequently result in severe scheduling problems among task managers.
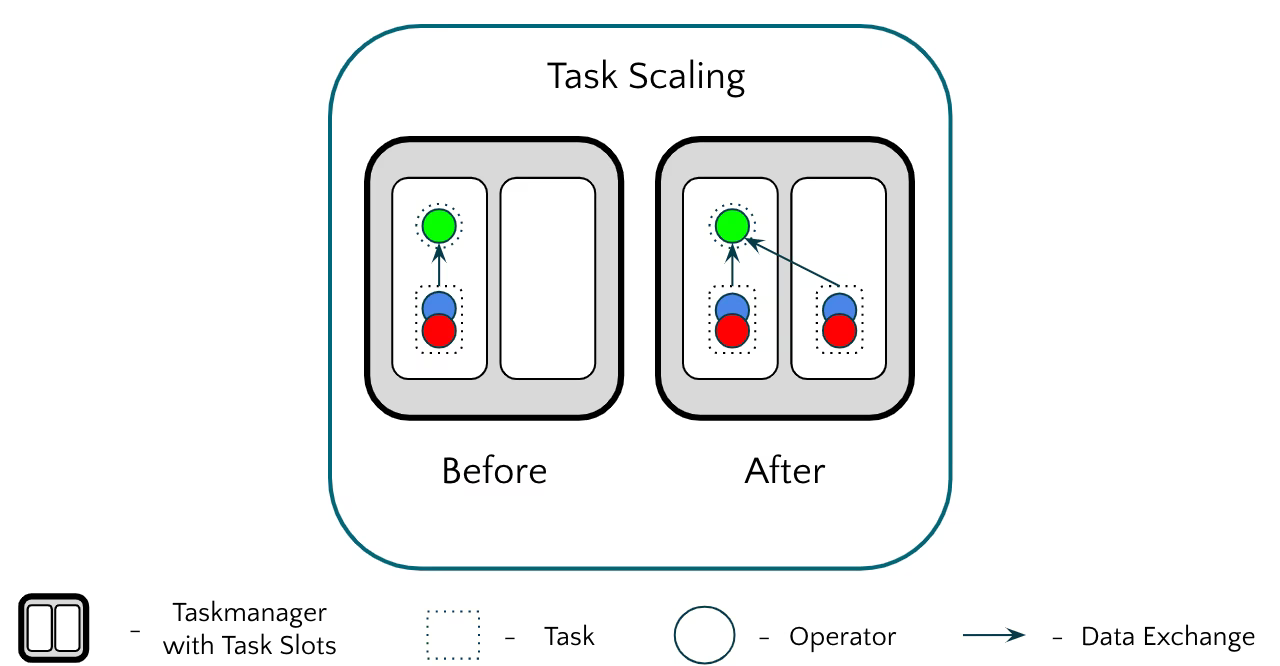
- **Pipeline scaling**: The third and final alternative we looked into was scaling the entire pipeline. With pipeline scaling, we were able to achieve an evenly-balanced load across tasks and operators. In contrast to task scaling, we might create unnecessary non-load intensive tasks that can be neglected due to the low resource footprint.
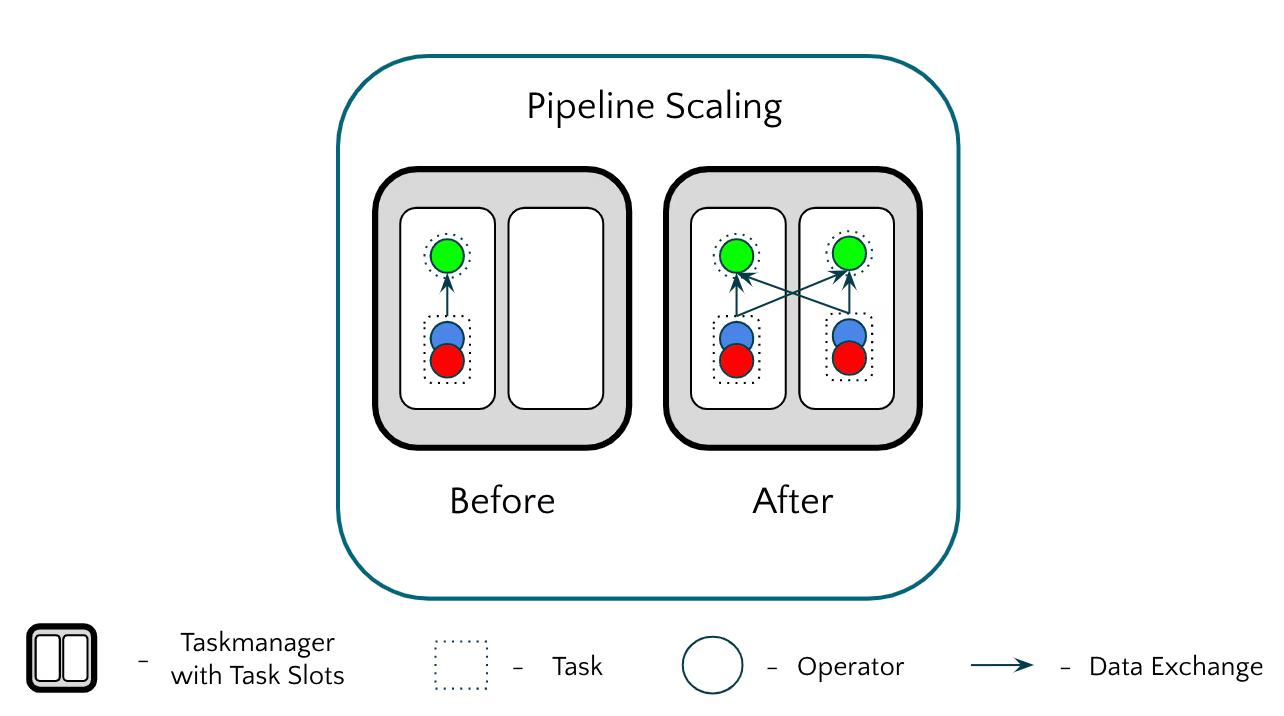
## When to scale your Flink Applications
Now that we have established our preferred mechanism for scaling a Flink application in Ververica Platform it is time for us to explore when is the right time to scale a Flink application. For this, we firstly looked at the CPU utilization of the application. At first sight, we thought that if the CPU utilization is increasing or decreasing we are getting a good overview of the current state of the application. This proved to be wrong because CPU utilization seems to be rather difficult to measure in virtualized environments and the async I/O is not always represented in the CPU utilization metrics because other systems might be covering the backpressure.
As a solution, we looked at the idle TimeMsPerSecond metric. With this metric, an operator is essentially counting the time that it has remained idle (hasn’t processed any events or performed any other activity). With the idle TimeMsPerSecond metric, we can now understand the capacity of each task in our pipeline for every given point-in-time. However, the idle TimeMsPerSecond metric has specific limitations, since you cannot compute and directly derive the appropriate parallelism for scaling your application. As the name of the metric already suggests, only numbers between 0 and 1000 are emitted. Taking for example the increasing load in a pipeline, this might lead to all operators in the pipeline reporting 0. In such an instance, the Autopilot cannot track any gradual increase in the load and therefore cannot determine the needed parallelism. A way to alleviate this could be using some probing technique which is very inefficient due to the high number of rescaling operations.
## Where to scale your Flink Applications
We have now identified that the idleTimeMSperSecond metric is useful, but needs to be used in conjunction with a different metric that can provide the information we need to confirm where the application should scale to. For this, we used the connector metrics stored in the Kafka connector, as an example. We specifically looked at Apache Kafka’s internal metric describing the lag. What lag means in Kafka is the number of records that are stored in Apache Kafka and are not being processed immediately. Using this metric can help us define a backpressure-free state in our application by ensuring that the lag metric in Kafka is either remaining stable or has a value of zero.
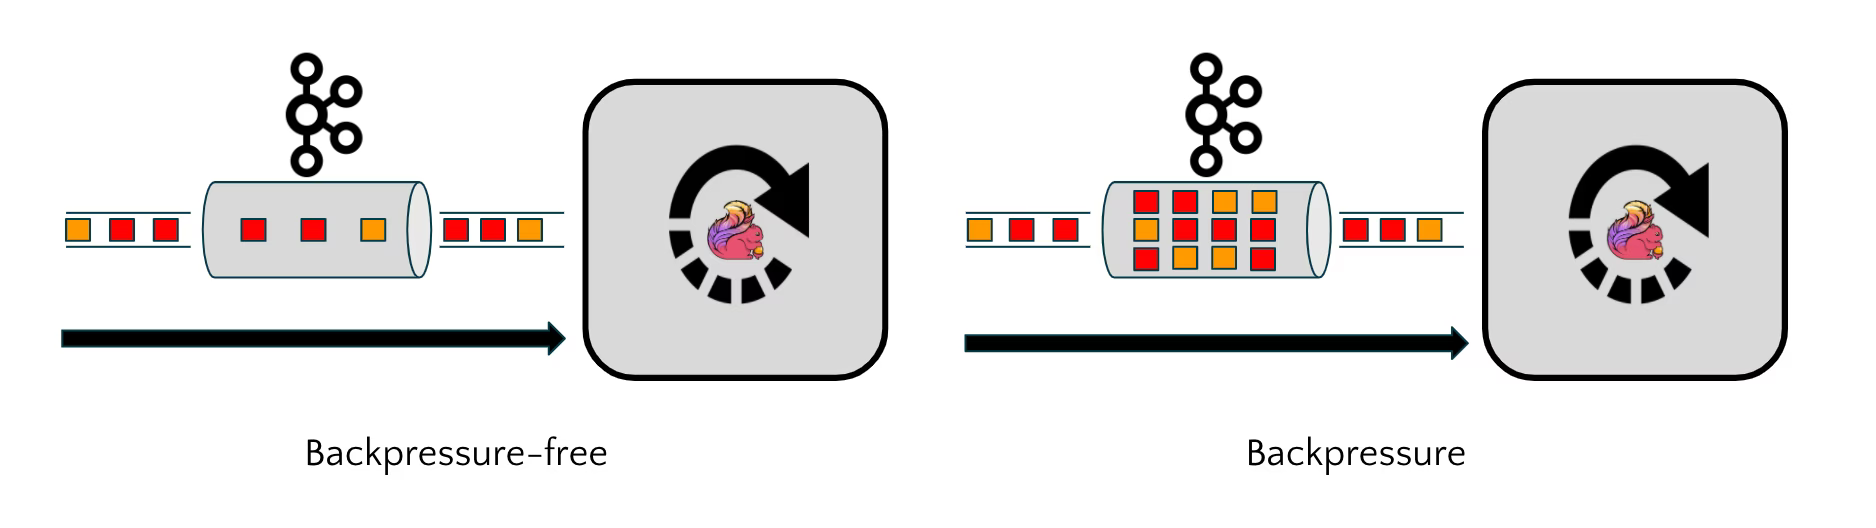
## Ververica Platform Autopilot future direction
What you can now experience in Ververica Platform is the Ververica Platform Autopilot cockpit that gives you some real time insight into how each of the sources is impacting the overall resource utilization of your Flink application. Based on this information you can identify the capacity of each of the sources, how much you need to scale your application and what is its current state. Looking at potential developments for the Ververica Platform Autopilot, we are going to incorporate more connector metrics — beyond Apache Kafka — in upcoming releases. As the Apache Flink community is working on [FLIP-27](https://cwiki.apache.org/confluence/display/FLINK/FLIP-27%3A+Refactor+Source+Interface) that refactors the source interface and [FLIP-33](https://cwiki.apache.org/confluence/display/FLINK/FLIP-33%3A+Standardize+Connector+Metrics) which introduces standardized connector metrics, we expect to have some generalized notion of lag for all connectors in Apache Flink that we can also leverage for the Ververica Platform Autopilot. Additionally, upcoming releases of Ververica Platform are going to not only include horizontal scaling but also vertical scaling of your Flink applications, meaning that you no longer have to continue adding task managers to your graph and decreasing the parallelism (something not ideal in many cases because of increased cost for you virtual machines) but rather spawn larger task managers in the first place. In the long term, we are also working on giving our customers the option to dynamically scale their entire pod instead of task managers and also minimize the downtime of your application by ensuring that new task managers can be added to the job graph before scaling up your Flink application.
For a deep dive into Ververica Platform Autopilot, you can check our [documentation](https://docs.ververica.com/user_guide/application_operations/autopilot.html).
---
---
title: "Real-Time Performance Monitoring with Flink SQL: AdTech Use Case"
description: "Discover how to monitor ad campaign performance in real-time using Flink SQL to calculate click-through rates from impressions and clicks without coding."
lastUpdated: 2026-07-07T11:42:27.000Z
source_url:
html: "https://www.ververica.com/blog/real-time-performance-monitoring-with-flink-sql-ad-tech-use-case"
md: "https://www.ververica.com/blog/real-time-performance-monitoring-with-flink-sql-ad-tech-use-case.md"
---
## Background
Advertising Technologies (Ad Tech) is a collective name that describes systems and tools for managing and analyzing programmatic advertising campaigns. The goal of digital advertising is to reach the largest number of relevant audience members possible. Therefore, ad tech is intrinsically related to processing large volumes of data.
In this blog post, we'll look into how to correlate two streams of events — ad servings (so called impressions) and clicks and calculate an important ad tech metric — a click-through rate (CTR). Our calculations will be performed based on the in-flight data using Apache Flink’s horizontally scalable execution engine. We will focus on getting the results without writing any code in Java or Scala, but rather by completely relying on SQL.
In a typical scenario, a placement of an ad is performed via a mechanism called Real-Time Bidding. In essence, Real-Time Bidding is an auction where a multitude of participants compete for displaying a banner or a video (collectively called a _creative_) to a specific end user. During this process, demand-side platforms (DSPs) get offerings to show advertisements to users, identified by their device IDs and reply with their bets.
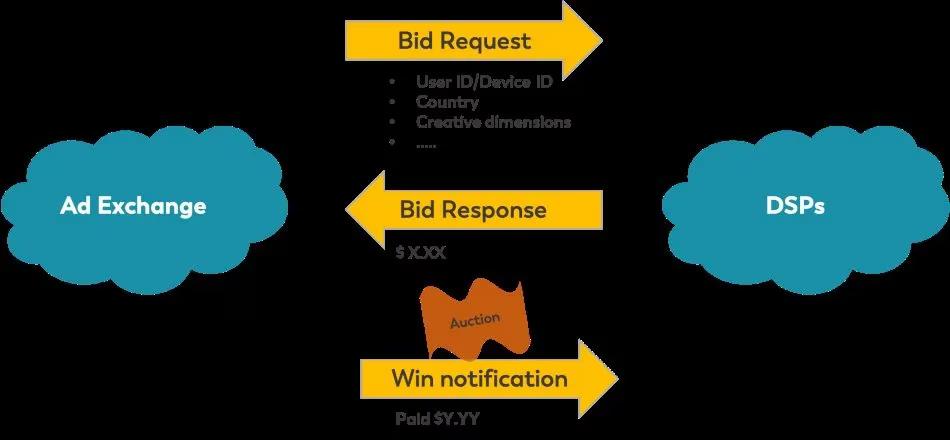
Tracking which impressions were shown and which of them were clicked on is one of the key tasks in digital advertising technologies.
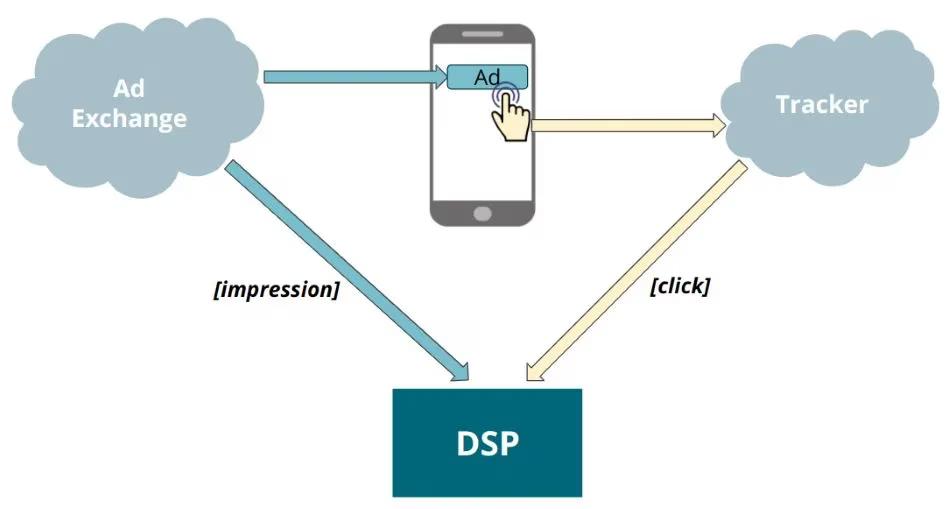
Although the process of placing advertisements is largely automated, there is usually still a significant degree of manual control employed by advertisement campaign managers and business analysts. Frequently, the definition of a campaign and selectors for the audience, such as demographics, country of origin as well as campaign’s performance criteria are defined manually. Closely monitoring the performance of a campaign and adjusting certain parameters might be necessary, especially during an early after-launch phase - the time when assumptions are being validated.
## Why Stream Processing?
The task of getting insights into large volumes of data was traditionally addressed by utilizing batch processing. This approach comes into contradiction with the highly dynamic nature of the digital advertising business. It is critical to get insights in real time - waiting for an hour or more for a periodic batch job to finish processing raw data and meanwhile depleting the budget due to wrong initial parameters of a campaign is highly undesirable. Moreover, for any metric that relies on correlating two subsequent events, batch processing will not deliver correct results for occurrences that lie on the opposite sides of the batch “cut-off” and, hence, get processed by two different batch jobs.
## Why Flink SQL?
The task of monitoring a campaign is typically performed by a data- or a business analyst. Due to the dynamic nature of the business, potential ad-hoc integrations with new data feeds, addition of new dimensions to the existing data streams and other similar adjustments can be expected. In this scenario, it is desirable to remove the dependency of data analysts on data engineers in performing their day-to-day tasks. In order to achieve that, a flexible toolset with a low barrier of adoption is required. SQL is the lingua franca of data analysis and its knowledge is widespread. Running SQL statements in Flink allows you to utilize the power of Flink’s horizontally-scalable stream processing engine without the requirement of being a Java or a Scala developer. It makes it possible to easily tap into large volumes of raw in-flight data and facilitate creation of interactive custom dashboards in a self-service manner.
## Hands-on
In our example we are going to work with two streams of data. First, those streams are registered as tables by defining their schema and table options.
The first stream is the stream of _impressions_. Each of these events indicates a win in the Real-Time Bidding auction and successful demonstration of a _creative_ to the user. It contains such details as _creative's_ dimensions, a country code, and an id of the advertising campaign.
```sql
CREATE TEMPORARY TABLE `impressions` (
bid_id VARCHAR NOT NULL,
`timestamp` VARCHAR,
serve_time AS
TO_TIMESTAMP(`timestamp`, 'EEE MMM dd HH:mm:ss zzz yyyy'),
campaign_id INT,
creative_dimensions VARCHAR,
country_code VARCHAR(2),
WATERMARK FOR serve_time AS serve_time - INTERVAL '5' SECOND
)
WITH (
'connector' = 'kafka',
'format' = 'json',
'properties.bootstrap.servers' = 'kafka.svc:9092',
'properties.group.id' = 'impressions',
'scan.startup.mode' = 'latest-offset',
'topic' = 'impressions-ingest'
);
```
In this example, events are consumed from Kafka in JSON format. See [this](https://www.ververica.com/blog/data-pipelines-with-flink-sql-on-ververica-platform) blog post for various other connectors and data formats supported by Ververica Platform.
WATERMARK FOR serve_time AS serve_time - INTERVAL '5' SECOND means that we can tolerate out-of-order delivery of events in the timeframe of 5 seconds and still produce correct results.
> **NOTE:** TEMPORARY modifier means that this schema definition will not be persisted in the catalog. It is a convenient way to start working with new schemas without having to use ALTER statements for changes.
One of the most important outcomes that we can track after displaying an ad is a click on the creative.
```sql
CREATE TABLE TEMPORARY `clicks` (
correlation_id VARCHAR NOT NULL,
`timestamp` VARCHAR,
click_time AS
TO_TIMESTAMP(`timestamp`, 'EEE MMM dd HH:mm:ss zzz yyyy'),
tracker VARCHAR,
WATERMARK FOR click_time AS click_time - INTERVAL '5' SECOND
)
WITH (
'connector' = 'kafka',
'format' = 'json',
'properties.bootstrap.servers' = 'kafka.svc:9092',
'properties.group.id' = 'clicks',
'scan.startup.mode' = 'latest-offset',
'topic' = 'clicks-ingest'
);
```
The correlation_id of the clicks stream corresponds to the bid_id field of the impressions stream (Figure 2). This will be the basis for joining respective data streams and calculating the Click-Through Rate (CTR). But before we look into the CTR calculation, let’s first start with something simpler to check that all of the moving parts are in the right place.
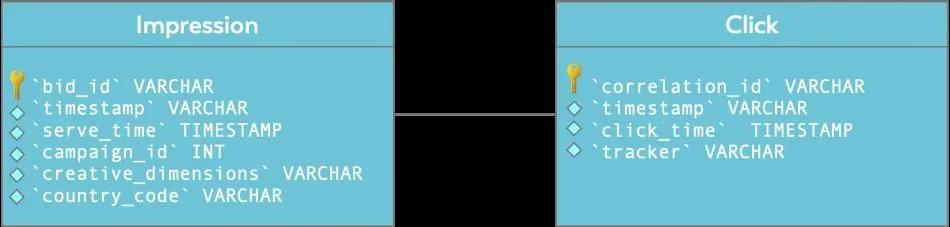
The following query calculates the number of impressions within a [tumbling window](https://docs.ververica.com/user_guide/sql_development/queries.html#group-by-window-aggregation) of 60 seconds broken down by campaign_id and creative_dimensions:
```sql
SELECT
campaign_id,
creative_dimensions,
TUMBLE_ROWTIME(event_time, INTERVAL '60' SECOND)
AS window_end, COUNT(*) AS c
FROM impressions
GROUP BY
TUMBLE(event_time, INTERVAL '60' SECOND),
campaign_id,
creative_dimensions
ORDER BY window_end, c DESC;
```
Executing this query in Ververica Platform will display the respective breakdown in its live results preview:
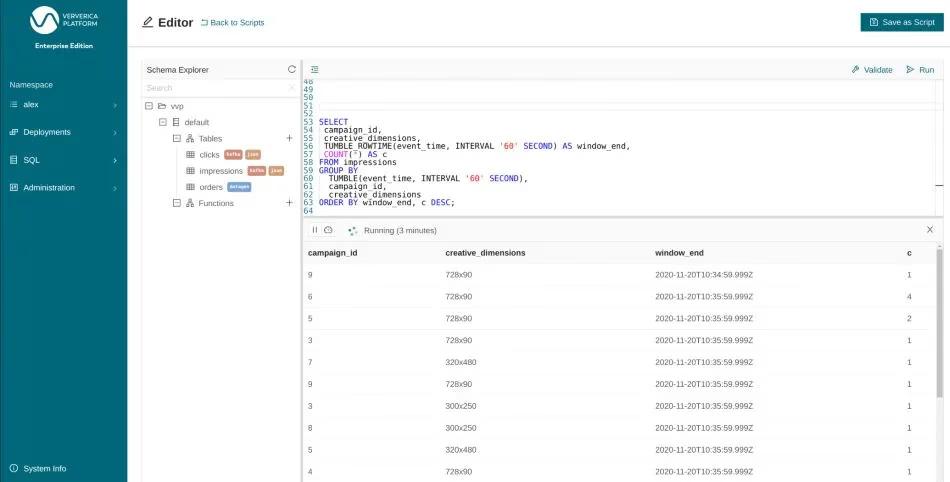
## Calculating Click-Through Rate (CTR)
CTR is defined as the relation between the number of clicks to the overall number of served impressions. From this definition it becomes clear that we need to join two streams together:
```sql
CREATE TEMPORARY VIEW impressions_with_clicks_raw AS
SELECT
i.bid_id,
i.campaign_id,
i.country_code,
i.creative_dimensions,
i.`event_time` AS serve_time,
c.tracker,
c.`timestamp` AS click_time,
CASE
WHEN c.`timestamp` IS NULL THEN FALSE
WHEN c.`timestamp` IS NOT NULL THEN TRUE
END AS clicked
FROM impressions i
LEFT OUTER JOIN clicks c
ON i.bid_id = c.correlation_id AND
c.event_time BETWEEN i.event_time AND
i.event_time + INTERVAL '2' MINUTE ;
```
This query will produce one row for each impression and match it with a click (if any) that was observed within two minutes after serving the ad.
> **NOTE:** Creation of a VIEW is a logical operation that makes combining multiple queries easier. It does not result in the actual execution of the job until it is referenced elsewhere. When used as part of another query, Flink’s SQL runtime will generate the execution plan and perform optimizations as if it was one joint nested query. Temporary views are used in this blog post for simplifying the description, they are optional and the same results can be produced without them.
A view can be queried just like a table:
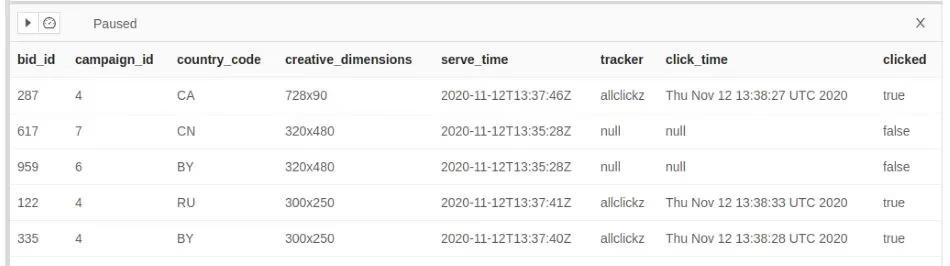
The next step is to aggregate raw data and count the number of impressions with and without clicks broken down by the relevant dimensions (campaign_id, country_code in this example):
```sql
CREATE TEMPORARY VIEW impressions_with_clicks_5m AS
SELECT
TUMBLE_ROWTIME(serve_time, INTERVAL '5' MINUTE) AS window_end,
campaign_id,
country_code,
clicked,
COUNT(*) AS cnt
FROM impressions_with_clicks_raw
GROUP BY
TUMBLE(serve_time, INTERVAL '5' MINUTE),
campaign_id,
country_code,
clicked;
```
We use [TUMBLE](https://docs.ververica.com/user_guide/sql_development/queries.html#tumble) window to group and count elements within five-minute intervals. This results in a reduced and predictable number of updates compared to the raw impressions and clicks data:
#campaign_ids * #country_codes * 2 (clicked flag) every 5 minutes
```sql
SELECT * FROM impressions_with_clicks_5m;
```
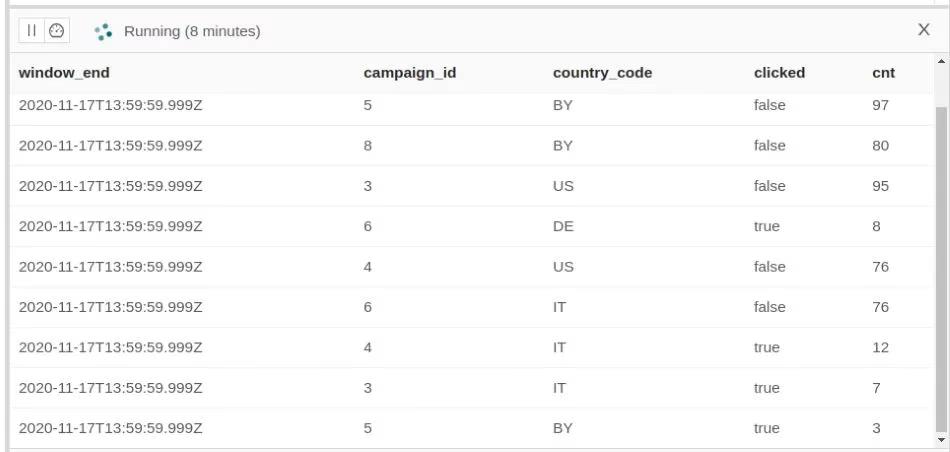
As the last step, we need to perform a self-join to calculate the final click-through rates per campaign per country:
```sql
CREATE TEMPORARY VIEW ctr_campaigns AS
SELECT
ic1.country_code,
ic1.campaign_id,
ic1.cnt AS `clicks_count`,
ic2.cnt AS `no_clicks_count`,
CAST(((100.0*ic1.cnt/(ic1.cnt + ic2.cnt)))
AS DECIMAL(8,4) ) AS ctr
FROM impressions_with_clicks_60s AS ic1
JOIN impressions_with_clicks_60s AS ic2
ON ic1.window_end = ic2.window_end AND
ic1.country_code = ic2.country_code AND
ic1.campaign_id = ic2.campaign_id AND
ic1.clicked = TRUE AND
ic2.clicked = FALSE;
```
ic1.clicked = TRUE AND ic2.clicked = FALSE removes duplicates caused by the self-join.
```sql
SELECT * FROM ctr_campaigns;
```
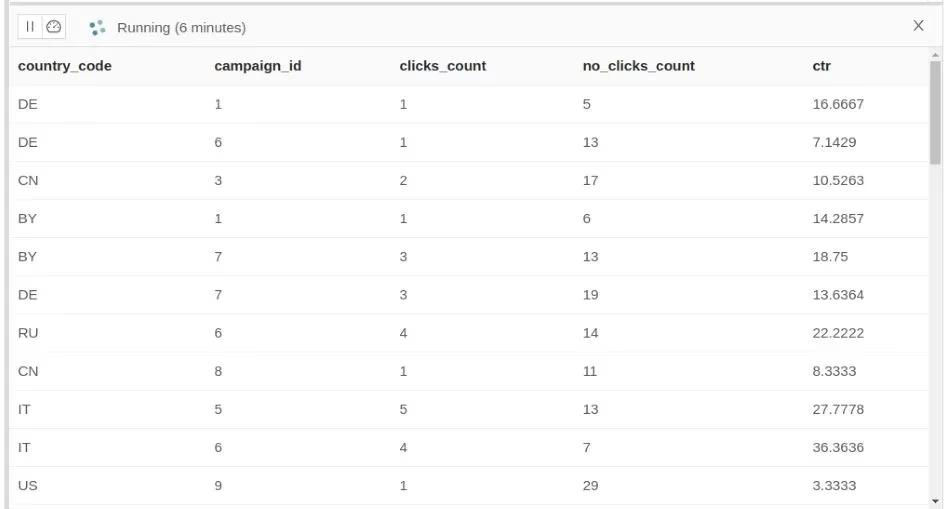
At this point we are ready to build our dashboard. According to the definition, impressions_with_clicks_5m produces updates every 5 minutes. These updates trigger the corresponding emission of the results by the ctr_campaigns query with the same cadence. Skipping the window_end field allows to interpret them as in-place, most recent results of the CTR calculation. In order to make those updates available to the external systems, such as BI tools, we can write them into a table that is backed by a database.
```sql
CREATE TEMPORARY TABLE `ctr_dashboard` (
`country_code` VARCHAR(2),
`campaign_id` INT,
`clicks_count` BIGINT NOT NULL,
`no_clicks_count` BIGINT NOT NULL,
`ctr` DECIMAL(8, 4) NOT NULL,
PRIMARY KEY (`country_code`, `campaign_id`) NOT ENFORCED
)
WITH (
'connector' = 'jdbc',
'url' = 'jdbc:postgresql://postgres.databases.svc:5432/adtech',
'table-name' = 'ctr_dashboard_campaigns',
'username' = 'flink',
'password' = '12345'
);
```
> **NOTE:** A corresponding table has to be pre-created in the database itself. Flink’s DDL statements only store the table metadata in the catalog, but do not produce side-effects in external systems (e.g. table/topic/index creation).
```sql
INSERT INTO ctr_dashboard
SELECT
ic1.country_code,
ic1.campaign_id,
ic1.cnt AS `clicks_count`,
ic2.cnt AS `no_clicks_count`,
CAST(((100.0*ic1.cnt/(ic1.cnt + ic2.cnt))) AS decimal(8,4) )
AS ctr
FROM impressions_with_clicks_5m as ic1
JOIN impressions_with_clicks_5m as ic2
ON ic1.window_end = ic2.window_end
AND ic1.country_code = ic2.country_code
AND ic1.campaign_id = ic2.campaign_id AND ic1.clicked = TRUE
AND ic2.clicked = FALSE;
```
When executing an INSERT INTO statement in Ververica Platform you will be presented with the following dialog which leads to a creation of a long-running Flink SQL Deployment:
A Deployment is Ververica Platform’s abstraction of a long-running service or application.

After letting the Deployment run for some time we can observe the results in the ctr_dashboard_campaigns table.
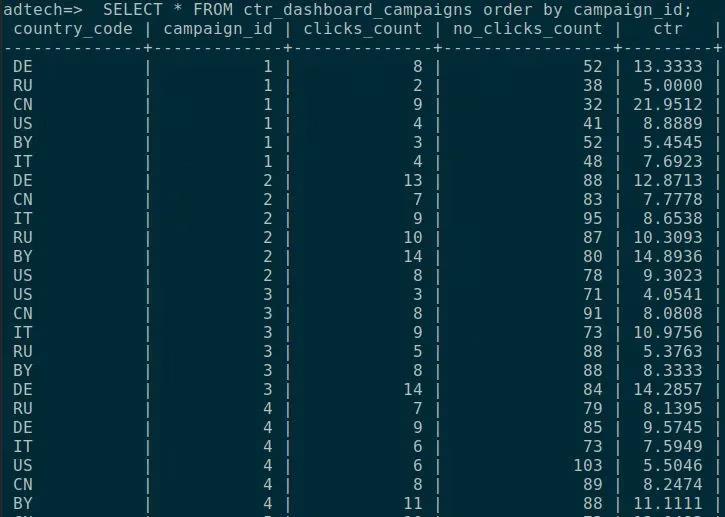
Definition of the PRIMARY KEY on the country_code and campaign_id fields allows to show the most recent CTR values for combinations of these dimensions, updated roughly every 5 minutes. By that point, all incoming raw impressions and clicks events have been evaluated, efficiently converted by Flink into the relevant metric and can now easily be presented in a BI tool of your choice
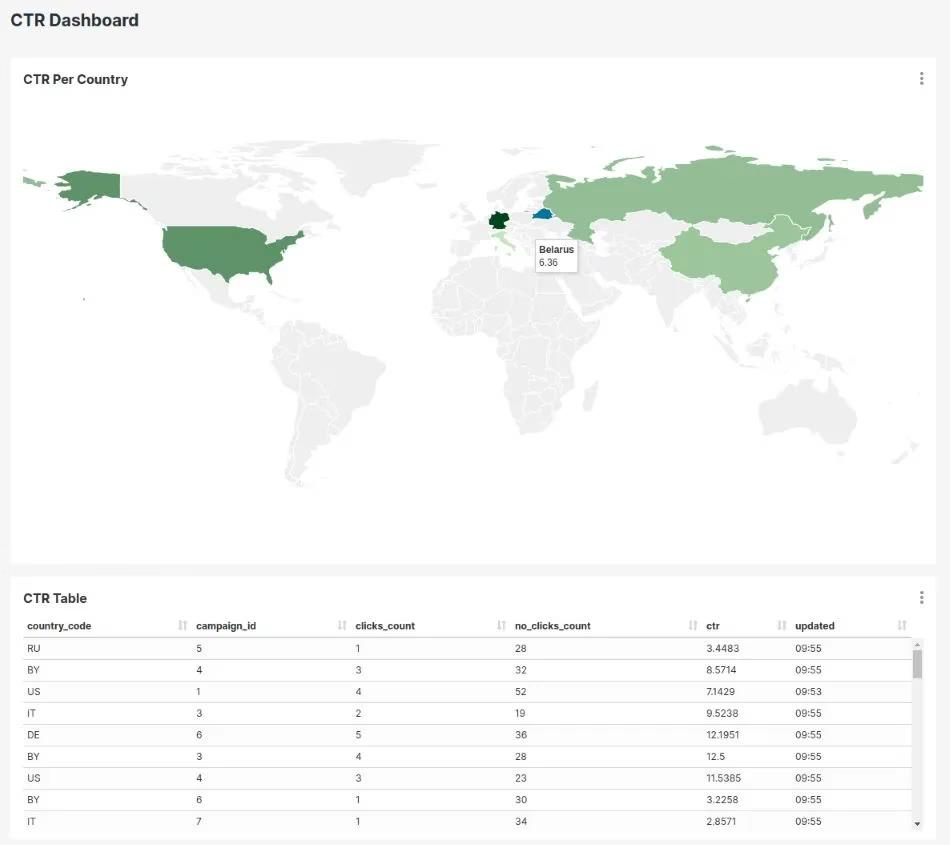
## Performance considerations
A demand-side platform participating in the Real-Time Bidding auction can receive traffic in the order of 100 000s of requests per second. Depending on the campaign size and the bidding strategy it can result in a very significant number of impressions per second. Flink allows to handle this large volume of data in-flight, without having to “bombard” the SQL database which analysts use for creating dashboards with raw events. At the same time, they can use the same language and mental approach as if they had access to the raw data stored in the database.
An important aspect of Flink’s approach is the clear separation it makes between processing, table persistence (via connectors e.g. Kafka or MySQL), and state fault tolerance (snapshots to blob storage). Flink SQL’s fault tolerance is based on the same lightweight checkpointing [mechanism](https://ci.apache.org/projects/flink/flink-docs-stable/learn-flink/fault_tolerance.html) used for non-SQL Flink applications. In contrast to KSQL, for example, Apache Flink does not need to rely on additional topics or partitions on your Apache Kafka cluster to ensure fault-tolerance of the running queries. The load on the systems that hold your in-flight business data is thereby kept to a minimum. This approach is arguably more suitable for self-service systems, where creation of large volumes of actively-replicated state upon submission of an arbitrary user query might present an operational challenge.
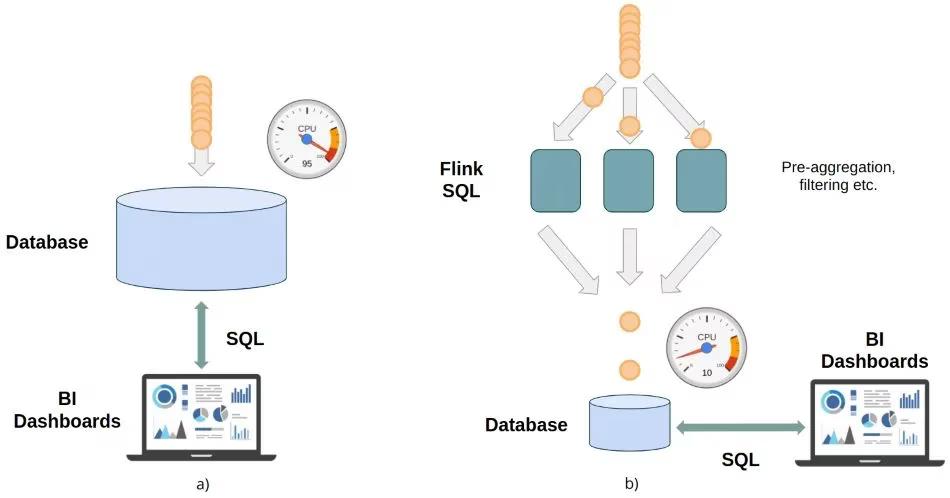
## Why Ververica Platform?
The latest release of Ververica Platform brough native support for Flink SQL. It includes, among other things, zero-configuration data [catalog](https://docs.ververica.com/user_guide/sql_development/catalogs.html#ververica-platform-s-built-in-catalog), convenient web-based editor for creating SQL scripts, [UDF](https://docs.ververica.com/user_guide/sql_development/functions.html) support and interactive results preview.
On top of that, Ververica Platform supports multi-tenancy, which is a key requirement for facilitating self-service workflows as described above. In combination with Kubernetes namespaces and resource quotas you can easily control how much computational capacity each team or even individuals within your organization can acquire for running their SQL queries.
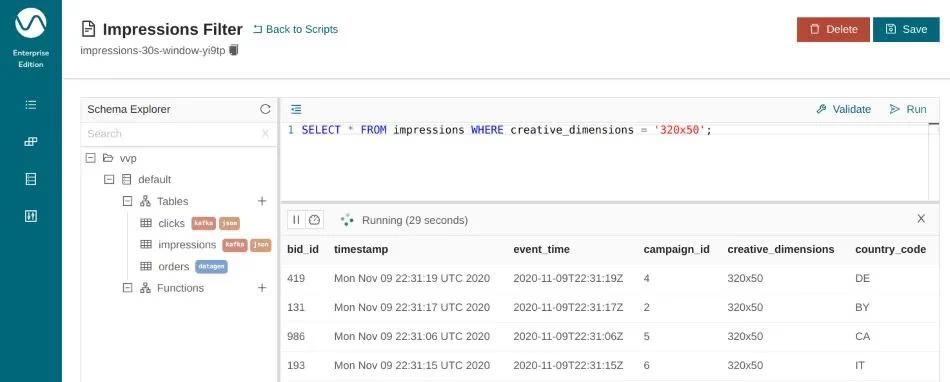
## Conclusion
While this blog post focused on Flink SQL applied to an Ad Tech use case, the general themes are applicable to a wide range of scenarios with any combination of the following requirements:
- Getting insights into data in real-time
- Lowering the barrier for accessing real-time data and performing analytics on it in your organization
- Reducing the load on traditional databases
---
---
title: "Introducing Ververica Platform 2.2 with Autoscaling for Apache Flink"
description: "Discover the new Ververica Platform 2.2, featuring autoscaling for Apache Flink and enhanced support for Flink 1.11, transforming real-time data processing."
lastUpdated: 2026-07-07T10:33:22.000Z
source_url:
html: "https://www.ververica.com/blog/introducing-ververica-platform-2-2-with-autoscaling-for-apache-flink"
md: "https://www.ververica.com/blog/introducing-ververica-platform-2-2-with-autoscaling-for-apache-flink.md"
---
> **TIP:** The latest release of Ververica Platform introduces autoscaling for Apache Flink and support for Apache Flink 1.11
We are very excited to announce the release of Ververica Platform 2.2, the enterprise stream processing platform by the original creators of Apache Flink.
Ververica Platform enables every enterprise to continuously derive immediate insight from its data and better serve its customers in real-time. It is powered by the leading stream processing framework, [Apache Flink](https://flink.apache.org/), and provides an integrated, enterprise-ready solution for secure, scalable, and cost-effective stateful stream processing and streaming analytics.
Let us focus on what's new in Ververica Platform 2.2: Ververica Platform 2.2 comes with two major features, [autoscaling of Apache Flink applications](https://ververica.com/blog/autoscaling-apache-flink-with-ververica-platform-autopilot) and support for Apache Flink 1.11, as well as a number of minor improvements.
Besides working on the functionality for this release, the team at Ververica has already put countless development hours into our integrated solution for Flink SQL. If you are interested to learn more about Flink SQL on Ververica Platform.
## Ververica Platform Autopilot: Autoscaling for Apache Flink
Stream processing applications are by nature long-running, continuous applications. As such, their workload usually varies greatly over their lifetime due to, for example,
- daily, weekly or seasonal load patterns
- higher or lower popularity of a service, feature or product over its lifetime
- processing a surge of data
When a stream processing application cannot keep up anymore, records will start to pile up in your streaming storage system (e.g. Apache Kafka® or Apache Pulsar®) and your application will process records with increasing delay. Consequently, you might break your latency objectives, drop end user requests, or lose data that is not consumed within its retention time. Operators of such systems will, on the one hand, continuously monitor the application and, on the other hand will err on the side of caution and overprovision the application as the cost of underprovisioning often exceeds the cost of overprovisioning. The result is a wastage of human and computational resources.
## Autoscaling Apache Flink
Ververica Platform aims to tackle this challenge for stream processing with Apache Flink. More specifically, it continuously monitors your Apache Flink applications and tries to converge to a resource configuration that is backpressure-free while also minimizing excess capacity.
When data rates increase, Ververica Platform Autopilot — available in the [Stream and River Editions](https://ververica.com/pricing-editions) of Ververica Platform — will scale out your application so that it continues to keep up with all of its sources. In such a backpressure-free configuration, latency is automatically kept to a minimum.
When data rates decrease, Autopilot will scale in based on the utilization of your pipeline while still maintaining a backpressure-free configuration.
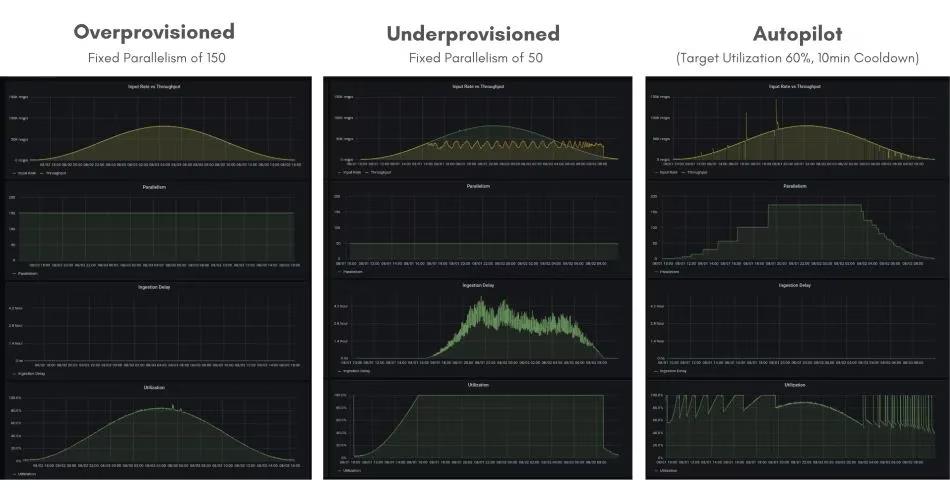
When developing a new stream processing application it is initially very hard to define parallelism and resource limits that sustain the anticipated throughput. With Autopilot this becomes a much easier task: start your application with parallelism of 1 (or a best guess) and let Autopilot converge to a resource efficient, backpressure-free state.
## Future Work
This release only marks the beginning of our efforts in the area of Flink-specific autoscaling and auto-configuration features. There are a lot of exciting ideas and approaches to be pursued mid-term, but three specific improvements are already under way: support for additional sources, vertical scaling, and improved down-scaling controls.
### Support for Additional Sources
Ververica Platform Autopilot relies on an estimate of the target input rate for all sources of your Apache Flink application. In this release, we can automatically estimate this rate only for Apache Kafka® sources. Over the next months we will add support for more sources as well as the ability to specify the desired throughput manually, in case it cannot be derived automatically for the current source connector.
### Vertical Scaling
In this initial release, Ververica Autopilot is limited to horizontal scaling, i.e. Autopilot will adjust the parallelism of the application as well as the number of TaskManagers. As of now, Autopilot will not scale the TaskManagers vertically before scaling them out horizontally. Support for vertical scaling is planned for upcoming Ververica Platform releases.
### Improved Downscaling Controls
As you can see in Figure 1, our algorithm tends to scale down conservatively leading to many subsequent downscaling operations when load decreases monotonically over a longer period of time. While this behavior is already configurable internally we believe there is great benefit in exposing this in a more explicit and consistent way in the future.
## Apache Flink/Flink 1.11
Ververica Platform 2.2.0 comes with support for [Flink 1.11](https://flink.apache.org/news/2020/07/06/release-1.11.0.html) and [Flink 1.10](https://flink.apache.org/news/2020/02/11/release-1.10.0.html). Apache Flink 1.9 is deprecated in this platform release and only supported on a best-effort basis.
[Apache Flink 1.11](https://flink.apache.org/news/2020/07/06/release-1.11.0.html) was released on July 6 and came with many exciting features throughout the whole stack, too many to cover them all in this post. In the following sections I will focus on the features and improvements that I believe impact Ververica Platform users and customers the most.
## Operations & Deployment
### Unaligned Checkpoints ([FLINK-14551](https://issues.apache.org/jira/browse/FLINK-14551))
Asynchronous Barrier Snapshots (short: [Checkpointing](https://www.ververica.com/blog/differences-between-savepoints-and-checkpoints-in-flink)) are the foundation of Flink’s lightweight fault-tolerance mechanism. The system takes periodic, consistent checkpoints of the application state and rolls back to the latest completed checkpoint when recovering from a failure. “Checkpoint Alignment”, one of the steps of performing a checkpoint, has proven to be problematic under backpressure. More specifically, alignment times can become high and unpredictable resulting in stalled pipelines & checkpoint timeouts.
To improve the performance of checkpointing under backpressure, the community has rolled out the first iteration of unaligned checkpoints with Flink 1.11. When enabled, checkpoint duration becomes independent of the current throughput of the pipeline. For more information and current limitations checkout the [Apache Flink documentation](https://ci.apache.org/projects/flink/flink-docs-release-1.11/ops/state/checkpoints.html#unaligned-checkpoints).
### Relocatable Savepoints ([FLINK-5763](https://issues.apache.org/jira/browse/FLINK-5763))
Savepoints are a consistent, point-in-time snapshot of the distributed state of a Flink application. They are typically used for application or framework upgrades, migration or simply as backups. So far, it was not possible to move a savepoint move a savepoint after it has completed. Hence, when migrating an application from one cluster to another both clusters needed access to the same distributed file system. Flink 1.11 makes savepoints fully self-contained and relocatable.
### Execution Configuration via the Flink Configuration ([FLINK-14785](https://issues.apache.org/jira/browse/FLINK-14785))
Flink 1.11 (and Flink 1.10) allows to pass all [execution configurations](https://ci.apache.org/projects/flink/flink-docs-release-1.11/ops/config.html#backup) via the flink-conf.yaml. This includes configuration options like the checkpointing interval, the auto-watermark interval or time characteristic, all of which were previously only configurable in code. Being able to control such operational aspects or your application via the configuration is very valuable. Passing execution configurations through the Flink configuration in Ververica Platform allows to, first, set reasonable defaults for such configurations and, second, to warn users if they are using platform features like the _LATEST_STATE_ upgrade strategy without configuring the execution environment accordingly.
### Improvements to the Flink Web User Interface
Flink 1.11 includes a number of improvements to its web user interface. Most notable features are the ability to trigger and analyze TaskManager thread dumps directly from the web user interface ([FLINK-14816](https://issues.apache.org/jira/browse/FLINK-14816)) and improved backpressure detection ([FLINK-14127](https://issues.apache.org/jira/browse/FLINK-14127)).
### Metrics Reporters as Plugins ([FLINK-16222](https://issues.apache.org/jira/browse/FLINK-16222))
Like file systems, metrics reporters can now be loaded as plugins. This allows us to bundle more metrics reporters in our distribution of Apache Flink without risking additional classloading conflicts.
## Table API & SQL
### A Good File System Connector
Flink 1.11 introduces a [new file system connector](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/table/connectors/filesystem.html) for the Table API & SQL. It is based on the battle-tested [StreamingFileSink](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/connectors/streamfile_sink.html) of the DataStream API providing exactly-once delivery guarantees and handling bounded and unbounded inputs transparently. While the legacy filesystem connector only supported CSV, the new file system connector introduced in Flink 1.11 supports CSV, [Apache Parquet®](https://parquet.apache.org/), ORC, [Apache Avro®](https://avro.apache.org/) and JSON formats.
In addition, the new connector comes with a special treat for all Hive users: when ingesting a stream into a partitioned Hive table, the file system connector will add the partition to the HiveMetastore once partitioning is complete.
### Ingestion of Changelogs & CDC Formats
So far, Flink’s SQL engine has only been able to ingest so-called append streams, meaning every ingested record is interpreted as a new row in a dynamic table. With Flink 1.11 the community added support for ingesting upsert streams or changelogs.
In practice, you can now read changelogs created by popular change data capture (CDC) tools like [Debezium](https://debezium.io/) or [Canal](https://github.com/alibaba/canal/wiki/Introduction), further process them with Flink SQL and finally write them to any downstream system supported by Apache Flink. A particularly popular application is materialized view maintenance using Flink SQL in order to reduce load on source systems and benefit from Flink’s advanced SQL features like temporal table joins.
## Other Improvements
### Universal Blob Storage
Ververica Platform comes with [Universal Blob Storage](https://docs.ververica.com/platform_operations/blob_storage.html), a feature that centrally manages the blob storage requirements of all platform components. For example, all your Apache Flink clusters can be automatically configured to consistently use the desired blob storage provider for savepoints, checkpoints and high-availability storage.
So far, Ververica Platform has been supporting [AWS S3](https://aws.amazon.com/s3/) and [Azure Blob Storage](https://azure.microsoft.com/en-us/services/storage/blobs/). With Ververica Platform 2.2.0 we are adding support for Apache Hadoop® HDFS 2.x and Apache Hadoop® HDFS 3.x including authentication & authorization via Kerberos.
### Suspend with Draining
When a Deployment is suspended or a stateful upgrade is triggered, Ververica Platform shuts down the Apache Flink application via the _stop_ command. This will atomically trigger a savepoint and stop the job. In addition to that, you can now instruct Ververica Platform to additionally drain the pipeline prior to stopping it.
This allows you to fully shut down your job without leaving any unhandled events or state behind. Another common scenario for this is an incompatible job upgrade: draining allows you to preserve important state such as [Kafka offsets](https://www.ververica.com/blog/how-apache-flink-manages-kafka-consumer-offsets) while flushing out incompatible state entries prior to the upgrade.
### SQL Server Support for Platform Persistence
Besides MySQL and PostgreSQL, Ververica Platform now supports [SQL Server](https://www.microsoft.com/en-us/sql-server/sql-server-downloads) as a persistence backend. On [Microsoft Azure](https://azure.microsoft.com/en-us/), support for SQL Server was the missing building block for automatic availability zone failover for your Apache Flink applications.
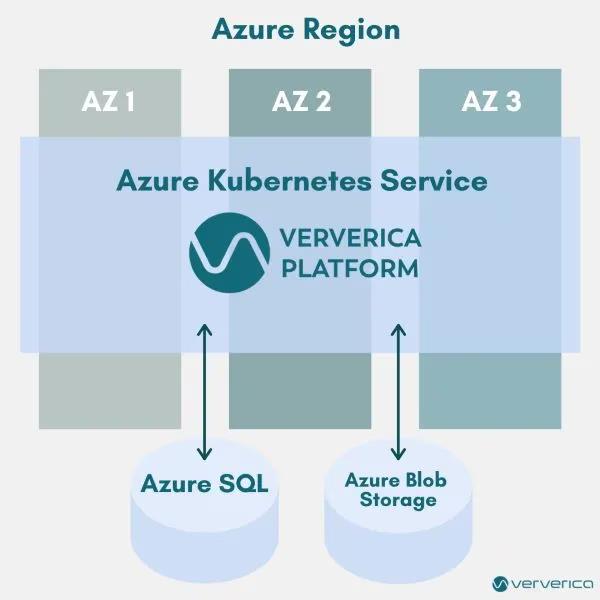
## What’s next?
With the wide variety of improvements in Flink 1.11 on the one hand, and Ververica Platform Autopilot on the other hand, Ververica Platform 2.2 is probably one of the most anticipated platform releases so far. And that’s probably only until the next one: the team at Ververica - together with our Early Access Program users - is already working full steam ahead towards the general availability of Flink SQL in Ververica Platform later this year. Excited? Stay tuned for more updates and announcements in the coming months!
---
---
title: "Setting up Role-based Access Control (RBAC) with UAA & LDAP in Ververica Platform"
description: "Learn how to set up Role-based Access Control in Ververica Platform by integrating UAA with LDAP, ensuring automatic role assignment based on user groups."
lastUpdated: 2026-07-07T10:21:07.000Z
source_url:
html: "https://www.ververica.com/blog/role-based-access-control-rbac-uaa-ldap-in-ververica-platform"
md: "https://www.ververica.com/blog/role-based-access-control-rbac-uaa-ldap-in-ververica-platform.md"
---
[**User Account and Authentication (UAA)**](https://docs.cloudfoundry.org/uaa/uaa-overview.html) from [**Cloud Foundry**](https://www.cloudfoundry.org/) is a free, open source, and enterprise scale identity management and authorization service. Its primary role is as an [**OAuth2**](https://oauth.net/2/) provider, issuing tokens for client applications to use when they act on behalf of end users. [**Ververica Platform**](https://www.ververica.com/platform) can be configured to [**authenticate**](https://docs.ververica.com/platform_operations/auth/authentication.html) against UAA thanks to its support of the [**OpenID Connect (OIDC)**](https://openid.net/connect) protocol. UAA can also be a bridge to other sources of truth about users and their groups, such as [**Lightweight Directory Access Protocol (LDAP)**](https://ldap.com/) services. [**Role-based Access Control (RBAC)**](https://docs.ververica.com/platform_operations/auth/authentication.html) in Ververica Platform allows you to control the platform access based on roles that can be bound to entities such as users or groups. In this article, we walk you through the steps to set up Ververica Platform RBAC with UAA integrated with LDAP such that an authenticated user is assigned a specified role automatically based on his/her groups in LDAP.
## Prerequisites
Before you continue, make sure you have the following setup in place:
- A running LDAP server.
- A running UAA server. If you do not have one, [**get UAA from GitHub and run it locally**](https://github.com/cloudfoundry/uaa/blob/develop/README.md#quick-start)
- A running instance of Ververica Platform Stream Edition or above. See the Ververica Platform documentation on [**how to get started locally with Minikube**](https://docs.ververica.com/getting_started/index.html).
- [**UAA CLI (UAAC)**](https://docs.cloudfoundry.org/uaa/uaa-user-management.html), to interact with UAA. UAAC is developed in [**Ruby**](https://www.ruby-lang.org/en/), so you will have to install [**Ruby**](https://www.ruby-lang.org/en/) first. An alternative to UAAC is to use UAA's REST API with curl.
- The [**openssl**](https://www.openssl.org/) command line tool to generate an [**RSA**](https://en.wikipedia.org/wiki/RSA_(cryptosystem)) key pair.
## The Big Picture
[**Authentication and authorization**](https://docs.ververica.com/platform_operations/auth/index.html) is available in Ververica Platform Stream Edition or above. Once authenticated, a user is assigned the role admin, owner, editor or viewer based on the configured [**role bindings**](https://docs.ververica.com/platform_operations/auth/authorization.html), the username, and the user’s group. These roles are associated with a [**Ververica Platform Namespace**](https://docs.ververica.com/platform_operations/namespaces.html). Different roles have [**different privileges**](https://docs.ververica.com/platform_operations/auth/authorization.html) in that namespace. For example, an editor has read and write access to all resources within a namespace except [**Deployment Targets**](https://docs.ververica.com/platform_operations/deployment_targets.html) and [**API Tokens**](https://docs.ververica.com/platform_operations/auth/api_tokens.html).
When the authentication and authorization against UAA and LDAP is configured, Ververica Platform can assign correct roles to users as it can get usernames and groups from LDAP via UAA. Here is the big picture showing the interactions between Ververica Platform, UAA and LDAP:
1. When [**authentication is enabled**](https://docs.ververica.com/platform_operations/auth/authentication.html)[,](https://docs.ververica.com/platform_operations/auth/authentication.html) the Ververica Platform Web UI is password-protected. Users who try to access the Web UI are redirected to the configured OIDC provider’s (here UAA’s) login page.
1. Once UAA receives a username and a password from a user, it searches the user’s Distinguished Name (DN) in the LDAP server based on the configured mapping (explained in a later section of this article). Then it attempts an [**LDAP bind**](https://tools.ietf.org/html/rfc4511#section-4.2) with the user’s DN and the provided password.
1. When the authentication succeeds, UAA retrieves the LDAP user and group information.
1. UAA encodes the user and group information into tokens which are then returned to Ververica Platform.
## LDAP Users and Groups
To setup authentication and authorization, users and groups have to be configured in LDAP. For demonstration purposes in this article, we are going to use the following setup:
Here we have four users: user1, user2, user3 and vvpadmin. user1, user2, and user3 are members of the group default.editors. user1 is also a member of the group devops.viewers. We use the objectClass groupOfNames to define LDAP groups. vvpadmin will be used as the administrator of Ververica Platform. The passwords of all users are password. We run our [**OpenLDAP**](https://www.openldap.org/) server locally at ldap://localhost:389.
> **NOTE:** If you are setting up a local testing OpenLDAP server for trying out the steps described in this article, you can bootstrap the users and the groups with the attached ldap-data.ldif.
## Integrate UAA with LDAP
To connect UAA to LDAP, append the following configuration into the UAA configuration file uaa.yml. If you started your UAA with ./gradlew run, this is ./scripts/cargo/uaa.yml. Otherwise, consult your UAA administrator for the location of the file. It should be specified by one of ${UAA_CONFIG_URL}, file:${UAA_CONFIG_FILE}, file:${UAA_CONFIG_PATH}/uaa.yml.
```yaml
spring_profiles: ldap,default
ldap:
profile:
file: ldap/ldap-search-and-bind.xml
base:
url: 'ldap://localhost:389/'
userDn: 'cn=admin,dc=example,dc=com'
password: 'secret'
searchBase: 'ou=people,dc=example,dc=com'
searchFilter: 'cn={0}'
referral: follow
groups:
file: 'ldap/ldap-groups-map-to-scopes.xml'
searchBase: 'ou=people,dc=example,dc=com'
searchSubtree: true
groupSearchFilter: 'member={0}'
maxSearchDepth: 10
autoAdd: true
attributeMappings:
external_groups:
- roles
externalGroupsWhitelist:
- '*'
```
In the configuration above, ldap.profile and ldap.base specify how UAA maps a username to a user DN in LDAP. The LDAP server is specified via ldap.base.url. You need to adjust the url according to your setup. ldap.groups specifies how UAA retrieves the group information for a given user DN. The configuration member={0} here is specific to the objectClass groupOfNames. If you use another objectClass to define LDAP groups, you need to adjust this accordingly. For more detailed explanations on ldap.base and ldap.groups, you can reference to [**the UAA and LDAP integration documentation**](https://github.com/cloudfoundry/uaa/blob/develop/docs/UAA-LDAP.md). The purpose of attributeMappings and externalGroupsWhitelist here is to **let UAA add the group information**into the roles claim of the returned ID token.
### Generate a JWS Key Pair
As Ververica Platform expects a signed JSON Web Token (JWT), we run the following command to generate a signing key:
```bash
openssl genrsa -out signing-key.pem 2048
```
then add the content of the key into uaa.yml:
```yaml
jwt:
token:
signing-key: |
```
### Use a Correct IP Address and Port
If your UAA runs remotely and binds to an IP address and a port, you can (re-)start your UAA server now. You can skip the rest of this section and substitute 192.168.64.1:18080 with your UAA IP address and port in the rest of the article.
If you run UAA locally on your computer, we need to bind UAA to an IP address which is reachable from Ververica Platform. This is because when Ververica Platform runs in a Kubernetes environment (e.g., Minikube), localhost is defined in the scope of the Ververica Platform pod, not the machine where you installed UAA. The solution here is to [**use the Minikube bridge IP**](https://minikube.sigs.k8s.io/docs/handbook/host-access/), which is 192.168.64.1 in our case. By default, UAA binds to two ports: 8080 and 8081. If any of the ports is occupied on your computer, you need to change the UAA ports. For example, to bind UAA to 192.168.64.1:18080, change issuer.uri in uaa.yml:
```yaml
issuer:
uri: http://192.168.64.1:18080/uaa
```
Now, we (re-)start our local UAA:
```bash
./gradlew -Pport=18080 run
```
UAA will then bind to 18080, and 18081.
> **NOTE:** Check ./uaa/build/reports/tests/uaa-server.log to confirm that UAA has started correctly
### Create a Client in UAA
Now that UAA has started, run the following commands to create a client vvp in UAA. Make sure to include roles in the scope because we will get the group information via the roles claim. Ververica Platform will use the client vvp to get tokens from UAA.
```bash
uaac target http://192.168.64.1:18080/uaa
uaac token client get admin -s adminsecret
uaac client add vvp --name VVP --secret vvpsecret \
--scope openid,roles \
--authorized_grant_types authorization_code,refresh_token,client_credentials,password \
--authorities uaa.resource \
--redirect_uri http://localhost:8080/login/oauth2/code/vvp
```
The password included in --authorized_grant_types above is optional. We use it only in the following verification:
```bash
uaac token owner get vvp user1 -s vvpsecret -p password
uaac context
uaac token decode
```
If authenticated correctly, we should be able to see the following roles claim in the ID token:
```bash
roles: default.editors devops.viewers
```
## Integrate Ververica Platform with UAA
To use UAA for authentication and authorization in Ververica Platform, add the following configuration into [**the Helm values file**](https://docs.ververica.com/installation/helm/index.html#completing-the-installation-using-helm) values.yaml. Make sure to request the roles scope and set groupsClaim to roles in order to retrieve group information via the roles claim when a user is authenticated. Note that provider.issuerUri and endSessionEndpoint reference to the IP address and the port where UAA binds.
```yaml
vvp:
auth:
enabled: true
admins:
- user:vvpadmin@example.com
oidc:
groupsClaim: roles
registrationId: vvp
registration:
clientId: vvp
clientSecret: vvpsecret
redirectUriTemplate: "{baseUrl}/{action}/oauth2/code/{registrationId}"
clientAuthenticationMethod: basic
authorizationGrantType: authorization_code
scope:
- openid
- roles
provider:
issuerUri: http://192.168.64.1:18080/uaa/oauth/token
userNameAttribute: email
endSessionEndpoint: http://192.168.64.1:18080/uaa/logout.do
```
Now we can start or upgrade Ververica Platform with the created values.yaml above. Do not forget to [**add your license**](https://docs.ververica.com/installation/helm/index.html) into values.yaml if you are using Ververica Platform 2.1 or above before you start.
When Ververica Platform starts, it has a namespace default. In the namespace default, any authenticated user (system:authenticated) is assigned the owner role by default. We can now login to Ververica Platform as vvpadmin, remove the default role binding and add a new role binding to assign all users in the group default.editors the role editor (see the screenshot below). Open a Private Window or a Incognito Window from your browser, login to Ververica Platform with user1, you will be able to tell you have editor role in the namespace default, e.g., you can create secret values but cannot create API tokens (the menu item is grayed out).
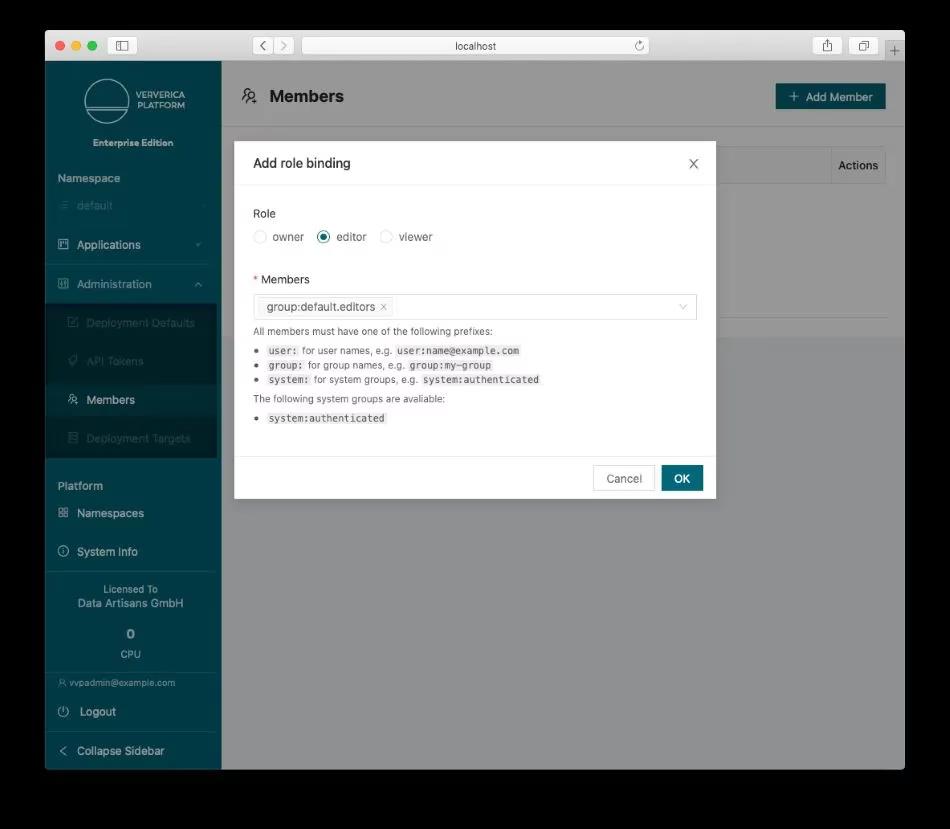
If you have another Ververica Platform namespace (e.g., devops), you can group your users into different LDAP groups (e.g., devops.editors, devops.viewers) and setup the role bindings in that namespace accordingly. This way, users will get their specified roles automatically once they login.
> **NOTE:** If you change the group membership of a user in LDAP after the user login to Ververica Platform, the new group membership assignment will be effective when the user logs out and logs in again.
## Summary
In this article, we set up the Role-based Access Control in Ververica Platform by integrating it with UAA and LDAP such that usernames and user groups are passed from LDAP to Ververica Platform via the UAA’s ID token. When the group-based role binding is set up in Ververica Platform, users are automatically assigned their roles based on their LDAP group membership once they login.
---
---
title: "How OpenSSL in Ververica Platform 2.1 improves your Flink performance"
description: "Discover how Ververica Platform 2.1 enhances Flink performance by utilizing OpenSSL for encrypted communication, achieving up to 3x better throughput."
lastUpdated: 2026-07-07T07:01:29.000Z
source_url:
html: "https://www.ververica.com/blog/how-openssl-in-ververica-platform-improves-your-flink-job-performance"
md: "https://www.ververica.com/blog/how-openssl-in-ververica-platform-improves-your-flink-job-performance.md"
---
With Ververica Platform, we are always striving to provide our users the best Flink experience they can get. Our newest release, version 2.1, includes a very nice performance improvement that does not require any user changes in the Flink applications or cluster setup: using OpenSSL for encrypted communication rather than relying on Java’s implementation. In our benchmarks, we were able to achieve throughput improvements of 50% to 200%. In the following sections we discuss how SSL generally affects a Flink jobs' performance and how OpenSSL in Ververica Platform changes that . We also give an overview of the setup and the technical implementation.
## Background
[**Flink’s network stack**](https://flink.apache.org/2019/06/05/flink-network-stack.html) is built on top of [**Netty**](https://netty.io/) and is one of the core components that make up the flink-runtime module and sit at the heart of every Flink job. It connects individual work units (subtasks) from all TaskManagers and is where your streamed-in data flows. The network stack is crucial to the performance of your Flink job for both the throughput and latency you observe.
For more information, please refer to the following blog posts on Flink’s network stack:
- [**A Deep-Dive into Flink's Network Stack**](https://flink.apache.org/2019/06/05/flink-network-stack.html)**,**
- [**Flink Network Stack Vol. 2: Monitoring,**](https://flink.apache.org/2019/07/23/flink-network-stack-2.html)
- [**Metrics,**](https://flink.apache.org/2019/07/23/flink-network-stack-2.html)
- [**and that Backpressure Thing**](https://flink.apache.org/2019/07/23/flink-network-stack-2.html).
Apache Flink supports SSL as a standard protocol for securing all network communication within a cluster. Since Flink 1.9, the project has supported default encryption using Java's SSL implementation along with OpenSSL, which [**claims significant performance improvements**](https://netty.io/wiki/requirements-for-4.x.html#wiki-h4-4).
## Setup
Since release 2.1, Ververica Platform includes Flink 1.9 and 1.10 images that include a dynamically-linked netty-tcnative version that fits the container they are built with. When you [**enable SSL**](https://docs.ververica.com/vvp/user-guide/application-operations/session-clusters/flink-configuration/#ssltls-setup) (with the push of a button as shown below; or a simple deployment flag for the REST API), we will automatically select Netty’s OpenSSL implementation for Flink 1.10 and ensure compatibility between this and the default Java SSL setup.
## Benchmarks
In order to see the magnitude of the actual performance gains (if any), we set up two different jobs that process data from artificial inputs and discard their computed results (to reduce the effects of any external systems). The first example leverages the [**Troubled Streaming Job**](https://github.com/ververica/flink-training-troubleshooting/blob/master/src/main/java/com/ververica/flinktraining/solutions/troubleshoot/TroubledStreamingJobSolution43.java) from our **Apache Flink Tuning & Troubleshooting training** which we regularly offer at the [**Flink Forward**](https://www.flink-forward.org/) conference. The second job performs a more complex SQL query which is joining a few tables to de-normalize dimensional data.
## Troubled Streaming Job
This job reads from a fake Kafka source with a total of 8 partitions, 2 of which are idle. These (binary) events are then deserialized, grouped/keyed by location for a windowed aggregation, and put into one DiscardingSink for normal data and one for late data (see the job graph below).
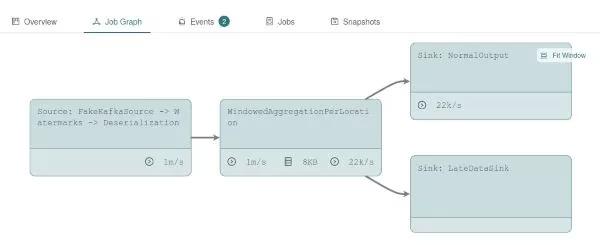
For the benchmark, we use our [**TroubledStreamingJobSolution43**](https://github.com/ververica/flink-training-troubleshooting/blob/master/src/main/java/com/ververica/flinktraining/solutions/troubleshoot/TroubledStreamingJobSolution43.java) and measure the throughput in numRecordsOutPerSecond for the source task and provide the average throughput in the last 10 minutes of a 15-minute long benchmark run. During this period, all benchmark runs showed rather stable results. As you can see, enabling Java-based SSL decreases the overall throughput by around 40% while using OpenSSL only costs 5-15% of the performance. Compared to Java-SSL, OpenSSL is thus up to 60% faster.
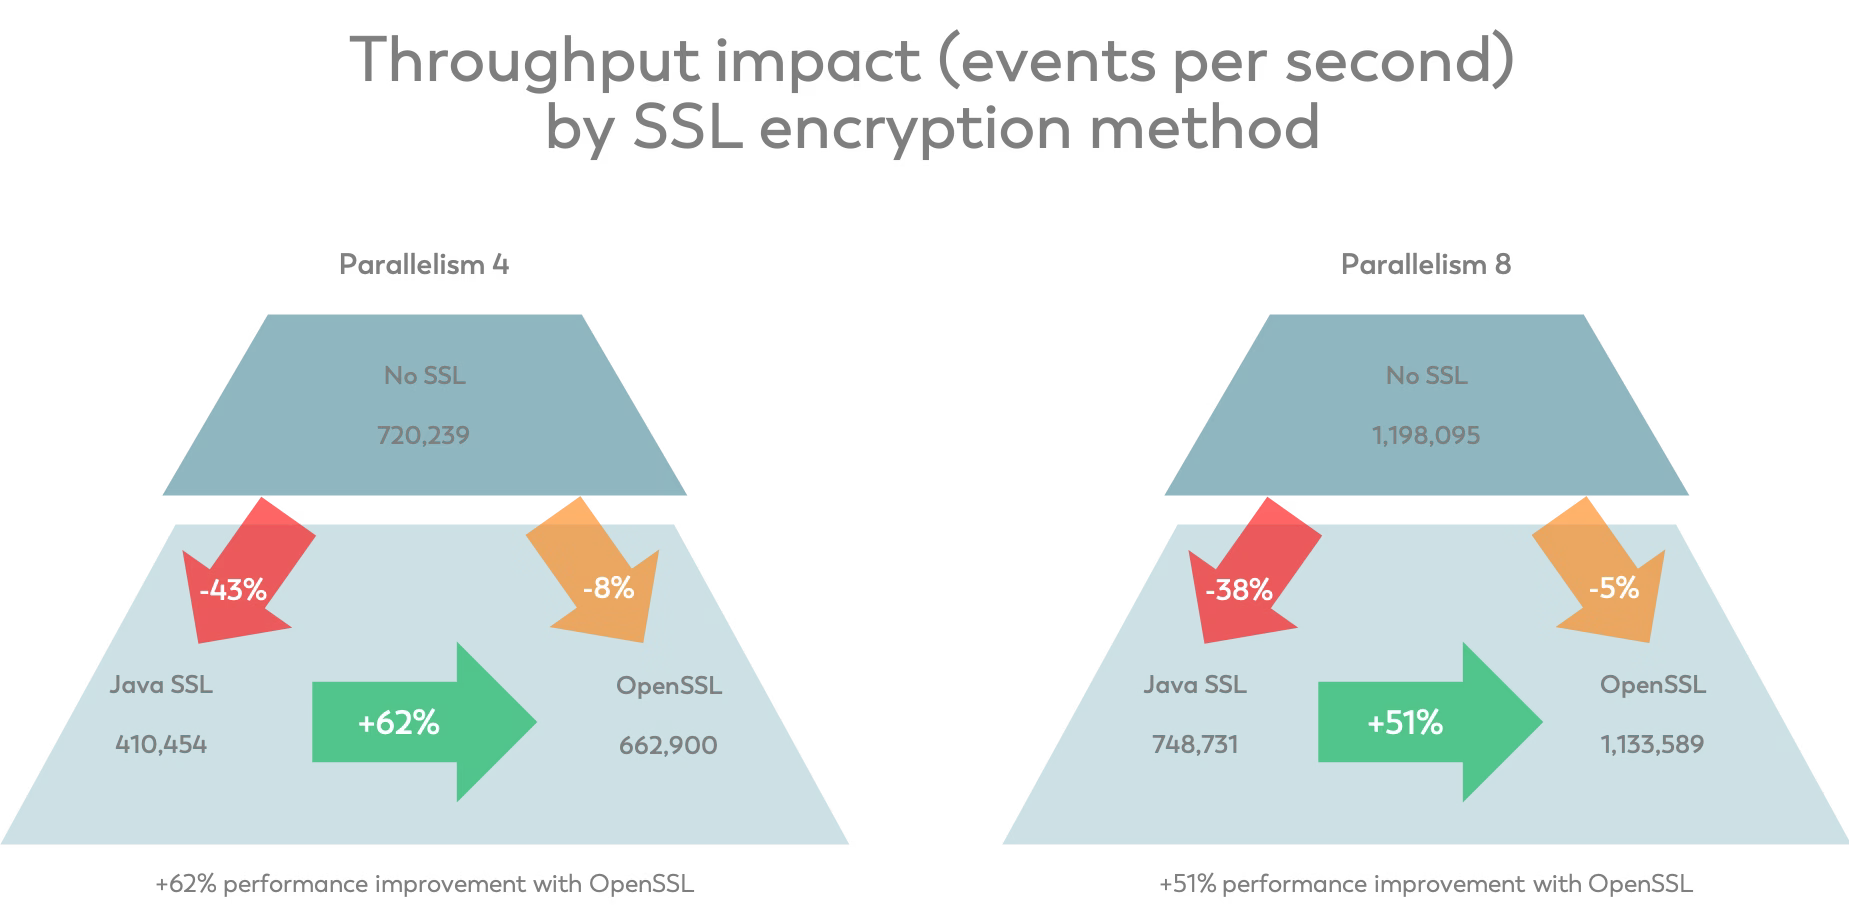
## Complex SQL Query
The troubled streaming job from above only has one network shuffle in its job graph which is exemplary for simple Flink jobs but does not cover more complex scenarios. Our second scenario is inspired by a real streaming SQL job we were given and joins an input stream from fact_table with a few dimensional tables to enrich incoming records. The query outlined below consists of 5 [**temporal table joins**](https://www.ververica.com/blog/flux-capacitor-huh-temporal-tables-and-joins-in-streaming-sql) on randomly generated data (Strings of up to 100 characters each) in processing time (for simplicity):
```sql
SELECT
D1.col1 AS A,
D1.col2 AS B,
D1.col3 AS C,
D1.col4 AS D,
D1.col5 AS E,
D2.col1 AS F,
D2.col2 AS G,
D2.col3 AS H,
...
D5.col4 AS X,
D5.col5 AS Y
FROM
fact_table,
LATERAL TABLE (dimension_table1(f_proctime)) AS D1,
LATERAL TABLE (dimension_table2(f_proctime)) AS D2,
LATERAL TABLE (dimension_table3(f_proctime)) AS D3,
LATERAL TABLE (dimension_table4(f_proctime)) AS D4,
LATERAL TABLE (dimension_table5(f_proctime)) AS D5
WHERE
fact_table.dim1 = D1.id
AND fact_table.dim2 = D2.id
AND fact_table.dim3 = D3.id
AND fact_table.dim4 = D4.id
AND fact_table.dim5 = D5.id
```
Flink’s Blink planner transforms this to the following job graph and, for the benchmark, we limit each dimensional data input stream to 1,000 events per second, leaving the fact stream unlimited. Eventually, the result of the query is written to a DiscardingSink like above.
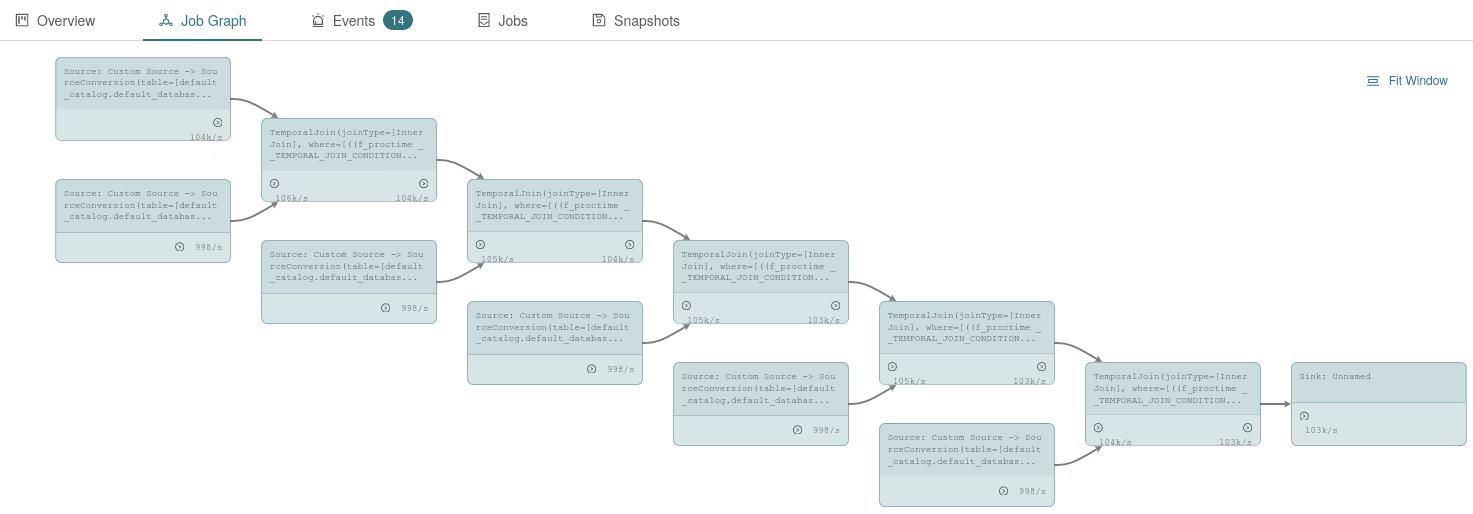
While the String serialization and deserialization certainly takes a lot of the performance in this scenario, there is also some overhead by the network communication alone. It also takes a bit longer to get into a stable state and we will show the average throughput, i.e. numRecordsOutPerSecond, for all sources combined for the last 5 minutes of a 15-minute-long benchmark run. Compared to the Troubled Streaming Job above, this job has a few more network shuffles and therefore, the effect of enabling SSL is larger than before. Using Java-based SSL costs up to 70% of the throughput while enabling OpenSSL reduces the number of processed records by only 10-15%. This makes your Flink job 3X as fast, just by optimizing the SSL implementation!
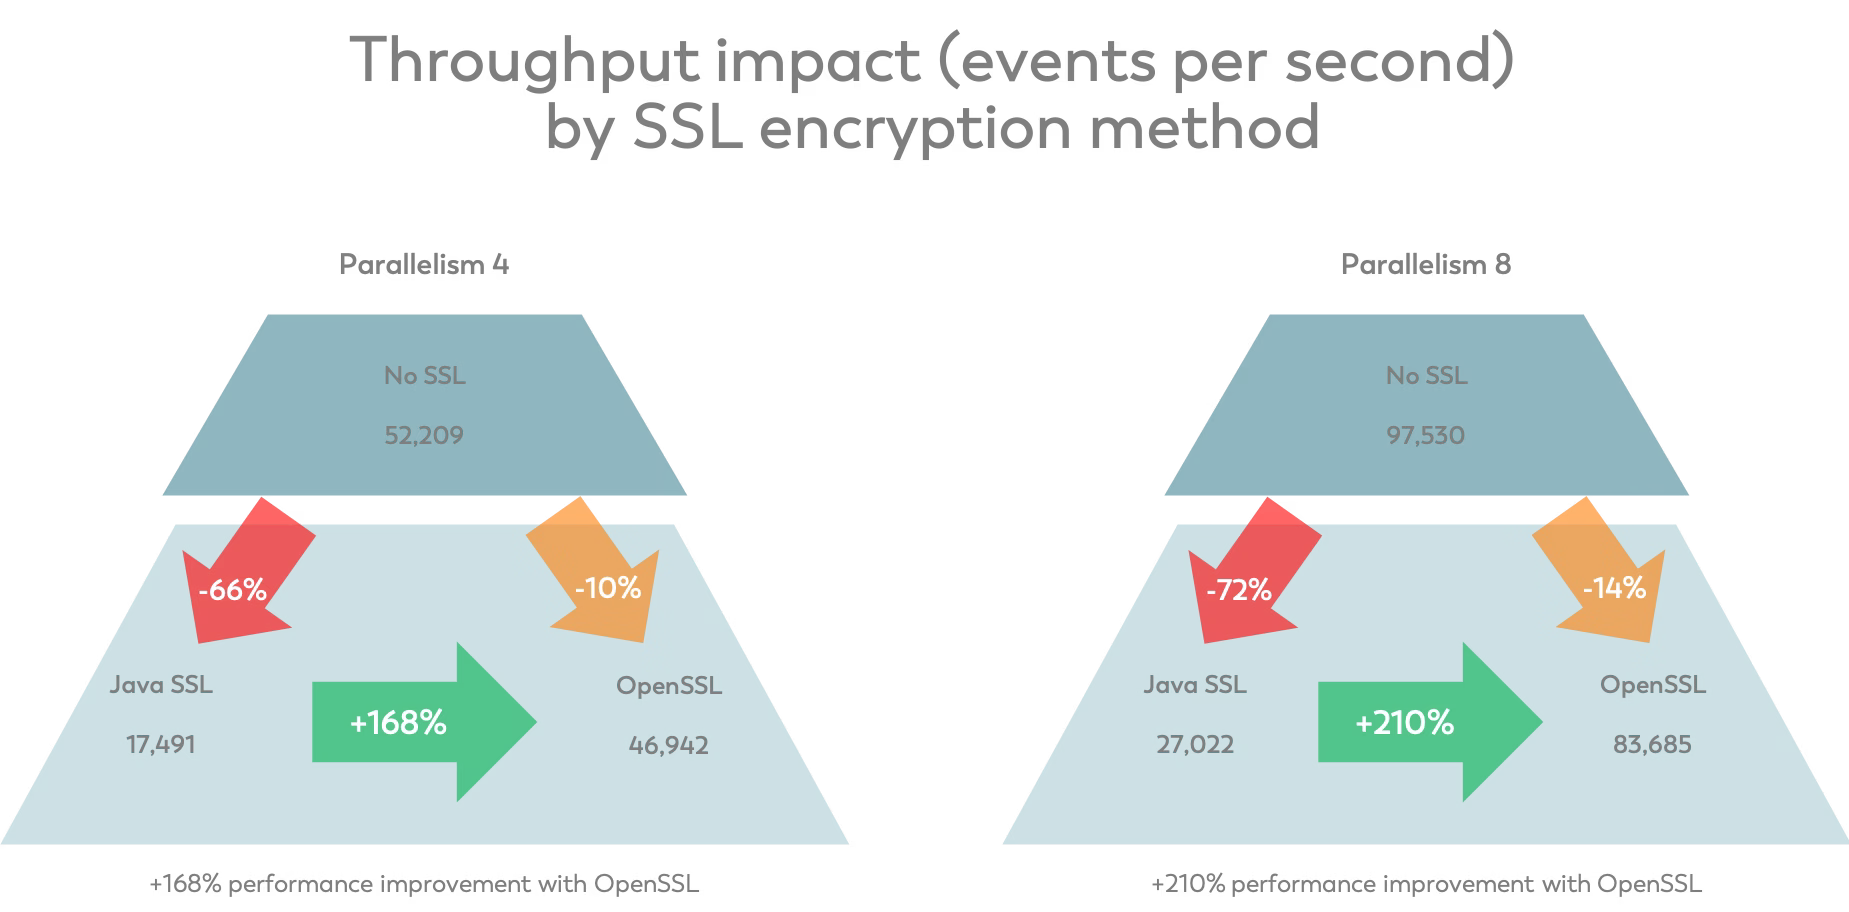
## Conclusion
As you can see from the results above, the improvements you can get from using OpenSSL for encrypted communication channels can be quite significant with up to 3x the performance that Java SSL can achieve. At the same time, enabling OpenSSL encryption does not require any changes to either your Flink application’s implementation or its configuration. All you need is just Ververica Platform 2.1 with Flink 1.9¹ or 1.10 while SSL is enabled. If needed, or for your own benchmarks, you can switch back to the Java-based SSL implementation setting security.ssl.provider: JDK. We are curious about the changes you observe in your jobs. Have a go, see for yourself, and report back to help spread the word.
¹ For backwards compatibility with your existing deployments and (older) Flink docker images they may run on, deployments on Flink 1.9 require setting the Flink configuration security.ssl.provider: OPENSSL explicitly to enable OpenSSL encryption. Please find details in the [**Ververica Platform documentation**](https://docs.ververica.com/user_guide/deployments/configure_flink.html#ssl-tls-setup).
## Appendix
- Technical Details
Support for running Apache Flink with OpenSSL is implemented using [**netty-tcnative**](https://netty.io/wiki/forked-tomcat-native.html), Netty’s fork of Tomcat Native. It works with OpenSSL (>= 1.0.2) and must be on the classpath in order for Flink to use it. Netty-tcnative comes in a few [flavors](https://netty.io/wiki/forked-tomcat-native.html#artifacts) of the provided jars:
- dynamically-linked to libapr-1 and OpenSSL (using your system’s libraries)
- statically-linked libraries against OpenSSL or [boringssl](https://boringssl.googlesource.com/) (Google’s fork of OpenSSL); both bundle the libraries inside the jar
Configuration is done via security.ssl.provider; please see the [**Flink docs**](https://ci.apache.org/projects/flink/flink-docs-release-1.10/ops/config.html#security-ssl-provider) for details on how to use it without our Flink images.
- Why is OpenSSL encryption not provided as a default in Apache Flink?
All of the mentioned flavors of providing [**netty-tcnative**](https://netty.io/wiki/forked-tomcat-native.html) have their flaws:
- Statically-linked binaries are the easiest approach to getting started, however, Apache Flink cannot ship these files due to conflicts between the Apache License and [**the dual OpenSSL and SSLeay license**](https://www.openssl.org/source/license.html) from OpenSSL 1.x.
- A dynamically-linked netty-tcnative does not suffer from this conflict but needs to be build specifically for the system (libraries) you want to deploy to; the default setup may or may not work on your system.